# Resource Reports
Source: https://docs.vantage.sh/active_resources
Monitor active cloud resources and their costs with Vantage Resource Reports across AWS, Azure, GCP, and other providers.
For supported providers, Vantage looks for active resources within your account. An active resource is a resource, such as a virtual machine, that is currently generating costs within a cloud account. This is in contrast to resources that are included in billing but may no longer be live. Examples of active resources include items like Amazon S3 buckets, Azure Load Balancers, Snowflake queries, Confluent clusters, etc.
You can create *resource reports* to see filtered views of your active resources. These reports provide visibility into all the currently operational resources within your account and the associated costs incurred by each resource. Reports include filterable dimensions, such as account, tag, region, service, and service-specific metadata.
Use Resource Reports when you need a current inventory with resource metadata. To see how the number of resources or other cost-bearing groupings changes over time, use [Count reporting in Cost Reports](/cost_reports#count-reporting).
Active resource views are currently supported for [AWS](/connecting_aws), [Azure](/connecting_azure), [GCP](/connecting_gcp), [Kubernetes](/connecting_kubernetes), [Snowflake](/connecting_snowflake), [MongoDB](/connecting_mongodb-atlas), [Confluent](/connecting_confluent), [PlanetScale](/connecting_planetscale), [Linode](/connecting_linode), [ClickHouse Cloud](/connecting_clickhouse), [Datadog](/connecting_datadog), [Anthropic](/connecting_anthropic), and [Modal](/connecting_modal).
## AWS Active Resources
Vantage shows only active resources that have an associated IAM role. One common source of confusion is when an organization has only a root/management account with an IAM role. To view active resources from each member account, create an IAM role for each member account. As you create each additional IAM role, the member account's resources are automatically added to the active resource inventory. See the [AWS integration](/connecting_aws) documentation for details.
Not every AWS service is supported for resource-level costs; however, most services that incur costs are supported. To see the full list of services for which there are resource-level costs, see the documentation on [supported AWS services](/aws_supported_services).
## Azure Active Resources
To see the full list of supported Azure services, see the [Azure documentation](/azure_supported_services).
Active Resources are not available for [Azure CSP integrations](/connecting_azure_csp). Azure does not expose any list or describe resource APIs through Partner Center to provide resource metadata.
## GCP Active Resources
To see the full list of supported GCP services, see the [GCP documentation](/gcp_supported_services).
## Kubernetes Active Resources
A Kubernetes *managed workload* is a higher-level abstraction than a pod that automatically manages pod objects on your behalf. Vantage currently supports Deployments, StatefulSets, DaemonSets, Jobs, CronJobs, and ArgoCD Rollouts and syncs these managed workloads as active resources in your account. When available, pods are grouped by controller, and you can view and filter on the following metadata:
* Controller name
* Controller type
* Cluster
* Namespace
* Controller labels
## Other Available Active Resources
The following active resources are available for the additional providers listed below.
| Provider | Available Active Resources |
| - | - |
| [Snowflake](/connecting_snowflake) | Snowflake queries |
| [MongoDB Atlas](/connecting_mongodb-atlas) | MongoDB Atlas clusters |
| [Confluent](/connecting_confluent) | Confluent Kafka clusters |
| [PlanetScale](/connecting_planetscale) | PlanetScale databases |
| [Linode](/connecting_linode) | Linode Instances, Kubernetes Clusters, Volumes, Object Storage, Images, and NodeBalancers |
| [ClickHouse Cloud](/connecting_clickhouse) | ClickHouse Cloud services |
| [Anthropic](/connecting_anthropic) | Anthropic API keys, Users, and Models |
| [Datadog](/connecting_datadog) | Custom metrics |
| [Modal](/connecting_modal) | Modal Apps |
Anthropic Users and Models active resources are synced only from the [Claude API integration](/connecting_anthropic#connect-the-claude-api) (Admin API key). If you connect only Claude.ai (Claude Enterprise Analytics API), Claude.ai cost and usage data is still available, but no active resources are synced. See the [Anthropic Active Resources](/connecting_anthropic#active-resources) documentation for details.
## View Active Resources
Active resources are synced for each [workspace](/workspaces) at least once every 24 hours. Vantage syncs all tags specific to a service.
From the top navigation, click **Active Resources**.
The **Services** screen is displayed, which contains each resource by name (e.g., CloudFront Distributions, Azure Databricks Workspaces, etc.), the total number of active resources, and accrued costs for each resource. The **Accrued Cost** column shows the past 30 days of costs. Select a resource from the parent list to see a list of all resources within that resource group. In the below example, the NAT Gateways resource is selected from the list.
Select an individual resource from the filtered list.

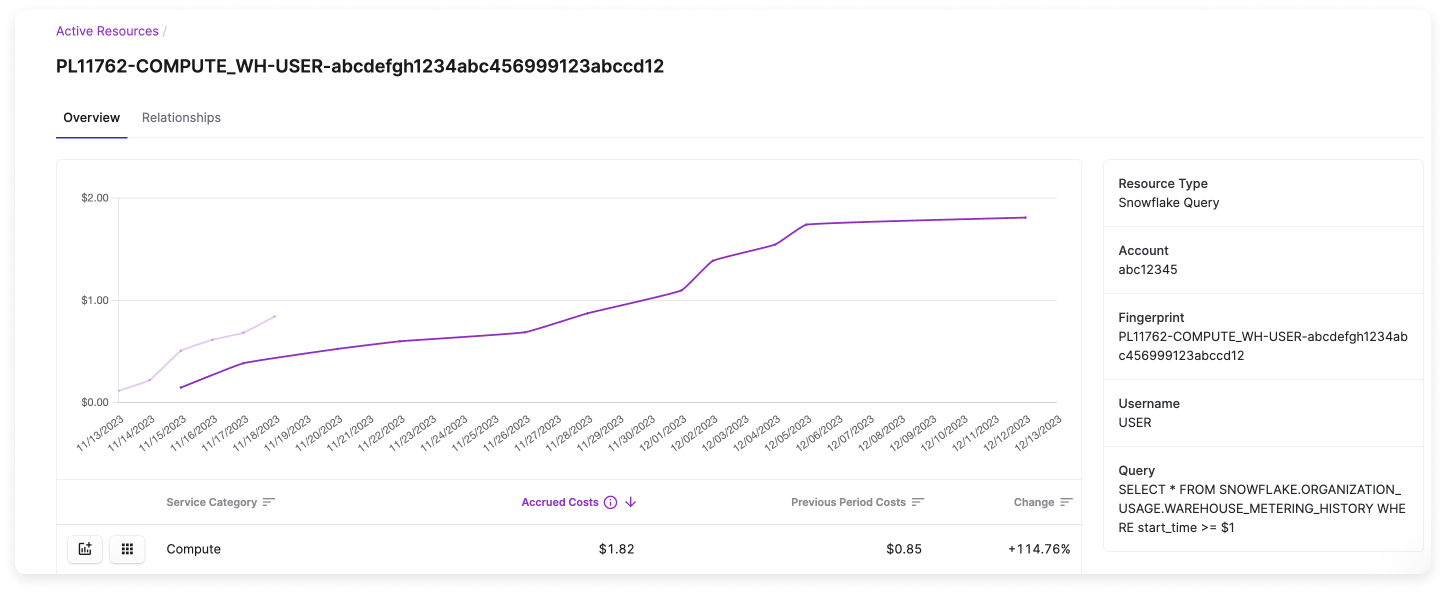
The resource is displayed along with a detailed view of its costs over time. In the below image, the selected AWS NAT Gateway resource is displayed along with associated metadata.

When available, a **View in Cost Report** button appears at the top of the active resource detail page, linking directly to the default Cost Report filtered by the resource's provider, service, and resource ID. An **Open in \[Provider]** button also appears, linking directly to the resource in the provider's console (e.g., AWS Console, Azure Portal, or GCP Console). The **Open in \[Provider]** button is available for most AWS, Azure, and GCP resources, as well as PlanetScale databases. Availability depends on the resource type and whether the necessary metadata (such as region or resource identifier) is present.
Any tags assigned to the resource, both provider and Virtual Tags, are also displayed in the **Assigned Tags** section at the bottom. Note that Virtual Tags are currently supported for only AWS and Azure resources in this view.

## Create a Resource Report
Create a resource report to filter by specific resources or groups of resources. Create detailed reports, including reports that show:
* Resources across AWS services that match a certain AWS tag
* Resources within a specific AWS member account
* All Amazon EC2 instances that are a certain type, like `m5.large`
* All Snowflake queries belonging to a specific label
To create a resource report:
From the top navigation, click **Active Resources**.
From the left navigation, click **Resource Reports**. You can create new reports and rename your existing reports from this page. The **All Active Resources Report** is provided by default.
From the top right of the page, click **New Resource Report**.

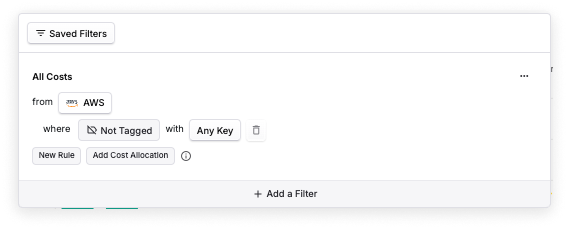
From the top left of the resource list, click **Filters**. The **Filters** panel is displayed.
* Select a **Provider** (e.g., AWS).
* Click **New Rule**, then select a filter category, like **Region**. (See the section below for details on available filter options.)
* Depending on the filter criteria, select an operator (e.g., is, is not, contains).
* Select a value (e.g., *Region* **is** *eu-west-1*).
* Click **New Rule** to add additional criteria to the same filter. Results are displayed where both rule 1 *AND* rule 2 are true.
* Click + Add Filter to add a new filter set. Results are displayed where *either* filter 1 *OR* filter 2 are true.
* At the top of the **Filters** panel, click **Apply Changes**.

At the top of the report, click **Save** or **Save as New**. The report name is displayed in the breadcrumbs above the report. To rename the report, click the pencil icon next to the default report name. Then, update the name and click **Save**.
If you have a Jira integration, you can create a corresponding issue for a Resource Report in your Jira instance. See the [Jira](/jira) documentation for details.
## Customize a Resource Report
You can customize which columns are displayed in your Resource Reports, such as resource-specific metadata fields and tag values, as well as arrange the columns in any order. Both provider tag keys and [Virtual Tag](/tagging) keys can be added as their own columns so you can analyze tag values across resources at scale.
Resource-specific metadata fields are available only when a Resource Report is filtered to a single service. Reports that span multiple services include only the default columns (i.e., **Label**, **Accrued Cost**, **Resource**, **Type**, **Region**, and **Account**) and any tag key columns you add. The **Accrued Cost** column shows the past 30 days of costs.
### Select Columns
To select which columns are displayed on your Resource Report:
From the top menu, select **Active Resources** > **Services**, then select a service. (Alternatively, filter a Resource Report to a single service, such as EC2.)
From the top-right corner of the report table, click **Manage Columns**.
Select or deselect any of the listed columns to adjust the display of your report.

### Reorder Columns
To reorder the columns of your Resource Report:
Click and drag a column header to the position between two existing columns. Arrows are displayed to indicate where the column will be inserted.
The column order is updated in both the Resource Report and the **Manage Columns** dropdown menu.

### Add Tag Columns
You can add specific tag keys as their own columns in a Resource Report so each resource displays the tag value inline, rather than as part of a single grouped tags field. This makes it easier to analyze resources by tag at scale—for example, identifying owners of unattached EBS volumes from [Cost Recommendations](/cost_recommendations), auditing team attribution for the highest-cost RDS instances, or finding resources running in non-prod environments.
Both provider tag keys and [Virtual Tag](/tagging) keys can be added as columns. To add tag columns:
From the top-right corner of the Resource Report table, click **Manage Columns**.
Open the **Tags** section to view available tag keys for the resources in your report.
Select one or more tag keys. Each selection is added as its own column to the report. The column header uses the tag key, and each row displays the corresponding tag value for that resource.
To save your selections so they persist across sessions, click **Save** or **Save as New** at the top of the report.
* If a resource does not have a value for the selected tag key, the column displays an empty value for that row, making it easy to identify untagged or inconsistently tagged resources.
* There is no limit to the number of tag columns you can add to a Resource Report.
* Tag columns are included in [CSV exports](#export-resource-report) and in API responses for the report.
### Sort Columns
To sort a column in a Resource Report, click the arrow next to a column name in the column header. The active sort column icon is highlighted in green, with an arrow indicating the sort direction. Sorting applies across the entire result set, not just the resources visible on the current page.
Sorting on the **Accrued Cost** column requires the report to be saved first.

The column order is saved per report. If you save a report after you customize the columns, the configuration—including visibility, order, and sort—will persist.
### Resource Report Filters
The following filters are available for resource reports.
| Filter | Provider | Examples |
| - | - | - |
| Account | AWS, GCP | AWS or GCP account name (e.g., production) |
| Billing Account | AWS | AWS billing account name |
| Label | All providers | The resource's label (i.e., name) |
| Metadata | All providers | Specific to each resource type (e.g., AWS S3 buckets object count; Azure Load Balancers provisioning state; GCP Dataflow Jobs create time; Confluent Kafka cluster type; MongoDB Atlas cluster deployed region; PlanetScale database branches count; Snowflake query invocations; Kubernetes workload namespace) |
| Not Tagged | All providers | Filter to see resources not tagged with a specific tag key or any tag key |
| Region | AWS, Azure, GCP, Linode | us-east-1, ap-northeast-2, eastus, us-east4, us-lax |
| Resource group | Azure | The Azure resource group name |
| Resource type | All providers | EC2 instances, S3 buckets, Confluent Kafka clusters, Snowflake queries, etc. |
| Subscription | Azure | The Azure subscription name |
| Tag | All providers | Filter to see resource by a specific tag key or tag key/value; Virtual Tags for only AWS and Azure at this time |
| UUID (ARN for AWS) | All providers | The unique provider ID (i.e., ARN for AWS) for the resource |
## Export Resource Report
To export a resource report, click the export button (looks like an arrow pointing down) on the top right of a resource report (does not need to be saved). The resources in the report are exported in a ZIP file with a CSV file per active resource type. Each row includes an active resource along with its cost and metadata. Any [tag columns](#add-tag-columns) added to the report are also included as dedicated columns in the CSV export. Select one or more Vantage user emails to send the report. Then, click **Export**. It may take a few minutes for the email to be sent.
## Additional Active Resource Views
The following tabs are available for specific resources on the **Active Resources** screen. These tabs provide additional resource-specific information.
Some of these tabs may also display [Cost Recommendations](/cost_recommendations) relevant to the specific resource you are viewing. In these cases, a recommendation card is displayed at the top of the tab containing a description of the recommendation and remediation steps. The remediation workflow can include CLI commands, links to provider console actions, a list of manual steps, and references to Vantage blogs. When displayed within a specific resource tab, like Rightsizing or Extended Support, the CLI command will automatically include the exact resource ARN of the resource you are viewing.
### Billing Code Descriptions
AWS practitioners who are having trouble understanding AWS billing codes can find descriptions of each billing code, other variations of that billing code, and other services that use the same billing code for specific services in Resource Reports. When you view a Resource Report for a specific service (e.g., EC2 instances), a link to [cur.vantage.sh](https://cur.vantage.sh/) is provided that takes you to a page with details for that billing line item.
[cur.vantage.sh](https://cur.vantage.sh/) is a free utility that gives cloud practitioners simple definitions of billing codes for every AWS service. The site has a distinct page for each AWS service (e.g., S3 or EC2) that clusters together similar billing codes for that service, as there may be separate or distinct billing codes for each individual region.

### Resource Relationships
You can view relationships between specific resources on the **Relationships** tab.

Below are some examples of relationships you may see within your active resources.
| Resource | Relationship |
| - | - |
| Amazon EBS Volumes | See associated EC2 instances, with accrued cost, account, instance ID, region, instance type, launch time, and lifecycle |
| Amazon EC2 Instances | See associated EBS volumes and IP addresses, with accrued cost, account, volume type, size, IOPs, and state |
| Amazon IP Addresses | See associated EC2 instances, with accrued cost, account, instance ID, region, instance type, launch time, and lifecycle |
| Amazon RDS Snapshots | See associated RDS instances, with accrued cost, account, database identifier, engine, engine version, instance type, status, and allocated storage |
| Azure Disks | See associated Azure Virtual Machines with accrued cost, account, resource ID, admin username, virtual machine size, boot diagnostics enabled, secure boot enabled, date/time created |
| Azure Virtual Machines | See associated disk resources with accrued cost, account, resource ID, disk size, OS type, disk IOPs read/write, disk state, encryption type, network access policy, provisioning state, public network access, zones, and date/time created |
| GCP Compute Disks | See associated Compute Instances, with accrued cost, account, instance name, machine type, creation timestamp, CPU platform, and resource URL |
| GCP Compute Instances | See associated Compute Disks, with accrued cost, account, disk name, disk type, size, architecture, creation timestamp, and resource URL |
The **Relationships** tab only appears when related resources are found. If a resource has no associated relationships, the tab will not be displayed.
### S3 Storage Summary
For S3 buckets, a **Storage Summary** tab is available that provides a list of storage classes, their corresponding storage sizes, and approximate monthly costs for objects in the S3 bucket.

When available, this screen also includes **S3 Intelligent Tiering Considerations** with a table of possible maximum savings you can potentially yield as a result of implementing S3 Intelligent Tiering across all objects in the bucket with Standard Storage.
### S3 Request Metrics and Egress
To view S3 request metrics and egress data, you must configure request metrics on the S3 bucket. It takes roughly 15 minutes for AWS to begin delivering these metrics after they are enabled. See the [AWS documentation](https://docs.aws.amazon.com/AmazonS3/latest/userguide/metrics-configurations.html) for more information about ingress and egress request metrics.
The required `s3:GetMetricsConfiguration` permission is included automatically via the `VantageS3RequestMetrics` policy in the default CloudFormation template and StackSet.
AWS charges you on a per-request basis for S3 with potentially different rates for each request type. The **Request Metrics & Egress** tab provides a summary of request metrics for the bucket and each metric's cost for the trailing 30 days.

A graph of each request type (`GET`, `PUT`, `HEAD`, `POST`, `SELECT`, and `LIST`) is provided, which visualizes the total number of requests. The total cost for each request type is also provided.
### EC2 Rightsizing Recommendations
For EC2 instances where Vantage identifies rightsizing opportunities, the **Rightsizing** tab is displayed with recommendations. See the [Cost Recommendations](/cost_recommendations) documentation for details.
### CloudWatch Metrics
For certain resources, you can view high-fidelity charts for CloudWatch metrics. On resources that support CloudWatch metrics, the **CloudWatch Metrics** tab is displayed. These metrics are useful for rightsizing servers and databases based on utilization.

When you connect an AWS account to Vantage, CloudWatch metrics are configured automatically, per resource. The following table lists the supported services and the specific metrics displayed for each.
| Service | Metrics |
| - | - |
| EC2 | CPU Utilization, Network In, Network Out, Memory Utilization\* |
| EBS | Read Bytes, Write Bytes, Queue Length |
| RDS | CPU Utilization, Database Connections, Free Storage Space, Write IOPS, Read IOPS |
| S3 | Bucket Size Bytes, Number of Objects |
| ECS/Fargate | CPU Utilization, Memory Utilization |
*\*EC2 Memory Utilization requires the [CloudWatch Agent](https://docs.aws.amazon.com/AmazonCloudWatch/latest/monitoring/Install-CloudWatch-Agent.html) to be installed on the instance. If CloudWatch Agent data is not available, a prompt is displayed with a link to the AWS installation documentation.*
### VPC Flow Logs
For active resources that generate network traffic costs, such as NAT Gateways and EC2 instances, the **VPC Flow Logs** tab is displayed. Select this tab to view peer resources and the associated traffic category (e.g., public). A Sankey diagram of each associated network flow is provided. See the [Network Flow Reports](/network_flow_reports) documentation for details on network flow reporting.

### Extended Support Recommendations
Vantage surfaces metadata and recommendations for AWS services that enter Extended Support to help teams understand upcoming end-of-support milestones and plan upgrades. This information is currently available for EKS, ElastiCache, OpenSearch/Elasticsearch, and RDS.
When you view EKS, ElastiCache, OpenSearch, or RDS Resource Reports, additional metadata fields for Support Type (Standard or Extended), Standard Support End Date, and Extended Support End Date are available.
From any Resource Report, add a new filter:
* Standard Support End Date: `from AWS where Metadata Standard Support End Date is `
* Support Status: `from AWS where Metadata Support Status is `

A report is displayed and shows resources that match the filter.
#### EKS Extended Support
For more information on [Amazon EKS Extended Support](https://www.vantage.sh/blog/amazon-eks-extended-support-cost-kubernetes), see the Vantage blog.
Select a cluster from the Resource Report list, then select the **Extended Support** tab. On this tab, Vantage provides a list of versions with their standard and extended support dates, displayed in descending order (newest first), as well as the current version of the cluster. Recommendations for the version to upgrade to are also provided. Vantage only recommends versions that have at least 90 days of standard support remaining, ensuring you won't be recommended a version that's about to enter extended support.

Click **Upgrade** to go to the AWS Management Console and perform the upgrade.
#### ElastiCache Extended Support
For more information on [Amazon ElastiCache Extended Support](https://www.vantage.sh/blog/opensearch-elasticsearch-elasticache-extended-support), see the Vantage blog.
Vantage automatically identifies Amazon ElastiCache for Redis clusters that are in, or approaching, Extended Support. This includes Redis OSS versions with published AWS Extended Support timelines, beginning with Redis OSS v4 and v5. For each ElastiCache for Redis cluster monitored in Vantage, the following process is used to estimate projected Extended Support costs:
Look up the End of Standard Support date for the cluster's Redis engine version.
Check if the cluster is within three months of this date.
* If yes, proceed with cost estimation.
Retrieve the relevant Extended Support premium for the supported Redis OSS version.
Calculate the projected monthly cost using the Extended Support pricing model published by AWS.
Select a cluster from the Resource Report list, then select the **Extended Support** tab. On this tab, Vantage provides upgrade recommendations, including the version required to exit Extended Support. The primary recommendation is to move to ElastiCache for Valkey or to a newer Redis OSS version supported by AWS. Vantage determines the next version number that does not have an Extended Support date within the next three months; however, it is recommended you upgrade to the highest allowable version based on your application's dependencies.
Click **Upgrade** to go to the AWS Management Console and perform the upgrade.
#### OpenSearch/Elasticsearch Extended Support
For more information on [Amazon OpenSearch Extended Support](https://www.vantage.sh/blog/opensearch-elasticsearch-elasticache-extended-support), see the Vantage blog.
Vantage automatically identifies Amazon OpenSearch Service domains that are in, or approaching, Extended Support. This includes both legacy Elasticsearch versions and OpenSearch versions with published Standard Support and Extended Support timelines. For each OpenSearch Service domain monitored in Vantage, the following process is used to estimate projected Extended Support costs:
Look up the End of Standard Support date for the domain's engine version.
Check if the domain is within three months of this date.
* If yes, proceed with cost estimation.
Retrieve the regional Extended Support fee (per normalized instance hour) for the domain.
Calculate projected monthly cost using:
$$
\text{Monthly Cost} = \text{Normalized Instance Hours (data + master nodes)} \times \text{Hourly Rate} \times 730
$$
Where **730** represents the assumed average runtime hours in a month.
Select a domain from the Resource Report list, then select the **Extended Support** tab. On this tab, Vantage provides upgrade recommendations, including the version required to exit Extended Support. Vantage determines the next version that does not have an Extended Support date within the next three months; however, it is recommended you upgrade to the highest allowable version based on your application's dependencies.
Click **Upgrade** to go to the AWS Management Console and perform the upgrade.
#### RDS Extended Support
For more information on [Amazon RDS Extended Support](https://www.vantage.sh/blog/amazon-rds-extended-support), see the Vantage blog.
Vantage automatically identifies Amazon RDS instances that are in, or approaching, Extended Support for MySQL and PostgreSQL. For each Amazon RDS MySQL or PostgreSQL instance monitored in Vantage, the following process is used to estimate projected Extended Support costs:
Look up the End of Standard Support date for the instance.
Check if the instance is within three months of this date.
* If yes, proceed with cost estimation.
* If auto-upgrade is enabled for [MySQL](https://docs.aws.amazon.com/AmazonRDS/latest/UserGuide/USER_UpgradeDBInstance.MySQL.Minor.html) or [PostgreSQL](https://docs.aws.amazon.com/AmazonRDS/latest/UserGuide/USER_UpgradeDBInstance.PostgreSQL.Minor.html), the instance is excluded.
Retrieve the number of vCPUs for the instance.
Retrieve the AWS hourly Extended Support rate (per vCPU) for the region.
Calculate the projected monthly cost using:
$$
\text{Monthly Cost} = \text{vCPUs} \times \text{Hourly Rate (per vCPU)} \times 730
$$
Where **730** represents the assumed runtime hours in a 30-day month.
Select an instance from the Resource Report list, then select the **Extended Support** tab. On this tab, Vantage provides upgrade recommendations, including the version required to exit Extended Support. Vantage determines the next minor version number that does not have an Extended Support date within the next three months; however, it is recommended you upgrade to the highest allowable version based on your application's dependencies.
Click **Upgrade** to go to the AWS Management Console and perform the upgrade.

### GCP Compute Rightsizing Recommendations
For GCP Compute resources where Vantage identifies rightsizing opportunities, the **Rightsizing** tab is displayed with recommendations. See the [Cost Recommendations](/cost_recommendations) documentation for details.
### Kubernetes Rightsizing Recommendations
For Kubernetes workloads where Vantage identifies rightsizing opportunities, the **Rightsizing** tab is displayed with recommendations. See the [Cost Recommendations](/cost_recommendations#kubernetes-rightsizing-recommendations) documentation for details on how to view and use this information.
### Datadog Host Costs
For cloud resources that have the Datadog agent installed, Vantage can associate Datadog per-host fees along with the primary cloud resources from AWS, Azure, and Google Cloud that drive those costs.
To view these costs and agent information, you need to have a [Datadog](/connecting_datadog) integration, along with either an [AWS](/connecting_aws), [Azure](/connecting_azure), or [GCP](/connecting_gcp) integration.
On Active Resource views for resources like EC2 instances or Virtual Machines, the **Associated Datadog Costs** section is displayed and provides a service breakdown of costs.
The following resources are supported:
* Compute resources with the Datadog agent installed, such as virtual machines or container services
* Databases that are monitored by Datadog’s DBM
The following Datadog services are supported:
* Infrastructure Monitoring
* Database Monitoring
* APM (Hosts)
For eligible resources, the **Datadog Agent Installed** dimension indicates whether the agent is installed. The below image shows resource data for a particular EC2 instance. On the right information panel, the **Datadog Agent Installed** dimension displays **True**. Observe associated Datadog costs for **Infrastructure Monitoring** and **APM** in the table at the bottom.

You can also create a Resource Report that filters for resources where the Datadog agent is installed. In the below image, the filter looks for EC2 instances where the agent is installed.
Vantage automatically generates this type of report when it finds the Datadog Agent installed on relevant resources. Navigate to the [Resource Reports](https://console.vantage.sh/resources) screen. Auto-generated reports will have a name similar to *AWS EC2 Instances with the Datadog Agent Installed*.
Select the **Metadata** filter option.
For **Resource Type**, select an eligible resource, like **EC2 Instances** or **RDS Instances**.
For **Select a Key**, select **Datadog Agent Installed**.
For **Value**, select **true**.

### Datadog Custom Metrics
For Datadog accounts with custom metrics, Vantage can surface unused custom metrics that are no longer providing value. Vantage identifies custom metrics that are unused by checking if:
* The metric has not been queried in the past 30 days
* The metric is not referenced by any dashboards, monitors, notebooks, or SLOs
Each custom metric is displayed as an active resource with the following metadata:
* **Metric Name**: The name of the custom metric
* **Unit**: The unit of measurement for the metric
* **Per Unit**: The per-unit cost for the metric
* **Description**: Description of the metric
* **Short Name**: Short name for the metric
* **Statsd Interval**: The StatsD interval for the metric
* **Integration**: The integration that created the metric
* **Tags**: Tags associated with the metric
* **Indexed Volume**: The indexed volume for the metric
* **Has Related Assets**: Whether the metric is related to any dashboards, monitors, notebooks, or SLOs
* **Has Been Queried**: Whether the metric has been queried in the last 30 days
You can create Resource Reports to filter and analyze your Datadog custom metrics, helping you identify which metrics can be removed to reduce costs.
In addition, the **Metric Cleanup** tab is displayed. See the [Datadog unused custom metrics](/cost_recommendations#unused-custom-metrics) cost recommendation documentation for details.
# Annotations
Source: https://docs.vantage.sh/annotations
Add contextual notes to Cost Reports with Vantage Annotations.
Annotations add context to events or data points within [Cost Reports](/cost_reports). An annotation includes a date and a comment, and is useful for explaining infrastructure changes, deployment events, billing updates, or other context that helps teammates understand a cost change.
Annotations can be created manually from a report, or automatically when certain alert types fire:
| Annotation Type | How It Is Created | Where It Appears |
| - | - | - |
| Manual annotation | A user adds it from a report chart or the **Annotations** sidebar. | On the selected Cost Report. |
| Cost Alert annotation | A [Cost Alert](/cost_alerts) is triggered. | On the Cost Report associated with the alert event. |
| Budget Alert annotation | A [Budget Alert](/budgets#budget-alerts) is triggered. | On the Cost Report associated with the budget alert. |
## Add an Annotation
You can add annotations directly from the chart on a Cost Report, or from the **Annotations** sidebar.
From any report chart or graph, hover over the chart's bars or line and select the date point you want to annotate.
The **Annotations** sidebar is displayed on the right side of the screen. Your username is displayed as well as the date that corresponds with the selected date point on the chart. Enter a comment for the annotation.
To save the annotation, click the arrow icon on the bottom right of the comment box.

From the top right of any report, click the **Annotation** icon (looks like a word bubble).
The **Annotations** sidebar is displayed. Click **New**.
Select the appropriate date from the date picker, and enter a comment.
To save the annotation, click the arrow icon on the bottom right of the comment box.
When you manually create an annotation, [a corresponding issue](/annotations#view-corresponding-issues) is also created.
## View and Edit Annotations
To view an annotation, from the top right of any Cost Report, click the **Annotation** icon (looks like a word bubble).
The **Annotations** sidebar is displayed, with the most recently added annotation at the top of the list. A vertical line is also displayed on the report chart or graph for dates that have an existing annotation.
To edit the annotation, click the ellipses (...) on the top right of the annotation, then select **Edit**.
Select a new date from the date picker and/or edit the text in the comment field.
To save the annotation, click the arrow icon on the bottom right of the comment box.
Clicking an annotation marker (the vertical line) on the report chart scopes the **Annotations** sidebar to that day, making it easier to find the annotations tied to a specific point in time. Clear the day filter to return to the full list.
## Hide Annotations
From the top right of any Cost Report, click the **Annotation** icon (looks like a word bubble).
From the top right of the Annotations pane, click the **Annotations Settings** icon (looks like a gear).
You can toggle an annotation's visibility in the **Chart Display** section.

## Delete an Annotation
To delete an annotation, from the top right of any Cost Report, click the **Annotation** icon (looks like a word bubble).
The **Annotations** sidebar is displayed. Click the ellipses (...) on the top right of the annotation, then select **Remove** > **OK**.
Instead of deleting an annotation, consider resolving the annotation, as described below.
## Resolve an Annotation
To resolve an annotation, from the top right of any Cost Report, click the **Annotation** icon (looks like a word bubble).
The **Annotations** sidebar is displayed. Click the ellipses (...) on the top right of the annotation, then select **Mark as Resolved**.
To unresolve an annotation, repeat the previous steps, but instead, select the **Unresolve** option.
### View Resolved Annotations
By default, reports hide resolved annotations from the annotations list and chart or graph.
To view resolved annotations, click the **Annotation** icon at the top right of the screen.
From the **Annotations** sidebar, click the filter icon (next to the **New** button), then click **Show Resolved**. Resolved annotations are displayed in both views.
## Share an Annotation
To share an annotation with a teammate, from the top right of any Cost Report, click the **Annotation** icon.
The **Annotations** sidebar is displayed. Click the ellipses (...) on the top right of the annotation, then select **Copy Link**. A link is added to your clipboard, which you can use to share with a teammate.
## View Corresponding Issues
When you manually create an annotation, a corresponding [issue](/issues) is also automatically created. Budget Alert annotations also have a corresponding issue. Cost Alert annotations are linked to the Cost Alert instead, so their menu shows **Go to Cost Alert** rather than **Go to Issue**.
To open the corresponding issue, click the ellipses (...) on the top right of the annotation.
Then, select **Go to Issue**.

For manual annotations, the issue is automatically created with the **Annotation** category label attached and a link to the annotated report. The issue's title defaults to the report name and annotation's date. You can use the comment function in the issue to also comment on the annotation.
When an annotation is resolved, the corresponding issue will become a closed issue. Unresolving an annotation reopens the corresponding issue.
## Cost Alert Annotations
When a [Cost Alert](/cost_alerts) is triggered, an annotation is added to the corresponding Cost Report. This happens even if you do not configure external notification delivery through email, Slack, Microsoft Teams, or Jira.
Cost Alert annotations show details about the alert event, such as the alert title, the grouping that triggered the alert, the change amount, and the comparison interval. From the annotation menu, select **Go to Cost Alert** to view or edit the alert configuration. See [Cost Alerts](/cost_alerts) for details on how to set up Cost Alerts.
If Jira delivery is configured for the Cost Alert, the annotation also includes a link to the Jira issue. If Jira delivery is not configured, no Jira issue is created, but the Cost Alert annotation still appears on the report.
## Budget Alert Annotations
When a Budget Alert is triggered, an annotation is added to the corresponding Cost Report. See the [Budget Alerts](/budgets#budget-alerts) documentation for details on how to set up Budget Alerts.
## Troubleshooting
The annotation was created by a Cost Alert. Cost Alert annotations are connected to the alert event, so the menu links back to the Cost Alert configuration. If the alert was also delivered to Jira, the annotation includes a separate **Go to Jira Issue** option.
Cost Alerts can be configured without external delivery channels. When a Cost Alert triggers, Vantage still adds an annotation to the associated Cost Report so the event is visible during report review.
Alert-generated annotations use the date of the cost event that triggered the alert. Cloud providers can update billing data after the original usage date, so an alert may be detected later while the annotation appears on the date the cost change occurred.
# Vantage API
Source: https://docs.vantage.sh/api
Access Vantage's REST API to programmatically manage cloud cost data.
The Vantage API allows you to programmatically access your cost data and create cost resources, like Cost Reports, folders, and dashboards.
Use the API when you need repeatable automation, custom integrations, or raw cost data for your own systems. If you want a point-in-time CSV (optionally FOCUS-formatted) or PDF that matches the current view of a Cost Report, use the [Cost Report export flow](/cost_reports#export-cost-reports) in the Vantage console instead.
Browse all API endpoints alphabetically in the left navigation menu. Each endpoint page features a **"Try it"** button at the top that opens an interactive API playground. Enter your [Vantage API token](/api/authentication) to test API calls directly from your browser.
**Keep in mind that the playground makes real API calls to your Vantage account using your live Vantage data. Exercise caution when testing endpoints that create, modify, or delete Vantage resources.**
The interactive API playground lets you test endpoints directly from your browser. In the video below, the user opens the API playground and enters their access token. As they fill in parameters on the left, the information populates in the request on the right. Click **Send** to complete the API call.
After a call is sent, the response—either a successful response or any errors—is displayed on the top right, with your original call information displayed on the bottom.
***
## Resources
Get started with the Vantage API. Understand the API schema and how to call various endpoints.
Learn how to authenticate and access the Vantage API. Create an API access token with Read and Write scopes enabled.
Vantage Query Language (VQL) is a SQL-like language designed to filter cloud cost data. VQL provides a normalized schema across various cloud providers.
Consult the Data Dictionary to view the normalized field names used to create VQL statements. Each provider that Vantage integrates with makes different fields available in their billing data.
## Libraries
The `v2` API currently supports the following libraries. These libraries are officially maintained by Vantage and are auto-generated from the API specification. If you want to have your client added to the list, please email [support@vantage.sh](mailto:support@vantage.sh).
* [Go](https://github.com/vantage-sh/vantage-go)
* [Python](https://github.com/vantage-sh/vantage-python)
* [TypeScript](https://github.com/vantage-sh/vantage-ts)
## OpenAPI Specifications
The API provides both [OAS (Swagger) 2.0](https://swagger.io/specification/v2/) and [OpenAPI 3.0.1](https://swagger.io/specification/) specifications. You can use either specification to generate your own client libraries or to explore the API using tools like [Swagger UI](https://swagger.io/tools/swagger-ui/) or [Postman](https://www.postman.com/).
* The Swagger 2.0 specification is available at [https://api.vantage.sh/v2/swagger.json](https://api.vantage.sh/v2/swagger.json).
* The OpenAPI 3.0.1 specification is available at [https://api.vantage.sh/v2/oas\_v3.json](https://api.vantage.sh/v2/oas_v3.json).
# Create access grant
Source: https://docs.vantage.sh/api/accessgrants/create-access-grant
https://api.vantage.sh/v2/oas_v3.json post /access_grants
Create an Access Grant.
# Delete access grant
Source: https://docs.vantage.sh/api/accessgrants/delete-access-grant
https://api.vantage.sh/v2/oas_v3.json delete /access_grants/{access_grant_token}
Delete an Access Grant.
# Get access grant by token
Source: https://docs.vantage.sh/api/accessgrants/get-access-grant-by-token
https://api.vantage.sh/v2/oas_v3.json get /access_grants/{access_grant_token}
Return a specific Access Grant.
# Get all access grants
Source: https://docs.vantage.sh/api/accessgrants/get-all-access-grants
https://api.vantage.sh/v2/oas_v3.json get /access_grants
Return all Access Grants that the current API token has access to.
# Update access grant
Source: https://docs.vantage.sh/api/accessgrants/update-access-grant
https://api.vantage.sh/v2/oas_v3.json put /access_grants/{access_grant_token}
Update an AccessGrant.
# Create access policy
Source: https://docs.vantage.sh/api/accesspolicies/create-access-policy
https://api.vantage.sh/v2/oas_v3.json post /access_policies
Create an Access Policy.
# Delete access policy
Source: https://docs.vantage.sh/api/accesspolicies/delete-access-policy
https://api.vantage.sh/v2/oas_v3.json delete /access_policies/{access_policy_token}
Delete an Access Policy.
# Get all access policies
Source: https://docs.vantage.sh/api/accesspolicies/get-all-access-policies
https://api.vantage.sh/v2/oas_v3.json get /access_policies
Return all Access Policies for the current account.
# Update access policy
Source: https://docs.vantage.sh/api/accesspolicies/update-access-policy
https://api.vantage.sh/v2/oas_v3.json put /access_policies/{access_policy_token}
Update an Access Policy.
# Create an annotation
Source: https://docs.vantage.sh/api/annotations/create-an-annotation
https://api.vantage.sh/v2/oas_v3.json post /annotations
Create an Annotation.
# Delete an annotation
Source: https://docs.vantage.sh/api/annotations/delete-an-annotation
https://api.vantage.sh/v2/oas_v3.json delete /annotations/{annotation_token}
Delete an Annotation.
# Get all annotations
Source: https://docs.vantage.sh/api/annotations/get-all-annotations
https://api.vantage.sh/v2/oas_v3.json get /annotations
Return all Annotations.
# Update an annotation
Source: https://docs.vantage.sh/api/annotations/update-an-annotation
https://api.vantage.sh/v2/oas_v3.json put /annotations/{annotation_token}
Update an Annotation.
# Get all anomaly alerts
Source: https://docs.vantage.sh/api/anomalyalerts/get-all-anomaly-alerts
https://api.vantage.sh/v2/oas_v3.json get /anomaly_alerts
Return all Anomaly Alerts that the current API token has access to.
# Get anomaly alert by token
Source: https://docs.vantage.sh/api/anomalyalerts/get-anomaly-alert-by-token
https://api.vantage.sh/v2/oas_v3.json get /anomaly_alerts/{anomaly_alert_token}
Return an AnomalyAlert that the current API token has access to.
# Update anomaly alert
Source: https://docs.vantage.sh/api/anomalyalerts/update-anomaly-alert
https://api.vantage.sh/v2/oas_v3.json put /anomaly_alerts/{anomaly_alert_token}
Update an AnomalyAlert.
# Create anomaly notification
Source: https://docs.vantage.sh/api/anomalynotifications/create-anomaly-notification
https://api.vantage.sh/v2/oas_v3.json post /anomaly_notifications
Create an Anomaly Notification for a Cost Report.
# Delete anomaly notification
Source: https://docs.vantage.sh/api/anomalynotifications/delete-anomaly-notification
https://api.vantage.sh/v2/oas_v3.json delete /anomaly_notifications/{anomaly_notification_token}
Delete an Anomaly Notification.
# Get all anomaly notifications
Source: https://docs.vantage.sh/api/anomalynotifications/get-all-anomaly-notifications
https://api.vantage.sh/v2/oas_v3.json get /anomaly_notifications
Return all Anomaly Notifications.
# Get anomaly notification by token
Source: https://docs.vantage.sh/api/anomalynotifications/get-anomaly-notification-by-token
https://api.vantage.sh/v2/oas_v3.json get /anomaly_notifications/{anomaly_notification_token}
Return an Anomaly Notification that the current API token has access to.
# Update anomaly notification
Source: https://docs.vantage.sh/api/anomalynotifications/update-anomaly-notification
https://api.vantage.sh/v2/oas_v3.json put /anomaly_notifications/{anomaly_notification_token}
Update an Anomaly Notification.
# Get all audit logs
Source: https://docs.vantage.sh/api/auditlogs/get-all-audit-logs
https://api.vantage.sh/v2/oas_v3.json get /audit_logs
Return all AuditLogs.
# Get audit log by token
Source: https://docs.vantage.sh/api/auditlogs/get-audit-log-by-token
https://api.vantage.sh/v2/oas_v3.json get /audit_logs/{audit_log_token}
Return a specific AuditLog.
# Authentication
Source: https://docs.vantage.sh/api/authentication
Learn how to authenticate your requests using API keys.
The Vantage API authenticates all requests with an API access token. Tokens are required to ensure stability of the API and enforce rate limiting. If you do not include a token along with a request or pass an incorrect value, an error is returned within the API response.
Keep your token in a safe place; do not share it.
## Create a Vantage API Service Token
Service tokens are associated with an account, not with an individual user. These tokens ensure that any changes to specific users within your Vantage account will not disrupt automated workflows.
All Service Tokens created in non-Enterprise accounts are assigned to the Everyone team.
For Enterprise customers who use Teams and Role-Based Access Control, tokens can be attached to specific teams and will inherit the permissions from their associated team. Users with Organization Owner or Team Owner permissions can create API service tokens.
**Best Practice for Kubernetes and Terraform:** Service tokens used for the [Kubernetes agent](/kubernetes_agent) or [Terraform provider](/terraform) should be assigned to the **Everyone** team. This is required for organization-level actions such as managing provider integrations and creating teams. Service tokens assigned to other teams will not have the necessary permissions for these organization-level operations, which can result in authorization errors.
To generate an API service token, access the [Service Tokens tab](https://console.vantage.sh/settings/access_tokens) on the API Access Tokens page:
On the left navigation of the **Settings** screen, select **API Access Tokens**.
Enter a new token name, choose a team (Enterprise accounts), select the **Read** and/or **Write** scope, and click **Create**.
Click **Show** to reveal and copy your token.
To revoke a token, click **Delete**.
## Create a Vantage API Personal Access Token
Personal access tokens are associated with the user who created the token.
To generate an API personal access token, access the [Personal Access Tokens tab](https://console.vantage.sh/settings/access_tokens/personal) on the API Access Tokens page:
On the left navigation of the **Settings** screen, select **API Access Tokens**, then navigate to the **Personal Access Tokens** tab.
Enter a new token name, select the **Read** and/or **Write** scope, and click **Create**.
Click **Show** to reveal and copy your token.
To revoke a token, click **Delete**.
## Choose the Right Token
Use the following guidance when deciding which token type to use:
| Token type | Best for | Notes |
| - | - | - |
| **Service token** | Shared automation, background jobs, CI pipelines, and long-lived integrations | In Enterprise accounts, the token inherits the permissions of its assigned team. |
| **Personal access token** | Interactive testing, local scripts, and requests that should run with an individual user's access | The token's access follows the user who created it. |
In Enterprise accounts, a token can only access the workspaces and items available to its team. If an automation needs organization-level access, such as managing provider integrations, assign the service token to the **Everyone** team. See the [RBAC permissions reference](/rbac_permissions).
## Use Your Access Token in a Request
Pass your access token through the `Authorization` header of a request:
```bash theme={null}
curl --request GET \
--url https://api.vantage.sh/v2/cost_reports \
--header 'Accept: application/json' \
--header 'Authorization: Bearer '
```
# Create billing profile
Source: https://docs.vantage.sh/api/billingprofiles/create-billing-profile
https://api.vantage.sh/v2/oas_v3.json post /billing_profiles
Create a billing profile (MSP invoicing required).
# Delete billing profile
Source: https://docs.vantage.sh/api/billingprofiles/delete-billing-profile
https://api.vantage.sh/v2/oas_v3.json delete /billing_profiles/{billing_profile_token}
Requires MSP invoicing to be enabled on the account.
# Get all billing profiles
Source: https://docs.vantage.sh/api/billingprofiles/get-all-billing-profiles
https://api.vantage.sh/v2/oas_v3.json get /billing_profiles
Returns a list of billing profiles (MSP invoicing required).
# Get billing profile by token
Source: https://docs.vantage.sh/api/billingprofiles/get-billing-profile-by-token
https://api.vantage.sh/v2/oas_v3.json get /billing_profiles/{billing_profile_token}
Requires MSP invoicing to be enabled on the account.
# Update billing profile
Source: https://docs.vantage.sh/api/billingprofiles/update-billing-profile
https://api.vantage.sh/v2/oas_v3.json put /billing_profiles/{billing_profile_token}
Requires MSP invoicing to be enabled on the account.
# Create billing rule
Source: https://docs.vantage.sh/api/billingrules/create-billing-rule
https://api.vantage.sh/v2/oas_v3.json post /billing_rules
Create a BillingRule.
# Delete billing rule
Source: https://docs.vantage.sh/api/billingrules/delete-billing-rule
https://api.vantage.sh/v2/oas_v3.json delete /billing_rules/{billing_rule_token}
Delete a BillingRule.
# Get all billing rules
Source: https://docs.vantage.sh/api/billingrules/get-all-billing-rules
https://api.vantage.sh/v2/oas_v3.json get /billing_rules
Returns a list of billing rules.
# Get billing rule by token
Source: https://docs.vantage.sh/api/billingrules/get-billing-rule-by-token
https://api.vantage.sh/v2/oas_v3.json get /billing_rules/{billing_rule_token}
Return a BillingRule.
# Update billing rule
Source: https://docs.vantage.sh/api/billingrules/update-billing-rule
https://api.vantage.sh/v2/oas_v3.json put /billing_rules/{billing_rule_token}
Update a BillingRule.
# Create budget alert
Source: https://docs.vantage.sh/api/budgetalerts/create-budget-alert
https://api.vantage.sh/v2/oas_v3.json post /budget_alerts
Create a Budget Alert.
# Delete budget alert
Source: https://docs.vantage.sh/api/budgetalerts/delete-budget-alert
https://api.vantage.sh/v2/oas_v3.json delete /budget_alerts/{budget_alert_token}
Delete a BudgetAlert.
# Get all budget alerts
Source: https://docs.vantage.sh/api/budgetalerts/get-all-budget-alerts
https://api.vantage.sh/v2/oas_v3.json get /budget_alerts
Return all BudgetAlerts.
# Get budget alert by token
Source: https://docs.vantage.sh/api/budgetalerts/get-budget-alert-by-token
https://api.vantage.sh/v2/oas_v3.json get /budget_alerts/{budget_alert_token}
Return a BudgetAlert.
# Update budget alert
Source: https://docs.vantage.sh/api/budgetalerts/update-budget-alert
https://api.vantage.sh/v2/oas_v3.json put /budget_alerts/{budget_alert_token}
Updates an existing BudgetAlert.
# Create budget
Source: https://docs.vantage.sh/api/budgets/create-budget
https://api.vantage.sh/v2/oas_v3.json post /budgets
Create a Budget.
# Delete budget
Source: https://docs.vantage.sh/api/budgets/delete-budget
https://api.vantage.sh/v2/oas_v3.json delete /budgets/{budget_token}
Delete a Budget.
# Get all budgets
Source: https://docs.vantage.sh/api/budgets/get-all-budgets
https://api.vantage.sh/v2/oas_v3.json get /budgets
Return all Budgets.
# Get budget by token
Source: https://docs.vantage.sh/api/budgets/get-budget-by-token
https://api.vantage.sh/v2/oas_v3.json get /budgets/{budget_token}
Return a Budget.
# Update budget
Source: https://docs.vantage.sh/api/budgets/update-budget
https://api.vantage.sh/v2/oas_v3.json put /budgets/{budget_token}
Update a Budget.
# Create business metric
Source: https://docs.vantage.sh/api/businessmetrics/create-business-metric
https://api.vantage.sh/v2/oas_v3.json post /business_metrics
Create a new BusinessMetric.
# Delete business metric
Source: https://docs.vantage.sh/api/businessmetrics/delete-business-metric
https://api.vantage.sh/v2/oas_v3.json delete /business_metrics/{business_metric_token}
Deletes an existing BusinessMetric.
# Delete business metric values
Source: https://docs.vantage.sh/api/businessmetrics/delete-business-metric-values
https://api.vantage.sh/v2/oas_v3.json delete /business_metrics/{business_metric_token}/values
Deletes Business Metric values (historical or forecasted unit metrics). BusinessMetrics whose values are stored in ClickHouse only support deleting every historical value or every forecasted value, so supplying start_date, end_date, or label returns 422.
# Get all business metrics
Source: https://docs.vantage.sh/api/businessmetrics/get-all-business-metrics
https://api.vantage.sh/v2/oas_v3.json get /business_metrics
Return all BusinessMetrics that the current API token has access to.
# Get business metric by token
Source: https://docs.vantage.sh/api/businessmetrics/get-business-metric-by-token
https://api.vantage.sh/v2/oas_v3.json get /business_metrics/{business_metric_token}
Return a BusinessMetric.
# Get business metric forecasted values
Source: https://docs.vantage.sh/api/businessmetrics/get-business-metric-forecasted-values
https://api.vantage.sh/v2/oas_v3.json get /business_metrics/{business_metric_token}/forecasted_values
Return forecasted values of a BusinessMetric
# Get business metric labels
Source: https://docs.vantage.sh/api/businessmetrics/get-business-metric-labels
https://api.vantage.sh/v2/oas_v3.json get /business_metrics/{business_metric_token}/labels
Return labels of a BusinessMetric.
# Get business metric values
Source: https://docs.vantage.sh/api/businessmetrics/get-business-metric-values
https://api.vantage.sh/v2/oas_v3.json get /business_metrics/{business_metric_token}/values
Return values of a BusinessMetric
# Update business metric
Source: https://docs.vantage.sh/api/businessmetrics/update-business-metric
https://api.vantage.sh/v2/oas_v3.json put /business_metrics/{business_metric_token}
Updates an existing BusinessMetric.
# Update business metric values from CSV
Source: https://docs.vantage.sh/api/businessmetrics/update-business-metric-values-from-csv
https://api.vantage.sh/v2/oas_v3.json put /business_metrics/{business_metric_token}/values.csv
Updates the values for an existing BusinessMetric from a CSV file.
# Create canvas
Source: https://docs.vantage.sh/api/canvases/create-canvas
https://api.vantage.sh/v2/oas_v3.json post /canvases
Create a Canvas.
# Delete canvas
Source: https://docs.vantage.sh/api/canvases/delete-canvas
https://api.vantage.sh/v2/oas_v3.json delete /canvases/{canvas_token}
Delete a Canvas.
# Get all canvases
Source: https://docs.vantage.sh/api/canvases/get-all-canvases
https://api.vantage.sh/v2/oas_v3.json get /canvases
Return all Canvases.
# Get canvas by token
Source: https://docs.vantage.sh/api/canvases/get-canvas-by-token
https://api.vantage.sh/v2/oas_v3.json get /canvases/{canvas_token}
Return a specific Canvas.
# Update canvas
Source: https://docs.vantage.sh/api/canvases/update-canvas
https://api.vantage.sh/v2/oas_v3.json put /canvases/{canvas_token}
Update a Canvas.
# Get all cost alert events
Source: https://docs.vantage.sh/api/costalertevents/get-all-cost-alert-events
https://api.vantage.sh/v2/oas_v3.json get /cost_alerts/{cost_alert_token}/events
Get all CostAlertEvents
# Get cost alert event by token
Source: https://docs.vantage.sh/api/costalertevents/get-cost-alert-event-by-token
https://api.vantage.sh/v2/oas_v3.json get /cost_alerts/{cost_alert_token}/events/{event_token}
Get a CostAlertEvent
# Create cost alert
Source: https://docs.vantage.sh/api/costalerts/create-cost-alert
https://api.vantage.sh/v2/oas_v3.json post /cost_alerts
Create a new Cost Alert
# Delete cost alert
Source: https://docs.vantage.sh/api/costalerts/delete-cost-alert
https://api.vantage.sh/v2/oas_v3.json delete /cost_alerts/{cost_alert_token}
Delete a Cost Alert
# Get all cost alerts
Source: https://docs.vantage.sh/api/costalerts/get-all-cost-alerts
https://api.vantage.sh/v2/oas_v3.json get /cost_alerts
List all Cost Alerts
# Get cost alert by token
Source: https://docs.vantage.sh/api/costalerts/get-cost-alert-by-token
https://api.vantage.sh/v2/oas_v3.json get /cost_alerts/{cost_alert_token}
Get a Cost Alert
# Update cost alert
Source: https://docs.vantage.sh/api/costalerts/update-cost-alert
https://api.vantage.sh/v2/oas_v3.json put /cost_alerts/{cost_alert_token}
Update a Cost Alert
# Get cost providers
Source: https://docs.vantage.sh/api/costprovider/get-cost-providers
https://api.vantage.sh/v2/oas_v3.json get /cost_providers
List CostProviders available to query in a given Workspace.
# Get all cost provider accounts
Source: https://docs.vantage.sh/api/costprovideraccounts/get-all-cost-provider-accounts
https://api.vantage.sh/v2/oas_v3.json get /cost_provider_accounts
List CostProviderAccounts available in a given Workspace.
# Create cost report
Source: https://docs.vantage.sh/api/costs/create-cost-report
https://api.vantage.sh/v2/oas_v3.json post /cost_reports
Create a CostReport.
# Delete cost report
Source: https://docs.vantage.sh/api/costs/delete-cost-report
https://api.vantage.sh/v2/oas_v3.json delete /cost_reports/{cost_report_token}
Delete a CostReport.
# Generate cost data export
Source: https://docs.vantage.sh/api/costs/generate-cost-data-export
https://api.vantage.sh/v2/oas_v3.json post /costs/data_exports
Generate a DataExport of costs.
# Get all cost reports
Source: https://docs.vantage.sh/api/costs/get-all-cost-reports
https://api.vantage.sh/v2/oas_v3.json get /cost_reports
Return all CostReports.
# Get cost report by token
Source: https://docs.vantage.sh/api/costs/get-cost-report-by-token
https://api.vantage.sh/v2/oas_v3.json get /cost_reports/{cost_report_token}
Return a CostReport.
# Get costs for cost report or VQL filter
Source: https://docs.vantage.sh/api/costs/get-costs-for-cost-report-or-vql-filter
https://api.vantage.sh/v2/oas_v3.json get /costs
Return all Costs for a CostReport or VQL filter.
# Get forecasted costs for a cost report
Source: https://docs.vantage.sh/api/costs/get-forecasted-costs-for-a-cost-report
https://api.vantage.sh/v2/oas_v3.json get /cost_reports/{cost_report_token}/forecasted_costs
Return all ForecastedCosts.
# Update cost report
Source: https://docs.vantage.sh/api/costs/update-cost-report
https://api.vantage.sh/v2/oas_v3.json put /cost_reports/{cost_report_token}
Update a CostReport.
# Get cost services
Source: https://docs.vantage.sh/api/costservice/get-cost-services
https://api.vantage.sh/v2/oas_v3.json get /cost_services
List CostServices available to query in a given Workspace.
# Create dashboard notification
Source: https://docs.vantage.sh/api/dashboardnotifications/create-dashboard-notification
https://api.vantage.sh/v2/oas_v3.json post /dashboard_notifications
Create a DashboardNotification.
# Delete dashboard notification
Source: https://docs.vantage.sh/api/dashboardnotifications/delete-dashboard-notification
https://api.vantage.sh/v2/oas_v3.json delete /dashboard_notifications/{dashboard_notification_token}
Delete a DashboardNotification.
# Get all dashboard notifications
Source: https://docs.vantage.sh/api/dashboardnotifications/get-all-dashboard-notifications
https://api.vantage.sh/v2/oas_v3.json get /dashboard_notifications
Return all DashboardNotifications.
# Get dashboard notification by token
Source: https://docs.vantage.sh/api/dashboardnotifications/get-dashboard-notification-by-token
https://api.vantage.sh/v2/oas_v3.json get /dashboard_notifications/{dashboard_notification_token}
Return a DashboardNotification.
# Update dashboard notification
Source: https://docs.vantage.sh/api/dashboardnotifications/update-dashboard-notification
https://api.vantage.sh/v2/oas_v3.json put /dashboard_notifications/{dashboard_notification_token}
Update a DashboardNotification.
# Create dashboard
Source: https://docs.vantage.sh/api/dashboards/create-dashboard
https://api.vantage.sh/v2/oas_v3.json post /dashboards
Create a Dashboard.
# Delete dashboard
Source: https://docs.vantage.sh/api/dashboards/delete-dashboard
https://api.vantage.sh/v2/oas_v3.json delete /dashboards/{dashboard_token}
Delete a Dashboard.
# Delete dashboard widget
Source: https://docs.vantage.sh/api/dashboards/delete-dashboard-widget
https://api.vantage.sh/v2/oas_v3.json delete /widgets/{widget_token}
Delete a Dashboard Widget.
# Get all dashboards
Source: https://docs.vantage.sh/api/dashboards/get-all-dashboards
https://api.vantage.sh/v2/oas_v3.json get /dashboards
Return all Dashboards.
# Get dashboard by token
Source: https://docs.vantage.sh/api/dashboards/get-dashboard-by-token
https://api.vantage.sh/v2/oas_v3.json get /dashboards/{dashboard_token}
Return a specific Dashboard.
# Get dashboard widget
Source: https://docs.vantage.sh/api/dashboards/get-dashboard-widget
https://api.vantage.sh/v2/oas_v3.json get /widgets/{widget_token}
Return a Dashboard Widget.
# Update dashboard
Source: https://docs.vantage.sh/api/dashboards/update-dashboard
https://api.vantage.sh/v2/oas_v3.json put /dashboards/{dashboard_token}
Update a Dashboard.
# Update dashboard widget
Source: https://docs.vantage.sh/api/dashboards/update-dashboard-widget
https://api.vantage.sh/v2/oas_v3.json patch /widgets/{widget_token}
Update a single Dashboard Widget.
# Get status of data export
Source: https://docs.vantage.sh/api/dataexports/get-status-of-data-export
https://api.vantage.sh/v2/oas_v3.json get /data_exports/{data_export_token}
Get the status of a data export.
# Get all enrichment sources
Source: https://docs.vantage.sh/api/enrichmentsources/get-all-enrichment-sources
https://api.vantage.sh/v2/oas_v3.json get /enrichment_sources
Return all EnrichmentSources.
# Get enrichment source by token
Source: https://docs.vantage.sh/api/enrichmentsources/get-enrichment-source-by-token
https://api.vantage.sh/v2/oas_v3.json get /enrichment_sources/{enrichment_source_token}
Return an EnrichmentSource.
# Get enrichment statistics
Source: https://docs.vantage.sh/api/enrichmentstatistics/get-enrichment-statistics
https://api.vantage.sh/v2/oas_v3.json get /enrichment_sources/{enrichment_source_token}/statistics
Return enrichment statistics.
# Errors
Source: https://docs.vantage.sh/api/errors
Understand potential errors and how to correct them when using the Vantage API.
All error responses follow a standard format and are nested under an errors key in the response. The value will be an array of error messages.
```curl theme={null}
{
"errors": [
"You are not authorized to view this resource."
]
}
```
| Status Code | Message | Reason |
| - | - | - |
| `401` | Unauthorized or Invalid Token | The token is missing, malformed, expired, or otherwise invalid. |
| `403` | Forbidden | The token is valid, but it does not have permission to perform that action or access that workspace or resource. |
| `404` | Not Found | The requested resource could not be found. This could be due to a mistyped URL or a resource that has been deleted. |
| `429` | Too Many Requests | The user has sent too many requests in a given amount of time. See the [Rate Limiting](/api/rate_limiting) section for details. |
| `500` | Internal Server Error | An unexpected condition was encountered. This is a generic error message for server-side issues. |
| `422` | Unprocessable Entity | The request was well-formed but could not be processed because of validation or other semantic errors in the request data. |
## Common Authentication and Permission Failures
* If you receive a `401`, verify that your `Authorization: Bearer ...` header is present and that the token value is correct.
* If you receive a `403`, verify that the token has the necessary scope and that it can access the relevant workspace or resource.
* If you are using an Enterprise team-scoped service token, make sure the token's team has access to the workspace you are trying to query or modify.
# Get all exchange rates
Source: https://docs.vantage.sh/api/exchangerates/get-all-exchange-rates
https://api.vantage.sh/v2/oas_v3.json get /exchange_rates
Return all Exchange Rates.
# Upload exchange rates via CSV
Source: https://docs.vantage.sh/api/exchangerates/upload-exchange-rates-via-csv
https://api.vantage.sh/v2/oas_v3.json post /exchange_rates/csv
Upload Exchange Rates via CSV.
# Create financial commitment report
Source: https://docs.vantage.sh/api/financialcommitmentreports/create-financial-commitment-report
https://api.vantage.sh/v2/oas_v3.json post /financial_commitment_reports
Create a FinancialCommitmentReport.
# Delete financial commitment report
Source: https://docs.vantage.sh/api/financialcommitmentreports/delete-financial-commitment-report
https://api.vantage.sh/v2/oas_v3.json delete /financial_commitment_reports/{financial_commitment_report_token}
Delete a FinancialCommitmentReport.
# Get all financial commitment reports
Source: https://docs.vantage.sh/api/financialcommitmentreports/get-all-financial-commitment-reports
https://api.vantage.sh/v2/oas_v3.json get /financial_commitment_reports
Return all FinancialCommitmentReports.
# Get costs for financial commitment report
Source: https://docs.vantage.sh/api/financialcommitmentreports/get-costs-for-financial-commitment-report
https://api.vantage.sh/v2/oas_v3.json get /financial_commitment_reports/{financial_commitment_report_token}/costs
Return costs for a FinancialCommitmentReport.
# Get financial commitment report by token
Source: https://docs.vantage.sh/api/financialcommitmentreports/get-financial-commitment-report-by-token
https://api.vantage.sh/v2/oas_v3.json get /financial_commitment_reports/{financial_commitment_report_token}
Return a FinancialCommitmentReport.
# Update financial commitment report
Source: https://docs.vantage.sh/api/financialcommitmentreports/update-financial-commitment-report
https://api.vantage.sh/v2/oas_v3.json put /financial_commitment_reports/{financial_commitment_report_token}
Update a FinancialCommitmentReport.
# Get all financial commitments
Source: https://docs.vantage.sh/api/financialcommitments/get-all-financial-commitments
https://api.vantage.sh/v2/oas_v3.json get /financial_commitments
Return all FinancialCommitments.
# Create folder
Source: https://docs.vantage.sh/api/folders/create-folder
https://api.vantage.sh/v2/oas_v3.json post /folders
Create a Folder for CostReports.
# Delete folder
Source: https://docs.vantage.sh/api/folders/delete-folder
https://api.vantage.sh/v2/oas_v3.json delete /folders/{folder_token}
Delete a Folder for CostReports.
# Get all folders
Source: https://docs.vantage.sh/api/folders/get-all-folders
https://api.vantage.sh/v2/oas_v3.json get /folders
Return all Folders for CostReports.
# Get folder by token
Source: https://docs.vantage.sh/api/folders/get-folder-by-token
https://api.vantage.sh/v2/oas_v3.json get /folders/{folder_token}
Return a specific Folder for CostReports.
# Update folder
Source: https://docs.vantage.sh/api/folders/update-folder
https://api.vantage.sh/v2/oas_v3.json put /folders/{folder_token}
Update a Folder for CostReports.
# Get OpenAPI specification
Source: https://docs.vantage.sh/api/getopenapispecifications
Retrieve the OpenAPI 3.0.1 specification for Vantage's API.
This endpoint returns a compliant OpenAPI 3.0.1 specification document for the Vantage API. You can use this specification to:
* Generate client libraries for your preferred programming language
* Explore the API using tools like [Swagger UI](https://swagger.io/tools/swagger-ui/) or [Postman](https://www.postman.com/)
* Understand the complete API schema, including all endpoints, request/response models, and authentication requirements
The OpenAPI specification is always up-to-date and reflects the current state of the Vantage API.
The "Try it" feature is not available for this endpoint. Please use the code examples below or make requests directly to the endpoint URL.
```bash cURL theme={null}
curl --request GET \
--url https://api.vantage.sh/v2/oas_v3.json \
--header 'authorization: Bearer TOKEN'
```
```python Python theme={null}
import requests
url = "https://api.vantage.sh/v2/oas_v3.json"
headers = {
"authorization": "Bearer TOKEN"
}
response = requests.get(url, headers=headers)
print(response.json())
```
```javascript JavaScript theme={null}
const response = await fetch('https://api.vantage.sh/v2/oas_v3.json', {
method: 'GET',
headers: {
'authorization': 'Bearer TOKEN'
}
});
const data = await response.json();
console.log(data);
```
## Authentication
This endpoint requires authentication via a Bearer token in the Authorization header. See [Authentication](/api/authentication) for details on creating an API access token.
## Request Parameters
This endpoint does not accept any query parameters or path parameters.
## Response
The response is a JSON object containing the full OpenAPI specification, including:
* API metadata (title, description, version, contact information)
* Server information
* Authentication schemes
* All available endpoints with their methods, paths, parameters, and request/response schemas
* Data models and schema definitions
```json theme={null}
{
"openapi": "3.0.1",
"info": {
"title": "Vantage",
"description": "Vantage API",
"termsOfService": "https://www.vantage.sh/terms-of-use",
"contact": {
"name": "Vantage Support",
"url": "https://www.vantage.sh",
"email": "support@vantage.sh"
}
},
...
}
```
The full specification document is extensive and includes detailed information about all endpoints, request/response models, and authentication methods available in the Vantage API.
# Create Azure integration
Source: https://docs.vantage.sh/api/integrations/create-azure-integration
https://api.vantage.sh/v2/oas_v3.json post /integrations/azure
Create an Azure Integration
# Create custom provider integration
Source: https://docs.vantage.sh/api/integrations/create-custom-provider-integration
https://api.vantage.sh/v2/oas_v3.json post /integrations/custom_provider
Create a Custom Provider Integration
# Create GCP integration
Source: https://docs.vantage.sh/api/integrations/create-gcp-integration
https://api.vantage.sh/v2/oas_v3.json post /integrations/gcp
Create a GCP Integration
# Create Twilio integration
Source: https://docs.vantage.sh/api/integrations/create-twilio-integration
https://api.vantage.sh/v2/oas_v3.json post /integrations/twilio
Create a Twilio Integration
# Delete integration
Source: https://docs.vantage.sh/api/integrations/delete-integration
https://api.vantage.sh/v2/oas_v3.json delete /integrations/{integration_token}
Delete an Integration.
# Delete user costs upload
Source: https://docs.vantage.sh/api/integrations/delete-user-costs-upload
https://api.vantage.sh/v2/oas_v3.json delete /integrations/{integration_token}/costs/{user_costs_upload_token}
Delete a UserCostsUpload.
# Get all integrations
Source: https://docs.vantage.sh/api/integrations/get-all-integrations
https://api.vantage.sh/v2/oas_v3.json get /integrations
Return all Integrations.
# Get all user costs uploads
Source: https://docs.vantage.sh/api/integrations/get-all-user-costs-uploads
https://api.vantage.sh/v2/oas_v3.json get /integrations/{integration_token}/costs
List UserCostUploads.
# Get integration by token
Source: https://docs.vantage.sh/api/integrations/get-integration-by-token
https://api.vantage.sh/v2/oas_v3.json get /integrations/{integration_token}
Return an Integration.
# Update integration
Source: https://docs.vantage.sh/api/integrations/update-integration
https://api.vantage.sh/v2/oas_v3.json put /integrations/{integration_token}
Update an Integration.
# Upload custom provider costs
Source: https://docs.vantage.sh/api/integrations/upload-custom-provider-costs
https://api.vantage.sh/v2/oas_v3.json post /integrations/{integration_token}/costs.csv
Create UserCostsUpload via CSV for a Custom Provider Integration.
# Create invoice
Source: https://docs.vantage.sh/api/invoices/create-invoice
https://api.vantage.sh/v2/oas_v3.json post /invoices
Create an invoice (MSP accounts only).
# Get all invoices
Source: https://docs.vantage.sh/api/invoices/get-all-invoices
https://api.vantage.sh/v2/oas_v3.json get /invoices
Returns a list of invoices (MSP invoicing required).
# Get cost report URL
Source: https://docs.vantage.sh/api/invoices/get-cost-report-url
https://api.vantage.sh/v2/oas_v3.json get /invoices/{invoice_token}/cost_report
Get cost report URL for invoice period.
# Get invoice by token
Source: https://docs.vantage.sh/api/invoices/get-invoice-by-token
https://api.vantage.sh/v2/oas_v3.json get /invoices/{invoice_token}
Return an invoice.
# Get invoice file
Source: https://docs.vantage.sh/api/invoices/get-invoice-file
https://api.vantage.sh/v2/oas_v3.json post /invoices/{invoice_token}/download
Download invoice file (PDF or CSV).
# Regenerate invoice
Source: https://docs.vantage.sh/api/invoices/regenerate-invoice
https://api.vantage.sh/v2/oas_v3.json post /invoices/{invoice_token}/regenerate
Regenerate an existing invoice (MSP accounts only).
# Send and approve invoice
Source: https://docs.vantage.sh/api/invoices/send-and-approve-invoice
https://api.vantage.sh/v2/oas_v3.json post /invoices/{invoice_token}/send_and_approve
Send and approve invoice via email (MSP accounts only).
# Send invoice
Source: https://docs.vantage.sh/api/invoices/send-invoice
https://api.vantage.sh/v2/oas_v3.json post /invoices/{invoice_token}/send
Send invoice via email.
# Create Kubernetes efficiency report
Source: https://docs.vantage.sh/api/kubernetesefficiencyreports/create-kubernetes-efficiency-report
https://api.vantage.sh/v2/oas_v3.json post /kubernetes_efficiency_reports
Create a KubernetesEfficiencyReport.
# Delete Kubernetes efficiency report
Source: https://docs.vantage.sh/api/kubernetesefficiencyreports/delete-kubernetes-efficiency-report
https://api.vantage.sh/v2/oas_v3.json delete /kubernetes_efficiency_reports/{kubernetes_efficiency_report_token}
Delete a KubernetesEfficiencyReport.
# Generate Kubernetes efficiency data export
Source: https://docs.vantage.sh/api/kubernetesefficiencyreports/generate-kubernetes-efficiency-data-export
https://api.vantage.sh/v2/oas_v3.json post /kubernetes_efficiency_reports/data_exports
Generate a DataExport of Kubernetes efficiency data.
# Get all Kubernetes efficiency reports
Source: https://docs.vantage.sh/api/kubernetesefficiencyreports/get-all-kubernetes-efficiency-reports
https://api.vantage.sh/v2/oas_v3.json get /kubernetes_efficiency_reports
Return all KubernetesEfficiencyReports.
# Get costs for Kubernetes efficiency report
Source: https://docs.vantage.sh/api/kubernetesefficiencyreports/get-costs-for-kubernetes-efficiency-report
https://api.vantage.sh/v2/oas_v3.json get /kubernetes_efficiency_reports/{kubernetes_efficiency_report_token}/costs
Return costs for a KubernetesEfficiencyReport.
# Get Kubernetes efficiency report by token
Source: https://docs.vantage.sh/api/kubernetesefficiencyreports/get-kubernetes-efficiency-report-by-token
https://api.vantage.sh/v2/oas_v3.json get /kubernetes_efficiency_reports/{kubernetes_efficiency_report_token}
Return a KubernetesEfficiencyReport.
# Update Kubernetes efficiency report
Source: https://docs.vantage.sh/api/kubernetesefficiencyreports/update-kubernetes-efficiency-report
https://api.vantage.sh/v2/oas_v3.json put /kubernetes_efficiency_reports/{kubernetes_efficiency_report_token}
Update a KubernetesEfficiencyReport.
# Configure SSO for managed account
Source: https://docs.vantage.sh/api/managedaccounts/configure-sso-for-managed-account
https://api.vantage.sh/v2/oas_v3.json post /managed_accounts/{managed_account_token}/sso_connection
Configure SSO for a Managed Account.
# Create managed account
Source: https://docs.vantage.sh/api/managedaccounts/create-managed-account
https://api.vantage.sh/v2/oas_v3.json post /managed_accounts
Create a Managed Account.
# Delete managed account
Source: https://docs.vantage.sh/api/managedaccounts/delete-managed-account
https://api.vantage.sh/v2/oas_v3.json delete /managed_accounts/{managed_account_token}
Delete a Managed Account.
# Delete SSO connection for managed account
Source: https://docs.vantage.sh/api/managedaccounts/delete-sso-connection-for-managed-account
https://api.vantage.sh/v2/oas_v3.json delete /managed_accounts/{managed_account_token}/sso_connection
Delete SSO connection for a Managed Account.
# Get all managed accounts
Source: https://docs.vantage.sh/api/managedaccounts/get-all-managed-accounts
https://api.vantage.sh/v2/oas_v3.json get /managed_accounts
Returns a list of managed accounts.
# Get managed account by token
Source: https://docs.vantage.sh/api/managedaccounts/get-managed-account-by-token
https://api.vantage.sh/v2/oas_v3.json get /managed_accounts/{managed_account_token}
Return a Managed Account.
# Get managed account integration
Source: https://docs.vantage.sh/api/managedaccounts/get-managed-account-integration
https://api.vantage.sh/v2/oas_v3.json get /managed_accounts/{managed_account_token}/integrations/{access_credential_token}
Returns the Integration delegated to this Managed Account from the Access Credential named in the path, along with the provider account identifiers it imports. Delegate an Access Credential to a Managed Account with access_credential_tokens before calling this.
# Update managed account
Source: https://docs.vantage.sh/api/managedaccounts/update-managed-account
https://api.vantage.sh/v2/oas_v3.json put /managed_accounts/{managed_account_token}
Update a Managed Account.
# Update managed account integration
Source: https://docs.vantage.sh/api/managedaccounts/update-managed-account-integration
https://api.vantage.sh/v2/oas_v3.json put /managed_accounts/{managed_account_token}/integrations/{access_credential_token}
Replaces the provider account identifiers a delegated Integration imports. An empty array applies no filter, so every provider account the Access Credential can see is imported. Identifiers are only accepted for providers that support scoping a delegation. Azure CSP uses subscription ids and GCP uses project ids. Stop delegating an Integration by removing its token from access_credential_tokens on the Managed Account.
# Update SSO configuration for managed account
Source: https://docs.vantage.sh/api/managedaccounts/update-sso-configuration-for-managed-account
https://api.vantage.sh/v2/oas_v3.json put /managed_accounts/{managed_account_token}/sso_connection
Update SSO configuration for a Managed Account.
# Get authenticated user info
Source: https://docs.vantage.sh/api/me/get-authenticated-user-info
https://api.vantage.sh/v2/oas_v3.json get /me
Get information about the authenticated BearerToken.
# Update authenticated user
Source: https://docs.vantage.sh/api/me/update-authenticated-user
https://api.vantage.sh/v2/oas_v3.json put /me
Update the authenticated User.
# Get network flow logs
Source: https://docs.vantage.sh/api/networkflowlogs/get-network-flow-logs
https://api.vantage.sh/v2/oas_v3.json get /network_flow_logs
Return aggregated Network Flow Logs for a saved report or ad hoc VQL query.
# Create network flow report
Source: https://docs.vantage.sh/api/networkflowreports/create-network-flow-report
https://api.vantage.sh/v2/oas_v3.json post /network_flow_reports
Create a NetworkFlowReport.
# Delete network flow report
Source: https://docs.vantage.sh/api/networkflowreports/delete-network-flow-report
https://api.vantage.sh/v2/oas_v3.json delete /network_flow_reports/{network_flow_report_token}
Delete a NetworkFlowReport.
# Get all network flow reports
Source: https://docs.vantage.sh/api/networkflowreports/get-all-network-flow-reports
https://api.vantage.sh/v2/oas_v3.json get /network_flow_reports
Return all NetworkFlowReports.
# Get network flow report by token
Source: https://docs.vantage.sh/api/networkflowreports/get-network-flow-report-by-token
https://api.vantage.sh/v2/oas_v3.json get /network_flow_reports/{network_flow_report_token}
Return a NetworkFlowReport.
# Update network flow report
Source: https://docs.vantage.sh/api/networkflowreports/update-network-flow-report
https://api.vantage.sh/v2/oas_v3.json put /network_flow_reports/{network_flow_report_token}
Update a NetworkFlowReport.
# Pagination
Source: https://docs.vantage.sh/api/pagination
Understand how to paginate through large sets of data.
When querying for lists of items, the responses will be paginated. The pagination will be represented in the `links` key of the response.
```json theme={null}
"links":{
"self": "https://api.vantage.sh/v2/folders?page=2",
"first": "https://api.vantage.sh/v2/folders?page=1",
"next": "https://api.vantage.sh/v2/folders?page=3",
"last": "https://api.vantage.sh/v2/folders?page=5",
"prev": "https://api.vantage.sh/v2/folders?page=1"
}
```
| Field | Description |
| - | - |
| `self` | The URL of the current page. |
| `first` | The URL of the first page of items. |
| `next` | The URL of the next page of items. |
| `last` | The URL of the last page of items. |
| `prev` | The URL of the previous page of items. |
The array of items will be available as a key that matches the name of the route. For instance, folders will have a top-level `folders` key.
```json theme={null}
{
"links": {},
"folders":[]
}
```
You can specify the page you want to access and the number of items per page by using the `page` and `limit` query parameters.
```bash theme={null}
curl --request GET \
--url https://api.vantage.sh/v2/folders?page=3&limit=10 \
--header 'Accept: application/json'
```
# Get ping
Source: https://docs.vantage.sh/api/ping/get-ping
https://api.vantage.sh/v2/oas_v3.json get /ping
This is a health check endpoint that can be used to determine Vantage API healthiness. It will return 200 if everything is running smoothly.
# Get all products
Source: https://docs.vantage.sh/api/prices/get-all-products
https://api.vantage.sh/v2/oas_v3.json get /products
Return available Products for a Service. For example, with a Provider of AWS and a Service of EC2, Products will be a list of all EC2 Instances. By default, this endpoint returns all Products across all Services and Providers but has optional query parameters for filtering listed below.
# Get price by ID
Source: https://docs.vantage.sh/api/prices/get-price-by-id
https://api.vantage.sh/v2/oas_v3.json get /products/{product_id}/prices/{id}
Returns a price
# Get prices for a product
Source: https://docs.vantage.sh/api/prices/get-prices-for-a-product
https://api.vantage.sh/v2/oas_v3.json get /products/{product_id}/prices
Return available Prices across all Regions for a Product.
# Get product by ID
Source: https://docs.vantage.sh/api/prices/get-product-by-id
https://api.vantage.sh/v2/oas_v3.json get /products/{id}
Return a product
# Quickstart
Source: https://docs.vantage.sh/api/quickstart
Get started with the Vantage API.
This quickstart guide will walk you through building a complete cost management workflow using the Vantage API. You'll learn to create folders, generate Cost Reports, and analyze spending data programmatically.
## Prerequisites
* A [Vantage account](https://console.vantage.sh/) with at least one provider integration
* A Vantage [API access token](/api/authentication) with Read and Write scopes enabled
All Vantage API `v2` requests use the following base URL:
```bash theme={null}
https://api.vantage.sh/v2
```
In this quickstart, we'll cover the following steps:
First, we'll retrieve all workspaces your API token has access to.
Set up a folder structure to organize your Cost Reports.
Create a VQL-powered Cost Report with specific filters.
Retrieve and analyze cost and usage data from your report.
This quickstart focuses on API-native resource creation and data retrieval. If you need a point-in-time CSV (including a CSV export in the FOCUS schema) or PDF that mirrors a Cost Report in the UI, use the [Cost Report export flow](/cost_reports#export-cost-reports) instead.
## Step 1: Discover Your Workspaces
Retrieve all workspaces your API token has access to. This endpoint returns workspace tokens and metadata that you'll use in subsequent API calls.
```bash theme={null}
curl --request GET \
--url https://api.vantage.sh/v2/workspaces \
--header 'accept: application/json' \
--header 'authorization: Bearer ACCESS_TOKEN'
```
The response includes pagination links and an array of workspace objects with tokens, names, and configuration details.
```json theme={null}
{
"links": {
"self": "https://api.vantage.sh/v2/workspaces",
"first": "https://api.vantage.sh/v2/workspaces?page=1",
"next": null,
"last": "https://api.vantage.sh/v2/workspaces?page=1",
"prev": null
},
"workspaces": [
{
"token": "wrkspc_123445abcde",
"name": "Management",
"created_at": "2023-10-01T01:00:56Z",
"enable_currency_conversion": false,
"currency": "USD",
"exchange_rate_date": "daily_rate"
},
{
"token": "wrkspc_5678fghijk",
"name": "Marketing",
"created_at": "2023-10-01T01:00:56Z",
"enable_currency_conversion": false,
"currency": "USD",
"exchange_rate_date": "daily_rate"
}
]
}
```
Save the workspace tokens from this response. You'll need them for creating folders and Cost Reports in the next steps.
If your account uses multiple workspaces or team-scoped service tokens, choose a workspace that your token can access and use that `workspace_token` consistently in your create requests.
## Step 2: Create an Organized Folder Structure
Create a folder to organize your Cost Reports. This helps maintain a clean structure for your cost management workflows.
```bash theme={null}
curl --request POST \
--url https://api.vantage.sh/v2/folders \
--header 'accept: application/json' \
--header 'authorization: Bearer ACCESS_TOKEN' \
--header 'content-type: application/json' \
--data '{
"title": "Team Reports",
"workspace_token": "wrkspc_123445abcde"
}'
```
Use the workspace token from Step 1. You can also specify a `parent_folder_token` to create nested folder structures.
The response includes the new folder's token, which you'll use when creating Cost Reports.
```json theme={null}
{
"token": "fldr_123456abcde123",
"title": "Team Reports",
"parent_folder_token": null,
"saved_filter_tokens": [],
"created_at": "2023-10-09T13:24:33Z",
"updated_at": "2023-10-09T13:24:33Z",
"workspace_token": "wrkspc_123445abcde"
}
```
Save the folder token (`fldr_123456abcde123`). You'll need it in the next step to create your Cost Report.
## Step 3: Create an Intelligent Cost Report
This step demonstrates the power of **Vantage Query Language (VQL)**, a flexible query system that lets you filter costs by provider, tags, services, and more. Learn more about [VQL syntax](/vql).
Create a VQL-powered Cost Report that automatically filters AWS production costs.
```bash theme={null}
curl --request POST \
--url https://api.vantage.sh/v2/cost_reports \
--header 'accept: application/json' \
--header 'authorization: Bearer ' \
--header 'content-type: application/json' \
--data '{
"settings": {
"include_credits": false,
"include_refunds": false,
"include_discounts": true,
"include_tax": true,
"amortize": true,
"unallocated": false,
"aggregate_by": "cost",
"show_previous_period": true
},
"chart_type": "line",
"date_bin": "cumulative",
"title": "AWS Production Costs",
"folder_token": "fldr_123456abcde123",
"filter": "costs.provider = 'aws' AND tags.name = 'environment' AND tags.value = 'production'"
}'
```
The VQL filter `costs.provider = 'aws' AND tags.name = 'environment' AND tags.value = 'production'` does the following:
* **`costs.provider = 'aws'`** - Only includes AWS costs
* **`tags.name = 'environment'`** - Filters for resources with an `environment` tag
* **`tags.value = 'production'`** - Only includes resources tagged as `production`
This creates a focused report showing only your production AWS spending.
The response includes the Cost Report token and all configuration details. This token is needed for retrieving cost data in the next step.
```json theme={null}
{
"token": "rprt_1234a5678b1ab234",
"title": "AWS Production Costs",
"folder_token": "fldr_123456abcde123",
"saved_filter_tokens": [],
"filter": "costs.provider = 'aws' AND tags.name = 'environment' AND tags.value = 'production'",
"groupings": "provider,service",
"settings": {
"include_credits": false,
"include_refunds": false,
"include_discounts": true,
"include_tax": true,
"amortize": true,
"unallocated": false,
"aggregate_by": "cost"
},
"created_at": "2023-10-09T15:51:48Z",
"workspace_token": "wrkspc_123445abcde",
"previous_period_start_date": null,
"previous_period_end_date": null,
"start_date": "2024-07-01",
"end_date": "2024-07-31",
"date_interval": "this_month",
"chart_type": "bar",
"date_bin": "day"
}
```
Save the report token (`rprt_1234a5678b1ab234`) - you'll use it to retrieve cost data in the next step.
## Step 4: Analyze Your Cost Data
Retrieve detailed cost data from your report with flexible filtering and grouping options. This demonstrates how to extract actionable insights from your cost data.
```bash theme={null}
curl --request GET \
--url 'https://api.vantage.sh/v2/costs?cost_report_token=rprt_1234a5678b1ab234&start_date=2023-12-01&end_date=2023-12-31&groupings=service&order=desc' \
--header 'accept: application/json' \
--header 'authorization: Bearer '
```
* **`cost_report_token`** - Uses the report token from Step 3
* **`start_date` & `end_date`** - ISO 8601 date range for filtering
* **`groupings=service`** - Groups costs by AWS service (EC2, RDS, etc.)
* **`order=desc`** - Sorts by date in descending order (newest first)
The response includes pagination links, total cost summary, and detailed cost breakdowns by service.
```json theme={null}
{
"links": {
"self": "https://api.vantage.sh/v2/costs?cost_report_token=rprt_1234a5678b1ab234&start_date=2023-12-01&end_date=2023-12-31&groupings=service&order=desc",
"first": "https://api.vantage.sh/v2/costs?cost_report_token=rprt_1234a5678b1ab234&start_date=2023-12-01&end_date=2023-12-31&groupings=service&order=desc&page=1",
"next": null,
"last": "https://api.vantage.sh/v2/costs?cost_report_token=rprt_1234a5678b1ab234&start_date=2023-12-01&end_date=2023-12-31&groupings=service&order=desc&page=1",
"prev": null
},
"total_cost": {
"amount": "1000.11",
"currency": "USD"
},
"costs": [
{
"accrued_at": "2023-12-31",
"amount": "300.05",
"currency": "USD",
"provider": "aws",
"account_id": "123456789012",
"service": "AmazonRDS"
},
{
"accrued_at": "2023-12-28",
"amount": "500.03",
"currency": "USD",
"provider": "aws",
"account_id": "123456789012",
"service": "AmazonVPC"
},
{
"accrued_at": "2023-12-24",
"amount": "200.03",
"currency": "USD",
"provider": "aws",
"account_id": "123456789012",
"service": "AmazonECS"
}
]
}
```
This data structure is perfect for building cost dashboards, automated alerts, and financial reporting tools.
## Bonus: Retrieve Usage Analytics
Beyond cost data, the Vantage API provides detailed usage analytics. This is perfect for understanding resource utilization patterns and optimizing your infrastructure.
Retrieve both cost and usage data by setting `aggregate_by=usage`. This provides comprehensive resource utilization insights.
```bash theme={null}
curl --request GET \
--url 'https://api.vantage.sh/v2/costs?cost_report_token=rprt_1234a5678b1ab234&order=desc&settings%5Binclude_credits%5D=false&settings%5Binclude_refunds%5D=false&settings%5Binclude_discounts%5D=true&settings%5Binclude_tax%5D=true&settings%5Bamortize%5D=true&settings%5Bunallocated%5D=false&settings%5Baggregate_by%5D=usage' \
--header 'accept: application/json' \
--header 'authorization: Bearer TOKEN'
```
The key parameter here is `settings[aggregate_by]=usage` which switches from cost aggregation to usage aggregation.
The response includes both cost and usage data, providing comprehensive insights into your resource utilization patterns.
```json theme={null}
{
"links": {
"self": "https://api.vantage.sh/v2/costs?cost_report_token=rprt_1234a5678b1ab234&start_date=2023-12-01&end_date=2023-12-31&groupings=service&order=desc",
"first": "https://api.vantage.sh/v2/costs?cost_report_token=rprt_1234a5678b1ab234&start_date=2023-12-01&end_date=2023-12-31&groupings=service&order=desc&page=1",
"next": null,
"last": "https://api.vantage.sh/v2/costs?cost_report_token=rprt_1234a5678b1ab234&start_date=2023-12-01&end_date=2023-12-31&groupings=service&order=desc&page=1",
"prev": null
},
"total_cost": {
"amount": "75455.01",
"currency": "USD"
},
"total_usage": [
{
"amount": "0.0",
"unit": ""
},
{
"amount": "147793.33",
"unit": "Hrs"
},
{
"amount": "8929.98",
"unit": "Hours"
}
],
"costs": [
{
"accrued_at": "2025-01-06",
"amount": "885.4577627912",
"currency": "USD",
"usage": {
"amount": "910.969248694",
"unit": "Hrs"
},
"provider": "aws",
"account_id": "123456789012",
"service": "AmazonEC2"
},
{
"accrued_at": "2025-01-06",
"amount": "19.4873999955",
"currency": "USD",
"usage": {
"amount": "142.9999999995",
"unit": "Hrs"
},
"provider": "aws",
"account_id": "123456789012",
"service": "AmazonEC2"
}
]
}
```
This usage data is perfect for building resource optimization tools and capacity planning dashboards.
You've successfully built a complete cost management workflow using the Vantage API:
* Discovered workspaces and retrieved access tokens
* Created organized folders for Cost Report management
* Generated intelligent Cost Reports using VQL filtering
* Analyzed cost data with flexible grouping and filtering
* Retrieved usage analytics for resource optimization
# Rate Limiting
Source: https://docs.vantage.sh/api/rate_limiting
Understand the rate limiting policies for the Vantage API to ensure optimal usage and avoid interruptions.
API calls are rate limited to prevent bursts of incoming traffic to help maximize stability. These limits are account-wide rather than per-user restrictions, meaning all API activity within your Vantage account contributes to these thresholds.
These limits include a general rate limit of 1,000 requests per hour across all API endpoints, and a more restrictive limit of 5 requests per 5 seconds, specifically for Cost Report endpoints. If a client is rate limited, the API will return a `429` status code. If you need higher rate limits, contact [support@vantage.sh](mailto:support@vantage.sh).
Three headers are returned with every API response that indicate how close the client is to being rate limited and when the limit will reset.
| Header | Description |
| - | - |
| `x-rate-limit-limit` | The total limit for the given period of time. |
| `x-rate-limit-remaining` | The number of requests remaining in the current rate limit window. |
| `x-rate-limit-reset` | The time at which the current rate limit window resets to the value in `x-rate-limit-limit`, provided in [Unix time](https://en.wikipedia.org/wiki/Unix_time). |
**Example:**
```bash theme={null}
x-rate-limit-limit: 1000
x-rate-limit-remaining: 995
x-rate-limit-reset: 1619380800
```
# Get all recommendations
Source: https://docs.vantage.sh/api/recommendations/get-all-recommendations
https://api.vantage.sh/v2/oas_v3.json get /recommendations
Return all Recommendations. Use the `type` query parameter with a fuzzy fragment to filter recommendation type case-insensitively (for example: aws, aws:ec2, aws:ec2:rightsizing).
# Get all resources for a recommendation
Source: https://docs.vantage.sh/api/recommendations/get-all-resources-for-a-recommendation
https://api.vantage.sh/v2/oas_v3.json get /recommendations/{recommendation_token}/resources
Return all Active Resources, including Recommendation Actions, referenced in this Recommendation.
# Get all resources for a recommendation type
Source: https://docs.vantage.sh/api/recommendations/get-all-resources-for-a-recommendation-type
https://api.vantage.sh/v2/oas_v3.json get /recommendations/by_type/{type}/resources
Return all Active Resources associated with recommendations of the specified type.
# Get recommendation by token
Source: https://docs.vantage.sh/api/recommendations/get-recommendation-by-token
https://api.vantage.sh/v2/oas_v3.json get /recommendations/{recommendation_token}
Return a Recommendation.
# Get specific resource for a recommendation
Source: https://docs.vantage.sh/api/recommendations/get-specific-resource-for-a-recommendation
https://api.vantage.sh/v2/oas_v3.json get /recommendations/{recommendation_token}/resources/{resource_token}
Return an Active Resource, including Recommendation Actions, referenced in this Recommendation.
# Create recommendation view
Source: https://docs.vantage.sh/api/recommendationviews/create-recommendation-view
https://api.vantage.sh/v2/oas_v3.json post /recommendation_views
Create a RecommendationView.
# Delete recommendation view
Source: https://docs.vantage.sh/api/recommendationviews/delete-recommendation-view
https://api.vantage.sh/v2/oas_v3.json delete /recommendation_views/{recommendation_view_token}
Delete a RecommendationView.
# Get all recommendation views
Source: https://docs.vantage.sh/api/recommendationviews/get-all-recommendation-views
https://api.vantage.sh/v2/oas_v3.json get /recommendation_views
Return all RecommendationViews.
# Get recommendation view by token
Source: https://docs.vantage.sh/api/recommendationviews/get-recommendation-view-by-token
https://api.vantage.sh/v2/oas_v3.json get /recommendation_views/{recommendation_view_token}
Return a specific RecommendationView.
# Update recommendation view
Source: https://docs.vantage.sh/api/recommendationviews/update-recommendation-view
https://api.vantage.sh/v2/oas_v3.json put /recommendation_views/{recommendation_view_token}
Update a RecommendationView.
# Create report forecast
Source: https://docs.vantage.sh/api/reportforecasts/create-report-forecast
https://api.vantage.sh/v2/oas_v3.json post /report_forecasts
Create a scenario-model ReportForecast.
# Delete report forecast
Source: https://docs.vantage.sh/api/reportforecasts/delete-report-forecast
https://api.vantage.sh/v2/oas_v3.json delete /report_forecasts/{report_forecast_token}
Delete a scenario-model ReportForecast.
# Get all report forecasts
Source: https://docs.vantage.sh/api/reportforecasts/get-all-report-forecasts
https://api.vantage.sh/v2/oas_v3.json get /report_forecasts
Return all scenario-model ReportForecasts for a CostReport.
# Get report forecast by token
Source: https://docs.vantage.sh/api/reportforecasts/get-report-forecast-by-token
https://api.vantage.sh/v2/oas_v3.json get /report_forecasts/{report_forecast_token}
Return a scenario-model ReportForecast.
# Update report forecast
Source: https://docs.vantage.sh/api/reportforecasts/update-report-forecast
https://api.vantage.sh/v2/oas_v3.json put /report_forecasts/{report_forecast_token}
Update a scenario-model ReportForecast.
# Create report notification
Source: https://docs.vantage.sh/api/reportnotifications/create-report-notification
https://api.vantage.sh/v2/oas_v3.json post /report_notifications
Create a ReportNotification.
# Delete report notification
Source: https://docs.vantage.sh/api/reportnotifications/delete-report-notification
https://api.vantage.sh/v2/oas_v3.json delete /report_notifications/{report_notification_token}
Delete a ReportNotification.
# Get all report notifications
Source: https://docs.vantage.sh/api/reportnotifications/get-all-report-notifications
https://api.vantage.sh/v2/oas_v3.json get /report_notifications
Return all ReportNotifications.
# Get report notification by token
Source: https://docs.vantage.sh/api/reportnotifications/get-report-notification-by-token
https://api.vantage.sh/v2/oas_v3.json get /report_notifications/{report_notification_token}
Return a ReportNotification.
# Update report notification
Source: https://docs.vantage.sh/api/reportnotifications/update-report-notification
https://api.vantage.sh/v2/oas_v3.json put /report_notifications/{report_notification_token}
Update a ReportNotification.
# Create resource report
Source: https://docs.vantage.sh/api/resourcereports/create-resource-report
https://api.vantage.sh/v2/oas_v3.json post /resource_reports
Create a ResourceReport.
# Delete resource report
Source: https://docs.vantage.sh/api/resourcereports/delete-resource-report
https://api.vantage.sh/v2/oas_v3.json delete /resource_reports/{resource_report_token}
Delete a ResourceReport.
# Get all resource reports
Source: https://docs.vantage.sh/api/resourcereports/get-all-resource-reports
https://api.vantage.sh/v2/oas_v3.json get /resource_reports
Return all ResourceReports.
# Get resource report by token
Source: https://docs.vantage.sh/api/resourcereports/get-resource-report-by-token
https://api.vantage.sh/v2/oas_v3.json get /resource_reports/{resource_report_token}
Return a ResourceReport.
# Get resource report columns
Source: https://docs.vantage.sh/api/resourcereports/get-resource-report-columns
https://api.vantage.sh/v2/oas_v3.json get /resource_reports/columns
List available columns for a resource type.
# Update resource report
Source: https://docs.vantage.sh/api/resourcereports/update-resource-report
https://api.vantage.sh/v2/oas_v3.json put /resource_reports/{resource_report_token}
Update a ResourceReport.
# Get resource by token
Source: https://docs.vantage.sh/api/resources/get-resource-by-token
https://api.vantage.sh/v2/oas_v3.json get /resources/{resource_token}
Return a single Resource
# Get resources
Source: https://docs.vantage.sh/api/resources/get-resources
https://api.vantage.sh/v2/oas_v3.json get /resources
Return Resources contained in a ResourceReport
# Create saved filter
Source: https://docs.vantage.sh/api/savedfilters/create-saved-filter
https://api.vantage.sh/v2/oas_v3.json post /saved_filters
Create a SavedFilter for CostReports.
# Delete saved filter
Source: https://docs.vantage.sh/api/savedfilters/delete-saved-filter
https://api.vantage.sh/v2/oas_v3.json delete /saved_filters/{saved_filter_token}
Delete a SavedFilter for CostReports.
# Get all saved filters
Source: https://docs.vantage.sh/api/savedfilters/get-all-saved-filters
https://api.vantage.sh/v2/oas_v3.json get /saved_filters
Return all SavedFilters that can be applied to a CostReport.
# Get saved filter by token
Source: https://docs.vantage.sh/api/savedfilters/get-saved-filter-by-token
https://api.vantage.sh/v2/oas_v3.json get /saved_filters/{saved_filter_token}
Return a specific SavedFilter.
# Update saved filter
Source: https://docs.vantage.sh/api/savedfilters/update-saved-filter
https://api.vantage.sh/v2/oas_v3.json put /saved_filters/{saved_filter_token}
Update a SavedFilter for CostReports.
# Create scenario model
Source: https://docs.vantage.sh/api/scenariomodels/create-scenario-model
https://api.vantage.sh/v2/oas_v3.json post /scenario_models
Create a ScenarioModel.
# Delete scenario model
Source: https://docs.vantage.sh/api/scenariomodels/delete-scenario-model
https://api.vantage.sh/v2/oas_v3.json delete /scenario_models/{scenario_model_token}
Delete a ScenarioModel.
# Get all scenario models
Source: https://docs.vantage.sh/api/scenariomodels/get-all-scenario-models
https://api.vantage.sh/v2/oas_v3.json get /scenario_models
Return all ScenarioModels.
# Get scenario model by token
Source: https://docs.vantage.sh/api/scenariomodels/get-scenario-model-by-token
https://api.vantage.sh/v2/oas_v3.json get /scenario_models/{scenario_model_token}
Return a ScenarioModel.
# Update scenario model
Source: https://docs.vantage.sh/api/scenariomodels/update-scenario-model
https://api.vantage.sh/v2/oas_v3.json put /scenario_models/{scenario_model_token}
Update a ScenarioModel.
# Create segment
Source: https://docs.vantage.sh/api/segments/create-segment
https://api.vantage.sh/v2/oas_v3.json post /segments
Create a Segment.
# Delete segment
Source: https://docs.vantage.sh/api/segments/delete-segment
https://api.vantage.sh/v2/oas_v3.json delete /segments/{segment_token}
Delete a Segment.
# Get all segments
Source: https://docs.vantage.sh/api/segments/get-all-segments
https://api.vantage.sh/v2/oas_v3.json get /segments
Return all Segments.
# Get segment by token
Source: https://docs.vantage.sh/api/segments/get-segment-by-token
https://api.vantage.sh/v2/oas_v3.json get /segments/{segment_token}
Return a Segment.
# Update segment
Source: https://docs.vantage.sh/api/segments/update-segment
https://api.vantage.sh/v2/oas_v3.json put /segments/{segment_token}
Update a Segment.
# Get all tags
Source: https://docs.vantage.sh/api/tags/get-all-tags
https://api.vantage.sh/v2/oas_v3.json get /tags
Return all Tags that the current API token has access to.
# Get tag values
Source: https://docs.vantage.sh/api/tags/get-tag-values
https://api.vantage.sh/v2/oas_v3.json get /tags/{key}/values
Returns corresponding TagValues for a given Tag.
# Update tag
Source: https://docs.vantage.sh/api/tags/update-tag
https://api.vantage.sh/v2/oas_v3.json put /tags
Updates an existing Tag.
# Add team member
Source: https://docs.vantage.sh/api/teams/add-team-member
https://api.vantage.sh/v2/oas_v3.json post /teams/{team_token}/members
Add a member to a Team.
# Create team
Source: https://docs.vantage.sh/api/teams/create-team
https://api.vantage.sh/v2/oas_v3.json post /teams
Create a new Team.
# Delete team
Source: https://docs.vantage.sh/api/teams/delete-team
https://api.vantage.sh/v2/oas_v3.json delete /teams/{team_token}
Delete a Team.
# Get all teams
Source: https://docs.vantage.sh/api/teams/get-all-teams
https://api.vantage.sh/v2/oas_v3.json get /teams
Return all Teams that the current API token has access to.
# Get team by token
Source: https://docs.vantage.sh/api/teams/get-team-by-token
https://api.vantage.sh/v2/oas_v3.json get /teams/{team_token}
Return a specific Team.
# Get team members
Source: https://docs.vantage.sh/api/teams/get-team-members
https://api.vantage.sh/v2/oas_v3.json get /teams/{team_token}/members
Return all members of a Team.
# Remove team member
Source: https://docs.vantage.sh/api/teams/remove-team-member
https://api.vantage.sh/v2/oas_v3.json delete /teams/{team_token}/members/{user_token}
Remove a member from a Team.
# Update team
Source: https://docs.vantage.sh/api/teams/update-team
https://api.vantage.sh/v2/oas_v3.json put /teams/{team_token}
Update a Team.
# Generate data export of unit costs
Source: https://docs.vantage.sh/api/unitcosts/generate-data-export-of-unit-costs
https://api.vantage.sh/v2/oas_v3.json post /unit_costs/data_exports
Generate a DataExport of unit costs.
# Get all unit costs for a cost report
Source: https://docs.vantage.sh/api/unitcosts/get-all-unit-costs-for-a-cost-report
https://api.vantage.sh/v2/oas_v3.json get /unit_costs
Return all UnitCosts for a CostReport.
# Submit user feedback
Source: https://docs.vantage.sh/api/userfeedback/submit-user-feedback
https://api.vantage.sh/v2/oas_v3.json post /user_feedback
Provide UserFeedback for our product and features.
# Get all users
Source: https://docs.vantage.sh/api/users/get-all-users
https://api.vantage.sh/v2/oas_v3.json get /users
Return all Users that the current API token has access to.
# Get user by token
Source: https://docs.vantage.sh/api/users/get-user-by-token
https://api.vantage.sh/v2/oas_v3.json get /users/{user_token}
Return a specific User.
# Update a user
Source: https://docs.vantage.sh/api/users/update-a-user
https://api.vantage.sh/v2/oas_v3.json put /users/{user_token}
Update a specific User.
# Vantage API Reference
Source: https://docs.vantage.sh/api/vantage_api_reference
Complete reference of all Vantage API endpoints. This page is auto-generated from the OpenAPI specification.
This page is auto-generated from the [OpenAPI specification](https://api.vantage.sh/v2/oas_v3.json).
For interactive testing and detailed schemas, visit the individual endpoint pages linked below.
## AccessGrants
### GET /access\_grants
**Get all access grants**
Return all Access Grants that the current API token has access to.
#### Query Parameters
* **page** (integer (int32)) - Optional: The page of results to return.
* **limit** (integer (int32)) - Optional: The amount of results to return. The maximum is 1000.
#### Responses
**200**: OK
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/accessgrants/get-all-access-grants](https://docs.vantage.sh/api/accessgrants/get-all-access-grants)
***
### POST /access\_grants
**Create access grant**
Create an Access Grant.
#### Request Body
```json theme={null}
{
"resource_token": string // required // The token of the resource for which you are granting access,
"team_token": string // required // The token of the Team you want to grant access to,
"access": string // The access level you want to grant. Defaults to 'allowed'. Allowed values: `denied`, `allowed`
}
```
#### Responses
**201**: Created
**400**: BadRequest
**403**: Forbidden
**404**: NotFound
**406**: NotAcceptable
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/accessgrants/create-access-grant](https://docs.vantage.sh/api/accessgrants/create-access-grant)
***
### DELETE /access\_grants/
**Delete access grant**
Delete an Access Grant.
#### Path Parameters
* **access\_grant\_token** (path) (string) - **Required**
#### Responses
**204**: No Content
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/accessgrants/delete-access-grant](https://docs.vantage.sh/api/accessgrants/delete-access-grant)
***
### GET /access\_grants/
**Get access grant by token**
Return a specific Access Grant.
#### Path Parameters
* **access\_grant\_token** (path) (string) - **Required**
#### Responses
**200**: OK
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/accessgrants/get-access-grant-by-token](https://docs.vantage.sh/api/accessgrants/get-access-grant-by-token)
***
### PUT /access\_grants/
**Update access grant**
Update an AccessGrant.
#### Path Parameters
* **access\_grant\_token** (path) (string) - **Required**
#### Request Body
```json theme={null}
{
"access": string // required // Allowed or denied access to resource. Allowed values: `denied`, `allowed`
}
```
#### Responses
**200**: OK
**400**: BadRequest
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/accessgrants/update-access-grant](https://docs.vantage.sh/api/accessgrants/update-access-grant)
***
## AccessPolicies
### GET /access\_policies
**Get all access policies**
Return all Access Policies for the current account.
#### Query Parameters
* **page** (integer (int32)) - Optional: The page of results to return.
* **limit** (integer (int32)) - Optional: The amount of results to return. The maximum is 1000.
#### Responses
**200**: OK
**403**: Forbidden
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/accesspolicies/get-all-access-policies](https://docs.vantage.sh/api/accesspolicies/get-all-access-policies)
***
### POST /access\_policies
**Create access policy**
Create an Access Policy.
#### Request Body
```json theme={null}
{
"title": string // required // The title of the AccessPolicy,
"policy": { // required // The AccessPolicy definition as a v1 document with vantage.* VQL
"api_version": string // required // The AccessPolicy document version. Allowed values: `v1`,
"policy": { // required // The AccessPolicy rules for this version
"filter": string // required // Vantage Query Language (VQL) that controls which costs this AccessPolicy allows
}
},
"description": string // The description of the AccessPolicy,
"team_tokens": [string] // The tokens for Teams this AccessPolicy is assigned to
}
```
#### Responses
**201**: Created
**400**: BadRequest
**403**: Forbidden
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/accesspolicies/create-access-policy](https://docs.vantage.sh/api/accesspolicies/create-access-policy)
***
### DELETE /access\_policies/
**Delete access policy**
Delete an Access Policy.
#### Path Parameters
* **access\_policy\_token** (path) (string) - **Required**
#### Responses
**204**: No Content
**403**: Forbidden
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/accesspolicies/delete-access-policy](https://docs.vantage.sh/api/accesspolicies/delete-access-policy)
***
### PUT /access\_policies/
**Update access policy**
Update an Access Policy.
#### Path Parameters
* **access\_policy\_token** (path) (string) - **Required**
#### Request Body
```json theme={null}
{
"title": string // The title of the AccessPolicy,
"policy": { // The AccessPolicy definition as a v1 document with vantage.* VQL
"api_version": string // required // The AccessPolicy document version. Allowed values: `v1`,
"policy": { // required // The AccessPolicy rules for this version
"filter": string // required // Vantage Query Language (VQL) that controls which costs this AccessPolicy allows
}
},
"description": string // The description of the AccessPolicy,
"team_tokens": [string] // The tokens for Teams this AccessPolicy is assigned to
}
```
#### Responses
**200**: OK
**400**: BadRequest
**403**: Forbidden
**404**: NotFound
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/accesspolicies/update-access-policy](https://docs.vantage.sh/api/accesspolicies/update-access-policy)
***
## Annotations
### GET /annotations
**Get all annotations**
Return all Annotations.
#### Query Parameters
* **page** (integer (int32)) - Optional: The page of results to return.
* **limit** (integer (int32)) - Optional: The number of results to return. The maximum is 5000.
* **report\_token** (string) - Optional: Filter by Report token.
#### Responses
**200**: OK
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/annotations/get-all-annotations](https://docs.vantage.sh/api/annotations/get-all-annotations)
***
### POST /annotations
**Create an annotation**
Create an Annotation.
#### Request Body
```json theme={null}
{
"report_tokens": [string] // required // The tokens of the Reports to annotate,
"title": string // The title of the Annotation. Defaults to a title generated from the first Report and date,
"date": string // required // The date of the Annotation. ISO 8601 formatted,
"message": string // required // The message of the Annotation
}
```
#### Responses
**201**: Annotation created successfully.
**400**: BadRequest
**403**: Forbidden
**404**: NotFound
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/annotations/create-an-annotation](https://docs.vantage.sh/api/annotations/create-an-annotation)
***
### DELETE /annotations/
**Delete an annotation**
Delete an Annotation.
#### Path Parameters
* **annotation\_token** (path) (string) - **Required**: The token of the Annotation.
#### Responses
**204**: Annotation deleted successfully.
**403**: Forbidden
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/annotations/delete-an-annotation](https://docs.vantage.sh/api/annotations/delete-an-annotation)
***
### PUT /annotations/
**Update an annotation**
Update an Annotation.
#### Path Parameters
* **annotation\_token** (path) (string) - **Required**: The token of the Annotation.
#### Request Body
```json theme={null}
{
"title": string // The title of the Annotation,
"date": string // The date of the Annotation. ISO 8601 formatted,
"message": string // The message of the Annotation,
"report_tokens": [string] // The tokens of the Reports to associate with the Annotation
}
```
#### Responses
**200**: Annotation updated successfully.
**400**: BadRequest
**403**: Forbidden
**404**: NotFound
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/annotations/update-an-annotation](https://docs.vantage.sh/api/annotations/update-an-annotation)
***
## AnomalyAlerts
### GET /anomaly\_alerts
**Get all anomaly alerts**
Return all Anomaly Alerts that the current API token has access to.
#### Query Parameters
* **page** (integer (int32)) - Optional: The page of results to return.
* **limit** (integer (int32)) - Optional: The amount of results to return. The maximum is 1000.
* **start\_date** (string (date-time)) - Optional: The start date of the anomalies to return. ISO 8601 formatted.
* **end\_date** (string (date-time)) - Optional: The end date of the anomalies to return. ISO 8601 formatted.
* **provider** (string) - Optional: The provider of the anomalies to return.
* **service** (string) - Optional: The service of the anomalies to return.
* **cost\_category** (string) - Optional: The cost category of the anomalies to return.
* **cost\_report\_token** (string) - Optional: The cost report token of the anomalies to return.
#### Responses
**200**: OK
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/anomalyalerts/get-all-anomaly-alerts](https://docs.vantage.sh/api/anomalyalerts/get-all-anomaly-alerts)
***
### GET /anomaly\_alerts/
**Get anomaly alert by token**
Return an AnomalyAlert that the current API token has access to.
#### Path Parameters
* **anomaly\_alert\_token** (path) (string) - **Required**
#### Responses
**200**: OK
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/anomalyalerts/get-anomaly-alert-by-token](https://docs.vantage.sh/api/anomalyalerts/get-anomaly-alert-by-token)
***
### PUT /anomaly\_alerts/
**Update anomaly alert**
Update an AnomalyAlert.
#### Path Parameters
* **anomaly\_alert\_token** (path) (string) - **Required**
#### Request Body
```json theme={null}
{
"status": string // required // The status of the Anomaly Alert,
"feedback": string // Optional additional comments for why this alert is ignored
}
```
#### Responses
**200**: OK
**400**: BadRequest
**403**: Forbidden
**404**: NotFound
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/anomalyalerts/update-anomaly-alert](https://docs.vantage.sh/api/anomalyalerts/update-anomaly-alert)
***
## AnomalyNotifications
### GET /anomaly\_notifications
**Get all anomaly notifications**
Return all Anomaly Notifications.
#### Query Parameters
* **page** (integer (int32)) - Optional: The page of results to return.
* **limit** (integer (int32)) - Optional: The amount of results to return. The maximum is 1000.
* **workspace\_token** (string) - Optional: Filter by workspace token.
* **cost\_report\_token** (string) - Optional: Filter by Cost Report token.
#### Responses
**200**: OK
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/anomalynotifications/get-all-anomaly-notifications](https://docs.vantage.sh/api/anomalynotifications/get-all-anomaly-notifications)
***
### POST /anomaly\_notifications
**Create anomaly notification**
Create an Anomaly Notification for a Cost Report.
#### Request Body
```json theme={null}
{
"cost_report_token": string // required // The token of the Cost Report that has the notification,
"threshold": integer // The threshold amount that must be met for the notification to fire,
"user_tokens": [string] // The tokens of the Users that receive the notification,
"recipient_emails": [string] // Email addresses that receive the notification. Must be organization users, on the account's SSO domain, or an approved third-party service address,
"recipient_channels": [string] // The Slack/MS Teams channels that receive the notification
}
```
#### Responses
**201**: Created
**400**: BadRequest
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/anomalynotifications/create-anomaly-notification](https://docs.vantage.sh/api/anomalynotifications/create-anomaly-notification)
***
### DELETE /anomaly\_notifications/
**Delete anomaly notification**
Delete an Anomaly Notification.
#### Path Parameters
* **anomaly\_notification\_token** (path) (string) - **Required**
#### Responses
**204**: No Content
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/anomalynotifications/delete-anomaly-notification](https://docs.vantage.sh/api/anomalynotifications/delete-anomaly-notification)
***
### GET /anomaly\_notifications/
**Get anomaly notification by token**
Return an Anomaly Notification that the current API token has access to.
#### Path Parameters
* **anomaly\_notification\_token** (path) (string) - **Required**
#### Responses
**200**: OK
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/anomalynotifications/get-anomaly-notification-by-token](https://docs.vantage.sh/api/anomalynotifications/get-anomaly-notification-by-token)
***
### PUT /anomaly\_notifications/
**Update anomaly notification**
Update an Anomaly Notification.
#### Path Parameters
* **anomaly\_notification\_token** (path) (string) - **Required**
#### Request Body
```json theme={null}
{
"threshold": integer // The threshold amount that must be met for the notification to fire,
"user_tokens": [string] // The tokens of the users that receive the notification,
"recipient_emails": [string] // Email addresses that receive the notification. Must be organization users, on the account's SSO domain, or an approved third-party service address,
"recipient_channels": [string] // The Slack/MS Teams channels that receive the notification
}
```
#### Responses
**200**: OK
**400**: BadRequest
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/anomalynotifications/update-anomaly-notification](https://docs.vantage.sh/api/anomalynotifications/update-anomaly-notification)
***
## AuditLogs
### GET /audit\_logs
**Get all audit logs**
Return all AuditLogs.
#### Query Parameters
* **page** (integer (int32)) - Optional: The page of results to return.
* **limit** (integer (int32)) - Optional: The amount of results to return. Defaults to 100. The maximum is 5000.
* **user** (integer (int32)) - Optional: Filter by personal or service API token that performed the action.
* **workspace\_token** (string) - Optional: Filter by workspace token.
* **action** (string) - Optional: Filter by action type.
* Allowed values: `create`, `update`, `delete`
* **object\_name** (string) - Optional: Filter by object name.
* **source** (string) - Optional: Filter by source.
* Allowed values: `console`, `api`, `finops_agent`
* **object\_type** (string) - Optional: Filter by object type.
* Allowed values: `virtual_tag`, `cost_report`, `recommendation_commitment`, `segment`, `access_policy`
* **token** (string) - Optional: Filter by audit log token.
* **object\_token** (string) - Optional: Filter by object token (auditable\_token).
* **start\_date** (string (date)) - Optional: Filter by start date (ISO 8601 format, e.g., 2024-06-01).
* **end\_date** (string (date)) - Optional: Filter by end date (ISO 8601 format, e.g., 2024-06-01).
#### Responses
**200**: OK
**403**: Forbidden
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/auditlogs/get-all-audit-logs](https://docs.vantage.sh/api/auditlogs/get-all-audit-logs)
***
### GET /audit\_logs/
**Get audit log by token**
Return a specific AuditLog.
#### Path Parameters
* **audit\_log\_token** (path) (string) - **Required**
#### Responses
**200**: OK
**403**: Forbidden
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/auditlogs/get-audit-log-by-token](https://docs.vantage.sh/api/auditlogs/get-audit-log-by-token)
***
## BillingProfiles
### GET /billing\_profiles
**Get all billing profiles**
Returns a list of billing profiles (MSP invoicing required).
#### Query Parameters
* **page** (integer (int32)) - Optional: The page of results to return.
* **limit** (integer (int32)) - Optional: The amount of results to return. The maximum is 1000.
#### Responses
**200**: OK
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/billingprofiles/get-all-billing-profiles](https://docs.vantage.sh/api/billingprofiles/get-all-billing-profiles)
***
### POST /billing\_profiles
**Create billing profile**
Create a billing profile (MSP invoicing required).
#### Request Body
```json theme={null}
{
"nickname": string // required // Display name for the billing profile,
"billing_information_attributes": { // Billing address and contact information
"token": string,
"company_name": string // Company name for billing,
"country_code": string // ISO country code,
"address_line_1": string // First line of billing address,
"address_line_2": string // Second line of billing address,
"city": string // City for billing address,
"state": string // State or province for billing address,
"postal_code": string // Postal or ZIP code,
"billing_email": [string] // Array of billing email addresses
},
"business_information_attributes": { // Business information and custom fields
"token": string,
"metadata": { // Business metadata including custom fields
"custom_fields": [ // Array of custom field objects
{
"name": string // Custom field name,
"value": string // Custom field value
}
]
}
},
"banking_information_attributes": { // Banking details (MSP accounts only)
"token": string,
"bank_name": string // Name of the bank,
"beneficiary_name": string // Name of the account beneficiary,
"tax_id": string // Tax identification number,
"secure_data": { // Encrypted banking details
"account_number": string // Bank account number (US),
"routing_number": string // Bank routing number (US),
"iban": string // International Bank Account Number (EU),
"swift_bic": string // SWIFT/BIC code (EU)
}
},
"invoice_adjustment_attributes": { // Invoice adjustments (taxes, fees, etc.)
"token": string,
"adjustment_items": [ // Array of adjustment items
{
"name": string // required // Name of the adjustment,
"adjustment_type": string // Type of adjustment. Allowed values: `charge`, `credit`, `discount`,
"calculation_type": string // required // How the adjustment is calculated. Allowed values: `fixed`, `percentage`,
"amount": number // required // Amount or percentage value
}
]
}
}
```
#### Responses
**201**: Created
**400**: BadRequest
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/billingprofiles/create-billing-profile](https://docs.vantage.sh/api/billingprofiles/create-billing-profile)
***
### DELETE /billing\_profiles/
**Delete billing profile**
Requires MSP invoicing to be enabled on the account.
#### Path Parameters
* **billing\_profile\_token** (path) (string) - **Required**
#### Responses
**204**: Billing Profile deleted successfully.
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/billingprofiles/delete-billing-profile](https://docs.vantage.sh/api/billingprofiles/delete-billing-profile)
***
### GET /billing\_profiles/
**Get billing profile by token**
Requires MSP invoicing to be enabled on the account.
#### Path Parameters
* **billing\_profile\_token** (path) (string) - **Required**
#### Responses
**200**: OK
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/billingprofiles/get-billing-profile-by-token](https://docs.vantage.sh/api/billingprofiles/get-billing-profile-by-token)
***
### PUT /billing\_profiles/
**Update billing profile**
Requires MSP invoicing to be enabled on the account.
#### Path Parameters
* **billing\_profile\_token** (path) (string) - **Required**
#### Request Body
```json theme={null}
{
"nickname": string // Display name for the billing profile,
"billing_information_attributes": { // Billing address and contact information
"token": string,
"company_name": string // Company name for billing,
"country_code": string // ISO country code,
"address_line_1": string // First line of billing address,
"address_line_2": string // Second line of billing address,
"city": string // City for billing address,
"state": string // State or province for billing address,
"postal_code": string // Postal or ZIP code,
"billing_email": [string] // Array of billing email addresses
},
"business_information_attributes": { // Business information and custom fields
"token": string,
"metadata": { // Business metadata including custom fields
"custom_fields": [ // Array of custom field objects
{
"name": string // Custom field name,
"value": string // Custom field value
}
]
}
},
"banking_information_attributes": { // Banking details (MSP accounts only)
"token": string,
"bank_name": string // Name of the bank,
"beneficiary_name": string // Name of the account beneficiary,
"tax_id": string // Tax identification number,
"secure_data": { // Encrypted banking details
"account_number": string // Bank account number (US),
"routing_number": string // Bank routing number (US),
"iban": string // International Bank Account Number (EU),
"swift_bic": string // SWIFT/BIC code (EU)
}
},
"invoice_adjustment_attributes": { // Invoice adjustments (taxes, fees, etc.)
"token": string,
"adjustment_items": [ // Array of adjustment items
{
"name": string // required // Name of the adjustment,
"adjustment_type": string // Type of adjustment. Allowed values: `charge`, `credit`, `discount`,
"calculation_type": string // required // How the adjustment is calculated. Allowed values: `fixed`, `percentage`,
"amount": number // required // Amount or percentage value
}
]
}
}
```
#### Responses
**200**: OK
**400**: BadRequest
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/billingprofiles/update-billing-profile](https://docs.vantage.sh/api/billingprofiles/update-billing-profile)
***
## BillingRules
### GET /billing\_rules
**Get all billing rules**
Returns a list of billing rules.
#### Query Parameters
* **page** (integer (int32)) - Optional: The page of results to return.
* **limit** (integer (int32)) - Optional: The amount of results to return. The maximum is 1000.
#### Responses
**200**: OK
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/billingrules/get-all-billing-rules](https://docs.vantage.sh/api/billingrules/get-all-billing-rules)
***
### POST /billing\_rules
**Create billing rule**
Create a BillingRule.
#### Request Body
```json theme={null}
{
"type": string // required // The type of the BillingRule. Note: the values are case insensitive. Allowed values: `exclusion`, `adjustment`, `credit`, `charge`, `custom`,
"title": string // required // The title of the BillingRule,
"start_period": string // The start period of the BillingRule. DEPRECATED: use start_date instead,
"start_date": string // The start date of the BillingRule. ISO 8601 formatted,
"end_date": string // The end date of the BillingRule. ISO 8601 formatted,
"apply_to_all": boolean // Determines if the BillingRule applies to all current and future managed accounts,
"charge_type": string // The charge type of the BillingRule. Required for Exclusion rules,
"percentage": number // The percentage of the cost shown. Required for Adjustment rules. Example value: 75.0,
"service": string // The service of the BillingRule. Required for Charge and Credit rules,
"category": string // The category of the BillingRule. Required for Charge and Credit rules,
"sub_category": string // The subcategory of the BillingRule. Required for Charge and Credit rules,
"amount": number // The amount for the BillingRule. Required for Charge and Credit rules. Example value: 300,
"sql_query": string // The SQL query for the BillingRule. Required for Custom rules. Example value: UPDATE costs SET costs.amount = costs.amount * 0.95
}
```
#### Responses
**201**: Created
**400**: BadRequest
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/billingrules/create-billing-rule](https://docs.vantage.sh/api/billingrules/create-billing-rule)
***
### DELETE /billing\_rules/
**Delete billing rule**
Delete a BillingRule.
#### Path Parameters
* **billing\_rule\_token** (path) (string) - **Required**
#### Responses
**204**: No Content
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/billingrules/delete-billing-rule](https://docs.vantage.sh/api/billingrules/delete-billing-rule)
***
### GET /billing\_rules/
**Get billing rule by token**
Return a BillingRule.
#### Path Parameters
* **billing\_rule\_token** (path) (string) - **Required**
#### Responses
**200**: OK
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/billingrules/get-billing-rule-by-token](https://docs.vantage.sh/api/billingrules/get-billing-rule-by-token)
***
### PUT /billing\_rules/
**Update billing rule**
Update a BillingRule.
#### Path Parameters
* **billing\_rule\_token** (path) (string) - **Required**
#### Request Body
```json theme={null}
{
"title": string // The title of the BillingRule,
"charge_type": string // The charge type of the BillingRule,
"percentage": number // The percentage of the cost shown. Example value: 75.0,
"service": string // The service of the BillingRule,
"category": string // The category of the BillingRule,
"sub_category": string // The subcategory of the BillingRule,
"start_period": string // The start period of the BillingRule,
"amount": number // The credit amount for the BillingRule. Example value: 300,
"start_date": string // The start date of the BillingRule. ISO 8601 formatted,
"end_date": string // The end date of the BillingRule. ISO 8601 formatted,
"apply_to_all": boolean // Determines if the BillingRule applies to all current and future managed accounts,
"sql_query": string // The SQL query of the BillingRule
}
```
#### Responses
**200**: OK
**400**: BadRequest
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/billingrules/update-billing-rule](https://docs.vantage.sh/api/billingrules/update-billing-rule)
***
## BudgetAlerts
### GET /budget\_alerts
**Get all budget alerts**
Return all BudgetAlerts.
#### Query Parameters
* **page** (integer (int32)) - Optional: The page of results to return.
* **limit** (integer (int32)) - Optional: The number of results to return. The maximum is 1000.
* **workspace\_token** (string) - Optional: Filter by workspace token.
* **budget\_token** (string) - Optional: Filter by budget token.
#### Responses
**200**: OK
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/budgetalerts/get-all-budget-alerts](https://docs.vantage.sh/api/budgetalerts/get-all-budget-alerts)
***
### POST /budget\_alerts
**Create budget alert**
Create a Budget Alert.
#### Request Body
```json theme={null}
{
"budget_tokens": [string] // required // The tokens of the Budget that has the alert,
"threshold": integer // required // The threshold amount that must be met for the alert to fire,
"workspace_token": string // The token of the Workspace to add the BudgetAlert to. Required if the API token is associated with multiple Workspaces,
"user_tokens": [string] // The tokens of the users that receive the alert,
"recipient_emails": [string] // Email addresses that receive the alert. Must be organization users, on the account's SSO domain, or an approved third-party service address,
"duration_in_days": string // required // The number of days from the start or end of the month to trigger the alert if the threshold is reached. For the full month, pass an empty value,
"period_to_track": string // The period tracked on the alert. Used with duration_in_days to determine the time window of the alert. Defaults to start_of_the_month if not passed. Possible values: start_of_the_month, end_of_the_month,
"recipient_channels": [string] // The channels receiving the alerts. Requires an integration provider to be connected
}
```
#### Responses
**201**: Created
**400**: BadRequest
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/budgetalerts/create-budget-alert](https://docs.vantage.sh/api/budgetalerts/create-budget-alert)
***
### DELETE /budget\_alerts/
**Delete budget alert**
Delete a BudgetAlert.
#### Path Parameters
* **budget\_alert\_token** (path) (string) - **Required**
#### Responses
**204**: No Content
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/budgetalerts/delete-budget-alert](https://docs.vantage.sh/api/budgetalerts/delete-budget-alert)
***
### GET /budget\_alerts/
**Get budget alert by token**
Return a BudgetAlert.
#### Path Parameters
* **budget\_alert\_token** (path) (string) - **Required**
#### Responses
**200**: OK
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/budgetalerts/get-budget-alert-by-token](https://docs.vantage.sh/api/budgetalerts/get-budget-alert-by-token)
***
### PUT /budget\_alerts/
**Update budget alert**
Updates an existing BudgetAlert.
#### Path Parameters
* **budget\_alert\_token** (path) (string) - **Required**
#### Request Body
```json theme={null}
{
"budget_tokens": [string] // The tokens of the Budget that has the alert,
"threshold": integer // The threshold amount that must be met for the alert to fire,
"workspace_token": string // The token of the Workspace the BudgetAlert belongs to. Required if the API token is associated with multiple Workspaces,
"user_tokens": [string] // The tokens of the users that receive the alert,
"recipient_emails": [string] // Email addresses that receive the alert. Must be organization users, on the account's SSO domain, or an approved third-party service address,
"duration_in_days": string // The number of days from the start or end of the month to trigger the alert if the threshold is reached. For the full month, pass an empty value,
"period_to_track": string // The period tracked on the alert. Used with duration_in_days to determine the time window of the alert. Defaults to start_of_the_month if not passed. Possible values: start_of_the_month, end_of_the_month,
"recipient_channels": [string] // The channels receiving the alerts. Requires an integration provider to be connected
}
```
#### Responses
**200**: OK
**400**: BadRequest
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/budgetalerts/update-budget-alert](https://docs.vantage.sh/api/budgetalerts/update-budget-alert)
***
## Budgets
### GET /budgets
**Get all budgets**
Return all Budgets.
#### Query Parameters
* **page** (integer (int32)) - Optional: The page of results to return.
* **limit** (integer (int32)) - Optional: The number of results to return. The maximum is 1000.
* **q** (string) - Optional: Search budgets by name.
* **workspace\_token** (string) - Optional: The workspace token of the budgets to return.
#### Responses
**200**: OK
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/budgets/get-all-budgets](https://docs.vantage.sh/api/budgets/get-all-budgets)
***
### POST /budgets
**Create budget**
Create a Budget.
#### Request Body
```json theme={null}
{
"name": string // required // The name of the Budget,
"workspace_token": string // The token of the Workspace to add the Budget to,
"cost_report_token": string // The CostReport token. Ignored for hierarchical Budgets,
"type": string // The type of Budget. One of: cost, usage. Allowed values: `cost`, `usage`,
"unit": string // The usage unit for usage Budgets,
"child_budget_tokens": [string] // The tokens of any child Budgets when creating a hierarchical Budget. Child budgets must share the same current period dates,
"period_cadence": { // The interval cadence for budget periods
"starts_at": string // required // The anchor date for budget period intervals. Send null to clear,
"interval_count": integer // The number of interval units per budget period,
"interval_unit": string // The unit for budget period intervals. One of: day, week, month, year. Allowed values: `day`, `week`, `month`, `year`
},
"periods": [ // The periods for the Budget. The start_at and end_at must be iso8601 formatted e.g. YYYY-MM-DD. Ignored for hierarchical Budgets
{
"start_at": string // required // The start date of the period,
"end_at": string // The end date of the period,
"amount": number // required // The amount of the period
}
]
}
```
#### Responses
**201**: Created
**400**: BadRequest
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/budgets/create-budget](https://docs.vantage.sh/api/budgets/create-budget)
***
### DELETE /budgets/
**Delete budget**
Delete a Budget.
#### Path Parameters
* **budget\_token** (path) (string) - **Required**
#### Responses
**204**: No Content
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/budgets/delete-budget](https://docs.vantage.sh/api/budgets/delete-budget)
***
### GET /budgets/
**Get budget by token**
Return a Budget.
#### Path Parameters
* **budget\_token** (path) (string) - **Required**
#### Query Parameters
* **include\_performance** (boolean) - Optional: Include performance data.
#### Responses
**200**: OK
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/budgets/get-budget-by-token](https://docs.vantage.sh/api/budgets/get-budget-by-token)
***
### PUT /budgets/
**Update budget**
Update a Budget.
#### Path Parameters
* **budget\_token** (path) (string) - **Required**
#### Request Body
```json theme={null}
{
"name": string // The name of the Budget,
"cost_report_token": string // The CostReport token. Ignored for hierarchical Budgets,
"type": string // The type of Budget. One of: cost, usage. Allowed values: `cost`, `usage`,
"unit": string // The usage unit for usage Budgets. Send null to clear,
"child_budget_tokens": [string] // The tokens of any child Budgets when creating a hierarchical Budget. Child budgets must share the same current period dates. Omitted on update to leave the current child list unchanged,
"period_cadence": { // The interval cadence for budget periods. Changing cadence after creation is rejected
"starts_at": string // required // The anchor date for budget period intervals. Send null to clear,
"interval_count": integer // The number of interval units per budget period,
"interval_unit": string // The unit for budget period intervals. One of: day, week, month, year. Allowed values: `day`, `week`, `month`, `year`
},
"periods": [ // The periods for the Budget. The start_at and end_at must be iso8601 formatted e.g. YYYY-MM-DD. Ignored for hierarchical Budgets
{
"start_at": string // required // The start date of the period,
"end_at": string // The end date of the period,
"amount": number // required // The amount of the period
}
]
}
```
#### Responses
**200**: OK
**400**: BadRequest
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/budgets/update-budget](https://docs.vantage.sh/api/budgets/update-budget)
***
## BusinessMetrics
### GET /business\_metrics
**Get all business metrics**
Return all BusinessMetrics that the current API token has access to.
#### Query Parameters
* **page** (integer (int32)) - Optional: The page of results to return.
* **limit** (integer (int32)) - Optional: The amount of results to return. The maximum is 5000.
* **q** (string) - Optional: Search business metrics by title.
#### Responses
**200**: OK
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/businessmetrics/get-all-business-metrics](https://docs.vantage.sh/api/businessmetrics/get-all-business-metrics)
***
### POST /business\_metrics
**Create business metric**
Create a new BusinessMetric.
#### Request Body
```json theme={null}
{
"title": string // required // The title of the BusinessMetrics,
"cost_report_tokens_with_metadata": [ // The tokens for any CostReports that use the BusinessMetric, the unit scale, and label filter
{
"cost_report_token": string // required // The token of the CostReport the BusinessMetric is attached to,
"unit_scale": string // Determines the scale of the BusinessMetric's values within the CostReport. Allowed values: `per_unit`, `per_hundred`, `per_thousand`, `per_million`, `per_billion`,
"calculation_type": string // The calculation type applied when this BusinessMetric is used in the CostReport. Allowed values: `unit_cost`, `gross_margin`, `usage_unit_cost`, `raw_business_metric`,
"label": string // Optional custom display name for this BusinessMetric on the CostReport. When omitted, a default is derived from the calculation type,
"label_filter": [string] // Include only values with these labels in the CostReport,
"label_filters": object // Include only ClickHouse BusinessMetric values matching every label key and one of its values
}
],
"values": [ // The dates, amounts, and (optional) labels for the BusinessMetric
{
"date": string // required,
"amount": number // required,
"label": string
}
],
"forecasted_values": [ // The dates, amounts, and (optional) labels for forecasted BusinessMetric values
{
"date": string // required,
"amount": number // required,
"label": string
}
],
"datadog_metric_fields": { // Datadog metric configuration fields
"integration_token": string // Integration token for the account from which you would like to fetch metrics,
"query": string // Datadog metrics query string. e.g. sum:aws.applicationelb.request_count{region:us-east-1}.rollup(avg,daily)
},
"cloudwatch_fields": { // Cloudwatch configuration fields
"integration_token": string // Integration token for the account from which you would like to fetch metrics,
"stat": string,
"region": string,
"namespace": string,
"metric_name": string,
"label_dimension": string,
"dimensions": [
{
"name": string,
"value": string
}
]
},
"gcp_bigquery_metric_fields": { // GCP BigQuery metric configuration fields
"integration_token": string // Integration token for the GCP integration from which you would like to fetch metrics,
"query_project_id": string // GCP project in which the BigQuery job should run,
"sql_query": string // BigQuery SQL query returning date, value, and optional label columns
},
"snowflake_metric_fields": { // Snowflake metric configuration fields
"integration_token": string // Integration token for the Snowflake integration from which you would like to fetch metrics,
"sql_query": string // Snowflake SQL query returning date, value, and optional label columns
},
"clickhouse_metric_fields": { // ClickHouse metric configuration fields
"integration_token": string // Integration token for the ClickHouse integration from which you would like to fetch metrics,
"query_endpoint_id": string // UUID of the ClickHouse query endpoint used to fetch metrics
}
}
```
#### Responses
**201**: Created
**400**: BadRequest
**403**: Forbidden
**404**: NotFound
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/businessmetrics/create-business-metric](https://docs.vantage.sh/api/businessmetrics/create-business-metric)
***
### DELETE /business\_metrics/
**Delete business metric**
Deletes an existing BusinessMetric.
#### Path Parameters
* **business\_metric\_token** (path) (string) - **Required**
#### Responses
**204**: No Content
**403**: Forbidden
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/businessmetrics/delete-business-metric](https://docs.vantage.sh/api/businessmetrics/delete-business-metric)
***
### GET /business\_metrics/
**Get business metric by token**
Return a BusinessMetric.
#### Path Parameters
* **business\_metric\_token** (path) (string) - **Required**
#### Responses
**200**: OK
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/businessmetrics/get-business-metric-by-token](https://docs.vantage.sh/api/businessmetrics/get-business-metric-by-token)
***
### PUT /business\_metrics/
**Update business metric**
Updates an existing BusinessMetric.
#### Path Parameters
* **business\_metric\_token** (path) (string) - **Required**
#### Request Body
```json theme={null}
{
"title": string // The title of the BusinessMetric,
"cost_report_tokens_with_metadata": [ // The tokens for any CostReports that use the BusinessMetric, and the unit scale
{
"cost_report_token": string // required // The token of the CostReport the BusinessMetric is attached to,
"unit_scale": string // Determines the scale of the BusinessMetric's values within the CostReport. Allowed values: `per_unit`, `per_hundred`, `per_thousand`, `per_million`, `per_billion`,
"calculation_type": string // The calculation type applied when this BusinessMetric is used in the CostReport. Allowed values: `unit_cost`, `gross_margin`, `usage_unit_cost`, `raw_business_metric`,
"label": string // Optional custom display name for this BusinessMetric on the CostReport. When omitted, a default is derived from the calculation type,
"label_filter": [string] // Include only values with these labels in the CostReport,
"label_filters": object // Include only ClickHouse BusinessMetric values matching every label key and one of its values
}
],
"values": [ // The dates, amounts, and (optional) labels for the BusinessMetric
{
"date": string // required,
"amount": number // required,
"label": string
}
],
"forecasted_values": [ // The dates, amounts, and (optional) labels for forecasted BusinessMetric values
{
"date": string // required,
"amount": number // required,
"label": string
}
],
"datadog_metric_fields": { // Datadog metric configuration fields
"integration_token": string // Integration token for the account from which you would like to fetch metrics,
"query": string // Datadog metrics query string. e.g. sum:aws.applicationelb.request_count{region:us-east-1}.rollup(avg,daily)
},
"cloudwatch_fields": { // Cloudwatch configuration fields
"integration_token": string // Integration token for the account from which you would like to fetch metrics,
"stat": string,
"region": string,
"namespace": string,
"metric_name": string,
"label_dimension": string,
"dimensions": [
{
"name": string,
"value": string
}
]
},
"snowflake_metric_fields": { // Snowflake metric configuration fields
"integration_token": string // Integration token for the Snowflake integration from which you would like to fetch metrics,
"sql_query": string // Snowflake SQL query returning date, value, and optional label columns
}
}
```
#### Responses
**200**: OK
**400**: BadRequest
**403**: Forbidden
**404**: NotFound
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/businessmetrics/update-business-metric](https://docs.vantage.sh/api/businessmetrics/update-business-metric)
***
### GET /business\_metrics//forecasted\_values
**Get business metric forecasted values**
Return forecasted values of a BusinessMetric
#### Path Parameters
* **business\_metric\_token** (path) (string) - **Required**
#### Query Parameters
* **page** (integer (int32)) - Optional: The page of results to return.
* **limit** (integer (int32)) - Optional: The amount of results to return. The maximum is 5000.
* **start\_date** (string (date)) - Optional: Query BusinessMetrics by the first date you would like to filter from. ISO 8601 Formatted - 2021-07-15
#### Responses
**200**: OK
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/businessmetrics/get-business-metric-forecasted-values](https://docs.vantage.sh/api/businessmetrics/get-business-metric-forecasted-values)
***
### GET /business\_metrics//labels
**Get business metric labels**
Return labels of a BusinessMetric.
#### Path Parameters
* **business\_metric\_token** (path) (string) - **Required**
#### Query Parameters
* **page** (integer (int32)) - Optional: The page of results to return.
* Default: `1`
* **limit** (integer (int32)) - Optional: The number of results to return per page. Defaults to 1000. The maximum is 5000.
* Default: `1000`
#### Responses
**200**: OK
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/businessmetrics/get-business-metric-labels](https://docs.vantage.sh/api/businessmetrics/get-business-metric-labels)
***
### DELETE /business\_metrics//values
**Delete business metric values**
Deletes Business Metric values (historical or forecasted unit metrics). BusinessMetrics whose values are stored in ClickHouse only support deleting every historical value or every forecasted value, so supplying start\_date, end\_date, or label returns 422.
#### Path Parameters
* **business\_metric\_token** (path) (string) - **Required**
#### Query Parameters
* **start\_date** (string) - Optional: Inclusive lower bound (ISO 8601 date or datetime, UTC). Date-only values start at 00:00:00 UTC that day.
* **end\_date** (string) - Optional: Inclusive upper bound (ISO 8601 date or datetime, UTC). Date-only values include the full calendar day through 23:59:59.999999999 UTC.
* **label** (string) - Optional: When present in the query string (including as an empty value), only unit metrics with this exact label are deleted. Omit the parameter to delete all labels in range.
* **forecasted** (boolean) - Optional: When true, deletes forecasted unit metrics instead of historical ones.
* Default: `False`
#### Responses
**200**: OK
**403**: Forbidden
**404**: NotFound
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/businessmetrics/delete-business-metric-values](https://docs.vantage.sh/api/businessmetrics/delete-business-metric-values)
***
### GET /business\_metrics//values
**Get business metric values**
Return values of a BusinessMetric
#### Path Parameters
* **business\_metric\_token** (path) (string) - **Required**
#### Query Parameters
* **page** (integer (int32)) - Optional: The page of results to return.
* **limit** (integer (int32)) - Optional: The amount of results to return. The maximum is 5000.
* **start\_date** (string (date)) - Optional: Query BusinessMetrics by the first date you would like to filter from. ISO 8601 Formatted - 2021-07-15
* **label\_values** (array) - Optional: Return values matching any exact label value. For multi-label metrics, matches values under any label key.
* **date\_bin** (string) - Optional: Sum values by UTC day or month while preserving labels. When omitted, values are returned without aggregation.
* Allowed values: `day`, `month`
#### Responses
**200**: OK
**400**: BadRequest
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/businessmetrics/get-business-metric-values](https://docs.vantage.sh/api/businessmetrics/get-business-metric-values)
***
### PUT /business\_metrics//values.csv
**Update business metric values from CSV**
Updates the values for an existing BusinessMetric from a CSV file.
#### Path Parameters
* **business\_metric\_token** (path) (string) - **Required**
#### Responses
**200**: OK
**400**: BadRequest
**403**: Forbidden
**404**: NotFound
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/businessmetrics/update-business-metric-values-from-csv](https://docs.vantage.sh/api/businessmetrics/update-business-metric-values-from-csv)
***
## Canvases
### GET /canvases
**Get all canvases**
Return all Canvases.
#### Query Parameters
* **page** (integer (int32)) - Optional: The page of results to return.
* **limit** (integer (int32)) - Optional: The amount of results to return. The maximum is 1000.
* **workspace\_token** (string) - Optional: Filter by workspace token.
* **q** (string) - Optional: Search canvases by title.
#### Responses
**200**: OK
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/canvases/get-all-canvases](https://docs.vantage.sh/api/canvases/get-all-canvases)
***
### POST /canvases
**Create canvas**
Create a Canvas.
#### Request Body
```json theme={null}
{
"title": string // required // The title of the Canvas,
"prompt": string // required // The prompt used to generate the Canvas,
"workspace_token": string // The token of the Workspace to add the Canvas to. Required if the API token is associated with multiple Workspaces
}
```
#### Responses
**201**: Created
**400**: BadRequest
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/canvases/create-canvas](https://docs.vantage.sh/api/canvases/create-canvas)
***
### DELETE /canvases/
**Delete canvas**
Delete a Canvas.
#### Path Parameters
* **canvas\_token** (path) (string) - **Required**
#### Responses
**204**: No Content
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/canvases/delete-canvas](https://docs.vantage.sh/api/canvases/delete-canvas)
***
### GET /canvases/
**Get canvas by token**
Return a specific Canvas.
#### Path Parameters
* **canvas\_token** (path) (string) - **Required**
#### Responses
**200**: OK
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/canvases/get-canvas-by-token](https://docs.vantage.sh/api/canvases/get-canvas-by-token)
***
### PUT /canvases/
**Update canvas**
Update a Canvas.
#### Path Parameters
* **canvas\_token** (path) (string) - **Required**
#### Request Body
```json theme={null}
{
"title": string // The title of the Canvas,
"prompt": string // The prompt used to generate the Canvas
}
```
#### Responses
**200**: OK
**400**: BadRequest
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/canvases/update-canvas](https://docs.vantage.sh/api/canvases/update-canvas)
***
## CostAlertEvents
### GET /cost\_alerts//events
**Get all cost alert events**
Get all CostAlertEvents
#### Path Parameters
* **cost\_alert\_token** (path) (string) - **Required**: The token of the CostAlertEvent.
#### Query Parameters
* **report\_token** (string) - Optional: The token of the report associated with the CostAlertEvent.
* **page** (integer (int32)) - Optional: The page of results to return.
* **limit** (integer (int32)) - Optional: The number of results to return. The maximum is 1000.
#### Responses
**200**: OK
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/costalertevents/get-all-cost-alert-events](https://docs.vantage.sh/api/costalertevents/get-all-cost-alert-events)
***
### GET /cost\_alerts//events/
**Get cost alert event by token**
Get a CostAlertEvent
#### Path Parameters
* **cost\_alert\_token** (path) (string) - **Required**
* **event\_token** (path) (string) - **Required**
#### Responses
**200**: OK
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/costalertevents/get-cost-alert-event-by-token](https://docs.vantage.sh/api/costalertevents/get-cost-alert-event-by-token)
***
## CostAlerts
### GET /cost\_alerts
**Get all cost alerts**
List all Cost Alerts
#### Query Parameters
* **page** (integer (int32)) - Optional: The page of results to return.
* **limit** (integer (int32)) - Optional: The amount of results to return. The maximum is 5000.
* **q** (string) - Optional: Search cost alerts by title.
* **workspace\_token** (string) - Optional: The workspace token of the cost alerts to return.
#### Responses
**200**: List all Cost Alerts
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/costalerts/get-all-cost-alerts](https://docs.vantage.sh/api/costalerts/get-all-cost-alerts)
***
### POST /cost\_alerts
**Create cost alert**
Create a new Cost Alert
#### Request Body
```json theme={null}
{
"title": string // required // The title of the Cost Alert,
"interval": string // required // The period of time used to compare costs. Options are 'day', 'week', 'month', 'quarter',
"threshold": number // required // The threshold value for the Cost Alert,
"unit_type": string // required // The unit type used to compare costs. Options are 'currency' or 'percentage',
"workspace_token": string // required // The token of the Workspace to add the Cost Alert to,
"report_tokens": [string] // required // The tokens of the reports to alert on,
"email_recipients": [string] // The email recipients for the Cost Alert. Accepts organization users, SSO-domain emails, and approved third-party service emails,
"slack_channels": [string] // The Slack channels that will receive the alert,
"teams_channels": [string] // The Microsoft Teams channels that will receive the alert,
"minimum_threshold": number // The minimum monetary amount threshold for percentage-based alerts. Only applicable when unit_type is 'percentage'
}
```
#### Responses
**201**: Cost Alert created successfully.
**400**: BadRequest
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/costalerts/create-cost-alert](https://docs.vantage.sh/api/costalerts/create-cost-alert)
***
### DELETE /cost\_alerts/
**Delete cost alert**
Delete a Cost Alert
#### Path Parameters
* **cost\_alert\_token** (path) (string) - **Required**: The token of the Cost Alert.
#### Responses
**204**: Cost Alert deleted successfully.
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/costalerts/delete-cost-alert](https://docs.vantage.sh/api/costalerts/delete-cost-alert)
***
### GET /cost\_alerts/
**Get cost alert by token**
Get a Cost Alert
#### Path Parameters
* **cost\_alert\_token** (path) (string) - **Required**: The token of the Cost Alert.
#### Responses
**200**: Get a Cost Alert
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/costalerts/get-cost-alert-by-token](https://docs.vantage.sh/api/costalerts/get-cost-alert-by-token)
***
### PUT /cost\_alerts/
**Update cost alert**
Update a Cost Alert
#### Path Parameters
* **cost\_alert\_token** (path) (string) - **Required**: The token of the Cost Alert.
#### Request Body
```json theme={null}
{
"title": string // The title of the Cost Alert,
"email_recipients": [string] // The email recipients for the Cost Alert. Accepts organization users, SSO-domain emails, and approved third-party service emails,
"interval": string // The period of time used to compare costs. Options are 'day', 'week', 'month', 'quarter',
"threshold": number // The threshold value for the Cost Alert,
"slack_channels": [string] // The Slack channels that will receive the alert. Make sure your slack integration is connected at https://console.vantage.sh/settings/slack,
"teams_channels": [string] // The Microsoft Teams channels that will receive the alert. Make sure your teams integration is connected at https://console.vantage.sh/settings/microsoft_teams,
"unit_type": string // The unit type used to compare costs. Options are 'currency' or 'percentage',
"report_tokens": [string] // The tokens of the reports to alert on,
"minimum_threshold": number // The minimum monetary amount threshold for percentage-based alerts. Only applicable when unit_type is 'percentage'
}
```
#### Responses
**200**: Cost Alert updated successfully.
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/costalerts/update-cost-alert](https://docs.vantage.sh/api/costalerts/update-cost-alert)
***
## CostProvider
### GET /cost\_providers
**Get cost providers**
List CostProviders available to query in a given Workspace.
#### Query Parameters
* **page** (integer (int32)) - Optional: The page of results to return.
* **limit** (integer (int32)) - Optional: The number of results to return. The maximum is 1000.
* **workspace\_token** (string) - Optional: The token of the Workspace to list CostProviders for. Required if the API token is associated with multiple Workspaces.
* **q** (string) - Optional: Search CostProviders by name or key.
#### Responses
**200**: List of connected CostProviders.
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/costprovider/get-cost-providers](https://docs.vantage.sh/api/costprovider/get-cost-providers)
***
## CostProviderAccounts
### GET /cost\_provider\_accounts
**Get all cost provider accounts**
List CostProviderAccounts available in a given Workspace.
#### Query Parameters
* **workspace\_token** (string) - Optional: The token of the Workspace to list CostProviderAccounts for. Required if the API token is associated with multiple Workspaces.
* **provider** (string) - Optional: Filter by provider type.
* Allowed values: `aws`, `azure`, `gcp`, `snowflake`, `databricks`, `mongo`, `datadog`, `fastly`, `new_relic`, `opencost`, `open_ai`, `oracle`, `confluent`, `planetscale`, `coralogix`, `kubernetes`, `custom_provider`, `github`, `linode`, `grafana`, `clickhouse`, `temporal`, `twilio`, `azure_csp`, `kubernetes_agent`, `anthropic`, `anyscale`, `cursor`, `elastic`, `vercel`, `redis_cloud`, `circle_ci`, `modal`, `eleven_labs`, `baseten`, `cloudflare`, `fireworks_ai`, `cartesia`, `depot`, `xai`, `digital_ocean`, `together_ai`, `coreweave`, `devin`, `openrouter`, `deepgram`, `crusoe`, `sentry_billing`
* **account\_id** (string) - Optional: Filter by provider account identifier.
* **account\_name** (string) - Optional: Filter by account name (exact match).
* **q** (string) - Optional: Search CostProviderAccounts by title.
#### Responses
**200**: List of provider accounts.
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/costprovideraccounts/get-all-cost-provider-accounts](https://docs.vantage.sh/api/costprovideraccounts/get-all-cost-provider-accounts)
***
## CostService
### GET /cost\_services
**Get cost services**
List CostServices available to query in a given Workspace.
#### Query Parameters
* **workspace\_token** (string) - Optional: The token of the Workspace to list CostServices for. Required if the API token is associated with multiple Workspaces.
#### Responses
**200**: List of CostServices, used to query costs using VQL.
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/costservice/get-cost-services](https://docs.vantage.sh/api/costservice/get-cost-services)
***
## Costs
### GET /cost\_reports
**Get all cost reports**
Return all CostReports.
#### Query Parameters
* **page** (integer (int32)) - Optional: The page of results to return.
* **limit** (integer (int32)) - Optional: The amount of results to return. The maximum is 1000.
* **folder\_token** (string) - Optional: The token for the Folder you would like to fetch Reports from.
* **q** (string) - Optional: Search cost reports by title.
* **workspace\_token** (string) - Optional: The workspace token of the cost reports to return.
#### Responses
**200**: OK
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/costs/get-all-cost-reports](https://docs.vantage.sh/api/costs/get-all-cost-reports)
***
### POST /cost\_reports
**Create cost report**
Create a CostReport.
#### Request Body
```json theme={null}
{
"title": string // required // The title of the CostReport,
"workspace_token": string // The token of the Workspace to add the Cost Report to. Ignored if 'folder_token' is set. Required if the API token is associated with multiple Workspaces,
"groupings": string // Grouping values for aggregating costs on the report. Valid groupings: account_id, billing_account_id, charge_type, cost_category, cost_subcategory, provider, region, resource_id, service, tagged, usage_unit, tag:tag_value. If providing multiple groupings, join as comma separated values: groupings=provider,service,region,
"filter": string // The filter query language to apply to the CostReport. Additional documentation available at https://docs.vantage.sh/vql,
"saved_filter_tokens": [string] // The tokens of the SavedFilters to apply to the CostReport,
"business_metric_tokens_with_metadata": [ // The tokens for any BusinessMetrics to attach to the CostReport, and the unit scale
{
"business_metric_token": string // required // The token of the BusinessMetric to attach to the CostReport,
"unit_scale": string // Determines the scale of the BusinessMetric's values within the CostReport. Allowed values: `per_unit`, `per_hundred`, `per_thousand`, `per_million`, `per_billion`,
"calculation_type": string // The calculation type applied when this BusinessMetric is used in the CostReport. Allowed values: `unit_cost`, `gross_margin`, `usage_unit_cost`, `raw_business_metric`,
"label": string // Optional custom display name for this BusinessMetric on the CostReport. When omitted, a default is derived from the calculation type,
"label_filter": [string] // Include only values with these labels in the CostReport,
"label_filters": object // Include only ClickHouse BusinessMetric values matching every label key and one of its values
}
],
"folder_token": string // The token of the Folder to add the CostReport to. Determines the Workspace the report is assigned to,
"settings": { // Report settings
"include_credits": boolean // Report will include credits,
"include_refunds": boolean // Report will include refunds,
"include_discounts": boolean // Report will include discounts,
"include_tax": boolean // Report will include tax,
"amortize": boolean // Report will amortize,
"unallocated": boolean // Report will show unallocated costs,
"aggregate_by": string // Report will aggregate by cost, usage, or count. Allowed values: `cost`, `usage`, `count`,
"show_previous_period": boolean // Report will show previous period cost, usage, or count comparison,
"complete_period": boolean // Report will restrict date ranges to completed periods only
},
"previous_period_start_date": string // The previous period start date of the CostReport. ISO 8601 Formatted,
"previous_period_end_date": string // required // The previous period end date of the CostReport. ISO 8601 Formatted. Required when previous_period_start_date is provided,
"start_date": string // The start date of the CostReport. ISO 8601 Formatted. Incompatible with 'date_interval' parameter,
"end_date": string // required // The end date of the CostReport. ISO 8601 Formatted. Required when start_date is provided. Incompatible with 'date_interval' parameter,
"date_interval": string // The date interval of the CostReport. Incompatible with 'start_date' and 'end_date' parameters. Defaults to 'this_month' if start_date and end_date are not provided. Allowed values: `this_month`, `last_7_days`, `last_30_days`, `last_month`, `last_3_months`, `last_6_months`, `custom`, `last_12_months`, `last_24_months`, `last_36_months`, `next_month`, `next_3_months`, `next_6_months`, `next_12_months`, `year_to_date`, `last_3_days`, `last_14_days`,
"chart_type": string // The chart type of the CostReport. Allowed values: `area`, `line`, `pie`, `bar`, `multi_bar`,
"date_bin": string // The date bin of the CostReport. Allowed values: `cumulative`, `day`, `week`, `month`, `quarter`, `hour`,
"chart_settings": { // Report chart settings
"x_axis_dimension": [string] // The dimension used to group or label data along the x-axis (e.g., by date, region, or service). NOTE: Only one value is allowed at this time. Defaults to ['date'],
"y_axis_dimension": string // The metric or measure displayed on the chart’s y-axis. Possible values: 'cost', 'usage', 'count'. Defaults to 'cost'. Allowed values: `cost`, `usage`, `count`
}
}
```
#### Responses
**201**: Created
**400**: BadRequest
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/costs/create-cost-report](https://docs.vantage.sh/api/costs/create-cost-report)
***
### DELETE /cost\_reports/
**Delete cost report**
Delete a CostReport.
#### Path Parameters
* **cost\_report\_token** (path) (string) - **Required**
#### Responses
**204**: No Content
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/costs/delete-cost-report](https://docs.vantage.sh/api/costs/delete-cost-report)
***
### GET /cost\_reports/
**Get cost report by token**
Return a CostReport.
#### Path Parameters
* **cost\_report\_token** (path) (string) - **Required**
#### Responses
**200**: OK
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/costs/get-cost-report-by-token](https://docs.vantage.sh/api/costs/get-cost-report-by-token)
***
### PUT /cost\_reports/
**Update cost report**
Update a CostReport.
#### Path Parameters
* **cost\_report\_token** (path) (string) - **Required**
#### Request Body
```json theme={null}
{
"title": string // The title of the CostReport,
"groupings": string // Grouping values for aggregating costs on the report. Valid groupings: account_id, billing_account_id, charge_type, cost_category, cost_subcategory, provider, region, resource_id, service, tagged, usage_unit, tag:tag_value. If providing multiple groupings, join as comma separated values: groupings=provider,service,region,
"filter": string // The filter query language to apply to the CostReport. Additional documentation available at https://docs.vantage.sh/vql,
"saved_filter_tokens": [string] // The tokens of the SavedFilters to apply to the CostReport,
"business_metric_tokens_with_metadata": [ // The tokens for any BusinessMetrics to attach to the CostReport, and the unit scale
{
"business_metric_token": string // required // The token of the BusinessMetric to attach to the CostReport,
"unit_scale": string // Determines the scale of the BusinessMetric's values within the CostReport. Allowed values: `per_unit`, `per_hundred`, `per_thousand`, `per_million`, `per_billion`,
"calculation_type": string // The calculation type applied when this BusinessMetric is used in the CostReport. Allowed values: `unit_cost`, `gross_margin`, `usage_unit_cost`, `raw_business_metric`,
"label": string // Optional custom display name for this BusinessMetric on the CostReport. When omitted, a default is derived from the calculation type,
"label_filter": [string] // Include only values with these labels in the CostReport,
"label_filters": object // Include only ClickHouse BusinessMetric values matching every label key and one of its values
}
],
"folder_token": string // The token of the Folder to add the CostReport to. Determines the Workspace the report is assigned to,
"default_forecast": { // The default forecast selection for the CostReport
"kind": string // required // The default forecast selection kind. Allowed values: `baseline`, `report_forecast`,
"report_forecast_token": string // The token for the report forecast to set as default when kind is report_forecast
},
"settings": { // Report settings
"include_credits": boolean // Report will include credits,
"include_refunds": boolean // Report will include refunds,
"include_discounts": boolean // Report will include discounts,
"include_tax": boolean // Report will include tax,
"amortize": boolean // Report will amortize,
"unallocated": boolean // Report will show unallocated costs,
"aggregate_by": string // Report will aggregate by cost, usage, or count. Allowed values: `cost`, `usage`, `count`,
"show_previous_period": boolean // Report will show previous period cost, usage, or count comparison,
"complete_period": boolean // Report will restrict date ranges to completed periods only
},
"chart_settings": { // Report chart settings
"x_axis_dimension": [string] // The dimension used to group or label data along the x-axis (e.g., by date, region, or service). NOTE: Only one value is allowed at this time. Defaults to ['date'],
"y_axis_dimension": string // The metric or measure displayed on the chart’s y-axis. Possible values: 'cost', 'usage', 'count'. Defaults to 'cost'. Allowed values: `cost`, `usage`, `count`
},
"previous_period_start_date": string // The previous period start date of the CostReport. ISO 8601 Formatted,
"previous_period_end_date": string // The previous period end date of the CostReport. ISO 8601 Formatted. Required when previous_period_start_date is provided,
"start_date": string // The start date of the CostReport. ISO 8601 Formatted. Incompatible with 'date_interval' parameter,
"end_date": string // The end date of the CostReport. ISO 8601 Formatted. Required when start_date is provided. Incompatible with 'date_interval' parameter,
"date_interval": string // The date interval of the CostReport. Incompatible with 'start_date' and 'end_date' parameters. Defaults to 'this_month' if start_date and end_date are not provided. Allowed values: `this_month`, `last_7_days`, `last_30_days`, `last_month`, `last_3_months`, `last_6_months`, `custom`, `last_12_months`, `last_24_months`, `last_36_months`, `next_month`, `next_3_months`, `next_6_months`, `next_12_months`, `year_to_date`, `last_3_days`, `last_14_days`,
"chart_type": string // The chart type of the CostReport. Allowed values: `area`, `line`, `pie`, `bar`, `multi_bar`,
"date_bin": string // The date bin of the CostReport. Allowed values: `cumulative`, `day`, `week`, `month`, `quarter`, `hour`
}
```
#### Responses
**200**: OK
**400**: BadRequest
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/costs/update-cost-report](https://docs.vantage.sh/api/costs/update-cost-report)
***
### GET /cost\_reports//forecasted\_costs
**Get forecasted costs for a cost report**
Return all ForecastedCosts.
#### Path Parameters
* **cost\_report\_token** (path) (string) - **Required**
#### Query Parameters
* **start\_date** (string (date)) - Optional: First date you would like to filter forecasted costs from. ISO 8601 formatted.
* **end\_date** (string (date)) - Optional: Last date you would like to filter forecasted costs from. ISO 8601 formatted.
* **provider** (string) - Optional: Limit the forecasted costs to a specific provider. 'all' is accepted to filter to overall forecast.
* Allowed values: `aws`, `azure`, `gcp`, `snowflake`, `databricks`, `mongo`, `datadog`, `fastly`, `new_relic`, `opencost`, `open_ai`, `oracle`, `confluent`, `planetscale`, `coralogix`, `kubernetes`, `custom_provider`, `github`, `linode`, `grafana`, `clickhouse`, `temporal`, `twilio`, `azure_csp`, `kubernetes_agent`, `anthropic`, `anyscale`, `cursor`, `elastic`, `vercel`, `redis_cloud`, `circle_ci`, `modal`, `eleven_labs`, `baseten`, `cloudflare`, `fireworks_ai`, `cartesia`, `depot`, `xai`, `digital_ocean`, `together_ai`, `coreweave`, `devin`, `openrouter`, `deepgram`, `crusoe`, `sentry_billing`, `all`
* **service** (string) - Optional: Limit the forecasted costs to a specific service. 'all' is accepted to filter to overall forecast. e.g. 'Amazon ElastiCache'.
* **page** (integer (int32)) - Optional: The page of results to return.
* **limit** (integer (int32)) - Optional: The amount of results to return. The maximum is 1000.
#### Responses
**200**: OK
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/costs/get-forecasted-costs-for-a-cost-report](https://docs.vantage.sh/api/costs/get-forecasted-costs-for-a-cost-report)
***
### GET /costs
**Get costs for cost report or VQL filter**
Return all Costs for a CostReport or VQL filter.
#### Query Parameters
* **cost\_report\_token** (string) - Optional: The CostReport token.
* **filter** (string) - Optional: The VQL filter to apply to the costs. If this is supplied you do not need cost\_report\_token.
* **workspace\_token** (string) - Optional: The token of the Workspace to query costs from. Ignored if 'cost\_report\_token' is set. Required if the API token is associated with multiple Workspaces.
* **start\_date** (string) - Optional: First date you would like to filter costs from. ISO 8601 formatted. When omitted with cost\_report\_token, the report's saved start date is used.
* **end\_date** (string) - Optional: Last date you would like to filter costs to. ISO 8601 formatted. When omitted with cost\_report\_token, the report's saved end date is used.
* **groupings** (array) - Optional: Group the results by specific field(s). When omitted with cost\_report\_token, the report's saved groupings are used; otherwise defaults to provider, service, account\_id. Valid groupings: account\_id, billing\_account\_id, charge\_type, cost\_category, cost\_subcategory, provider, region, resource\_id, service, tagged, usage\_unit, tag:tag\_value. If providing multiple groupings, join as comma separated values: groupings=provider,service,region
* **order** (string) - Optional: Whether to order costs by date in an ascending or descending manner.
* Allowed values: `asc`, `desc`
* Default: `desc`
* **limit** (integer (int32)) - Optional: The amount of results to return. The maximum is 5000.
* **page** (integer (int32)) - Optional: The page of results to return.
* **date\_bin** (string) - Optional: The date bin of the costs. Defaults to the report's default or day.
* Allowed values: `day`, `week`, `month`, `quarter`, `hour`
* **settings\[include\_credits]** (boolean) - Optional: Results will include credits.
* **settings\[include\_refunds]** (boolean) - Optional: Results will include refunds.
* **settings\[include\_discounts]** (boolean) - Optional: Results will include discounts.
* **settings\[include\_tax]** (boolean) - Optional: Results will include tax.
* **settings\[amortize]** (boolean) - Optional: Results will amortize.
* **settings\[unallocated]** (boolean) - Optional: Results will show unallocated costs.
* **settings\[aggregate\_by]** (string) - Optional: Results will aggregate by cost, usage, or count.
* Allowed values: `cost`, `usage`, `count`
* **settings\[show\_previous\_period]** (boolean) - Optional: Results will show previous period cost, usage, or count comparison.
#### Responses
**200**: OK
**400**: BadRequest
**402**: PaymentRequired
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/costs/get-costs-for-cost-report-or-vql-filter](https://docs.vantage.sh/api/costs/get-costs-for-cost-report-or-vql-filter)
***
### POST /costs/data\_exports
**Generate cost data export**
Generate a DataExport of costs.
#### Request Body
```json theme={null}
{
"cost_report_token": string // The CostReport token,
"filter": string // The VQL filter to apply to the costs. If this is supplied you do not need cost_report_token,
"workspace_token": string // The token of the Workspace to query costs from. Ignored if 'cost_report_token' is set. Required if the API token is associated with multiple Workspaces,
"start_date": string // First date you would like to filter costs from. ISO 8601 formatted. When omitted with cost_report_token, the report's saved start date is used,
"end_date": string // Last date you would like to filter costs to. ISO 8601 formatted. When omitted with cost_report_token, the report's saved end date is used,
"groupings": [string] // Group the results by specific field(s). When omitted with cost_report_token, the report's saved groupings are used; otherwise defaults to provider, service, account_id. Valid groupings: account_id, billing_account_id, charge_type, cost_category, cost_subcategory, provider, region, resource_id, service, tagged, usage_unit, tag:tag_value. If providing multiple groupings, join as comma separated values: groupings=provider,service,region,
"date_bin": string // The date bin of the costs. Defaults to the report's default or day. Allowed values: `day`, `week`, `month`, `quarter`, `hour`,
"schema": string // The schema of the data export. Allowed values: `vntg`, `focus`, `comparison`,
"settings": { // Cost-related settings
"include_credits": boolean // Results will include credits,
"include_refunds": boolean // Results will include refunds,
"include_discounts": boolean // Results will include discounts,
"include_tax": boolean // Results will include tax,
"amortize": boolean // Results will amortize,
"unallocated": boolean // Results will show unallocated costs,
"aggregate_by": string // Results will aggregate by cost, usage, or count. Allowed values: `cost`, `usage`, `count`,
"show_previous_period": boolean // Results will show previous period cost, usage, or count comparison
}
}
```
#### Responses
**202**: The data export has been queued and will be available at the location specified in the Location header.
**400**: BadRequest
**402**: PaymentRequired
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/costs/generate-cost-data-export](https://docs.vantage.sh/api/costs/generate-cost-data-export)
***
## DashboardNotifications
### GET /dashboard\_notifications
**Get all dashboard notifications**
Return all DashboardNotifications.
#### Query Parameters
* **page** (integer (int32)) - Optional: The page of results to return.
* **limit** (integer (int32)) - Optional: The amount of results to return. The maximum is 1000.
* **q** (string) - Optional: Search dashboard notifications by title.
#### Responses
**200**: OK
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/dashboardnotifications/get-all-dashboard-notifications](https://docs.vantage.sh/api/dashboardnotifications/get-all-dashboard-notifications)
***
### POST /dashboard\_notifications
**Create dashboard notification**
Create a DashboardNotification.
#### Request Body
```json theme={null}
{
"title": string // required // The title of the DashboardNotification,
"dashboard_token": string // required // The Dashboard token,
"workspace_token": string // The token of the Workspace to add the DashboardNotification to. Required if the API token is associated with multiple Workspaces,
"user_tokens": [string] // The Users that receive the notification,
"recipient_emails": [string] // Email addresses that receive the notification. Must be organization users, on the account's SSO domain, or an approved third-party service address,
"frequency": string // required // The frequency the DashboardNotification is sent. Possible values: daily, weekly, monthly. Allowed values: `daily`, `weekly`, `monthly`
}
```
#### Responses
**201**: Created
**400**: BadRequest
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/dashboardnotifications/create-dashboard-notification](https://docs.vantage.sh/api/dashboardnotifications/create-dashboard-notification)
***
### DELETE /dashboard\_notifications/
**Delete dashboard notification**
Delete a DashboardNotification.
#### Path Parameters
* **dashboard\_notification\_token** (path) (string) - **Required**
#### Responses
**204**: No Content
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/dashboardnotifications/delete-dashboard-notification](https://docs.vantage.sh/api/dashboardnotifications/delete-dashboard-notification)
***
### GET /dashboard\_notifications/
**Get dashboard notification by token**
Return a DashboardNotification.
#### Path Parameters
* **dashboard\_notification\_token** (path) (string) - **Required**
#### Responses
**200**: OK
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/dashboardnotifications/get-dashboard-notification-by-token](https://docs.vantage.sh/api/dashboardnotifications/get-dashboard-notification-by-token)
***
### PUT /dashboard\_notifications/
**Update dashboard notification**
Update a DashboardNotification.
#### Path Parameters
* **dashboard\_notification\_token** (path) (string) - **Required**
#### Request Body
```json theme={null}
{
"title": string // The title of the DashboardNotification,
"dashboard_token": string // The Dashboard token. Retargeting requires edit access to the new Dashboard,
"user_tokens": [string] // The Users that receive the notification,
"recipient_emails": [string] // Email addresses that receive the notification. Must be organization users, on the account's SSO domain, or an approved third-party service address,
"frequency": string // The frequency the DashboardNotification is sent. Possible values: daily, weekly, monthly. Allowed values: `daily`, `weekly`, `monthly`
}
```
#### Responses
**200**: OK
**400**: BadRequest
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/dashboardnotifications/update-dashboard-notification](https://docs.vantage.sh/api/dashboardnotifications/update-dashboard-notification)
***
## Dashboards
### GET /dashboards
**Get all dashboards**
Return all Dashboards.
#### Query Parameters
* **page** (integer (int32)) - Optional: The page of results to return.
* **limit** (integer (int32)) - Optional: The amount of results to return. The maximum is 1000.
* **q** (string) - Optional: Search dashboards by title.
* **workspace\_token** (string) - Optional: The workspace token of the dashboards to return.
#### Responses
**200**: OK
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/dashboards/get-all-dashboards](https://docs.vantage.sh/api/dashboards/get-all-dashboards)
***
### POST /dashboards
**Create dashboard**
Create a Dashboard.
#### Request Body
```json theme={null}
{
"title": string // required // The title of the Dashboard,
"widgets": [ // The widgets to add to the Dashboard. Report-backed widgets use widgetable_token. Free text widgets use widgetable_type set to free_text and require content
{
"widgetable_token": string // The token of the represented Resource,
"widgetable_type": string // The widget type. Use free_text for a free text widget. Allowed values: `free_text`,
"title": string // The title of the Widget (defaults to the Resource title, or Free Text for a free text widget),
"content": { // Rich-text document for a free text widget, for example {"type":"doc","content":[{"type":"paragraph","content":[{"type":"text","text":"Note"}]}]}
"type": string // required // Document root. Must be doc. Allowed values: `doc`,
"content": [object]
},
"settings": { // The display and grid layout settings for the DashboardWidget
"display_type": string // required // Allowed values: `table`, `chart`, `kpi`,
"kpi_calculation": string // The aggregation used when display_type is kpi. Allowed values: `sum`, `average`,
"kpi_type": string // The metric represented when display_type is kpi. Allowed values: `cost`, `usage`, `count`, `business_metric`,
"kpi_usage_unit": string // The usage unit represented when kpi_type is usage,
"grid": { // The widget's size and position in the dashboard's 12-column grid
"x": integer // required // The zero-based horizontal position,
"y": integer // required // The zero-based vertical position,
"w": integer // required // The widget width in grid columns,
"h": integer // required // The widget height in grid rows
}
}
}
],
"saved_filter_tokens": [string] // The tokens of the Saved Filters used in the Dashboard,
"date_bin": string // Determines how to group costs in the Dashboard. Allowed values: `cumulative`, `day`, `week`, `month`,
"date_interval": string // Determines the date range in the Dashboard. Incompatible with 'start_date' and 'end_date' parameters. Allowed values: `this_month`, `last_7_days`, `last_30_days`, `last_month`, `last_3_months`, `last_6_months`, `custom`, `last_12_months`, `last_24_months`, `last_36_months`, `next_month`, `next_3_months`, `next_6_months`, `next_12_months`, `year_to_date`, `last_3_days`, `last_14_days`,
"start_date": string // The start date for the date range for costs in the Dashboard. ISO 8601 Formatted. Incompatible with 'date_interval' parameter,
"end_date": string // The end date for the date range for costs in the Dashboard. ISO 8601 Formatted. Incompatible with 'date_interval' parameter,
"workspace_token": string // The token of the Workspace to add the Dashboard to. Required if the API token is associated with multiple Workspaces
}
```
#### Responses
**201**: Created
**400**: BadRequest
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/dashboards/create-dashboard](https://docs.vantage.sh/api/dashboards/create-dashboard)
***
### DELETE /dashboards/
**Delete dashboard**
Delete a Dashboard.
#### Path Parameters
* **dashboard\_token** (path) (string) - **Required**
#### Responses
**204**: No Content
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/dashboards/delete-dashboard](https://docs.vantage.sh/api/dashboards/delete-dashboard)
***
### GET /dashboards/
**Get dashboard by token**
Return a specific Dashboard.
#### Path Parameters
* **dashboard\_token** (path) (string) - **Required**
#### Responses
**200**: OK
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/dashboards/get-dashboard-by-token](https://docs.vantage.sh/api/dashboards/get-dashboard-by-token)
***
### PUT /dashboards/
**Update dashboard**
Update a Dashboard.
#### Path Parameters
* **dashboard\_token** (path) (string) - **Required**
#### Request Body
```json theme={null}
{
"title": string // The title of the Dashboard,
"widgets": [ // The complete replacement list of widgets for the Dashboard. Omit widgets or send null to preserve every existing widget. When provided, include every report-backed and free text widget to keep; an empty array removes all widgets. Report-backed widgets use widgetable_token. Free text widgets use widgetable_type set to free_text and require content
{
"widgetable_token": string // The token of the represented Resource,
"widgetable_type": string // The widget type. Use free_text for a free text widget. Allowed values: `free_text`,
"title": string // The title of the Widget (defaults to the Resource title, or Free Text for a free text widget),
"content": { // Rich-text document for a free text widget, for example {"type":"doc","content":[{"type":"paragraph","content":[{"type":"text","text":"Note"}]}]}
"type": string // required // Document root. Must be doc. Allowed values: `doc`,
"content": [object]
},
"settings": { // The display and grid layout settings for the DashboardWidget
"display_type": string // required // Allowed values: `table`, `chart`, `kpi`,
"kpi_calculation": string // The aggregation used when display_type is kpi. Allowed values: `sum`, `average`,
"kpi_type": string // The metric represented when display_type is kpi. Allowed values: `cost`, `usage`, `count`, `business_metric`,
"kpi_usage_unit": string // The usage unit represented when kpi_type is usage,
"grid": { // The widget's size and position in the dashboard's 12-column grid
"x": integer // required // The zero-based horizontal position,
"y": integer // required // The zero-based vertical position,
"w": integer // required // The widget width in grid columns,
"h": integer // required // The widget height in grid rows
}
}
}
],
"saved_filter_tokens": [string] // The tokens of the Saved Filters used in the Dashboard,
"date_bin": string // Determines how to group costs in the Dashboard. Allowed values: `cumulative`, `day`, `week`, `month`,
"date_interval": string // Determines the date range in the Dashboard. Incompatible with 'start_date' and 'end_date' parameters. Allowed values: `this_month`, `last_7_days`, `last_30_days`, `last_month`, `last_3_months`, `last_6_months`, `custom`, `last_12_months`, `last_24_months`, `last_36_months`, `next_month`, `next_3_months`, `next_6_months`, `next_12_months`, `year_to_date`, `last_3_days`, `last_14_days`, ``,
"start_date": string // The start date for the date range for costs in the Dashboard. ISO 8601 Formatted. Incompatible with 'date_interval' parameter,
"end_date": string // The end date for the date range for costs in the Dashboard. ISO 8601 Formatted. Incompatible with 'date_interval' parameter,
"workspace_token": string // The token of the Workspace the Dashboard belongs to. Required when updating widgets if the API token is associated with multiple Workspaces
}
```
#### Responses
**200**: OK
**400**: BadRequest
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/dashboards/update-dashboard](https://docs.vantage.sh/api/dashboards/update-dashboard)
***
### DELETE /widgets/
**Delete dashboard widget**
Delete a Dashboard Widget.
#### Path Parameters
* **widget\_token** (path) (string) - **Required**
#### Responses
**204**: No Content
**403**: Forbidden
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/dashboards/delete-dashboard-widget](https://docs.vantage.sh/api/dashboards/delete-dashboard-widget)
***
### GET /widgets/
**Get dashboard widget**
Return a Dashboard Widget.
#### Path Parameters
* **widget\_token** (path) (string) - **Required**
#### Responses
**200**: OK
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/dashboards/get-dashboard-widget](https://docs.vantage.sh/api/dashboards/get-dashboard-widget)
***
### PATCH /widgets/
**Update dashboard widget**
Update a single Dashboard Widget.
#### Path Parameters
* **widget\_token** (path) (string) - **Required**
#### Request Body
```json theme={null}
{
"widgetable_token": string // The token of the Resource represented by the Widget,
"title": string // The title of the Widget,
"settings": { // The settings for the DashboardWidget
"display_type": string // Allowed values: `table`, `chart`, `kpi`,
"kpi_calculation": string // Allowed values: `sum`, `average`,
"kpi_type": string // Allowed values: `cost`, `usage`, `count`, `business_metric`,
"kpi_usage_unit": string
}
}
```
#### Responses
**200**: OK
**400**: BadRequest
**403**: Forbidden
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/dashboards/update-dashboard-widget](https://docs.vantage.sh/api/dashboards/update-dashboard-widget)
***
## DataExports
### GET /data\_exports/
**Get status of data export**
Get the status of a data export.
#### Path Parameters
* **data\_export\_token** (path) (string) - **Required**
#### Responses
**200**: Returns the completed data export and its manifest. If it is still pending, the response will be a 202 and the caller should check the Location and Retry-After headers to determine where and how long to wait before polling again.
**400**: BadRequest
**402**: PaymentRequired
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/dataexports/get-status-of-data-export](https://docs.vantage.sh/api/dataexports/get-status-of-data-export)
***
## EnrichmentSources
### GET /enrichment\_sources
**Get all enrichment sources**
Return all EnrichmentSources.
#### Query Parameters
* **page** (integer (int32)) - Optional: The page of results to return.
* **limit** (integer (int32)) - Optional: The number of results to return. The maximum is 1000.
#### Responses
**200**: OK
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/enrichmentsources/get-all-enrichment-sources](https://docs.vantage.sh/api/enrichmentsources/get-all-enrichment-sources)
***
### GET /enrichment\_sources/
**Get enrichment source by token**
Return an EnrichmentSource.
#### Path Parameters
* **enrichment\_source\_token** (path) (string) - **Required**
#### Responses
**200**: OK
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/enrichmentsources/get-enrichment-source-by-token](https://docs.vantage.sh/api/enrichmentsources/get-enrichment-source-by-token)
***
## EnrichmentStatistics
### GET /enrichment\_sources//statistics
**Get enrichment statistics**
Return enrichment statistics.
#### Path Parameters
* **enrichment\_source\_token** (path) (string) - **Required**
#### Query Parameters
* **page** (integer (int32)) - Optional: The page of results to return.
* Default: `1`
* **limit** (integer (int32)) - Optional: The number of results to return. The maximum is 1000.
* Default: `50`
* **provider** (string) - Optional: Filter statistics to costs for a specific provider key.
* Allowed values: `aws`, `azure`, `gcp`, `snowflake`, `databricks`, `mongo`, `datadog`, `fastly`, `new_relic`, `opencost`, `open_ai`, `oracle`, `confluent`, `planetscale`, `coralogix`, `kubernetes`, `custom_provider`, `github`, `linode`, `grafana`, `clickhouse`, `temporal`, `twilio`, `azure_csp`, `kubernetes_agent`, `anthropic`, `anyscale`, `cursor`, `elastic`, `vercel`, `redis_cloud`, `circle_ci`, `modal`, `eleven_labs`, `baseten`, `cloudflare`, `fireworks_ai`, `cartesia`, `depot`, `xai`, `digital_ocean`, `together_ai`, `coreweave`, `devin`, `openrouter`, `deepgram`, `crusoe`, `sentry_billing`
* Example: `aws`
#### Responses
**200**: OK
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/enrichmentstatistics/get-enrichment-statistics](https://docs.vantage.sh/api/enrichmentstatistics/get-enrichment-statistics)
***
## ExchangeRates
### GET /exchange\_rates
**Get all exchange rates**
Return all Exchange Rates.
#### Query Parameters
* **page** (integer (int32)) - Optional: The page of results to return.
* **limit** (integer (int32)) - Optional: The number of results to return. The maximum is 1000.
#### Responses
**200**: OK
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/exchangerates/get-all-exchange-rates](https://docs.vantage.sh/api/exchangerates/get-all-exchange-rates)
***
### POST /exchange\_rates/csv
**Upload exchange rates via CSV**
Upload Exchange Rates via CSV.
#### Responses
**201**: CSV uploaded successfully
**400**: BadRequest
**403**: Forbidden
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/exchangerates/upload-exchange-rates-via-csv](https://docs.vantage.sh/api/exchangerates/upload-exchange-rates-via-csv)
***
## FinancialCommitmentReports
### GET /financial\_commitment\_reports
**Get all financial commitment reports**
Return all FinancialCommitmentReports.
#### Query Parameters
* **page** (integer (int32)) - Optional: The page of results to return.
* **limit** (integer (int32)) - Optional: The amount of results to return. The maximum is 1000.
* **q** (string) - Optional: Search financial commitment reports by title.
* **workspace\_token** (string) - Optional: The workspace token of the financial commitment reports to return.
#### Responses
**200**: OK
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/financialcommitmentreports/get-all-financial-commitment-reports](https://docs.vantage.sh/api/financialcommitmentreports/get-all-financial-commitment-reports)
***
### POST /financial\_commitment\_reports
**Create financial commitment report**
Create a FinancialCommitmentReport.
#### Request Body
```json theme={null}
{
"workspace_token": string // required // The Workspace in which the FinancialCommitmentReport will be created,
"title": string // required // The title of the FinancialCommitmentReport,
"filter": string // The filter query language to apply to the FinancialCommitmentReport. Additional documentation available at https://docs.vantage.sh/vql,
"start_date": string // The start date of the FinancialCommitmentReport. YYYY-MM-DD formatted. Incompatible with 'date_interval' parameter,
"end_date": string // The end date of the FinancialCommitmentReport. YYYY-MM-DD formatted. Incompatible with 'date_interval' parameter,
"date_interval": string // The date interval of the FinancialCommitmentReport. Unless 'custom' is used, this is incompatible with 'start_date' and 'end_date' parameters. Defaults to 'last_3_months'. Allowed values: `this_month`, `last_7_days`, `last_30_days`, `last_month`, `last_3_months`, `last_6_months`, `custom`, `last_12_months`, `last_24_months`, `last_36_months`, `year_to_date`, `last_3_days`, `last_14_days`,
"date_bucket": string // The date bucket of the FinancialCommitmentReport. Allowed values: `hour`, `day`, `week`, `month`, `quarter`,
"on_demand_costs_scope": string // The scope for the costs. Possible values: discountable, all. Allowed values: `discountable`, `all`,
"groupings": [string] // Grouping values for aggregating costs on the FinancialCommitmentReport. Group by up to 100 fields. Valid groupings: cost_type, provider, commitment_type, commitment_id, service, resource_account_id, provider_account_id, region, cost_category, cost_sub_category, instance_type, tag:label_name
}
```
#### Responses
**201**: Created
**400**: BadRequest
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/financialcommitmentreports/create-financial-commitment-report](https://docs.vantage.sh/api/financialcommitmentreports/create-financial-commitment-report)
***
### DELETE /financial\_commitment\_reports/
**Delete financial commitment report**
Delete a FinancialCommitmentReport.
#### Path Parameters
* **financial\_commitment\_report\_token** (path) (string) - **Required**
#### Responses
**204**: No Content
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/financialcommitmentreports/delete-financial-commitment-report](https://docs.vantage.sh/api/financialcommitmentreports/delete-financial-commitment-report)
***
### GET /financial\_commitment\_reports/
**Get financial commitment report by token**
Return a FinancialCommitmentReport.
#### Path Parameters
* **financial\_commitment\_report\_token** (path) (string) - **Required**
#### Responses
**200**: OK
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/financialcommitmentreports/get-financial-commitment-report-by-token](https://docs.vantage.sh/api/financialcommitmentreports/get-financial-commitment-report-by-token)
***
### PUT /financial\_commitment\_reports/
**Update financial commitment report**
Update a FinancialCommitmentReport.
#### Path Parameters
* **financial\_commitment\_report\_token** (path) (string) - **Required**
#### Request Body
```json theme={null}
{
"title": string // The title of the FinancialCommitmentReport,
"filter": string // The filter query language to apply to the FinancialCommitmentReport. Additional documentation available at https://docs.vantage.sh/vql,
"start_date": string // The start date of the FinancialCommitmentReport. YYYY-MM-DD formatted. Incompatible with 'date_interval' parameter,
"end_date": string // The end date of the FinancialCommitmentReport. YYYY-MM-DD formatted. Incompatible with 'date_interval' parameter,
"date_interval": string // The date interval of the FinancialCommitmentReport. Unless 'custom' is used, this is incompatible with 'start_date' and 'end_date' parameters. Defaults to 'last_3_months'. Allowed values: `this_month`, `last_7_days`, `last_30_days`, `last_month`, `last_3_months`, `last_6_months`, `custom`, `last_12_months`, `last_24_months`, `last_36_months`, `year_to_date`, `last_3_days`, `last_14_days`,
"date_bucket": string // The date bucket of the FinancialCommitmentReport. Allowed values: `hour`, `day`, `week`, `month`, `quarter`,
"on_demand_costs_scope": string // The scope for the costs. Possible values: discountable, all. Allowed values: `discountable`, `all`,
"groupings": [string] // Grouping values for aggregating costs on the FinancialCommitmentReport. Group by up to 100 fields. Valid groupings: cost_type, provider, commitment_type, commitment_id, service, resource_account_id, provider_account_id, region, cost_category, cost_sub_category, instance_type, tag:label_name
}
```
#### Responses
**200**: OK
**400**: BadRequest
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/financialcommitmentreports/update-financial-commitment-report](https://docs.vantage.sh/api/financialcommitmentreports/update-financial-commitment-report)
***
### GET /financial\_commitment\_reports//costs
**Get costs for financial commitment report**
Return costs for a FinancialCommitmentReport.
#### Path Parameters
* **financial\_commitment\_report\_token** (path) (string) - **Required**
#### Query Parameters
* **start\_date** (string (date)) - Optional: First date you would like to filter costs from, inclusive. YYYY-MM-DD formatted.
* Example: `2024-03-01`
* **end\_date** (string (date)) - Optional: Last date you would like to filter costs to, inclusive. YYYY-MM-DD formatted.
* Example: `2024-03-31`
* **date\_bin** (string) - Optional: The date bin of the costs. Defaults to the report's configured date bucket. Hourly costs are limited to 14 days.
* Allowed values: `hour`, `day`, `week`, `month`, `quarter`
* **groupings** (array) - Optional: Group the results by up to 100 fields. Valid groupings: cost\_type, provider, commitment\_type, commitment\_id, service, resource\_account\_id, provider\_account\_id, region, cost\_category, cost\_sub\_category, instance\_type, tag:label\_name. Serialize as a CSV query parameter: groupings=cost\_type,service. Repeated parameters (groupings\[]=cost\_type\&groupings\[]=service) are also accepted.
* **filter** (string) - Optional: The VQL filter to apply to the costs. Overrides the report's saved filter.
* **on\_demand\_costs\_scope** (string) - Optional: The scope for the costs. Possible values: discountable, all.
* Allowed values: `discountable`, `all`
* **order** (string) - Optional: Whether to order costs by date in an ascending or descending manner.
* Allowed values: `asc`, `desc`
* Default: `desc`
* **limit** (integer (int32)) - Optional: The number of cost rows to return, not the number of date buckets. The maximum is 5000.
* Default: `2500`
* **page** (integer (int32)) - Optional: The page of results to return.
* Default: `1`
#### Responses
**200**: OK
**400**: BadRequest
**402**: PaymentRequired
**404**: NotFound
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/financialcommitmentreports/get-costs-for-financial-commitment-report](https://docs.vantage.sh/api/financialcommitmentreports/get-costs-for-financial-commitment-report)
***
## FinancialCommitments
### GET /financial\_commitments
**Get all financial commitments**
Return all FinancialCommitments.
#### Query Parameters
* **page** (integer (int32)) - Optional: The page of results to return.
* **limit** (integer (int32)) - Optional: The amount of results to return. The maximum is 1000.
#### Responses
**200**: OK
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/financialcommitments/get-all-financial-commitments](https://docs.vantage.sh/api/financialcommitments/get-all-financial-commitments)
***
## Folders
### GET /folders
**Get all folders**
Return all Folders for CostReports.
#### Query Parameters
* **page** (integer (int32)) - Optional: The page of results to return.
* **limit** (integer (int32)) - Optional: The amount of results to return. The maximum is 1000.
* **type** (string) - Optional: Filter by folder type.
* Allowed values: `CostFolder`, `ProviderResourceFolder`
* **q** (string) - Optional: Search folders by title.
* **workspace\_token** (string) - Optional: The workspace token of the folders to return.
#### Responses
**200**: OK
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/folders/get-all-folders](https://docs.vantage.sh/api/folders/get-all-folders)
***
### POST /folders
**Create folder**
Create a Folder for CostReports.
#### Request Body
```json theme={null}
{
"title": string // required // The title of the Folder,
"parent_folder_token": string // The token of the parent Folder,
"saved_filter_tokens": [string] // The tokens of the SavedFilters to apply to any Cost Report contained within the Folder,
"workspace_token": string // The token of the Workspace to add the Folder to. Ignored if 'parent_folder_token' is set. Required if the API token is associated with multiple Workspaces,
"type": string // The type of the Folder. Allowed values: `CostFolder`, `ProviderResourceFolder`
}
```
#### Responses
**201**: Created
**400**: BadRequest
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/folders/create-folder](https://docs.vantage.sh/api/folders/create-folder)
***
### DELETE /folders/
**Delete folder**
Delete a Folder for CostReports.
#### Path Parameters
* **folder\_token** (path) (string) - **Required**
#### Responses
**204**: No Content
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/folders/delete-folder](https://docs.vantage.sh/api/folders/delete-folder)
***
### GET /folders/
**Get folder by token**
Return a specific Folder for CostReports.
#### Path Parameters
* **folder\_token** (path) (string) - **Required**
#### Responses
**200**: OK
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/folders/get-folder-by-token](https://docs.vantage.sh/api/folders/get-folder-by-token)
***
### PUT /folders/
**Update folder**
Update a Folder for CostReports.
#### Path Parameters
* **folder\_token** (path) (string) - **Required**
#### Request Body
```json theme={null}
{
"title": string // The title of the Folder,
"parent_folder_token": string // The token of the parent Folder,
"saved_filter_tokens": [string] // The tokens of the SavedFilters to apply to any Cost Report contained within the Folder
}
```
#### Responses
**200**: OK
**400**: BadRequest
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/folders/update-folder](https://docs.vantage.sh/api/folders/update-folder)
***
## Integrations
### GET /integrations
**Get all integrations**
Return all Integrations.
#### Query Parameters
* **provider** (string) - Optional: Query by provider name to list all Integrations for a specific provider.
* Allowed values: `aws`, `azure`, `gcp`, `snowflake`, `databricks`, `mongo`, `datadog`, `fastly`, `new_relic`, `opencost`, `open_ai`, `oracle`, `confluent`, `planetscale`, `coralogix`, `kubernetes`, `custom_provider`, `github`, `linode`, `grafana`, `clickhouse`, `temporal`, `twilio`, `azure_csp`, `kubernetes_agent`, `anthropic`, `anyscale`, `cursor`, `elastic`, `vercel`, `redis_cloud`, `circle_ci`, `modal`, `eleven_labs`, `baseten`, `cloudflare`, `fireworks_ai`, `cartesia`, `depot`, `xai`, `digital_ocean`, `together_ai`, `coreweave`, `devin`, `openrouter`, `deepgram`, `crusoe`, `sentry_billing`
* **account\_identifier** (string) - Optional: Query by account identifier to list all Integrations that match a specific account. For Azure, this is the subscription ID. Must include provider when using this parameter.
* **page** (integer (int32)) - Optional: The page of results to return.
* **limit** (integer (int32)) - Optional: The number of results to return. The maximum is 1000.
#### Responses
**200**: OK
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/integrations/get-all-integrations](https://docs.vantage.sh/api/integrations/get-all-integrations)
***
### POST /integrations/azure
**Create Azure integration**
Create an Azure Integration
#### Request Body
```json theme={null}
{
"tenant": string // required // Azure AD Tenant ID,
"app_id": string // required // Service Principal Application ID,
"password": string // required // Service Principal Password,
"billing_account_id": string // Microsoft Customer Agreement (MCA) or Enterprise Agreement (EA) billing account ID. Must not contain whitespace
}
```
#### Responses
**201**: Created
**400**: BadRequest
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/integrations/create-azure-integration](https://docs.vantage.sh/api/integrations/create-azure-integration)
***
### POST /integrations/custom\_provider
**Create custom provider integration**
Create a Custom Provider Integration
#### Request Body
```json theme={null}
{
"name": string // required // Name of the Custom Provider Integration,
"description": string // Description of the Custom Provider Integration
}
```
#### Responses
**201**: Created
**400**: BadRequest
**403**: Forbidden
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/integrations/create-custom-provider-integration](https://docs.vantage.sh/api/integrations/create-custom-provider-integration)
***
### POST /integrations/gcp
**Create GCP integration**
Create a GCP Integration
#### Request Body
```json theme={null}
{
"billing_account_id": string // required // GCP billing account ID,
"project_id": string // required // GCP project ID,
"dataset_name": string // required // BigQuery dataset name
}
```
#### Responses
**201**: Created
**400**: BadRequest
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/integrations/create-gcp-integration](https://docs.vantage.sh/api/integrations/create-gcp-integration)
***
### POST /integrations/twilio
**Create Twilio integration**
Create a Twilio Integration
#### Request Body
```json theme={null}
{
"api_key": string // required // Twilio API key SID,
"api_secret": string // required // Twilio API key secret,
"account_sid": string // required // Twilio account SID,
"friendly_account_name": string // required // Name for this Twilio account in Vantage,
"description": string // required // Description of the integration,
"is_oauth": boolean // When true, api_key and api_secret are an OAuth client id and secret
}
```
#### Responses
**201**: Created
**400**: BadRequest
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/integrations/create-twilio-integration](https://docs.vantage.sh/api/integrations/create-twilio-integration)
***
### DELETE /integrations/
**Delete integration**
Delete an Integration.
#### Path Parameters
* **integration\_token** (path) (string) - **Required**
#### Responses
**204**: No Content
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/integrations/delete-integration](https://docs.vantage.sh/api/integrations/delete-integration)
***
### GET /integrations/
**Get integration by token**
Return an Integration.
#### Path Parameters
* **integration\_token** (path) (string) - **Required**
#### Responses
**200**: OK
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/integrations/get-integration-by-token](https://docs.vantage.sh/api/integrations/get-integration-by-token)
***
### PUT /integrations/
**Update integration**
Update an Integration.
#### Path Parameters
* **integration\_token** (path) (string) - **Required**
#### Request Body
```json theme={null}
{
"workspace_tokens": [string] // The Workspace tokens to associate to the Integration
}
```
#### Responses
**200**: OK
**400**: BadRequest
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/integrations/update-integration](https://docs.vantage.sh/api/integrations/update-integration)
***
### GET /integrations//costs
**Get all user costs uploads**
List UserCostUploads.
#### Path Parameters
* **integration\_token** (path) (string) - **Required**
#### Responses
**200**: OK
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/integrations/get-all-user-costs-uploads](https://docs.vantage.sh/api/integrations/get-all-user-costs-uploads)
***
### POST /integrations//costs.csv
**Upload custom provider costs**
Create UserCostsUpload via CSV for a Custom Provider Integration.
#### Path Parameters
* **integration\_token** (path) (string) - **Required**
#### Responses
**201**: Created
**400**: BadRequest
**403**: Forbidden
**404**: NotFound
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/integrations/upload-custom-provider-costs](https://docs.vantage.sh/api/integrations/upload-custom-provider-costs)
***
### DELETE /integrations//costs/
**Delete user costs upload**
Delete a UserCostsUpload.
#### Path Parameters
* **integration\_token** (path) (string) - **Required**
* **user\_costs\_upload\_token** (path) (string) - **Required**: Token of the UserCostsUpload to delete.
#### Responses
**204**: No Content
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/integrations/delete-user-costs-upload](https://docs.vantage.sh/api/integrations/delete-user-costs-upload)
***
## Invoices
### GET /invoices
**Get all invoices**
Returns a list of invoices (MSP invoicing required).
#### Query Parameters
* **page** (integer (int32)) - Optional: The page of results to return.
* **limit** (integer (int32)) - Optional: The amount of results to return. The maximum is 1000.
* **managed\_account\_token** (string) - Optional: Filter invoices by managed account token (MSP accounts only)
#### Responses
**200**: OK
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/invoices/get-all-invoices](https://docs.vantage.sh/api/invoices/get-all-invoices)
***
### POST /invoices
**Create invoice**
Create an invoice (MSP accounts only).
#### Request Body
```json theme={null}
{
"billing_period_start": string // required // Start date of billing period (YYYY-MM-DD),
"billing_period_end": string // required // End date of billing period (YYYY-MM-DD),
"account_token": string // required // Token of the managed account to invoice
}
```
#### Responses
**201**: Created
**400**: BadRequest
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/invoices/create-invoice](https://docs.vantage.sh/api/invoices/create-invoice)
***
### GET /invoices/
**Get invoice by token**
Return an invoice.
#### Path Parameters
* **invoice\_token** (path) (string) - **Required**
#### Responses
**200**: OK
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/invoices/get-invoice-by-token](https://docs.vantage.sh/api/invoices/get-invoice-by-token)
***
### GET /invoices//cost\_report
**Get cost report URL**
Get cost report URL for invoice period.
#### Path Parameters
* **invoice\_token** (path) (string) - **Required**
#### Responses
**200**: Get cost report URL for invoice period.
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/invoices/get-cost-report-url](https://docs.vantage.sh/api/invoices/get-cost-report-url)
***
### POST /invoices//download
**Get invoice file**
Download invoice file (PDF or CSV).
#### Path Parameters
* **invoice\_token** (path) (string) - **Required**
#### Request Body
```json theme={null}
{
"file_type": string // required // Type of file to download (pdf or csv). Allowed values: `pdf`, `csv`
}
```
#### Responses
**200**: Returns download URL for the invoice file
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/invoices/get-invoice-file](https://docs.vantage.sh/api/invoices/get-invoice-file)
***
### POST /invoices//regenerate
**Regenerate invoice**
Regenerate an existing invoice (MSP accounts only).
#### Path Parameters
* **invoice\_token** (path) (string) - **Required**
#### Responses
**200**: Invoice regeneration started
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/invoices/regenerate-invoice](https://docs.vantage.sh/api/invoices/regenerate-invoice)
***
### POST /invoices//send
**Send invoice**
Send invoice via email.
#### Path Parameters
* **invoice\_token** (path) (string) - **Required**
#### Responses
**200**: Invoice sent successfully
**400**: BadRequest
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/invoices/send-invoice](https://docs.vantage.sh/api/invoices/send-invoice)
***
### POST /invoices//send\_and\_approve
**Send and approve invoice**
Send and approve invoice via email (MSP accounts only).
#### Path Parameters
* **invoice\_token** (path) (string) - **Required**
#### Responses
**200**: Invoice approved and sent successfully
**400**: BadRequest
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/invoices/send-and-approve-invoice](https://docs.vantage.sh/api/invoices/send-and-approve-invoice)
***
## KubernetesEfficiencyReports
### GET /kubernetes\_efficiency\_reports
**Get all Kubernetes efficiency reports**
Return all KubernetesEfficiencyReports.
#### Query Parameters
* **page** (integer (int32)) - Optional: The page of results to return.
* **limit** (integer (int32)) - Optional: The amount of results to return. The maximum is 1000.
* **workspace\_token** (string) - Optional: Filter by workspace token.
* **q** (string) - Optional: Search Kubernetes efficiency reports by title.
#### Responses
**200**: OK
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/kubernetesefficiencyreports/get-all-kubernetes-efficiency-reports](https://docs.vantage.sh/api/kubernetesefficiencyreports/get-all-kubernetes-efficiency-reports)
***
### POST /kubernetes\_efficiency\_reports
**Create Kubernetes efficiency report**
Create a KubernetesEfficiencyReport.
#### Request Body
```json theme={null}
{
"workspace_token": string // required // The Workspace in which the KubernetesEfficiencyReport will be created,
"title": string // required // The title of the KubernetesEfficiencyReport,
"filter": string // The filter query language to apply to the KubernetesEfficiencyReport. Additional documentation available at https://docs.vantage.sh/vql,
"start_date": string // The start date of the KubernetesEfficiencyReport. ISO 8601 Formatted. Incompatible with 'date_interval' parameter,
"end_date": string // The end date of the KubernetesEfficiencyReport. ISO 8601 Formatted. Incompatible with 'date_interval' parameter,
"date_interval": string // The date interval of the KubernetesEfficiencyReport. Incompatible with 'start_date' and 'end_date' parameters. Defaults to 'this_month' if start_date and end_date are not provided. Allowed values: `this_month`, `last_7_days`, `last_30_days`, `last_month`, `last_3_months`, `last_6_months`, `custom`, `last_12_months`, `last_24_months`, `last_36_months`, `next_month`, `next_3_months`, `next_6_months`, `next_12_months`, `year_to_date`, `last_3_days`, `last_14_days`,
"aggregated_by": string // The column by which the costs are aggregated. Allowed values: `idle_cost`, `amount`, `cost_efficiency`,
"date_bucket": string // The date bucket of the KubernetesEfficiencyReport. Allowed values: `day`, `week`, `month`, `quarter`,
"groupings": [string] // Grouping values for aggregating costs on the KubernetesEfficiencyReport. Group by up to 100 fields. Valid groupings: cluster_id, namespace, region, labeled, category, pod, label:label_name
}
```
#### Responses
**201**: Created
**400**: BadRequest
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/kubernetesefficiencyreports/create-kubernetes-efficiency-report](https://docs.vantage.sh/api/kubernetesefficiencyreports/create-kubernetes-efficiency-report)
***
### POST /kubernetes\_efficiency\_reports/data\_exports
**Generate Kubernetes efficiency data export**
Generate a DataExport of Kubernetes efficiency data.
#### Query Parameters
* **groupings** (array) - Optional: Group the results by up to 100 fields. Valid groupings: cluster\_id, namespace, region, labeled, category, pod, label:label\_name.
#### Request Body
```json theme={null}
{
"kubernetes_efficiency_report_token": string // The KubernetesEfficiencyReport token. If not provided, the default report for the workspace will be used,
"filter": string // The filter query language to apply to the KubernetesEfficiencyReport. Additional documentation available at https://docs.vantage.sh/vql,
"workspace_token": string // The token of the Workspace to export data from. Ignored if 'kubernetes_efficiency_report_token' is set. Required if the API token is associated with multiple Workspaces,
"start_date": string // First date you would like to filter data from. ISO 8601 formatted,
"end_date": string // Last date you would like to filter data to. ISO 8601 formatted,
"date_bin": string // The date bin of the data. Defaults to the report's default or day. Allowed values: `day`, `week`, `month`, `quarter`
}
```
#### Responses
**202**: The data export has been queued and will be available at the location specified in the Location header.
**400**: BadRequest
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/kubernetesefficiencyreports/generate-kubernetes-efficiency-data-export](https://docs.vantage.sh/api/kubernetesefficiencyreports/generate-kubernetes-efficiency-data-export)
***
### DELETE /kubernetes\_efficiency\_reports/
**Delete Kubernetes efficiency report**
Delete a KubernetesEfficiencyReport.
#### Path Parameters
* **kubernetes\_efficiency\_report\_token** (path) (string) - **Required**
#### Responses
**204**: No Content
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/kubernetesefficiencyreports/delete-kubernetes-efficiency-report](https://docs.vantage.sh/api/kubernetesefficiencyreports/delete-kubernetes-efficiency-report)
***
### GET /kubernetes\_efficiency\_reports/
**Get Kubernetes efficiency report by token**
Return a KubernetesEfficiencyReport.
#### Path Parameters
* **kubernetes\_efficiency\_report\_token** (path) (string) - **Required**
#### Responses
**200**: OK
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/kubernetesefficiencyreports/get-kubernetes-efficiency-report-by-token](https://docs.vantage.sh/api/kubernetesefficiencyreports/get-kubernetes-efficiency-report-by-token)
***
### PUT /kubernetes\_efficiency\_reports/
**Update Kubernetes efficiency report**
Update a KubernetesEfficiencyReport.
#### Path Parameters
* **kubernetes\_efficiency\_report\_token** (path) (string) - **Required**
#### Request Body
```json theme={null}
{
"title": string // The title of the KubernetesEfficiencyReport,
"filter": string // The filter query language to apply to the KubernetesEfficiencyReport. Additional documentation available at https://docs.vantage.sh/vql,
"start_date": string // The start date of the KubernetesEfficiencyReport. ISO 8601 Formatted. Incompatible with 'date_interval' parameter,
"end_date": string // The end date of the KubernetesEfficiencyReport. ISO 8601 Formatted. Incompatible with 'date_interval' parameter,
"date_interval": string // The date interval of the KubernetesEfficiencyReport. Incompatible with 'start_date' and 'end_date' parameters. Defaults to 'this_month' if start_date and end_date are not provided. Allowed values: `this_month`, `last_7_days`, `last_30_days`, `last_month`, `last_3_months`, `last_6_months`, `custom`, `last_12_months`, `last_24_months`, `last_36_months`, `next_month`, `next_3_months`, `next_6_months`, `next_12_months`, `year_to_date`, `last_3_days`, `last_14_days`,
"aggregated_by": string // The column by which the costs are aggregated. Allowed values: `idle_cost`, `amount`, `cost_efficiency`,
"date_bucket": string // The date bucket of the KubernetesEfficiencyReport. Allowed values: `day`, `week`, `month`, `quarter`,
"groupings": [string] // Grouping values for aggregating costs on the KubernetesEfficiencyReport. Group by up to 100 fields. Valid groupings: cluster_id, namespace, region, labeled, category, pod, label:label_name
}
```
#### Responses
**200**: OK
**400**: BadRequest
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/kubernetesefficiencyreports/update-kubernetes-efficiency-report](https://docs.vantage.sh/api/kubernetesefficiencyreports/update-kubernetes-efficiency-report)
***
### GET /kubernetes\_efficiency\_reports//costs
**Get costs for Kubernetes efficiency report**
Return costs for a KubernetesEfficiencyReport.
#### Path Parameters
* **kubernetes\_efficiency\_report\_token** (path) (string) - **Required**
#### Query Parameters
* **start\_date** (string (date)) - Optional: First date to query costs from, inclusive. YYYY-MM-DD formatted.
* Example: `2026-09-01`
* **end\_date** (string (date)) - Optional: Last date to query costs through, inclusive. YYYY-MM-DD formatted.
* Example: `2026-09-30`
* **date\_bin** (string) - Optional: The date bin for the costs. Defaults to the report's configured date bucket.
* Allowed values: `day`, `week`, `month`, `quarter`
* **groupings** (array) - Optional: Group the cost rows by up to 100 fields. Valid groupings: cluster\_id, namespace, region, labeled, category, pod, label:label\_name.
* **filter** (string) - Optional: The VQL filter to apply to the costs. Overrides the report's saved filter.
* **order** (string) - Optional: Whether to order cost rows by date ascending or descending.
* Allowed values: `asc`, `desc`
* Default: `desc`
* **page** (integer (int32)) - Optional: The page of cost rows to return.
* Default: `1`
* **limit** (integer (int32)) - Optional: The number of cost rows to return. The maximum is 2500.
* Default: `500`
#### Responses
**200**: OK
**400**: BadRequest
**402**: PaymentRequired
**404**: NotFound
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/kubernetesefficiencyreports/get-costs-for-kubernetes-efficiency-report](https://docs.vantage.sh/api/kubernetesefficiencyreports/get-costs-for-kubernetes-efficiency-report)
***
## ManagedAccounts
### GET /managed\_accounts
**Get all managed accounts**
Returns a list of managed accounts.
#### Query Parameters
* **page** (integer (int32)) - Optional: The page of results to return.
* **limit** (integer (int32)) - Optional: The amount of results to return. The maximum is 1000.
#### Responses
**200**: OK
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/managedaccounts/get-all-managed-accounts](https://docs.vantage.sh/api/managedaccounts/get-all-managed-accounts)
***
### POST /managed\_accounts
**Create managed account**
Create a Managed Account.
#### Request Body
```json theme={null}
{
"name": string // required // The name of the Managed Account,
"contact_email": string // required // The contact email address for the Managed Account,
"access_credential_tokens": [string] // Access Credential (aka Integrations) tokens to assign to the Managed Account,
"billing_rule_tokens": [string] // Billing Rule tokens to assign to the Managed Account, in their desired execution order. Tokens must be ordered by execution group: AWS transforms, then COST inserts, then COST transforms, then monthly post-transform inserts. Within a group any order is accepted and persisted as-is. Submitting a list whose cross-group ordering does not match the pipeline returns a 400.Existing rules with apply_to_all enabled will be added implicity to the end of their execution group,
"email_domain": string // Email domain to associate with this Managed Account for SSO
}
```
#### Responses
**201**: Created
**400**: BadRequest
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/managedaccounts/create-managed-account](https://docs.vantage.sh/api/managedaccounts/create-managed-account)
***
### DELETE /managed\_accounts/
**Delete managed account**
Delete a Managed Account.
#### Path Parameters
* **managed\_account\_token** (path) (string) - **Required**
#### Responses
**204**: No Content
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/managedaccounts/delete-managed-account](https://docs.vantage.sh/api/managedaccounts/delete-managed-account)
***
### GET /managed\_accounts/
**Get managed account by token**
Return a Managed Account.
#### Path Parameters
* **managed\_account\_token** (path) (string) - **Required**
#### Responses
**200**: OK
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/managedaccounts/get-managed-account-by-token](https://docs.vantage.sh/api/managedaccounts/get-managed-account-by-token)
***
### PUT /managed\_accounts/
**Update managed account**
Update a Managed Account.
#### Path Parameters
* **managed\_account\_token** (path) (string) - **Required**
#### Request Body
```json theme={null}
{
"name": string // The name of the Managed Account,
"contact_email": string // The contact email address for the Managed Account,
"access_credential_tokens": [string] // Access Credential (aka Integrations) tokens to assign to the Managed Account,
"billing_rule_tokens": [string] // Billing Rule tokens to assign to the Managed Account, in their desired execution order. Tokens must be ordered by execution group: AWS transforms, then COST inserts, then COST transforms, then monthly post-transform inserts. Within a group any order is accepted and persisted as-is. Submitting a list whose cross-group ordering does not match the pipeline returns a 400,
"email_domain": string // Email domain to associate with this Managed Account for SSO,
"msp_billing_profile_token": string // Token of the MSP billing profile to use for this managed account (MSP invoicing accounts only),
"payment_terms_days": integer // Number of days until payment is due after invoice date (MSP invoicing accounts only). Defaults to 10,
"include_managed_account_integrations": boolean // Whether to include managed account's own integrations in invoice cost calculations (MSP invoicing accounts only). Defaults to false,
"billing_information_attributes": { // Billing address and contact information (MSP invoicing accounts only)
"id": integer,
"token": string,
"company_name": string // Company name for billing,
"country_code": string // ISO country code,
"address_line_1": string // First line of billing address,
"address_line_2": string // Second line of billing address,
"city": string // City for billing address,
"state": string // State or province for billing address,
"postal_code": string // Postal or ZIP code,
"billing_email": [string] // Array of billing email addresses
},
"business_information_attributes": { // Business information and custom fields (MSP invoicing accounts only)
"id": integer,
"token": string,
"metadata": { // Business metadata including custom fields
"custom_fields": [ // Array of custom field objects
{
"name": string // Custom field name,
"value": string // Custom field value
}
]
}
}
}
```
#### Responses
**200**: OK
**400**: BadRequest
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/managedaccounts/update-managed-account](https://docs.vantage.sh/api/managedaccounts/update-managed-account)
***
### GET /managed\_accounts//integrations/
**Get managed account integration**
Returns the Integration delegated to this Managed Account from the Access Credential named in the path, along with the provider account identifiers it imports. Delegate an Access Credential to a Managed Account with access\_credential\_tokens before calling this.
#### Path Parameters
* **managed\_account\_token** (path) (string) - **Required**
* **access\_credential\_token** (path) (string) - **Required**
#### Responses
**200**: OK
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/managedaccounts/get-managed-account-integration](https://docs.vantage.sh/api/managedaccounts/get-managed-account-integration)
***
### PUT /managed\_accounts//integrations/
**Update managed account integration**
Replaces the provider account identifiers a delegated Integration imports. An empty array applies no filter, so every provider account the Access Credential can see is imported. Identifiers are only accepted for providers that support scoping a delegation. Azure CSP uses subscription ids and GCP uses project ids. Stop delegating an Integration by removing its token from access\_credential\_tokens on the Managed Account.
#### Path Parameters
* **managed\_account\_token** (path) (string) - **Required**
* **access\_credential\_token** (path) (string) - **Required**
#### Request Body
```json theme={null}
{
"provider_account_identifiers": [string] // required // The provider account identifiers this delegated Integration should import, replacing the current list. For Azure CSP these are subscription ids and for GCP these are project ids. An empty array applies no filter
}
```
#### Responses
**200**: OK
**400**: BadRequest
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/managedaccounts/update-managed-account-integration](https://docs.vantage.sh/api/managedaccounts/update-managed-account-integration)
***
### DELETE /managed\_accounts//sso\_connection
**Delete SSO connection for managed account**
Delete SSO connection for a Managed Account.
#### Path Parameters
* **managed\_account\_token** (path) (string) - **Required**
#### Responses
**204**: No Content
**400**: BadRequest
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/managedaccounts/delete-sso-connection-for-managed-account](https://docs.vantage.sh/api/managedaccounts/delete-sso-connection-for-managed-account)
***
### POST /managed\_accounts//sso\_connection
**Configure SSO for managed account**
Configure SSO for a Managed Account.
#### Path Parameters
* **managed\_account\_token** (path) (string) - **Required**
#### Request Body
```json theme={null}
{
"type": string // required // The type of SSO connection. Currently supported: saml. Allowed values: `saml`,
"saml_metadata_url": string // The SAML metadata URL for the identity provider. Required when type is saml,
"additional_domains": [string] // Additional email domains to associate with this SSO configuration. The account's SSO domain is always included
}
```
#### Responses
**201**: Created
**400**: BadRequest
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/managedaccounts/configure-sso-for-managed-account](https://docs.vantage.sh/api/managedaccounts/configure-sso-for-managed-account)
***
### PUT /managed\_accounts//sso\_connection
**Update SSO configuration for managed account**
Update SSO configuration for a Managed Account.
#### Path Parameters
* **managed\_account\_token** (path) (string) - **Required**
#### Request Body
```json theme={null}
{
"saml_metadata_url": string // The SAML metadata URL for the identity provider,
"additional_domains": [string] // Additional email domains to associate with this SSO configuration. Replaces existing additional domains. The account's SSO domain is always preserved
}
```
#### Responses
**200**: OK
**400**: BadRequest
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/managedaccounts/update-sso-configuration-for-managed-account](https://docs.vantage.sh/api/managedaccounts/update-sso-configuration-for-managed-account)
***
## Me
### GET /me
**Get authenticated user info**
Get information about the authenticated BearerToken.
#### Responses
**200**: General information about the user.
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/me/get-authenticated-user-info](https://docs.vantage.sh/api/me/get-authenticated-user-info)
***
### PUT /me
**Update authenticated user**
Update the authenticated User.
#### Request Body
```json theme={null}
{
"default_dashboard_token": string // The token of a Dashboard to set as the User default. Send null to clear
}
```
#### Responses
**200**: OK
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/me/update-authenticated-user](https://docs.vantage.sh/api/me/update-authenticated-user)
***
## NetworkFlowLogs
### GET /network\_flow\_logs
**Get network flow logs**
Return aggregated Network Flow Logs for a saved report or ad hoc VQL query.
#### Query Parameters
* **network\_flow\_report\_token** (string) - Optional
* **workspace\_token** (string) - Optional
* **filter** (string) - Optional
* **date\_interval** (string) - Optional
* Allowed values: `last_3_days`, `last_7_days`, `last_14_days`, `last_30_days`
* **start\_date** (string (date)) - Optional
* **end\_date** (string (date)) - Optional
* **groupings** (array) - Optional
* **flow\_direction** (string) - Optional
* Allowed values: `all`, `ingress`, `egress`
* **flow\_weight** (string) - Optional
* Allowed values: `costs`, `bytes`
* **page** (integer (int32)) - Optional
* Default: `1`
* **limit** (integer (int32)) - Optional
* Default: `100`
#### Responses
**200**: OK
**400**: BadRequest
**402**: PaymentRequired
**404**: NotFound
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/networkflowlogs/get-network-flow-logs](https://docs.vantage.sh/api/networkflowlogs/get-network-flow-logs)
***
## NetworkFlowReports
### GET /network\_flow\_reports
**Get all network flow reports**
Return all NetworkFlowReports.
#### Query Parameters
* **q** (string) - Optional: A search query to filter NetworkFlowReports by title.
* **workspace\_token** (string) - Optional: Filter by workspace token.
* **page** (integer (int32)) - Optional: The page of results to return.
* **limit** (integer (int32)) - Optional: The amount of results to return. The maximum is 1000.
#### Responses
**200**: OK
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/networkflowreports/get-all-network-flow-reports](https://docs.vantage.sh/api/networkflowreports/get-all-network-flow-reports)
***
### POST /network\_flow\_reports
**Create network flow report**
Create a NetworkFlowReport.
#### Request Body
```json theme={null}
{
"workspace_token": string // required // The Workspace in which the NetworkFlowReport will be created,
"title": string // required // The title of the NetworkFlowReport,
"filter": string // The filter query language to apply to the NetworkFlowReport. Additional documentation available at https://docs.vantage.sh/vql,
"start_date": string // The start date of a custom NetworkFlowReport. YYYY-MM-DD formatted,
"end_date": string // The end date of a custom NetworkFlowReport. YYYY-MM-DD formatted,
"date_interval": string // The date interval of the NetworkFlowReport. Dates are used only for the 'custom' interval. Defaults to 'last_7_days'. Allowed values: `last_3_days`, `last_7_days`, `last_14_days`, `last_30_days`, `custom`,
"groupings": [string] // Grouping values for aggregating data on the NetworkFlowReport. Valid groupings: account_id, az_id, dstaddr, dsthostname, flow_direction, interface_id, instance_id, peer_resource_uuid, peer_account_id, peer_vpc_id, peer_region, peer_az_id, peer_subnet_id, peer_interface_id, peer_instance_id, region, resource_uuid, srcaddr, srchostname, subnet_id, traffic_category, traffic_path, vpc_id,
"flow_direction": string // The flow direction of the NetworkFlowReport. Allowed values: `all`, `ingress`, `egress`,
"flow_weight": string // The dimension by which the logs in the report are sorted. Defaults to costs. Allowed values: `costs`, `bytes`
}
```
#### Responses
**201**: Created
**400**: BadRequest
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/networkflowreports/create-network-flow-report](https://docs.vantage.sh/api/networkflowreports/create-network-flow-report)
***
### DELETE /network\_flow\_reports/
**Delete network flow report**
Delete a NetworkFlowReport.
#### Path Parameters
* **network\_flow\_report\_token** (path) (string) - **Required**
#### Responses
**204**: No Content
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/networkflowreports/delete-network-flow-report](https://docs.vantage.sh/api/networkflowreports/delete-network-flow-report)
***
### GET /network\_flow\_reports/
**Get network flow report by token**
Return a NetworkFlowReport.
#### Path Parameters
* **network\_flow\_report\_token** (path) (string) - **Required**
#### Responses
**200**: OK
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/networkflowreports/get-network-flow-report-by-token](https://docs.vantage.sh/api/networkflowreports/get-network-flow-report-by-token)
***
### PUT /network\_flow\_reports/
**Update network flow report**
Update a NetworkFlowReport.
#### Path Parameters
* **network\_flow\_report\_token** (path) (string) - **Required**
#### Request Body
```json theme={null}
{
"title": string // The title of the NetworkFlowReport,
"filter": string // The filter query language to apply to the NetworkFlowReport. Additional documentation available at https://docs.vantage.sh/vql,
"start_date": string // The start date of a custom NetworkFlowReport. YYYY-MM-DD formatted,
"end_date": string // The end date of a custom NetworkFlowReport. YYYY-MM-DD formatted,
"date_interval": string // The date interval of the NetworkFlowReport. Dates are used only for the 'custom' interval. Defaults to 'last_7_days'. Allowed values: `last_3_days`, `last_7_days`, `last_14_days`, `last_30_days`, `custom`,
"groupings": [string] // Grouping values for aggregating data on the NetworkFlowReport. Valid groupings: account_id, az_id, dstaddr, dsthostname, flow_direction, interface_id, instance_id, peer_resource_uuid, peer_account_id, peer_vpc_id, peer_region, peer_az_id, peer_subnet_id, peer_interface_id, peer_instance_id, region, resource_uuid, srcaddr, srchostname, subnet_id, traffic_category, traffic_path, vpc_id,
"flow_direction": string // The flow direction of the NetworkFlowReport. Allowed values: `all`, `ingress`, `egress`,
"flow_weight": string // The dimension by which the logs in the report are sorted. Defaults to costs. Allowed values: `costs`, `bytes`
}
```
#### Responses
**200**: OK
**400**: BadRequest
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/networkflowreports/update-network-flow-report](https://docs.vantage.sh/api/networkflowreports/update-network-flow-report)
***
## Ping
### GET /ping
This is a health check endpoint that can be used to determine Vantage API healthiness. It will return 200 if everything is running smoothly.
#### Responses
**200**: This is a health check endpoint that can be used to determine Vantage API healthiness. It will return 200 if everything is running smoothly.
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/ping/](https://docs.vantage.sh/api/ping/)
***
## Prices
### GET /products
**Get all products**
Return available Products for a Service. For example, with a Provider of AWS and a Service of EC2, Products will be a list of all EC2 Instances. By default, this endpoint returns all Products across all Services and Providers but has optional query parameters for filtering listed below.
#### Query Parameters
* **provider\_id** (string) - Optional: Query by Provider to list all Products across all Services for a Provider. e.g. aws
* **service\_id** (string) - Optional: Query by Service to list all Products for a specific provider service. e.g. aws-ec2
* **name** (string) - Optional: Query by name of the Product to see a list of products which match that name. e.g. m5a.16xlarge
* **page** (integer (int32)) - Optional: The page of results to return.
* **limit** (integer (int32)) - Optional: The amount of results to return. The maximum is 1000
#### Responses
**200**: OK
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/prices/get-all-products](https://docs.vantage.sh/api/prices/get-all-products)
***
### GET /products/
**Get product by ID**
Return a product
#### Path Parameters
* **id** (path) (string) - **Required**
#### Responses
**200**: OK
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/prices/get-product-by-id](https://docs.vantage.sh/api/prices/get-product-by-id)
***
### GET /products//prices
**Get prices for a product**
Return available Prices across all Regions for a Product.
#### Path Parameters
* **product\_id** (path) (string) - **Required**
#### Query Parameters
* **page** (integer (int32)) - Optional: The page of results to return.
* **limit** (integer (int32)) - Optional: The amount of results to return. The maximum is 1000
#### Responses
**200**: OK
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/prices/get-prices-for-a-product](https://docs.vantage.sh/api/prices/get-prices-for-a-product)
***
### GET /products//prices/
**Get price by ID**
Returns a price
#### Path Parameters
* **product\_id** (path) (string) - **Required**
* **id** (path) (string) - **Required**
#### Responses
**200**: OK
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/prices/get-price-by-id](https://docs.vantage.sh/api/prices/get-price-by-id)
***
## RecommendationViews
### GET /recommendation\_views
**Get all recommendation views**
Return all RecommendationViews.
#### Query Parameters
* **page** (integer (int32)) - Optional: The page of results to return.
* **limit** (integer (int32)) - Optional: The amount of results to return. The maximum is 1000.
* **workspace\_token** (string) - Optional: Filter by workspace token.
* **q** (string) - Optional: Search recommendation views by title.
#### Responses
**200**: OK
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/recommendationviews/get-all-recommendation-views](https://docs.vantage.sh/api/recommendationviews/get-all-recommendation-views)
***
### POST /recommendation\_views
**Create recommendation view**
Create a RecommendationView.
#### Request Body
```json theme={null}
{
"title": string // required // The title of the RecommendationView,
"workspace_token": string // required // The Workspace to associate the RecommendationView with,
"provider_ids": [string] // Filter by one or more providers (e.g. aws, gcp, azure, kubernetes, datadog),
"billing_account_ids": [string] // Filter by billing account identifiers,
"account_ids": [string] // Filter by cloud account identifiers,
"regions": [string] // Filter by region slugs (e.g. us-east-1, eastus, asia-east1),
"types": [string] // Filter by one or more recommendation type slugs,
"tag_key": string // Filter by tag key (must be used with tag_value),
"tag_value": string // Filter by tag value (requires tag_key),
"start_date": string // Filter recommendations created on/after this YYYY-MM-DD date,
"end_date": string // Filter recommendations created on/before this YYYY-MM-DD date,
"min_savings": number // Filter recommendations with at least this amount of potential savings
}
```
#### Responses
**201**: Created
**400**: BadRequest
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/recommendationviews/create-recommendation-view](https://docs.vantage.sh/api/recommendationviews/create-recommendation-view)
***
### DELETE /recommendation\_views/
**Delete recommendation view**
Delete a RecommendationView.
#### Path Parameters
* **recommendation\_view\_token** (path) (string) - **Required**
#### Responses
**204**: No Content
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/recommendationviews/delete-recommendation-view](https://docs.vantage.sh/api/recommendationviews/delete-recommendation-view)
***
### GET /recommendation\_views/
**Get recommendation view by token**
Return a specific RecommendationView.
#### Path Parameters
* **recommendation\_view\_token** (path) (string) - **Required**
#### Responses
**200**: OK
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/recommendationviews/get-recommendation-view-by-token](https://docs.vantage.sh/api/recommendationviews/get-recommendation-view-by-token)
***
### PUT /recommendation\_views/
**Update recommendation view**
Update a RecommendationView.
#### Path Parameters
* **recommendation\_view\_token** (path) (string) - **Required**
#### Request Body
```json theme={null}
{
"title": string // The title of the RecommendationView,
"provider_ids": [string] // Filter by one or more providers (e.g. aws, gcp, azure, kubernetes, datadog),
"billing_account_ids": [string] // Filter by billing account identifiers,
"account_ids": [string] // Filter by cloud account identifiers,
"regions": [string] // Filter by region slugs (e.g. us-east-1, eastus, asia-east1),
"types": [string] // Filter by one or more recommendation type slugs,
"tag_key": string // Filter by tag key (must be used with tag_value),
"tag_value": string // Filter by tag value (requires tag_key),
"start_date": string // Filter recommendations created on/after this YYYY-MM-DD date,
"end_date": string // Filter recommendations created on/before this YYYY-MM-DD date,
"min_savings": number // Filter recommendations with at least this amount of potential savings
}
```
#### Responses
**200**: OK
**400**: BadRequest
**404**: NotFound
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/recommendationviews/update-recommendation-view](https://docs.vantage.sh/api/recommendationviews/update-recommendation-view)
***
## Recommendations
### GET /recommendations
**Get all recommendations**
Return all Recommendations. Use the `type` query parameter with a fuzzy fragment to filter recommendation type case-insensitively (for example: aws, aws:ec2, aws:ec2:rightsizing).
#### Query Parameters
* **provider\_ids** (array) - Optional: Filter by one or more providers. Requires workspace\_token.
* **billing\_account\_ids** (array) - Optional: Filter by billing account identifiers. Requires workspace\_token.
* **account\_ids** (array) - Optional: Filter by account identifiers. Requires workspace\_token.
* **regions** (array) - Optional: Filter by region slugs (e.g. us-east-1, eastus, asia-east1). Requires workspace\_token.
* **tag\_key** (string) - Optional: Filter by tag key (must be used with tag\_value). Requires workspace\_token.
* **tag\_value** (string) - Optional: Filter by tag value (requires tag\_key). Requires workspace\_token.
* **start\_date** (string) - Optional: Filter recommendations created on/after this YYYY-MM-DD date. Requires workspace\_token.
* **end\_date** (string) - Optional: Filter recommendations created on/before this YYYY-MM-DD date. Requires workspace\_token.
* **status** (string) - Optional: Filter by status.
* Allowed values: `active`, `archived`
* **min\_savings** (number (float)) - Optional: Filter by recommendations whose potential savings are greater than or equal to this amount, in the workspace's currency. Requires workspace\_token.
* **page** (integer (int32)) - Optional: The page of results to return.
* **limit** (integer (int32)) - Optional: The number of results to return. The maximum is 1000.
* **workspace\_token** (string) - Optional: Filter by workspace.
* **provider\_account\_id** (string) - Optional: Filter by provider account id (AWS account, Azure subscription id, etc).
* **category** (string) - Optional: Filter by exact recommendation category. Ignored when type is provided.
* **type** (string) - Optional: Fuzzy filter by recommendation type using a case-insensitive literal substring. Examples: aws, aws:ec2, aws:ec2:rightsizing.
* **provider** (string) - Optional: Filter by provider.
* Allowed values: `aws`, `gcp`, `azure`, `kubernetes`, `datadog`
#### Responses
**200**: OK
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/recommendations/get-all-recommendations](https://docs.vantage.sh/api/recommendations/get-all-recommendations)
***
### GET /recommendations/by\_type//resources
**Get all resources for a recommendation type**
Return all Active Resources associated with recommendations of the specified type.
#### Path Parameters
* **type** (path) (string) - **Required**
#### Query Parameters
* **provider\_ids** (array) - Optional: Filter by one or more providers. Requires workspace\_token.
* **billing\_account\_ids** (array) - Optional: Filter by billing account identifiers. Requires workspace\_token.
* **account\_ids** (array) - Optional: Filter by account identifiers. Requires workspace\_token.
* **regions** (array) - Optional: Filter by region slugs (e.g. us-east-1, eastus, asia-east1). Requires workspace\_token.
* **tag\_key** (string) - Optional: Filter by tag key (must be used with tag\_value). Requires workspace\_token.
* **tag\_value** (string) - Optional: Filter by tag value (requires tag\_key). Requires workspace\_token.
* **start\_date** (string) - Optional: Filter recommendations created on/after this YYYY-MM-DD date. Requires workspace\_token.
* **end\_date** (string) - Optional: Filter recommendations created on/before this YYYY-MM-DD date. Requires workspace\_token.
* **status** (string) - Optional: Filter by status.
* Allowed values: `active`, `archived`
* **min\_savings** (number (float)) - Optional: Filter by recommendations whose potential savings are greater than or equal to this amount, in the workspace's currency. Requires workspace\_token.
* **page** (integer (int32)) - Optional: The page of results to return.
* **limit** (integer (int32)) - Optional: The number of results to return. The maximum is 1000.
* **workspace\_token** (string) - **Required**: The workspace token to filter recommendations by. Required.
#### Responses
**200**: OK
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/recommendations/get-all-resources-for-a-recommendation-type](https://docs.vantage.sh/api/recommendations/get-all-resources-for-a-recommendation-type)
***
### GET /recommendations/
**Get recommendation by token**
Return a Recommendation.
#### Path Parameters
* **recommendation\_token** (path) (string) - **Required**
#### Responses
**200**: OK
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/recommendations/get-recommendation-by-token](https://docs.vantage.sh/api/recommendations/get-recommendation-by-token)
***
### GET /recommendations//resources
**Get all resources for a recommendation**
Return all Active Resources, including Recommendation Actions, referenced in this Recommendation.
#### Path Parameters
* **recommendation\_token** (path) (string) - **Required**
#### Query Parameters
* **page** (integer (int32)) - Optional: The page of results to return.
* **limit** (integer (int32)) - Optional: The number of results to return. Defaults to 25. The maximum is 500.
#### Responses
**200**: OK
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/recommendations/get-all-resources-for-a-recommendation](https://docs.vantage.sh/api/recommendations/get-all-resources-for-a-recommendation)
***
### GET /recommendations//resources/
**Get specific resource for a recommendation**
Return an Active Resource, including Recommendation Actions, referenced in this Recommendation.
#### Path Parameters
* **recommendation\_token** (path) (string) - **Required**
* **resource\_token** (path) (string) - **Required**
#### Responses
**200**: OK
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/recommendations/get-specific-resource-for-a-recommendation](https://docs.vantage.sh/api/recommendations/get-specific-resource-for-a-recommendation)
***
## ReportForecasts
### GET /report\_forecasts
**Get all report forecasts**
Return all scenario-model ReportForecasts for a CostReport.
#### Query Parameters
* **cost\_report\_token** (string) - **Required**
* **page** (integer (int32)) - Optional
* **limit** (integer (int32)) - Optional
#### Responses
**200**: Return all scenario-model ReportForecasts for a CostReport.
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/reportforecasts/get-all-report-forecasts](https://docs.vantage.sh/api/reportforecasts/get-all-report-forecasts)
***
### POST /report\_forecasts
**Create report forecast**
Create a scenario-model ReportForecast.
#### Request Body
```json theme={null}
{
"cost_report_token": string // required,
"title": string // required,
"scenario_model_tokens": [string],
"business_metric_token": string,
"set_as_default": boolean
}
```
#### Responses
**201**: Create a scenario-model ReportForecast.
**403**: Forbidden
**404**: NotFound
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/reportforecasts/create-report-forecast](https://docs.vantage.sh/api/reportforecasts/create-report-forecast)
***
### DELETE /report\_forecasts/
**Delete report forecast**
Delete a scenario-model ReportForecast.
#### Path Parameters
* **report\_forecast\_token** (path) (string) - **Required**
#### Responses
**204**: Delete a scenario-model ReportForecast.
**403**: Forbidden
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/reportforecasts/delete-report-forecast](https://docs.vantage.sh/api/reportforecasts/delete-report-forecast)
***
### GET /report\_forecasts/
**Get report forecast by token**
Return a scenario-model ReportForecast.
#### Path Parameters
* **report\_forecast\_token** (path) (string) - **Required**
#### Responses
**200**: Return a scenario-model ReportForecast.
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/reportforecasts/get-report-forecast-by-token](https://docs.vantage.sh/api/reportforecasts/get-report-forecast-by-token)
***
### PUT /report\_forecasts/
**Update report forecast**
Update a scenario-model ReportForecast.
#### Path Parameters
* **report\_forecast\_token** (path) (string) - **Required**
#### Request Body
```json theme={null}
{
"title": string,
"scenario_model_tokens": [string],
"business_metric_token": string,
"set_as_default": boolean
}
```
#### Responses
**200**: Update a scenario-model ReportForecast.
**403**: Forbidden
**404**: NotFound
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/reportforecasts/update-report-forecast](https://docs.vantage.sh/api/reportforecasts/update-report-forecast)
***
## ReportNotifications
### GET /report\_notifications
**Get all report notifications**
Return all ReportNotifications.
#### Query Parameters
* **page** (integer (int32)) - Optional: The page of results to return.
* **limit** (integer (int32)) - Optional: The amount of results to return. The maximum is 1000.
* **workspace\_token** (string) - Optional: Filter by workspace token.
* **q** (string) - Optional: Search report notifications by title.
#### Responses
**200**: OK
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/reportnotifications/get-all-report-notifications](https://docs.vantage.sh/api/reportnotifications/get-all-report-notifications)
***
### POST /report\_notifications
**Create report notification**
Create a ReportNotification.
#### Request Body
```json theme={null}
{
"title": string // required // The title of the ReportNotification,
"cost_report_token": string // required // The CostReport token,
"workspace_token": string // The token of the Workspace to add the ReportNotification to. Required if the API token is associated with multiple Workspaces,
"user_tokens": [string] // The Users that receive the notification,
"recipient_emails": [string] // Email addresses that receive the notification. Must be organization users, on the account's SSO domain, or an approved third-party service address,
"recipient_channels": [string] // The Slack or Microsoft Teams channels that receive the notification,
"frequency": string // required // The frequency the ReportNotification is sent. Possible values: daily, weekly, monthly,
"change": string // required // The type of change the ReportNotification is tracking. Possible values: percentage, dollars
}
```
#### Responses
**201**: Created
**400**: BadRequest
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/reportnotifications/create-report-notification](https://docs.vantage.sh/api/reportnotifications/create-report-notification)
***
### DELETE /report\_notifications/
**Delete report notification**
Delete a ReportNotification.
#### Path Parameters
* **report\_notification\_token** (path) (string) - **Required**
#### Responses
**204**: No Content
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/reportnotifications/delete-report-notification](https://docs.vantage.sh/api/reportnotifications/delete-report-notification)
***
### GET /report\_notifications/
**Get report notification by token**
Return a ReportNotification.
#### Path Parameters
* **report\_notification\_token** (path) (string) - **Required**
#### Responses
**200**: OK
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/reportnotifications/get-report-notification-by-token](https://docs.vantage.sh/api/reportnotifications/get-report-notification-by-token)
***
### PUT /report\_notifications/
**Update report notification**
Update a ReportNotification.
#### Path Parameters
* **report\_notification\_token** (path) (string) - **Required**
#### Request Body
```json theme={null}
{
"title": string // The title of the ReportNotification,
"cost_report_token": string // The CostReport token,
"user_tokens": [string] // The Users that receive the notification,
"recipient_emails": [string] // Email addresses that receive the notification. Must be organization users, on the account's SSO domain, or an approved third-party service address,
"recipient_channels": [string] // The Slack or Microsoft Teams channels that receive the notification,
"frequency": string // The frequency the ReportNotification is sent. Possible values: daily, weekly, monthly,
"change": string // The type of change the ReportNotification is tracking. Possible values: percentage, dollars
}
```
#### Responses
**200**: OK
**400**: BadRequest
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/reportnotifications/update-report-notification](https://docs.vantage.sh/api/reportnotifications/update-report-notification)
***
## ResourceReports
### GET /resource\_reports
**Get all resource reports**
Return all ResourceReports.
#### Query Parameters
* **page** (integer (int32)) - Optional: The page of results to return.
* **limit** (integer (int32)) - Optional: The number of results to return. The maximum is 1000.
* **workspace\_token** (string) - Optional: Filter by workspace token.
* **q** (string) - Optional: A search query to filter ResourceReports by title.
#### Responses
**200**: OK
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/resourcereports/get-all-resource-reports](https://docs.vantage.sh/api/resourcereports/get-all-resource-reports)
***
### POST /resource\_reports
**Create resource report**
Create a ResourceReport.
#### Request Body
```json theme={null}
{
"workspace_token": string // required // The token of the Workspace to add the ResourceReport to,
"title": string // The title of the ResourceReport,
"filter": string // The filter query language to apply to the ResourceReport. Additional documentation available at https://docs.vantage.sh/vql,
"columns": [string] // Array of column names to display in the table. Column names should match those returned by the /resource_reports/columns endpoint. The order determines the display order. Only available for reports with a single resource type filter,
"folder_token": string // The token of the Folder to add the ResourceReport to
}
```
#### Responses
**201**: Created
**400**: BadRequest
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/resourcereports/create-resource-report](https://docs.vantage.sh/api/resourcereports/create-resource-report)
***
### GET /resource\_reports/columns
**Get resource report columns**
List available columns for a resource type.
#### Query Parameters
* **resource\_type** (string) - **Required**: VQL resource type name ([https://docs.vantage.sh/vql\_resource\_report#costs-by-resource-type](https://docs.vantage.sh/vql_resource_report#costs-by-resource-type))
#### Responses
**200**: Returns array of available column names for the specified resource type
**400**: BadRequest
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/resourcereports/get-resource-report-columns](https://docs.vantage.sh/api/resourcereports/get-resource-report-columns)
***
### DELETE /resource\_reports/
**Delete resource report**
Delete a ResourceReport.
#### Path Parameters
* **resource\_report\_token** (path) (string) - **Required**
#### Responses
**204**: No Content
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/resourcereports/delete-resource-report](https://docs.vantage.sh/api/resourcereports/delete-resource-report)
***
### GET /resource\_reports/
**Get resource report by token**
Return a ResourceReport.
#### Path Parameters
* **resource\_report\_token** (path) (string) - **Required**
#### Responses
**200**: OK
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/resourcereports/get-resource-report-by-token](https://docs.vantage.sh/api/resourcereports/get-resource-report-by-token)
***
### PUT /resource\_reports/
**Update resource report**
Update a ResourceReport.
#### Path Parameters
* **resource\_report\_token** (path) (string) - **Required**
#### Request Body
```json theme={null}
{
"title": string // The title of the ResourceReport,
"filter": string // The filter query language to apply to the ResourceReport. Additional documentation available at https://docs.vantage.sh/vql,
"columns": [string] // Array of column names to display in the table. Column names should match those returned by the /resource_reports/columns endpoint. The order determines the display order. Only available for reports with a single resource type filter,
"folder_token": string // The token of the Folder to move the ResourceReport to
}
```
#### Responses
**200**: OK
**400**: BadRequest
**404**: NotFound
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/resourcereports/update-resource-report](https://docs.vantage.sh/api/resourcereports/update-resource-report)
***
## Resources
### GET /resources
**Get resources**
Return Resources contained in a ResourceReport
#### Query Parameters
* **resource\_report\_token** (string) - Optional: The ResourceReport token.
* **filter** (string) - Optional: The filter query language to apply to the Resources. Additional documentation available at [https://docs.vantage.sh/vql](https://docs.vantage.sh/vql).
* **workspace\_token** (string) - Optional: The Workspace in which the Resources are located.
* **include\_cost** (boolean) - Optional: Include cost information in the response.
* **page** (integer (int32)) - Optional: The page number for pagination.
* **limit** (integer (int32)) - Optional: The number of resources to return per page.
#### Responses
**200**: OK
**400**: BadRequest
**402**: PaymentRequired
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/resources/get-resources](https://docs.vantage.sh/api/resources/get-resources)
***
### GET /resources/
**Get resource by token**
Return a single Resource
#### Path Parameters
* **resource\_token** (path) (string) - **Required**
#### Query Parameters
* **include\_cost** (boolean) - Optional: Include cost information in the response.
#### Responses
**200**: OK
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/resources/get-resource-by-token](https://docs.vantage.sh/api/resources/get-resource-by-token)
***
## SavedFilters
### GET /saved\_filters
**Get all saved filters**
Return all SavedFilters that can be applied to a CostReport.
#### Query Parameters
* **page** (integer (int32)) - Optional: The page of results to return.
* **limit** (integer (int32)) - Optional: The amount of results to return. The maximum is 1000.
* **q** (string) - Optional: Search saved filters by title.
* **workspace\_token** (string) - Optional: The workspace token of the saved filters to return.
#### Responses
**200**: OK
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/savedfilters/get-all-saved-filters](https://docs.vantage.sh/api/savedfilters/get-all-saved-filters)
***
### POST /saved\_filters
**Create saved filter**
Create a SavedFilter for CostReports.
#### Request Body
```json theme={null}
{
"title": string // required // The title of the SavedFilter,
"workspace_token": string // The Workspace to associate the SavedFilter with. Required if the API token is associated with multiple Workspaces,
"filter": string // The filter query language to apply to the SavedFilter, which subsequently gets applied to a CostReport. Additional documentation available at https://docs.vantage.sh/vql
}
```
#### Responses
**201**: Created
**400**: BadRequest
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/savedfilters/create-saved-filter](https://docs.vantage.sh/api/savedfilters/create-saved-filter)
***
### DELETE /saved\_filters/
**Delete saved filter**
Delete a SavedFilter for CostReports.
#### Path Parameters
* **saved\_filter\_token** (path) (string) - **Required**
#### Responses
**204**: No Content
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/savedfilters/delete-saved-filter](https://docs.vantage.sh/api/savedfilters/delete-saved-filter)
***
### GET /saved\_filters/
**Get saved filter by token**
Return a specific SavedFilter.
#### Path Parameters
* **saved\_filter\_token** (path) (string) - **Required**
#### Responses
**200**: OK
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/savedfilters/get-saved-filter-by-token](https://docs.vantage.sh/api/savedfilters/get-saved-filter-by-token)
***
### PUT /saved\_filters/
**Update saved filter**
Update a SavedFilter for CostReports.
#### Path Parameters
* **saved\_filter\_token** (path) (string) - **Required**
#### Request Body
```json theme={null}
{
"title": string // The title of the SavedFilter,
"filter": string // The filter query language to apply to the SavedFilter, which subsequently gets applied to a CostReport. Additional documentation available at https://docs.vantage.sh/vql
}
```
#### Responses
**200**: OK
**400**: BadRequest
**404**: NotFound
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/savedfilters/update-saved-filter](https://docs.vantage.sh/api/savedfilters/update-saved-filter)
***
## ScenarioModels
### GET /scenario\_models
**Get all scenario models**
Return all ScenarioModels.
#### Query Parameters
* **page** (integer (int32)) - Optional
* **limit** (integer (int32)) - Optional
#### Responses
**200**: Return all ScenarioModels.
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/scenariomodels/get-all-scenario-models](https://docs.vantage.sh/api/scenariomodels/get-all-scenario-models)
***
### POST /scenario\_models
**Create scenario model**
Create a ScenarioModel.
#### Request Body
```json theme={null}
{
"title": string // required,
"priority": integer,
"provider": string,
"service": string,
"workspace_token": string,
"periods": [ // The periods for the ScenarioModel
{
"start_at": string // required,
"end_at": string,
"amount": number // required,
"amount_type": string // required // Allowed values: `dollar`, `percent`
}
]
}
```
#### Responses
**201**: Create a ScenarioModel.
**403**: Forbidden
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/scenariomodels/create-scenario-model](https://docs.vantage.sh/api/scenariomodels/create-scenario-model)
***
### DELETE /scenario\_models/
**Delete scenario model**
Delete a ScenarioModel.
#### Path Parameters
* **scenario\_model\_token** (path) (string) - **Required**
#### Responses
**204**: Delete a ScenarioModel.
**403**: Forbidden
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/scenariomodels/delete-scenario-model](https://docs.vantage.sh/api/scenariomodels/delete-scenario-model)
***
### GET /scenario\_models/
**Get scenario model by token**
Return a ScenarioModel.
#### Path Parameters
* **scenario\_model\_token** (path) (string) - **Required**
#### Responses
**200**: Return a ScenarioModel.
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/scenariomodels/get-scenario-model-by-token](https://docs.vantage.sh/api/scenariomodels/get-scenario-model-by-token)
***
### PUT /scenario\_models/
**Update scenario model**
Update a ScenarioModel.
#### Path Parameters
* **scenario\_model\_token** (path) (string) - **Required**
#### Request Body
```json theme={null}
{
"title": string,
"priority": integer,
"provider": string,
"service": string,
"workspace_token": string,
"periods": [ // The periods for the ScenarioModel
{
"start_at": string // required,
"end_at": string,
"amount": number // required,
"amount_type": string // required // Allowed values: `dollar`, `percent`
}
]
}
```
#### Responses
**200**: Update a ScenarioModel.
**403**: Forbidden
**404**: NotFound
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/scenariomodels/update-scenario-model](https://docs.vantage.sh/api/scenariomodels/update-scenario-model)
***
## Segments
### GET /segments
**Get all segments**
Return all Segments.
#### Query Parameters
* **page** (integer (int32)) - Optional: The page of results to return.
* **limit** (integer (int32)) - Optional: The amount of results to return. The maximum is 1000.
* **q** (string) - Optional: Search segments by title.
* **workspace\_token** (string) - Optional: The workspace token of the segments to return.
#### Responses
**200**: OK
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/segments/get-all-segments](https://docs.vantage.sh/api/segments/get-all-segments)
***
### POST /segments
**Create segment**
Create a Segment.
#### Request Body
```json theme={null}
{
"title": string // required // The title of the Segment,
"description": string // The description of the Segment,
"priority": integer // The priority of the Segment,
"track_unallocated": boolean // Track Unallocated Costs which are not assigned to any of the created Segments,
"report_settings": { // Report settings configurable on top-level Segments
"include_credits": boolean // Reports created under this Segment will include credits,
"include_refunds": boolean // Reports created under this Segment will include refunds,
"include_discounts": boolean // Reports created under this Segment will include discounts,
"include_tax": boolean // Reports created under this Segment will include tax,
"amortize": boolean // Reports created under this Segment will amortize
},
"workspace_token": string // The token of the Workspace to add the Segment to. Ignored if 'segment_token' is set. Required if the API token is associated with multiple Workspaces,
"filter": string // The filter query language to apply to the Segment. Additional documentation available at https://docs.vantage.sh/vql,
"parent_segment_token": string // The token of the parent Segment this new Segment belongs to. Determines the Workspace the segment is assigned to
}
```
#### Responses
**201**: Created
**400**: BadRequest
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/segments/create-segment](https://docs.vantage.sh/api/segments/create-segment)
***
### DELETE /segments/
**Delete segment**
Delete a Segment.
#### Path Parameters
* **segment\_token** (path) (string) - **Required**
#### Responses
**204**: No Content
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/segments/delete-segment](https://docs.vantage.sh/api/segments/delete-segment)
***
### GET /segments/
**Get segment by token**
Return a Segment.
#### Path Parameters
* **segment\_token** (path) (string) - **Required**
#### Responses
**200**: OK
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/segments/get-segment-by-token](https://docs.vantage.sh/api/segments/get-segment-by-token)
***
### PUT /segments/
**Update segment**
Update a Segment.
#### Path Parameters
* **segment\_token** (path) (string) - **Required**
#### Request Body
```json theme={null}
{
"title": string // The title of the Segment,
"description": string // The description of the Segment,
"priority": integer // The priority of the Segment,
"track_unallocated": boolean // Track Unallocated Costs which are not assigned to any of the created Segments,
"report_settings": { // Report settings configurable on top-level Segments
"include_credits": boolean // Reports created under this Segment will include credits,
"include_refunds": boolean // Reports created under this Segment will include refunds,
"include_discounts": boolean // Reports created under this Segment will include discounts,
"include_tax": boolean // Reports created under this Segment will include tax,
"amortize": boolean // Reports created under this Segment will amortize
},
"filter": string // The filter query language to apply to the Segment. Additional documentation available at https://docs.vantage.sh/vql,
"parent_segment_token": string // The token of the parent Segment this new Segment belongs to. Determines the Workspace the segment is assigned to
}
```
#### Responses
**200**: OK
**400**: BadRequest
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/segments/update-segment](https://docs.vantage.sh/api/segments/update-segment)
***
## Tags
### GET /tags
**Get all tags**
Return all Tags that the current API token has access to.
#### Query Parameters
* **providers** (array) - Optional: An array of providers to scope Tags by.
* **search\_query** (string) - Optional: A search query to filter Tags by tag key.
* **sort\_direction** (string) - Optional: The direction in which you would like to sort the data by. Defaults to 'asc'.
* Allowed values: `asc`, `desc`
* **page** (integer (int32)) - Optional: The page of results to return.
* Default: `1`
* **limit** (integer (int32)) - Optional: The number of results to return per page. Defaults to 100. The maximum is 1000.
* Default: `100`
#### Responses
**200**: OK
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/tags/get-all-tags](https://docs.vantage.sh/api/tags/get-all-tags)
***
### PUT /tags
**Update tag**
Updates an existing Tag.
#### Request Body
```json theme={null}
{
"tag_key": string,
"tag_keys": [string],
"hidden": boolean // Whether the Tag is hidden from the Vantage UI,
"preferred": boolean // Whether the Tag is marked as preferred in the Vantage UI
}
```
#### Responses
**200**: OK
**400**: BadRequest
**403**: Forbidden
**404**: NotFound
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/tags/update-tag](https://docs.vantage.sh/api/tags/update-tag)
***
### GET /tags//values
**Get tag values**
Returns corresponding TagValues for a given Tag.
#### Path Parameters
* **key** (path) (string) - **Required**: The key of the Tag for which you would like to retrieve TagValues.
#### Query Parameters
* **providers** (array) - Optional: An array of providers to scope TagValues by.
* **sort\_direction** (string) - Optional: The direction in which to sort the TagValues. Defaults to 'asc'.
* Allowed values: `asc`, `desc`
* Default: `asc`
* **search\_query** (string) - Optional: A search query to filter TagValues by the value name.
* **page** (integer (int32)) - Optional: The page of results to return.
* Default: `1`
* **limit** (integer (int32)) - Optional: The number of results to return per page. Defaults to 100. The maximum is 1000.
* Default: `100`
#### Responses
**200**: OK
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/tags/get-tag-values](https://docs.vantage.sh/api/tags/get-tag-values)
***
## Teams
### GET /teams
**Get all teams**
Return all Teams that the current API token has access to.
#### Query Parameters
* **page** (integer (int32)) - Optional: The page of results to return.
* **limit** (integer (int32)) - Optional: The amount of results to return. The maximum is 1000.
* **q** (string) - Optional: Search teams by name.
* **workspace\_token** (string) - Optional: Filter by workspace token.
#### Responses
**200**: OK
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/teams/get-all-teams](https://docs.vantage.sh/api/teams/get-all-teams)
***
### POST /teams
**Create team**
Create a new Team.
#### Request Body
```json theme={null}
{
"name": string // required // The name of the Team,
"description": string // The description of the Team,
"workspace_tokens": [string] // The Workspace tokens to associate to the Team,
"user_tokens": [string] // The User tokens to associate to the Team,
"user_emails": [string] // The User emails to associate to the Team,
"role": string // The role to assign to the provided Users. Defaults to 'editor' which has editor permissions. Allowed values: `owner`, `editor`, `viewer`,
"default_dashboard_token": string // The token of a Dashboard to set as the Team default. Send null to clear
}
```
#### Responses
**201**: Created
**400**: BadRequest
**403**: Forbidden
**404**: NotFound
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/teams/create-team](https://docs.vantage.sh/api/teams/create-team)
***
### DELETE /teams/
**Delete team**
Delete a Team.
#### Path Parameters
* **team\_token** (path) (string) - **Required**
#### Responses
**204**: No Content
**400**: BadRequest
**403**: Forbidden
**404**: NotFound
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/teams/delete-team](https://docs.vantage.sh/api/teams/delete-team)
***
### GET /teams/
**Get team by token**
Return a specific Team.
#### Path Parameters
* **team\_token** (path) (string) - **Required**
#### Responses
**200**: OK
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/teams/get-team-by-token](https://docs.vantage.sh/api/teams/get-team-by-token)
***
### PUT /teams/
**Update team**
Update a Team.
#### Path Parameters
* **team\_token** (path) (string) - **Required**
#### Request Body
```json theme={null}
{
"name": string // The name of the Team,
"description": string // The description of the Team,
"workspace_tokens": [string] // The Workspace tokens to associate to the Team,
"user_tokens": [string] // The User tokens to associate to the Team,
"user_emails": [string] // The User emails to associate to the Team,
"role": string // The role to assign to the provided Users. Defaults to 'editor' which has editor permissions. Allowed values: `owner`, `editor`, `viewer`,
"default_dashboard_token": string // The token of a Dashboard to set as the Team default. Send null to clear
}
```
#### Responses
**200**: OK
**400**: BadRequest
**403**: Forbidden
**404**: NotFound
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/teams/update-team](https://docs.vantage.sh/api/teams/update-team)
***
### GET /teams//members
**Get team members**
Return all members of a Team.
#### Path Parameters
* **team\_token** (path) (string) - **Required**
#### Query Parameters
* **page** (integer (int32)) - Optional: The page of results to return.
* **limit** (integer (int32)) - Optional: The amount of results to return. The maximum is 1000.
#### Responses
**200**: OK
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/teams/get-team-members](https://docs.vantage.sh/api/teams/get-team-members)
***
### POST /teams//members
**Add team member**
Add a member to a Team.
#### Path Parameters
* **team\_token** (path) (string) - **Required**
#### Request Body
```json theme={null}
{
"user_email": string // required // The email address of the user to add to the Team,
"role": string // required // The role to assign to the user. Defaults to 'editor'. Allowed values: `owner`, `editor`, `viewer`, `integration_owner`
}
```
#### Responses
**201**: Created
**400**: BadRequest
**403**: Forbidden
**404**: NotFound
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/teams/add-team-member](https://docs.vantage.sh/api/teams/add-team-member)
***
### DELETE /teams//members/
**Remove team member**
Remove a member from a Team.
#### Path Parameters
* **team\_token** (path) (string) - **Required**
* **user\_token** (path) (string) - **Required**
#### Responses
**204**: No Content
**400**: BadRequest
**403**: Forbidden
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/teams/remove-team-member](https://docs.vantage.sh/api/teams/remove-team-member)
***
## UnitCosts
### GET /unit\_costs
**Get all unit costs for a cost report**
Return all UnitCosts for a CostReport.
#### Query Parameters
* **cost\_report\_token** (string) - **Required**: The CostReport token.
* **start\_date** (string) - Optional: First date you would like to filter unit costs from. Defaults to the report's default. ISO 8601 formatted.
* **end\_date** (string) - Optional: Last date you would like to filter unit costs to. Defaults to the report's default. ISO 8601 formatted.
* **date\_bin** (string) - Optional: The date bin of the unit costs. Defaults to the report's default or day.
* Allowed values: `day`, `week`, `month`, `quarter`, `hour`
* **order** (string) - Optional: Whether to order unit costs by date in an ascending or descending manner.
* Allowed values: `asc`, `desc`
* Default: `desc`
* **limit** (integer (int32)) - Optional: The amount of results to return. The maximum is 1000.
* **page** (integer (int32)) - Optional: The page of results to return.
#### Responses
**200**: OK
**400**: BadRequest
**402**: PaymentRequired
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/unitcosts/get-all-unit-costs-for-a-cost-report](https://docs.vantage.sh/api/unitcosts/get-all-unit-costs-for-a-cost-report)
***
### POST /unit\_costs/data\_exports
**Generate data export of unit costs**
Generate a DataExport of unit costs.
#### Request Body
```json theme={null}
{
"cost_report_token": string // required // The CostReport token,
"workspace_token": string // The token of the Workspace to query costs from. Required if the API token is associated with multiple Workspaces,
"start_date": string // First date you would like to filter unit costs from. Defaults to the report's default. ISO 8601 formatted,
"end_date": string // Last date you would like to filter unit costs to. Defaults to the report's default. ISO 8601 formatted,
"date_bin": string // The date bin of the unit costs. Defaults to the report's default or day. Allowed values: `day`, `week`, `month`, `quarter`, `hour`
}
```
#### Responses
**202**: The data export has been queued and will be available at the location specified in the Location header.
**400**: BadRequest
**402**: PaymentRequired
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/unitcosts/generate-data-export-of-unit-costs](https://docs.vantage.sh/api/unitcosts/generate-data-export-of-unit-costs)
***
## UserFeedback
### POST /user\_feedback
**Submit user feedback**
Provide UserFeedback for our product and features.
#### Request Body
```json theme={null}
{
"message": string // required // UserFeedback message
}
```
#### Responses
**201**: Provide UserFeedback for our product and features.
**400**: BadRequest
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/userfeedback/submit-user-feedback](https://docs.vantage.sh/api/userfeedback/submit-user-feedback)
***
## Users
### GET /users
**Get all users**
Return all Users that the current API token has access to.
#### Query Parameters
* **page** (integer (int32)) - Optional: The page of results to return.
* **limit** (integer (int32)) - Optional: The amount of results to return. The maximum is 1000.
#### Responses
**200**: OK
**403**: Forbidden
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/users/get-all-users](https://docs.vantage.sh/api/users/get-all-users)
***
### GET /users/
**Get user by token**
Return a specific User.
#### Path Parameters
* **user\_token** (path) (string) - **Required**
#### Responses
**200**: OK
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/users/get-user-by-token](https://docs.vantage.sh/api/users/get-user-by-token)
***
### PUT /users/
**Update a user**
Update a specific User.
#### Path Parameters
* **user\_token** (path) (string) - **Required**
#### Request Body
```json theme={null}
{
"default_dashboard_token": string // The token of a Dashboard to set as the User default. Send null to clear
}
```
#### Responses
**200**: OK
**404**: NotFound
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/users/update-a-user](https://docs.vantage.sh/api/users/update-a-user)
***
## VirtualTags
### GET /virtual\_tag\_configs
**Get all virtual tag configs**
Return all VirtualTagConfigs that the current API token has access to.
#### Query Parameters
* **q** (string) - Optional: A search query to filter VirtualTagConfigs by key.
#### Responses
**200**: OK
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/virtualtags/get-all-virtual-tag-configs](https://docs.vantage.sh/api/virtualtags/get-all-virtual-tag-configs)
***
### POST /virtual\_tag\_configs
**Create virtual tag config**
Create a new VirtualTagConfig.
#### Request Body
```json theme={null}
{
"key": string // required // The key of the VirtualTagConfig,
"overridable": boolean // required // Whether the VirtualTagConfig can override a provider-supplied tag on a matching Cost,
"backfill_until": string // The earliest month the VirtualTagConfig should be backfilled to,
"collapsed_tag_keys": [ // Tag keys to collapse values for
{
"key": string // required // The tag key to collapse values for,
"providers": [string] // Provider-only scope for this collapsed tag key. Invalid when filter is set; include provider restrictions in filter instead. Defaults to all providers,
"filter": string // The VQL filter this collapsed tag key applies to. When set, do not also set providers; include any provider restrictions directly in filter
}
],
"values": [ // Values for the VirtualTagConfig, with match precedence determined by order in the list
{
"filter": string // required // The filter query language to apply to the value. Additional documentation available at https://docs.vantage.sh/vql,
"name": string // The name of the value,
"business_metric_token": string // The token of an associated business metric,
"label_key": string // The business metric label key used for this virtual tag value,
"label_values": [string] // Optional business metric label values. An empty array includes every value for the label key,
"label_filters": object // ClickHouse BusinessMetric row filters. Each key must match, and values within a key are alternatives. Cannot include the fan-out label_key. Send null or an empty object to clear,
"display_name": string // The display name for an allocation value (cost_metric or percentages). Invalid when name is set,
"label_transforms": [
{
"type": string // required,
"delimiter": string,
"index": integer,
"template": string
}
],
"cost_metric": {
"filter": string // required,
"aggregation": { // required
"tag": string // required
}
},
"percentages": [
{
"value": string // required,
"pct": number // required
}
],
"date_ranges": [ // Date ranges restricting when this value applies. Each range has optional start_date and end_date (inclusive, YYYY-MM-DD)
{
"start_date": string // Inclusive start date (YYYY-MM-DD), or null for unbounded,
"end_date": string // Inclusive end date (YYYY-MM-DD), or null for unbounded
}
]
}
]
}
```
#### Responses
**201**: Created
**400**: BadRequest
**403**: Forbidden
**404**: NotFound
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/virtualtags/create-virtual-tag-config](https://docs.vantage.sh/api/virtualtags/create-virtual-tag-config)
***
### GET /virtual\_tag\_configs/async/
**Get async virtual tag config update status**
Check the status of an async VirtualTagConfig update.
#### Path Parameters
* **request\_id** (path) (string) - **Required**
#### Responses
**200**: Request completed successfully
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/virtualtags/get-async-virtual-tag-config-update-status](https://docs.vantage.sh/api/virtualtags/get-async-virtual-tag-config-update-status)
***
### DELETE /virtual\_tag\_configs/
**Delete virtual tag config**
Deletes an existing VirtualTagConfig.
#### Path Parameters
* **token** (path) (string) - **Required**
#### Responses
**204**: No Content
**403**: Forbidden
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/virtualtags/delete-virtual-tag-config](https://docs.vantage.sh/api/virtualtags/delete-virtual-tag-config)
***
### GET /virtual\_tag\_configs/
**Get virtual tag config by token**
Return a specific VirtualTagConfig.
#### Path Parameters
* **token** (path) (string) - **Required**
#### Responses
**200**: OK
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/virtualtags/get-virtual-tag-config-by-token](https://docs.vantage.sh/api/virtualtags/get-virtual-tag-config-by-token)
***
### PUT /virtual\_tag\_configs/
**Update virtual tag config**
Updates an existing VirtualTagConfig.
#### Path Parameters
* **token** (path) (string) - **Required**
#### Request Body
```json theme={null}
{
"key": string // The key of the VirtualTagConfig,
"overridable": boolean // Whether the VirtualTagConfig can override a provider-supplied tag on a matching Cost,
"backfill_until": string // The earliest month the VirtualTagConfig should be backfilled to,
"collapsed_tag_keys": [ // Tag keys to collapse values for
{
"key": string // required // The tag key to collapse values for,
"providers": [string] // Provider-only scope for this collapsed tag key. Invalid when filter is set; include provider restrictions in filter instead. Defaults to all providers,
"filter": string // The VQL filter this collapsed tag key applies to. When set, do not also set providers; include any provider restrictions directly in filter
}
],
"values": [ // Values for the VirtualTagConfig, with match precedence determined by order in the list
{
"filter": string // required // The filter query language to apply to the value. Additional documentation available at https://docs.vantage.sh/vql,
"name": string // The name of the value,
"business_metric_token": string // The token of an associated business metric,
"label_key": string // The business metric label key used for this virtual tag value,
"label_values": [string] // Optional business metric label values. An empty array includes every value for the label key,
"label_filters": object // ClickHouse BusinessMetric row filters. Each key must match, and values within a key are alternatives. Cannot include the fan-out label_key. Send null or an empty object to clear,
"display_name": string // The display name for an allocation value (cost_metric or percentages). Invalid when name is set,
"label_transforms": [
{
"type": string // required,
"delimiter": string,
"index": integer,
"template": string
}
],
"cost_metric": {
"filter": string // required,
"aggregation": { // required
"tag": string // required
}
},
"percentages": [
{
"value": string // required,
"pct": number // required
}
],
"date_ranges": [ // Date ranges restricting when this value applies. Each range has optional start_date and end_date (inclusive, YYYY-MM-DD)
{
"start_date": string // Inclusive start date (YYYY-MM-DD), or null for unbounded,
"end_date": string // Inclusive end date (YYYY-MM-DD), or null for unbounded
}
]
}
]
}
```
#### Responses
**200**: OK
**202**: Request accepted for processing
**400**: BadRequest
**403**: Forbidden
**404**: NotFound
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/virtualtags/update-virtual-tag-config](https://docs.vantage.sh/api/virtualtags/update-virtual-tag-config)
***
### PUT /virtual\_tag\_configs//async
**Update virtual tag config asynchronously**
Asynchronously updates an existing VirtualTagConfig.
#### Path Parameters
* **token** (path) (string) - **Required**
#### Request Body
```json theme={null}
{
"key": string // The key of the VirtualTagConfig,
"overridable": boolean // Whether the VirtualTagConfig can override a provider-supplied tag on a matching Cost,
"backfill_until": string // The earliest month the VirtualTagConfig should be backfilled to,
"collapsed_tag_keys": [ // Tag keys to collapse values for
{
"key": string // required // The tag key to collapse values for,
"providers": [string] // Provider-only scope for this collapsed tag key. Invalid when filter is set; include provider restrictions in filter instead. Defaults to all providers,
"filter": string // The VQL filter this collapsed tag key applies to. When set, do not also set providers; include any provider restrictions directly in filter
}
],
"values": [ // Values for the VirtualTagConfig, with match precedence determined by order in the list
{
"filter": string // required // The filter query language to apply to the value. Additional documentation available at https://docs.vantage.sh/vql,
"name": string // The name of the value,
"business_metric_token": string // The token of an associated business metric,
"label_key": string // The business metric label key used for this virtual tag value,
"label_values": [string] // Optional business metric label values. An empty array includes every value for the label key,
"label_filters": object // ClickHouse BusinessMetric row filters. Each key must match, and values within a key are alternatives. Cannot include the fan-out label_key. Send null or an empty object to clear,
"display_name": string // The display name for an allocation value (cost_metric or percentages). Invalid when name is set,
"label_transforms": [
{
"type": string // required,
"delimiter": string,
"index": integer,
"template": string
}
],
"cost_metric": {
"filter": string // required,
"aggregation": { // required
"tag": string // required
}
},
"percentages": [
{
"value": string // required,
"pct": number // required
}
],
"date_ranges": [ // Date ranges restricting when this value applies. Each range has optional start_date and end_date (inclusive, YYYY-MM-DD)
{
"start_date": string // Inclusive start date (YYYY-MM-DD), or null for unbounded,
"end_date": string // Inclusive end date (YYYY-MM-DD), or null for unbounded
}
]
}
]
}
```
#### Responses
**202**: Request accepted for processing
**400**: BadRequest
**403**: Forbidden
**404**: NotFound
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/virtualtags/update-virtual-tag-config-asynchronously](https://docs.vantage.sh/api/virtualtags/update-virtual-tag-config-asynchronously)
***
### GET /virtual\_tag\_configs//status
**Get virtual tag config processing status**
Return the processing status of a specific VirtualTagConfig.
#### Path Parameters
* **token** (path) (string) - **Required**
#### Responses
**200**: Processing is complete
**202**: Processing is still in progress
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/virtualtags/get-virtual-tag-config-processing-status](https://docs.vantage.sh/api/virtualtags/get-virtual-tag-config-processing-status)
***
### POST /virtual\_tag\_configs//values
**Create virtual tag config value**
Create a VirtualTagConfigValue.
#### Path Parameters
* **virtual\_tag\_config\_token** (path) (string) - **Required**
#### Request Body
```json theme={null}
{
"filter": string // required // The filter query language to apply to the value. Additional documentation available at https://docs.vantage.sh/vql,
"name": string // The name of the value,
"business_metric_token": string // The token of an associated business metric,
"label_key": string // The business metric label key used for this virtual tag value,
"label_values": [string] // Business metric label values. An empty array includes every value for the label key,
"label_filters": { // ClickHouse BusinessMetric row filters. Each key must match, and values within a key are alternatives. Cannot include the fan-out label_key. Null and an empty object leave stored filters unchanged
},
"display_name": string // The display name for a cost metric or percentage allocation value,
"label_transforms": [
{
"type": string // required // Allowed values: `split`, `format`,
"delimiter": string,
"index": integer,
"template": string
}
],
"cost_metric": {
"filter": string // required,
"aggregation": { // required
"tag": string // required
}
},
"percentages": [
{
"value": string // required,
"pct": number // required
}
],
"date_ranges": [ // Date ranges restricting when this value applies
{
"start_date": string,
"end_date": string
}
]
}
```
#### Responses
**201**: Created
**400**: BadRequest
**403**: Forbidden
**404**: NotFound
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/virtualtags/create-virtual-tag-config-value](https://docs.vantage.sh/api/virtualtags/create-virtual-tag-config-value)
***
### DELETE /virtual\_tag\_configs//values/
**Delete virtual tag config value**
Delete a VirtualTagConfigValue.
#### Path Parameters
* **virtual\_tag\_config\_token** (path) (string) - **Required**
* **virtual\_tag\_config\_value\_token** (path) (string) - **Required**
#### Responses
**204**: No Content
**403**: Forbidden
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/virtualtags/delete-virtual-tag-config-value](https://docs.vantage.sh/api/virtualtags/delete-virtual-tag-config-value)
***
### GET /virtual\_tag\_configs//values/
**Get virtual tag config value by token**
Return a VirtualTagConfigValue.
#### Path Parameters
* **virtual\_tag\_config\_token** (path) (string) - **Required**
* **virtual\_tag\_config\_value\_token** (path) (string) - **Required**
#### Responses
**200**: OK
**403**: Forbidden
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/virtualtags/get-virtual-tag-config-value-by-token](https://docs.vantage.sh/api/virtualtags/get-virtual-tag-config-value-by-token)
***
### PATCH /virtual\_tag\_configs//values/
**Update virtual tag config value**
Update a VirtualTagConfigValue.
#### Path Parameters
* **virtual\_tag\_config\_token** (path) (string) - **Required**
* **virtual\_tag\_config\_value\_token** (path) (string) - **Required**
#### Request Body
```json theme={null}
{
"filter": string // The filter query language to apply to the value. Additional documentation available at https://docs.vantage.sh/vql,
"name": string // The name of the value,
"business_metric_token": string // The token of an associated business metric,
"label_key": string // The business metric label key used for this virtual tag value,
"label_values": [string] // Business metric label values. An empty array includes every value for the label key,
"label_filters": { // ClickHouse BusinessMetric row filters. Each key must match, and values within a key are alternatives. Cannot include the fan-out label_key. Null and an empty object leave stored filters unchanged
},
"display_name": string // The display name for a cost metric or percentage allocation value,
"label_transforms": [
{
"type": string // required // Allowed values: `split`, `format`,
"delimiter": string,
"index": integer,
"template": string
}
],
"cost_metric": {
"filter": string // required,
"aggregation": { // required
"tag": string // required
}
},
"percentages": [
{
"value": string // required,
"pct": number // required
}
],
"date_ranges": [ // Date ranges restricting when this value applies
{
"start_date": string,
"end_date": string
}
]
}
```
#### Responses
**200**: OK
**400**: BadRequest
**403**: Forbidden
**404**: NotFound
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/virtualtags/update-virtual-tag-config-value](https://docs.vantage.sh/api/virtualtags/update-virtual-tag-config-value)
***
## Workspaces
### GET /workspaces
**Get all workspaces**
Return all Workspaces that the current API token has access to.
#### Query Parameters
* **page** (integer (int32)) - Optional: The page of results to return.
* **limit** (integer (int32)) - Optional: The amount of results to return. The maximum is 1000.
* **q** (string) - Optional: Search workspaces by name.
#### Responses
**200**: OK
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/workspaces/get-all-workspaces](https://docs.vantage.sh/api/workspaces/get-all-workspaces)
***
### POST /workspaces
**Create workspace**
Create a workspace
#### Request Body
```json theme={null}
{
"name": string // required // Name of the workspace,
"enable_currency_conversion": boolean // Enable currency conversion for the workspace,
"currency": string // Currency code for the workspace,
"exchange_rate_date": string // The date to use for currency conversion. Allowed values: `daily_rate`, `end_of_billing_period_rate`
}
```
#### Responses
**201**: Created
**400**: BadRequest
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/workspaces/create-workspace](https://docs.vantage.sh/api/workspaces/create-workspace)
***
### DELETE /workspaces/
**Delete workspace**
Delete a workspace
#### Path Parameters
* **workspace\_token** (path) (string) - **Required**
#### Responses
**204**: No Content
**403**: Forbidden
**404**: NotFound
**422**: UnprocessableEntity
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/workspaces/delete-workspace](https://docs.vantage.sh/api/workspaces/delete-workspace)
***
### GET /workspaces/
**Get workspace by token**
Return a specific Workspace.
#### Path Parameters
* **workspace\_token** (path) (string) - **Required**
#### Responses
**200**: OK
**404**: NotFound
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/workspaces/get-workspace-by-token](https://docs.vantage.sh/api/workspaces/get-workspace-by-token)
***
### PUT /workspaces/
**Update workspace**
Update a workspace
#### Path Parameters
* **workspace\_token** (path) (string) - **Required**
#### Request Body
```json theme={null}
{
"name": string // Name of the workspace,
"enable_currency_conversion": boolean // Enable currency conversion for the workspace,
"currency": string // Currency code for the workspace. Allowed values: `AED`, `AFN`, `ALL`, `AMD`, `ANG`, `AOA`, `ARS`, `AUD`, `AWG`, `AZN`, `BAM`, `BBD`, `BDT`, `BGN`, `BHD`, `BIF`, `BMD`, `BND`, `BOB`, `BRL`, `BSD`, `BTC`, `BTN`, `BWP`, `BYN`, `BYR`, `BZD`, `CAD`, `CDF`, `CHF`, `CLF`, `CLP`, `CNY`, `COP`, `CRC`, `CUC`, `CUP`, `CVE`, `CZK`, `DJF`, `DKK`, `DOP`, `DZD`, `EGP`, `ERN`, `ETB`, `EUR`, `FJD`, `FKP`, `GBP`, `GEL`, `GGP`, `GHS`, `GIP`, `GMD`, `GNF`, `GTQ`, `GYD`, `HKD`, `HNL`, `HRK`, `HTG`, `HUF`, `IDR`, `ILS`, `IMP`, `INR`, `IQD`, `IRR`, `ISK`, `JEP`, `JMD`, `JOD`, `JPY`, `KES`, `KGS`, `KHR`, `KMF`, `KPW`, `KRW`, `KWD`, `KYD`, `KZT`, `LAK`, `LBP`, `LKR`, `LRD`, `LSL`, `LTL`, `LVL`, `LYD`, `MAD`, `MDL`, `MGA`, `MKD`, `MMK`, `MNT`, `MOP`, `MRO`, `MUR`, `MVR`, `MWK`, `MXN`, `MYR`, `MZN`, `NAD`, `NGN`, `NIO`, `NOK`, `NPR`, `NZD`, `OMR`, `PAB`, `PEN`, `PGK`, `PHP`, `PKR`, `PLN`, `PYG`, `QAR`, `RON`, `RSD`, `RUB`, `RWF`, `SAR`, `SBD`, `SCR`, `SDG`, `SEK`, `SGD`, `SHP`, `SLL`, `SOS`, `SRD`, `SSP`, `STD`, `STN`, `SVC`, `SYP`, `SZL`, `THB`, `TJS`, `TMT`, `TND`, `TOP`, `TRY`, `TTD`, `TWD`, `TZS`, `UAH`, `UGX`, `USD`, `UYU`, `UZS`, `VEF`, `VND`, `VUV`, `WST`, `XAF`, `XCD`, `XDR`, `XOF`, `XPF`, `YER`, `ZAR`, `ZMW`, `ZWL`,
"exchange_rate_date": string // The date to use for currency conversion. Allowed values: `daily_rate`, `end_of_billing_period_rate`
}
```
#### Responses
**200**: OK
**400**: BadRequest
For interactive testing, request/response examples, and detailed schemas, visit: [https://docs.vantage.sh/api/workspaces/update-workspace](https://docs.vantage.sh/api/workspaces/update-workspace)
***
## Summary
This reference includes **233** endpoints across **52** categories.
For the most up-to-date information, always refer to the [OpenAPI specification](https://api.vantage.sh/v2/oas_v3.json) or the individual endpoint pages.
# Create virtual tag config
Source: https://docs.vantage.sh/api/virtualtags/create-virtual-tag-config
https://api.vantage.sh/v2/oas_v3.json post /virtual_tag_configs
Create a new VirtualTagConfig.
# Create virtual tag config value
Source: https://docs.vantage.sh/api/virtualtags/create-virtual-tag-config-value
https://api.vantage.sh/v2/oas_v3.json post /virtual_tag_configs/{virtual_tag_config_token}/values
Create a VirtualTagConfigValue.
# Delete virtual tag config
Source: https://docs.vantage.sh/api/virtualtags/delete-virtual-tag-config
https://api.vantage.sh/v2/oas_v3.json delete /virtual_tag_configs/{token}
Deletes an existing VirtualTagConfig.
# Delete virtual tag config value
Source: https://docs.vantage.sh/api/virtualtags/delete-virtual-tag-config-value
https://api.vantage.sh/v2/oas_v3.json delete /virtual_tag_configs/{virtual_tag_config_token}/values/{virtual_tag_config_value_token}
Delete a VirtualTagConfigValue.
# Get all virtual tag configs
Source: https://docs.vantage.sh/api/virtualtags/get-all-virtual-tag-configs
https://api.vantage.sh/v2/oas_v3.json get /virtual_tag_configs
Return all VirtualTagConfigs that the current API token has access to.
# Get async virtual tag config update status
Source: https://docs.vantage.sh/api/virtualtags/get-async-virtual-tag-config-update-status
https://api.vantage.sh/v2/oas_v3.json get /virtual_tag_configs/async/{request_id}
Check the status of an async VirtualTagConfig update.
# Get virtual tag config by token
Source: https://docs.vantage.sh/api/virtualtags/get-virtual-tag-config-by-token
https://api.vantage.sh/v2/oas_v3.json get /virtual_tag_configs/{token}
Return a specific VirtualTagConfig.
# Get virtual tag config processing status
Source: https://docs.vantage.sh/api/virtualtags/get-virtual-tag-config-processing-status
https://api.vantage.sh/v2/oas_v3.json get /virtual_tag_configs/{token}/status
Return the processing status of a specific VirtualTagConfig.
# Get virtual tag config value by token
Source: https://docs.vantage.sh/api/virtualtags/get-virtual-tag-config-value-by-token
https://api.vantage.sh/v2/oas_v3.json get /virtual_tag_configs/{virtual_tag_config_token}/values/{virtual_tag_config_value_token}
Return a VirtualTagConfigValue.
# Update virtual tag config
Source: https://docs.vantage.sh/api/virtualtags/update-virtual-tag-config
https://api.vantage.sh/v2/oas_v3.json put /virtual_tag_configs/{token}
Updates an existing VirtualTagConfig.
# Update virtual tag config asynchronously
Source: https://docs.vantage.sh/api/virtualtags/update-virtual-tag-config-asynchronously
https://api.vantage.sh/v2/oas_v3.json put /virtual_tag_configs/{token}/async
Asynchronously updates an existing VirtualTagConfig.
# Update virtual tag config value
Source: https://docs.vantage.sh/api/virtualtags/update-virtual-tag-config-value
https://api.vantage.sh/v2/oas_v3.json patch /virtual_tag_configs/{virtual_tag_config_token}/values/{virtual_tag_config_value_token}
Update a VirtualTagConfigValue.
# Create workspace
Source: https://docs.vantage.sh/api/workspaces/create-workspace
https://api.vantage.sh/v2/oas_v3.json post /workspaces
Create a workspace
# Delete workspace
Source: https://docs.vantage.sh/api/workspaces/delete-workspace
https://api.vantage.sh/v2/oas_v3.json delete /workspaces/{workspace_token}
Delete a workspace
# Get all workspaces
Source: https://docs.vantage.sh/api/workspaces/get-all-workspaces
https://api.vantage.sh/v2/oas_v3.json get /workspaces
Return all Workspaces that the current API token has access to.
# Get workspace by token
Source: https://docs.vantage.sh/api/workspaces/get-workspace-by-token
https://api.vantage.sh/v2/oas_v3.json get /workspaces/{workspace_token}
Return a specific Workspace.
# Update workspace
Source: https://docs.vantage.sh/api/workspaces/update-workspace
https://api.vantage.sh/v2/oas_v3.json put /workspaces/{workspace_token}
Update a workspace
# Audit Logs
Source: https://docs.vantage.sh/audit_logs
Track changes and maintain compliance with Vantage Audit Logs.
Audit logs in Vantage provide a detailed record of changes to certain resources in your workspace. You can use them to trace when a change occurred, who made it, and what was modified.
Currently, audit logs are available for Virtual Tags, Cost Reports, [Dashboards](/dashboards), [Canvas](/canvas), [Budgets](/budgets), Business Metrics (when assigned to Cost Reports), [billing rules](/partners#billing-rules) (including [custom SQL billing rules](/sql_billing_rules)), Integration Delegations (for [MSP Partner Integrations](/partners#manage-partner-integrations)), MSP Invoices, FinOps Agent actions, [MCP Connections](/vantage_finops_agent#mcp-connectors), and preferred and hidden [tag settings](/tagging). Each log entry contains the action performed, the actor, the source of the change, and any relevant object details. Audit logs are available to users with the **Organization Owner** role. Events are logged for all changes to supported resources, regardless of who made the change. Logs are retained for 24 months.
When you edit a [saved filter](/saved_filters), an audit log event is created for all Cost Reports that the saved filter is applied to. This provides visibility into when saved filter changes affect multiple reports across your workspace. Additionally, when a Cost Report is deleted, any saved filters associated with that report are included in the audit log entry to provide complete visibility into the deletion event.
For longer log retention, contact [support@vantage.sh](mailto:support@vantage.sh).
## Access and Filter Audit Logs
You can access audit logs from the **Settings** UI or directly from a Cost Report or Virtual Tag.
From the top navigation, select **Settings**. In the left navigation, under **General Settings**, select **Audit Logs**.
At the top of a Cost Report, click the ellipses (…) and select **View Audit Logs**.

A list of audit log events is displayed for that particular report.
Audit Logs are made available for events starting on July 22, 2025.
From the top right of any Virtual Tag, click the **View Audit Logs** icon.

### Filter Audit Logs
On the **Audit Logs** screen, a table is displayed that contains a row for each audit log event. You can complete the following actions on this screen:
* Filter audit logs by **Event** (create, update, destroy), **Object Type** (Cost Report, Dashboard, Canvas, Budget, Virtual Tag, Billing Rule, Integration Delegations, MSP Invoice, MCP Connection, Preferred Tags, Hidden Tags, or FinOps Agent Cost Recommendation action), **Object** (the object's name), **Workspace**, **User** (or Team when using service tokens), and **Source** (the console or API).
* Filter audit logs based on a date range, up to 24 months.
* View more details for an audit log.
**Business Metrics**: When you assign or remove a Business Metric from a Cost Report, or change Business Metric settings (such as label filters or unit scale), these changes are tracked in audit logs under the associated Cost Report. Changes to the default forecast selection (choosing which Business Metric forecast to display) are also tracked as updates to the Cost Report.
Select any row in the table to view more details. On the details screen, changes are displayed in a GitHub-style diff format with color-coded additions and removals, making it easy to see exactly what was modified.
## FinOps Agent Audit Logs
When the FinOps Agent takes action on savings recommendations, detailed audit log entries are created. FinOps Agent actions are visually distinguished in the audit log table with a different object icon, making it easy to identify agent actions at a glance. Within the Vantage Audit Logs, you can see the following information for each FinOps Agent action:
* **Time the recommendation was provided**: When the Agent first identified and presented the savings opportunity
* **Time the recommendation was approved**: When a user approved the remediation action (if Owner Approval mode is enabled)
* **Vantage User that approved the remediation**: The user who approved the action (only applicable in Owner Approval mode)
* **What Resources were altered**: The specific resources that were modified as part of the recommendation remediation
* **Time the action was taken in the cloud provider**: When the action was executed in your cloud environment
For more information about the FinOps Agent, see the [Vantage FinOps Agent](/vantage_finops_agent) documentation.
## MCP Connection Audit Logs
When a user connects, reconnects, or disconnects a [FinOps Agent MCP connector](/vantage_finops_agent#mcp-connectors), Vantage creates an audit log entry with the **MCP Connection** object type. The entry identifies the provider and user who changed the connection. Credentials and authentication tokens are excluded from audit log details.
## Canvas Audit Logs
Canvas create, update, and delete actions are tracked in Audit Logs. Updates include changes to the Canvas title and prompt. Generated table output is not tracked as a user-editable configuration change.
## Integration Delegation Audit Logs
All additions and removals of integration assignments to Managed Accounts from the [Partner Integrations](/partners#manage-partner-integrations) page are logged in the Audit Log of the Management Account. An audit log entry is created for each integration that was modified. The log entry includes the following details:
* **Integration name**: The name of the integration that was modified
* **Managed Accounts added**: Which Managed Accounts were newly assigned to the integration
* **Managed Accounts removed**: Which Managed Accounts were unassigned from the integration
* **Current Managed Accounts**: The complete list of Managed Accounts connected to the integration after the change
You can filter audit logs by the **Integration Delegations** object type to view only these events.
## Audit Log Metadata and Details
All audit logs contain the following object metadata at the top of the log.
| **Field** | **Description** | **Log Type** | Example Value(s) |
| - | - | - | - |
| Object Type | What type of object was updated. | All | Cost Report; Canvas; Virtual Tag; MSP Invoice |
| Workspace | Workspace where the object belongs, or in the case of Virtual Tags, what workspace the user took the action from. | All | Management |
| User/Team | The name of the user or team that performed the action. When using a service token (Team token), this field displays as **Team** and shows the team name. Any actions taken by Vantage Support will be denoted as Vantage Support. | All | Firstname Lastname; Team Name |
| User Role/Team Role | The role of the user or team. When using a service token, this field displays as **Team Role** and shows the team name. For users, this shows their role (Admin, Member, etc.). | All | Admin; Member; Team Name |
| Source | Where the action originated. **Console** indicates actions taken through the Vantage web interface. **API** indicates actions taken via the Vantage API or Terraform provider, including actions performed using service tokens. | All | Console; API |
When actions are performed using a service token (Team token), the audit log displays **Team** and **Team Role** fields instead of **User** and **User Role**. The **Source** field will show **API** to indicate the action was performed via the API using a service token. The team name is displayed in both the **Team** and **Team Role** fields.
### Object Details
Two sections are displayed to indicate what has been changed or not changed on the object. These tables list the values updated by the user. When a value or setting changes, both the previous and new values appear in the object details. In the example below, the date binning, date interval, and report groupings have all been updated.

| Field Name | Description | Report | Example |
| - | - | - | - |
| Account | The account associated with the Virtual Tag. | Virtual Tag | Vantage |
| Backfill Until | The date until which historical data is populated in a Virtual Tag. | Virtual Tag | Jul 31, 2025, 20:00:00 |
| Change Unit | How period-over-period changes are displayed: as a percentage or as a currency amount. In audit logs, this may appear as `0` (percentage) or `1` (currency). | Cost Report | 0 (percentage), 1 (currency) |
| Chart Settings | Configuration settings for the chart visualization. | Cost Report | `{"x_axis_dimension": ["date"], "y_axis_dimension": "cost"}` |
| Chart Type | The type of chart visualization used for the report. | Cost Report | area, line, pie, bar, multi\_bar |
| Created At | When the object was originally created. | Cost Report and Virtual Tag | Feb 24, 2025, 15:36:57 |
| Created By | The user who created the object. | Cost Report and Virtual Tag | First Last |
| Created By Type | Type of user who created the object: User or Team (Service Token). | Cost Report and Virtual Tag | User |
| Date Bucket | The date binning used for the chart (how dates are grouped). | Cost Report | cumulative, day, week, month, quarter |
| Date Interval | The date interval of the report. | Cost Report | last\_month |
| Default Forecast | The forecast selected as the default for the Cost Report. This can be the Baseline Forecast, a Dynamic (business metric) forecast, or a Scenario Model forecast. | Cost Report | User Sessions |
| Filter | The conditions used to filter the report's data. | Cost Report | `(costs.provider = 'azure' AND costs.allocation = 0.0 AND costs.region IN ('germany', 'eastus'))` |
| Grouping Filter | Additional filter applied to the grouping dimension. | Cost Report | `service = 'EC2'` |
| Groupings | What the report is grouped by. | Cost Report | `["provider","tag:container"]` |
| Key | The name of the Virtual Tag key. | Virtual Tag | Test Tag |
| Labels | The label filters applied to a Business Metric on a Cost Report. | Cost Report | `["app1", "app2"]` |
| Previous Period Start Date/ Previous Period End Date | Separate fields for start and end date set for previous period on report. | Cost Report | 2025-01-26 |
| Refreshed At | When the object was last refreshed. | Cost Report and Virtual Tag | Aug 13, 2025, 12:59:17 |
| Referenced Tag Keys By Provider | Mapping of tag keys referenced per provider. | Virtual Tag | `{"aws": []}` |
| Settings | Define how the report is displayed or calculated. | Cost Report | `{"include_credits": false, "include_refunds": false, "include_discounts": true, "include_tax": true, "unallocated": false, "amortize": true, "show_previous_period": true, "aggregate_by": "cost"}` |
| Start Date/ End Date | Separate fields for start and end date set for report. | Cost Report | 2025-01-26 |
| Table Layout | How the cost table is displayed: cumulative view or by date view. In audit logs, this may appear as `0` (cumulative\_view) or `1` (by\_date\_view). | Cost Report | 0 (cumulative\_view), 1 (by\_date\_view) |
| Title | The title of the report or canvas. | Cost Report and Canvas | My Cost Report |
| Token | Unique identifier for the object. | Cost Report, Canvas, and Virtual Tag | `rprt_12345abcde67890f`, `cnvs_12345abcde67890f`, `vtag_82741abfce690354` |
| Unit Scale | The unit scale applied to a Business Metric on a Cost Report (per unit, per hundred, per thousand, etc.). | Cost Report | per\_thousand |
| User VQL | Custom Vantage Query Language (VQL) query used to filter the report's data. | Cost Report | `(costs.provider = 'aws' AND costs.service = 'EC2')` |
## Share Audit Logs
You can share an audit log with other Vantage users. The log detail page has a unique URL that allows you to share log events with any authenticated Vantage user who has access to audit logs (i.e., Owners). A URL looks similar to: `https://console.vantage.sh/settings/audit_logs/adt_lg_123a4f5a6c7dab94`.
# Autopilot for AWS Savings Plans
Source: https://docs.vantage.sh/autopilot
Automate AWS Savings Plans purchases with Autopilot.
Autopilot for AWS Savings Plans allows Vantage to purchase Compute Savings Plans and Database Savings Plans commitments on your behalf, with manual and automated options. Autopilot continuously evaluates your compute workloads, and when enabled, can automatically purchase the most suitable Compute Savings Plans to maximize your savings. Compute Savings Plans provide broad coverage, applying to all instance types across any AWS Region. Autopilot also provides savings recommendations for Database Savings Plans (covering Amazon RDS, Aurora, DynamoDB, ElastiCache (Valkey), DocumentDB, Neptune, Keyspaces, Timestream, and AWS Database Migration Service) and Reserved Instances for RDS, ElastiCache, Redshift, and OpenSearch.
At this time, Autopilot supports only AWS; however, there are plans to expand this functionality to GCP and Azure.
## How Autopilot Works
Autopilot works along with the AWS APIs by ingesting and analyzing Cost and Usage Report data. Autopilot will group your compute workloads on the dashboard by instance hour for each respective compute class. A compute class is defined as compute instance usage structured by instance type (e.g., t3.xlarge, r5.large), Region (e.g., us-east-1, us-west-2), and platform (e.g., Linux, Windows), tracked hourly.
### Coverage Determination
Autopilot looks at historical compute usage (up to 3 months) to understand your average compute usage. This method is intended to help find a relatively steady-state compute footprint to base the coverage percentage, avoiding accidentally purchasing too much coverage because of a temporary spike in compute usage. Compute Savings Plans provide flexibility and apply to EC2, Fargate, and Lambda.
### Configurable Lookback Period and Savings Plan Type
Autopilot allows customers to set a lookback period of either 7, 30, or 60 days, which will generate different effective discounts based on actual usage during that period. You can configure the lookback period that most accurately captures your compute usage to ensure the correct coverage level is purchased. Consider the following general suggestions for lookback periods:
* 7 days is a good selection for linearly increasing, steady-state workloads.
* 60 days is a good selection for workloads with higher peak-to-average variation.
You can configure your Savings Plans settings for Autopilot to use 1- or 3-year term lengths and All Upfront, Partial Upfront, or No Upfront payment plans.
### Existing Savings Plans
Autopilot will account for your existing AWS Savings Plans (including Compute Savings Plans and Database Savings Plans) and Reserved Instances. You will not be charged for existing AWS Savings Plans. Even if you feel that you have good coverage with existing AWS Savings Plans, you can consider enabling Autopilot as an insurance policy if they expire or your usage footprint changes.
## Legacy Autopilot (EC2 Reserved Instances)
Because of changes to the underlying Reserved Instance (RI) market, the way Autopilot initially worked changed from supporting AWS Reserved Instances to instead supporting AWS Savings Plans. See the [*Migrate from Autopilot (EC2 RIs) to Autopilot for AWS Savings Plans*](/autopilot#migrate-from-autopilot-ec2-ris-to-autopilot-for-aws-savings-plans) section below for details on how to get started. Consult the following resources for additional information:
* For more details on AWS's changes to RIs, see [this Vantage blog post](https://www.vantage.sh/blog/aws-reserved-instances-updates).
* For a primer on AWS Savings Plans, see the [following Vantage blog post](https://www.vantage.sh/blog/what-is-an-aws-savings-plan).
## Autopilot Permissions
Review the `VantageAutoPilot` policy on the public AWS CloudFormation template, where you can audit the template's [list of required permissions](https://vantage-public.s3.amazonaws.com/vantage-integration-combined-latest.json). This template is the same one that's used when you configure your Vantage and AWS connection.
Autopilot cannot and will never change your underlying infrastructure.
## Enable Autopilot (New Users)
To use Autopilot, ensure that you've [connected AWS](/connecting_aws) as a provider. Then, from the top navigation, select **Financial Planning** > **Autopilot**. If this is your first time using Autopilot, you will need to complete the onboarding workflow for Autopilot.
From the top right of the Autopilot dashboard, click the **Autopilot Enabled** toggle to access the onboarding workflow.
Click **Get Started**. Vantage performs a permissions check to ensure you have the right permissions configured for Autopilot. These permissions are used to view billing data, generate Savings Plans recommendations, and purchase them on your behalf. See the [*Autopilot Permissions*](/autopilot#autopilot-permissions) section above for details. If you fail the permissions check, click **Upgrade Integration** to configure the correct permissions.
Click **Continue**.
Review the provided Autopilot **Master Services Agreement** and click the checkbox to acknowledge that you accept the terms. Click **Accept and Continue.**
Click **Go to Autopilot Dashboard** to begin reviewing your savings.
Autopilot will automatically start to analyze your compute trends and can apply savings within days. Typically, you can expect to wait about one week before you start to see material savings on the Autopilot dashboard.
You can also disable Autopilot at any time. To disable Autopilot, click the **Autopilot Enabled** toggle on the top right of the Autopilot dashboard.
### Migrate from Autopilot (EC2 RIs) to Autopilot for AWS Savings Plans
Autopilot no longer supports purchasing and selling Reserved Instances. If you are a customer that uses Autopilot to manage Reserved Instances, you have three options:
* **Continue to use your Reserved Instances until they expire**: Vantage will continue to charge you for 5% of savings realized from the original purchase of these RIs.
* **Opt in to Autopilot for AWS Savings Plans:** When you opt in, Vantage will list your Reserved Instances for sale on the Reserved Instance marketplace; however, there is no guarantee that these Reserved Instances will sell. If they sell, Autopilot will automatically backfill your Reserved Instances with new Savings Plans coverage.
* **Contact your AWS account team to discuss a migration from Reserved Instances to Savings Plans**: It's been noted that some customers could negotiate with AWS to replace Reserved Instances with Savings Plans, depending on the specifics of the request. Vantage does not have any details about what makes this more likely to succeed with AWS, and it does not seem to be a guarantee that AWS will perform a swap.
If you have any questions, contact [support@vantage.sh](mailto:support@vantage.sh). If you're a current Autopilot customer, a message is displayed at the top of the console to migrate to Autopilot for AWS Savings Plans. Click **Get Started**, and the onboarding workflow previously described will be displayed.
## Review Autopilot for AWS Savings Plans Dashboards
From the Autopilot dashboard, you can toggle between the Compute, RDS, ElastiCache, Redshift, and OpenSearch tabs. This section describes the actions you can take on the **Compute** tab.
### Configuration Screen
After you onboard to Autopilot, the **Compute Configuration** page is displayed. By default, Autopilot is configured to a 60-day lookback with 1-year No Upfront payment types. You can also access this page by selecting **Configuration** from the left menu of the **Compute** tab. On this page, you can configure the following options.
On the Autopilot configuration page, you can configure the lookback period and payment options for both Compute Savings Plans and Database Savings Plans (DBSPs). However, the term length setting applies only to Compute Savings Plans, since Database Savings Plans are available only with 1-year terms.
#### Toggle Automatic Purchases
Automatic Savings Plans purchases are initially disabled. If you want to have Autopilot make Savings Plans purchases on your behalf, click the toggle and acknowledge the displayed confirmation message. You can leave this toggle disabled if you would rather manually approve or decline recommendations. See the [*Review Coverage Recommendations*](/autopilot#review-coverage-recommendations) section below for details on how to manually approve purchases.
#### Lookback Period
Autopilot allows customers to set a lookback period of either 7, 30, or 60 days, which will generate different effective discounts based on actual usage during that period. You can configure the lookback period that most accurately captures your usage to ensure the correct coverage level is purchased.
#### Savings Plan Purchase Configuration
Configure the length of time and payment options for your purchases. For **Term Length**, select either 1- or 3-year term lengths. For **Payment**, select either All Upfront, Partial Upfront, or No Upfront payment plans.
For more information about term lengths and payment options, see [this Vantage blog](https://www.vantage.sh/blog/what-is-an-aws-savings-plan) on Savings Plans.
The configuration settings in Autopilot (lookback period and payment options) apply to both Compute Savings Plans and Database Savings Plans recommendations. However, Database Savings Plans only support 1-year terms, so the term length setting does not apply to Database Savings Plans. Database Savings Plans recommendations are also available in the [Recommendations](/cost_recommendations) tab, where you can view and manage them alongside other cost optimization recommendations.
### Coverage Overview and Recommended Coverage
Based on your configured inputs, Autopilot provides a recommended Compute Savings Plan for purchase to cover the remaining spend. You can view your recommended coverage to get a better idea of how you are currently committed along with Autopilot's recommendations.
#### Coverage Overview
As Autopilot adjusts the commitment level, this tab includes a graph that displays your On-Demand, Savings Plans, and (if applicable) Reserved and Spot Instance usage. The graph shows daily usage, and you can use the date picker above the graph to change the time period that's shown.
Above the graph, your savings are displayed, along with the percentage decrease or increase between this and last month. Your **Coverage** is also displayed, which shows your coverage across all commitment types. Finally, your **All Time Savings** found by Autopilot are displayed.
This page includes all commitments, regardless of whether they're covered by Autopilot.
#### Recommended Coverage
On the **Recommended Coverage** screen, a graph with On-Demand vs. Recommended Coverage is displayed. Above the chart, the **Projected On-Demand Cost** is displayed. This is the remaining On-Demand cost that's estimated to not be covered by the recommended Savings Plans, over the lookback period. On the graph, you can filter by the following options:
* **Service:** Amazon EC2, ECS, Fargate, or Lambda (for Compute Savings Plans)
* **Category:** A compute category that is a representation of your normalized compute workloads (e.g., *USE1-Fargate-GB-Hours*)
* **Region:** AWS Region (e.g., us-east-1)
The table displays the **On-Demand Cost** for each combination of service and compute category. **Recommended Coverage** is displayed as a trendline you can toggle on and off, as shown in the example below. You can also change the date range displayed above the chart.
#### Review Coverage Recommendations
The per-hour **Recommended Coverage** is also displayed in the section above the graph, along with projected savings. Click **Review the recommendation** to review currently active recommendations. The **Review Recommendation** panel is displayed on the right. From this panel, you can view the recommendation based on your term length, lookback, and payment configuration. If you do not have automatic purchases enabled on Autopilot, you can click **Approve Purchase** and Autopilot will make the purchase.
When you review a recommendation, you can also choose a coverage level. Full Coverage is the recommended option, with the commitment level calculated to maximize savings based on your historical usage. If you prefer an incremental purchase strategy, Partial Coverage and Conservative Coverage leave more headroom so you can stagger Savings Plan purchases over time and evaluate smaller purchases later.
The **Approve Purchase** button will not be visible if automatic purchases are enabled.
#### Purchase Window
Note that Vantage generates recommendations daily. When Autopilot makes a purchase, there is a short window where Autopilot doesn't generate additional proposed recommendations so that the recently accepted recommendation can take effect. Ensure that you have not already made a purchase that would cover this recommendation. Autopilot purchases Savings Plans in increments that are eligible for AWS's 7-day return policy threshold, so if there's a mistake or a change in your plans, Vantage can request a return for the unneeded Savings Plans. Autopilot specifically follows [AWS's policy](https://docs.aws.amazon.com/savingsplans/latest/userguide/sp-purchase.html#return-sp) regarding Savings Plan returns:
> *Any Savings Plan with an hourly commitment of \$100 or less that has been purchased in the last seven days and in the same calendar month can be returned. Once the calendar month ends (UTC time), these purchased Savings Plans can no longer be returned.*
In addition, Autopilot also purchases Savings Plans from AWS with a start date that's 24 hours from the time it's manually approved or automatically purchased in Autopilot. During the 24-hour window, the plan is queued. The plan can be deleted at any time within the 24-hour window without restriction. To request a return, contact [support@vantage.sh](mailto:support@vantage.sh).
When a purchase is made, either manually or via an automatic purchase, all account owners will receive an email notification indicating that a purchase was made and will be finalized in 24 hours.
## Autopilot Graphs
Autopilot provides recommendations and the option to purchase Database Savings Plans (covering Amazon RDS, Aurora, DynamoDB, ElastiCache (Valkey), DocumentDB, Neptune, Keyspaces, Timestream, and AWS Database Migration Service) and Reserved Instances for RDS, ElastiCache, Redshift, and OpenSearch.
Database Savings Plans are only available with 1-year terms. The configuration settings in Autopilot (lookback period and payment options) apply to Database Savings Plans recommendations, but the term length is fixed at 1 year.
Vantage automatically reallocates Database Savings Plan costs to linked accounts that consume the discount, using the same cost allocation logic as Compute Savings Plans and Reserved Instances. When you have amortization enabled on a Cost Report, Database Savings Plan fees are allocated to the linked accounts that benefit from the discount, rather than staying in the account that purchased the commitment. This allocation appears in Cost Reports as the `AllocatedAmortizedFee` and `AllocatedAmortizedDiscount` [charge types](https://docs.vantage.sh/cost_reports#charge-type-grouping-category), allowing you to see the commitment costs attributed to the accounts that actually used the discount. For more information about how Vantage handles committed use cost attribution for linked accounts, see this [Committed Use Attribution blog post](https://www.vantage.sh/blog/vantage-launches-committed-use-float-cost-attribution).
The EC2 tab was previously displayed for legacy Autopilot for EC2 Reserved Instances customers. On this tab, you could control the buying and selling of each compute category displayed. These controls are no longer available with Autopilot for AWS Savings Plans. Instead, you can use [Financial Commitment Reports](/financial_commitment_reports) to see a unified view of all your AWS financial commitments, with the ability to filter or create custom aggregations and groupings. Financial Commitment Reports track Savings Plans, Reserved Instances, Spot Instance usage, and EDP discounts for AWS costs.
Recommendations are displayed for individual compute categories, which are a representation of your normalized workloads that consist of the following elements:
* An instance family, such as *m5a*
* A Region
* A platform (e.g., Redis, PostgreSQL Community Edition)
Each compute category has usage tracked hourly and grouped by the following compute types.
* Existing customer usage covered by existing Reserved Instances
* Existing customer usage covered by credits
* On-Demand usage
You can also view associated [active resources](/active_resources). Click the **Active Resources** link at the bottom of the graph.
### RDS
For RDS, the Y-axis unit is expressed in normalized instance units per hour for each compute category. The rationale for this is that RDS has the benefit of flexible instance families, where a Reserved Instance in the smallest possible unit can add up to have multiple units cover a single larger unit in that family.
### Redshift, OpenSearch, and ElastiCache
For **Redshift**, **OpenSearch**, and **ElastiCache**, the Y-axis is expressed as the number of instances. Unlike the above example, there isn't flexibility for these classes, so this is a more straightforward scenario where the units represented are the exact number of instances you should purchase.
### Purchase a Recommendation
For each service, you are provided with the option to view and make purchases for provided savings recommendations. These purchases are manual and not automatically completed by Autopilot.
Above any of the graphs, click **View Savings Recommendations**.
The **Savings Recommendations** panel is displayed on the right. At the top of the panel, select the number of instances you want to purchase. A table of potential options is provided along with potential monthly savings to help you decide on the best option.
Click **Purchase via AWS Console** to make these purchases on AWS.
Note that recommendations for these other services are generated weekly and indicate the date range for which recent Reserved Instance purchases are not included in the current recommendation. Ensure you have not already made a purchase that would cover this recommendation.
# AWS Bedrock Enrichment
Source: https://docs.vantage.sh/aws_bedrock_enrichment
Attribute AWS Bedrock spend to teams, applications, customers, and features using Model Invocation Logs and requestMetadata in Vantage.
Contact Sales (or [support@vantage.sh](mailto:support@vantage.sh)/your account team) to enable LLM Enrichment for your account and discuss availability.
Vantage reads your [Bedrock Model Invocation Logs](https://docs.aws.amazon.com/bedrock/latest/userguide/model-invocation-logging.html) from an S3 bucket. It joins each logged invocation to the matching Bedrock cost row in your [AWS Cost and Usage Report (CUR)](/connecting_aws#cur-format), then splits that cost row into multiple enriched rows, proportionally allocated by token share. Each enriched row carries any `requestMetadata` key/value pairs your application attaches at invocation time, plus [Managed AI Tags](/managed_ai_tags) such as the model, Region, operation, and calling IAM principal. These become tags you can filter and group on in [Cost Reports](/cost_reports), [Virtual Tags](/tagging), [Budgets](/budgets), and [Cost Alerts](/cost_alerts).
This unlocks request-level cost attribution that the CUR alone cannot provide. See the [example use cases](#use-cases) for scenarios such as per-customer margins, per-feature spend, and team chargeback.
AWS Bedrock LLM Enrichment is the native path for Bedrock: you enable Model Invocation Logging in AWS and Vantage reads the logs AWS already writes, with no telemetry to emit from your own applications. If your Bedrock traffic runs through an AI gateway, or you want to attribute spend across several providers from one stream, see [Custom LLM Enrichment](/custom_llm_enrichment) instead.
Do not enable AWS Bedrock LLM Enrichment and [Custom LLM Enrichment](/custom_llm_enrichment) for the same AWS account. Both features allocate the same Bedrock cost rows, so running them together counts the same usage twice in the token pool: your totals still reconcile, but each source's slices receive a diluted share and the attribution becomes misleading. Pick one path per account: use AWS Bedrock LLM Enrichment when AWS writes your Model Invocation Logs, and Custom LLM Enrichment when you emit your own per-request telemetry.
Enrichment is metadata-only. Vantage reads the model, Region, operation, token counts, IAM principal, and the `requestMetadata` you attach at invocation time. Vantage does not collect or store your Bedrock prompt or completion content, and it is never written to a Vantage-owned artifact. This data is not used to train any models.
## How It Works
When logging is enabled, Amazon Bedrock records every model invocation (i.e., `InvokeModel`, `InvokeModelWithResponseStream`, `Converse`, and `ConverseStream`) as a JSON record in your Model Invocation Logs. Each record includes token counts, the model, the calling identity, and the `requestMetadata` your application supplied. Vantage joins those records to your Bedrock CUR costs during AWS cost ingestion.
See [How LLM Enrichment works](/llm_enrichment#how-it-works) for the shared indexing, join, split, and tag pipeline.
### How Bedrock Costs Are Matched
Vantage does not match logs to costs on the model alone, because Bedrock prices the same model differently depending on how it was called. A logged invocation and a cost row are joined on the billing day, the token kind, and the following dimensions:
| Dimension | Why it is part of the join |
| - | - |
| Model | The canonical model identifier, resolved from both sides. See [Model Normalization](#model-normalization). |
| Region | Bedrock prices the same model differently per Region. |
| Operation | Streaming and non-streaming inference are priced separately. |
| Inference scope | Global and regional inference profiles are priced separately. |
| Tier | Standard and batch meters are priced separately. |
The model and the tier must always agree. Region, operation, and inference scope behave as *qualifiers*: when either the log record or the cost row does not report one, that side becomes a *wildcard* that matches any value on the other side. Vantage matches exactly qualified pools of logs first, so a precisely qualified group of invocations claims its cost rows before a wildcard pool can absorb what is left. The tier never wildcards; both sides default to standard. After the join, Vantage narrows the match further by AWS account and, when available, by calling IAM principal.
If you also deliver gateway telemetry for Bedrock, the same qualifiers apply to those records. See [How Telemetry Matches Provider Costs](/custom_llm_enrichment#how-telemetry-matches-provider-costs) for the per-field breakdown.
Token counts are matched per kind, using a shared vocabulary of `input`, `output`, `cache_read`, and `cache_write`.
Bedrock reports cache token counts separately from `inputTokenCount`, so its input count already excludes cached tokens. Vantage accounts for this when normalizing, and does not subtract cache tokens a second time.
### Model Normalization
Model Invocation Logs and the CUR often identify the same model in different ways. A log record may carry an inference-profile ARN:
```text theme={null}
arn:aws:bedrock:us-west-2:123456789012:inference-profile/global.anthropic.claude-opus-4-5-20251101-v1:0
```
While the CUR may carry an AWS Marketplace display name:
```text theme={null}
Claude Opus 4.5 (Amazon Bedrock Edition)
```
Vantage resolves both to the same canonical model key, such as `anthropic.claude-opus-4-5`, so the two sides join. On the cost side, Vantage reads the model identity from the resource ID when it contains a Bedrock foundation-model or inference-profile ARN, then falls back to the transformed model identifier and finally to the service name.
Models and token dimensions that Vantage cannot recognize are not guessed. An unmatchable record is recorded with its normalization reason and excluded from allocation rather than attributed to the wrong model.
### How Cost Rows Are Split
Vantage splits each matching provider cost row into enriched rows, allocated proportionally by token share. Splits are additive, so the enriched rows always reconcile to the original total: usage your logs do not cover stays on a **leftover** row, and cost rows with no matching usage pass through unsplit. Enabling enrichment never changes your totals.
See the allocation formula, a worked example, and how leftover rows keep totals reconciled.
### Data Freshness and Backfill
Enrichment runs inside the existing AWS cost ingestion pipeline, so it follows the same cadence as the rest of your AWS cost data. Month-to-date Bedrock rows are refreshed on every AWS data refresh, and recent days are reprocessed within a rolling three-day window so late-arriving logs are picked up. See the [provider data refresh documentation](/provider_data_refresh) for AWS timing.
There is no Vantage-imposed backfill window: a billing period is enriched whenever it is processed while an active source exists, for as long as the matching logs remain in your bucket. Connecting a source does not, by itself, reprocess months that have already finished importing. Those periods are enriched the next time they are reprocessed, such as when AWS restates that month's CUR or when the period is re-ingested through the [AWS CUR backfill process](/connecting_aws#backfilling-aws-cur-for-previous-reporting-periods).
## Prerequisites
Before you begin, make sure:
* An active [AWS billing (CUR) integration](/connecting_aws) exists for the bucket's AWS account, or for its management/payer account.
* You have a Vantage **Organization Owner** or **Integration Owner** role. See [Role-Based Access Control](/rbac).
## Set Up AWS Bedrock LLM Enrichment
Setup has three steps: [enable Model Invocation Logging in AWS](#step-1-enable-bedrock-model-invocation-logging), [attach `requestMetadata` to your invocations](#step-2-configure-request-metadata-recommended) (optional, but recommended), and [connect the log buckets in Vantage](#step-3-connect-the-log-buckets-in-vantage).
### Step 1: Enable Bedrock Model Invocation Logging
In the AWS Bedrock console (or via the AWS API), enable Model Invocation Logging and choose an **S3 bucket** as the destination. Vantage ingests logs from S3 only; a CloudWatch-only destination is not supported. For full setup instructions, see the [AWS documentation on model invocation logging](https://docs.aws.amazon.com/bedrock/latest/userguide/model-invocation-logging.html).
Model Invocation Logging is disabled by default in AWS and is configured per Region. Enable it in each Region where you invoke Bedrock and deliver the logs to an S3 bucket.
AWS delivers logs as gzipped JSON objects under a predictable prefix. Vantage automatically discovers this prefix from your Bedrock logging configuration, but for reference the path pattern is:
```text theme={null}
{prefix}/AWSLogs/{accountId}/BedrockModelInvocationLogs/{region}/{YYYY}/{MM}/{DD}/{HH}/*.json.gz
```
Each connected bucket is scanned for a single AWS Region, resolved automatically from your Bedrock logging configuration. Because you can connect more than one bucket, multi-Region coverage is a matter of connecting one bucket per Region:
* **One bucket per AWS account**, for example a separate log bucket for Development, Staging, and Production.
* **Multiple regional buckets on the same AWS account**, for example one bucket for `eu-central-1` and another for `us-east-1`.
Connect a bucket for every Region where you invoke Bedrock. Bedrock usage in a Region with no connected bucket still appears in your costs, but it is not split into enriched rows.
Confirm logging is enabled for the Region you deliver to each bucket, and that new objects appear in the S3 bucket after you make a test invocation.
### Step 2: Configure Request Metadata (Recommended)
Request metadata lets you attribute Bedrock cost to per-request dimensions such as team, application, customer, and feature. You attach a flat map of string key/value pairs to each invocation, AWS records it in the `requestMetadata` field of the matching log record, and Vantage surfaces those pairs as tags. Costs for invocations without metadata are still split by the model, Region, operation, and IAM principal, but they will not carry your custom dimensions.
The way you attach metadata depends on the API:
```python Converse / ConverseStream (boto3) theme={null}
import boto3
client = boto3.client("bedrock-runtime", region_name="us-east-1")
response = client.converse(
modelId="anthropic.claude-3-5-sonnet-20240620-v1:0",
messages=[{"role": "user", "content": [{"text": "Summarize this document."}]}],
requestMetadata={
"team": "data-engineering",
"application": "rag-pipeline",
"environment": "production",
"cost-center": "12345",
},
)
```
```http InvokeModel / InvokeModelWithResponseStream (HTTP header) theme={null}
POST /model/anthropic.claude-3-haiku-20240307-v1:0/invoke HTTP/1.1
Content-Type: application/json
X-Amzn-Bedrock-Request-Metadata: {"team": "data-engineering", "application": "rag-pipeline"}
{
"anthropic_version": "bedrock-2023-05-31",
"max_tokens": 50,
"messages": [{"role": "user", "content": "Summarize this document."}]
}
```
* **`Converse` and `ConverseStream`** accept a `requestMetadata` field in the request body.
* **`InvokeModel` and `InvokeModelWithResponseStream`** accept the `X-Amzn-Bedrock-Request-Metadata` HTTP header.
See the AWS guide on [per-request metadata tagging](https://docs.aws.amazon.com/bedrock/latest/userguide/cost-mgmt-request-metadata.html) for full details.
When you sign requests with AWS Signature Version 4 (SigV4), include `X-Amzn-Bedrock-Request-Metadata` in the `SignedHeaders` list. Requests that omit the header from the signed list are rejected with an `InvalidSignatureException`. AWS SDKs that expose request metadata as a parameter handle this automatically.
**Limits and constraints** (apply to both the header and the body field):
| Constraint | Value |
| - | - |
| Maximum entries per request | 16 key/value pairs |
| Key length | Up to 256 characters |
| Value length | Up to 256 characters |
| Allowed characters | Alphanumeric plus a restricted set of punctuation: `a-z A-Z 0-9` and `: _ @ $ # = / + , - .` and whitespace |
Follow these best practices when attaching request metadata:
* Set `requestMetadata` in a shared client or LLM gateway so every invocation is tagged consistently, without relying on each caller to remember.
* Choose stable, low-cardinality keys such as `team`, `environment`, or `feature` for easy aggregation, and reserve high-cardinality values such as `customer_id` or `flow_run_id` for when you need per-entity tracing.
* Avoid placing personally identifiable information (PII), credentials, or other sensitive data in request metadata. Values are stored in your logs and any system that reads them.
* Request metadata is only recorded when Model Invocation Logging is enabled in the Region where the call is made. Otherwise the invocation still succeeds, but no metadata is retained.
Vantage derives some dimensions itself, such as the model, Region, operation, and IAM principal, and surfaces them as [Managed AI Tags](#enrichment-tag-reference). If one of your `requestMetadata` keys collides with one of those names, the value Vantage derives wins. The AWS account and IAM principal are always taken from the log record and cannot be set through `requestMetadata`.
### Step 3: Connect the Log Buckets in Vantage
In Vantage, navigate to the [Integrations page](https://console.vantage.sh/settings/integrations) and, under **LLM Enrichment**, select **AWS Bedrock**, then select the S3 buckets that receive your Bedrock logs. The connect screen walks you through granting read access and validating it.
You can also reach the same screen from the **Bedrock Model Invocation Logs** tab on the [AWS Settings page](https://console.vantage.sh/settings/aws), which appears once at least one AWS account is connected.
You can connect one or more buckets per AWS account, including multiple regional buckets for the same account. Vantage creates one enrichment source per bucket, and each source is scanned for a single Region.
Connecting a bucket reuses your existing [AWS cross-account IAM role](/connecting_aws#how-vantage-connects-with-aws), adding read-only access to the bucket that holds your Model Invocation Logs. It does not create a new role or require new credentials.
Select the S3 buckets that receive your Bedrock logs. You can select several at once. Once Vantage can read your Bedrock logging configuration, the list is narrowed to the buckets Bedrock is actually configured to log to, so you do not have to search your whole S3 inventory; until then, every bucket in the account is listed. Buckets that are already connected or paused are shown with a **Connected** or **Paused** label and cannot be selected again.
If your bucket does not appear in the list, it may not be synced into Vantage's inventory yet. Newly created buckets can take up to 24 hours to appear.
Deploy in the **AWS account that owns the Model Invocation Log bucket**, and make sure the bucket ARN in the policy matches the bucket you connect in Vantage. A mismatch is the most common cause of an `access denied` result when you check permissions.
The connect screen offers three ways to grant access, each prefilled for your account:
The connect screen provides a CloudFormation quick-create link that opens the AWS Console with the stack name, template URL, and parameters prefilled. Acknowledge that CloudFormation may create IAM resources, then create the stack.
The stack applies the [Vantage-published template](https://vantage-public.s3.amazonaws.com/vantage-integration-model-invocation-logging.json) with two parameters:
* `VantageCrossAccountRole`: the name of your existing Vantage cross-account IAM role.
* `ModelInvocationLoggingBuckets`: a comma-separated list of destination bucket ARNs, each as `arn:aws:s3:::your-bucket/*`.
Deploy the stack in the account that owns the bucket, not necessarily your management/payer account. The quick-create link targets `us-east-1`, which only controls where the stack is created; it does not limit which bucket Regions are covered.
The connect screen provides a ready-to-run `aws cloudformation create-stack` command using the same template and parameters as the Console method:
```bash theme={null}
aws cloudformation create-stack \
--stack-name BedrockModelInvocationLogAccess- \
--template-url https://vantage-public.s3.amazonaws.com/vantage-integration-model-invocation-logging.json \
--capabilities CAPABILITY_IAM \
--region us-east-1 \
--parameters \
ParameterKey=VantageCrossAccountRole,ParameterValue= \
ParameterKey=ModelInvocationLoggingBuckets,ParameterValue=arn:aws:s3:::your-bucket/*
```
Run the command with credentials for the AWS account that owns the bucket. For multiple buckets, pass a comma-separated list of ARNs as a single `ParameterValue`.
If you manage your Vantage integration with the [`vantage-sh/vantage-integration/aws`](https://registry.terraform.io/modules/vantage-sh/vantage-integration/aws/latest) module, add the Bedrock read permissions through the module's `additional_inline_policies` argument:
```hcl main.tf theme={null}
module "vantage-integration" {
source = "vantage-sh/vantage-integration/aws"
additional_inline_policies = [
{
name = "BedrockModelInvocationLogs-"
policy = jsonencode({
Version = "2012-10-17",
Statement = [
{
Action = ["s3:GetObject", "s3:GetObjectAcl"],
Resource = ["arn:aws:s3:::your-bucket/*"],
Effect = "Allow"
},
{
Action = ["bedrock:GetModelInvocationLoggingConfiguration"],
Resource = "*",
Effect = "Allow"
}
]
})
}
]
}
```
This attaches the policy to your existing cross-account role; it does not create a new role. Bucket listing and location come from the base role, so only object read and the Bedrock logging-configuration read are added here. Replace `arn:aws:s3:::your-bucket/*` with each destination bucket ARN. See the [Terraform documentation](/terraform#vantage-terraform-integrations-module-for-aws) for base module setup.
Whichever method you use, Vantage needs the following read-only access to validate and ingest your Model Invocation Logs:
| Permission | When it is needed |
| - | - |
| `s3:GetObject` | Read the log objects in the bucket you connect. |
| `bedrock:GetModelInvocationLoggingConfiguration` | Read your Bedrock logging configuration so Vantage can auto-discover the log prefix and Region. |
| `s3:ListBucket` | List objects under the log prefix to find a sample object. |
| `s3:GetBucketLocation` | Resolve the bucket's Region. |
| `kms:Decrypt` | The bucket or objects are encrypted with AWS KMS (SSE-KMS). Without it, Vantage cannot read KMS-encrypted log objects. |
Your existing Vantage cross-account role already grants `s3:ListBucket` and `s3:GetBucketLocation`. The grant above adds only object read on the log bucket (`s3:GetObject`, and the generated policy always includes `s3:GetObjectAcl`) plus the Bedrock logging-configuration read.
The CloudFormation, CLI, and Terraform options above grant S3 and Bedrock read access only. If your log bucket uses SSE-KMS encryption, you must grant `kms:Decrypt` separately. See [KMS-Encrypted Buckets](#kms-encrypted-buckets).
Click **Check Permissions**. Vantage validates that it can read your Bedrock logging configuration, resolve the bucket Region, list objects under the log prefix, and read a sample log object. If the bucket doesn't contain any logs yet, you can still connect: Vantage shows a notice that the bucket looks empty and runs the sample-object checks once logs arrive. Resolve any reported issues using the [Troubleshooting](#troubleshooting) section. Then click **Connect**. Vantage resolves the log prefix and Region for each bucket from your Bedrock logging configuration and begins enriching Bedrock costs on the next AWS data refresh.
A success message confirms the sources are configured. Each bucket then appears in the connected sources table with its AWS account and status.
## Roll Out Across an AWS Organization
For multi-account environments, Vantage publishes a reference [Bedrock Token Allocation solution in the FinOps as Code repository](https://github.com/vantage-sh/finops-as-code/tree/main/cloudformation/bedrock-token-allocation). It uses CloudFormation StackSets to deploy the AWS-side setup across many accounts and Regions at once, rather than repeating the per-bucket steps above by hand.
The toolkit:
* Identifies the accounts and Regions where Bedrock has generated spend.
* Creates or adopts a regional S3 log bucket in each.
* Enables Bedrock Model Invocation Logging to that bucket.
* Adds read access to your existing Vantage cross-account role.
* Verifies that logs are arriving with the fields Vantage needs.
The solution centralizes deployment, not log storage: Model Invocation Logging remains configured per account and Region, and each resulting bucket is still connected to Vantage as its own enrichment source (see [Step 3](#step-3-connect-the-log-buckets-in-vantage)). To protect existing setups, it refuses to overwrite a logging configuration that already points to another bucket or a CloudWatch destination.
Test the template in a single account first, then use the included `preflight.py` and `verify.py` tools to plan and validate the organization-wide rollout before deploying broadly.
## Manage AWS Bedrock Enrichment Sources
Manage your connected buckets from the **AWS Bedrock** integration page. The sources table lists each bucket with its AWS account, creation date, and **Status** (for example, **Pending** before an import starts, **Importing** while one runs, **Stable** once all imports succeed, **Warning** if only some imports fail, **Error** if all imports fail, or **Paused** if the source is stopped). Error details appear beneath the status. Paused sources show a **Resume** button, and each row has an ellipses (**...**) menu with **Stop** for sources that are not paused.
Because Bedrock logs carry their own account and Region path layout, Vantage knows which costs each bucket applies to as soon as it connects. There is no log-scanning step, no provider review screen, and no per-source edit screen, which is how this integration differs from [Custom LLM Enrichment](/custom_llm_enrichment) and [Cloudflare AI Gateway Enrichment](/cloudflare_ai_gateway_enrichment). The details page behind the bucket name has no **Manage** tab for the same reason, so the bucket link opens straight onto the Enrichment Runs table. To change which buckets are connected, connect or stop sources from this page.
### View Import History
In the sources table, select the **bucket name** to open that source's details page, which shows the **Enrichment Runs** table for that bucket.
You can also reach the sources table from the **Bedrock Model Invocation Logs** tab on the [AWS Settings page](https://console.vantage.sh/settings/aws).
The **Enrichment Runs** table lists one row per provider cost integration and billing period that ran enrichment, newest first, with columns for the **Integration** (and its account), **Status**, **Tokens Kept**, **Log Lines Kept**, **Bill Match**, **Billing Period**, and **Last Enriched At**. Lifecycle changes appear as their own rows: **Added** when enrichment is first enabled for an integration, and **Paused** or **Resumed** when you stop, disable, resume, or re-enable it.
The three percentages look similar but measure different things at different stages, so a low number in one column means something very different from a low number in another:
| Metric | Stage | Counts | A Low Value Means |
| - | - | - | - |
| **Tokens Kept** | Join | Tokens | Your logs were read fine, but the usage in them did not line up with your provider bill. |
| **Log Lines Kept** | Log Scan | Log lines | Vantage could not read or index many of your log lines, usually because records are malformed or missing required fields. |
| **Bill Match** | Join | Provider cost rows | Many provider cost rows received no logged usage at all, so they passed through unsplit. Often your logs cover only part of your traffic. |
A low percentage does not change your totals. Usage Vantage cannot attribute stays on a **leftover** row, the unallocated remainder of the original cost row, so the enriched rows always add back up to what the provider billed.
Select the **Tokens Kept** percentage on any run to open **Token Metrics**, which breaks that run down by disposition across the two stages and lets you view sample records for anything that did not make it through.
Full reference for the Import History screen: every column and status, how to read the three percentages, the Log Scan and Join dispositions with a fix for each, sample record fields, and a troubleshooting table.
### Stop a Source
To stop a source, click the ellipses (**...**) next to the row and select **Stop**, then confirm in the **Stop enrichment source** dialog. This is a soft deactivation, not a hard delete: Vantage stops enriching new cost data for that bucket, but your existing enriched history is left unchanged, and the source stays visible in the list so you can bring it back at any time.
Stopping a source does not re-import or roll back already-enriched costs. Going-forward enrichment simply pauses for that bucket until you resume it.
### Resume a Source
To resume a stopped source, select **Resume** in its row. Going-forward enrichment restarts on the next AWS data refresh. A paused bucket cannot be re-added through the connect flow; use **Resume** instead.
## View Enriched Costs on Cost Reports
Once enrichment runs, a single Bedrock CUR line is split into multiple rows, each carrying enrichment tags. You can filter and group by these tags anywhere tags are supported: [Cost Reports](/cost_reports), [Virtual Tags](/tagging), [Budgets](/budgets), and [Cost Alerts](/cost_alerts).
Because enrichment splits (allocates) your Bedrock costs, enrichment tags behave like Vantage's [cost allocation tags](/tagging#cost-allocation-tags): you can build a Virtual Tag on them, but a cost can be allocated only once, so an enrichment tag can belong to only [one allocation chain](/tagging#virtual-tag-allocation-rules).
### Enrichment Tag Reference
| Tag key | Description | Example value |
| - | - | - |
| *Your `requestMetadata` keys* | Every key you attach at invocation time becomes a tag on the enriched rows for that usage slice, verbatim. | `team`, `application`, `customer_id`, `feature` |
| `vntg:ai:model` | The normalized model identifier that generated the cost, derived from the cost row. Vantage adds it to every enriched row. | `claude-opus-4-5` |
| `vntg:ai:model_provider` | The provider family inferred from the model (for example, Anthropic, Amazon, Meta), added automatically alongside `vntg:ai:model` when the family is recognized. | `Anthropic` |
| `vntg:ai:token_type` | The token kind the enriched row covers: `input`, `output`, `cache_read`, or `cache_write`. Added automatically to every enriched row. | `input` |
| `vntg:ai:provider_region` | The Region the request ran in. Promoted from the matching log field when present and renamed under the prefix. | `us-west-2` |
| `vntg:ai:service_tier` | The pricing tier for the usage. | `standard`, `priority`, `flex`, `reserved`, `batch` |
| `vntg:ai:operation` | Whether the invocation was streaming or non-streaming. | `streaming`, `inference` |
| `vntg:ai:inference_scope` | Whether the request used a global or regional inference profile. | `global`, `regional` |
| `vntg:ai:principal_id` | The normalized IAM principal that made the call. See [IAM Principal Normalization](#iam-principal-normalization). | `my-role/session-name` |
| *Existing AWS tags* | Any tags Vantage already puts on your Bedrock cost rows are preserved on the enriched rows, including [Managed AI Tags](/managed_ai_tags) such as `vntg:ai:raw_model`. Where a `vntg:ai:` key is present on both sides, the value derived from your CUR wins. | `vntg:ai:raw_model=anthropic.claude-opus-4-5-20251101-v1:0` |
Your own `requestMetadata` keys appear exactly as you send them, with no prefix. The dimensions Vantage derives and adds itself, such as the model identifier, carry a `vntg:ai:` prefix (for example, `vntg:ai:model`); this keeps them distinct from your keys and consistent with the AI tags Vantage applies across every provider you have connected. Because your key is just `team` (not provider-namespaced), the same key lines up across Bedrock, OpenAI, Anthropic, and the other providers, so you can group your entire AI stack by one `team` tag. Consistent key naming matters: `team` and `Team` are two different keys.
Vantage writes a tag only when the source data provides a reliable value for it, so the exact set you see depends on what your logs and CUR report. See [Managed AI Tags](/managed_ai_tags) for the full cross-provider schema.
Enrichment tags behave like any other provider tag in the console:
* **To group:** open the **Group By** menu, select **Tag**, and choose the tag key, for example `vntg:ai:model`, or one of your own keys such as `team`.
* **To filter:** open the **Filters** menu, click **New Rule**, select **Tag**, choose the **Tag Key**, then pick an operator and one or more values.
The tag keys appear in the **Tag Key** dropdown once enriched costs exist. If you use a handful of keys often, mark them as [preferred tags](/tagging#preferred-tags) so they sort to the top of these menus.
Enriched rows retain your existing AWS tags and add the Vantage-managed `vntg:ai:*` tags (such as `vntg:ai:model`); split rows also carry the `requestMetadata` from their usage slice. When a `vntg:ai:` key is present on both the cost row and the enrichment, the value derived from your CUR wins. The leftover row (usage not covered by your logs) keeps the original CUR dimensions and the applicable `vntg:ai:*` tags but carries none of your `requestMetadata`. The AWS account and IAM principal are always taken from the log record and can never be supplied through `requestMetadata`.
In the example below, a Cost Report splits Amazon Bedrock spend by the `team` and `purpose` metadata attached at invocation time, alongside `vntg:ai:model`, so the same model can be compared across teams and workloads.

### IAM Principal Normalization
Vantage derives `vntg:ai:principal_id` from the caller identity (`identity.arn`) in each log record and normalizes it to a readable value:
| IAM caller ARN shape | Stored `vntg:ai:principal_id` value |
| - | - |
| AWS IAM Identity Center assumed role (`assumed-role/AWSReservedSSO_*/{session}`) | The session name only, e.g. `jane.doe` |
| Other assumed role (`assumed-role/{role}/{session}`) | `{role}/{session}` |
| IAM user (`user/{name}`) | `{name}` |
| IAM role (`role/{name}`) | `{name}` |
| Unrecognized ARN shape | The full ARN, unchanged |
This tag comes from your logs, so it does not depend on your CUR format. When your CUR *also* reports a calling principal, Vantage uses it to narrow which logged invocations can match a given cost row:
* If your logs carry no principal, the match is not scoped by principal.
* If the cost row names a specific user or session, only invocations from that principal can match it.
* If the cost row names a bare IAM role, every logged session of that role can match it.
* If the cost row names a principal that matches none of the logged invocations, that row is left unenriched rather than attributed to the wrong caller.
* If some cost rows for the same model and day name a principal and others do not, the unattributed rows draw only from invocations that carry no principal, so usage is never counted against two callers.
Cost splitting is scoped per AWS account. To distinguish the same principal name across multiple accounts in a report, add both the **Account** dimension and the `vntg:ai:principal_id` tag to your **Group By**.
## CUR 2.0 and IAM Principal Attribution
AWS Bedrock LLM Enrichment works with both AWS Legacy CUR and CUR 2.0. Vantage converts CUR 2.0 rows to a common format before enrichment runs, so the same join and cost-splitting behavior applies regardless of which CUR format your AWS integration uses. See [CUR Format](/connecting_aws#cur-format) for how to enable CUR 2.0.
CUR 2.0 can also attribute Bedrock cost by the calling IAM principal without Model Invocation Logs. When you enable **Include caller identity (IAM principal) allocation data** on the CUR 2.0 export, Vantage surfaces the caller as the `aws:IamPrincipal` tag (plus any activated `aws:iamPrincipal:*` tags), and copies its normalized value into `vntg:ai:principal_id`. You can use this alongside LLM Enrichment, but it is less detailed: it tells you which IAM role or user made the call, not the per-request dimensions (such as team, customer, or feature) that Model Invocation Logs capture. When both sources report a principal, the CUR value takes precedence.
The two paths support different attribution dimensions:
| Attribution dimension | CUR 2.0 IAM principal | Model Invocation Logs (`requestMetadata`) |
| - | - | - |
| IAM role or user that made the call | Supported (`aws:IamPrincipal`) | Supported (`vntg:ai:principal_id`) |
| Team or department | Supported only if each team uses a dedicated IAM role | Supported via a `team` key |
| Per-request dimensions (customer, feature, prompt version, workflow run) | Not supported | Supported via `requestMetadata` keys |
AWS [advises against high-cardinality IAM principal tag values](https://docs.aws.amazon.com/awsaccountbilling/latest/aboutv2/iam-principal-cost-allocation.html#iam-principal-cost-allocation-best-practices) such as customer, session, or request identifiers, so those per-request dimensions belong in `requestMetadata` rather than on IAM principals.
## Troubleshooting
Most errors are displayed when you click **Check Permissions** or **Connect**. The tables below list the messages you may see, their cause, and how to resolve them. Expand a section for the relevant category.
| Message | Cause and fix |
| - | - |
| `Vantage cannot read Bedrock model invocation logging configuration for bucket {bucket}. Grant bedrock:GetModelInvocationLoggingConfiguration to the cross-account role.` | Add `bedrock:GetModelInvocationLoggingConfiguration` to the cross-account role. |
| `Vantage cannot determine the location for bucket {bucket}. Grant s3:GetBucketLocation to the cross-account role.` | Add `s3:GetBucketLocation` to the cross-account role. |
| `Vantage cannot list objects under s3://{bucket}/{prefix}. Grant s3:ListBucket for the configured prefix.` | Add `s3:ListBucket` scoped to the log prefix. |
| `Vantage cannot read object s3://{bucket}/{key}. Grant s3:GetObject to the cross-account role.` | Add `s3:GetObject` (and `s3:GetObjectAcl`) for the bucket. |
| `Vantage cannot decrypt KMS-encrypted object s3://{bucket}/{key}. Grant kms:Decrypt to the cross-account role.` | The bucket uses SSE-KMS. Grant `kms:Decrypt` for the encrypting key. |
| `Vantage could not assume the AWS cross-account role. Verify that the role exists, its trust policy allows Vantage to call sts:AssumeRole, and the configured external ID matches.` | Vantage cannot assume your [cross-account IAM role](/connecting_aws#how-vantage-connects-with-aws). Confirm the role still exists, its trust policy allows Vantage's `sts:AssumeRole`, and the external ID matches. |
Confirm the permissions were deployed in the **AWS account that owns the bucket**, and that the bucket ARN in the policy matches the connected bucket.
| Message | Cause and fix |
| - | - |
| `Bucket {bucket} does not exist or could not be found.` | The bucket does not exist or is not reachable by the role. Verify the name and account. |
| `Bucket {bucket} is not configured as an S3 destination for Bedrock model invocation logging in this account.` | Model Invocation Logging is not enabled to this bucket in this Region/account. [Enable it in AWS](https://docs.aws.amazon.com/bedrock/latest/userguide/model-invocation-logging.html). |
| `Bucket {bucket} is not the configured Bedrock model invocation logging destination (configured destination: {other}).` | The connected bucket differs from the one Bedrock logs to. Connect the actual logging destination bucket. |
| `No Bedrock model invocation logs were found in bucket {bucket}.` | The bucket has no log objects yet. Make a test invocation and wait for delivery, then re-check. |
| `Sample object s3://{bucket}/{key} no longer exists.` | A log object was deleted mid-validation (for example, by a lifecycle rule). Re-run **Check Permissions**. |
| Message | Cause and fix |
| - | - |
| `Bucket {name} could not be found for your account.` (or `Buckets {names} could not be found for your account.`) | The selected bucket is not in Vantage's synced inventory. Newly created buckets can take up to 24 hours to appear. |
| `Buckets cannot be configured more than once: {names}` | The same bucket was selected multiple times. Select it once. |
| `Vantage could not validate bucket {bucket}: {message}` | The permission check failed unexpectedly for that bucket. Re-run **Check Permissions**, and contact [Vantage Support](mailto:support@vantage.sh) if it persists. |
| `Connect AWS billing (CUR) for this AWS account (or its management/payer account) before connecting Bedrock model invocation logs.` | No AWS CUR integration exists for the bucket's account. Connect [AWS billing](/connecting_aws) first. Clicking **Check Permissions** shows the same requirement worded as "…before checking Bedrock log permissions." |
**Pending** means Vantage has not run an enrichment import for this source yet. Enrichment runs during each provider's regular cost ingestion, so a newly connected source shows **Pending** until the next data refresh of a provider it enriches. See the [provider data refresh documentation](/provider_data_refresh) for per-provider timing. If the status is still **Pending** after that refresh, check the following:
* Model Invocation Logging is enabled and still writing logs to the connected bucket (see [Step 1](#step-1-enable-bedrock-model-invocation-logging)).
* An active [AWS billing (CUR) integration](/connecting_aws) exists for the bucket's AWS account, or for its management/payer account.
* The bucket's Region matches the Region where your Bedrock calls are made.
Enrichment can only split costs by dimensions present in your logs. If enriched rows are missing your custom tags:
* Confirm your application is attaching [`requestMetadata`](#step-2-configure-request-metadata-recommended) to Bedrock invocations. Costs from invocations without metadata are split by model, Region, operation, and IAM principal only.
* Confirm Model Invocation Logging is enabled in the **Region** where the calls are made, and that a bucket for that Region is connected. Metadata is recorded only when logging is on for that Region.
* Allow a full AWS data refresh to complete after connecting. Enrichment applies on the next refresh.
Bedrock costs pass through unchanged (no split) when any of the following is true:
* There is no active Model Invocation Log source for the account, the source is paused, or the log import has not completed successfully.
* The cost row is not a Bedrock usage row, or its model, Region, operation, inference scope, tier, or token type could not be matched to a logged invocation.
* The cost row is a batch inference row. Model Invocation Logging does not record asynchronous batch jobs, so batch costs pass through unchanged.
* The cost row reports an IAM principal that does not match any logged invocation.
* Your AWS integration still imports on the legacy cost pipeline, which has no enrichment stage.
Unmatched usage is preserved on the **leftover** row with the original CUR dimensions, so totals always reconcile.
Enrichment tags appear in the console as regular provider tags. To confirm what was enriched:
* **Check coverage in Import History:** Open the source's [Import History](/llm_enrichment_import_history) and review **Tokens Kept** (the share of your logged tokens Vantage attached to a cost row) and **Bill Match** (the share of eligible provider cost rows that received logged usage) for each integration and billing period.
* **Check a Cost Report:** Filter to the provider, then group by one of your own tag keys. Costs from requests that carried that key show its values. The leftover row (the portion of the bill your usage did not cover) and any usage sent without that key appear as **Not tagged with** the key name.
Totals should not change. Splits are additive and always sum to the original cost row to the cent, even when more than one enrichment source is connected. Enrichment only makes new dimensions available on the underlying rows; it never adds or removes cost.
If your totals reconcile but the split looks wrong, check whether more than one feature is enriching the same Bedrock costs, such as AWS Bedrock LLM Enrichment and [Custom LLM Enrichment](/custom_llm_enrichment) both being active for the same AWS account. When two sources describe the same invocations, their tokens pool into a single denominator, so each source's slices receive a diluted share and the same usage is represented twice under two different sets of metadata. The totals still reconcile, but the attribution is misleading. Enable only one per AWS account.
### KMS-Encrypted Buckets
If the bucket you connect is encrypted with AWS Key Management Service (KMS), **Check Permissions** reports a decryption error until Vantage can read the objects. Either remove encryption on the bucket, or grant the cross-account role `kms:Decrypt` for the encrypting key and allow that role in the KMS key policy.
The CloudFormation, CLI, and Terraform options in [Step 3](#step-3-connect-the-log-buckets-in-vantage) grant S3 and Bedrock read access only, so KMS access must be added separately.
## Use Cases
Each row below shows example `requestMetadata` keys to attach to your Bedrock calls and what that attribution enables in Vantage. The key names are examples; you choose your own, and Vantage surfaces whatever `requestMetadata` you send. "Attach" means including those key/value pairs in each invocation's `requestMetadata`, as shown in [Step 2](#step-2-configure-request-metadata-recommended). All rows assume Model Invocation Logging is enabled and the bucket is connected.
| Use Case | Attach to `requestMetadata` | What It Enables |
| - | - | - |
| Chargeback by team or cost center | `team`, `cost-center` | Group a [Cost Report](/cost_reports) by `team` for a per-team Bedrock chargeback, or roll `team` values into a business hierarchy with a [Virtual Tag](/tagging). |
| Per-customer margins (SaaS) | `customer_id` | Group by `customer_id` to see Bedrock spend per customer for margin analysis and pricing validation, which CUR IAM principal tags cannot provide. |
| Per-feature spend | `feature` | Compare cost per product feature (for example, `summarization` vs. `classification`), or across A/B prompt variants. |
| Environment separation | `environment` | Filter non-production inference out of showback reports, or budget each environment (`production`, `staging`) separately. |
| Streaming and inference-profile mix | (none required) | Group by `vntg:ai:operation` or `vntg:ai:inference_scope` to see how much of your spend comes from streaming calls or global inference profiles, which are priced separately. |
## Frequently Asked Questions
You need the **Organization Owner** or **Integration Owner** role to connect the source. Viewing the enriched costs does not require a special role; the resulting tags follow the same access rules as other cost data. See [Role-Based Access Control](/rbac).
Read-only access to the Model Invocation Log bucket you connect: `s3:GetObject`, `s3:ListBucket`, `s3:GetBucketLocation`, and `kms:Decrypt` for KMS-encrypted objects (generated policies may also include `s3:GetObjectAcl`), plus `bedrock:GetModelInvocationLoggingConfiguration` to auto-discover the log prefix and Region. The policy attaches to your existing cross-account role; no new role is created. See [Step 3: Connect the Log Buckets in Vantage](#step-3-connect-the-log-buckets-in-vantage).
Use AWS Bedrock LLM Enrichment. It is the native path: AWS writes the Model Invocation Logs for you, so there is no telemetry to emit or maintain in your own applications. [Custom LLM Enrichment](/custom_llm_enrichment) is the right choice when your Bedrock traffic runs through an AI gateway that already emits per-request telemetry, or when you want one telemetry stream to cover several providers at once. Do not enable both for the same AWS account. They allocate the same Bedrock cost rows, so the same usage is counted twice in the token pool and each source's slices receive a diluted, misleading share.
No. Splits are additive and always sum to the original cost row. Existing provider-level reports continue to show the same totals; enrichment only makes new dimensions available on the underlying rows.
There is no Vantage-imposed backfill window: a billing period is enriched when it is processed while a source is active, as long as the matching logs are still in your bucket. The current month enriches automatically on the next refresh. Months that have already finished importing are not reprocessed just by connecting a source; they are enriched the next time they are reprocessed, such as a CUR restatement from AWS or a re-ingestion through the [AWS CUR backfill process](/connecting_aws#backfilling-aws-cur-for-previous-reporting-periods).
No. Bedrock Model Invocation Logging records runtime calls only, so asynchronous batch inference costs pass through without being split.
Connect one bucket per Region and per AWS account. Each connected bucket becomes its own enrichment source and is scanned for a single Region, and you can connect several at once from the same screen. See [Step 1](#step-1-enable-bedrock-model-invocation-logging).
Vantage publishes a reference [Bedrock Token Allocation solution in the FinOps as Code repository](https://github.com/vantage-sh/finops-as-code/tree/main/cloudformation/bedrock-token-allocation) that uses CloudFormation StackSets to enable Model Invocation Logging and grant read access across many accounts and Regions at once. Each resulting bucket is still connected to Vantage as its own enrichment source. See [Roll Out Across an AWS Organization](#roll-out-across-an-aws-organization).
Configuration of the enrichment source is done in the Vantage console. The AWS-side permissions can be deployed via CloudFormation, the AWS CLI, or Terraform (see [Step 3: Connect the Log Buckets in Vantage](#step-3-connect-the-log-buckets-in-vantage)).
No code changes are required to invoke Bedrock. To attribute costs by your own dimensions, attach [`requestMetadata`](#step-2-configure-request-metadata-recommended), a standard Bedrock invocation parameter, to your calls.
No. Enrichment is metadata-only. Vantage reads the model, Region, operation, token counts, IAM principal, and the `requestMetadata` you attach at invocation time. Prompt and completion text are never collected or stored.
# AWS Services & Regions for Active Resources
Source: https://docs.vantage.sh/aws_supported_services
Vantage supports a number of AWS services for reporting and viewing active resources.
## Supported Services
Vantage will show 100% of your organization's accrued costs across all services. Vantage also offers per-resource pricing for the following services using custom logic to query APIs for each AWS service. While Vantage supports per-resource pricing for the most popular services, some services are not currently supported.
To request new service support on Vantage, email [support@vantage.sh](mailto:support@vantage.sh) with the subject line of *New AWS Service Support*. Include as much information as you can about the data you want to see.
Below is a list of currently supported AWS services for [active resources](/active_resources). Vantage maintains read-only access to the AWS APIs for these resources.
| Service | Description/Supported Resources |
| - | - |
| AppStream | Vantage supports AppStream fleets and image builders. |
| Auto-Scaling Groups | Vantage supports Auto-Scaling Groups. |
| AWS Backup | Vantage supports Backup Vault recovery points. |
| AWS Batch | Vantage supports Batch job definitions. |
| CloudFront | Vantage supports CloudFront distributions. |
| CloudTrail | Vantage supports CloudTrail trails. |
| CodePipeline | Vantage supports CodePipeline pipelines. |
| CloudWatch | Vantage supports CloudWatch Log Groups. |
| CodeBuild | Vantage supports CodeBuild projects. |
| Cost and Usage Reports | Vantage supports CUR Report Definitions. |
| AWS Config | Vantage supports Config rules. |
| Direct Connect | Vantage supports Direct Connect connections and virtual interfaces. |
| DocumentDB | Vantage supports Amazon DocumentDB (with MongoDB compatibility) cluster instances. |
| DynamoDB | Vantage supports DynamoDB tables. |
| EBS | Vantage supports EBS volumes and all volume types with corresponding pricing. |
| EC2 | Vantage supports EC2 instances and Reserved Instances. Vantage also supports all instance types, on-demand and spot pricing, CloudWatch metrics and logs, and imports underlying EC2 images where possible. |
| ECS | Vantage supports ECS container services and task definitions. |
| EFS | Vantage supports EFS file systems. |
| ECR | Vantage supports ECR container repositories. |
| ELB | Vantage supports Load Balancers. |
| ElastiCache | Vantage supports ElastiCache clusters. |
| EKS | Vantage supports EKS clusters. |
| EMR | Vantage supports EMR clusters. |
| Elasticsearch Service | Vantage supports Elasticsearch domains. |
| Fargate | Vantage supports Fargate services through ECS container services. |
| FSx | Vantage supports FSx file systems and volumes. |
| Glacier | Vantage supports Glacier vaults. |
| Global Accelerator | Vantage supports Global Accelerator accelerators. |
| Glue | Vantage supports Glue jobs. |
| Lambda | Vantage supports Lambda functions. |
| KMS | Vantage supports KMS keys. |
| Amazon MemoryDB | Vantage supports MemoryDB clusters. |
| Amazon MSK | Vantage supports MSK Kafka clusters. |
| Media Services | Vantage supports MediaLive channels, MediaConvert jobs, MediaConnect flows, MediaPackage channels, MediaPackage VOD assets, MediaStore containers, MediaTailor channels, and MediaTailor configurations. |
| MQ | Vantage supports MQ brokers. |
| Amazon Neptune | Vantage supports Neptune database instances and clusters. |
| Networking | Vantage supports networking resources including internet gateways, IP addresses, NAT gateways, network interfaces, prefix lists, route tables, subnets, transit gateways, VPC endpoints, VPC peering connections, VPCs, VPN gateways, and WAFV2 Web ACLs. |
| Outposts | Vantage supports Outposts outposts. |
| Redshift | Vantage supports Redshift clusters. |
| Route 53 | Vantage supports Route 53 hosted zones and resolver query log configurations. We also have write access for Route 53 Record Sets. |
| RDS | Vantage supports RDS instances, Reserved Instances, and snapshots. |
| S3 | Vantage supports S3 buckets and corresponding bucket pricing. We provide daily storage and object count figures. Vantage shows total costs per S3 bucket as well as summaries by storage classes. Vantage will also provide some calculations for you to determine savings impact of enabling S3 Intelligent-Tiering. We do not have permission to read from your S3 buckets. |
| SageMaker | Vantage supports SageMaker models. |
| Savings Plans | Vantage supports AWS Savings Plans. |
| Secrets Manager | Vantage supports AWS Secrets Manager secrets. We do not have permissions to read your secrets. |
| SNS | Vantage supports SNS topics. |
| SQS | Vantage supports SQS queues. |
| Transfer | Vantage supports AWS Transfer servers. |
| VPC Flow Logs | Vantage supports VPC Flow Logs. |
| WorkSpaces | Vantage supports WorkSpaces workspaces. |
## Supported Regions
Vantage can sync resources from all AWS regions with external connectivity.
# Azure Services & Regions for Active Resources
Source: https://docs.vantage.sh/azure_supported_services
Vantage supports a number of Azure services for reporting and viewing active resources.
## Supported Services
Vantage will show 100% of your organization's accrued costs across all services. Vantage also offers per-resource pricing for the following services using custom logic to query APIs for each Azure service. While Vantage supports per-resource pricing for the most popular services, some services are not currently supported.
To request new service support on Vantage, email [support@vantage.sh](mailto:support@vantage.sh) with the subject line of *New Azure Service Support*. Include as much information as you can about the data you want to see.
Below is a list of currently supported Azure services for [active resources](/active_resources). Vantage maintains read-only access to the Azure APIs for these resources.
| Service | Description/Supported Resources |
| - | - |
| App Service | Vantage supports App Service plans. |
| Application Gateway | Vantage supports Application Gateways. |
| Azure Backup | Vantage supports Recovery Services vaults and backup protected items. |
| Azure Cache for Redis | Vantage supports Redis caches. |
| Azure Compute | Vantage supports compute snapshots and virtual machines. |
| Azure Container Registry | Vantage supports Container Registries. |
| Azure Cosmos DB | Vantage supports Cosmos database accounts. |
| Azure Databricks | Vantage supports Databricks workspaces. |
| Azure Database for PostgreSQL | Vantage supports PostgreSQL servers and flexible servers. |
| Azure ExpressRoute | Vantage supports ExpressRoute circuits. |
| Azure Firewall | Vantage supports Azure Firewalls. |
| Azure Kubernetes Service (AKS) | Vantage supports AKS managed clusters. |
| Azure Monitor Application Insights | Vantage supports Application Insights components. |
| Azure Monitor Log Analytics | Vantage supports Log Analytics workspaces. |
| Azure SQL | Vantage supports SQL databases, SQL managed instances, and elastic pools. |
| Azure Storage | Vantage supports Storage accounts and disks. |
| Azure Synapse Analytics | Vantage supports Synapse workspaces. |
| Azure Virtual Machines | Vantage supports virtual machines and virtual machine scale sets. |
| Azure Virtual Network | Vantage supports NAT gateways. |
| Domain Services | Vantage supports domain names. |
| Load Balancer | Vantage supports Load Balancers. |
| Logic Apps | Vantage supports Logic Apps workflows. |
| Microsoft Defender for Cloud | Vantage supports security pricing configurations. |
| Power BI Embedded | Vantage supports Power BI Dedicated Capacity. |
| Private Endpoints | Vantage supports private endpoints. |
| Public IP Addresses | Vantage supports public IP addresses. |
| Virtual Network Gateway | Vantage supports virtual network gateways. |
## Supported Regions
Vantage can sync resources from all Azure regions with external connectivity.
# Budgets
Source: https://docs.vantage.sh/budgets
Create and manage budgets in Vantage to track cloud spending, set cost thresholds, and receive alerts.
You can create and assign a *budget* to a Cost Report. Once a budget is assigned, it's easy to see how costs are trending for a particular service, business unit, or team. A budget can track either cumulative **cost** (dollar spend) or a **usage** quantity, such as tokens consumed, EC2 instance-hours, or GB of data transfer, so you can plan against the same units you're billed or metered in. Each budget runs on a *budget period* that can run anywhere from a single day up to multiple years, so budgets align to how your team actually plans. You can also create *budget alerts* to alert you based on configurable thresholds.
To get started with budgets, you can also view video demos on [Vantage University](/vantage_university_budgeting) .
## Budget Types
In Vantage, you can create either *Standard* or *Hierarchical* budgets:
### Standard Budget
This type of budget has one level with a defined budget period and one or more periods of budgeted amounts associated with it. For example, you could use this type of budget to track costs for a single department or project.
### Hierarchical Budget
This type of budget is made up of multiple child budgets that roll up to a parent budget.
* For example, an application team can create individual budgets for AWS, Azure, and Databricks usage and then create a single budget for their application that combines all three of these child budgets. If the AWS budget changes, the parent application budget is automatically updated.
* Similarly, the organization’s FinOps team can consolidate multiple AWS budgets from various teams into a single, comprehensive parent budget to measure all AWS spend.
Hierarchical Budgets have the following characteristics:
* You can create a budget hierarchy with a maximum of 10 levels.
* A Hierarchical Budget does not have its own budget period or amounts. Instead, it aggregates the periods and amounts of its child budgets. If a child budget has no allocated budget for a specific period, that period contributes nothing to the parent’s total.
* Every child budget under the same parent must cover the exact same current period, both the same length and the same dates. For example, you can combine budgets that are all monthly and start on the same day, but you can't mix a monthly budget with a weekly one, and you can't combine two monthly budgets if one starts on the 1st and the other on the 15th (their periods don't line up). If a budget's period doesn't match, Vantage won't let you add it as a child.
* Every budget in a hierarchy must share the same metric (**Cost** or **Usage**), and Usage budgets must also share the same usage unit. You can't mix Cost and Usage budgets, or different usage units, under the same parent. The parent budget inherits its metric and unit from its children.
* A child budget can be used only once within a given hierarchy.
* *Example: You create a hierarchy with a parent budget for the "Marketing Organization" and child budgets for "Social Media Campaigns," "Event Marketing," and "Content Creation." The child budget for "Social Media Campaigns" cannot also appear under "Event Marketing" within the same hierarchy to avoid duplication in budget calculations.*
* A child budget can belong to multiple separate hierarchies.
* *Example: Suppose your organization is structured both by departments and projects. A child budget for "Mobile App Redesign" might belong to the "Product Development" department’s hierarchy, while also appearing in a completely separate hierarchy for cross-functional "Q1 Strategic Initiatives." This allows you to manage and report on budgets across different organizational contexts.*
## Cost and Usage Budgets
Every budget tracks one of two metrics, which you choose when you create or edit the budget:
* **Cost**: Tracks cumulative dollar spend against your budgeted amount. This is the default, and all existing budgets remain Cost budgets unless you change them.
* **Usage**: Tracks a usage quantity, such as tokens consumed, EC2 instance-hours, or GB of data transfer, against a budgeted amount expressed in that unit, rather than in dollars. This is useful for monitoring prepaid credits, committed usage, or metered consumption directly in the units you're billed in.
A Usage budget measures a usage quantity that already appears in its attached Cost Report, so the budget must be assigned to a Cost Report that contains usage data. The available units (for example, `Tokens` or `GB`) are sourced from that report, and you choose which unit to budget against. Budgeted amounts, actuals, and variance for a Usage budget are then all shown in that unit instead of dollars.
You can also pair a Cost budget and a Usage budget on the same Cost Report, for example to track AI spend in dollars and token consumption side by side. A report holds at most one budget per metric: one Cost and one Usage.
The metric is selected per budget. Within a Hierarchical Budget, every budget must share the same metric and, for Usage budgets, the same usage unit. You can't mix Cost and Usage budgets, or different usage units, in one hierarchy. See [Budget Types](/budgets#budget-types) for details.
## Budget Periods
Every Standard Budget runs on a *budget period*, which is defined by a **start date** and a **period length**. Rather than choosing a named cadence, you enter a number and a unit (**Days**, **Weeks**, **Months**, or **Years**), for example, `1 Week` for a weekly budget, `1 Month` for a monthly budget, `3 Months` for a quarterly budget, or `1 Year` for an annual budget.
Vantage automatically generates the sequence of periods from the start date, and you assign a budgeted amount to each period.
A budget period measured in months or years can't exceed how far back your account retains cost and usage data. This retention window is defined by your Vantage contract. If you choose a period longer than your retention window, Vantage displays an error similar to: *"interval exceeds your account's 6-month cost data retention window."* Period lengths measured in days or weeks are always allowed.
## Budgets Screen
To access the main **Budgets** screen in the console:
1. From the top navigation, click **Financial Planning**.
2. On the left navigation, select **Budgets**.
All existing budgets are displayed here. You can also edit or delete budgets from this screen.
The main **Budgets** screen lists budgets in an expandable tree. Hierarchical budgets are labeled and can be expanded to reveal the child budgets that roll up under them. The following columns are available:
| Column | Description |
| - | - |
| **Name** | Links to each budget's configuration screen. |
| **Metric** | Whether the budget tracks **Cost** or **Usage**. |
| **Current Period** | The date range of the budget's active period (for example, *Aug 1, 2026 – Aug 31, 2026*). |
| **Current Period Performance Summary** | A progress bar comparing actual spend against the budgeted amount for the current period. |
| **Cost Report** | The attached Cost Report. Only terminal child budgets can be associated with a Cost Report. |
| **Status** (optional) | The current-period utilization state (see [Utilization states](/budgets#utilization-states)). Enable it from **Manage Columns**. |
| **Created By** (optional) | Who created the budget. Enable it from **Manage Columns**. |
Use the **Cost Report**, **Budget structure** (**Standard Budgets** or **Hierarchical Budgets**), and **Budget metric** (**Cost Budgets** or **Usage Budgets**) filters to narrow the list, and the **search** field to find a budget by name. Click **Manage Columns** to choose which columns are shown or to reset to the defaults; you can also reorder columns by dragging one up or down in the list (or focusing it and using the arrow keys). Required columns such as **Name** stay in a fixed position. Click **Import** (next to **New budget**) to upload budgets from a CSV.
## Create a Budget - UI Method
The below instructions describe how to manually create a budget in the UI. You can also upload a CSV file to create a budget. See the [section below](/budgets#create-a-budget-csv-import-method) for details.
Begin on the main **Budgets** screen. From the top right of the screen, click **New budget** and choose either **Standard budget** or **Hierarchical budget**. The options that follow differ for each budget type.
The **New Standard Budget** dialog is displayed. Configure the following:
* **Name your budget**: Enter a descriptive name. You can rename it later.
* **Select costs to measure your budget against**: Select the Cost Report you want the budget to track and be displayed on. See the [section below](/budgets#view-budgets-on-cost-reports) for details.
*Note: Budgets are scoped to a report within a specific [workspace](/workspaces/), and access can be controlled via [teams](/rbac).*
* **Choose what to budget**: Select **Cost** to budget against cumulative spend, or **Usage** to budget against a usage quantity from the selected Cost Report. You must select a Cost Report first. If you choose **Usage**, select the usage unit to track (for example, `Tokens`). When a report has several usage units, the highest-volume unit is selected by default. See [Cost and Usage Budgets](/budgets#cost-and-usage-budgets) for details.
*Note: A Cost Report can hold one Cost budget and one Usage budget. If the report you select already has a budget for one metric, that option is disabled and the other is selected automatically (for example, "This cost report already has a Cost budget. Create a Usage budget instead."). A report leaves the picker only once both its Cost and Usage slots are filled.*
*Note: If the selected Cost Report has no usage data, Vantage displays a warning such as "This cost report has no usage unit. Choose a report with usage data." Choose a report that includes usage data, or budget against Cost instead.*
* **Set a start date**: The first budget period starts on this date, and future periods follow the selected schedule.
* **Set the period length**: Enter a number and select a unit (**Days**, **Weeks**, **Months**, or **Years**). See [Budget Periods](/budgets#budget-periods) for common cadences and limits.
Click **Continue** to create the budget and open its detail page.
Next, add budget periods and amounts. On the **Manage** tab, in the **Budget Periods** section, click **Add period** to add a period, then enter a **Budget amount** for each period. You can also click **Upload a CSV** to import periods for this budget. Each period row displays a **Start Date**, an **End date**, and a **Budget amount**.
For a Usage budget, the **Budget amount** column is labeled with the selected unit (for example, **Budget amount (Tokens)**), and you enter each period's budget as a usage quantity rather than a dollar amount.
To create a budget hierarchy, it’s recommended to start by creating all your terminal child budgets as **Standard** budgets. Once the child budgets are in place, you can proceed to create the parent budgets. This ensures that the child budgets are available to select and connect when setting up the parent budget.
Selecting **Hierarchical budget** creates a new parent budget and opens its detail page. On the **Manage** tab, use the hierarchy editor to add the immediate child budgets that directly roll up to this parent. Click **Add child budgets** to open the picker and select them. For example, if you have an "Org" budget with a "Department" budget as its child, and the "Department" budget has a "Team" budget as its child, you would only select the "Department" budget as the child when creating the "Org" budget.
All child budgets in a hierarchy must share the same budget period. Budgets on a different cadence are disabled in the picker with the note *"Child budgets must share the same current period."* Child budgets must also match the hierarchy's metric and usage unit; if they don't, Vantage blocks the addition with a message such as *"Cannot add Usage budgets to a Cost budget hierarchy. Select Cost budgets only."* or *"Cannot mix usage units in a hierarchy. Select budgets that share the same usage unit."* See [Budget Types](/budgets#budget-types) for details.
Hierarchical Budgets do not have their own budget period, budget amounts, or Cost Report. These are configured on the terminal child budgets, and the parent aggregates them automatically.
At the top right, click **Save Changes**.
### Edit Budget Settings
To edit a budget after creation, open it and go to the **Manage** tab. What you can change depends on the budget type.
The **Budget Settings** section summarizes the current **Name**, **Cost Report**, **Metric**, **Start Date**, and **Period Length**. The **Metric** row shows whether the budget tracks **Cost** or **Usage** (for a Usage budget, the unit is shown, for example *Usage (Tokens)*). A matching badge appears in the budget's detail page header, showing **Cost** or **Usage · ** (for example, **Usage · Tokens**). Click **Edit settings** to open the **Edit Budget Settings** dialog. You can always update the **Name** and **Cost Report**. The **Start Date** and **budget frequency** (period length) are fixed once the budget has any periods, so those fields are disabled with the tooltip *"Start date and budget frequency can't be edited while budget periods exist."* The **Budget Periods** section below is where you add, edit, or remove individual periods and amounts.
You can switch a budget's metric (**Cost** or **Usage**) or its usage unit from **Edit settings**, but doing so removes any periods you've already entered, since amounts are denominated in different units. Vantage warns before you save: *"Saving this change will delete all existing budget periods. This action cannot be undone."*
Use the **Date range** filter above the periods table to control which periods are shown; for a newly created budget it defaults to the last 12 months. Before any periods are added, the section shows the empty state *"You haven't created any budget periods yet."*
If periods you just added or imported don't appear in the **Budget Periods** table, they're most likely outside the current **Date range** filter rather than missing. Open the **Date range** filter and widen the range.
A budget's cadence (its start date and period length) can be changed only while the budget has no periods. Once any period exists, the cadence is locked. Attempting to change it returns the error *"Budget cadence cannot be changed after creation."*
The **Manage** tab shows the budget hierarchy, where you add or remove the child budgets that roll up to this parent. Rename the budget using the editable title at the top of the page. Hierarchical Budgets have no Cost Report, start date, period length, or amounts of their own. Those are set on the terminal child budgets.
## Create a Budget - CSV Import Method
If you have existing budgets in spreadsheets or another tool, you can import them all at once by uploading a CSV file.
### Expected Format
Budget import files must adhere to the following requirements:
* The file must be in a valid CSV format.
* The header row of the CSV must start with a unique string or identifier (e.g., `Budget Name`).
* The remaining values in the header row are budget period start dates. Use `YYYY-MM` format for monthly periods (e.g., `2026-08` for August 2026), or `YYYY-MM-DD` for any cadence (e.g., `2026-08-01`). Each period column header is the period's start date, and the period ends the day before the next column.
* Each additional row in the CSV must start with the name of the budget. Corresponding values must be expressed as decimals (e.g., `25000.00`) for every period with an associated budget. If there is no budget for a period, the value can be blank.
* If the budget is a Hierarchical Budget, include the `Parent Budget` column.
* To set a budget's [period](/budgets#budget-periods) cadence, include the optional **`Start Date`**, **`Interval Count`**, and **`Interval Unit`** columns. `Interval Unit` must be one of `day`, `week`, `month`, or `year`. If you omit these columns, the budget uses the default monthly cadence.
* To create a Usage budget, include the optional **`Budget metric`** column set to `cost` or `usage`, and the **`Usage unit`** column set to a usage unit available on the budget's Cost Report (for example, `Tokens`). If you omit `Budget metric`, the budget defaults to `cost`. Period values for a Usage budget are entered as usage quantities rather than dollars.
#### Standard Budget Format
The below example of three Standard Budgets shows a readable view, CSV file format, the budget import screen, and the final budgets in Vantage. Team 3 does not have a budget for 2026-10, and therefore, no budget period is added for Team 3 during that timeframe. On the import, the period start and end date are set based on the column headers.
| Budget Name | 2026-08 | 2026-09 | 2026-10 |
| - | - | - | - |
| Team 1 | 50000 | 51000 | 52000 |
| Team 2 | 30000 | 30000 | 40000 |
| Team 3 | 45000 | 50000 | |
```bash theme={null}
Budget Name,2026-08,2026-09,2026-10
Team 1,50000,51000,52000
Team 2,30000,30000,40000
Team 3,45000,50000,
```
#### Set the Budget Period via CSV
To import a budget on a cadence other than monthly, add the **`Start Date`**, **`Interval Count`**, and **`Interval Unit`** columns and use `YYYY-MM-DD` period column headers that align to the cadence. The example below creates a budget on a two-week cadence starting `2026-08-01`, with \$5,000 budgeted per period.
| Budget Name | Start Date | Interval Count | Interval Unit | 2026-08-01 | 2026-08-15 |
| - | - | - | - | - | - |
| Platform Weekly | 2026-08-01 | 2 | week | 5000 | 5000 |
```bash theme={null}
Budget Name,Start Date,Interval Count,Interval Unit,2026-08-01,2026-08-15
Platform Weekly,2026-08-01,2,week,5000,5000
```
#### Usage Budget Format
To import a Usage budget, add the **`Budget metric`** and **`Usage unit`** columns. Set `Budget metric` to `usage` and `Usage unit` to a unit available on the budget's Cost Report. Period values are usage quantities, not dollars. The example below budgets a monthly token allowance.
| Budget Name | Budget metric | Usage unit | 2026-08 | 2026-09 | 2026-10 |
| - | - | - | - | - | - |
| AI Token Budget | usage | Tokens | 5000000 | 5500000 | 6000000 |
```bash theme={null}
Budget Name,Budget metric,Usage unit,2026-08,2026-09,2026-10
AI Token Budget,usage,Tokens,5000000,5500000,6000000
```
You can combine the Usage columns with the cadence columns (`Start Date`, `Interval Count`, `Interval Unit`) and the `Parent Budget` column, just like Cost budgets. Remember that every budget in a hierarchy must use the same metric and usage unit.
#### Hierarchical Budget Format
The below example of a Hierarchical Budget shows a readable view, CSV file format, the budget import screen, and the final budget in Vantage. Note that the parent budgets—Engineering Org, Development Dept, and Infrastructure Dept—do not have any amounts listed since these budgets are composed of the corresponding child budgets—Frontend Redesign, Backend Refactor, New Cloud Environment, and Cost Optimization Task. The associated next-level parent is listed in the `Parent Budget` column.
| Budget Name | Parent Budget | 2026-08 | 2026-09 | 2026-10 |
| - | - | - | - | - |
| Engineering Org | | | | |
| Development Dept | Engineering Org | | | |
| Infrastructure Dept | Engineering Org | | | |
| Frontend Redesign | Development Dept | 30000 | 35000 | 35000 |
| Backend Refactor | Development Dept | 40000 | 45000 | 50000 |
| New Cloud Environment | Infrastructure Dept | 60000 | 60000 | 60000 |
| Cost Optimization Task | Infrastructure Dept | 20000 | 30000 | 40000 |
```bash theme={null}
Budget Name,Parent Budget,2026-08,2026-09,2026-10
Engineering Org,,,,
Development Dept,Engineering Org,,,
Infrastructure Dept,Engineering Org,,,
Frontend Redesign,Development Dept,30000,35000,35000
Backend Refactor,Development Dept,40000,45000,50000
New Cloud Environment,Infrastructure Dept,60000,60000,60000
Cost Optimization Task,Infrastructure Dept,20000,30000,40000
```
You can combine the two formats to import a hierarchy on a non-monthly cadence: add the cadence columns to each child row and keep every child on the same schedule. In the example below, both child budgets are weekly starting `2026-08-01`, so they roll up cleanly under the parent.
| Budget Name | Parent Budget | Start Date | Interval Count | Interval Unit | 2026-08-01 | 2026-08-08 |
| - | - | - | - | - | - | - |
| Platform Org | | | | | | |
| Frontend | Platform Org | 2026-08-01 | 1 | week | 2000 | 2000 |
| Backend | Platform Org | 2026-08-01 | 1 | week | 3000 | 3000 |
```bash theme={null}
Budget Name,Parent Budget,Start Date,Interval Count,Interval Unit,2026-08-01,2026-08-08
Platform Org,,,,,,
Frontend,Platform Org,2026-08-01,1,week,2000,2000
Backend,Platform Org,2026-08-01,1,week,3000,3000
```
### Import Budget
Once your CSV file is prepared, follow the steps below to import any type of budget.
From the top navigation, click **Financial Planning**.
On the left navigation, select **Budgets**.
From the top right of the screen, click **Import**. The **Import Budget Data** modal is displayed.
Click **Choose File** and select a CSV file.
Click **Upload**. The **Review Imported Data** screen is displayed. If no errors are present, click **Confirm** > **OK**.
After you confirm, Vantage returns you to the main **Budgets** screen. Your imported budgets appear in the list, which is sorted alphabetically—use the **search** bar at the top to quickly find a budget by name.
When you open an imported budget, its **Manage** tab may not show every period right away because the **Date range** filter defaults to the last 12 months. If periods look missing, open the **Date range** filter and widen the range.
### Fix Import Errors
If a formatting error is found in your imported CSV file, the import wizard indicates where the error occurred. To fix the error, correct the issue in your source CSV and re-upload the file. In the below example, an error occurred because the CSV file contained duplicate values in the header row.
```bash theme={null}
Budget Name,2026-08,2026-10,2026-10
Team 1,50000.00,51000.00,52000.00,
```
When an import can't be completed, the review screen flags the affected budgets and shows the reason. Budget-specific errors are listed with the budget name first, in the format `Budget name: error` (for example, `New Cloud Environment: Child budgets must share the same current period.`). Use the table below to match an error to a fix. Also make sure the file has no extra blank columns and that amounts are plain decimals (e.g., `56000.00`, not `$56,000.00`).
| Error | Cause | Fix |
| - | - | - |
| `The file is unparseable.` | The upload isn't valid CSV. | Re-export as CSV and remove any stray characters or malformed rows. |
| `'202303' has an invalid date format.` | A period column header isn't `YYYY-MM` or `YYYY-MM-DD`. | Use `YYYY-MM` for monthly periods or `YYYY-MM-DD` for any cadence. |
| `'2026-10' appears more than once in the header row.` | A period column header is repeated. | Use each period date only once in the header row. |
| `'Team 1' appears more than once in the file.` | A budget name is duplicated in the file. | Make each budget name unique. |
| `A budget with this name already exists.` | The name matches a budget already in Vantage. | Rename the budget, or select **Overwrite budget periods** to replace the existing one (see the video below). |
| `Child budgets must share the same current period.` | A hierarchy mixes children with different periods. | Give every child under a parent the same cadence and aligned period dates. |
| `Cannot add Usage budgets to a Cost budget hierarchy. Select Cost budgets only.` | A hierarchy mixes Cost and Usage budgets. | Use a single metric per hierarchy, all Cost or all Usage. |
| `Cannot add Cost budgets to a Usage budget hierarchy. Select Usage budgets only.` | A hierarchy mixes Cost and Usage budgets. | Use a single metric per hierarchy, all Cost or all Usage. |
| `Cannot mix usage units in a hierarchy. Select budgets that share the same usage unit.` | Usage child budgets use different units. | Give every child in the hierarchy the same usage unit. |
| `This budget's report does not support usage amounts and cannot be added to a Usage hierarchy.` | A child's Cost Report has no usage data to measure. | Attach the child to a Cost Report that includes usage data, or keep the hierarchy on Cost. |
| `Budget hierarchy is too deep.` | The hierarchy exceeds 10 levels. | Flatten the hierarchy to 10 levels or fewer. |
| `Child budgets already assigned to another hierarchy.` | A child budget is already a child under a different parent. | Use a different budget, or remove it from the other hierarchy first. |
| `Cycle detected in budget hierarchy.` | A budget is set as its own ancestor. | Fix the `Parent Budget` references so the hierarchy doesn't loop. |
| `Period interval unit is not included in the list.` | `Interval Unit` isn't `day`, `week`, `month`, or `year`. | Use one of `day`, `week`, `month`, or `year`. |
| `Period interval count must be greater than 0.` | `Interval Count` is 0, negative, or not a whole number. | Use a whole number greater than 0. |
| `Interval exceeds your account's N-month cost data retention window.` | The cadence is longer than your account's data retention. | Choose a shorter period, or contact Vantage about your retention window. |
| `Start date must match the first budget period start date.` | `Start Date` doesn't match the earliest period column. | Set `Start Date` to the first period column's date. |
| `Budget cadence cannot be changed after creation.` | An overwrite tried to change an existing budget's start date or period length. | Keep the original cadence, or delete and recreate the budget. |
## View Budget Performance
For any budget, select the **Performance** tab to see how the budget is tracking against its budgeted amounts. The Performance tab has three parts: summary cards, a time-series chart, and a per-period table. The details vary slightly depending on whether you are viewing a Standard Budget or a Hierarchical (parent) budget.
For a Usage budget, the Performance tab is denominated in the budget's usage unit instead of dollars. The summary cards, chart, and per-period table all show budgeted amounts, actuals, and variance in that unit (for example, *Tokens*).
### Performance Summary Cards
At the top of the tab, summary cards provide an at-a-glance view of the current period:
| Card | What it shows |
| - | - |
| **Current Period Utilization** (labeled **Rollup Utilization** for Hierarchical Budgets) | The current period's date range, the amount spent versus the budgeted amount (e.g., *\$18,000 spent of \$40,000*), a progress bar, and a footer summarizing how much of the budget has been used and how much of the period has elapsed (e.g., *45% of budget used · 39% of period elapsed*). |
| **Current Performance** | The dollar amount you are currently over or under budget, labeled **Over as of today** or **Remains as of today**. |
| **Projected Performance** | The dollar amount you are projected to be over or under budget by the end of the period, labeled **Over at period end** or **Will remain at period end**. The projection extrapolates your current spend pace across the full period (it is not the Cost Report's forecast). |
| **Child budgets at risk or over** (Hierarchical Budgets only) | The number of child budgets that are over budget or at risk, with a breakdown below the count (e.g., *2 over · 1 at risk*). |
### Utilization States
A status badge on the utilization card (and in the optional **Status** column on the Budgets screen) reflects one of the following states:
| State | Meaning |
| - | - |
| 🟢 **On Track** | Spending is within budget so far and is projected to stay within budget through the end of the period. |
| 🟡 **At risk** | Spending is not over budget yet, but at the current pace it is projected to exceed the budget before the period ends. |
| 🔴 **Over** | Spend has already exceeded the full budgeted amount for the period. |
| ⚪ **Not Started** | No spend has been recorded for the current period yet. |
### Performance Chart
Below the cards, a time-series chart plots cumulative **Budget** against **Actuals** over time. For a Usage budget, the actuals series is labeled with the unit (for example, **Actuals (Tokens)**). You can:
* Adjust the **date range** with the date range picker.
* Change the chart **granularity** (day, week, month, or year).
* Toggle whether variance is displayed as a dollar amount or a percentage.
### Performance Table
The table below the chart differs depending on the budget type.
Each row is a budget period, with the following columns:
* **Period**: The date range of the period. The in-progress period is tagged with a **Current Period** badge, and future periods are tagged **Forecast**.
* **Budget**: The budgeted amount for the period. For a Usage budget, this column includes the unit (for example, **Budget (Tokens)**).
* **Actuals**: Actual cost or usage for the period. For a Usage budget, this column includes the unit (for example, **Actuals (Tokens)**). For the current period, this reflects actuals to date; the value is highlighted red if it exceeds the budget.
* **Variance (\$)** or **Variance (%)**: How far actuals are over or under the budgeted amount, depending on the variance display you selected. For a Usage budget, currency variance is labeled with the unit (for example, **Variance (Tokens)**).
The table is a matrix of budgets by period. Each **row** is a budget in the hierarchy, shown in an expandable tree under the **Budget Name** column. Expand a parent to reveal its child budgets, and click any name to open that budget. Each **column** is grouped by period (the in-progress period is tagged **Current Period** and future periods **Forecast**), and within each period group you'll see **Budget**, **Actuals**, and **Variance (\$)** or **Variance (%)** for every budget in the hierarchy. For a Usage hierarchy, those headers include the shared usage unit.
If a child has no periods yet, the parent rollup cell shows *"Add periods to child budget"* instead of *"Outside current period."* That message is a reminder to add periods on the Standard child budgets; mismatched child period dates still show *"Outside current period."*
For the in-progress period, projected spend and variance extrapolate your current spend pace across the full period, since the period is not yet complete. Budgeted amounts are spread evenly across the days in each period, so a partially elapsed period is compared against the prorated portion of its budget.
If there's nothing to show yet, the Performance tab displays a prompt with a shortcut to the **Manage** tab.
## View Budgets on Cost Reports
Once a budget is assigned to a [Cost Report](/cost_reports/), a budget report with current-period performance is displayed at the top of the Cost Report. The budget reflects amortized costs throughout the period, indicating whether spending is above or below the budget so far. The report's accrued and forecasted budget labels—shown in the top-line metric, chart tooltip, and chart legend—include the budget's name (for example, **Accrued \[Developer Costs] Budget** and **Forecasted \[Developer Costs] Budget**).
Budgets are displayed as a yellow line on the graph in the cumulative, daily, weekly, and monthly views on a Cost Report. The dotted portion of the line corresponds to the future budget, which you can track against your forecasted costs.
Because budget amounts are spread evenly across the days in each period, aggregated views (such as **Weekly** or **Monthly**) may show the budget line dip for partial periods at the start or end of the budget period.
A Usage budget appears on its Cost Report the same way, with accrued and forecasted usage budget lines (for example, **Accrued \[AI Token Budget] Budget**). The usage budget line is shown only when the Cost Report is displaying that same usage unit; if the report isn't displaying matching usage, the budget line won't appear.
### Cost and Usage Budgets on the Same Report
When a Cost Report has both a Cost budget and a Usage budget, the report shows four summary figures at the top: **Accrued Actuals (Costs)**, the Cost budget (for example, **Accrued \[Developer Costs] Budget**), **Accrued Actuals** for the usage unit (for example, **Accrued Actuals (Tokens)**), and the Usage budget (for example, **Accrued \[AI Token Budget] Budget**). This lets finance watch spend while platform teams watch consumption on a single report. The same four figures appear on the report's [dashboard](/dashboards) widget.
The budget line on the chart follows the metric you're viewing: the **Cost budget** is drawn in the dollar (Cost) view, and the **Usage budget** is drawn when the report is in usage view and the table includes that budget's unit, even if other units appear alongside it. Switch the report between Cost and its usage unit to see each budget's line. Count charts show no budget line.
## Budget Alerts
Budget alerts are automated alerts based on configurable budget thresholds. Create a budget alert for any of your existing budgets to notify you when a percentage of a budget is exceeded. You can configure alerts to notify Vantage users via email, Slack, Microsoft Teams, or Jira. You can optionally scope an alert to a window at the beginning or end of the budget period (e.g., within the first 10 days of the period).
You can create budget alerts for any budget: Standard or Hierarchical, Cost or Usage. Because thresholds are percentage-based, they apply the same way whether the budget tracks cost or a usage quantity. For Hierarchical Budgets, the amounts associated with the child budgets are aggregated at the parent budget level to determine if a budget alert should be set off.
You can manage budget alerts in two places:
* From a budget's detail page, using the **Budget Alerts** drawer (the steps below).
* From the standalone **Budget Alerts** screen, which lists every budget alert in the workspace. To open it, click **Financial Planning** in the top navigation, then select **Budget Alerts** in the left navigation.
If you want to send alerts to Slack, Microsoft Teams, or Jira, see the [Slack](/slack), [Microsoft Teams](/microsoft_teams), or [Jira](/jira) integration documentation. Once you've set up an integration, follow the steps below to set up a budget alert.
Open the budget you want to alert on. From the top of the budget's detail page, click **Budget Alerts** to open the **Budget Alerts** drawer, which lists any existing alerts for the budget.
Click **Add budget alert**. The **New Budget Alert** panel is displayed.
Configure the following parameters:
* For **Budget**, select one or more budgets the alert applies to.
* For **Alert when spend exceeds**, enter a percentage threshold (e.g., 85% of the budget). You'll receive an alert only if the threshold is reached.
* Optionally, for **Within first**, enter a number of days (between 1 and 31) and choose **beginning of the period** or **end of the period** to scope the alert to a window within the budget period.
* For **Email recipients**, select the recipients who are members of your team in Vantage that you want to receive the alert.
* Under **App alerts**, optionally select any Slack channels, Microsoft Teams channels, or Jira projects you want to receive the alert.
Click **Save Budget Alert**. Budget alerts will look similar to the below image.
Recipients will be notified immediately after a Cost Report is updated with the latest data. Reports are updated with the latest data at least once per day. If your budget exceeds the threshold for multiple alerts, you'll be notified only about the most severe alert (the alert with the highest threshold).
An [annotation](/annotations) is also added to the corresponding Cost Report on the date the alert was triggered.
You can create multiple budget alerts with the same threshold and window but different recipients. For example, you can create one alert that sends email notifications to a specific team member and another alert with the same threshold that sends notifications to a Slack channel. This allows you to route the same alert to different destinations based on your team's needs.
### Budget Alert Limitations
At this time, only dynamic, percentage-based thresholds are supported. Budget alerts can be configured only to send alerts based on actual, not forecasted costs.
A single cost increase will not typically trigger a budget alert. If you are interested in this feature, see the [Cost Anomaly Alerts](/cost_anomaly_alerts) documentation.
By default, a budget alert evaluates spend against the budgeted amount for the entire budget period. If you want to be alerted based on only part of the period, use the **Within first** option (e.g., within the first 10 days of the period) to scope the alerting window.
Keep the **Within first** window shorter than the budget's period. If the number of days is longer than the period length (for example, a 20-day window on a weekly budget), the alert is skipped and won't fire.
### Budget Alerts and Cost Reports
If you update a Cost Report that is associated with a budget alert, the following message is displayed: *This report has budget alerts and may trigger a notification. Are you sure you want to save the report?* You must confirm before saving the report.
# Build Hours
Source: https://docs.vantage.sh/build_hours
Understand Build Hours in Vantage, a usage metric for the compute used to process your cost data when you customize it with Virtual Tags and MSP SQL billing rules.
Build Hours measure the compute Vantage uses to process your cost and usage data when you customize how that data is organized with [Virtual Tags](/tagging#virtual-tags). For [MSP partners](/partners), Build Hours also cover the [SQL billing rules](/sql_billing_rules) applied to Managed Accounts, the customer accounts an MSP provisions and administers. They give you visibility into the processing footprint of that configuration.
Build Hours are a *usage metric*, not a direct dollar charge in the product. Your subscription covers platform access. Build Hours help you and your account team understand how much processing your Virtual Tags and billing rules require.
The Build Hours tab is enabled on request. Contact [support@vantage.sh](mailto:support@vantage.sh) or your Customer Success Manager to turn it on for your account.
## Overview
Vantage reports two kinds of Build Hours. They measure different processing steps and are shown as separate series.
* **Virtual Tag hours:** The time spent applying [Virtual Tags](/tagging#virtual-tags). Virtual Tags let you assign custom tag values to your cloud costs based on filters, business logic, and time frames.
* **Billing Rule hours:** The time spent applying line-item billing rules on a Managed Account. Line-item rules are Adjustment and Exclusion rules, and custom SQL `UPDATE` and `DELETE` rules. Billing Rule hours apply only to MSP partners. The Management Account, the MSP's own central administrative account, does not receive them.
You can view your usage in the product at **Settings > Tags > Build Hours**. Build Hours are shown for the account you are currently viewing, so to see a Managed Account's Billing Rule hours, open that Managed Account's settings.
## When Build Hours Are Recorded
Vantage records Build Hours when a processing run completes successfully. Runs that don't complete successfully aren't counted.
### Virtual Tag Hours
Virtual Tag hours are recorded whenever Vantage processes cost data and runs the tagging step, including:
* Scheduled imports, as new billing data arrives from your connected providers.
* Virtual Tag configuration changes, when you create, update, or delete a Virtual Tag or change its values, filters, or time frames.
* Downstream reprocessing, when another configuration change causes the tagging step to run again as part of a full reprocess.
Each successful processing run that includes tagging produces one measurement. Runs with no tagging work aren't counted.
### Billing Rule Hours
Billing Rule hours are recorded on a Managed Account when the transform step runs and that account has line-item billing rules applied. This includes:
* Scheduled imports, as new billing data arrives for a Managed Account that already has line-item rules.
* Rule changes, when you create or edit an Adjustment rule, an Exclusion rule, or a custom SQL `UPDATE` or `DELETE` rule.
* Assignment changes, when you assign or unassign those rules on a Managed Account.
Charge rules, Credit rules, and SQL `INSERT` rules, including [Monthly Insert](/sql_billing_rules#monthly-insert-aggregate-rules) rules, do not generate Billing Rule hours on their own.
## How Build Hours Are Calculated
Vantage measures processing time in milliseconds. 3,600,000 is the number of milliseconds in an hour (1,000 ms × 60 seconds × 60 minutes).
### Virtual Tag Hours
One Virtual Tag hour equals one hour of processing time spent in the tagging step. Vantage adds up the time each tagging task in a run takes, then converts that total to hours:
$$
\text{Virtual Tag hours} = \frac{\text{tagging processing time (ms)}}{3{,}600{,}000}
$$
Vantage tags many batches of your cost data at the same time, so the processing time recorded for a run can be greater than the time that elapsed on the clock while it ran.
### Billing Rule Hours
Billing Rule hours use the same millisecond total for the transform step, then apply a cost weight of 0.35. Transform processing runs on lighter infrastructure than tagging, so one hour of transform time counts as 0.35 Build Hours:
$$
\text{Billing Rule hours} = \frac{\text{transform processing time (ms)} \times 0.35}{3{,}600{,}000}
$$
Two hours of transform time show as 0.7 Billing Rule hours. Transform work also runs many batches at once, so the recorded time can be greater than the time that elapsed on the clock.
The two series stay separate. Virtual Tag hours and Billing Rule hours measure different processing steps.
Build Hours are measured *per account*. Parent and Managed Accounts are tracked separately.
## What Drives Your Usage
Both kinds of Build Hours increase when you have more cost and usage data to process, such as more accounts, providers, or billing periods.
### Virtual Tag Hours
Your Virtual Tag hours generally increase when you:
* Maintain more Virtual Tag configurations or values.
* Change Virtual Tags frequently, since each change that has a backfill period triggers reprocessing.
* Use complex filters or time-bound tag values that require more matching work.
See [Scaling Virtual Tags](/guides/scaling_tagging) for tips on scoping tags efficiently, which also helps keep your Build Hours down.
### Billing Rule Hours
Your Billing Rule hours generally increase when you:
* Assign more line-item billing rules to Managed Accounts.
* Change those rules often, since each save can restart reprocessing.
* Leave a billing rule's start date empty, or set it far back, so Vantage reprocesses more history.
## View Your Build Hours
From the top navigation, click **Settings**.
Under **General Settings** in the left navigation, click **Tags**.
Open the **Build Hours** tab to view your usage.

The tab has two parts:
* **Daily Build Hours over the last 90 days:** A chart of how many Build Hours each day's processing used. Hover over any point to see that day's exact total. In the example above, June 22 used 4.38 Build Hours.
* **Usage Summary:** A table of rolling totals for the last 7, 15, 30, 60, and 90 days. The **Hours** column is Virtual Tag hours, and **Daily Avg** is that total divided by the number of days in the window. In the example above, this account used 25.0 Build Hours over the last 7 days (a 3.57 daily average) and 181.4 over the full 90 days.
The example above shows an account with Virtual Tag hours only. When an account also has Billing Rule hours, the chart shows two series, **Virtual Tags** and **Billing Rules**, with a legend, and hovering over a day shows both values. The Usage Summary adds a **Billing Rule Hours** column and renames **Hours** to **Virtual Tag Hours**. **Daily Avg** remains the Virtual Tag total for that window divided by the number of days.
Comparing a shorter window's daily average to the 90-day average is a quick way to see which direction your Virtual Tag usage is trending. A higher recent average means those hours are climbing, often because you've been changing Virtual Tags, changing line-item billing rules, or backfilling more history than usual.
## Frequently Asked Questions
Changing a Virtual Tag triggers reprocessing so your reports reflect the new configuration. Vantage reprocesses cost data back to the tag's [Billing Period Backfill](/tagging#create-virtual-tags), so the amount of work depends on how many billing periods that covers and how complex your tag rules are.
Creating, editing, assigning, or unassigning a line-item billing rule reprocesses the Managed Account's cost data back to the rule's start date. If the start date is empty, Vantage reprocesses the account's full history. That work adds Billing Rule hours for the transform step. The same reprocess also runs tagging again, which can add Virtual Tag hours for the same change.
Billing Rule hours are recorded for line-item rules on Managed Accounts: Adjustment rules, Exclusion rules, and custom SQL `UPDATE` and `DELETE` rules. Charge rules, Credit rules, and SQL `INSERT` rules, including Monthly Insert rules, do not generate Billing Rule hours on their own. The Management Account does not receive this series.
You can manage Virtual Tag hours by:
* Finalizing your Virtual Tag configuration before saving, since each save can restart reprocessing.
* Setting the [Billing Period Backfill](/tagging#create-virtual-tags) to the earliest month you actually need, instead of backfilling further into your history than your reporting requires.
* Avoiding unnecessary Virtual Tag changes on accounts with large cost datasets.
* Scoping tag filters as narrowly as your use case allows.
You can manage Billing Rule hours by:
* Finalizing billing-rule SQL before you save it, since each save can restart reprocessing.
* Setting a billing rule start date to the earliest month you need, instead of leaving it empty.
* Avoiding broad `UPDATE` and `DELETE` rules on Managed Accounts with large cost datasets.
No. Build Hours are a usage metric for the data processing tied to your configuration. Your subscription covers platform access. Build Hours help you and your account team understand the processing footprint of your Virtual Tags and billing rules.
# Business Metrics
Source: https://docs.vantage.sh/business_metrics
Import business metrics and apply unit cost, usage unit cost, gross margin, and raw value calculations alongside your cloud costs in Vantage.
A *business metric* is any metric that your business tracks, such as users, requests, transactions, customers, revenue, or tokens. By importing these business metrics into Vantage, you can combine them with your cloud costs to answer questions that dollars alone can't—like cost per customer, gross margin, tokens consumed per pull request, or how spend tracks against customer growth.
Business metrics are applied as a visualization on [Cost Reports](/cost_reports). When you assign a metric to a Cost Report, you choose a *calculation type* that determines how Vantage combines the metric with your costs. All calculation types render on a secondary y-axis as a line overlay. See [Calculation Types](/business_metrics#calculation-types) for the full list.
In the visual example below, a business metric is visualized in the graph as a line alongside daily costs. You can use this visualization to understand how changes in the metric relate to changes in your costs.
## Labeled Business Metrics
You can optionally attach one or more named label columns to each uploaded metric value. Label columns identify the business dimensions of the metric—such as application, team, environment, or cost center—so a single metric can model the same usage across several dimensions without duplicate metrics or delimiter workarounds.
For example, a metric like *Weekly Active Users* might include columns for `application`, `team`, and `environment`. When you assign that metric to a [Cost Report](/business_metrics#assign-business-metrics-to-cost-reports) or use it in a [Virtual Tag](/tagging#business-metrics-based-allocation-tags), you choose which label column to use for the calculation or allocation. The same underlying metric can power a cost-per-application view, a cost-per-team view, and a cost-per-environment view by selecting a different column in each place.
When you filter by label values on a Cost Report, any selected values for a column are aggregated in the calculation. For example, if you select the `application` column and include only `app1`, the calculation uses only that set of data. If you also include `app2`, the calculation aggregates both.
Multiple label columns are supported when you import via [CSV](/business_metrics#import-from-a-csv-file), [ClickHouse](/business_metrics#import-via-clickhouse), [Datadog](/business_metrics#import-from-datadog), [GCP BigQuery](/business_metrics#import-via-gcp-bigquery), [Metronome](/business_metrics#import-from-metronome), or [Snowflake](/business_metrics#import-from-snowflake). [Amazon CloudWatch](/business_metrics#import-from-amazon-cloudwatch) metrics carry a single label column.
A single business metric supports up to 100 label columns, and each column can have an unlimited number of values.
Business metrics created before multiple label columns were supported continue to work with their single `label` column. To use multiple label columns, delete the existing metric and create a new one, then reassign it to its Cost Reports and Virtual Tags.
## Import Business Metrics
To get started with business metrics, you can also view a video demo on [Vantage University](/vantage_university_unit_costs) .
Business metrics can be imported from other systems directly into Vantage and analyzed alongside cost data. You can automatically import metrics from Amazon CloudWatch, ClickHouse, Datadog, GCP BigQuery, Metronome, and Snowflake; import them manually from a CSV file; or upload them via the Vantage API.
The following steps are for creating a Business Metric and importing historical metrics. If you want to automatically import metrics from another application, see [Import via the Vantage API](/business_metrics#import-via-the-vantage-api).
Imports load one billing period (month) at a time. On the **Imported Metrics** tab, each month in the period picker shows its own import state—a month still being imported is labeled **Importing…** and its data appears automatically once ready, while a month that could not be imported is labeled **Failed**. You can review completed months while others are still processing.
From the top navigation, click **Financial Planning**.
On the left navigation, click **Business Metrics**. All existing business metrics are displayed. You can edit or delete business metrics from this screen.
From the top right of the screen, click **New Business Metric**.
Enter a business metric **Title** and click **Create Business Metric**.
The **Business Metrics** screen is displayed with three tabs:
* **Metric Overview**: Displays basic metric information (name, import type, integration details) and allows you to assign the metric to Cost Reports. See the [Assign Business Metrics to Cost Reports](/business_metrics#assign-business-metrics-to-cost-reports) section for details.
* **Imported Metrics**: Import historical business metrics from a [CSV file](/business_metrics#import-from-a-csv-file), [Amazon CloudWatch](/business_metrics#import-from-amazon-cloudwatch), [ClickHouse](/business_metrics#import-via-clickhouse), [Datadog](/business_metrics#import-from-datadog), [GCP BigQuery](/business_metrics#import-via-gcp-bigquery), [Metronome](/business_metrics#import-from-metronome), [Snowflake](/business_metrics#import-from-snowflake), or [upload via the Vantage API](/business_metrics#import-via-the-vantage-api). This tab stores your historical metric data and is used for calculations on Cost Reports. While you can upload any dates (past, present, or future) to this tab, only dates up to the current cost buffer date are used for calculations. Future dates uploaded here are stored and will automatically appear on Cost Reports once that date becomes current (passes the cost buffer). Only data uploaded to the **Forecasted Metrics** tab will be used for Dynamic Forecasting.
* **Forecasted Metrics**: Upload future projections of your business metrics to create [Dynamic Forecasts](/forecasting#dynamic-forecast). Only data uploaded to this tab will be used for Dynamic Forecasting. See the [Forecasted Metrics](/business_metrics#forecasted-metrics) section for details.
### Import from a CSV File
You can upload a CSV file that uses the following format. This CSV file can replace existing data or be used to import new data.
The `date` and `amount` columns are required. The `date` column must be in `YYYY-MM-DD` format, and the `amount` column must be a number. Every additional header becomes a named [label column](/business_metrics#labeled-business-metrics), and column order does not matter. Label columns are optional: you can provide a single column (for example, `label`), several named columns, or none at all. CSV uploads must be under 25 MB.
Each row must be a unique combination of `date` plus its label values. Duplicate rows are rejected. For example, in the CSV below, `2024-01-09,295,app1,payments,production` and `2024-01-09,344,app2,checkout,staging` are both valid because their label values differ, but a second `2024-01-09,...,app1,payments,production` row would be a duplicate.
```bash theme={null}
date,amount,application,team,environment
2024-01-09,295,app1,payments,production
2024-01-16,909,app1,payments,production
2024-01-23,934,app1,payments,production
2024-01-30,772,app1,payments,production
2024-01-09,344,app2,checkout,staging
2024-01-16,789,app2,checkout,staging
2024-01-23,922,app2,checkout,staging
2024-01-30,768,app2,checkout,staging
...
```
Click the **Imported Metrics** tab, then click **Upload a CSV**. Select the CSV file and upload. After the file is imported, a dropdown menu for each month is displayed. For months with imported metrics, the date and associated metric number are displayed. Months with no metrics are blank.
To add additional metrics or change the value of a metric, update your source CSV file. Then, click **Edit** and upload the edited file. The new or updated metric is displayed in the table.
When you re-upload a business metric:
* Dates present in the new file fully replace the stored values for those dates.
* Dates omitted from the new file carry forward their previous values.
When you re-upload a metric that supports multiple label columns, new CSV headers add label columns. If the CSV omits a previously used label column, that column is absent from rows replaced by the upload.
See the [Assign Business Metrics to Cost Reports](/business_metrics#assign-business-metrics-to-cost-reports) section for the next steps.
### Import from Amazon CloudWatch
To import business metrics from Amazon CloudWatch, you need a specific metric name and AWS account, as described below. Ensure AWS is one of your [connected providers](/connecting_aws).
If Vantage does not have a Cross-Account IAM Role associated with your AWS account, you need to create one. See the [AWS integration](/connecting_aws) documentation for details.
Click the **Imported Metrics** tab, then click **Import via CloudWatch**.
For **AWS Account**, select the connected AWS account you want to import metrics from.
Select an AWS **Region**.
Enter a **Namespace**. A complete list of available namespaces can be found in the AWS documentation for [AWS services that publish CloudWatch Metrics](https://docs.aws.amazon.com/AmazonCloudWatch/latest/monitoring/aws-services-cloudwatch-metrics.html). Namespaces start with `AWS/` followed by the service name (e.g., `AWS/EC2`).
Enter a **Metric name**. Each AWS service has metrics that it [sends to CloudWatch](https://docs.aws.amazon.com/AmazonCloudWatch/latest/monitoring/viewing_metrics_with_cloudwatch.html). Available metrics can be found in CloudWatch or the AWS documentation.
The AWS documentation includes a list of available metrics for services. For example, you can view [EC2 instance metrics](https://docs.aws.amazon.com/AWSEC2/latest/UserGuide/viewing_metrics_with_cloudwatch.html). An example metric to track in this instance is `CPUUtilization`. For [Amazon RDS](https://docs.aws.amazon.com/AmazonRDS/latest/UserGuide/rds-metrics.html), an example metric to track is `WriteIOPS` or `ReadIOPS`.
For **Dimensions**, enter a **Name** and **Value**. [Dimensions](https://docs.aws.amazon.com/AmazonCloudWatch/latest/monitoring/cloudwatch_concepts.html#Dimension) are used to pull specific statistical data for a metric. For example, enter `InstanceId` with a value of `i-1234567890abcdef0`. Each CloudWatch metric has a set of dimensions you can select. Click **+ Add a Dimension** to add more than one dimension.
For each import, you must specify the **Aggregation** function to be used because metrics will be aggregated to the day. Select either **Sum**, **Average**, **Maximum**, or **Minimum**.
Optionally, enter a [dimension **name**](https://docs.aws.amazon.com/AmazonCloudWatch/latest/monitoring/cloudwatch_concepts.html#Dimension) for the **Label Dimension** field.
Click **Import Data**.
The metrics will be automatically synced, daily, along with cost data from other integrations. See the [Assign Business Metrics to Cost Reports](/business_metrics#assign-business-metrics-to-cost-reports) section for the next steps.
### Import via ClickHouse
To import business metrics from ClickHouse, ensure ClickHouse Cloud is one of your [connected providers](/connecting_clickhouse). Rather than entering SQL in Vantage, you save the query in ClickHouse Cloud and expose it as a [query API endpoint](https://clickhouse.com/docs/cloud/get-started/query-endpoints), then give Vantage the endpoint ID. The endpoint must be shared with the API key from your ClickHouse Cloud integration. The **Billing** and **Service reader** roles used for cost ingestion are sufficient; you do not need an additional role. Scheduled query execution consumes ClickHouse compute in your account.
The saved query behind the endpoint must meet two requirements:
* **Return `date` and `value` columns:** The `date` column must be convertible by ClickHouse's `toDate` function. Every other column the query returns becomes a named [label column](/business_metrics#labeled-business-metrics), named after your SQL alias, so you can return `team`, `application`, `environment`, or any dimension you want to track. Use column aliases (`AS`) if your source table uses different column names.
* **Declare `start_date` and `end_date` query parameters and filter on them:** Vantage imports one month at a time and passes that month's boundaries to the endpoint as these parameters. Both bounds are inclusive.
ClickHouse imports use `value` in the SQL result set. CSV and API imports use `amount` for the metric value.
Common ClickHouse-backed metrics include daily requests, events, jobs, transactions, customers, or other operational measures you already aggregate in ClickHouse. For example, if several teams share one application, you could import daily event counts by team and environment. Vantage would import rows like `2026-01-01, 1500000, team-a, production`, where `date` is the usage date, `value` is the number of events, and `team` and `environment` are label columns. You could then attach that metric to a Cost Report and use a **Unit Scale** like **Per Million** to view cost per million events. For allocation use cases, label columns can represent teams, applications, customers, or cost centers.
In the ClickHouse Cloud SQL console, write a query that returns `date`, `value`, and any label columns you want to track, filtered on the `start_date` and `end_date` parameters. Then click **Save**. For example, the following query imports daily event counts broken down by team and environment:
```sql theme={null}
SELECT
toDate(created_at) AS date,
count(*) AS value,
team,
environment
FROM events
WHERE toDate(created_at) BETWEEN {start_date:Date} AND {end_date:Date}
GROUP BY date, team, environment
```
Filter on `start_date` and `end_date` rather than a hard-coded date range. If the query ignores these parameters, it returns your full history on every import, which is likely to exceed the 100,000-row limit for a single monthly import. Keep the query fast, too: ClickHouse stops a query that runs longer than 25 seconds, which fails the import.
With the saved query open, click **Share**, then select the **API Endpoint** tab.
* Under **API Keys**, select the API key you used to connect ClickHouse Cloud to Vantage.
* Under **Access control**, select the database roles used to run the query. **Read only** is sufficient, since Vantage only reads data.
* Leave **Allowed domains** empty. This setting controls browser (CORS) access, and Vantage calls the endpoint from its own servers.
Click **Save**. ClickHouse generates the endpoint and displays an example request.
For screenshots of each of these ClickHouse console screens, see ClickHouse's [query API endpoints documentation](https://clickhouse.com/docs/cloud/get-started/query-endpoints).
After you save, ClickHouse displays the endpoint URL and an example request. The endpoint ID is the UUID in that URL, such as `7c6a3a87-12fd-41f5-afdf-caa4697a2886`. Copy only the UUID, not the full URL.
In Vantage, click the **Imported Metrics** tab, then click **Import via ClickHouse**. If you have not connected ClickHouse Cloud, click **Connect ClickHouse** and complete the [ClickHouse Cloud integration](/connecting_clickhouse) setup first.
For **ClickHouse Connection**, select the connected ClickHouse organization that owns the endpoint. Then paste the UUID into **Query Endpoint ID** and click **Import Data**.
After it's saved, Vantage creates monthly imports for your account's retained history plus the current month, and refreshes the data daily along with your other integrations. See the [Assign Business Metrics to Cost Reports](/business_metrics#assign-business-metrics-to-cost-reports) section for the next steps.
You can keep editing the saved query in ClickHouse Cloud afterward. Each import runs the latest saved version, so you don't need to reconfigure the metric in Vantage unless the endpoint ID itself changes.
If you disconnect the ClickHouse Cloud integration, daily imports stop for any business metric that uses it. Previously imported values remain on the **Imported Metrics** tab. To resume importing, reconnect the integration or edit the business metric to point at a different connection or query endpoint.
Vantage only verifies that it can reach the endpoint when you save the import. Problems with the query's results, such as missing columns or an oversized result, are reported on the **Imported Metrics** tab instead of blocking setup. A brand-new query that has no data yet is also allowed.
If an import fails, the **Imported Metrics** tab shows one of the following messages.
| Message | How to Fix It |
| - | - |
| `ClickHouse query endpoint access was denied` | The endpoint is no longer shared with the API key for the selected connection, or the key's credentials are no longer valid. Confirm the key is still listed under **API Keys** on the endpoint. |
| `ClickHouse could not run the business metric query endpoint` | The query failed to run. Common causes are a query that exceeds the 25-second execution limit, a referenced table that no longer exists, or a database role on the endpoint that can't read a referenced table. |
| `ClickHouse query endpoints must select date and value columns` | The query is missing a `date` column, a `value` column, or both. Alias the columns in ClickHouse Cloud and re-save the query. |
| `ClickHouse query endpoints cannot return more than 100000 rows` | A single monthly import returned too many rows. This limit applies to everything the endpoint returns, before Vantage narrows the rows to the import's month, so filter the query on `start_date` and `end_date` and aggregate to a daily grain. |
| `ClickHouse query endpoint returned an unusable date` | A value in the `date` column couldn't be read as a date. Confirm the column is a `Date` or `DateTime`, or wrap it in `toDate`. |
### Import from Datadog
To import business metrics from Datadog, ensure Datadog is one of your [connected providers](/connecting_datadog). If you do not have Datadog as one of your connected providers, you will be prompted to connect your Datadog account the first time you try to create a metric.
Click the **Imported Metrics** tab, then click **Import via Datadog**.
For **Account**, select the connected Datadog account for which you want to import metrics. If this is your first Datadog metric, you may be prompted to reauthorize your Datadog credentials and the required scopes for Vantage (i.e., `billing_read`, `usage_read`, `metrics_read`, and `timeseries_query` scopes).
For **Raw Query**, enter your Datadog metric, including aggregation, rollup formula, and label filters, into the text field. Your syntax should be similar to the following example:
```bash theme={null}
aws.applicationelb.request_count{availabilityzone:us-east-1c, region:us-east-1}
```
The minimum aggregation for business metrics is daily. If you enter a lower granularity than daily, Vantage will perform aggregation at the daily level. For more information on the Datadog filtering syntax, see the [Datadog documentation](https://docs.datadoghq.com/metrics/advanced-filtering/).
When your query groups by one or more tags (for example, `by {team,env}`), each tag key becomes a named [label column](/business_metrics#labeled-business-metrics) on the metric. Tag values without a key are grouped under the default `label` column.
Click **Import Data**.
The metrics will be automatically synced, daily, along with cost data from other integrations. See the [Assign Business Metrics to Cost Reports](/business_metrics#assign-business-metrics-to-cost-reports) section for the next steps.
### Import via GCP BigQuery
To import business metrics from GCP BigQuery, you run a SQL query against your own BigQuery data and Vantage imports the results as a business metric. This import reuses the service account from an existing [GCP](/connecting_gcp) integration, so you don't create or upload a second credential. Ensure you have a connected GCP detailed billing integration before you start.
Vantage uses the selected GCP integration's service account to run your query, so it needs permission both to run the BigQuery job and to read every dataset the query references:
* **BigQuery Job User** on the project that runs the query (the **BigQuery Job Project**), which allows `bigquery.jobs.create`.
* **BigQuery Data Viewer** on each dataset referenced by the query.
The **BigQuery Data Viewer** role is the same one you grant when [connecting GCP](/connecting_gcp#step-1-grant-the-vantage-service-account-permission-to-access-the-bigquery-dataset). Because Business Metric queries run in your own project, unlike the billing extract that Vantage runs in its own project, you must additionally grant **BigQuery Job User** on the query project. If your query reads data in additional datasets, grant **BigQuery Data Viewer** on each of those datasets; **BigQuery Job User** is only required on the job project where the query runs. See the [GCP integration](/connecting_gcp) documentation for the full permission steps.
Query execution and validation consume BigQuery capacity in the selected **BigQuery Job Project**, and you are responsible for those BigQuery charges.
Your SQL query must return columns named `date` and `value`. Every other column your query returns becomes a named [label column](/business_metrics#labeled-business-metrics), named after your SQL alias, so you can return `team`, `application`, `environment`, or any dimension you want to track. Use column aliases (`AS`) if your source table uses different column names. When you save the import, Vantage validates the query against BigQuery and requires it to return at least one row.
Click the **Imported Metrics** tab, then click **Import via GCP BigQuery**.
For **GCP Billing Integration**, select the connected GCP integration whose service account has access to the data you want to query.
Set the **BigQuery Job Project**. This is the project where the query runs and where BigQuery charges are attributed. Vantage defaults this to the selected integration's project, but you can enter another project where the service account has **BigQuery Job User**.
For **SQL Query**, enter a query that returns `date`, `value`, and any label columns you want to track. Use fully qualified `project.dataset.table` names, and aggregate to the intended daily and label grain. For example:
```sql theme={null}
SELECT
DATE(event_timestamp) AS date,
COUNT(*) AS value,
team_slug AS team,
environment
FROM `analytics-prod.usage.api_requests`
GROUP BY date, team, environment
```
Don't hard-code a short date window that would exclude future scheduled imports. Vantage automatically applies a per-import date filter to the query. To help control BigQuery cost, filter on the partition column if your tables are partitioned, and avoid unnecessary `SELECT *` scans.
Click **Import Data**.
GCP BigQuery uses `value` in the SQL result set. CSV and API imports use `amount` for the metric value.
After it's saved, Vantage creates monthly imports for your account's retained history plus the current month, and refreshes the data daily along with your other integrations. See the [Assign Business Metrics to Cost Reports](/business_metrics#assign-business-metrics-to-cost-reports) section for the next steps.
If you disconnect the GCP integration, daily imports stop for any business metric that uses it. Previously imported values remain on the **Imported Metrics** tab. To resume importing, reconnect the integration or edit the business metric to point at a different integration or query.
If an import fails, the **Imported Metrics** tab shows one of the following messages.
| Message | How to Fix It |
| - | - |
| `GCP BigQuery access was denied` | The service account is missing **BigQuery Job User** on the job project or **BigQuery Data Viewer** on a referenced dataset. Grant the missing role and try again. |
| `GCP BigQuery could not complete the query` | The query is invalid or references a table or dataset that doesn't exist. Check the SQL, table names, and dataset location. |
### Import from Metronome
To import revenue or usage data from Metronome, ensure Metronome is one of your [connected apps](/metronome). Metronome imports create labeled business metrics that can be assigned to Cost Reports, used in [Canvas](/canvas), and queried with the [FinOps Agent](/vantage_finops_agent).
Metronome supports two metric types in Vantage:
* **Daily invoice revenue**: Daily revenue from Metronome invoice breakdowns, labeled by customer. Use this for gross margin, customer profitability, and cost as a percentage of revenue.
* **Usage**: Daily usage from a selected Metronome billable metric, labeled by customer. Use this for unit costs such as cost per compute hour, cost per API request, cost per storage GB-hour, or cost per AI token.
Click the **Imported Metrics** tab, then click **Import via Metronome**.
For **Account**, select the connected Metronome account for which you want to import revenue or usage metrics. If you have not connected Metronome yet, complete the [Metronome integration](/metronome) setup first.
Select the Metronome metric you want to import.
* Select **Daily invoice revenue** to import customer-level revenue.
* Select a billable usage metric, such as `Compute Hours`, `API Requests`, `Storage GB-Hours`, `AI Tokens`, or `Virtual Machine Hours`, to import product usage.
Select a **Label Source**. Labels identify the customer associated with each metric value and power Cost Report calculations and Virtual Tag allocation.
* Use **Customer name** for readable reporting by customer.
* Use **Ingest alias** if your Metronome aliases are cleaner or match the identifiers your team uses outside Metronome.
* Use **Customer ID** when you need stable identifiers or want to troubleshoot customer matching.
Metrics that support [multiple label columns](/business_metrics#labeled-business-metrics) import each customer identifier—`customer_id`, `customer_name`, and `ingest_alias`—plus any customer custom fields as separate label columns, so you can filter and allocate by any of them. The **Label Source** selection applies to existing single-label metrics.
Click **Import Data**.
The metrics will be automatically synced daily. After the import completes, review the imported dates, amounts, and labels. Then see the [Assign Business Metrics to Cost Reports](/business_metrics#assign-business-metrics-to-cost-reports) section to use the metric for unit costs, COGS analysis, margin reporting, or customer-level allocation.
For examples of Metronome-backed Canvas prompts, FinOps Agent prompts, and troubleshooting, see the [Metronome integration](/metronome) documentation.
### Import from Snowflake
To import business metrics from Snowflake, ensure Snowflake is one of your [connected providers](/connecting_snowflake). Vantage uses the selected Snowflake integration to run your query, so the configured Snowflake role needs read access to the tables or views referenced in the query. Scheduled query execution consumes Snowflake credits in your account.
Your SQL query must return columns named `date` and `value`. Every other column your query returns becomes a named [label column](/business_metrics#labeled-business-metrics), named after your SQL alias, so you can return `team`, `application`, `environment`, or any dimension you want to track. Use column aliases (`AS`) if your source table uses different column names. When you save the import, Vantage validates the query against Snowflake and requires the query to return at least one row.
Snowflake imports use `value` in the SQL result set. CSV and API imports use `amount` for the metric value.
Common Snowflake-backed metrics include daily requests, users, sessions, seats, transactions, orders, or product-specific usage events, such as AI invocations. For example, if several teams share one CloudFront distribution, you could import daily request counts by team from Snowflake. Vantage would import rows like `2026-01-01, 1500000, team-a`, where `date` is the usage date, `value` is the number of requests, and `team` is a label column. You could then attach that metric to a Cost Report filtered to the shared CloudFront distribution and use a **Unit Scale** like **Per Million** to view cost per million requests. For allocation use cases, label columns can represent teams, applications, customers, or cost centers.
Click the **Imported Metrics** tab, then click **Import via Snowflake**.
For **Snowflake Integration**, select the connected Snowflake integration you want to query. If you have not connected Snowflake, click **Connect Snowflake** and complete the [Snowflake integration](/connecting_snowflake) setup first. Confirm the `vantage` user you created during connection has read access to any of the databases and schemas that you want to use for business metrics.
For **SQL Query**, enter a query that returns `date`, `value`, and any label columns you want to track. In the shared CloudFront distribution example discussed earlier, the following query imports daily request counts broken down by team and environment:
```sql theme={null}
SELECT
CAST(request_date AS DATE) AS date,
COUNT(*) AS value,
team,
environment
FROM analytics.cloudfront_requests
WHERE distribution_id = 'E123EXAMPLE'
GROUP BY date, team, environment
```
If this data is already modeled in Snowflake, such as in a dbt model or analytics view, query that model directly and alias the output columns to `date`, `value`, and your label columns. If the query references objects outside the database or schema configured for the Snowflake integration, use fully qualified names like `database.schema.table` and confirm the Vantage Snowflake role has `SELECT` access.
Click **Import Data**.
The metrics will be automatically synced, daily, along with cost data from other integrations. See the [Assign Business Metrics to Cost Reports](/business_metrics#assign-business-metrics-to-cost-reports) section for the next steps.
### Import via the Vantage API
You can import business metrics to Vantage, from other applications, with the Vantage API. Use the `/business_metrics` endpoint to view, create, update, and delete business metrics. You can also delete specific business metric values by date range and label with [`DELETE /business_metrics/{token}/values`](https://docs.vantage.sh/api/businessmetrics/delete-business-metric-values). Ensure you have a valid Read/Write [Vantage API token](/api/authentication). See the [API documentation](https://docs.vantage.sh/api/businessmetrics/get-all-business-metrics) for details on how to use these endpoints.
JSON `values` and `forecasted_values` accept a single optional `label` per row. To import multiple named label columns, upload a CSV with [`PUT /business_metrics/{token}/values.csv`](https://docs.vantage.sh/api/businessmetrics/update-business-metric-values-from-csv). For a metric that supports multiple label columns, every header other than `date` and `amount` becomes a label column. When reading values, [`GET /business_metrics/{token}/values`](https://docs.vantage.sh/api/businessmetrics/get-business-metric-values) supports a `label_values` query parameter to filter by exact label value.
## Calculation Types
When you assign a business metric to a Cost Report, you choose a *calculation type* that determines how Vantage combines the metric with your costs. Each calculation is performed per date bin (day, week, or month) and rendered on a secondary y-axis as a line overlay.
You can apply only **one calculation type per Cost Report**. You can add multiple business metrics to the same report, but they must all use the same calculation type so the secondary axis stays consistent. For example, if a report already uses a Gross Margin calculation, any additional metrics you add to that report must also use Gross Margin.
The same business metric can use different calculation types on different Cost Reports. For example, you can apply a Revenue metric as Gross Margin on one report and as Raw Value on another.
Vantage supports four calculation types:
| Calculation type | Formula (per date bin) | Unit Scale | Typical metric | Example question |
| - | - | - | - | - |
| **Unit Cost** | total cost ÷ business metric | Applies | Any unit (users, requests, customers) | What does it cost to serve one customer? |
| **Usage Unit Cost** | total provider usage ÷ business metric | Applies | A usage-driving unit | How many tokens do we burn per pull request? |
| **Gross Margin** | (revenue − cost) ÷ revenue | Ignored | Revenue | Is our cloud spend compressing margin? |
| **Raw Value** | business metric value (no calculation) | Ignored | Any raw value | How does customer growth track against spend? |
### Unit Cost
For each date bin, Vantage sums all costs on the report and divides by the summed (and optionally label-filtered) business metric to produce a cost per unit, such as cost per customer or cost per million API requests. This is the original business metric behavior, and existing metric applications continue to use it with no action required.
Use the **Unit Scale** option to divide the business metric before the calculation—for example, to view *cost per thousand requests* instead of cost per request.
Use Unit Cost for reports where you care about spend efficiency against a business driver: AI coding tools vs. pull requests merged, infrastructure vs. active customers, or CDN spend vs. requests served. Look for patterns like cost per unit rising while the business metric stays flat (spend growing without matching output) or falling as volume scales (efficiency improving).
### Usage Unit Cost
For each date bin, Vantage divides a cloud provider usage quantity by the business metric, producing a ratio like GB-hours per employee or LLM tokens consumed per pull request. **Unit Scale** applies exactly as it does for Unit Cost.
Usage Unit Cost is only available on Cost Reports that expose a usage quantity. Because a report can contain many different usage units, apply a [Usage Unit filter](/cost_reports#filter-by-usage-unit) so all included costs share the same unit (for example, GBs of storage) before applying this calculation.
Use Usage Unit Cost when you want efficiency in *resource consumption*, not dollars: tokens per pull request, storage GB-hours per employee, or compute hours per deployment. Look for patterns like usage per unit climbing (more wasteful consumption) or falling (each unit of output needing less resource), independent of price changes.
### Gross Margin
For each date bin, Vantage calculates `(revenue − cost) ÷ revenue` and renders the result as a margin percentage alongside your costs. Because the result is a ratio, **Unit Scale is ignored**.
The business metric should represent revenue for this calculation to be meaningful. Metronome [daily invoice revenue](/business_metrics#import-from-metronome) is a common source for this metric.
Use Gross Margin for Cost Reports scoped to the costs that deliver your product: cloud COGS, AI inference providers, or delivery infrastructure, paired with a revenue metric. Look for patterns like margin expanding as revenue outpaces those costs, or compressing when cost growth eats into profitability.
### Raw Value
Vantage overlays the business metric value as-is on the secondary axis—no calculation is performed. Use this to visually correlate a raw metric, such as customer or transaction volume, against spend over time. Because the value is passed through directly, **Unit Scale is ignored**.
Use Raw Value when you want to overlay a business signal next to spend without calculating a ratio: monthly active users vs. core cloud spend, transactions vs. payment-processing costs, or signups vs. acquisition infrastructure. Look for patterns like spend rising while the metric stays flat, or the metric growing faster than costs.
## Assign Business Metrics to Cost Reports
Once your import is complete, you can assign metrics to one or more Cost Reports. You can also assign as many different business metrics to a Cost Report as you want, provided they use the same [calculation type](/business_metrics#calculation-types).
You can start this assignment from either direction: from a business metric's **Metric Overview** tab using the steps below, or directly from a [Cost Report](/cost_reports) by opening the report's action menu and selecting **Assign a Business Metric**, which opens the same assignment dialog.
Under **Assigned Cost Reports**, click **Assign a Report**.
The **Assign a Report** popup window is displayed. In the **Report** dropdown menu, search for and select a Cost Report.
For **Calculation**, select how Vantage should apply the metric to the report: **Unit Cost**, **Usage Unit Cost**, **Gross Margin**, or **Raw Value**. See [Calculation Types](/business_metrics#calculation-types) for details on each option. If the report already has other business metrics assigned, you must select the same calculation type they use.
For **Unit Scale**, select either **Per Unit**, **Per Hundred**, **Per Thousand**, **Per Million**, or **Per Billion**. The scale is used to divide the business metric before calculating the per unit value. Use this scale to create a per-unit cost, such as *Cost per Thousand Requests*. If you select **Per Unit**, no division occurs, and the actual metric number will be used within the Cost Report.
Unit Scale applies only to the **Unit Cost** and **Usage Unit Cost** calculation types. It is ignored for **Gross Margin** and **Raw Value**.
For **Label Filter**, optionally filter the metric by label column and values.
* First select a label **column** (for example, `application`, `team`, or `environment`), then select one or more values for that column. Selected values within a column are aggregated (OR), and filters across columns are combined (AND).
* Click **+ Add Filter** to filter by additional label columns on the same assignment.
* You can assign the same metric to different Cost Reports and select a different label column on each (e.g., cost per application on one report and cost per team on another).
* Select **unlabeled** to include values where the selected label column is blank.
(Optional) For **Cost Report Label**, enter a custom label that controls how this metric is named on the Cost Report chart and legend. Leave it blank to use the default label for the selected calculation type.
Click **Save**. The metric is displayed on the corresponding Cost Report based on the selected calculation type, scale, and optionally selected labels.
Calculations appear the same way when the Cost Report is added as a widget on a [Dashboard](/dashboards). They are also included when you [export a Cost Report](/cost_reports#export-cost-reports) or [Dashboard](/dashboards#export-dashboards).
### Change a Calculation Type
You can change the calculation type of an assigned metric by editing its entry under **Assigned Cost Reports**. Because a report can use only one calculation type at a time, you can only change a metric's calculation type if it is the sole business metric on that report. If the report has other business metrics assigned, remove them before changing the calculation type.
### Assign via the API or Terraform
You can assign a business metric to a Cost Report and set its calculation type programmatically. When creating or updating a business metric with the [`/business_metrics`](https://docs.vantage.sh/api/businessmetrics/get-all-business-metrics) endpoint, include the `calculation_type` field (`unit_cost`, `usage_unit_cost`, `gross_margin`, or `raw_business_metric`) alongside `unit_scale` and either `label_filter` (single-label metrics) or `label_filters` (a map of label column to values for multi-column metrics) on each Cost Report token. To retrieve the calculated values for a report, use the [`GET /unit_costs`](https://docs.vantage.sh/api/unitcosts/get-all-unit-costs-for-a-cost-report) endpoint. The same assignment can be managed in Terraform with the [`vantage_business_metric`](/terraform_docs/resources/business_metric) resource.
## Forecasted Metrics
Dynamic forecasting is available to Enterprise customers only.
You can upload projected future values of your business metrics to create [Dynamic Forecasts](/forecasting#dynamic-forecast) that align your cost projections with business growth expectations. When you upload forecasted business metrics, Vantage analyzes historical correlations between your costs and metrics, then incorporates your projections into forecasting models. Each business metric has a single set of forecasted values; to model different projections for that metric, update its forecasted values and all associated Cost Reports will reflect the updated projections. The same business metric can also serve as the base for [Scenario Model forecasts](/forecasting#scenario-model-forecasts) on a Cost Report.
Dynamic Forecasts are a distinct forecast type from forecasts built with [Scenario Models](/scenario_models), which model known future costs, credits, or trends and are applied to a Cost Report as [Scenario Model forecasts](/forecasting#scenario-model-forecasts). See the [Forecasting](/forecasting) overview for a comparison of all three forecast types.
Follow the steps in the [Import Business Metrics](/business_metrics#import-business-metrics) section above if you haven't created a business metric yet.
Once you've uploaded historical costs, select the **Forecasted Metrics** tab.
Only data uploaded to the **Forecasted Metrics** tab will be used for Dynamic Forecasting. Upload a CSV file with your projected metrics, use [the Vantage API](/business_metrics#import-via-the-vantage-api), or import them from a connected integration using the same steps as [historical metrics](/business_metrics#import-business-metrics). Use the same CSV format as historical data, including multiple named [label columns](/business_metrics#labeled-business-metrics) when needed. Label filters configured on the assigned Cost Report also apply to forecasted values when the forecasted data uses the same label structure. For example:
```csv theme={null}
date,amount,application,team
2026-11-01,5000,app1,payments
2026-11-02,5200,app1,payments
2026-11-03,5400,app1,payments
2026-11-01,3000,app2,checkout
2026-11-02,3100,app2,checkout
2026-11-03,3200,app2,checkout
```
Assign the business metric to a Cost Report if you haven't already. See the [Assign Business Metrics to Cost Reports](/business_metrics#assign-business-metrics-to-cost-reports) section for details.
Review the [Forecasting](/forecasting#dynamic-forecast) documentation to learn how to view your Dynamic Forecast on Cost Reports and compare forecast types.
## View Business Metrics on Cost Reports
To inspect your business metric calculations, navigate to the assigned Cost Report. The calculation renders on a secondary y-axis as a line overlay:
* **Unit Cost** and **Usage Unit Cost** display the per-unit value, and the average for the selected date range is displayed at the top of the screen. This average is calculated by first binning business metrics according to the selected date bucket (day, week, or month), then dividing the total costs (or usage) by the total binned business metrics for date bins where both values are available. This ensures accurate results that respect the date bucket size used by the report.
* **Gross Margin** displays the margin percentage over the selected date range.
* **Raw Value** displays the metric value as-is, making it easy to correlate the metric against spend.
To see the calculation line, ensure your view is set to daily, weekly, or monthly.
Hover over a data point to see the value for that day, week, or month. If you add multiple business metrics to the same Cost Report, each business metric is displayed as a separate line, as shown in the example above.
# Canvas
Source: https://docs.vantage.sh/canvas
Create custom, refreshable reports from natural-language prompts.
Canvas turns a plain-language prompt into a structured, editable report. Describe the data, time range, groupings, and calculations you need, and Canvas creates a table you can refine by updating the prompt.
Canvas is powered by the same [FinOps Agent](/vantage_finops_agent) that answers cost questions in the console and Slack. If you are new to prompting the agent, the [FinOps AI Prompt Guide](/finops_ai_prompt_guide) covers the general Intent, Scope, and Direction framework that the [Prompt Library](#prompt-library) below builds on.
## Create a Canvas
From the top navigation, click **Reporting**, then select **Canvas**. This page displays saved canvases along with the creator and creation date. A **Processing** badge means Canvas is still generating or refreshing that report's table data. A **Paused** or **Pausing Tomorrow** badge means nightly refresh has stopped or will stop soon because the Canvas hasn't been viewed recently. See [Automatic Refresh and Pausing](#automatic-refresh-and-pausing).
Click **New Canvas**.
In the prompt editor, write what you want the report to show. Include the data to pull, how to group it, the time range, any calculations, and how to sort. For example:
Show AWS spend for the last 6 months grouped by service. Add a column for each service's share of total spend, sort by spend descending, and include a total row.
See [Prompting Best Practices](#prompting-best-practices) for details on how to best structure your prompts. On the New Canvas screen, you can also click one of the example prompts to prefill the editor.
Click **Generate Canvas**. Table generation can take a few minutes for larger requests. After the table is generated, you can refine the prompt and click **Update Canvas** to regenerate the table as many times as you want before saving it.
A new canvas isn't saved until you click **Save**. If you start a generation on the New Canvas page and then navigate away or close the tab before saving, your browser warns you with **"Changes you made may not be saved."** Stay on the page until the table appears, then save it.
Give the Canvas a title (click the title to edit it inline) and click **Save**. The Canvas is added to your Canvas list so you and your team can return to it. Unsaved canvases you were experimenting with are cleaned up automatically and won't clutter the list.

After you create a Canvas, you can keep it updated in a few ways:
* **Edit the prompt:** Open the prompt sidebar, change the text, and click **Update Canvas** to regenerate the table with your new instructions. Click **Save** to keep the updated prompt and table.
* **Automatic nightly refresh:** Saved canvases refresh automatically once per night as long as they are being viewed. After 5 days without a view, nightly refresh pauses. Opening the Canvas (or a dashboard that includes it) resumes the nightly schedule; the table updates on the next nightly run, not immediately. See [Automatic Refresh and Pausing](#automatic-refresh-and-pausing). The last updated time is shown in the top-right corner.
## Automatic Refresh and Pausing
Saved canvases refresh automatically once per night so the table stays current. The last updated time is shown in the top-right corner of the Canvas.
Nightly refresh runs only for canvases that have been viewed in the last 5 days. After 4 days without a view, the Canvas list shows a **Pausing Tomorrow** badge. After 5 days without a view, nightly refresh stops and the Canvas shows a **Paused** badge.
The following actions count as a view:
* Opening the Canvas in the console
* Viewing a [Dashboard](/dashboards) that includes the Canvas as a widget
* Retrieving or updating the Canvas by token with the API (`GET` or `PUT /canvases/{token}`), including the [Vantage MCP](/vantage_mcp) `get-canvas` tool
The following actions do **not** count as a view:
* Opening the Canvas list page
* Listing canvases with the API or the Vantage MCP `list-canvases` tool
Opening a paused Canvas (or otherwise recording a view) resumes the nightly refresh schedule. The table does not regenerate immediately; it updates on the next nightly run. On the Canvas page, a **Paused** badge is shown with **Data refreshes on the next nightly run** until that run completes.
To regenerate the table immediately, edit the prompt and click **Update Canvas**.
| Badge | Meaning |
| - | - |
| **Processing** | Canvas is generating or refreshing the table. |
| **Pausing Tomorrow** | The Canvas has not been viewed in 4 days. Nightly refresh will pause tomorrow unless it is viewed. |
| **Paused** | Nightly refresh has stopped after 5 days without a view. Opening the Canvas resumes the nightly schedule. |
## Table Formatting
Vantage formats each column based on the type of data it contains:
| Column type | Used for | Rendering |
| - | - | - |
| `string` | Names, labels, identifiers (service, account, tag value) | Plain text |
| `number` | Counts, quantities, ratios | Numeric |
| `currency` | Cost and spend values | Currency-formatted (for example, `$1,234.56`) |
| `date` | Days, months, periods | Date-formatted |
| `percent` | Shares, variance, change | Percent-formatted (for example, `12.4%`) |
You can ask for computed columns (for example, the dollar and percentage change between two periods), a specific sort order, and a total row in your prompt. Each Canvas renders a single table from its prompt. To present multiple tables, create multiple canvases. Charts are not supported today; if you want a visual summary, ask Canvas to create a table with the categories, totals, shares, or status columns you want to compare.
Currency columns reflect the currency selected for your [workspace](/workspaces).
## Sharing and Access
Canvas uses the same access model as your other [Cost Reporting items](/rbac#manage-access-for-specific-cost-reporting-items):
* **Workspace and team access:** When you save a Canvas, access follows the [RBAC](/rbac) rules for the workspace, just like [Cost Reports](/cost_reports) and [dashboards](/dashboards).
* **Manage Access per Canvas:** Use the **Manage Access** option on a Canvas to grant or restrict access to specific teams, the same way you would for a report or dashboard.
## Prompting Best Practices
Canvas prompts and [FinOps Agent](/vantage_finops_agent) prompts share the same foundation: be clear about your **Intent** (what you want), **Scope** (which data), and **Direction** (how to present it). The [FinOps AI Prompt Guide](/finops_ai_prompt_guide) covers that framework in depth. The difference with Canvas is that the output is always a **table**, so the most useful prompts describe the table itself.
When you describe a Canvas, think in terms of the table you want to see and include these details:
| Prompt detail | What to include |
| - | - |
| Rows/grouping | What each row represents: group by service, account, region, tag, team, day, or month. |
| Columns/metrics | Which values to show per row: amortized or billed cost, usage quantity, a count, or a business metric. |
| Computed columns | Derived values like dollar change, percentage change, variance against a budget, or a unit cost. |
| Comparison periods | A second period to compare against, such as month-over-month, week-over-week, or a fixed baseline. |
| Sort and limit | How to order rows (for example, by current spend descending) and how many to keep (top 10). |
| Totals and formatting | Whether to add a total row, and which columns should read as currency or percent. |
A fully specified Canvas prompt names several of these in one sentence:
Show AWS costs grouped by the `department` tag for May 2026. Include a previous-period comparison column for April 2026, plus computed columns for the dollar change and percentage change between periods. Sort by current-period spend descending and add a total row at the bottom.
How that maps to the table:
* **Rows/grouping:** "grouped by the `department` tag"
* **Columns/metrics:** AWS cost for the current month
* **Comparison period:** "previous-period comparison column for April 2026"
* **Computed columns:** "dollar change and percentage change between periods"
* **Sort and totals:** "sort by current-period spend descending and add a total row"
You can also control two more elements directly in the prompt:
* **Formatting:** Tell Canvas how to render a column—for example, "format currency rounded to the nearest thousand, like \$100K" or "show the change as a percentage with one decimal."
* **Templates:** Reference an existing [Cost Report](/cost_reports) by token to reuse its filters and settings, for example, "use Cost Report `rprt_xyz789abc123def4` as a template, keeping its filters but changing the date range to last month."
If a prompt references something the agent can't find, such as a tag or Virtual Tag that doesn't exist, Canvas surfaces a human-readable explanation of what went wrong instead of an empty table. Check the tag name or scope and try again. See [Troubleshooting](#troubleshooting) for the full list of messages you might see.
## Prompt Library
Copy any of these prompts as a starting point and replace the values in brackets (such as `[workspace]` or `[time period]`) with your own. Each one is written to produce a table.
### Cost Breakdowns
Break spend down by service, account, region, or tag to see where the money goes.
Show me my top 10 AWS costs by service over the last 6 months.
Break down last month's spend by provider and service in the \[workspace] workspace. Sort by cost descending and add a total row.
Show spend by AWS account and region for \[time period], sorted by cost descending.
### Period Comparison and Variance
Compare two periods and compute the change in dollars and percent.
Compare spend by service for this month vs. last month. Add columns for the dollar change and percentage change, sort by the largest increase, and include a total row.
Show weekly spend by team tag for the current week with a previous-week comparison column and the percentage change between them.
### Budgets and Variance
Track actuals against targets to see what's on- or off-track. [Budgets](/budgets) can run on a period from weekly up to multi-year, so you can compare spend against the budget for whatever period you track.
Show weekly spend by team tag with budget and variance in dollars and percent.
For each team in the \[workspace] workspace, show current-period spend, the budget for the current period, the dollar variance, and the percent of budget used. Sort by percent of budget used descending.
Show rows from my `department` Virtual Tag values. Add columns for their weekly accrued costs, the corresponding budget with a header of "Target" instead of "Budget", then two computed columns for the difference in dollars and in percent.
Analyze AI spending across engineering teams. Compare actual spend against budget allocations, identify teams at risk of exceeding budget, and assign a Budget Health status to each team.
### AI and Token Usage Efficiency
Track AI provider spend and usage to understand efficiency over time. If you've configured a [Business Metric](/business_metrics) such as Linear requests completed or Jira tickets closed, you can divide AI spend by it to compute a per-unit cost.
Break down monthly token usage by provider and show month-over-month change.
Show AI provider spend by model for the last 3 months, with a column for cost per million tokens. Sort by spend descending.
Show my top 10 developers by Cursor spend over the last 3 months. Using my "Linear Requests Completed" Business Metric, add a per-unit cost column for spend per completed request and sort by it, lowest cost first.
### Team and Department Showback
Allocate spend across teams or departments for showback and chargeback.
Show last month's spend grouped by `tag:team`, sorted by cost descending, with each team's share of total as a percentage column.
Show spend by department for the current quarter with a previous-quarter comparison column and the percentage change.
Show all of my `customers` Virtual Tag values and their spend as a percent of our total spend, month over month.
### Unit Economics and Business Metrics
Combine Vantage cost data with an existing [Business Metric](/business_metrics) to compute unit costs or compare spend against business outcomes.
If you import revenue and usage from [Metronome](/metronome), reference the Metronome-backed business metric by name and pair it with the Cost Report that represents the cost you want to analyze.
Show monthly total spend for the last 6 months. Use my "Revenue" Business Metric and add a column for cost as a percentage of revenue.
Using my "COGS" Cost Report and the "Metronome Virtual Machine Hours" business metric, calculate cost per VM hour by customer for the last 30 days. Include total COGS, total VM hours, cost per VM hour, and rank customers by total COGS.
Compare "Metronome Revenue" to my "COGS" Cost Report for the last month. Group by customer label and include revenue, COGS, gross margin dollars, and gross margin percent.
Show monthly infrastructure spend per customer for the last 6 months using my "Active Customers" Business Metric. Include the cost-per-customer column and the month-over-month change.
Compare infrastructure spend against my "Product Growth" Business Metric across engineering initiatives. Identify which products are scaling efficiently and assign a Scaling Health status.
### Trends Over Time
Build a time series to see how spend moves day over day or month over month.
Show daily total spend for the last 30 days as a two-column table of date and cost.
Show monthly spend by service for the last 6 months with a column for each month, so I can scan the trend across the row.
## Verify Your Results
Canvas generates tables from your prompt, so small wording changes can change the output. If a table does not look right, use the checks below to validate the data and refine your prompt.
* **Compare the scope:** If a total is different from what you expected, compare the Canvas prompt against an existing [Cost Report](/cost_reports) and make sure both use the same workspace, filters, date range, and cost settings.
* **Check how derived columns are defined:** For columns like variance or percentage change, confirm that the prompt clearly states which columns or periods should be compared.
* **Refine and re-run:** If the table does not match your intent, make the prompt more explicit: name the exact metric, period, grouping, and calculation you want, then regenerate the Canvas.
## Troubleshooting
If a Canvas doesn't behave as expected, use the table below to identify the cause and resolution.
| Symptom | Possible Cause | Resolution |
| - | - | - |
| A **"Changes you made may not be saved."** browser warning appears when you leave a Canvas page | The Canvas has unsaved changes, such as a generated table that has not been saved yet, an edited title, or an edited prompt | Save the Canvas or discard your changes before leaving. |
| Canvas returns an error mentioning a tag or field instead of a table | A referenced tag, Virtual Tag, or field doesn't exist for the provider or time range you're querying | Confirm the spelling and that the tag exists for that provider and period, then regenerate. |
| Canvas shows **"This prompt could not be generated"** | The prompt is ambiguous or too complex. Too many columns or calculations at once | Simplify the request and clearly describe the data, groupings, columns, calculations, or filters you want included. |
| Canvas shows **"Something went wrong generating your canvas. Please try again."** | Generation failed before Canvas could return a more specific prompt error | Try simplifying the prompt, avoid asking for unsupported output such as charts, and regenerate. |
| The table comes back empty | No cost data matches the provider, account, tag, or time range in your prompt | Widen the scope or adjust the dates. |
| Generation is slow or returns a timeout error | Large or complex prompts exceed the \~3-minute processing window | Narrow the scope (fewer columns, a shorter time range, or less granular rows) or break the report into multiple canvases. |
| You asked for a chart, such as a pie chart or bar chart | Canvas currently returns tables only | Rephrase the request as a table, for example, ask for categories, totals, percentage share, and status columns. |
| The Canvas shows a **Paused** badge, or the table looks stale | The Canvas has not been viewed in 5 or more days, so nightly refresh stopped | Open the Canvas or a [Dashboard](/dashboards) that includes it. Nightly refresh resumes; the table updates on the next nightly run. To regenerate now, edit the prompt and click **Update Canvas**. See [Automatic Refresh and Pausing](#automatic-refresh-and-pausing). |
| The Canvas list shows a **Pausing Tomorrow** badge | The Canvas has not been viewed in 4 days | Open the Canvas (or a dashboard that includes it) to keep nightly refresh active. |
| The numbers don't look right | Canvas may have interpreted the prompt differently than you intended, especially for filters, periods, or derived columns | [Verify your results](#verify-your-results). Compare the scope against a [Cost Report](/cost_reports), clarify the exact metric, period, grouping, or calculation you want, then regenerate. |
## Frequently Asked Questions
[Cost Reports](/cost_reports) are built from a fixed set of filters, groupings, and chart types. Canvas builds a custom table from a natural-language prompt, which lets you create views that don't map to a standard report, custom computed columns, period comparisons, or cost data combined with your own business metrics.
Canvas uses the same [FinOps Agent](/vantage_finops_agent) under the hood. The difference is in how you use each: Canvas is for defining persistent reporting views you come back to for recurring analysis and decision-making, while the agent is for investigating, answering questions, and taking action in the moment. Canvas is also read-only—it builds tables but never changes your Vantage configuration.
No. Canvas is read-only. The agent reads from Vantage to build your table, but it cannot create, update, or delete cost data, budgets, Virtual Tags, reports, or any other Vantage configuration.
Saved canvases refresh automatically once per night as long as they are being viewed. After 5 days without a view, nightly refresh pauses until you open the Canvas (or a dashboard that includes it). Viewing resumes the nightly schedule; the table updates on the next nightly run, not immediately. To regenerate the table now, edit the prompt and click **Update Canvas**. The last updated time is shown in the top-right corner. See [Automatic Refresh and Pausing](#automatic-refresh-and-pausing).
Saved canvases are shared within your organization according to the [RBAC](/rbac) rules of the workspace they're created in, the same as [Cost Reports](/cost_reports) and [Dashboards](/dashboards). Use **Manage Access** on a Canvas to grant or restrict access for specific teams.
Canvas can query the Vantage cost and usage data available in your current workspace, within your access scope. If your organization has connected [MCP Connectors](/vantage_finops_agent#mcp-connectors) such as Datadog, GitHub, Linear, or Notion, Canvas can also bring context from those tools into a table—for example, tracking the number of Linear tickets each developer closes against the cost of the tokens they spent to complete them. If a connector needs attention or is still pending, Canvas flags it in the connector menu with a link to that connector's settings. Canvas can also pull public AWS, Azure, and GCP instance specifications and list pricing from [instances.vantage.sh](https://instances.vantage.sh). To combine cost data with a business metric such as revenue or customer counts, provide the metric directly in your prompt or import it through [Business Metrics](/business_metrics).
Yes. Create, update, and delete actions on a Canvas are recorded in your [audit logs](/audit_logs).
You can add a Canvas to a [Dashboard](/dashboards) as a widget, alongside Cost Reports and other report types. Exporting a Canvas to CSV or PDF is planned for a future release.
# Vantage Changelog
Source: https://docs.vantage.sh/changelog
Product updates and improvements.
This page was last updated on October 2, 2026, with product updates for September 2026.
## Major Product Updates
* **Usage Budgets:** [Budgets](/budgets#cost-and-usage-budgets) can now track a usage quantity (e.g., tokens or GB) against a unit-denominated amount, including pairing a Cost budget and a Usage budget on the same [Cost Report](/cost_reports).
* **Cartesia integration:** Vantage now integrates with [Cartesia](/connecting_cartesia), ingesting model credit usage by capability and Line agent cost and minutes through the Cartesia usage APIs.
* **DigitalOcean integration:** Vantage now integrates with [DigitalOcean](/connecting_digitalocean), ingesting day-over-day billing by service, Droplet size, region, and SKU through the Billing API.
* **ClickHouse and GCP BigQuery Business Metrics:** Import [Business Metrics](/business_metrics) from [ClickHouse Cloud query endpoints](/business_metrics#import-via-clickhouse) and [GCP BigQuery SQL](/business_metrics#import-via-gcp-bigquery), including labeled metrics.
* **AWS Bedrock token allocation:** [AWS Bedrock LLM Enrichment](/aws_bedrock_enrichment) reads your Amazon Bedrock Model Invocation Logs from S3 and splits each Bedrock cost row by token share, carrying the `requestMetadata` your application attaches plus [Managed AI Tags](/managed_ai_tags) for attributing Bedrock spend to teams, applications, customers, and features in [Cost Reports](/cost_reports).
* **OpenAI Codex costs:** Vantage now ingests [OpenAI Codex](/connecting_openai#connect-openai-codex) usage and estimated costs from ChatGPT Enterprise workspaces (broken down by Codex client, model, token type, speed, and user) alongside OpenAI Platform API costs under one OpenAI provider.
* **Managed AI Tags:** Vantage now applies [Managed AI Tags](/managed_ai_tags) to supported AI provider costs, mapping billing and usage fields into a shared `vntg:ai:` schema for consistent filtering and grouping of AI spend by dimensions such as model, model provider, token type, and user.
* **Cloudflare AI Gateway enrichment:** [Cloudflare AI Gateway Enrichment](/cloudflare_ai_gateway_enrichment) joins encrypted AI Gateway Logpush logs from your S3 bucket to proxied provider costs, splitting spend by token share and gateway metadata so teams, applications, and features appear in [Cost Reports](/cost_reports) without requiring the [Custom LLM Enrichment](/custom_llm_enrichment) schema.
* **Flexible Budget Periods:** [Budgets](/budgets#budget-periods) now support a flexible start date and period length (from one day through multiple years), with updated performance views and hierarchical budgets that require children to share the same current period.
## Product Updates and Improvements
This month, we made a number of improvements and updates to enhance the Vantage experience:
* **Provider integrations:**
* **Integration connection checks:** AWS and Snowflake integration settings now display [connection-validation results](/vantage_account#connection-validation-checks) and let you run connection checks on demand.
* **Azure CSP subscription term tags:** [Azure CSP](/connecting_azure_csp#azure-csp-reporting-dimensions) costs now include `azure:subscriptionStartDate`, `azure:subscriptionEndDate`, `azure:termAndBillingCycle`, and `azure:billingFrequency` provider tags from invoice reconciliation data for filtering and grouping by subscription term and billing cycle.
* **Custom provider icons:** You can now upload a custom icon (JPEG, PNG, or GIF) for a [Custom Provider](/connecting_custom_providers#set-a-custom-provider-icon), shown wherever the provider appears, including [Cost Reports](/cost_reports), filters, the Overview page, tags, and anomaly alerts.
* **Datadog cost totals:** Fixed an issue where some [Datadog](/connecting_datadog) costs, such as Infrastructure Host costs, could be undercounted when Datadog reported an organization's costs in more than one entry.
* **Snowflake warehouse attribution:** Fixed an issue where [Snowflake](/connecting_snowflake) warehouse credits could be assigned to the wrong account when warehouses in different accounts shared the same name.
* **MongoDB Atlas dated unit prices:** You can now set [MongoDB Atlas](/connecting_mongodb-atlas#set-custom-rates) unit price multipliers with date ranges in the integration settings, so a rate change applies only to the billing periods it covers.
* **Databricks SKU mappings:** [Databricks](/connecting_databricks) now maps the `LAKEFLOW_CONNECT_FREE_USAGE` SKU pattern and the Asia Pacific (Sydney) enterprise model training SKU so those costs are categorized correctly.
* **Cursor agent and pull request tags:** [Cursor](/connecting_cursor#cursor-reporting-dimensions) costs now include provider tags that attribute spend to agent and pull request work: Cloud Agent, automation, and agent conversation IDs; pull request number, repository, and author; and service account and headless usage.
* **Fireworks AI Dedicated Training API:** [Fireworks AI](/connecting_fireworks_ai) Training API GPU-hour charges are now categorized under a **Dedicated Training API** service, with usage measured in GPU-hours.
* **Azure Kubernetes amortized costs:** Fixed an issue where [Kubernetes](/kubernetes) costs for AKS clusters could be missing when node Virtual Machines were covered by Reserved Instances or Savings Plans and costs were reported as amortized.
* **Azure Marketplace Anthropic Managed AI Tags:** [Managed AI Tags](/managed_ai_tags#supported-providers) now apply to Anthropic models billed through Azure Marketplace, including model, model provider, region, service tier, and token type.
* **Anthropic API key attribution:** Fixed an issue where some [Anthropic](/connecting_anthropic) spend lost its API key attribution and appeared as **No Resource** when Anthropic's cost and usage data reported different inference regions.
* **Cost Reports:**
* **Dynamic previous-period comparisons:** [Cost Reports](/cost_reports) using relative date ranges (e.g., **Last 7 Days**) now keep their previous-period comparison aligned as the window advances.
* **Named budget labels:** [Budgets](/budgets#view-budgets-on-cost-reports) shown on a Cost Report now include the budget's name in the accrued and forecasted labels, so reports with a budget identify which one is applied.
* **Forecast and accrued overlap:** Fixed an issue where accrued actuals and forecast rows could double-count overlapping days on accounts with delayed cost removal disabled, overstating the current month on the [Forecasts](/cost_reports#forecasts-tab) view.
* **Dashboards:**
* **Sticky Accrued Costs column:** The first column in [period-based Dashboard cost tables](/dashboards#edit-widget-settings) remains visible while scrolling.
* **Dashboard and report saved filters:** Applying a saved filter to a [Dashboard](/dashboards) now keeps each widget's own report filter and applies both, instead of replacing the report filter.
* **Cost Recommendations:**
* **Azure Reserved Instance recommendations:** [Cost Recommendations](/cost_recommendations) now include Azure Data Explorer, Azure VMware Solution, and Azure Dedicated Host Reserved Instance recommendations.
* **Azure Reserved Instance recommendation fixes:** Fixed an issue where Azure Files, Blob Storage, and SQL Database Reserved Instance recommendations from Azure Advisor could be missing from [Cost Recommendations](/cost_recommendations).
* **External AWS Savings Plans context:** [Cost Recommendations](/cost_recommendations) now surface context when a matching external AWS Savings Plan purchase already exists, clarifying Autopilot Compute Savings Plan recommendations.
* **Kubernetes rightsizing copy:** Clarified the [Kubernetes rightsizing](/cost_recommendations#kubernetes-rightsizing-recommendations) **Average Max Memory** label so it is clear the value is an average of per-window maxima, not the true peak.
* **Active Resources & Resource Reports:**
* **Azure Backup protected items:** [Active Resources](/active_resources) now list Azure Backup protected items with their vault, policy, protection status, and latest backup and recovery-point details. See [supported Azure services](/azure_supported_services).
* **Azure Virtual Machine metadata:** Azure Virtual Machine [Active Resources](/active_resources) now include resource group, power status, and state reason. Resource sync also preserves Virtual Machine size so reports no longer show a blank size.
* **New AWS database resources:** [Active Resources](/active_resources) now include Amazon MemoryDB clusters and Amazon Neptune database instances. See [supported AWS services](/aws_supported_services).
* **AWS Direct Connect resources:** [Active Resources](/active_resources) now include AWS Direct Connect connections and virtual interfaces, which you can also query in [Resource Reports](/vql_resource_report). See [supported AWS services](/aws_supported_services).
* **EFS size columns:** Amazon EFS [Active Resources](/active_resources) now split size metadata into clearer columns instead of a single combined size field.
* **RDS Reserved Instance term details:** Amazon RDS Reserved Instance [Active Resources](/active_resources) now show a human-readable duration (e.g., **1 Year**) and an end date alongside start time.
* **FinOps Agent & AI:**
* **Agent shortcut from global search:** Press **⌘⇧A** (Ctrl+Shift+A) in the [command palette](/vantage_finops_agent#use-the-command-palette) to open the FinOps Agent with the current search text as its prompt.
* **Search Agent conversations:** Global search now finds your existing [FinOps Agent](/vantage_finops_agent) conversations by title. Results include only conversations you own, and selecting one opens that chat.
* **Instance specs and pricing in the Agent:** The [FinOps Agent](/vantage_finops_agent) can now answer questions about public AWS, Azure, and GCP instance specifications, families, region availability, and list pricing from [instances.vantage.sh](https://instances.vantage.sh), alongside your own cost data, in the console, Slack, and [Canvas](/canvas).
* **MCP connector status on Canvas:** [Canvas](/canvas) pages now check your [MCP Connectors](/vantage_finops_agent#mcp-connectors) live and flag any that need attention or are still pending, with a link to each connector's settings.
* **Multi-region Bedrock logs:** [AWS Bedrock LLM Enrichment](/aws_bedrock_enrichment) now supports multiple regional Model Invocation Log S3 buckets for the same AWS account.
* **xAI Grok models on Bedrock:** [AWS Bedrock LLM Enrichment](/aws_bedrock_enrichment) now enriches costs for xAI Grok models on Amazon Bedrock. Previously, invocation logs for these models were skipped.
* **Enrichment import help:** [Enrichment](/aws_bedrock_enrichment) Import History and Token Metrics surfaces now include in-product help and documentation links.
* **Connect empty log buckets:** [AWS Bedrock LLM Enrichment](/aws_bedrock_enrichment) and [Cloudflare AI Gateway Enrichment](/cloudflare_ai_gateway_enrichment) now let you connect a log bucket that doesn't contain logs yet. Vantage shows a notice that the bucket looks empty and runs the sample-object checks once logs arrive.
* **Amazon Nova cache token costs:** Fixed an issue where [AWS Bedrock LLM Enrichment](/aws_bedrock_enrichment) didn't match Amazon Nova cache read and cache write costs to your Model Invocation Logs. These costs are now allocated like other Bedrock token costs.
* **Vantage MCP tools:** The [Vantage MCP](/vantage_mcp#vantage-mcp-tools) added tools to create, update, and delete teams; list, add, and remove team members; query Financial Commitment Report costs; create, list, get, update, and delete [Kubernetes Efficiency Reports](/kubernetes#create-efficiency-reports), plus query their costs; and create, list, get, update, and delete [Saved Filters](/saved_filters).
* **Account Settings, Audit Logs, & RBAC:**
* **SSO configuration fixes:** You can now save multiple [SSO group-to-team mappings](/sso#set-up-sso-group-mapping-for-teams) together, and enabling or disabling an SSO connection now works reliably.
* **New audit log events:** [Audit logs](/audit_logs) now record Budget create, update, and delete events, as well as connecting, reconnecting, or disconnecting [FinOps Agent MCP connectors](/vantage_finops_agent#mcp-connectors) (recorded as an **MCP Connection** event without logging credentials).
* **MSP features:**
* **Unallocated parent spend:** MSP tracked-infrastructure billing and exports now include unallocated parent spend so Management Account totals match expected billable infrastructure.
## Kubernetes Agent Updates
* Helm Chart [vantage-kubernetes-agent-1.10.0](https://github.com/vantage-sh/helm-charts/releases/tag/vantage-kubernetes-agent-1.10.0), for agent version 1.3.3, adds an optional `priorityClassName` setting for assigning an existing PriorityClass to the agent pod.
## API Updates
* **Usage Budgets:** [Create](https://docs.vantage.sh/api/budgets/create-budget), [update](https://docs.vantage.sh/api/budgets/update-budget), and [get](https://docs.vantage.sh/api/budgets/get-budget-by-token) budget endpoints now expose `type` (`cost` or `usage`) and `unit` for usage-denominated budgets.
* **ClickHouse and GCP BigQuery Business Metrics:** [Create](https://docs.vantage.sh/api/businessmetrics/create-business-metric) and [update](https://docs.vantage.sh/api/businessmetrics/update-business-metric) Business Metrics now support importing from ClickHouse Cloud query endpoints and GCP BigQuery SQL.
* **Enrichment sources:** New endpoints [list](https://docs.vantage.sh/api/enrichmentsources/get-all-enrichment-sources) and [get](https://docs.vantage.sh/api/enrichmentsources/get-enrichment-source-by-token) enrichment sources, plus [enrichment statistics](https://docs.vantage.sh/api/enrichmentstatistics/get-enrichment-statistics) for a source.
* **Twilio integrations:** You can now [create a Twilio integration](https://docs.vantage.sh/api/integrations/create-twilio-integration) through the API.
* **Kubernetes Efficiency Report costs:** A new [costs endpoint](https://docs.vantage.sh/api/kubernetesefficiencyreports/get-costs-for-kubernetes-efficiency-report) returns cost rows for a Kubernetes Efficiency Report.
* **Dashboard widgets:** New endpoints [get](https://docs.vantage.sh/api/dashboards/get-dashboard-widget), [update](https://docs.vantage.sh/api/dashboards/update-dashboard-widget), and [delete](https://docs.vantage.sh/api/dashboards/delete-dashboard-widget) a single Dashboard widget by token. Updates can change a widget's title, report, or settings without replacing the dashboard's full widget list.
* **Financial Commitment Report costs:** A new [costs endpoint](https://docs.vantage.sh/api/financialcommitmentreports/get-costs-for-financial-commitment-report) returns Financial Commitment Report cost rows with date, grouping, filter, scope, ordering, and pagination controls.
* **Integration enrichment:** [List](https://docs.vantage.sh/api/integrations/get-all-integrations) and [get integration](https://docs.vantage.sh/api/integrations/get-integration-by-token) responses now include `enriched_by`, listing active enrichment integration tokens.
* **Authenticated user ownership:** [Get authenticated user info](https://docs.vantage.sh/api/me/get-authenticated-user-info) now returns `is_account_owner`.
* **Terraform provider:** The [Vantage Terraform provider](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs) has been updated through v0.3.21:
* **Usage Budgets:** The [`vantage_budget`](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/resources/budget) resource now supports `type` and `unit` for usage-denominated budgets.
* **Budget Alerts:** Added the [`vantage_budget_alert`](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/resources/budget_alert) resource and [`vantage_budget_alerts`](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/data-sources/budget_alerts) data source.
* **Flexible Budget Periods:** The [`vantage_budget`](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/resources/budget) resource now supports `period_cadence`.
* **Provider resource folders:** The [`vantage_folder`](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/resources/folder) resource now supports provider resource folders.
* **Preferred Virtual Tags:** Fixed updates where `preferred` is the only changed field on [`vantage_virtual_tag_config`](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/resources/virtual_tag_config).
## Major Product Updates
* **Custom LLM Enrichment:** [Custom LLM Enrichment](/custom_llm_enrichment) joins your own per-request LLM usage logs from Amazon S3 to your OpenAI, Anthropic, AWS Bedrock, Google Cloud, and Azure costs using the provider-agnostic [Token Cost Allocation Specification](/custom_llm_enrichment#step-1-emit-telemetry-in-the-common-schema). Vantage splits each matching cost row by token share and adds your allocation tags, so you can filter and group AI spend that the provider bill never itemized.
* **MCP Connectors for the FinOps Agent:** The [FinOps Agent](/vantage_finops_agent#mcp-connectors) now connects to [Linear](/linear_mcp), [GitHub](/github_mcp), and [Notion](/notion_mcp) through MCP Connectors, so you can search issues, pull requests, and docs and turn a cost finding into tracked engineering work without leaving Vantage. Each user authorizes their own account, and the connectors work in the Vantage console, Slack, and [Canvas](/canvas).
* **Kubernetes Network Cost Attribution:** The [Vantage Kubernetes agent](/kubernetes_agent) can now allocate [pod-level network costs](/kubernetes_network_costs). Network spend is broken down by destination type (intra-zone, intra-region, cross-region, and internet egress) and appears in [Cost Reports](/cost_reports) alongside compute, memory, GPU, and storage costs. You can then charge it back to teams with [Virtual Tags](/tagging).
* **Cloudflare integration:** Vantage now integrates with [Cloudflare](/connecting_cloudflare) as its latest cost provider, ingesting self-serve cost and [usage data](/usage_based_reporting) through the Cloudflare API.
* **SpaceXAI integration:** Vantage now integrates with [SpaceXAI](/connecting_spacexai) (formerly xAI), ingesting Grok and SpaceXAI API cost and usage data broken down by model and SKU (e.g., `grok-4.3`), billable unit type, and API key.
* **Fireworks AI integration:** Vantage now integrates with [Fireworks AI](/connecting_fireworks_ai), ingesting serverless inference, dedicated deployment, and training costs broken down by product, model or accelerator type, and usage category (e.g., tokens and GPU-hours).
* **Updated status site:** [status.vantage.sh](https://status.vantage.sh/) now publishes major, multi-customer incident updates. Existing email subscriptions were carried over, and you can subscribe to Slack or webhook notifications from **Subscribe to Updates** on that page. Use Slack for channel posts or a webhook for your incident tooling.
* **Multi-dimensional Business Metrics:** [Business Metrics](/business_metrics#labeled-business-metrics) now support multiple named label columns (e.g., application, team, and environment), so a single metric can model the same usage across several dimensions and power cost-per-application, cost-per-team, and cost-per-environment views. Multiple label columns are supported for [CSV](/business_metrics#import-from-a-csv-file), [Datadog](/business_metrics#import-from-datadog), [Snowflake](/business_metrics#import-from-snowflake), and [Metronome](/business_metrics#import-from-metronome) imports.
## Product Updates and Improvements
This month, we made a number of improvements and updates to enhance the Vantage experience:
* **Provider integrations:**
* **Anthropic API key attribution tags:** [Anthropic](/connecting_anthropic) cost rows now include `anthropic:api_key_created_by_email`, `anthropic:api_key_created_by_name`, and `anthropic:workspace_name` provider tags, so you can filter and group Anthropic spend by the API key's creator and workspace.
* **ElastiCache cache engine tag:** Amazon ElastiCache costs now include an [`aws:cacheEngine`](/connecting_aws) provider tag, so you can filter and group ElastiCache spend by cache engine.
* **CUR 2.0 by default for AWS onboarding:** New [AWS](/connecting_aws) integrations set up through CloudFormation (AWS Console or CLI) now create a [CUR 2.0 Data Export](/connecting_aws#cur-format) by default, which unlocks richer cost data such as account-level cost allocation (AWS Organizations) tags. Existing Legacy CUR integrations keep ingesting, and the Terraform module still defaults to Legacy CUR unless you set `upgrade_to_cur_2 = true`.
* **Twilio double-counting fix:** Fixed an issue where [Twilio](/connecting_twilio) Authy and Verify costs could be double-counted when aggregate and leaf usage categories overlapped.
* **Cost Reports:**
* **Search finds reports in folders:** [Cost Report](/cost_reports) search now returns matching reports nested inside folders, not just top-level reports.
* **Provider filter duplicates:** Fixed the provider picker showing duplicate rows for accounts with both a base and an analytics integration for the same provider (e.g., Anthropic and Anthropic Analytics). The picker now shows one row per resolved provider.
* **Dashboards:**
* **Clear dashboard date range:** [Dashboards](/dashboards) now include a **Reset** control to clear a dashboard-level date range and return widgets to their own date settings.
* **Table periods as columns:** [Cost Report table widgets](/dashboards#edit-widget-settings) on Dashboards now offer a **By period** view that displays each time period as its own column, making period-over-period comparisons easier to read.
* **Cost Alerts:**
* **Small-baseline percentage alerts:** Fixed [Cost Alerts](/cost_alerts) so sub-1% percentage thresholds reliably fire on small-value and boundary changes.
* **Cost Recommendations:**
* **RDS Extended Support accuracy:** [Cost Recommendations](/cost_recommendations) no longer flag minor database versions as nearing Amazon RDS Extended Support, correcting overstated Extended Support savings.
* **Autopilot currency display:** [Autopilot](/autopilot) savings now display using your account's configured [currency](/vantage_account#currency-conversion).
* **Active Resources & Resource Reports:**
* **Azure Private Endpoint and Virtual Network Gateway metadata:** Azure Private Endpoint and Virtual Network Gateway [Active Resources](/active_resources#azure-active-resources) now include additional metadata—resource group and connection status for Private Endpoints, and point-to-site VPN configuration for Virtual Network Gateways.
* **Resource costs in your workspace currency:** [Active Resource](/active_resources) cost estimates, including S3 bucket storage summaries and provider resource costs, now display in your workspace's configured [currency](/vantage_account#currency-conversion) instead of USD.
* **Financial Commitments:**
* **Percent of total column:** [Financial Commitment Reports](/financial_commitment_reports) now include a **% of total** column, making it easier to see each row's share of committed spend.
* **Commitment amounts in workspace currency:** [Financial Commitment Reports](/financial_commitment_reports) now convert commitment amounts to your workspace's configured [currency](/vantage_account#currency-conversion) instead of always showing them in USD.
* **Account ID filtering:** The Commitments list page account filter now accepts Account IDs in addition to account names.
* **CSV export:** [Financial Commitment Reports](/financial_commitment_reports#export-the-report) can now be exported to CSV directly from the report page.
* **Savings Planner in your workspace currency:** [Savings Planner](/savings_planner) models now display amounts in your workspace's configured [currency](/vantage_account#currency-conversion) instead of USD.
* **Business Metrics & Unit Costs:**
* **Datadog import account labels:** The [Business Metrics](/business_metrics#import-from-datadog) Datadog import dropdown now shows each connected Datadog organization's name, making it easier to pick the right account.
* **Assign a business metric from the report menu:** You can now attach a [business metric](/business_metrics#assign-business-metrics-to-cost-reports) to a [Cost Report](/cost_reports) directly from the report's action menu, in addition to assigning it from the metric's page.
* **FinOps Agent & AI:**
* **Vantage MCP tools:** The [Vantage MCP](/vantage_mcp#vantage-mcp-tools) added new tools:
* **Virtual Tag tools:** List, retrieve, update, and delete [Virtual Tag Configs](/tagging), along with create, retrieve, update, and delete for their individual values.
* **Annotation tools:** Create, list, update, and delete [Cost Report annotations](/annotations).
* **MCP search and workspace filtering:** Several [Vantage MCP](/vantage_mcp#vantage-mcp-tools) list tools (e.g., cost reports, dashboards, budgets, folders, canvases, and resource reports) now support searching by name and filtering by workspace.
* **Budget Alert MCP tools:** The [Vantage MCP](/vantage_mcp#vantage-mcp-tools) added tools to create, retrieve, list, update, and delete [Budget Alerts](/budgets).
* **Canvas refresh pausing:** [Canvas](/canvas#automatic-refresh-and-pausing) now pauses a canvas's automatic nightly refresh after 5 days without a view—shown by **Pausing Tomorrow** and **Paused** badges—and resumes it when you open the canvas.
* **Account Settings, Audit Logs, & RBAC:**
* **Audit logs for preferred and hidden tags:** Marking a tag as preferred or hidden now records an event in [audit logs](/audit_logs).
* **MSP features:**
* **Billing rule backfill on assignment:** Assigning a [billing rule](/partners#billing-rules) to a Managed Account now reprocesses that account's affected historical cost periods, so the rule applies retroactively within its configured date range.
* **Billing rule reprocessing on deletion:** Deleting a [billing rule](/partners#billing-rules) now reprocesses the affected historical cost periods for every Managed Account it was assigned to, removing the rule's effects from those periods.
## Kubernetes Agent Updates
* Version 1.3.3, Helm Chart [vantage-kubernetes-agent-1.9.5](https://github.com/vantage-sh/helm-charts/releases/tag/vantage-kubernetes-agent-1.9.5), includes the following updates:
* Reduces the [network collector's](/kubernetes_network_costs) conntrack memory usage.
* Adds pod annotations for the network collector.
## API Updates
* **Search list endpoints by name:** A new `q` query parameter lets you search by name or title when listing [business metrics](https://docs.vantage.sh/api/businessmetrics/get-all-business-metrics), [cost reports](https://docs.vantage.sh/api/costs/get-all-cost-reports), [dashboards](https://docs.vantage.sh/api/dashboards/get-all-dashboards), [budgets](https://docs.vantage.sh/api/budgets/get-all-budgets), [saved filters](https://docs.vantage.sh/api/savedfilters/get-all-saved-filters), [folders](https://docs.vantage.sh/api/folders/get-all-folders), [cost alerts](https://docs.vantage.sh/api/costalerts/get-all-cost-alerts), [financial commitment reports](https://docs.vantage.sh/api/financialcommitmentreports/get-all-financial-commitment-reports), [segments](https://docs.vantage.sh/api/segments/get-all-segments), and [workspaces](https://docs.vantage.sh/api/workspaces/get-all-workspaces), so you can find a specific object by name instead of paging through every result.
* **Workspace filtering:** A `workspace` filter is now available when listing [canvases](https://docs.vantage.sh/api/canvases/get-all-canvases), [budget alerts](https://docs.vantage.sh/api/budgetalerts/get-all-budget-alerts), [network flow reports](https://docs.vantage.sh/api/networkflowreports/get-all-network-flow-reports), [Kubernetes efficiency reports](https://docs.vantage.sh/api/kubernetesefficiencyreports/get-all-kubernetes-efficiency-reports), [recommendation views](https://docs.vantage.sh/api/recommendationviews/get-all-recommendation-views), [report notifications](https://docs.vantage.sh/api/reportnotifications/get-all-report-notifications), [resource reports](https://docs.vantage.sh/api/resourcereports/get-all-resource-reports), [anomaly notifications](https://docs.vantage.sh/api/anomalynotifications/get-all-anomaly-notifications), and [teams](https://docs.vantage.sh/api/teams/get-all-teams).
* **Virtual Tag config values:** Individual [Virtual Tag](/tagging) config values are now addressable by token, with new endpoints to [retrieve](https://docs.vantage.sh/api/virtualtags/get-virtual-tag-config-value-by-token), [update](https://docs.vantage.sh/api/virtualtags/update-virtual-tag-config-value), and [delete](https://docs.vantage.sh/api/virtualtags/delete-virtual-tag-config-value) a single value.
* **Cost Alerts:** The [`/cost_alerts`](https://docs.vantage.sh/api/costalerts/get-all-cost-alerts) endpoint now exposes pagination parameters.
* **Audit logs:** Fixed an issue where account changes made through the API recorded the account's first organization as the workspace in [audit logs](/audit_logs) instead of the correct one.
* **Preferred and hidden tags:** The [`/tags`](https://docs.vantage.sh/api/tags/update-tag) endpoint now accepts `preferred` and `hidden`, letting you control which tags take precedence and which are hidden from reports.
* **Dashboards:** Updating a dashboard's name through the [`/dashboards`](https://docs.vantage.sh/api/dashboards/update-dashboard) endpoint no longer requires a `workspace_token`.
* **Financial Commitment Reports:** Fixed [Financial Commitment Report](https://docs.vantage.sh/api/financialcommitmentreports/get-financial-commitment-report-by-token) responses so Azure reserved instance rows return the correct account identifier and region instead of a blank account or a subscription path.
* **Cost Reports:** The [costs endpoint](https://docs.vantage.sh/api/costs/get-costs-for-cost-report-or-vql-filter) now respects a report's saved groupings and date range when queried by cost report token.
* **Cost providers:** The [`/cost_providers`](https://docs.vantage.sh/api/costprovider/get-cost-providers) endpoint now returns every connected integration, including each [Custom Provider](/connecting_custom_providers) (keyed `custom_provider:`) and analytics-API integrations such as Anthropic Analytics API and OpenAI Analytics API, instead of only built-in providers with a matching key. Both [`/cost_providers`](https://docs.vantage.sh/api/costprovider/get-cost-providers) and [`/cost_provider_accounts`](https://docs.vantage.sh/api/costprovideraccounts/get-all-cost-provider-accounts) now also support searching by name (`q`) and pagination.
* **Terraform provider:** The [Vantage Terraform provider](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs) has been updated across v0.3.15–v0.3.17:
* **Granular Virtual Tag values:** The `vantage_virtual_tag_config` resource now adopts the per-value endpoints and exposes `values[].token`.
* **Preferred tags:** The `vantage_virtual_tag_config` resource now supports the `preferred` attribute.
## Major Product Updates
* **Metronome business metrics:** Vantage now imports [Metronome](/metronome) revenue and usage data as [Business Metrics](/business_metrics#import-from-metronome), letting you analyze customer profitability, gross margin, and per-unit costs alongside your cloud spend.
* **Anthropic Enterprise Analytics:** The [Anthropic](/connecting_anthropic) integration now ingests data from the Claude [Enterprise Analytics (Admin) API](/connecting_anthropic#claude-enterprise-analytics-api-permissions), attributing Claude API spend across the users and workspaces in your organization for more granular cost allocation.
* **ElevenLabs integration:** Vantage now integrates with [ElevenLabs](/connecting_elevenlabs), ingesting credit-based usage costs, with support for [regional data residency endpoints](/connecting_elevenlabs#create-the-connection) (EU, India, and Singapore) for Enterprise accounts.
* **Modal integration:** Vantage now integrates with [Modal](/connecting_modal) as its latest cost provider, ingesting serverless compute costs broken down by App, environment, and compute resource (e.g., CPU, Memory, or GPU type), with Modal Apps synced as [Active Resources](/active_resources).
* **Baseten integration:** Vantage now integrates with [Baseten](/connecting_baseten), ingesting Dedicated Inference, Training, and Model API costs along with [usage data](/usage_based_reporting) measured in hours and tokens.
* **Snowflake business metrics:** You can now import [Snowflake](/connecting_snowflake) query results as [Business Metrics](/business_metrics#import-from-snowflake), joining warehouse usage and revenue data with Vantage cost data for unit economics and margin analysis.
* **New Business Metric calculation types:** [Business Metrics](/business_metrics#calculation-types) assigned to Cost Reports now support **Usage Unit Cost**, **Gross Margin**, and **Raw Value** calculations alongside **Unit Cost**, each rendered on a secondary y-axis so you can chart margin and per-unit economics directly against spend.
* **Scenario Model forecasting:** Build reusable [Scenario Models](/scenario_models) that represent known future costs, credits, or trends, such as an upcoming committed-use discount, provider credits, a one-time migration expense, or planned savings from an optimization project. Attach them to a [Cost Report forecast](/forecasting#scenario-model-forecasts) to project spend against your actual plans. Available to Enterprise customers.
* **Redesigned Dashboards experience:** [Dashboards](/dashboards) have been redesigned with a new add-widget flow, free-text widgets alongside report widgets, a resizable drag-and-drop layout, autosave, and refreshed empty states, making it faster to build and arrange dashboards.
* **Count reporting on Cost Reports:** [Cost Reports](/cost_reports#count-reporting) now support **Count** as a y-axis display type alongside Cost and Usage, showing how many distinct **Group By** values had a nonzero cost in each date bin, so you can trend the number of resources, services, models, or tagged users driving your spend.
## Product Updates and Improvements
This month, we made a number of improvements and updates to enhance the Vantage experience:
* **Provider integrations:**
* **OpenAI token usage accuracy:** Improved OpenAI token usage accuracy so reported usage aligns with the OpenAI Costs API.
* **GCP legacy usage units:** Improved accuracy for legacy GCP usage SKUs measured in seconds, so Compute usage costs are reported correctly.
* **Custom Provider CSV uploads for Integration Owners:** Users with the [Integration Owner role](/rbac#understanding-rbac-roles) can now upload CSVs to existing [Custom Providers](/connecting_custom_providers) from the UI.
* **CircleCI settings editing:** The [CircleCI](/connecting_circle_ci) integration settings page now lets you update the configured price per credit and rotate the API token in place, without removing and re-adding the integration.
* **Azure subscription tags:** Azure costs now include [`azure:subscriptionId` and `azure:subscriptionName`](/connecting_azure#azure-reporting-dimensions) provider tags, so you can filter and group Azure spend by subscription.
* **Databricks SKU coverage:** [Databricks](/connecting_databricks) added SKU mappings for Genie and London inference, and Azure-backed Databricks accounts now skip the unavailable `system.billing.account_prices` table.
* **OpenAI Resource filter:** [OpenAI](/connecting_openai#openai-reporting-dimensions) Cost Reports now expose **Resource** (the API key ID that generated the usage) as a filter option, matching the existing Resource grouping.
* **Oracle Kubernetes storage costs:** [Kubernetes](/kubernetes) PersistentVolumes on [Oracle Cloud (OKE)](/connecting_oracle) clusters are now priced from Oracle Block Volume storage rates, so Oracle-backed Kubernetes storage costs are reported accurately.
* **Cost Reports:**
* **Drilldown across saved-filter providers:** [Cost Report drilldown](/cost_reports#drill-down-in-costs-table) now applies tag drilldown constraints to all providers in a saved filter, even when the drilled tag value is missing for some of them.
* **Full filter labels on hover:** [Cost Report](/cost_reports#filter-cost-reports) and [Virtual Tag](/tagging) filters now reveal the full Resource and Service names in a tooltip on hover when a label is truncated.
* **All Resources pinned to the top:** The reporting list now always renders the default **All Resources** [Cost Report](/cost_reports) as the first row, above all folders and other reports, with a distinct icon.
* **Report and folder search scoping:** Searching the reporting list now returns matching Cost Reports and folders, and preserves the active **Starred**, **Created**, or **Recently Viewed** view while filtering in place.
* **Friendly resource names in CSV exports:** [Cost Report CSV exports](/cost_reports#export-cost-reports) now map resource IDs to their friendly names, matching what the report displays.
* **Dashboards:**
* **Wider widget metric display:** [Dashboard](/dashboards) Cost Report widgets now show more business metrics when the widget is wide enough.
* **Widget legends and tooltips:** Cost Report widgets with many groupings now aggregate excess chart datasets, keeping legends and tooltips readable.
* **Emoji in PDF exports:** [Dashboard PDF exports](/dashboards#export-dashboards) now render emoji characters.
* **Workspace currency in widgets:** [Dashboard](/dashboards) widgets now display costs in the workspace's [configured currency](/vantage_account#currency-conversion) rather than defaulting to USD.
* **Cost Alerts:**
* **Sub-1% alert thresholds:** [Cost Alerts](/cost_alerts#create-a-cost-alert) now accept percentage thresholds below one percent, down to 0.01%, so you can monitor small but meaningful cost changes on high-spend reports.
* **Cost Recommendations:**
* **Azure VMSS rightsizing and shutdown:** [Azure Cost Recommendations](/cost_recommendations#azure-recommendations) now identify underutilized Virtual Machine Scale Sets to rightsize or shut down.
* **Recommendations empty state:** The [Cost Recommendations](/cost_recommendations) page and navigation now remain visible when recommendations are enabled but currently return zero results.
* **Azure generational upgrades:** [Azure Cost Recommendations](/cost_recommendations#azure-recommendations) now identify Virtual Machines running on older instance generations that can be upgraded for better price performance.
* **Recommendation currency conversion:** [Cost Recommendations](/cost_recommendations) now convert savings amounts into your [workspace currency](/vantage_account#currency-conversion) consistently, so recommendations no longer display a converted currency symbol alongside an unconverted USD value.
* **Active Resources & Resource Reports:**
* **Resource type multi-select filter:** [Resource Reports](/active_resources) now support selecting multiple resource types in a single filter on the reporting pages.
* **Anthropic API key metadata:** [Anthropic](/connecting_anthropic) API key [Active Resources](/active_resources) now include the creator and workspace name as metadata.
* **Business Metrics & Unit Costs:**
* **Custom Cost Report labels:** When you [assign a Business Metric to a Cost Report](/business_metrics#assign-business-metrics-to-cost-reports), you can now set a custom label that controls how the metric appears on that specific report.
* **Per-billing-period import states:** The **Imported Metrics** tab now shows an import state for each billing period, so you can review completed months while others are still importing or have failed. See [Business Metrics](/business_metrics).
* **Zero-amount unit costs:** Unit cost calculations now return `0` instead of a null value when the business metric amount for a date bin is zero.
* **Virtual Tags & Tagging:**
* **Kubernetes storage namespace tag:** [Kubernetes](/kubernetes) storage cost rows now include the workload namespace as a tag, so you can group and filter Kubernetes storage spend by namespace.
* **FinOps Agent & AI:**
* **Datadog MCP Connector settings:** The [Datadog MCP Connector](/datadog_mcp) settings have been redesigned with a Connected Organizations table for viewing and disconnecting connected Datadog organizations.
* **ChatGPT app version 2:** The [Vantage ChatGPT app](/chatgpt_app) is now on version 2, supporting a broader set of read and write Vantage workflows.
* **Agent chat formatting:** [FinOps Agent](/vantage_finops_agent) chat responses now render markdown headings, lists, and accent styling consistent with the rest of the console.
* **Vantage MCP tools:** The [Vantage MCP](/vantage_mcp#vantage-mcp-tools) added new tools:
* **Canvas tools:** Create, list, retrieve, update, and delete [Canvases](/canvas).
* **`get-user` tool:** Retrieve a single user, with the users tools now grouped together.
* **Network Flow Report tools:** Create, list, retrieve, update, and delete [Network Flow Reports](/network_flow_reports), and query aggregated network flow log data by cost or bytes.
* **`list-business-metric-labels` tool:** List the distinct label values for a [Business Metric](/business_metrics#labeled-business-metrics), flattened across label keys for multi-label metrics.
* **Scenario Model and forecast tools:** Create, list, retrieve, update, and delete [Scenario Models](/scenario_models) and their Cost Report forecasts.
* **Count aggregate:** The cost tools now support the **Count** aggregate for [Count reporting](/cost_reports#count-reporting).
* **Account Settings, Audit Logs, & RBAC:**
* **Microsoft Teams reconnection:** Vantage now detects all expired Microsoft Teams tokens and displays a reconnect banner on the integration settings page. See [Email Notifications](/vantage_account#email-notifications) for related notification settings.
* **MSP features:**
* **Post-transform billing rule guardrail:** [SQL billing rules](/sql_billing_rules#monthly-insert-aggregate-rules) now require an aggregation function (e.g., `SUM()`) in post-transform Monthly Insert rules to prevent unintended row inserts.
* **Billing rule unassignment reprocessing:** Unassigning a [billing rule](/partners#billing-rules) from a child account now correctly triggers reprocessing of that account's data.
* **Duplicate charge prevention:** [Billing rules](/partners#billing-rules) that add a fixed charge are no longer applied more than once, preventing duplicated charges on managed account invoices.
* **Charge billing rule visibility:** [Billing rules](/partners#billing-rules) that add a charge now write `Usage` as the cost type, so charged rows appear in Managed Account Cost Reports.
* **Additional updates:**
* **ec2instances.info updates:** In addition to a [full rewrite](https://www.vantage.sh/blog/ec2instances-info-updates) earlier this year, the [Instances site](https://instances.vantage.sh/) has continued to receive updates. This month's updates added columns for max pods, Nitro support, and network burst/baseline bandwidth, as well as EKS Auto Mode pricing and configurable price precision. RDS Multi-AZ pricing was also added, savings plan types were separated in the UI, and Database Savings Plans shipped for RDS and ElastiCache.
* **New Guides section in the docs:** The Vantage documentation now includes a [Guides](/guides) section with outcome-oriented workflows, covering a [30-day getting started playbook](/guides/getting_started_playbook), [chargeback and showback](/guides/chargeback_showback), [RBAC setup](/guides/rbac_setup), [scaling Virtual Tags](/guides/scaling_tagging), the [FinOps AI prompt guide](/guides/finops_ai_prompt_guide), and [FinOps as Code](/guides/finops_as_code).
## Kubernetes Agent Updates
* Version 1.3.2, Helm Chart [vantage-kubernetes-agent-1.9.3](https://github.com/vantage-sh/helm-charts/releases/tag/vantage-kubernetes-agent-1.9.3), includes the following updates:
* Upgrades the Go runtime to 1.26.5.
* Fixes GPU exporter scraping on IPv6 clusters for [Kubernetes GPU cost allocation](/kubernetes#kubernetes-gpu-idle-costs).
* Warns when `nf_conntrack_acct` is disabled on the conntrack source.
* Adds Prometheus metrics endpoints and pod affinity configuration for the network collector.
* Reports whether the network and GPU collectors are enabled in the agent metadata.
## API Updates
* **API access and RBAC:** Improved [RBAC](/rbac) handling for API access, so [service tokens](/rbac_setup) consistently inherit their team's permissions across all granted resources, including teams outside the token's linked workspaces.
* **Network Flow Reports:** New endpoints are available to manage and query Network Flow Reports: [`GET /network_flow_reports`](https://docs.vantage.sh/api/networkflowreports/get-all-network-flow-reports), [`POST /network_flow_reports`](https://docs.vantage.sh/api/networkflowreports/create-network-flow-report), [`GET /network_flow_reports/{network_flow_report_token}`](https://docs.vantage.sh/api/networkflowreports/get-network-flow-report-by-token), and [`GET /network_flow_logs`](https://docs.vantage.sh/api/networkflowlogs/get-network-flow-logs) for aggregated flow log costs and bytes.
* **Business Metrics:** A new [`GET /business_metrics/{business_metric_token}/labels`](https://docs.vantage.sh/api/businessmetrics/get-business-metric-labels) endpoint returns the distinct label values for a metric. Cost Report attachments now accept multi-key `label_filters`, and the [`/business_metrics`](https://docs.vantage.sh/api/businessmetrics/get-all-business-metrics) response limit was raised to 5000.
* **Cost Reports:** The [`/costs`](https://docs.vantage.sh/api/costs/get-costs-for-cost-report-or-vql-filter) endpoint supports the new **Count** display type, and **Usage Unit** is available as a filter and grouping dimension.
* **Scenario Models:** New endpoints manage [Scenario Models](/scenario_models) and Cost Report forecasts: [`GET /scenario_models`](https://docs.vantage.sh/api/scenariomodels/get-all-scenario-models), [`POST /scenario_models`](https://docs.vantage.sh/api/scenariomodels/create-scenario-model), [`GET /scenario_models/{scenario_model_token}`](https://docs.vantage.sh/api/scenariomodels/get-scenario-model-by-token), and the corresponding [`/report_forecasts`](https://docs.vantage.sh/api/reportforecasts/get-all-report-forecasts) endpoints to assign models to a Cost Report and set a default forecast.
* **Terraform provider:** The [Vantage Terraform provider](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs) has been updated across v0.3.9–v0.3.14:
* **Workspace and folder data sources:** New `vantage_workspace` and `vantage_folder` data sources let you look up workspaces and folders by name, with pagination support.
* **Business metric calculations:** The `vantage_business_metric` resource supports the new calculation types and per-report Cost Report labels.
* **Cost report count display:** The `vantage_cost_report` resource supports the **Count** display type.
* **Scenario Models:** New `vantage_scenario_model` and `vantage_report_forecast` resources manage [Scenario Models](/scenario_models) and their Cost Report forecasts.
* **Team member updates:** Fixed an error when updating a `vantage_team` where `user_emails` and `user_tokens` were both present.
## Major Product Updates
* **Canvas:** With [Canvas](/canvas), you can use natural-language prompts to create persistent, refreshable tabular reports that combine Vantage cost data, business metrics, calculations, comparisons, and custom formatting without building a dashboard or spreadsheet from scratch.
* **Datadog MCP Connector for the FinOps Agent:** The [FinOps Agent](/vantage_finops_agent) now supports [MCP Connectors](/vantage_finops_agent#mcp-connectors), starting with the [Datadog MCP Connector](/datadog_mcp). Connect your Datadog organizations to join live Datadog telemetry—metrics, logs, monitors, dashboards, APM, and events—with your Vantage cost data in a single conversation to investigate anomalies, validate rightsizing, and correlate cost with performance, available in the console, Slack, and [Canvas](/canvas).
* **Temporal Cloud Billing API integration:** The [Temporal Cloud](/connecting_temporal) integration now ingests cost and usage data directly from Temporal's Cloud Billing API, using contracted costs, namespace-level attribution, and any credits, discounts, or adjustments from Temporal's billing report instead of estimating costs from manually configured rates. Existing customers can [migrate from the legacy Usage API estimate model](/connecting_temporal#migrate-to-cloud-billing-data).
* **Post-transform aggregate billing rules:** [SQL billing rules](/sql_billing_rules#monthly-insert-aggregate-rules) now support post-transform **Monthly Insert** rules that calculate a value from existing monthly cost rows—using aggregate functions such as `SUM()` and conditional `CASE WHEN` logic—and insert a new monthly cost row for charges like management fees, surcharges, or tiered support. These rules run after all other [billing rule stages](/partners#billing-rule-execution-order), so they operate on the final transformed costs.
## Product Updates and Improvements
This month, we made a number of improvements and updates to enhance the Vantage experience:
* **Provider integrations:**
* **MongoDB Atlas project names as tags:** MongoDB Atlas Cost Reports now include a `mongo:group_name` provider tag from Atlas invoice project names, making it easier to filter and group costs by the human-readable project name. See [MongoDB Atlas reporting dimensions](/connecting_mongodb-atlas#mongodb-atlas-reporting-dimensions).
* **Temporal Cloud API key validation:** The [Temporal Cloud](/connecting_temporal) integration now validates API keys before saving the integration. Invalid, expired, or insufficient-role keys display a form error.
* **Custom Provider integration status:** The Integrations page now reflects [Custom Provider](/connecting_custom_providers) connections more precisely, showing a Custom Provider as connected only when a Custom Provider cost integration exists. [Business Metric](/business_metrics) CSV uploads are tracked independently and no longer affect Custom Provider status.
* **Cost Reports:**
* **Account starts-with and ends-with filters:** [Cost Report filters](/cost_reports#filter-cost-reports) using **starts with** or **ends with** now match friendly account names, consistent with **contains** filters.
* **Drilldown filter preservation:** [Cost Report drilldown](/cost_reports#drill-down-in-costs-table) no longer removes existing report filters when a selected row cannot be converted into an additional filter.
* **Blank Virtual Tag drilldowns:** [Cost Report drilldowns](/cost_reports#drill-down-in-costs-table) now match grouped **Not tagged** Virtual Tag rows more accurately when a tag key exists with a blank value.
* **Allocated Virtual Tag report notifications:** Scheduled [Cost Report notifications](/report_notifications#set-up-cost-report-notifications) now include allocated Virtual Tag costs when determining whether a report has data, so reports based on allocated tags or Business Metrics send as expected.
* **Report grouping menu:** The [Cost Report grouping menu](/cost_reports#configure-report-groups) now lists tags alphabetically and shows the first 100, with search to quickly find additional tags, making it easier to scan and select group-by tags on accounts with many tags.
* **Preferred Tags in the grouping menu:** The [Cost Report grouping menu](/cost_reports#configure-report-groups) now sorts [Preferred Tags](/tagging#preferred-tags) to the top of the tag list.
* **Saved Filter VQL display:** The **View as VQL** panel now shows the saved filter's VQL on the [Saved Filters](/saved_filters) settings page.
* **Dashboards:**
* **Canvas dashboard widgets:** You can now add a [Canvas](/canvas) to a [Dashboard](/dashboards) as a widget, alongside Cost Reports and other report types.
* **Dashboard PDF export labels:** [Dashboard PDF exports](/dashboards#export-dashboards) no longer clip chart labels.
* **Cost Recommendations:**
* **Lambda rightsizing utilization metrics:** [AWS Lambda rightsizing recommendations](/cost_recommendations#aws-recommendations) now include additional utilization metrics from AWS Compute Optimizer, such as duration, memory, and provisioned-state details, on the resource rightsizing tab.
* **S3 Intelligent-Tiering recommendations:** [AWS S3 recommendations](/cost_recommendations#aws-recommendations) now account for lifecycle policies that delete objects before the 30-day minimum storage period, avoiding Intelligent-Tiering recommendations for short-lived objects.
* **Virtual Tags & Tagging:**
* **Collapsed tag key fixes:** [Collapsed tags](/tagging#tag-key-collapsing) now apply across the correct provider scope when native and Virtual Tag keys overlap, and Vantage now honors collapsed-tag priority when multiple tag match versions exist.
* **FinOps Agent & AI:**
* **Vantage MCP tools:** The [Vantage MCP](/vantage_mcp#vantage-mcp-tools) added new tools and capabilities:
* **Dashboard tools:** Get, update, and delete Dashboards.
* **Resource Report tools:** Create, list, retrieve, update, and delete Resource Reports, and list available Resource Report columns.
* **`date_bin` on `create-cost-report`:** Create Cost Reports with a specific date bin, such as day, week, month, quarter, hour, or cumulative.
* **Cost Alert tools:** Create, list, retrieve, update, and delete Cost Alerts, and list and retrieve Cost Alert events.
* **Workspaces tools:** Create, list, retrieve, and update Workspaces.
* **Account Settings, Audit Logs, & RBAC:**
* **Canvas and deleted-object Audit Log updates:** [Audit Logs](/audit_logs) now track Canvas create, update, and delete events. Audit Log details also display deleted Cost Reports, Virtual Tags, and Segments as plain text instead of linking to objects that no longer exist.
* **Dashboard Audit Logs:** [Audit Logs](/audit_logs) now track Dashboard create, update, and delete events, and the [Dashboard](/dashboards) action menu includes a **View Audit Logs** option that links to the audit logs filtered to that dashboard, matching the Cost Report flow.
* **People page performance:** The People settings page now supports server-side pagination, sorting, and search, improving load times for workspaces with many users. See [RBAC setup](/rbac_setup).
* **MSP features:**
* **Billing Rule execution stages:** [Billing Rules](/partners#billing-rules) are now grouped by execution stage, and reordering applies within each stage, making rule priority clearer for MSP billing workflows.
* **SQL billing rule comments:** [SQL billing rules](/sql_billing_rules) now support leading `--` and `/* */` comments when saving and running custom SQL.
* **SQL billing rule error messages:** [SQL billing rules](/sql_billing_rules) now show clearer validation errors for unsupported SQL syntax, operators, functions, and invalid values.
* **Managed Account default report settings:** New MSP Managed Accounts now inherit default Cost Report display settings from the parent account's oldest default report, while keeping their own title and filters.
* **Partner integration account assignment:** The Partner Integrations page now includes AWS member accounts that do not have mapped display names when assigning integrations to Managed Accounts.
## Kubernetes Agent Updates
* Version 1.3.0, Helm Chart [vantage-kubernetes-agent-1.8.2](https://github.com/vantage-sh/helm-charts/releases/tag/vantage-kubernetes-agent-1.8.2), includes the following updates:
* Collects GPU product and memory from NVIDIA node labels for more accurate [Kubernetes GPU cost allocation](/kubernetes#kubernetes-gpu-idle-costs).
* Upgrades the Go runtime to 1.26.4.
## API Updates
* **Canvases:** New Canvas API endpoints are available to list, create, retrieve, update, and delete Canvases: [`GET /canvases`](https://docs.vantage.sh/api/canvases/get-all-canvases), [`POST /canvases`](https://docs.vantage.sh/api/canvases/create-canvas), [`GET /canvases/{canvas_token}`](https://docs.vantage.sh/api/canvases/get-canvas-by-token), [`PUT /canvases/{canvas_token}`](https://docs.vantage.sh/api/canvases/update-canvas), and [`DELETE /canvases/{canvas_token}`](https://docs.vantage.sh/api/canvases/delete-canvas).
* **Cost Reports:** [`PUT /cost_reports/{cost_report_token}`](https://docs.vantage.sh/api/costs/update-cost-report) no longer resets `chart_type` or `date_bin` when a partial update only changes another field, such as the report filter.
* **Managed Accounts:** [`PUT /managed_accounts/{managed_account_token}`](https://docs.vantage.sh/api/managedaccounts/update-managed-account) now safely handles delegated access credential tokens returned by the API and treats an explicit empty `billing_rule_tokens` array as a request to clear billing rules. The endpoint also accepts `billing_rule_tokens` in their desired execution order and returns them in execution order; tokens must be ordered by execution group, and a list whose cross-group order does not match the pipeline returns a `400`.
* **Resource Reports:** [`PUT /resource_reports/{resource_report_token}`](https://docs.vantage.sh/api/resourcereports/update-resource-report) now treats omitted fields as unchanged during partial updates.
## Major Product Updates
* **FinOps Agent in the Vantage Console:** The [FinOps Agent](/vantage_finops_agent) is now available [in the Vantage console](/vantage_finops_agent#in-the-console) as a dedicated, full-screen agent page for all customers, including users on free trials. Use it to have threaded, persistent conversations about your cloud costs and to create or update Vantage resources—Cost Reports, Dashboards, Virtual Tags, Budgets, and more—directly from chat.
* **Snowflake Data Sharing:** Query your processed Vantage cost data directly from your Snowflake account via a managed [Secure Data Share](/snowflake_data_sharing). Available to Vantage Enterprise customers—contact [support@vantage.sh](mailto:support@vantage.sh) to enable.
* **Tag Key Columns in Active Resource Reports:** [Active Resource Reports](/active_resources) now support adding any provider tag key or [Virtual Tag](/tagging) key as a [dedicated column](/active_resources#add-tag-columns), so each resource displays its tag value inline rather than as part of a single grouped tags field.
* **Simplified Provider Filtering across all providers:** [Cost Reports](/cost_reports#filter-cost-reports) and [Virtual Tags](/tagging) now support filtering across every connected provider in a single filter set—select **All Providers** in the UI or omit `costs.provider` in [VQL](/vql_cost_report#filter-across-all-providers) to query against shared dimensions like Service, Account, Region, Tag, or Resource ID without re-creating per-provider filter logic.
## Product Updates and Improvements
This month, we made a number of improvements and updates to enhance the Vantage experience:
* **Provider integrations:**
* **AWS `aws:IamPrincipal` tag:** A new [`aws:IamPrincipal`](/connecting_aws#reporting-dimensions) tag is now available on AWS [Cost Reports](/cost_reports) for accounts using CUR 2.0, allowing you to filter and group costs by the IAM principal (user, role, or assumed-role ARN) that generated the usage.
* **Azure CSP `azure:OrderDate` tag:** Azure CSP costs now include an [`azure:OrderDate`](/connecting_azure_csp#azure-csp-reporting-dimensions) provider tag when present in the source data, allowing you to filter and group costs by the order date from Microsoft invoice reconciliation data.
* **MongoDB Atlas project names:** [MongoDB Atlas](/connecting_mongodb-atlas#mongodb-atlas-reporting-dimensions) Cost Reports now use the Atlas project name for account grouping when available, falling back to the project ID only when the name is unavailable.
* **Cost Reports:**
* **Cost Report export recipients:** [Cost Report exports](/cost_reports#export-cost-reports) can now be sent to any email address in your organization's verified domain, while still offering existing Vantage users as selectable recipients. The emailed download link still requires signing in to Vantage, so anyone who opens the report must be a Vantage user.
* **Annotation sidebar scoping:** Clicking an [annotation](/annotations) marker on a Cost Report chart now scopes the annotations sidebar to that day, making it easier to find the annotations tied to a specific point in time.
* **Dashboards:**
* **Truncated legend labels:** [Dashboard](/dashboards) widgets with long legend item names now truncate the label and reveal the full value in a hover tooltip, keeping wide legends readable. Long legends with many business metrics also now wrap and scroll cleanly within the widget instead of overflowing.
* **Cost Recommendations:**
* **Kubernetes rightsizing peak usage:** [Kubernetes rightsizing recommendations](/cost_recommendations#kubernetes-rightsizing-recommendations) now show a **Highest Peak** value—the single highest CPU and memory usage observed over the lookback period—alongside the existing average figures. The previous **Maximum Usage** row is now labeled **Average Max Memory** to clarify that it reflects the average of each window's maximum rather than the true peak.
* **Active Resources & Resource Reports:**
* **Azure NAT Gateway metadata:** Azure NAT Gateway [Active Resources](/active_resources#azure-active-resources) now include additional metadata—subscription name, resource group, virtual network, and associated subnets.
* **Financial Commitments:**
* **Account name on commitment expiration emails:** Commitment expiration notification emails now include an **Account** column showing the provider account name for each expiring [commitment](/commitments), making it easier to identify which account a commitment belongs to.
* **Virtual Tags & Tagging:**
* **Preferred Tags on Financial Commitment Reports:** [Preferred Tags](/tagging#preferred-tags) are now sorted to the top of filter and group-by menus on [Financial Commitment Reports](/financial_commitment_reports), matching the behavior already available on Cost Reports, Resource Reports, and Cost Recommendations.
* **Layered virtual tag allocations:** [Cost-based Virtual Tag allocations](/tagging#virtual-tag-allocation-rules) can now aggregate by the key of another allocated Virtual Tag in the same provider allocation chain, so you can build multi-step allocations where one Virtual Tag's output feeds into another (e.g., allocate shared costs to teams, then to each team's projects).
* **FinOps Agent & AI:**
* **Vantage MCP tools:** The [Vantage MCP](/vantage_mcp#vantage-mcp-tools) added new tools and capabilities:
* **Financial Commitment Report tools:** Create, list, retrieve, update, and delete Financial Commitment Reports.
* **Recommendation View tools:** Create, list, retrieve, update, and delete Recommendation Views.
* **Business Metric tools:** Read-only tools to list and retrieve [Business Metrics](/business_metrics) along with their actual and forecasted values.
* **Billing Rule tools:** Create, list, retrieve, update, and delete [billing rules](/partners#billing-rules).
* **`update-cost-report`:** Update an existing [Cost Report](/cost_reports)—including its title, VQL filter, groupings, date range, chart type, folder, and attached business metrics—completing create, read, update, and delete support for Cost Reports.
* **`min_savings` on `list-recommendations`:** The `list-recommendations` tool accepts an optional `min_savings` argument to return only recommendations with at least the specified monthly savings ([vantage-mcp-server v2.11.0](https://github.com/vantage-sh/vantage-mcp-server/releases/tag/v2.11.0)).
* **Account Settings, Audit Logs, & RBAC:**
* **Search AWS member accounts:** The AWS [Integration settings page](/connecting_aws) now supports searching connected member accounts across paginated lists, with the OU/payer tree structure preserved as you filter.
* **Expanded Audit Log coverage:** More actions now generate [Audit Log](/audit_logs) entries:
* **Billing rules:** Create, update, and delete actions on [billing rules](/partners#billing-rules) and [custom SQL billing rules](/sql_billing_rules) are now recorded, giving you a history of every change to revenue-impacting rule logic.
* **API Virtual Tag changes:** Updates to [Virtual Tags](/tagging) made through the API are now recorded even though they are processed asynchronously.
## Kubernetes Agent Updates
* Helm Chart [vantage-kubernetes-agent-1.6.0](https://github.com/vantage-sh/helm-charts/releases/tag/vantage-kubernetes-agent-1.6.0) adds an optional [`agent.allowedLabels`](/kubernetes_agent#enable-collection-of-annotations-and-namespace-labels) parameter that accepts a comma-separated allow list of Kubernetes node labels (up to 10) to collect and send to Vantage. This makes it possible to ingest well-known node labels like `node.kubernetes.io/instance-type` and `kubernetes.io/arch`.
* Version 1.2.2, Helm Chart [vantage-kubernetes-agent-1.5.1](https://github.com/vantage-sh/helm-charts/releases/tag/vantage-kubernetes-agent-1.5.1), is a security and maintenance release:
* Upgraded the Go runtime to 1.26.2.
* Refreshed Kubernetes client libraries and other dependencies so the agent stays compatible with current Kubernetes versions.
## API Updates
* **Enriched resource names in Costs API:** When a cost report includes the `resource` grouping, [`/costs`](https://docs.vantage.sh/api/costs/get-costs-for-cost-report-or-vql-filter) responses now include a human-readable `resource_name` field alongside `resource_id`, matching what the Vantage console shows. For example, an Anthropic API key resource that previously returned only its key ID now also returns its friendly key name (e.g., `claude_code_key_engineering`), making programmatic consumers easier to read.
* **`min_savings` recommendations filter:** The [`/recommendations`](https://docs.vantage.sh/api/recommendations/get-all-recommendations) endpoint now accepts a `min_savings` query parameter to return only recommendations with at least the specified monthly savings, and the same filter is now correctly applied on [`/recommendations/by_type/{type}/resources`](https://docs.vantage.sh/api/recommendations/get-all-resources-for-a-recommendation-type) (previously accepted but ignored).
* **Audit log pagination defaults:** The [`/audit_logs`](https://docs.vantage.sh/api/auditlogs/get-all-audit-logs) endpoint now returns 100 results by default and accepts up to 5,000 results per page (previously 1,000).
* **Terraform provider:** The [Vantage Terraform provider](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs) has been updated:
* **Business metric plan visibility:** Fixed an issue where `vantage_business_metric` values could appear as `(known after apply)` in update plans, making static value changes visible before applying.
* **Virtual tag config consistency:** Fixed an issue where `terraform apply` on [`vantage_virtual_tag_config`](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/resources/virtual_tag_config) reported `Provider produced inconsistent result after apply` for empty `values[].date_ranges` and `collapsed_tag_keys[].providers` lists. The provider and the underlying `/virtual_tag_configs` API now emit known-empty lists consistently across plan, apply, and refresh.
## Major Product Updates
* **Vantage plugin for Cursor:** Vantage is now available as an official [Cursor Marketplace plugin](https://cursor.com/marketplace/vantage), letting you use the [Vantage MCP](/vantage_mcp) directly in Cursor to query cloud costs and take action on Vantage workflows without leaving the editor.
* **GitHub integration for FinOps Agent (Private Preview):** The [FinOps Agent](/vantage_finops_agent) now integrates with GitHub to turn Cost Recommendations into actionable GitHub issues. When Vantage detects a new recommendation, the Agent scans your connected repositories, identifies the relevant infrastructure code, and opens an issue with the file path, current configuration, recommended change, and estimated savings. Contact [support@vantage.sh](mailto:support@vantage.sh) to enroll in the private preview. See the [blog post](https://www.vantage.sh/blog/github-finops-agent-preview) for details.
* **CircleCI integration:** Vantage now integrates with [CircleCI](/connecting_circle_ci) to ingest cost and usage data for your CircleCI organizations. Connect with a personal API token to view costs broken down by project, resource class, and compute type, with up to six months of historical data imported on initial setup.
* **Editable VQL in filters:** [Report filters](/cost_reports#edit-filters-as-vql) and [Saved Filters](/saved_filters) now support direct VQL editing. Click **View as VQL** from the Filters menu to see the current filter as a [VQL](/vql) query, then click **Edit VQL** to make adjustments.
* **Collapsed tag value prefixes:** [Collapsed tags](/tagging#collapsed-tags) now support an optional string prefix, so every collapsed value can include a descriptive label (e.g., adding a `team:` prefix produces values like `team: engineering`, `team: marketing`), making grouped tag values easier to identify in filters, Cost Reports, and dashboards.
* **Explore bar:** A new global Explore bar is available across the Vantage console. Press `Cmd+K` (Mac) or `Ctrl+K` (Windows) to quickly search and navigate to any Cost Report, dashboard, Saved Filter, Segment, or settings page without leaving your current view.
* **Extended Support Recommendations for OpenSearch, Elasticsearch, and ElastiCache:** [Cost Recommendations](/cost_recommendations) now identify Amazon OpenSearch and Elasticsearch domains, and ElastiCache for Redis clusters, that are currently incurring or approaching [extended support](/cost_recommendations#extended-support) costs.
## Product Updates and Improvements
This month, we made a number of improvements and updates to enhance the Vantage experience:
* **Provider integrations:**
* **AWS `aws:LegalEntity` tag:** A new [`aws:LegalEntity`](/connecting_aws#reporting-dimensions) tag is now available on AWS Cost Reports, allowing you to filter and group costs by the legal entity associated with each line item.
* **GCP Project ID tag:** A new [`gcp:project_id`](/connecting_gcp#reporting-dimensions) provider tag is now available on GCP Cost Reports, allowing you to filter and group costs by the project ID associated with each line item.
* **Custom Provider amortization date handling:** [Custom Provider](/connecting_custom_providers#data-format) CSV uploads now treat `ChargePeriodEnd` as an exclusive end date for amortized costs, matching the FOCUS specification and preventing single-day rows from being amortized across an extra day.
* **Cost Reports:**
* **Add to Dashboard shortcut:** The [Cost Report](/cost_reports) ellipsis menu now includes an **Add to Dashboard** option, letting you navigate directly to [Dashboards](/dashboards) to add the current report as a widget.
* **Kubernetes Efficiency Report regions:** [Kubernetes Efficiency Reports](/kubernetes#create-efficiency-reports) now support filtering and grouping by **Region**, making it easier to analyze idle and total Kubernetes costs by cloud region.
* **Budget Performance in report notifications:** [Cost Report notifications](/report_notifications#set-up-cost-report-notifications) now include a **Budget Performance** section when the report has linked budgets, helping recipients compare actual spend against budget targets directly from scheduled email, Slack, or Microsoft Teams updates.
* **Cost Recommendations:**
* **Potential Savings currency conversion:** [Cost Recommendations](/cost_recommendations) Potential Savings amounts on Resource Reports and rightsizing views now correctly display in your workspace's configured [currency](/vantage_account#currency-conversion).
* **Idle GKE cluster recommendations:** Vantage now surfaces idle [Google Kubernetes Engine (GKE)](/cost_recommendations#gcp-recommendations) cluster recommendations, identifying clusters with little or no workload activity so you can scale them down or delete them. A new **Idle GKE Cluster** tab is available on affected GKE cluster resources with the recommended remediation.
* **Active Resources & Resource Reports:**
* **ELB instance metadata:** [ELB Active Resources](/active_resources#aws-active-resources) now display registered EC2 instance metadata, including target group details, making it easier to understand which instances are behind each load balancer.
* **Active Resources chart and Cost Report link:** The [Active Resources](/active_resources) detail page now defaults to a stacked bar chart grouped by service and category, and includes a **View in Cost Report** button that links directly to the default Cost Report filtered by the resource.
* **Resource Report folders:** [Resource Reports](/active_resources) can now be organized into folders, with support for bulk move operations and search across folders—matching the same folder experience already available for Cost Reports.
* **S3 Last Accessed Date:** [S3 Active Resources](/active_resources#aws-active-resources) now include a **Last Accessed Date** metadata field, derived from S3 request activity in your billing data, making it easier to identify unused or infrequently accessed buckets.
* **Virtual Tags & Tagging:**
* **Preferred virtual tags:** You can now mark [Virtual Tags](/tagging#preferred-tags) as preferred directly from the **Virtual Tags** tab on the Tags settings page, in addition to the existing **All Tags** tab workflow.
* **FinOps Agent & AI:**
* **New Vantage MCP budget tools:** Three new budget management tools have been added to the Vantage MCP: `get-budget`, `update-budget`, and `delete-budget`, giving you full CRUD control over [Budgets](/budgets) from any MCP client. See the [Vantage MCP Tools](/vantage_mcp#vantage-mcp-tools) section for details.
* **Filter `list-cost-reports` by folder:** The [`list-cost-reports`](/vantage_mcp#vantage-mcp-tools) Vantage MCP tool now accepts an optional `folder_token` argument to return only Cost Reports within a specific folder.
* **Expanded Vantage MCP cost tools:** The [`list-recommendations`](/vantage_mcp#vantage-mcp-tools) tool now supports more filters, including tag key/value, provider, account, region, type, and date filters. The `list-costs` and `query-costs` tools now expose cost settings and grouping controls, including credits, refunds, discounts, taxes, amortization, unallocated costs, aggregate-by mode, previous-period comparison, and grouping fields.
* **Account Settings, Audit Logs, & RBAC:**
* **Audit Log diff display:** [Audit Logs](/audit_logs) now display changes in a GitHub-style diff format with color-coded additions and removals, making it easier to see exactly what was modified in each audit event.
* **MSP features:**
* **Managed Accounts on billing rules:** [Billing rule](/partners#billing-rules) detail pages now include a **Managed Accounts** section that shows which Managed Accounts currently use the rule.
* **SQL billing rule validation and formatting:** The [Custom billing rule](/partners#custom-billing-rules) editor now includes **Validate** and **Format** buttons. **Validate** checks the SQL query for syntax errors, schema mismatches, and common issues before saving. **Format** auto-formats the SQL for readability.
* **AI-assisted SQL billing rules:** The [SQL billing rules](/sql_billing_rules) documentation now includes an AI assistant that can draft, validate, and troubleshoot billing rules from plain-language descriptions. Click one of the quick-start prompts on the page, or open the assistant in ChatGPT, Claude, Cursor, or Perplexity using the direct links.
## Kubernetes Agent Updates
* Version 1.2.1, Helm Chart [vantage-kubernetes-agent-1.4.1](https://github.com/vantage-sh/helm-charts/releases/tag/vantage-kubernetes-agent-1.4.1), is a security and maintenance release:
* Upgraded Go runtime to 1.26.1, addressing a crypto/TLS session resumption vulnerability (CVE-2025-68121).
* Updated `golang.org/x/net` dependency to v0.38.0 for additional security fixes.
* Added security hardening for tar extraction and HTTP server configurations.
* Helm Chart [vantage-kubernetes-agent-1.5.0](https://github.com/vantage-sh/helm-charts/releases/tag/vantage-kubernetes-agent-1.5.0) adds optional [`agent.extraEnv`](/kubernetes_agent#data-persistence) configuration for passing additional environment variables to the agent container. This enables AWS S3 persistence on non-EKS clusters, such as GKE clusters using AWS IAM OIDC federation.
## API Updates
* **Business Metric value deletion:** A new [`DELETE /business_metrics/{token}/values`](https://docs.vantage.sh/api/businessmetrics/delete-business-metric-values) endpoint deletes historical or forecasted Business Metric values by date range and optional label, returning the number of rows removed.
* **Pagination for recommendation resources:** The [`GET /recommendations/{token}/resources`](https://docs.vantage.sh/api/recommendations/get-all-resources-for-a-recommendation) endpoint now paginates results with a default page size of 25 and a maximum of 500 (via a new `limit` query parameter), preventing timeouts on recommendations with large resource sets.
* **Virtual tag config label transforms:** The [`/virtual_tag_configs`](https://docs.vantage.sh/api/virtualtags/create-virtual-tag-config) create and update endpoints now support an optional `label_transforms` array on business metric values. Label transforms let you extract or reformat the label before it becomes the tag value—for example, using `{"type": "split", "delimiter": ":", "index": 1}` to extract the second segment of a colon-delimited label like `env:production` into the value `production`.
* **Terraform provider:** The [Vantage Terraform provider](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs) has been updated:
* **Workspace resource:** New [`vantage_workspace`](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/resources/workspace) resource for creating and managing workspaces via Terraform, including `name`, `currency`, `enable_currency_conversion`, and `exchange_rate_date` attributes.
* **Virtual tag config values:** The [`vantage_virtual_tag_config`](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/resources/virtual_tag_config) resource `values` blocks now support `date_ranges` for configuring [Virtual Tag time frames](/tagging#virtual-tag-time-frames) and `label_transforms` for business metric labels.
* **Managed account fields:** The [`vantage_managed_account`](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/resources/managed_account) resource now exposes `include_managed_account_integrations` and `payment_terms_days` attributes for [MSP invoicing](/msp_invoicing) configuration.
* **Custom Providers:** New [`vantage_custom_provider`](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/resources/custom_provider) and [`vantage_custom_provider_costs_upload`](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/resources/custom_provider_costs_upload) resources let you create [Custom Provider](/connecting_custom_providers) integrations and upload Custom Provider CSV costs through Terraform.
## Major Product Updates
* **Vantage ChatGPT app:** Vantage is now available as a [ChatGPT app](/chatgpt_app), giving you a native way to query cloud costs, inspect recommendations and anomalies, and take actions, like creating budgets, dashboards, cost reports, and cost alerts, directly from ChatGPT.
* **Preferred Tags:** Owners can now mark tag keys as [Preferred Tags](/tagging#preferred-tags) from the Tags settings page. Preferred Tags are automatically sorted to the top of filter and group-by dropdowns across Cost Reports, Resource Reports, Recommendations, and Financial Commitment Reports, making it easier for all users in the account to find and use the most important tags.
* **instances.vantage.sh APIs and SDKs:** New dedicated APIs and SDKs for [instances.vantage.sh](https://instances.vantage.sh) provide programmatic access to compute pricing and specifications across AWS, Azure, and GCP.
* **AWS Blended Commitment Discounts:** [Blended Commitment Discounts](/cost_reports#aws-blended-commitment-discounts) are now available for AWS, allowing you to evenly spread commitment-based discounts (Savings Plans and Reserved Instances) across all eligible usage. Vantage calculates an effective savings rate per service and applies it proportionally, creating fair and consistent chargeback across teams and workloads. Contact [support@vantage.sh](mailto:support@vantage.sh) to enable.
* **vantage.sh/models:** Vantage has launched [vantage.sh/models](https://vantage.sh/models), a free and open-source site for comparing LLM prices, specifications, benchmarks, and hosting information in one place. The site includes customizable SQL-powered comparison views, model detail pages with pricing calculators, and data refreshed daily from provider APIs.
* **FOCUS 1.2/1.3 column support:** [Custom Provider](/connecting_custom_providers#finops-focus-schema) CSV uploads now accept additional FOCUS 1.2/1.3 columns—such as `AvailabilityZone`, `CommitmentDiscountId`, `EffectiveCost`, `ListCost`, `Provider`, and `Publisher`—without requiring you to remove them before uploading.
* **FinOps Agent improvements:** The [FinOps Agent](/vantage_finops_agent) now provides more reliable responses by better understanding time periods (e.g., "last March"), recognizing common service names (e.g., "EC2"), and routing product feedback directly through the built-in feedback flow. The Agent has also expanded into a more complete interface for exploring, analyzing, and managing Vantage data—including costs, forecasts, anomalies, recommendations, budgets, dashboards, tags, integrations, and teams. See the [blog post](https://www.vantage.sh/blog/finops-agent-anomaly-investigation) for details.
## Product Updates and Improvements
This month, we made several improvements and updates to enhance the Vantage experience:
* **Provider integrations:**
* **Twilio usage categories:** Updated [Twilio](/connecting_twilio) integration to expand SKU coverage.
* **New GCP tags:** Two new [GCP provider tags](/connecting_gcp#reporting-dimensions) are now available on Cost Reports—`gcp:invoice_month` for filtering and grouping costs by invoice month, and `gcp:sku` for filtering and grouping costs by SKU ID.
* **AWS `aws:physicalProcessor` tag:** A new [`aws:physicalProcessor`](/connecting_aws#reporting-dimensions) tag is now available on AWS Cost Reports, allowing you to filter and group costs by physical processor type.
* **Custom provider setup without CSV:** You can now create a [Custom Provider](/connecting_custom_providers) integration without uploading a CSV file during initial setup, allowing you to configure the provider first and add cost data later via CSV or the API.
* **GCP credit reclassification:** GCP `FEE_UTILIZATION_OFFSET` and `SUBSCRIPTION_BENEFIT` charge types are now classified as credits rather than usage. These values, such as CUD fee utilization offsets and subscription benefits, are now controlled by the credits/discounts toggles in [Cost Report settings](/cost_reports#credits-discounts-refunds-and-taxes) rather than always being included in usage totals.
* **Cost Reports:**
* **Usage Unit export grouping:** The [data export](/cost_reports#export-cost-reports) form now includes a **Usage Unit** grouping option, which adds a column for the unit of measure (e.g., `GB-Mo`, `Hrs`) in CSV exports. This grouping is automatically selected when the report is in [usage view](/usage_based_reporting).
* **Forecast confidence bounds:** The monthly cost view on [Cost Reports](/cost_reports#forecasts-tab) now displays min, median, and max forecast values, giving you a range of expected spend alongside the primary forecast line.
* **Include Current Month toggle:** A new **Include Current Month** toggle is available in the [Cost Report](/cost_reports) datepicker for month- and week-based date ranges. By default, the toggle is on and date ranges include the current partial period, for example, "Last 3 Months" on March 24 shows January 1 through March 24. Turn the toggle off to constrain the range to only complete periods, "Last 3 Months" then shows December 1 through February 28. The toggle label adjusts to **Include Current Week** for week-based intervals and is hidden for day-based ranges.
* **Save as Default:** Users with the [Organization Owner](/rbac#understanding-rbac-roles) role can now save the current chart type, date range, and cost settings as the default view for the **All Resources** Cost Report using the new [**Save as Default**](/cost_reports#save-as-default) option in the split save button. The option is enabled after changing at least one setting from the current default.
* **Filter input enter-key behavior:** Typing a value in [Cost Report filter](/cost_reports#filter-cost-reports) dropdowns and pressing **Enter** now consistently adds the typed value as a filter selection across all filter types, including when the dropdown has no matching results.
* **Dashboards:**
* **Cost change indicators on widgets:** [Dashboard](/dashboards) widgets now display dollar and percentage cost changes compared to the previous period, giving you an at-a-glance view of spending trends directly on the dashboard.
* **Dashboard saved filter RBAC:** [Saved filter](/cost_reports#saved-filters) permissions are now enforced on [dashboards](/dashboards), ensuring that users can only view dashboard widgets scoped to saved filters they have access to.
* **Cost Alerts:**
* **Anomaly alert currency update:** [Cost anomaly alert](/cost_anomaly_alerts) notifications (email, Slack, Microsoft Teams, and Jira) now display amounts using your workspace's configured [currency](/vantage_account#currency-conversion) instead of defaulting to USD.
* **Anomaly access for report viewers:** Users with [viewer](/rbac) access can now open and view [cost anomaly alerts](/cost_anomaly_alerts) associated with the reports they have access to.
* **Cost alert breadcrumbs:** The [Cost Alert](/cost_alerts) create and edit pages now display breadcrumbs for easier navigation.
* **Cost Recommendations:**
* **Multi-payer Savings Plans recommendations:** Fixed an issue where [Database Savings Plans](/cost_recommendations) recommendations were not shown for customers with multiple AWS payer accounts. Recommendations are now correctly generated and displayed per payer.
* **Archived recommendations hidden:** Archived [Cost Recommendations](/cost_recommendations) are no longer shown in the side panel, keeping the recommendations view focused on active items.
* **EBS rightsizing IOPS parameter:** [EBS rightsizing recommendations](/cost_recommendations) now include IOPS as a parameter when suggesting volume type changes, providing more complete information for evaluating storage optimization recommendations.
* **Idle NAT Gateway recommendations:** [Cost Recommendations](/cost_recommendations) now include idle NAT Gateway recommendations from AWS Compute Optimizer, with details on current state, utilization metrics, estimated savings, and CLI remediation commands.
* **Active Resources & Resource Reports:**
* **RDS FreeStorageSpace metric:** [RDS Active Resources](/active_resources#aws-active-resources) now include the **FreeStorageSpace** CloudWatch metric, providing visibility into available storage capacity alongside existing performance metrics.
* **Elastic IP disassociation timestamp:** [AWS Active Resources](/active_resources#aws-active-resources) for Elastic IPs now show the disassociation date, making it easier to identify unused IPs and act on related [Cost Recommendations](/cost_recommendations).
* **S3 request metrics permissions:** The `s3:GetMetricsConfiguration` and `s3:ListBucketMetricsConfigurations` permissions are now included automatically via the `VantageS3RequestMetrics` policy in the default CloudFormation template and StackSet. See [S3 Request Metrics and Egress](/active_resources#s3-request-metrics-and-egress) for details.
* **EC2 Core Count:** [EC2 Active Resources](/active_resources#aws-active-resources) now display the vCPU core count as a metadata field, providing visibility into the compute capacity of each instance.
* **EC2 memory utilization metric:** [EC2 Active Resources](/active_resources#cloudwatch-metrics) now include a `mem_used_percent` CloudWatch metric chart when the CloudWatch Agent is installed, providing memory utilization visibility alongside existing CPU and network metrics.
* **Amazon EMR Active Resources:** [Amazon EMR](/active_resources#aws-active-resources) clusters are now available as Active Resources, including cluster metadata and fleet capacity information.
* **Financial Commitments:**
* **Commitments CSV export:** You can now [export commitment data](/commitments) to CSV with FOCUS 1.3 columns, providing standardized financial commitment reporting.
* **Commitment Cost column:** The [Commitments](/commitments) page now includes a **Commitment Cost** column showing the total cost over the commitment's full term (e.g., hourly rate multiplied by term length).
* **Provider filter:** The [Commitments](/commitments) page now supports filtering by cloud provider, and the filter is also available in the export modal.
* **Azure commitment permissions banner:** The [Commitments](/commitments) page now displays a warning banner when Azure integrations are missing the required Reservations Reader or Savings Plan Reader RBAC scopes, with a link to the [configuration steps](/connecting_azure#optional-azure-reservations-and-savings-plans).
* **Account names with provider icons:** The [Commitments](/commitments) page and [Financial Commitment Report](/financial_commitment_reports) account filters now display human-readable account names with provider icons instead of raw account IDs.
* **Network Flow Reports:**
* **Sampling-aware cost estimates:** [Network Flow Reports](/network_flow_reports#flow-log-sampling) now account for sampling when estimating traffic costs. When sampling is active, the **Flow** and **Cost** columns display scaled estimates with a tooltip showing the maximum sampling rate applied.
* **Account Settings, Audit Logs, & RBAC:**
* **SSO additional domains:** The SSO [Connected page](/sso#associated-domains) now displays all additional domains associated with an Account Identity Provider.
* **Integration Owner permissions:** Users with the [Integration Owner](/rbac#understanding-rbac-roles) role can now manage [Virtual Tags](/tagging), [Custom Providers](/connecting_custom_providers), and [Business Metrics](/business_metrics) from the console.
* **Segment audit logs:** Changes to [Segments](/segments) are now tracked in [Audit Logs](/audit_logs), including creates, updates, and deletes with detailed diffs of filter changes.
* **MSP features:**
* **MSP invoice audit logging:** Changes to MSP invoices (creates, updates, and deletes) are now tracked in [Audit Logs](/audit_logs).
## Kubernetes Agent Updates
*See February's update for the most recent Kubernetes agent release.*
## API Updates
* **Teams:** The [`/teams`](https://docs.vantage.sh/api/teams/create-team) POST and PUT endpoints now support an optional `default_dashboard_token` parameter for setting a Team's default dashboard. Pass `null` to clear the value. The `default_dashboard_token` field is also exposed on the Team entity in GET responses.
* **Users:** New `PUT /users/:token` and `PUT /me` endpoints allow setting a `default_dashboard_token` on a user. The field is also exposed on [User](https://docs.vantage.sh/api/users/get-all-users) and `/me` GET responses.
* **Audit Logs:** The [`/audit_logs`](https://docs.vantage.sh/api/auditlogs/get-all-audit-logs) endpoint now supports filtering by `segment` as an object type.
* **Recommendations resource metadata:** The [`/recommendations/{token}/resources`](https://docs.vantage.sh/api/recommendations/get-all-recommendations) endpoint now returns additional resource metadata.
* **Virtual Tag Config allocation names:** The [`/virtual_tag_configs`](https://docs.vantage.sh/api/virtualtags/get-all-virtual-tag-configs) response now includes optional `display_name` and `percentages_display_name` fields on allocation values.
* **Teams user ordering:** The [`/teams`](https://docs.vantage.sh/api/teams/get-all-teams) endpoint now returns `user_emails` and `user_tokens` in consistent insertion order.
* **Delete workspaces:** A new `DELETE /workspaces/:token` [endpoint](https://docs.vantage.sh/api/workspaces/delete-workspace) is available for deleting workspaces via the API.
* **Tags preferred status:** The [`/tags`](https://docs.vantage.sh/api/tags/get-all-tags) GET response now includes a `preferred` field, and the [`PUT /tags`](https://docs.vantage.sh/api/tags/update-tag) endpoint accepts an optional `preferred` parameter for setting a tag as a [Preferred Tag](/tagging#preferred-tags).
* **Terraform provider:** The [Vantage Terraform provider](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs) has been updated:
* **Team default dashboard:** The `vantage_team` [resource](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/resources/team) and data source now support `default_dashboard_token` for setting a Team's default dashboard.
* **Folder saved filters:** The `vantage_folder` [resource](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/resources/folder) now supports `saved_filter_tokens` for associating saved filters with a folder.
* **Cost report settings:** The `vantage_cost_report` [resource](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/resources/cost_report) now supports a `settings` block (including `include_credits`, `include_refunds`, `include_discounts`, `include_tax`, `amortize`, `unallocated`, `aggregate_by`, and `show_previous_period`) and a `chart_settings` block for managing report display options via Terraform.
## Major Product Updates
* **Elastic Cloud integration:** Vantage now integrates with [Elastic Cloud](/connecting_elastic) to ingest cost and [usage](/usage_based_reporting) data for your Elastic organizations—broken down by service (Elasticsearch, Kibana, APM, and more), category, region, and resource.
* **Vercel integration:** Vantage now integrates with [Vercel](/connecting_vercel) to ingest cost, [usage](/usage_based_reporting), and [commitment](/commitments) data—broken down by service and filterable by project, region, and provider tags.
* **MSP Integration Management:** A new [Partner Integrations](/partners#manage-partner-integrations) page gives MSPs a centralized view of all integrated accounts across providers, with the ability to filter, assign, and remove integrations from Managed Accounts individually or in bulk.
* **AWS Database Savings Plans:** [Autopilot](/autopilot), [Cost Recommendations](/cost_recommendations), and the [FinOps Agent](/vantage_finops_agent) now support AWS Database Savings Plans—recommendations and purchases alongside existing Compute Savings Plans and Reserved Instances (RDS, ElastiCache, Redshift, OpenSearch).
* **Vantage University:** [Vantage University](/vantage_university) now includes a [Hands-On Demo](/vantage_university_demo) and updated role-based tracks (FinOps Analyst, Developer, Finance Manager) with videos and hands-on practice.
* **Virtual Tag time frames:** [Virtual Tags](/tagging#virtual-tag-time-frames) now support optional start and end dates on any value, so you can control when a rule applies as cost ownership changes over time. See the [time-bound Virtual Tag example](/tagging_examples#time-bound-virtual-tag-example) for a walkthrough.
* **LLM Token Allocation (Private Preview):** Vantage now supports [LLM Token Allocation](https://www.vantage.sh/blog/llm-token-allocation-preview), allowing you to enrich model provider costs from OpenAI and AWS Bedrock with metadata like team, user, or application. Connect token observability data via Amazon CloudWatch, Datadog, or CSV upload, and Vantage automatically joins it to cost data—making enriched dimensions available in Cost Reports, Virtual Tags, Segments, and Alerts. Contact your account team to request access.
## Product Updates and Improvements
This month, we made a number of improvements and updates to enhance the Vantage experience:
* **Provider integrations:**
* **Anyscale account names:** When grouping by **Account** on [Anyscale](/connecting_anyscale#anyscale-reporting-dimensions) Cost Reports, projects now display human-readable names instead of IDs.
* **AWS CUR tags:** Eight new [AWS system tags](/connecting_aws#reporting-dimensions) are available for filtering and grouping on Cost Reports: `aws:Operation`, `aws:UsageType`, `aws:LineItemDescription`, `aws:instanceType`, `aws:operatingSystem`, `aws:licenseModel`, `aws:databaseEngine`, and `aws:deploymentOption`.
* **Datadog organization name tag:** A new [`datadog:organization:name`](/connecting_datadog#datadog-reporting-dimensions) tag is available on Datadog Cost Reports, allowing you to filter and group multi-org costs by organization name.
* **Datadog cost allocation by tags:** Vantage now tries several [usage keys and patterns](/connecting_datadog#usage-based-cost-allocation) when allocating Datadog cost to tags, so more cost is attributed to named tags (e.g., `team`) and less is left as untagged—without changing your total Datadog spend.
* **GCP project name tag:** A new [`gcp:project_name`](/connecting_gcp#reporting-dimensions) tag is available on GCP Cost Reports, allowing you to filter and group costs by human-readable project name.
* **Azure CSP Account filter:** [Azure CSP](/connecting_azure_csp#azure-csp-reporting-dimensions) Cost Reports now support filtering by **Account** (Subscription/Entitlement ID).
* **Datadog auth error handling:** The Datadog [integration settings](/connecting_datadog) page now displays clearer error messages when an OAuth connection is disconnected or encounters authentication issues, making it easier to diagnose and reconnect.
* **Cost Reports:**
* **Wildcard category and subcategory filters:** When [filtering Cost Reports](/cost_reports#filter-cost-reports) by **Category** or **Subcategory**, you can now select **All Categories** or **All Subcategories** to filter across all services for a provider. In [VQL](/vql_cost_report#costs-by-specific-category), use `costs.service = '*'` as the service value.
* **Tagged drilldown:** [Drilldown](/cost_reports#drill-down-in-costs-table) is now supported when a Cost Report is grouped by **Tagged**, allowing you to click into tagged rows to view only costs that have tags applied.
* **Dashboards:**
* **Duplicate widgets:** You can now [duplicate a widget](/dashboards#duplicate-widgets) on a dashboard to create a copy with the same report and display settings, making it easy to show the same report with different configurations (e.g., chart and table) side by side.
* **Cost Alerts:**
* **Minimum dollar threshold:** Percentage-based [Cost Alerts](/cost_alerts#create-a-cost-alert) now support an optional minimum dollar threshold, so alerts are only sent when both the percentage and a minimum dollar amount are exceeded.
* **Currency support in alert emails:** [Cost Alert](/cost_alerts) email notifications now display amounts using your workspace's configured [currency](/vantage_account#currency-conversion), including the correct currency symbol and formatting.
* **Cost Recommendations:**
* **Minimum savings filter:** The [Cost Recommendations](/cost_recommendations) page now includes a minimum monthly savings filter, allowing you to focus on recommendations that meet a specific savings threshold. The filter is persisted as part of saved recommendation views.
* **Database Savings Plan slideouts:** The [recommendation details slideout](/cost_recommendations#view-recommendation-categories) now supports Database Savings Plans, showing commitment details (hourly commitment, term length, payment type, savings percentage) and selectable coverage levels.
* **Zero-usage container rightsizing:** [Kubernetes rightsizing recommendations](/cost_recommendations#kubernetes-rightsizing-recommendations) now display improved copy for containers with zero observed CPU or memory usage, making it clearer when a container has had no measurable utilization during the analysis period.
* **OpenSearch Engine column fix:** Fixed an issue where the **Engine** column was not displayed in [OpenSearch recommendations](/cost_recommendations), so you can now see the engine type when evaluating rightsizing recommendations for OpenSearch domains.
* **Financial Commitments:**
* **Commitment ARN grouping:** [Financial Commitment Reports](/financial_commitment_reports) now support grouping by **Commitment ARN**, so you can break down costs by individual Savings Plan or Reserved Instance.
* **Commitment filters and sort order:** The [Commitments](/commitments#filter-commitments) screen now supports filtering by commitment type, service, account, term, payment type, and region—in addition to the existing status filter. The page also defaults to sorting by **Status** with active commitments first.
* **Network Flow Reports:**
* **Human-readable names:** [Network Flow Reports](/network_flow_reports) now display human-readable resource names instead of raw ARNs, matching the behavior already available on Cost Reports.
* **Exact value filter matching:** [Network Flow Report](/network_flow_reports) filter dropdowns now support searching by exact value, so you can filter by a specific identifier even when it doesn't appear in the default dropdown options.
* **FinOps Agent & AI:**
* **New Vantage MCP tools:** Several new tools have been added to the Vantage MCP, including folder management (`create-folder`, `list-folders`, `update-folder`, `delete-folder`), cost alerts (`create-cost-alert`, `get-cost-alert`, `list-cost-alerts`), and cost report management (`delete-cost-report`). See the [Vantage MCP Tools](/vantage_mcp#vantage-mcp-tools) section for details.
* **FinOps Agent anomaly investigation:** The FinOps Agent can now [investigate Cost Anomaly Alerts](/vantage_finops_agent#investigate-cost-anomalies) directly in Slack. When anomaly alerts are sent, an **Investigate Anomaly** button is included. Click it to have the Agent analyze the spike, query daily cost trends, identify attributed resources, and present a structured summary in the thread.
* **FinOps Agent Slack channel update:** You can now update the connected Slack channel directly from the [FinOps Agent settings page](/vantage_finops_agent#update-slack-settings) without needing to re-onboard. The page also displays a prompt when the Slack integration needs re-authorization.
* **Account Settings, Audit Logs, & RBAC:**
* **Currency symbols and copy:** Currency symbols and formatting across the Vantage console now consistently reflect your workspace's configured [currency](/vantage_account#currency-conversion), including input fields, summary widgets, and report displays.
* **People page Organization Role column:** The [People](/rbac#manage-account-access) page (**Settings > People**) now displays an **Organization Role** column, making it easier to see each user's [organization-level role](/rbac#understanding-rbac-roles) at a glance without navigating to individual user profiles.
* **MSP features:**
* **MSP invoicing improvements:** MSP invoices now include a searchable account filter. In addition, you can [add configurable payment terms](/msp_invoicing#step-2-add-managed-account-billing-information) (e.g., Net 30, Net 60) on Managed Accounts.
* **Invoice billing month selector:** The [MSP invoicing](/msp_invoicing) page now uses a monthly billing period selector instead of a free-form date range picker, defaulting to the most recent month with invoices.
* **Delegation audit logging:** [Audit Logs](/audit_logs) now track when a Management Account delegates or undelegates provider integrations to Managed Accounts.
## Kubernetes Agent Updates
* **Neocloud Kubernetes GPU support:** The [Vantage Kubernetes agent](/kubernetes_agent#enable-neocloud-gpu-support) supports GPU cost monitoring for neocloud providers (e.g., DigitalOcean, CoreWeave, Nebius) using the same annotation-based approach as on-prem. Requires **Agent 1.2.0** (Helm **v1.4.0**) or higher. See [Enable Neocloud GPU Support](/kubernetes_agent#enable-neocloud-gpu-support).
## API Updates
* **Recommendations:** New [Recommendation Views](https://docs.vantage.sh/api/recommendationviews/get-all-recommendation-views) endpoints (GET list, GET by token, POST, PUT, DELETE) for managing saved filter presets. The [`/recommendations`](https://docs.vantage.sh/api/recommendations/get-all-recommendations) endpoint now paginates when filter params are used, supports a `category` query param, and the [`/recommendations/{token}/resources`](https://docs.vantage.sh/api/recommendations/get-all-recommendations) endpoint now returns detailed resource data including identifiers, current configuration, and recommended actions.
* **Virtual tag configs:** New [`GET /virtual_tag_configs/{token}/status`](https://docs.vantage.sh/api/virtualtags/get-virtual-tag-config-processing-status) returns processing status by provider (queued, processing, complete, failed). Async update via `PUT .../async` and status check via `GET /virtual_tag_configs/async/{request_id}`; long-running updates may return 202 with `Retry-After`. Destroy now respects the auto-updating-disabled setting.
* **Cost Reports:** The [`/cost_reports`](https://docs.vantage.sh/api/costs/get-all-cost-reports) endpoint now preserves the order of `saved_filter_tokens` as specified during creation and updates.
* **Cost Alerts:** [Create](https://docs.vantage.sh/api/costalerts/create-cost-alert) and [update](https://docs.vantage.sh/api/costalerts/update-cost-alert) support optional `minimum_threshold` (dollar amount) for percentage-based alerts.
* **Data exports:** [Data export](https://docs.vantage.sh/api/dataexports/get-status-of-data-export) creation and update endpoints now validate the VQL `filter` parameter, returning descriptive error messages for invalid filter syntax and auto-correcting common formatting issues.
* **Integrations:** The [`/integrations`](https://docs.vantage.sh/api/integrations/get-all-integrations) endpoint now includes a `managed_accounts` field listing the [Managed Accounts](/partners) each integration is delegated to, making it easier to audit integration sharing across an MSP portal.
* **Managed Accounts:** [`/managed_accounts`](https://docs.vantage.sh/api/managedaccounts/create-managed-account) POST and PUT now support an optional `email_domain` parameter for associating an SSO email domain with a managed account.
* **Improved error codes:** API endpoints now return more specific HTTP status codes (404 for not found, 422 for validation errors) instead of generic 500 errors, making it easier to diagnose and handle errors programmatically.
* **Fixes:** The [`/tags/{tag_key}/values`](https://docs.vantage.sh/api/tags/get-tag-values) response now includes the `links` object for pagination; the [`/resources`](https://docs.vantage.sh/api/resources/get-resources) endpoint correctly applies `page` and `limit` query params.
* **API client libraries:** Official [TypeScript](https://github.com/vantage-sh/vantage-ts) and [Python](https://github.com/vantage-sh/vantage-python) client libraries for the Vantage API are now available.
* **Terraform provider:** The [Vantage Terraform provider](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs) has been updated:
* **Cost report chart settings:** The `vantage_cost_report` resource now supports `chart_settings` (e.g., `x_axis_dimension`, `y_axis_dimension`) for configuring how Cost Report charts display data.
* **Recommendation views:** New `vantage_recommendation_view` resource and `vantage_recommendation_views` data source for managing recommendation filter presets (title, workspace, provider/account/region/tag/date filters).
* **OpenAPI timeout:** The provider’s OpenAPI client timeout now matches the configured `timeout` (or `VANTAGE_TIMEOUT`), so long-running operations respect the same limit.
* **Managed account:** Fixed an issue where managed accounts with no `custom_fields` could cause unnecessary plan changes on subsequent applies.
* **Virtual tag config time bounds:** The `vantage_virtual_tag_config` resource now supports `start_date` and `end_date` parameters on tag values, allowing you to configure [Virtual Tag time frames](/tagging#virtual-tag-time-frames) via Terraform.
* **Dashboard date default fix:** Fixed an issue where the `vantage_dashboard` resource could produce plan drift on the `date_interval` field when using default values.
* **Budget hierarchical fix:** Fixed an issue where the `vantage_budget` resource did not correctly handle hierarchical child budget configurations.
## Major Product Updates
* **Tag key collapsing:** [Tag key collapsing](/tagging#tag-key-collapsing) is now available for virtual tags, allowing you to consolidate semantically redundant tag keys (e.g., `env`, `environment`, `Environment`) into a single standardized virtual tag. See the [Tag Key Collapsing Examples](/tagging_examples#tag-key-collapsing-examples) section for step-by-step guidance.
* **Percent-based cost allocation tagging:** [Percent-based allocation tags](/tagging#percent-based-allocation-tags) are now available for virtual tags, allowing you to allocate costs using fixed percentages for predefined chargeback models, manual cost-splitting, and fixed allocation agreements.
* **Cursor integration:** Vantage now integrates with [Cursor](/connecting_cursor) as its latest cost provider.
* **Dynamic forecasting general availability:** [Dynamic forecasting](/forecasting#dynamic-forecast) is now generally available to all Enterprise customers. Previously available in private preview, dynamic forecasting lets customers align their cloud cost forecasts with business growth projections by uploading future projections of business metrics that influence their underlying costs.
## Product Updates and Improvements
This month, we made a number of improvements and updates to enhance the Vantage experience:
* **Provider integrations:**
* **Azure invoice section provider tags:** Azure costs now include `azure:InvoiceSectionId` and `azure:InvoiceSectionName` as provider tags when present in the source data, allowing you to filter and group costs by invoice section in [Cost Reports](/cost_reports#filter-cost-reports) and [Virtual Tags](/tagging#virtual-tags). This is available for both standard Azure integrations and [Azure CSP](/connecting_azure_csp) integrations. See the [Azure Reporting Dimensions](/connecting_azure#azure-reporting-dimensions) and [Azure CSP Reporting Dimensions](/connecting_azure_csp#azure-csp-reporting-dimensions) sections for details.
* **AWS provider tags:** AWS costs now include two new provider tags: `aws:invoiceId` (when invoice ID is present in the source data) and `aws:instanceTypeFamily` (when instance type family is present, e.g., m5, c5, r5). These tags allow you to filter and group costs in [Cost Reports](/cost_reports#filter-cost-reports) and [Virtual Tags](/tagging#virtual-tags). The instance type family tag also enables instance family group-by options in Financial Cost Reports (FCRs). See the [AWS Reporting Dimensions](/connecting_aws#reporting-dimensions) section for details.
* **AWS CUR 2.0 format support:** Vantage now supports AWS CUR 2.0 format in addition to the legacy CUR format. See the [CUR Format](/connecting_aws#cur-format) section for details.
* **Cost Reports:**
* **Cost Report drilldown in By Date view:** The drilldown functionality is now available in the **By Date** view of [Cost Reports](/cost_reports#update-the-costs-table), allowing you to drill down into costs by category, resource, or other grouping dimensions when viewing costs broken down by date. This provides the same exploration capabilities in the By Date view as in the Cumulative view. See the [Drill Down in Costs Table](/cost_reports#drill-down-in-costs-table) section for details.
* **Filters dropdown empty state:** The filters dropdown now displays a helpful message when no filter sets are available, improving clarity when working with [Cost Report filters](/cost_reports#filter-cost-reports).
* **Dashboards:**
* **Dashboard export date range fix:** Dashboard PDF exports now use the date range currently displayed on screen (from the date picker) rather than the dashboard's saved date range. This ensures that exported dashboards match what you're currently viewing, making it easier to export dashboards with custom date ranges without needing to save the filters first. See the [Dashboard export documentation](/dashboards#export-dashboards) for details.
* **Cost Alerts:**
* **Cost Alert notification date fields:** Cost Alert notifications (email, Slack, Microsoft Teams, and Jira) now display two date fields: **Occurred On** (the date when the cost change actually occurred) and **Detected On** (when Vantage detected and created the alert event). See the [Cost Alerts documentation](/cost_alerts#view-external-alert-notifications) for details on these date fields.
* **Cost Recommendations:**
* **Currency conversion support:** The [Cost Recommendations](/cost_recommendations) screen now supports currency conversion, allowing you to view potential savings and other cost amounts in your workspace's configured currency. See the [Currency Conversion](/vantage_account#currency-conversion) documentation for details.
* **Archive Autopilot recommendations:** You can now archive individual [Autopilot recommendations](/autopilot) (Savings Plans, Reserved Instances for RDS, ElastiCache, Redshift, and OpenSearch) or bulk archive multiple recommendations at once. Archived Autopilot recommendations are moved to the **Archived** tab and excluded from savings potential calculations, making it easier to manage which recommendations you want to track. See the [Archive Recommendations](/cost_recommendations#archive-recommendations) section for details.
* **EKS extended support recommendations:** EKS upgrade recommendations now only suggest versions that have at least 90 days of standard support remaining, preventing recommendations for versions that are about to enter extended support. Additionally, EKS versions are now displayed in descending order (newest first) in the Extended Support tab for easier navigation. See the [EKS Extended Support documentation](/active_resources#eks-extended-support) for details.
* **Kubernetes rightsizing chart fix:** A fix was made to ensure CPU and RAM usage lines are properly displayed in [Kubernetes rightsizing charts](/cost_recommendations#kubernetes-rightsizing-recommendations) for single-point data and today's data. Single-point datasets now display visible point markers, and data points at the end date are correctly included in the chart's x-axis range, providing complete visibility into resource usage patterns.
* **Business Metrics & Unit Costs:**
* **Business metrics table pagination:** The [Business Metrics](/business_metrics#import-business-metrics) table now supports pagination and sorting, improving performance when viewing business metrics with large datasets. You can sort by date, label, and amount columns for easier navigation.
* **Virtual Tags & Tagging:**
* **Improved icons for allocated and collapsed tags:** The [Tags settings page](/tagging#tag-management-provider-and-virtual-tags) now displays improved visual indicators for virtual tags. Tags with cost allocations display an "Allocated" badge, and tags with collapsed tag keys display a "Collapsed" badge. These badges appear next to the tag name, making it easier to identify tags with these properties at a glance.
* **FinOps Agent & AI:**
* **FinOps Agent onboarding channel guidance:** When no Slack channels are available during [FinOps Agent onboarding](/vantage_finops_agent#enable-the-finops-agent), Vantage now displays a helpful message indicating that the @Vantage app must be invited to a Slack channel before it will appear in the channel selection list. This provides clearer guidance during the onboarding process.
* **New Vantage MCP tools:** Two new tools have been added to the [Vantage MCP](/vantage_mcp): `create-dashboard` for creating Dashboards with widgets and `create-virtual-tag-config` for creating Virtual Tag Configs. See the [Vantage MCP Tools](/vantage_mcp#vantage-mcp-tools) section for details.
* **Account Settings, Audit Logs, & RBAC:**
* **Audit Log saved filter tracking fix:** A fix was made to ensure that [saved filters](/saved_filters) are properly tracked in [Audit Logs](/audit_logs) when a Cost Report is deleted. Previously, saved filters associated with a deleted report were not included in the audit log entry, but they are now correctly captured to provide complete visibility into report deletion events.
* **Enter Workspace button on workspace settings:** An **Enter Workspace** button has been added to the top right of the [workspace settings page](/workspaces#manage-workspaces), making it easier to switch between workspaces.
* **Workspace integration redirect improvement:** When accessing a workspace with no integrations assigned, but integrations exist at the account level, Vantage now redirects to the [integration settings page](/vantage_account#configure-integrations) with a helpful notice message. This provides clearer guidance when managing integrations across multiple [workspaces](/workspaces#manage-workspace-provider-integrations).
* **MSP features:**
* **MSP invoicing account name links:** Account names in the [MSP invoicing](/msp_invoicing) invoices table are now clickable links that navigate directly to the managed account profile page, making it easier to access account details when reviewing invoices.
* **MSP invoice Error status filter:** The invoice status filter dropdown now includes an **Error** status option, allowing you to filter invoices that encountered errors during generation. See the [MSP Invoicing documentation](/msp_invoicing#step-3-generate-an-invoice) for details on invoice statuses.
* **MSP Billing Rules:** The following improvements were made to [MSP billing rules](/partners#billing-rules):
* **Adjustment billing rule percentage limit removed:** The 100% maximum limit on adjustment billing rule percentages has been removed for [per-service adjustments](/partners#billing-rules). MSPs can now enter percentage values greater than 100% when creating adjustment billing rules, enabling markups and premium pricing scenarios where costs are shown to customers at rates above the original cost.
* **Billing rule form service name mapping fix:** A fix was made to ensure AWS service names are correctly mapped and displayed in the [billing rule form](/sql_billing_rules), improving accuracy when creating custom billing rules.
* **SQL billing rule `INSERT` column validation:** Columns specified in `INSERT INTO` statements are now validated against the allowed column list when creating [custom SQL billing rules](/sql_billing_rules). This ensures that only permitted columns can be used in `INSERT` statements.
## Kubernetes Agent Updates
*See December's update for the most recent Kubernetes agent release.*
## API Updates
* **New API documentation site:** A new dedicated [API documentation site](/api) is now available, providing a comprehensive and interactive reference for the Vantage API.
* **Audit Logs API enhancements:** The [`/audit_logs`](https://docs.vantage.sh/api/auditlogs/get-all-audit-logs) endpoint has been enhanced with the following updates:
* **New object type filter:** You can now filter audit logs by `recommendation_commitment` object type to view audit logs for Autopilot commitment recommendations.
* **FinOps Agent source filter:** The `source` parameter now supports `finops_agent` as a filter option, allowing you to filter audit logs by actions taken by the FinOps Agent. The endpoint continues to support filtering by `console` and `api` sources.
* **Business Metrics API forecasted values support:** The [`/business_metrics`](https://docs.vantage.sh/api/businessmetrics/get-all-business-metrics) endpoint now supports `forecasted_values` in POST and PUT requests, allowing you to create and update forecasted business metric values via the API. A new [`GET /business_metrics/{business_metric_token}/forecasted_values`](https://docs.vantage.sh/api/businessmetrics/get-business-metric-forecasted-values) endpoint has been added to retrieve forecasted values for a business metric. This enables programmatic management of [forecasted metrics](/business_metrics#forecasted-metrics) used for Dynamic Forecasting.
* **Recommendations API enhancements:** The [`/recommendations`](https://docs.vantage.sh/api/recommendations/get-all-recommendations) endpoint now includes `currency_code` and `currency_symbol` fields in recommendation responses, providing the currency information for the workspace associated with each recommendation.
* **Virtual tags endpoint:** The `/virtual_tag_configs` [endpoint](https://docs.vantage.sh/api/virtualtags/create-virtual-tag-config) now supports creating percentage-based virtual tag values. You can use the `values.percentages` parameter when creating or updating virtual tag config values, where each percentage entry includes a `value` and `pct` field.
* **Terraform provider updates:** The following updates are available in the [Vantage Terraform provider](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs):
* **HTTP client timeout configuration:** The provider now supports configurable timeout for HTTP client requests. You can set the timeout by configuring the `timeout` attribute in the provider block (e.g., `timeout = "60s"`) or by setting the `VANTAGE_TIMEOUT` environment variable in the shell environment where Terraform is executed (e.g., `export VANTAGE_TIMEOUT=60s` before running `terraform plan` or `terraform apply`). The timeout defaults to 30 seconds if not specified. This is particularly useful for operations that may take longer, such as virtual tag configuration operations.
* **Business metric forecasted values support:** The `vantage_business_metric` [resource](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/resources/business_metric) now supports `forecasted_values`, allowing you to manage forecasted business metric values via Terraform for use with [Dynamic Forecasting](/forecasting#dynamic-forecast). This aligns with the API support for forecasted values added this month.
## Major Product Updates
* **Azure CSP integration:** Vantage now integrates with [Azure Cloud Solution Provider (CSP)](/connecting_azure_csp) for Managed Service Providers (MSPs) using the Microsoft CSP Partner Program. This integration allows MSPs to ingest and visualize their customers' Azure costs inclusive of CSP-specific discounts and SKUs, such as Partner Earned Credits and New Commerce Experience (NCE) Licenses, directly in Vantage. Costs can be delegated to Vantage Managed Accounts for customer consumption.
* **Dynamic forecasting:** Available to Enterprise customers, dynamic forecasting lets customers align their cloud cost forecasts with business growth projections. Customers can upload future projections of [Business Metrics](https://docs.vantage.sh/business_metrics) that influence their underlying costs, such as subscribers or application requests, and Vantage will incorporate these projections into forward-looking cost models.
* **Vantage MCP updates:** The [Vantage MCP](/vantage_mcp) has been enhanced with the following updates:
* **Open source:** The Vantage MCP is now fully open source. Vantage's Local and Remote MCP Servers have been unified into a single, open-source codebase available on [GitHub](https://github.com/vantage-sh/vantage-mcp-server). Customers can now review and extend the server, run it in their own environments, and contribute to the codebase. The same functionality is available whether you choose to connect remotely (Vantage-managed) or host locally (self-hosted), giving you the flexibility to choose the deployment mode that best fits your needs.
* **New `list-audit-logs` tool:** A new `list-audit-logs` tool has been added to the Vantage MCP, allowing you to list audit logs for actions taken within the Vantage workspace. See the [Vantage MCP Tools](/vantage_mcp#vantage-mcp-tools) section for details.
* **Cost Recommendations updates:** The [Cost Recommendations](/cost_recommendations) page has been enhanced with several new features:
* **Recommendations summary widgets:** Summary widgets at the top of the page display key metrics including Potential Savings, Savings Rate, and Savings Realized. See the [Recommendations Summary Widgets](/cost_recommendations#recommendations-summary-widgets) section for details.
* **Daily recommendation count chart:** A new bar chart displays the number of recommendations detected each day over the selected time period, with interactive filtering capabilities. Click any bar to filter recommendations by that date or date range. See the [Daily Recommendation Count Chart](/cost_recommendations#daily-recommendation-count-chart) section for details.
* **Recommendation tabs:** Recommendations are now organized into tabs (Ready for Review, In Progress, Completed, and Archived) to help you track the status of recommendations. See the [Recommendation Tabs](/cost_recommendations#recommendation-tabs) section for details.
* **Recommendation Action column:** The **Recommendation Action** column is now displayed in Resource Reports when viewing recommendations, showing the specific action recommended for each resource. See the [View Recommendation Categories](/cost_recommendations#view-recommendation-categories) section for details.
* **FinOps Agent updates:** Additional updates to the [Vantage FinOps Agent](/vantage_finops_agent) were released including:
* Updates to improve text and response format rendering in Slack, including improved date parsing so the agent correctly identifies the current month and date context.
* Onboarding flow improvements: The onboarding wizard now automatically skips the provider permissions step if AWS access credentials are already configured. You can also navigate between onboarding steps using the stepper navigation, and the stepper is now visible on the completion page for better progress tracking.
* **MSP invoicing updates:** The following improvements were made to [MSP invoicing](/msp_invoicing) (private preview):
* Invoices now display the actual custom provider names (from [Custom Provider](/connecting_custom_providers) access credentials) instead of technical identifiers.
* CSV exports now include a currency code field, making it easier to identify the currency used for each invoice when importing into accounting systems.
## Product Updates and Improvements
This month, we made a number of improvements and updates to enhance the Vantage experience:
* **Provider integrations:**
* **Custom Provider name and description editing:** You can now edit the name and description of [Custom Providers](/connecting_custom_providers#edit-custom-provider-name-and-description) after creation, making it easier to update provider information as your needs change.
* **Datadog tag attribution for container services:** Tag attribution is now enabled for Datadog Container Services, allowing you to filter and group costs by [Datadog usage attribution tags](/connecting_datadog#datadog-cost-tags-usage-attribution-tags) for container services.
* **Grafana Stack filter:** You can now filter [Grafana Cloud](/connecting_grafana) costs by Stack (AccountId) in [virtual tags](/tagging#virtual-tags) and [Cost Reports](/cost_reports), providing better visibility into costs across different Grafana stacks and custom tag allocations.
* **Custom Provider CSV encoding fix:** A fix was made to normalize character encoding for [Custom Provider](/connecting_custom_providers) CSV uploads. CSV files with non-UTF-8 encoding or invalid characters are now automatically normalized to UTF-8, ensuring proper processing of special characters and international characters.
* **GCP project names in Cost Reports:** When grouping by **Account** in [Cost Reports](/cost_reports), GCP projects now display their friendly project names (e.g., "production-project") instead of project IDs, making it easier to identify and analyze costs by project.
* **Cost Reports:**
* **Cost Report drilldown improvements:** The drilldown experience on [Cost Reports](/cost_reports#drill-down-in-costs-table) has been enhanced with a more intuitive and reliable implementation. Drilldown now automatically suggests the next grouping in Vantage's standard sequence and adds appropriate filters based on the selected row. You can also use the drilldown menu to choose a specific grouping to drill into, giving you more control over how you explore your costs.
* **Report notification previous period fix:** A fix was made to ensure that when the previous period comparison is disabled on a [Cost Report](/cost_reports#create-a-cost-report), report notifications no longer display an empty previous period total. The previous period total is now only shown in notifications when the previous period comparison is enabled on the report.
* **Previous period data alignment fix:** A fix was made to ensure that previous period data is correctly aligned on [Cost Reports](/cost_reports#create-a-cost-report) when using monthly or quarterly date binning, preventing misalignment of previous period comparison data points on the chart.
* **Cost Report usage display fix:** A fix was made to ensure [Cost Reports](/cost_reports) correctly identify and display usage-based units when configured to show usage instead of cost.
* **Cost Alerts:**
* **Cost Alert form validation:** Validation input messages were added to the [Cost Alert](/cost_alerts) creation form to provide clearer feedback when required fields are missing or invalid. Form data is now preserved when validation errors occur, so you don't need to re-enter your information.
* **Cost Alert date bucketing fix:** A fix was made to ensure [Cost Alerts](/cost_alerts) use complete date buckets when comparing costs between periods (day-over-day, week-over-week, month-over-month, quarter-over-quarter). The start date for lookback periods is now aligned to the beginning of the interval (e.g., Sunday for weekly intervals), ensuring accurate comparisons and preventing misleading alerts from partial-period comparisons.
* **Active Resources & Resource Reports:**
* **EBS volume ID:** Volume ID is now available as a field in EBS [Active Resource](/active_resources) pages and can be used as a column in Resource Reports (e.g., vol-0a1b2c3d4e5f6g7h8).
* **EBS volume virtual tags display fix:** A fix was made to ensure that [virtual tags](/tagging#virtual-tags) are properly displayed in the **Assigned Tags** section when viewing EBS volumes on [Active Resource](/active_resources) pages.
* **Business Metrics & Unit Costs:**
* **Business Metric Average display fix:** The [Business Metric Average](/business_metrics) displayed above Cost Reports now shows precise values for very small amounts (less than \$0.001) instead of rounding them to \$0.00. This provides more accurate visibility into unit costs when business metric averages are close to zero but not exactly zero.
* **Virtual Tags & Tagging:**
* **Tags sort order fix:** A fix was made to ensure the "Created at" column on the [Tags](/tagging) settings page correctly sorts tags by creation date in chronological order.
* **Account Settings, Audit Logs, & RBAC:**
* **Audit Log updates:** [Audit Logs](/audit_logs) now support service tokens (Team tokens). When actions are performed using a service token, the audit log displays **Team** and **Team Role** fields instead of **User** and **User Role**, and the **Source** field shows **API** to indicate the action was performed via the API. The team name is displayed in both the **Team** and **Team Role** fields. FinOps Agent actions are now visually distinguished in the audit log table with a different object icon, making it easier to identify agent actions at a glance.
* **Integration importing status:** The [Integrations](/vantage_account#configure-integrations) settings page now displays an "Importing" status indicator when an integration is actively importing data for the first time and hasn't been assigned to any workspaces yet. This provides better visibility into the integration setup process.
* **Provider summary widget updates:** Provider summary widgets on the Overview page now automatically update to reflect newly added or removed providers, ensuring the widget always displays the current list of providers and their costs.
* **Currency conversion:** Currency conversion now displays on [budget alert](/budgets#budget-alerts) notifications, and the amount is displayed in their account's configured currency.
* **System performance and other updates:**
* **Load time improvements:** A fix was made to improve load times on Cost Alert and Budget Alert pages. In addition, filtering by labels on [Kubernetes Efficiency Reports](/kubernetes#create-efficiency-reports) now loads faster.
* **Pagination text update:** Updated pagination text in data tables for a cleaner, more concise display format.
## Kubernetes Agent Updates
*See November's update for the most recent Kubernetes agent release.*
## API Updates
* **Terraform updates:** The `vantage_business_metric` [resource](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/resources/business_metric) now preserves the order of cost report tokens and properly handles empty label filters to prevent configuration drift when Terraform plans are applied.
* **`/costs` endpoint:** The `/costs` [endpoint](/api) now returns raw numeric values for `total_cost` and `total_usage` amounts instead of rounding to 2 decimal places, providing more precise cost and usage data in API responses.
## Product Updates
* **Vantage FinOps Agent:** The [Vantage FinOps Agent](/vantage_finops_agent) is now available as a Slack-integrated AI assistant that provides cost optimization capabilities for your cloud infrastructure.
* The Agent can answer questions about Vantage features and your cloud spend (via the [Vantage Docs MCP](/docs_mcp) and [Vantage MCP](/vantage_mcp)), and can automatically identify and remediate cost optimization opportunities with optional approval workflows.
* A new [onboarding page](https://console.vantage.sh/settings/finops_agent) is available and allows you to control agent settings.
* All actions are logged to the [Vantage Audit Log](/audit_logs) for full transparency.
* **Dashboard notifications:** You can now subscribe to email notifications for [dashboard exports](/report_notifications#set-up-dashboard-notifications). When exporting a dashboard as a PDF, you can choose to receive an email notification when the export is ready to download.
* **Databricks MCP Marketplace listing:** The [Vantage MCP](/vantage_mcp) is now available in the [Databricks Marketplace](https://www.vantage.sh/blog/databricks-mcp), allowing you to easily deploy the MCP within your Databricks environment to query Vantage cost data.
* **Saved filter audit logging:** Editing a [saved filter](/saved_filters) now creates an [audit log](/audit_logs) event for all Cost Reports that the saved filter is applied to, providing visibility into when saved filter changes affect multiple reports.
* **Cost Report export simplification:** The Basic and Advanced export views have been combined into a single export interface. You can now customize groupings, date range, and other export settings directly in the [export modal](/cost_reports#export-cost-reports).
* **Budget alert duplicate validation removed:** You can now create multiple [budget alerts](/budgets#budget-alerts) with the same threshold and duration but different recipients. This allows you to route the same alert to different destinations (e.g., email to one team member and Slack to a channel) without creating duplicate alert configurations.
* **MSP invoicing taxes and additional charges:** You can now add taxes and additional charges to [billing profiles](/partners) for MSP invoicing (private preview). These charges are calculated at invoice creation time based on the subtotal cost after credits, discounts, and billing rules, and appear after the subtotal on invoices.
* **Business metrics API upload button:** A new **Upload via API** button has been added to the [Import Business Metrics](/business_metrics#import-business-metrics) section, providing a direct link to the API documentation for programmatically uploading business metrics.
* **Unit cost average calculation fix:** A fix was made to the [unit cost](/business_metrics) average calculation to ensure accurate and consistent results across different date bucket sizes (day, week, month). The calculation now bins business metrics according to the selected date bucket and uses the ratio of total costs to total binned metrics (rather than averaging per-bin ratios), ensuring the average remains consistent regardless of the selected date bucket size.
* **Cost Recommendations redesign:** The [Cost Recommendations](/cost_recommendations) page has been redesigned with a new interface that organizes recommendations by category in an expandable list format. The page now includes additional tabs, enhanced filtering options (Date Range, Account, Billing Account, Region, Provider, and Tag), and summary information displaying total potential savings and savings rate. You can now archive entire recommendation sets or individual resource recommendations.
* **Virtual tag limit warning:** A warning is now displayed when you approach the virtual tag limit to help you manage your virtual tag usage before reaching the limit.
## Kubernetes Agent Updates
Added a configurable setting for [`PodDisruptionBudget`](https://kubernetes.io/docs/tasks/run-application/configure-pdb/) in the Kubernetes agent [Helm chart](https://github.com/vantage-sh/helm-charts) to define how many agent pods can be disrupted. Uses `maxUnavailable` to set the number of pods that may be voluntarily taken down, or `minAvailable` to ensure a minimum number of pods always remain running.
## API Updates
* **`/billing_profiles` endpoint:** The `/billing_profiles` [endpoint](/api) now supports invoice adjustments for MSP invoicing. You can include an `invoice_adjustment_attributes` object when creating or updating billing profiles to configure taxes, fees, and other adjustments. Adjustment items support the following fields: `name` (name of the adjustment), `adjustment_type` (`charge`, `credit`, or `discount`), `calculation_type` (`fixed` or `percentage`), and `amount` (amount or percentage value). Invoice adjustment data is now included in billing profile responses.
* **`/integrations` endpoint:** The `/integrations` [endpoint](/api) now returns more granular integration status values. The `status` field can now be one of: `connected`, `error`, `pending`, `importing`, `imported`, or `disconnected` (previously only `connected` or `disconnected`). A new `last_updated` field has been added to integration responses, showing the ISO 8601 timestamp of when the integration was last updated.
* **`/cost_alerts` endpoint:** The `/cost_alerts` [endpoint](/api) now requires report tokens when creating or updating cost alerts. Previously, report tokens were optional, which could cause alerts to be created without associated reports.
## Product Updates
* **Dashboard title:** Dashboard titles are now displayed in browser tabs for easier identification of the dashboard you are viewing.
* **Snowflake integration update:** An update was made to the [Snowflake integration](/connecting_snowflake) view definitions, meaning that customers won't need to recreate them when Snowflake makes minor upstream changes to the tables they rely on.
* **Dashboard PDFs:** You can now [export dashboards as PDF files](/dashboards#export-dashboards) and send them via email.
* **MCP update:** The [Vantage MCP](/vantage_mcp) now supports HTTP transport with a new /mcp endpoint, replacing the previous SSE-based connection. Backward compatibility with existing authentication modes is maintained. The new endpoint is: `https://mcp.vantage.sh/mcp`.
* **GCP subcategories:** The subcategory filter is now available in [GCP](/connecting_gcp) Cost Reports for more granular cost breakdowns. This filter is useful in cases where the Category is Other. The Subcategory will provide more detail, such as a SKU description, like "Compute Engine - E2 Custom Instance Ram running in Americas".
* **Settings > Cost Settings:** The **Settings** dropdown menu, which contains selections like Credits, Discounts, and Amortization, has been renamed to **Cost Settings** for clarity.
* **Resource filter fix:** A fix was made to the resource filter on Cost Reports so that when filtering by resource, the **contains** option now properly works with resource names.
* **Azure secret update:** You can now update expired Azure secrets directly in the [Vantage console](/connecting_azure#update-your-client-secret).
* **Anomaly alert UI fix:** When updating an existing anomaly alert, the Slack blade will now automatically open if Slack alerts are configured, making them easier to see.
* **Ungrouped bar charts update:** On [Cost Reports](/cost_reports), you can now view cumulative costs as ungrouped bar charts.
* **Comparative bar chart:** You can now view [side-by-side comparison charts](/cost_reports#side-by-side-comparison-charts) on Cost Reports to compare spending across different categories, displaying current and previous period costs side-by-side for report groupings, like service or region.
* **Terraform on Docs MCP:** The [Vantage Docs MCP](/docs_mcp) now supports Terraform, allowing you to query how to create resources and data sources with the Vantage Terraform provider.
* **Datadog unused metrics recommendation:** A new [cost recommendation](/cost_recommendations) was added to identify unused Datadog metrics that can be deleted to reduce costs.
### Kubernetes Agent Updates
* **Azure GPU support:** Vantage now supports [Azure GPUs](/kubernetes#kubernetes-gpu-idle-costs), allowing you to track, allocate, and optimize GPU-backed workloads running on Azure Kubernetes Service.
* **OCI Kubernetes support:** Vantage now supports Oracle Cloud Infrastructure (OCI) Kubernetes clusters, allowing you to gain cost visibility into your OCI workloads.
* **On-prem Kubernetes support:** Vantage now supports on-prem Kubernetes clusters, allowing you to gain cost visibility into your on-prem workloads. See the [connecting on-prem Kubernetes guide](/kubernetes_agent#enable-on-premises-support) for setup instructions.
### API Updates
* The `chart_settings` object is now available on the `/cost_reports` [endpoint](/api) to programmatically configure chart settings for Cost Reports.
## Product Updates
* **AI integrations**: Two new integrations were added this month.
* Vantage now integrates with [Anthropic](/connecting_anthropic) to provide cost visibility by operation and model.
* Vantage now integrates with [Anyscale](/connecting_anyscale) to provide cost visibility by organization, project, cloud provider, and more.
* **Cost Report updates**: Two major Cost Report updates were shipped.
* You can now [export Cost Reports](/cost_reports#export-cost-reports) as PDF files directly from the Vantage console.
* You can also now [configure the X axis](/cost_reports#configure-the-x-axis) on Cost Reports to display either by date or another category, like service.
* **MSP currency conversion:** Managed Service Providers (MSPs) can now [set a currency display preference](/partners#configure-currency-management) for each Managed Account.
* **Quality of life updates:** Below are some fixes and upgrades seen throughout the console:
* **Integrations updated time:** The **Last Updated** column now appears next to integrations on the **Integrations settings** page.
* **Moving folders:** A fix was released so that the **Move** dialog box now properly opens when selected on the Folders screen.
* **Active Resources assigned tags:** For any [Active Resource](/active_resources) that has tags assigned, the **Assigned Tags** section of the resource screen now shows both virtual and provider tags, with icons to denote the tag type.
* **[MCP updates](/vantage_mcp):** Two updates for the Vantage MCP were released.
* If you have an LLM or script that is not compatible with OAuth, you can now pass an API token the same way you would a regular call to the Vantage API to authenticate requests.
* A new `list-recommendations` tool has been added to the hosted Vantage MCP to list all cost optimization recommendations available in the user's Vantage account.
* **Billing rules UI:** The MSP **Billing Rules** tab now has links within the table to corresponding [billing rules pages](/partners#billing-rules).
* **Docs site updates and MCP:** The docs now have a new AI search, as well as support for the [Vantage Docs MCP](/docs_mcp). The content throughout these docs has also been optimized for AI.
* **Extended Support and End of Life Notifications for Amazon RDS:** You can now [get visibility](/active_resources#rds-extended-support) into the support status of RDS MySQL and PostgreSQL, highlighting database instances incurring Extended Support fees and those approaching end-of-life milestones.
### Kubernetes Agent Updates
*See August's update for the most recent Kubernetes agent release.*
### API Updates
`v0.1.65` is the most [recent Terraform version](https://registry.terraform.io/providers/vantage-sh/vantage/0.1.65/docs). Recent updates include new data sources and resources for the MSP invoicing feature:
* `vantage_billing_profile` [resource](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/resources/billing_profile)
* `vantage_billing_profiles` [data source](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/data-sources/billing_profiles)
* `vantage_invoice` [resource](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/resources/invoice)
* `vantage_invoices` [data source](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/data-sources/invoices)
## Product Updates
* **AWS FsX active resource:** AWS FsX file systems are now synced as [active resources](/aws_supported_services).
* **EBS throughput:** Volume Throughput is added as a field in EBS Active Resource pages.
* **Remediation steps for Cost Recommendations:** [Cost recommendations](/cost_recommendations) now include actionable remediation steps, such as CLI commands or links to additional resources.
* **Audit logs:** [Audit logs](/audit_logs) are now available in Vantage so that account administrators can view user actions taken on Cost Reports and Virtual Tags.
* **Additional sortable columns:** You can now sort by Resource, Account, and Type in [Resource Reports](/active_resources#sort-columns).
* **ClickHouse `entityName`:** [ClickHouse costs](/connecting_clickhouse) now include `entityName`, represented as a tag.
* **MSP invoicing:** Invoicing for Managed Service Providers (MSPs) is in Private Preview. This feature allows MSPs to automate generation and distribution of invoices to their end customers. See the [release blog](https://www.vantage.sh/blog/msp-invoicing-private-preview) for details.
* **Nested tag report drilldown:** On Cost Reports, you can [drill down](/cost_reports#tagging-drilldown) into tag values to view nested tags and their associated costs.
* **Quarterly date binning:** You can now [bin Cost Reports](/cost_reports#create-a-cost-report) by quarter (in addition to other existing binning options, like day and month).
* **Autopilot date picker:** The date dropdown on the [Autopilot](/autopilot) coverage page is updated so that you can select a full date range, rather than just an individual month.
* **Databricks system tables:** The [Databricks integration](/connecting_databricks) is updated to use Databricks system tables for more accurate, granular cost data.
### Kubernetes Agent Updates
Added a configurable `listLimit` [setting](https://github.com/vantage-sh/helm-charts) to load Kubernetes resources in batches during startup, improving performance on large clusters.
### API Updates
* **Audit logs endpoint:** The new `/audit_logs` [endpoint](/api) is available to programmatically return audit logs from your account.
* **New Vantage MCP version:** A new version of the [Vantage MCP](/vantage_mcp) is available. This version includes additional parameter support, such as the ability to recognize report settings and groupings on the `query-costs` tool. Support is also available for SSO login on the remote MCP.
* **Terraform updates:** With last month's release of custom columns in Resource Reports, the `vantage_resource_report` [resource](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/resources/resource_report) is updated to include a `columns` parameter. The `vantage_resource_report_columns` [data source](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/data-sources/resource_report_columns) is available for retrieving available columns for a specific resource type in Resource Reports.
## Product Updates
* **Incomplete costs on Financial Commitment Reports:** A tooltip was added to [Financial Commitment Reports](/financial_commitment_reports#hourly-reporting) with hourly binning to indicate when costs are incomplete and still processing.
* **Budget screen UI updates:** Tooltips have been added to the [Budget Hierarchy](/budgets#budget-hierarchy) page to indicate what each value means.
* **Remote MCP:** Vantage now offers a [remote MCP server](/vantage_mcp) to let AI agents access cloud cost data, with no infrastructure management required.
* **Tags confirmation screen:** A new confirmation box is added to the [Tags screen](/tagging) to prevent loss of unsaved changes when a user attempts to navigate away from the page.
* **Filter UI update:** An update was made to the **where** section of a [report filter](/cost_reports#filter-cost-reports) for improved dropdown usability by auto-focusing the search input when selecting from large filterable lists.
* **Show/hide previous period:** You can now show or hide the [previous period](/cost_reports#create-a-cost-report) on Cost Reports. A new toggle is displayed on the report date picker.
* **Active Resources and Resource Report updates:** The following updates were made to update Resource Reports and [Active Resources](/active_resources).
* You can now filter by a tag name substring using the **contains** and **does not contain** filters on a Resource Report.
* The [dashboard](/dashboards) widget for Resource Reports now shows a tooltip indicating the accrued costs are from the past 30 days.
* AWS Backup Vault Recovery Points and AWS FSx Volumes are now available as Active Resources.
* Stopped EC2 instances are now available as Active Resources. **State** now appears as a report column to determine if the instance is running or stopped.
* Vantage now supports ad-hoc downloads of any Resource Report, allowing users to export filtered views without saving them first.
* You can now [customize](/active_resources#customize-a-resource-report) which columns are displayed in your Resource Reports, such as resource-specific metadata fields, as well as arrange the columns in any order.
* **MSP RBAC enhancements:** Two enhancements [were released](/partners#role-based-access-control) for Managed Service Provider (MSP) access controls:
* Role Based Access Control (RBAC) is now available for MSP Managed Accounts.
* Inherited roles are available for Management Users who enter into Managed Accounts via the Management Account.
### Kubernetes Agent Updates
* The agent [now collects](/kubernetes#filter-by-pvc-and-node-labels) Node and PVC labels for additional reporting metrics.
* With [Persistent Metrics Recovery](/kubernetes_agent#persistent-metrics-recovery), resource metrics are retained when the upload endpoint is unreachable.
* Support was added for the following options in the [Kubernetes agent configuration](https://github.com/vantage-sh/helm-charts):
* `dnsConfig`: specifies the pod's DNS configuration
* `collectPVCLabels`: optionally enable the collection of PVC labels
### API Updates
* **Billing rules parameter:** The `sql_query` parameter is available on the `/billing_rules` [endpoint](/api) and supports creating [custom billing rules](/partners#custom-billing-rules) for MSP customers.
* **Terraform updates:** The following Terraform updates are available:
* `vantage_billing_rule` [resource](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/resources/billing_rule) and `vantage_billing_rules` [data source](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/data-sources/billing_rules) are now available to support the [MSP custom billing rules](/partners#custom-billing-rules) feature.
## Product Updates
* **Hourly granularity for Financial Commitment Reports:** You can now view Financial Commitment Reports at an [hourly granularity](/financial_commitment_reports#hourly-reporting).
* **SQL Billing Engine**: MSP customers now can create billing rules via the [SQL Billing Engine](/partners#custom-billing-rules), allowing for any custom logic on billing data on both Vantage-schema data and AWS Cost and Usage data.
* **EKS extended support recommendations**: Vantage now provides [recommendations](/cost_recommendations) for both EKS clusters currently incurring Extended Support charges and clusters that will incur costs within the next three months.
* **Updated AWS rightsizing and idle recommendations**: Coverage for [rightsizing and idle recommendations](/cost_recommendations#rightsizing-recommendations) has now been extended to EC2, RDS, EBS, ECS, Lambda, and Auto-Scaling Groups. Each new recommendation includes 10+ contextual usage metrics, up to three instance-level optimization suggestions, projections on savings, migration effort, and future utilization metrics.
* **Provider Summary widget now links to filtered Cost Report**: In the Provider Summary widget in the Overview page, provider names are now clickable and will bring you to a filtered Cost Report for the selected provider.
* **Ability to Hide Annotations**: You can now [hide annotations](/annotations#hide-annotations) on a Cost Report.
* **Integration tokens added to integration URL**: You can now obtain your Integration Token from the URL of any integration you are viewing in the Vantage console.
* **Additional metadata added to Cost Alerts**: Alerts for a percentage-based [Cost Alert](/cost_alerts/) will now include metrics about both percentage and dollar increases to provide additional context to the alert.
* **Update to small values display**: Cost Report Y-Axis will no longer include negative numbers for small values.
* **Cost Report bars with incomplete costs**: The bars for days with incomplete data from providers will now be displayed as gray in [Cost Report](/cost_reports) bar charts to distinguish from complete costs or forecasts.
* **Auto-Scaling Groups added to active resources**: AWS AutoScaling Groups (ASGs) are now available as active resources.
* **focus.vantage.sh**: The new micro-site, [focus.vantage.sh](https://focus.vantage.sh/), is a free web-based tool that converts cost CSVs or PDF invoices from select Cloud, AI, and SaaS providers into CSVs in the [FinOps FOCUS](https://focus.finops.org/what-is-focus/) 1.1 format.
### Kubernetes Agent Updates
*See May's update for the most recent Kubernetes agent release.*
### API Updates
* **Business Metrics API**: the `/business_metrics` [endpoint](/api) now supports segment tokens to assign business metrics for unit calculation.
* The following updates were made to the Terraform provider. The latest version is [version 0.1.61](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs):
* `vantage-integration` [module](https://registry.terraform.io/modules/vantage-sh/vantage-integration/aws/0.1.6) now includes an optional `cur_report_time_unit` attribute for adjusting report granularity.
## Product Updates
* **Anomaly Detection with resource attribution**: Vantage will [associate anomalies with individual resource ARNs](/cost_anomaly_alerts#how-anomaly-detection-works) to enable faster root-cause analysis.
* **Flexible match filter operation**: The [Flexible Match](/cost_reports#flexible-match) filter operator ignores casing, whitespace, underscores, and hyphenation to match all variants of a string when performing a look-up for a value.
* **FOCUS-compatible exports**: You can now [export](/cost_reports#export-cost-reports) your cloud cost and usage data in the FinOps Foundation’s open-source FinOps Open Cost and Usage Specification ([FOCUS](https://focus.finops.org/)) format.
* **Filter by human-readable name**: If a resource has a human-readable name in Vantage, you can now search for that in addition to the resource ARN when using filters in reports.
* **Cost Report legend human-readable names**: Human-readable names now replace the ARN of a resource in the legend when viewing a [Cost Report](/cost_reports).
* **EFS in active resources**: EFS has been added as an [active resource](/active_resources).
* **Business Metric sources:** The source of your Business Metric—either Datadog, CloudWatch, or CSV—will now be displayed on the main Business Metrics page.
* **Google OAuth**: Google Workspace is now available for SSO authentication.
* **Previous Period Usage Metrics**: When you view a [Usage-Based Cost Report](/usage_based_reporting/), the table view will now show previous period usage in addition to previous period cost.
* **Azure VM active resources**: Azure VMs are now available as active resources.
* **Units added to active resource fields**: Units have been added to active resource fields, where applicable, such as **EBS Size** or **RDS Allocated Storage**.
### Kubernetes Agent Updates
**Configurable polling period:** You can now set [configurable polling periods](/kubernetes_agent#configure-polling-interval) for the Vantage Kubernetes agent, as short as 5 seconds.
### API Updates
* **Data Export API update:** New `schema` parameter is available in the `/costs/data_exports` [endpoint](/api)
* **Anomaly Alerts**: The Anomaly Alerts [endpoint](/api) now returns the resource that drove the anomaly, if applicable.
* **Business Metrics**: The `/business_metrics` [endpoint](/api) now has new objects for `datadog_metric_fields` and `cloudwatch_fields` to programmatically configure Datadog and CloudWatch business metric integrations.
* The following updates were made to the Terraform provider. The latest version is [version 0.1.60](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs):
* `vantage_business_metric` [resource](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/resources/business_metric) now has additional optional attributes for `cloudwatch_fields` and `datadog_metric_fields`.
* The `vantage_cost_alert` [resource](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/resources/cost_alert) is now available.
## Product Updates
* **Vantage MCP Server:** The [Vantage MCP Server](https://github.com/vantage-sh/vantage-mcp-server/tree/main) is now generally available, which allows you to interact with Vantage through LLM tools.
* **Custom Cost Alerts:** The [Cost Alerts](/cost_alerts) feature automatically detects and notifies you of cost changes—whether by percentage or fixed amount—across customizable time periods, like day-over-day, month-over-month, or quarter-over-quarter.
* **Twilio integration:** Vantage now integrates with [Twilio](/connecting_twilio) as its latest cost provider.
* **Datadog query syntax:** You can now use [Datadog queries](/business_metrics#import-from-datadog) directly within Vantage to import Business Metrics.
* **Unit Cost export:** You can now [export Unit Costs](/cost_reports#export-cost-reports) from Cost Reports from the Vantage console.
* **App integrations:** The connection workflows for [Microsoft Teams](/microsoft_teams) and [Slack](/slack) have moved from the **Notifications** page to the **Settings** page in the App integrations section.
* **Jira budget display fix:** A fix was made to the **Budget Alerts** screen so that if a [Jira alert](/jira) is set for a budget, this now displays for configured alerts.
* **EBS volume unattached times:** EBS volume attach/detach times are available when querying EBS volume [active resources](/active_resources).
* **MSP updates:** The following updates were released for the [Vantage for MSPs](/partners) feature:
* Optional start and end dates are added to adjustment billing rules.
* The Retiering adjustment billing rule now has an option for whether to include Free Tier.
* You can now use the **Apply to All** functionality to add a new billing rule to all new and existing Managed Accounts.
* A new button for deleting a billing rule from a Managed Account is available on the Managed Account's billing rule settings.
* **Azure amortization:** You can now switch between viewing your actual costs and your [amortized costs](/connecting_azure#azure-amortization) in Azure Cost Reports.
* **Snowflake query tags:** [Snowflake](/connecting_snowflake) query tags that are written in JSON will now be parsed accordingly and turned into tag key/values.
* **Savings Plan Covered Spend renamed:** Savings Plan Covered Spend has been renamed in reports to Savings Plan Discounted Spend in [Financial Commitment Reports](/financial_commitment_reports).
* **ARN names:** ARN names have been added to EBS and CloudFront. When viewing a CloudFront distribution in a Cost Report, the domain is displayed instead of the shortened ARN for easier reading. In Cost Reports and Active Resource views, when a human-readable name is available for an EBS volume, the ARN is replaced for a more readable experience.
* **CloudWatch metrics for EBS:** you can now view VolumeReadBytes, VolumeWriteBytes, and VolumeQueueLength directly within [Resource Reports](/active_resources) for EBS volumes.
* **New report placeholder:** The default text in the Save Report modal for Cost Reports has been updated—you no longer need to delete "Untitled Report" before entering a title.
* **Autopilot managed service graphs:** You can now hover over the charts within [Autopilot](/autopilot#autopilot-graphs).
* **Updated UI for Business Metrics:** Imported [business metrics](/business_metrics) data is now added to the **Imported Metrics** tab.
* **EC2 termination recommendations:** More specific language is added to the Recommendations tab regarding Active Resources for EC2 instances that are recommended to be terminated.
* **Multiple label grouping values for Datadog Business Metrics:** You can now group by multiple label values for Datadog Business Metrics.
* **Unit standardization for hours:** Vantage will now automatically correct various forms of the "Hours" usage units across providers, such as "Hrs" or "hr" to enhance group-by experiences for usage types that use hours.
### Kubernetes Agent Updates
* **Updated Efficiency Calculations:** Kubernetes [efficiency calculations](/kubernetes#efficiency-calculations) will now be prorated based on node uptime for a more accurate calculation.
### API Updates
* **Dashboards endpoint:** On the `/dashboards` [endpoint](/api), you can now pass an empty string to the `date_interval` parameter. In addition, `end_date` is now an optional parameter.
* **Costs endpoint:** The `workspace_token` and `page` parameters are now available on the `/costs` [endpoint](/api).
* **Anomaly filtering:** Filtering (e.g., for category or provider) parameters have been added to the `/anomaly_alerts` [endpoint](/api).
* **Cost Alerts endpoints:** New `cost_alerts` [endpoints](/api) are available to support the newly released Cost Alerts feature.
* **Unit Costs:** The new `/unit_costs` [endpoint](/api) lets you retrieve the Unit Costs for a Cost Report.
* **Updates to Billing Rules API:** The new parameters `start_date`, `end_date`, and `apply_to_all` are available for additional flexibility when creating billing rules.
* **Data Export:** New `/costs/data_exports` [endpoint](/api) and `/data_exports/{data_export_token}` [endpoint](/api) available to initiate a CSV export of a Cost Report, and check on the status of an export to retrieve the URL to download the report.
* **Pagination in tags API endpoint:** Results in the `/tags` endpoint are now paginated for a better experience when fetching large lists of tag keys or tag values.
* The following updates were made to the Terraform provider. The latest version is [version 0.1.56](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs):
* `vantage_cost_alerts` [resource](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs) was added.
* `vantage_billing_rule` [resource](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/resources/billing_rule) was updated to include `start_period`, `end_period`, and `apply_to_all`.
## Product Updates
* **cur.vantage.sh console integration:** [cur.vantage.sh](https://cur.vantage.sh/) integrates with the Vantage console. Navigate to descriptions for subcategory costs on Cost Reports and service descriptions on Resource Reports.
* **New cost provider integrations:** Support is now available for [Temporal](/connecting_temporal) and [ClickHouse Cloud](/connecting_clickhouse) costs in the console. Support has also been updated for the [GitHub](/connecting_github) integration to use the new Enhanced Billing API.
* **Virtual Tags updates:** The following Virtual Tags updates were released this month:
* [Nested Virtual Tags](/tagging#nested-virtual-tags) allow you to use the filter criteria from existing Virtual Tags in the creation of new Virtual Tags.
* Pagination has been added to the Virtual Tags page to assist with readability.
* **Vantage for MSPs updates:** The following updates are available for [Vantage for MSPs](/partners) functionality:
* A new adjustment for [Re-Rate to Public Pricing](/partners#re-rate-to-public-pricing-adjustment) allows Vantage for MSPs users to revert their customers’ pricing back to list price, removing any enterprise discounts or private pricing.
* A new adjustment for [Remove SP/RI Discounts](/partners#remove-spri-discounts-adjustment) lets Vantage for MSPs users decide which Reserved Instance and Savings Plan benefits their end customers receive.
* A new adjustment for [Re-Rate Tiered Discounts](/partners#re-rate-tiered-discounts) lets Management Accounts recalculate tiered pricing models for applicable services for a customer's Managed Account.
* A customer Managed Account's **Tracked Spend** is now displayed on the **Managed Accounts** homepage.
* **Kubernetes report updates:** The following updates are available for Kubernetes Cost Reports and Efficiency Reports:
* The Kubernetes `__idle__` namespace is now enabled by default on [Kubernetes Efficiency Reports](/kubernetes#understanding-the-idle-namespace-in-kubernetes-efficiency-reports).
* Filtering by [category](/kubernetes#kubernetes-cost-reports) to see CPU, RAM, and GPU is available on Kubernetes Cost Reports.
* The aggregated total metric is now available at the top of Kubernetes Efficiency Reports.
### Kubernetes Agent Updates
The Vantage Kubernetes agent now supports ingesting costs for Amazon SageMaker hyperpods. *See February's update for other recent updates.*
### API Updates
* **Costs endpoint:** The `filters` parameter is now available on the `/costs` [endpoint](/api). If this parameter is supplied, you do not need to supply the `cost_report_token` parameter.
* **Dashboards endpoint:** A fix was made on the `/dashboards` [endpoint](/api) so that you can create a dashboard with a null date interval.
## Product Updates
* **Business metrics on reports:** The [business metrics](/business_metrics) line is now displayed on reports, regardless of binning type (e.g., cumulative, daily).
* **Forecasts on segment reports:** Forecasts are now displayed on ungrouped [segment reports](/segments).
* **Budget hierarchy chart updates:** On the [Budgets **Hierarchy**](/budgets#budget-hierarchy) screen, when you hover over the chart, the difference between the total budget and actual spend is now displayed. The chart is also updated to show costs aggregated by day rather than month.
* **Tag updates:**
* On the **Group by** menu in reports, when you select to group by **Tag**, an icon indicating the associated cost provider is displayed next to each listed tag key.
* On the **Tags** configuration screen, the **View in Cost Report** button is now available for [Virtual Tags](/tagging).
* When creating a custom tag value filter on the **Virtual Tags** screen, hidden tags are now displayed with a hidden eye icon, indicating they are only usable in Virtual Tag configurations.
* The `@` character is now an accepted character for Virtual Tag value names.
* **Grafana Cloud integration:** Vantage now integrates with [Grafana Cloud](/connecting_grafana) as its latest cost provider.
* **View as VQL:** On Financial Commitment and Network Flow Report filters, a new button is available to see the [VQL](/vql) representation of a Financial Commitment or Network Flow Report filter.
* **cur.vantage.sh:** The new microsite, [cur.vantage.sh](https://cur.vantage.sh/), helps you decode AWS Cost and Usage Report (CUR) billing codes for any AWS service.
### Kubernetes Agent Updates
* Version 1.0.28, Helm Chart [vantage-kubernetes-agent-1.1.0](https://github.com/vantage-sh/helm-charts/releases/tag/vantage-kubernetes-agent-1.1.0), includes the following update:
* Support was added for mounting volumes to the agent.
### API Updates
* **Business metric values endpoint:** The new `/business_metrics/{business_metric_token}/values` [endpoint](/api) lets you return values related to a business metric.
* **Forecasted costs endpoint:** The new `/cost_reports/{cost_report_token}/forecasted_costs` [endpoint](/api) lets you retrieve projected future spend from a Cost Report.
* **Tags endpoint:** The new `/tags/{key}/values` [endpoint](/api) lets you retrieve corresponding tag values for a given tag.
* **Date bucket on costs:** The `date_bin` parameter is now available on the `/costs` [endpoint](/api).
* **Network Flow Reports endpoint:** The `/network_flow_reports` [endpoint](/api) lets you create and manage Network Flow Reports with `POST`, `GET`, `DELETE`, and `PUT` methods.
* **Financial Commitment Reports endpoint:** The `/financial_commitment_reports` [endpoint](/api) lets you create and manage Financial Commitment Reports with `POST`, `GET`, `DELETE`, and `PUT` methods.
* The following updates were made to the Terraform provider. The latest version is [version 0.1.46](https://github.com/vantage-sh/terraform-provider-vantage/releases/tag/v0.1.46).
* The following resources and data source were added:
* `vantage_network_flow_report` [resource](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/resources/network_flow_report)
* `vantage_financial_commitment_report` [resource](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/resources/financial_commitment_report)
* `vantage_financial_commitment_reports` [data source](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/data-sources/financial_commitment_reports)
* The `vantage_business_metric` [resource](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/resources/business_metric) is updated to support the above-mentioned modification to the corresponding API endpoint, which no longer returns the `values` field in the API response. Values are now served via the `/business_metrics/{business_metric_token}/values` endpoint.
## Product Updates
* **Tagging updates:** Multiple updates were released related to tagging and [virtual tags](/tagging):
* New Tags Settings page to manage virtual and provider-created tags
* The ability to hide and unhide tag keys
* The ability to view an associated Cost Report for a given tag
* **Jira integration:** Vantage integrates with [Jira](/jira) for tracking issues connected to budget alerts, cost anomalies, and Resource Reports.
* **Annotations for Budget Alerts:** An [annotation](/annotations#budget-alert-annotations) is now added to the corresponding Cost Report when a budget alert is triggered.
* **Filter by Commitment ARN:** You can now filter by Commitment ARN on [Financial Commitment Reports](/financial_commitment_reports#create-a-financial-commitment-report) to understand the discount impact of a single Savings Plan or Reserved Instance.
* **Commitments pagination:** Pagination has been added to the [**Commitments** screen](https://console.vantage.sh/financial_planning/financial_commitments) for better readability when there are many commitments.
* **Acronym searching for resource services:** A fix was added so that when searching for a specific resource in report filters, you can now search by common acronyms for AWS services, such as **RDS** or **S3**, rather than typing the full service name.
* **Budgets UI updates:** On the **Budgets** [screen](/budgets), you can now filter by **Budget Type**. Additional UI updates have been made to the **Performance** and **Hierarchy** screens.
* **Kubernetes Efficiency Report export:** You can now export [Kubernetes Efficiency Reports](/kubernetes#export-kubernetes-efficiency-reports) from the console.
### Kubernetes Agent Updates
* Version 1.0.28, Helm Chart [vantage-kubernetes-agent-1.0.40](https://github.com/vantage-sh/helm-charts/releases/tag/vantage-kubernetes-agent-1.0.40), includes the following updates:
* Default value for `disableKubeTLSverify` is corrected from `string` to `boolean`.
* Now includes [sidecar init containers](https://kubernetes.io/docs/concepts/workloads/pods/sidecar-containers/) resource requests in pod resources.
### API Updates
* **Tags API:** The `tags` [endpoint](/api) was added with `PUT` and `GET` methods for retrieving all tags and hiding tags.
* **Usage API:** The `/costs` [endpoint](/api) has been updated to include the ability to aggregate by and retrieve usage values via the `settings[aggregate_by]` parameter.
* **Hierarchical budgets:** The `/budgets` [endpoint](/api) is updated to return or specify `child_budget_tokens` for any hierarchical budgets.
* **Parameter name update:** On the `/kubernetes_efficiency_reports` [endpoint](/api), the `date_bin` parameter is now `date_bucket`.
## Product Updates
* **OpenAI cost support:** Vantage now fully integrates with [OpenAI](/connecting_openai) as its latest cost provider.
* **Service aliases in Financial Commitment Reports:** When searching for services in [Financial Commitment Report](/financial_commitment_reports) filters, you can now search by common acronyms for AWS services, such as **RDS** or **S3**, rather than typing the full service name.
* **Explore menu:** The new **Explore** menu, on the top right of the console, allows you to perform quick actions, like view recent reports, view starred reports, and create new reports—all from one menu.
* **Customized Dashboards:** Vantage now supports the ability to move around the widget order on [Dashboards](/dashboards), change between chart and table widget types, and rename widgets directly from the Dashboard.
* **Hierarchical Budgets:** [Hierarchical Budgets](/budgets) are available to help you match your budgets to your organization's structure. Create parent-child budgeting relationships and hierarchies.
* **AWS Model Training SKU Group:** The AWS Model Training SKU Group is added to the [supported custom pricing](/connecting_databricks#databricks-reporting-dimensions) Databricks SKU Groups.
* **Choose a currency display preference:** If your imported costs are already billed in a currency other than USD, you can enable a [display preference](/vantage_account#currency-conversion). This lets you view your costs with the appropriate currency symbol—without using Vantage's currency conversion rates.
### Kubernetes Agent Updates
*See September's update for the most recent Kubernetes agent release.*
### API Updates
* **Dashboards endpoint:** The `widget_tokens` parameter of the `/dashboards` [endpoint](/api) now supports `CostReport`, `ResourceReport`, `KubernetesEfficiencyReport`, and `FinancialCommitmentReport` tokens.
* **Dashboards Terraform:** `widget_tokens` is now a supported parameter on the `vantage_dashboard` [resource](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/resources/dashboard) and `vantage_dashboards` [data source](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/data-sources/dashboards).
## Product Updates
* **Update Dashboard order:** You now have the option to update the [report order](/dashboards#edit-dashboard-widget-order) on Dashboards.
* **AWS human-readable account names:** In addition to the account number, the human-readable account name is now visible on the [AWS Integrations](/connecting_aws) page for AWS account integrations.
* **Virtual Tags processing status:** The "Processing..." indicator on [Virtual Tags](/tagging) now provides more accurate status updates, specifically for the initial run of new or updated Virtual Tag configurations.
* **Virtual Tags in Resource Reports:** You can now [filter by Virtual Tags](/active_resources#resource-report-filters) within Resource Report filters.
* **Linode integration:** Vantage now integrates with [Linode from Akamai Connected Cloud](/connecting_linode) as its latest cost provider.
* **Integration Owner role:** The new [Integration Owner role](/rbac) has all the privileges of the Editor role, as well as the ability to configure and manage access to provider integrations. The role does not have access to other sensitive configuration settings.
* **View as VQL:** On Kubernetes Efficiency Report filters, a new button is available to see the [VQL](/vql) representation of a Kubernetes Efficiency Report filter.
* **Costs drilldown:** New costs [drilldown options](/cost_reports#drill-down-in-costs-table) are available to add additional targeted filters and grouping criteria to a Cost Report.
* **Service aliases:** When searching for services in report filters, you can now search by common acronyms for AWS services, such as **RDS** or **S3**, rather than typing the full service name.
### Kubernetes Agent Updates
*See September's update for the most recent Kubernetes agent release.*
### API Updates
* **Kubernetes Efficiency Endpoint:** The following API methods were added to support the new `/kubernetes_efficiency_reports` [endpoint](/api):
* `POST` `/kubernetes_efficiency_reports`: Creates a new Kubernetes Efficiency Report
* `PUT` `/kubernetes_efficiency_reports/{kubernetes_efficiency_report_token}`: Updates an existing Kubernetes Efficiency Report
* `GET` `/kubernetes_efficiency_reports`: Retrieves all existing Kubernetes Efficiency Reports
* `GET` `/kubernetes_efficiency_reports/{kubernetes_efficiency_report_token}`: Retrieves a specific Kubernetes Efficiency Report by its `kubernetes_efficiency_report_token`
* `DELETE` `/kubernetes_efficiency_reports/{kubernetes_efficiency_report_token}`: Deletes a specific Kubernetes Efficiency Report by its `kubernetes_efficiency_report_token`
* **Terraform updates:** The following resource and data source were added to the Terraform Provider to support the new Kubernetes Efficiency Reports API:
* `vantage_kubernetes_efficiency_report` [resource](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/resources/kubernetes_efficiency_report)
* `vantage_kubernetes_efficiency_reports` [data source](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/data-sources/kubernetes_efficiency_reports)
## Product Updates
* **Usage Reporting:** [Usage-Based Reporting](/usage_based_reporting) is available to provide infrastructure consumption in non-monetary metrics, such as virtual machine running hours, stored gigabytes of data, and read/write units consumed.
* **New Azure recommendations:** Additional [recommendations](/cost_recommendations#azure-recommendations), such as for rightsizing, were added for Azure.
* **Visual UI updates:** Visual updates have been made to the look and feel of the Cost Reporting and Segments screens.
* **View as VQL:** On Resource Report filters, a new button is available to see the [VQL](/vql) representation of a Resource Report filter.
### Kubernetes Agent Updates
*See September's update for the most recent Kubernetes agent release.*
### API Updates
* **User token endpoint:** The `last_seen_at` field is added to the response of the `/users/{user_token}` [endpoint](/api).
* **Currency on workspaces:** The `enable_currency_conversion` parameter is added to the `/workspaces` [endpoint](/api) to enable currency conversion on workspaces.
* **Resource Reports API:** The following endpoints were added to support the new Resource Reports API:
* `POST` option for the `/resource_reports` [endpoint](/api)
* `PUT` option for the `/resource_reports/{resource_report_token}` [endpoint](/api)
* `GET` option for `/resources` [endpoint](/api)
* `GET` option for the `/resources/{resource_token}` [endpoint](/api)
* [VQL is now available](/vql_resource_report) with its own namespace and schema to support creating and managing Resource Reports
* **Resource Reports Terraform updates:** The following resource and data source were added to the Terraform Provider to support the new Resource Reports API:
* `vantage_resource_report` [Terraform resource](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/resources/resource_report)
* `vantage_resource_reports` [data source](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/data-sources/resource_reports)
* **`vantage-go` updates:** [Version 0.0.40](https://github.com/vantage-sh/vantage-go) of the `vantage-go` library includes the following updates:
* `GET /resources` added
* `GET`/`PUT`/`POST`/`DELETE` of `/resource_reports`
* `PUT /workspaces` can now configure currency for a workspace
* `/users` API response now includes `last_seen_at`
* You can now use `terraform import` to manage Terraform resources outside of the current state on the [Terraform provider](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Product Updates
* **Currency conversion:** You can now set a [presentational currency](/vantage_account#currency-conversion), on a per-workspace basis, to visualize cost reporting data in a currency of your choice.
* **Datadog integration update:** Vantage provides a [visual alert](/connecting_datadog#update-the-datadog-integration) in the integration settings screen when the Datadog integration requires an update.
* **Datadog hosts costs:** For cloud resources that have the Datadog agent installed, Vantage [can associate](/active_resources#datadog-host-costs) Datadog per-host fees along with the primary cloud resources from AWS, Azure, and Google Cloud that drive those costs.
* **Auto-generated Datadog Resource Reports:** Vantage automatically generates a Resource Report when it finds the Datadog Agent installed on relevant resources. Auto-generated reports will have a name similar to *AWS EC2 Instances with the Datadog Agent Installed*.
* **Visual UI updates:** Visual updates have been made to the look and feel of the Cost Reporting sidebar.
* **View as VQL:** On Cost Report filters, a new button is available to see the [VQL](/vql) representation of a Cost Report filter.
* **GitHub integration:** Vantage now integrates with GitHub. See the [Connecting GitHub](/connecting_github) documentation for details on how to get started.
* **New Autopilot banner:** A banner is now displayed at the top of the **Coverage Overview** page on [Autopilot](/autopilot) when a Savings Plan is purchased.
* **Drill down on Cost Reports:** You can now [drill down](/cost_reports#drill-down-in-costs-table) in the Cost Report table when the report is grouped by more than three options.
* **Account search for Cost Recommendations:** Organizations with many accounts can now search for an account to filter by on the [Cost Recommendations](/cost_recommendations) screen.
* **Faster Budget loads:** Performance improvements were made to the [Budgets](/budgets) page for faster page loads.
* **Cost Report link in Slack alerts:** A link to the corresponding Cost Report is now displayed on Slack budget alerts.
* **AWS Organization tags:** You can now filter and group by [AWS Organization tags](/cost_reports#aws-organization-tags) on Cost Reports.
### Kubernetes Agent Updates
* **Updated cost calculation:** Kubernetes Efficiency Reporting and Rightsizing Recommendations now accurately [calculate pod costs](/kubernetes#cost-data-source) down to the minute, meaning if a pod runs for only 5 minutes within an hour, Vantage recognizes only 5 minutes of spend, rather than the full hour.
* Version 1.0.26, Helm Chart [vantage-kubernetes-agent-1.0.36](https://github.com/vantage-sh/helm-charts/releases/tag/vantage-kubernetes-agent-1.0.36), includes the following update:
* Added support for `podSecurityContext` to define the security options the pod should be run with
### API Updates
[v0.1.27](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs) of the Vantage Terraform Provider is now available:
* The `created_by_token` is now available as an option on the [`vantage_budgets`](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/data-sources/budgets) data source.
## Product Updates
* **Savings Planner visual updates:** Visual updates were made to [Savings Planner](/savings_planner) for navigability.
* **Custom Providers integration:** [Custom Providers](/connecting_custom_providers) are now available as an integration option, so you can connect any of your providers to Vantage using the FinOps FOCUS schema.
* **Cost Report and Dashboard header visual updates:** Visual updates were made to Cost Report and Dashboard headers for better organization and navigation.
* **Provider icons visual improvements:** On the main [Virtual Tags](https://console.vantage.sh/settings/virtual_tags) and [Cost Reporting](https://console.vantage.sh/reporting) screens, visual updates were made to include provider icons next to each report or virtual tag in the list.
* **Autopilot for AWS Savings Plans:** [Autopilot](/autopilot) for AWS Savings Plans is now available, which allows Vantage to purchase Compute Savings Plans commitments on your behalf, with manual and automated options.
* **Account filter matching:** For cost providers, like AWS, that have human-readable account names, you can now wildcard-match on account names in [Cost Report filters](/cost_reports#filter-cost-reports) (e.g., set a filter, like *Account **contains** dev*).
* **Total costs by date:** On [Cost Reports](/cost_reports#comparative-cost-reporting), the **Total Costs** row is displayed when you change the table display to **By Date**.
* **Set default dashboard:** You can set the [default dashboard](/dashboards#set-a-default-dashboard) that's displayed for a team or individual users when they log in to Vantage.
* **Additional GCP Active Resources:** The following [GCP services](/gcp_supported_services) were added and synced as active resources:
* Cloud AlloyDB clusters, instances, and backups
* Cloud Container clusters
* Cloud Functions
* Memorystore for Redis instances
* Secrets Manager secrets
### Kubernetes Agent Updates
*See May's update for the most recent Kubernetes agent release.*
### API Updates
* The following API endpoints were released along with the Custom Providers feature:
* `/integrations/custom_provider` [endpoint](/api) to create a Custom Provider
* `/integrations/{integration_token}/costs.csv` [endpoint](/api) to upload a Custom Provider CSV file
* `/integrations/{integration_token}/costs/{user_costs_upload_token}` [endpoint](/api) to delete a Custom Provider CSV file
* `/integrations/{integration_token}/costs` [endpoint](/api) to list all uploaded CSV files for a Custom Provider
## Product Updates
* **Dynamic Cost Allocation:** Dynamic cost allocation, which is the process of allocating costs based on another existing cost or metric, is now available. See the [Virtual Tagging](/tagging) documentation for details.
* **Workspace access updates:** If you are granted access via [RBAC](/rbac) to a report in a workspace outside your regularly accessed workspace, when you access the link to the report, you will have temporary access to the new workspace and can view the items that you were granted access to.
* **Share reports across workspaces:** You can now share report links across different [workspaces](/workspaces). For example, if you're in Workspace A and open a report link from Workspace B, you'll be automatically switched to Workspace B to view the report. Previously, a `404` error was displayed.
* **GCP active resources:** [GCP active resources](/gcp_supported_services) are now synced and available to filter within Resource Reports.
* **GCP cost recommendations:** [Recommendations](/cost_recommendations#gcp-compute-rightsizing-recommendations) are now available for GCP Compute rightsizing and commitments.
* **Grouped report forecasts:** You can now view [forecasts](/forecasting#baseline-forecast) for bar charts when they are grouped.
* **Flow weight on Network Flow Reports:** You can now change the Sankey diagram to be weighted by either costs or bytes on [Network Flow Reports](/network_flow_reports#adjust-flow-weight).
* **Save as new on reports:** On existing reports, like a [Cost Report](/cost_reports#save-a-cost-report), you can now click **Save as New** at the top to create a new report based on the current report's filters.
* **Vantage for MSPs**: Vantage for MSPs is a new set of features for managed service providers. Learn more on the [Partners website](https://www.vantage.sh/partners).
### Kubernetes Agent Updates
*See May's update for the most recent Kubernetes agent release.*
### API Updates
* **Costs endpoint updates:** The `/costs` [endpoint](/api) has been updated with the ability to specify settings parameters for returned costs, like credits, refunds, etc.
* **Cost Report endpoint updates:** The `/cost_reports` [endpoint](/api) has been updated to include the following parameters for `POST` and `PUT`:
* `previous_period_start_date`
* `previous_period_end_date`
* `start_date`
* `end_date`
* `date_interval`
* `chart_type`
* `date_bin`
* Two version updates were released of the Terraform provider:
* [v0.1.23](https://github.com/vantage-sh/terraform-provider-vantage/releases/tag/v0.1.23) is based on the above API changes, including new parameters for the `vantage_cost_report` [resource](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/resources/cost_report) and the `vantage_cost_reports` [data source](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/data-sources/cost_reports).
* [v0.1.24](https://github.com/vantage-sh/terraform-provider-vantage/releases/tag/v0.1.24) adds support for dynamic cost allocation on the `virtual_tag_config` resource.
## Product Updates
* **Visual UI updates:** Visual updates have been made to the look and feel of the main navigation and related Active Resources screens.
* **New dashboard widgets:** Resource Reports are a new widget option on [dashboards](/dashboards).
* **Data transfer cost visibility:** [Network Flow Reports](/network_flow_reports) are available to provide visibility by source and destination to the flows within your network that are driving costs.
* **New active resources:** VPC Flow Logs are now synced as [active resources](/active_resources).
* **VPC Flow Logs active resources tab:** The **VPC Flow Logs** tab is available on the [Active Resources screen](/active_resources#vpc-flow-logs) for resources that generate network traffic. This tab shows network flows for related resources.
* **Network costs:** A new **Network Costs** button is displayed on [Cost Reports](/cost_reports#network-costs) for resources that generate network costs, like NAT Gateways.
### Kubernetes Agent Updates
*See May's update for the most recent Kubernetes agent release.*
### API Updates
New `/integrations` [endpoints](/api) are available:
* `GET` `/integrations`: retrieves all existing integrations
* `POST` `/integrations/azure`: creates a new Azure integration
* `POST` `/integrations/gcp`: creates a new GCP integration
* `DELETE` `/integrations/{integration_token}`: deletes a specific integration
* `GET` `/integrations/{integration_token}`: gets information about an existing integration
* `PUT` `/integrations/{integration_token}`: updates workspace access for an existing integration
## Product Updates
* **Visual UI updates:** Visual updates have been made to the look and feel of the Budgets, Business Metrics, Cost Recommendations, Active Resources, and Resource Reports screens.
* **Segments RBAC:** Users with the [editor role](/rbac) can now update [segments](/segments).
* **MongoDB tags:** Tags are now available as a filtering dimension for [MongoDB](/connecting_mongodb-atlas) Cost Reports.
* **Forecasted performance of a budget:** Future [budget periods](/budgets) are now displayed and compared to forecasts on Cost Reports.
* **Reserved Instance recommendations:** Reserved Instance [recommendations](/cost_recommendations) now include a link to [Autopilot](/autopilot) with split-out categories and usage.
* **Negative cost axis:** The range of the cost axis on Cost Reports is updated to include negative values. This is visible in cases where costs may be negative due to things like credits.
* **Vantage University:** [Vantage University](/vantage_university) is available on the docs site and includes a set of videos for getting started with Vantage.
* **Labeled business metrics:** [Labeled business metrics](/business_metrics#labeled-business-metrics) are available to identify the source of a metric—like an associated application or cost center.
* **Kubernetes GPU idle costs:** For each Kubernetes pod, you can now view the [idle and total costs](/kubernetes#kubernetes-gpu-idle-costs) for NVIDIA GPU usage within a Kubernetes cluster.
### Kubernetes Agent Updates
* Version 1.0.26, Helm Chart [vantage-kubernetes-agent-1.0.34](https://github.com/vantage-sh/helm-charts/releases/tag/vantage-kubernetes-agent-1.0.34), includes the following updates:
* Support is now available for NVIDIA GPU exporters.
* Fargate nodes are now ignored.
* Version 1.0.25, Helm Chart [vantage-kubernetes-agent-1.0.33](https://github.com/vantage-sh/helm-charts/releases/tag/vantage-kubernetes-agent-1.0.33), includes the following update:
* The `report_http_proxy` flag is available to supply during configuration. HTTP proxy is used for the HTTP client that calls Vantage and S3 during periodic reports. Overrides `HTTP_PROXY` in the event both are specified.
### API Updates
* **Cost recommendations endpoint:** The `/recommendations` [endpoint](/api) automates the retrieval of cost recommendations. The endpoint includes filtering options for parameters like category and provider.
* **Integrations endpoint:** The `/integrations` [endpoint](/api) automates the retrieval of information about existing integrations. You can also send a `DELETE` call to delete existing integrations.
* **Segment tokens in budgets:** The `cost_report_token` parameter of the `/budgets` [endpoint](/api) now accepts segment tokens (in addition to Cost Report tokens).
* **Business metrics endpoint updates:** With the release of labeled business metrics, the `/business_metrics` [endpoint](/api) is updated to include a `label` object as part of the `values` array of objects.
## Product Updates
* **Visual navigation improvements:** A **Create New** menu for quick actions is available on the top navigation bar.
* **Datadog metrics:** Business metrics have been updated with the option to directly ingest [Datadog metrics](/business_metrics#import-from-datadog).
* **New virtual tagging feature:** [Virtual tagging](/tagging) is available to consistently tag costs across providers in Vantage. This feature can help to increase tagging coverage across your cloud infrastructure.
* **New rightsizing recommendations:** Kubernetes [rightsizing recommendations](/cost_recommendations#kubernetes-rightsizing-recommendations) are now available for rightsizing managed workloads in Kubernetes.
* **New to active resources:** Kubernetes managed workloads are synced as [active resources](/active_resources) in Vantage.
* **Expanded forecasts:** [Forecasts](/forecasting) have been expanded to include the upcoming month, the next three months, and six months ahead.
* **Kubernetes agent version:** The [Clusters](/kubernetes_agent#upgrade-agent) section of the Kubernetes agent settings screen is updated to show cluster name, version, and indicate if the cluster is out of date.
* **Expanded chart options:** [Expanded chart options](/cost_reports#adjust-chart-visualization) are available for Cost Reports, including expanded date bin selections for area and line charts and multi-line charts for grouped data.
* **API service tokens:** Users with owner-level permissions can now create [API service tokens](/api/authentication) for authenticating with the Vantage API at the account level, rather than being associated with a specific user.
### Kubernetes Agent Updates
*See March's update for the most recent Kubernetes agent release.*
### API Updates
* **New API endpoints:** The following endpoints have been added to the API:
* The [`/resource_reports`](/api) endpoint automates the retrieval of existing [resource reports](/active_resources).
* The [`/financial_commitment_reports`](/api) endpoint automates the retrieval of [financial commitment reports](/financial_commitment_reports).
* The [`/kubernetes_efficiency_reports`](/api) endpoint automates the retrieval of [Kubernetes efficiency reports](/kubernetes).
* The [`/anomaly_alerts`](/api) endpoint allows you to retrieve and update [anomaly alerts](/cost_anomaly_alerts).
* The [`/virtual_tag_configs`](/api) endpoint automates the creation, retrieval, and update of [virtual tags](/tagging).
* The [`/anomaly_notifications`](/api) endpoint automates the creation, retrieval, and update of anomaly notifications.
* The [`/budgets`](/api) endpoint automates the creation, retrieval, and update of [budgets](/budgets).
* The [`/budgets_alerts`](/api) endpoint automates the creation, retrieval, and update of budget alerts.
* **New Terraform resources:** The following resources have been added to the Terraform provider:
* [`vantage_virtual_tag_config`](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/resources/virtual_tag_config)
* [`vantage_anomaly_notification`](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/resources/anomaly_notification)
* [`vantage_budget`](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/resources/budget)
* [`vantage_business_metric`](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/resources/business_metric)
* [`vantage_report_notification`](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/resources/report_notification)
* **New Terraform data sources:** The following data sources have been added to the Vantage provider:
* [`vantage_anomaly_notifications`](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/data-sources/anomaly_notifications)
* [`vantage_financial_commitment_reports`](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/data-sources/financial_commitment_reports)
* [`vantage_kubernetes_efficiency_reports`](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/data-sources/kubernetes_efficiency_reports)
* [`vantage_resource_reports`](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/data-sources/resource_reports)
* [`vantage_virtual_tag_configs`](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/data-sources/virtual_tag_configs)
* [`vantage_budgets`](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/data-sources/budgets)
* [`vantage_business_metrics`](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/data-sources/business_metrics)
* [`vantage_report_notifications`](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/data-sources/report_notifications)
## Product Updates
* **Saved filters on dashboards**: You can now add a [saved filter](/dashboards#add-a-saved-filter-to-a-dashboard) to a dashboard to view all Cost Reports on the dashboard with consistent filters applied.
* **Updated Overview page**: Associated budget and per unit costs are now displayed on Cost Report widgets on the [Overview](/overview) page.
* **Updated UI look and feel**: Visual improvements were made to the look and feel of the Overview and Budgets screens.
* **Segments sync status**: Cost allocation [segments](/segments#edit-a-segment) are now updated to show segment sync status. The look and feel of this page have been visually updated as well.
* **Filterable cost recommendations**: Recommendations are now filterable by provider on the [Cost Recommendations](/cost_recommendations) screen.
* **Pie chart option**: You can now change the [graph view](/cost_reports#configure-report-groups) on Cost Reports to a pie chart.
* **Custom date filtering**: The date picker on [Cost Reports](/cost_reports#create-a-cost-report) is updated to allow for custom period selections.
* **Custom Databricks pricing**: Custom discounts are [now supported](/connecting_databricks#databricks-reporting-dimensions) for Databricks SKU groups.
### Kubernetes Agent Updates
The following versions were released this month.
* **Version 1.0.24** includes the following update:
* Supports monitoring ArgoCD resources in the cluster.
* **Version 1.0.23** includes the following updates:
* `app.kubernetes.io` labels are now allowed.
* Agent scrape results are added to agent metadata.
* [Prometheus metrics](/kubernetes_agent#monitoring) are added for tracking reporting successes/failures.
* Dependencies are updated to the latest stable versions.
* Additional controller metadata is included in agent reports for use in [Active Resources](/active_resources).
### API Updates
* **New `tagged` option**: On the `/cost_reports` [endpoint](/api) in the API, and the `vantage_cost_report` [resource](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/resources/cost_report) in the Terraform provider, `tagged` is a valid option for the `groupings` parameter.
* **New dashboard parameter**: The `saved_filter_tokens` parameter is now available on the `/dashboards` [endpoint](/api). It is also available on the `vantage_dashboard` [resource](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/resources/dashboard) in the Terraform provider.
* **New Terraform resources**: Additional Terraform resources are now available:
* The `vantage_segment` [resource](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/resources/segment) automates the creation of cost allocation segments in Vantage. Large segment hierarchies can easily be automated with filters applied as needed.
* The `vantage_team` [resource](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/resources/segment) automates the creation of Vantage teams. Create a team and assign Vantage users, by email, to the team.
* The `vantage_access_grant` [resource](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/resources/access_grant) automates access grants via role-based access controls in Vantage. Create grants to allow or deny teams access to resources, like folders or Cost Reports.
* The `vantage_report_notification` [resource](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/resources/report_notification) automates the creation of Report Notifications. Create a notification for a specific Cost Report. Specify the notification’s frequency (e.g., daily) and change (e.g., in dollars).
* **Terraform data sources**: [Data sources](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/data-sources/access_grants) are now available to retrieve information outside your Terraform configuration.
* **Business metrics endpoint**: The `/business_metric` [endpoint](/api) is now available to create and update business metrics in the console.
## Product Updates
* **Ability to group by multiple tags**: You can now group by multiple tags in the console.
* **EC2 rightsizing recommendations**: New [recommendations](/cost_recommendations) are added for rightsizing EC2 instances.
* **Segment settings**: You can now edit the default report settings on a top-level [segment report](/segments#create-a-segment).
* **Updated UI look and feel**: Visual updates were made to Financial Planning menus and screens.
* **Financial Commitment Reports**: [Financial commitment reports](/financial_commitment_reports) are now available to help you understand how your organization is utilizing financial commitments.
* **Bulk actions for folders and Cost Reports**: You can now [move and star](/folders#move-cost-reports-and-folders) folders and Cost Reports in bulk.
* **Additional operators on resource reports**: The `is greater than` and `is less than` operators are both available for Metadata filters on [resource reports](/active_resources). For example: **where** Metadata CloudWatch Log Groups Retention in Days **is greater than** 5.
### API Updates
* **New notifications endpoint:** The `/report_notifications` [endpoint](/api) is now available. This endpoint also now has support via the [Terraform provider](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/resources/report_notification).
* **Multi-tag support**: The `groupings` parameter of the `/costs` [endpoint](/api) has support for multiple tags.
* **Data sources in Terraform**: [Data sources](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/data-sources/access_grants) for multiple Vantage resources are now available in the Terraform provider.
* **Segment costs**: You can now obtain costs for segment reports from the `/costs` [endpoint](/api).
* **Settings options on segments**: The `report_settings` object is now available on the `/segments` [endpoint](/api).
* **Settings on Cost Reports**: The `settings` [object](/api) is now available on the `/cost_reports` endpoint.
## Product Updates
* **PlanetScale support**: [PlanetScale](/connecting_planetscale) is now supported as a provider in Vantage.
* **Updated UI look and feel**: The **Settings** UI and main navigation bar are visually updated for better navigability.
* **Charge Type filter and group**: Charge Type is available as a new [filter and grouping category](/cost_reports#configure-report-groups) on Cost Reports.
* **Created by column**: The **Created by** column is added to Business Metrics, Savings Models, as well as Cost Reporting screens, like Dashboards.
* **Created On column sort**: The **Created On** column, available on Cost Reporting screens, correctly sorts by date.
* **Created by me filter**: The **Created by me** filter screen is available in Cost Reporting. New reports you create will now be visible within this view.
* **Tag grouping for advanced exports**: The [advanced export](/cost_reports#export-cost-reports) on Cost Reports now has a Tag grouping option.
* **"Other" grouping expanded**: The [**Other** grouping](/cost_reports#starred-by-me) is expanded on Cost Reports so you can display additional costs, beyond what's already displayed, in the table and graph.
* **Cost Reports line and area charts**: When grouping by specific criteria, you can now adjust the Cost Report graph to be displayed as an area chart or [line chart](/cost_reports#configure-report-groups), with a line for each group.
* **Searchable Business Metrics Report dropdown**: The **Report** dropdown menu on the [Business Metrics](/business_metrics#assign-business-metrics-to-cost-reports) screen is now searchable.
### API Updates
* **Priority added to `PUT` request for segments:** The `priority` parameter is available on the [`/segments/{segment_token}`](/api) endpoint.
* **New groupings parameter:** The `groupings` parameter is available on the [`/costs`](/api) endpoint.
* **Access grant endpoint update:** [Update/destroy endpoints](/api) for `/access_grant` now use the access grant token to identify an access grant.
## Product Updates
* **Expanded recommendations**: [Cost recommendations](/cost_recommendations) have been expanded for Azure.
* **Kubernetes efficiency reports**: [Kubernetes efficiency reports](/kubernetes) allow teams to quickly identify which Kubernetes pods are running inefficiently. These reports are a customized view of Kubernetes idle and total costs based on Cluster, Namespace, and Label.
* **Official Kubernetes integration**: The [Vantage Kubernetes agent](/kubernetes_agent) provides a single in-cluster deployment that handles both metrics collection and upload to Vantage—without any intermediary requirements.
### API Updates
* **Cost allocations segment API**: Script both the creation and modification of cost allocation segments via new [API endpoints](/api).
## Product Updates
* **Automatic team assignment for SSO**: Automatically assign users to teams in Vantage based on your organization's [existing SSO groups](/sso).
* **Confluent support**: [Confluent](/connecting_confluent) is now supported as a provider in Vantage.
* **Team-based access controls**: Enterprise customers can now use [role-based access control](/rbac) to create fine-grained permissions for teams across their organizations.
## Product Updates
* **Resource report exports**: You can now download lists of resources for further exploration via [resource reports](/active_resources).
## Product Updates
* **Annotations for reports**: You can now add [annotations](/annotations) to Cost Reports for infrastructure changes or events.
* **Oracle support**: [Oracle](/connecting_oracle) is now supported as a provider in Vantage.
* **Dashboards**: You can now create [dashboards](/dashboards) with custom collections of Cost Reports and apply date range and period filters to all reports present on them.
### API Updates
* **Write API**: The new write [API](/api) automates the management of Cost Reports, saved filters, and dashboards.
* **New Terraform resources**: [New Terraform resources](/terraform) are available for Cost Reports, folders, saved filters, and dashboards.
## Product Updates
* **Alert thresholds for anomaly detection**: Set custom alert thresholds on [cost anomaly alerts](/cost_anomaly_alerts), so alerts are tailored to your tolerance for cost spikes.
* **Comparative cost reporting**: [Cost Reports](/cost_reports) now have a **By Date** toggle to display costs by day, week, or month in the costs table.
* **Budget alerts**: You can now create [budget alerts](/budgets#budget-alerts-and-cost-reports) to receive automated notifications when costs exceed user-defined alert thresholds.
## Product Updates
* **Datadog support**: [Datadog](/connecting_datadog) is now supported as a provider in Vantage.
* **Multi-dimensional cost reporting**: You can now group [Cost Reports](/cost_reports) by multiple dimensions.
## Product Updates
* **GCP resource-level costs**: Resource-level costs are available for GCP Cost Reports.
* **Resource reports**: You can create [resource reports](/active_resources) to view and access resources generated per provider.
## Product Updates
* **Kubernetes cost efficiency metrics**: Manage the [efficiency of your Kubernetes clusters](/kubernetes) in addition to enterprise reporting, visibility, and cost allocation.
## Product Updates
* **Self-service SAML**: Users can now [configure SAML-based SSO](/sso) for their account without contacting Vantage support.
* **Saved filters**: [Saved filters](/cost_reports#saved-filters) are available to save and reuse filter logic across multiple Cost Reports.
* **Azure cost recommendations**: Azure [cost recommendations](/cost_recommendations) are now supported.
## Product Updates
* **Cost Report exports**: You can now [export Cost Reports](/cost_reports#export-cost-reports) via custom exports.
* **Per-unit cost support**: With [per-unit costs](/business_metrics), you can track costs per customer, endpoint, transaction, etc.
### API Updates
* **Terraform provider**: [Terraform provider](https://www.vantage.sh/blog/vantage-launches-terraform-provider) is now available to integrate AWS accounts with Vantage.
## Product Updates
* **New Relic support**: [New Relic](/connecting_new_relic) is now supported as a provider in Vantage.
* **Expanded resource filtering**: You can now filter by resource in [Cost Reports](/cost_reports).
* **MongoDB Atlas support**: [MongoDB Atlas](/connecting_mongodb-atlas) is now supported as a provider in Vantage.
## Product Updates
* **Updates to Cost Reports**: You can now save custom date ranges, date bins, and groupings to share with teammates in [Cost Reports](/cost_reports).
* **Autopilot recommendations expanded**: [Autopilot](/autopilot) is expanded to recommend Reserved Instance purchases on RDS, ElastiCache, Redshift, and OpenSearch.
* **Cost allocation segments**: [Segments](/segments) are now enabled for teams to allocate costs to business units.
# ChatGPT App
Source: https://docs.vantage.sh/chatgpt_app
Use the Vantage ChatGPT app to explore and act on your cloud costs directly from ChatGPT.
The official Vantage ChatGPT app gives you direct access to Vantage, via the [Vantage MCP Server](/vantage_mcp), from ChatGPT. Instead of manually configuring an MCP server URL in another client, you can connect your Vantage account, add the app to a conversation, and begin asking questions or taking supported actions directly in ChatGPT.
The app uses your existing Vantage account for authentication and respects the same account and workspace access already available to that user.
ChatGPT
@Vantage give me a breakdown of my AWS costs by region for the past month
Here’s your AWS cost breakdown by region for last month:
📍 By Region (March 2026)
• us-west-1: 8,678.97
• us-east-2: 8,674.81
• eu-west-2: 8,173.95
• us-west-2: 8,107.17
• us-east-1: 7,807.88
• eu-west-1: 7,750.83
If you want to connect Vantage to other AI clients, such as Claude, Cursor, Goose, or Codex, see [Vantage MCP](/vantage_mcp).
## Install the Vantage ChatGPT App
Navigate to the [Vantage ChatGPT app](https://chatgpt.com/apps/vantage/asdk_app_694462199dd48191bedf3493b499d605) listing in ChatGPT and click **Connect**.
Complete the Vantage authorization flow when prompted. Sign in with your Vantage account and approve access.
In ChatGPT, click the **+** button in the chat box, select **More**, and choose **Vantage** to add it to your conversation.
Ask a question like, *"Which workspaces do I have access to in Vantage?"* or *"What were our AWS costs last month?"* ChatGPT will use the Vantage MCP tools behind the scenes to return account-scoped answers and perform supported actions.
For prompting ideas and best practices, see the [FinOps AI Prompt Guide](/guides/finops_ai_prompt_guide).
## What You Can Do
Version `2.0.0` of the Vantage ChatGPT app supports a broad set of Vantage workflows for both read and write use cases, mirroring the capabilities of the [Vantage MCP](/vantage_mcp#vantage-mcp-tools).
* **Read workflows** include querying cloud costs and Cost Reports (including costs, spending forecasts, and unit costs), Canvases, Dashboards, Folders, budgets, Cost Alerts and alert events, anomalies, cost recommendations and their affected resources, Recommendation Views, Financial Commitment Reports, Resource Reports, provider resources, Business Metrics and their historical and forecasted values, [billing rules](/partners#billing-rules) ([Vantage for MSPs](/partners) only), tags, report notifications, cost provider integrations and accounts, workspaces, teams, users, and Audit Logs.
* **Write workflows** include creating, updating, and deleting budgets, Cost Alerts, Cost Reports, Dashboards, Folders, [billing rules](/partners#billing-rules) ([Vantage for MSPs](/partners) only), Financial Commitment Reports, Recommendation Views, Report Notifications, Resource Reports, and Canvases; creating and updating Workspaces; creating Virtual Tag Configs; and updating anomaly status.
* **Account-scoped context** includes workspace access, default workspace information, and other account-scoped metadata needed to answer questions accurately and take supported actions in the right context.
## Privacy and Permissions
The Vantage ChatGPT app uses your existing Vantage account for authentication. It respects the same Vantage account and workspace permissions that apply in the Vantage console and APIs. If a user does not have access to a given workspace, report, alert, or other resource in Vantage, the app should not be able to access it on that user's behalf.
Prompts are handled in the AI client environment, while Vantage receives the underlying API calls needed to fulfill the request. For more information, see the [Privacy Policy](https://www.vantage.sh/legal/privacy-policy) and [Service Agreement](https://www.vantage.sh/legal/service-agreement).
# Cloudflare AI Gateway Enrichment
Source: https://docs.vantage.sh/cloudflare_ai_gateway_enrichment
Attribute LLM spend to teams, users, applications, and features by reading your encrypted Cloudflare AI Gateway Logpush logs from an S3 bucket that Vantage joins to your provider costs.
Contact Sales (or [support@vantage.sh](mailto:support@vantage.sh)/your account team) to enable LLM Enrichment for your account and discuss availability.
Vantage reads your encrypted [Cloudflare AI Gateway](https://developers.cloudflare.com/ai-gateway/) Logpush logs from an S3 bucket and joins them to your model-provider costs. Each log record describes one request the gateway proxied: the upstream provider, model, token counts, and any custom metadata you attach. Vantage splits each matching cost row into enriched rows by token share and adds tags derived from your metadata, so you can filter and group that spend in [Cost Reports](/cost_reports), [Virtual Tags](/tagging), [Budgets](/budgets), and [Cost Alerts](/cost_alerts). Because the telemetry comes from your gateway, this surfaces attribution the provider bill never itemized, even when many applications share one API key.
Cloudflare AI Gateway enriches costs for the model providers your gateway proxies: **OpenAI**, **Anthropic**, **Amazon Bedrock**, **Azure OpenAI**, **Google Vertex AI**, **Google AI Studio**, **Cloudflare Workers AI**, **xAI**, **ElevenLabs**, and **Baseten**. Vantage automatically routes each log record to the matching provider's costs.
This integration enriches the costs of the **downstream model providers** your gateway proxies. It is not the same as the [Cloudflare cost integration](/connecting_cloudflare), which imports Cloudflare's own billing. You do not need a Cloudflare cost integration to use enrichment.
Enrichment is metadata-only. To read the provider, model, token counts, and the custom metadata you emit, Vantage transiently decrypts each record's encrypted fields (including the request and response bodies) in memory, but it extracts only those values. Vantage does not store your prompt or completion content, and it is never written to a Vantage-owned artifact. This data is not used to train any models.
## How It Works
Cloudflare AI Gateway writes one encrypted Logpush record per request to an S3 bucket you own. Vantage decrypts those records with the private key you provide, normalizes them into a common usage index, and joins that index to your provider costs during each provider's cost ingestion.
See [How LLM Enrichment works](/llm_enrichment#how-it-works) for the shared indexing, join, split, and tag pipeline.
### How Cost Rows Are Split
Vantage splits each matching provider cost row into enriched rows, allocated proportionally by token share. Splits are additive, so the enriched rows always reconcile to the original total: usage your logs do not cover stays on a **leftover** row, and cost rows with no matching usage pass through unsplit. Enabling enrichment never changes your totals.
See the allocation formula, a worked example, and how leftover rows keep totals reconciled.
### Data Freshness and Backfill
Enrichment runs as part of each provider's existing cost ingestion, so it follows that provider's refresh cadence. Recent days are reprocessed within a rolling three-day window so late-arriving logs are picked up. See the [provider data refresh documentation](/provider_data_refresh) for per-provider timing.
A billing period is enriched whenever it is processed while an active source exists, for as long as the matching logs remain in your bucket. Late-arriving logs for recent days are picked up automatically within the rolling three-day window. For older periods, Vantage re-enriches a day when the set of log objects for that day changes (files are added or removed) or when a full rebuild is triggered; replacing the contents of an existing object under the same key does not, on its own, re-trigger enrichment. Re-enrichment reads the already-normalized cost data, so it does not require a full cost re-import.
## Prerequisites
Before you begin, make sure:
* An active cost integration exists for at least one supported provider: [OpenAI](/connecting_openai), [Anthropic](/connecting_anthropic), or [Azure](/connecting_azure).
* An active [AWS integration](/connecting_aws) (cross-account IAM role) exists for the account that owns the S3 bucket. Vantage reads the bucket through this role, so it is required even when the model-provider costs you enrich are not themselves on AWS.
* Cloudflare AI Gateway **Workers Logpush** is available to you (it requires the Workers Paid plan), and logging is enabled on the gateway whose traffic you want to attribute.
* You have an S3 bucket you own where Cloudflare AI Gateway delivers (or will deliver) your Logpush logs.
* You have an RSA key pair for [Workers Logpush encryption](https://developers.cloudflare.com/ai-gateway/observability/logging/logpush/): the public key is uploaded to your AI Gateway settings, and you have the matching PEM-encoded private key to provide to Vantage.
* You have a Vantage **Organization Owner** or **Integration Owner** role. See [Role-Based Access Control](/rbac).
## Set Up Cloudflare AI Gateway Enrichment
Setup has two steps: [configure Cloudflare AI Gateway Logpush to your S3 bucket](#step-1-configure-cloudflare-ai-gateway-logpush) and [connect the source in Vantage](#step-2-connect-the-source-in-vantage), where you select the bucket, provide your decryption key, grant Vantage read access, and then review which providers Vantage detected.
### Step 1: Configure Cloudflare AI Gateway Logpush
In Cloudflare, turn on logging for the gateway, then create a [Logpush job](https://developers.cloudflare.com/ai-gateway/observability/logging/logpush/) for your AI Gateway that delivers logs to your S3 bucket. When you create the job, select the **AI Gateway** dataset so Vantage receives gateway logs rather than another log type.
* **Destination:** point the job at the S3 bucket you own, and enable **[Organize logs into daily subfolders](https://developers.cloudflare.com/logs/logpush/logpush-job/enable-destinations/aws-s3/)** in the destination setup (or include `{DATE}` in the destination path if you configure the job through the API). This produces the day-partitioned path Vantage requires; without it, Vantage cannot discover your logs. Vantage expects the day partition and gzip log objects at the end of the path:
```text theme={null}
s3:////YYYYMMDD/*.log.gz
```
* **Timestamp format:** in the Logpush job's advanced options, keep the timestamp format as **RFC3339** (the default). **Unix** (epoch seconds) is also accepted, but do **not** use **UnixNano**. Vantage reads those values as seconds, which produces invalid dates, so those records will not be enriched.
* **Encryption:** generate an RSA key pair and upload the public key to your AI Gateway settings, as described in [Workers Logpush](https://developers.cloudflare.com/ai-gateway/observability/logging/logpush/). Uploading the public key is what enables Workers Logpush; Cloudflare then encrypts the `Metadata`, `RequestBody`, and `ResponseBody` fields of each record, and Vantage decrypts them with the private key you provide in Step 2. The private key is required.
* **Custom metadata:** attach [custom metadata](https://developers.cloudflare.com/ai-gateway/observability/custom-metadata/) to your gateway requests to drive allocation. Cloudflare saves up to five metadata entries per request (extra entries are dropped), accepts only string, number, and boolean values, and reserves keys beginning with `cf.`. Each saved entry that Vantage considers safe becomes a tag on the enriched costs (see the [Enrichment Tag Reference](#enrichment-tag-reference)). Prefer stable keys with a limited set of values, such as `team`, `environment`, and `purpose`.
Each S3 object is a gzip-compressed file of newline-delimited JSON records. A single record has plaintext gateway fields plus encrypted body fields:
```json theme={null}
{
"Provider": "openai", // upstream provider proxied by the gateway
"Model": "gpt-5.2-2025-12-11", // model as reported by the provider
"Gateway": "my-gateway", // gateway name
"Endpoint": "responses", // API path the request used
"Cached": false, // whether the gateway served a cached response
"RateLimited": false, // whether the request was rate limited
"StatusCode": 200, // upstream HTTP status
"Metadata": { "type": "encrypted", "key": "...", "iv": "...", "data": "..." },
"RequestBody": { "type": "encrypted", "key": "...", "iv": "...", "data": "..." },
"ResponseBody": { "type": "encrypted", "key": "...", "iv": "...", "data": "..." }
}
```
After Vantage decrypts the record, it reads the following from each field. Vantage reads only the values below; prompt and completion content are never stored.
| Field | What Vantage reads |
| - | - |
| `Provider` | The upstream provider that handled the request. Cloudflare sets this automatically; you do not control it. Vantage routes each record to the matching provider's costs when the provider is supported. |
| `Model` / `ResponseBody.model` / `RequestBody.model` | The model identifier as reported by the provider. Vantage uses the first non-blank value as the default join key against your provider cost data. |
| `ResponseBody.usage` | Token counts for the request: `input_tokens`, `output_tokens`, `cache_read_input_tokens`, and `cache_write_input_tokens`, plus optional `uncached_input_tokens` (Vantage also reads `input_tokens_details.cached_tokens` for cached input). At least one count must be a positive integer for the record to be used. |
| `ResponseBody.id` | The provider request identifier, used to deduplicate records. When absent, Vantage derives a stable fingerprint from the request ID, timestamp, model, endpoint, and usage. |
| `Metadata.timestamp` / `ResponseBody.created_at` / `Timestamp` / object key | The request time, which determines the billing day the record joins to. Vantage uses the first available value, in that order, falling back to a timestamp embedded in the object key. |
| `Metadata.resourceAccountId` (or `resource_account_id`) | The provider account that generated the usage. Set it when one bucket carries logs for multiple integrations of the same provider so Vantage matches each request to the correct costs. |
| `Metadata` (other keys) | Your custom metadata, turned into allocation tags. |
| `Metadata.providerRegion` / `region`, `serviceTier`, `ResponseBody.service_tier` | Region and service tier, used to match and allocate costs and available as grouping dimensions. Vantage does not infer batch processing from the request body, so set `serviceTier` to `batch` if your gateway does not already report it and you need batch usage kept separate. |
| `Gateway`, `Endpoint`, `Cached`, `RateLimited` | Gateway request context. `Gateway`, `Cached`, and `RateLimited` are added as tags; `Endpoint` is promoted to `vntg:ai:endpoint`. |
| `StatusCode`, `ResponseBody.error`, `RateLimited` | Used to determine whether the request succeeded. Non-successful requests are skipped. |
Vantage normalizes model identifiers on both sides so gateway logs and provider billing join even when they differ. For example, OpenAI billing always uses dated model names (`gpt-5.2-2025-12-11`) while your gateway logs may use dated or undated names (`gpt-5.2`); Vantage prefers the dated form and normalizes undated names to match.
Never include API key values, credentials, secrets, or other sensitive authentication material in custom metadata. Prefer keeping request-scoped identifiers out of metadata as well. Request identifiers and `resourceAccountId` / `resource_account_id` are never turned into tags, and high-cardinality keys make reports harder to use.
### Step 2: Connect the Source in Vantage
In Vantage, go to the [Integrations page](https://console.vantage.sh/settings/integrations). Under **LLM Enrichment**, add **Cloudflare AI Gateway**, then select the S3 bucket (or buckets) that hold your Logpush logs and paste your decryption key. The connect screen walks you through granting read access and validating it, and connecting then scans your recent logs so you can review which providers were found.
Connecting reuses your existing [AWS cross-account IAM role](/connecting_aws#how-vantage-connects-with-aws), adding read-only access to the bucket that holds your logs. It does not create a new role or require new credentials.
You can connect one or more buckets per account. After you connect a bucket, Vantage scans your recent logs and you choose which of your supported provider cost integrations should receive enrichment from that bucket; you can change that selection later from the source's **Manage** tab. Provider cost integrations you connect *after* setting up a source are not enriched automatically; open the source's **Manage** tab and enable the new integration there.
Select the S3 bucket (or buckets) that receive your Logpush logs, and paste the PEM-encoded private key that matches the public key you configured in Cloudflare. Vantage uses this key only to decrypt your records; it does not decrypt without it.
There is no prefix field to fill in: Vantage discovers the log path from where your objects actually live. To narrow where Vantage looks (for example, if the permission check reports too many objects), point the Logpush job at a dedicated bucket or a more specific destination path rather than sharing the bucket with unrelated data.
If your bucket does not appear in the list, it may not be synced into Vantage's inventory yet. Newly created buckets can take up to 24 hours to appear.
Deploy in the **AWS account that owns the bucket**, and make sure the bucket ARN in the policy matches the bucket you connect in Vantage. A mismatch is the most common cause of an `access denied` result when you check permissions.
The connect screen offers three ways to grant access, each prefilled for your account.
The connect screen provides a CloudFormation quick-create link that opens the AWS Console with the stack name, template URL, and parameters prefilled. Acknowledge that CloudFormation may create IAM resources, then create the stack.
The stack applies the [Vantage-published template](https://vantage-public.s3.amazonaws.com/vantage-integration-custom-llm-enrichment.json) with two parameters:
* `VantageCrossAccountRole`: the name of your existing Vantage cross-account IAM role.
* `CustomLlmEnrichmentBuckets`: a comma-separated list of bucket ARNs, each as `arn:aws:s3:::your-bucket/*`.
Deploy the stack in the account that owns the bucket, not necessarily your management/payer account.
The connect screen provides a ready-to-run `aws cloudformation create-stack` command using the same template and parameters as the Console method:
```bash theme={null}
aws cloudformation create-stack \
--stack-name CustomLLMEnrichmentSourceAccess- \
--template-url https://vantage-public.s3.amazonaws.com/vantage-integration-custom-llm-enrichment.json \
--capabilities CAPABILITY_IAM \
--region us-east-1 \
--parameters \
ParameterKey=VantageCrossAccountRole,ParameterValue= \
ParameterKey=CustomLlmEnrichmentBuckets,ParameterValue=arn:aws:s3:::your-bucket/*
```
Run the command with credentials for the AWS account that owns the bucket. For multiple buckets, pass a comma-separated list of ARNs as a single `ParameterValue`.
If you manage your Vantage integration with the [`vantage-sh/vantage-integration/aws`](https://registry.terraform.io/modules/vantage-sh/vantage-integration/aws/latest) module, add the log read permissions through the module's `additional_inline_policies` argument:
```hcl main.tf theme={null}
module "vantage-integration" {
source = "vantage-sh/vantage-integration/aws"
additional_inline_policies = [
{
name = "CustomLLMEnrichmentSource-"
policy = jsonencode({
Version = "2012-10-17",
Statement = [
{
Action = ["s3:GetObject", "s3:GetObjectAcl"],
Resource = ["arn:aws:s3:::your-bucket/*"],
Effect = "Allow"
}
]
})
}
]
}
```
This attaches the policy to your existing cross-account role; it does not create a new role. Bucket listing and location come from the base role, so only object read is added here. See the [Terraform documentation](/terraform#vantage-terraform-integrations-module-for-aws) for base module setup.
Whichever method you use, Vantage needs the following read-only access to validate and ingest logs:
| Permission | When it is needed |
| - | - |
| `s3:GetObject` | Read the log objects in the bucket you connect. |
| `s3:ListBucket` | List objects under the log path to find your logs. |
| `s3:GetBucketLocation` | Resolve the bucket's Region. |
| `kms:Decrypt` | The bucket or objects are encrypted with AWS KMS (SSE-KMS). Without it, Vantage cannot read KMS-encrypted objects. |
Your existing Vantage cross-account role already grants `s3:ListBucket` and `s3:GetBucketLocation`. The grant above adds only object read on the log bucket (`s3:GetObject`, and the generated policy always includes `s3:GetObjectAcl`).
The CloudFormation, CLI, and Terraform options above grant S3 read access only. If your log bucket uses SSE-KMS encryption, you must grant `kms:Decrypt` separately. See [KMS-Encrypted Buckets](#kms-encrypted-buckets). This is separate from Cloudflare Logpush log encryption, which Vantage handles with the private key you provide.
Click **Check Permissions**. Vantage validates that it can resolve the bucket Region, list objects, and read a sample object, and that your private key can decrypt a sample log record. Blocking problems (for example, objects that are not under the `YYYYMMDD/*.log.gz` layout, or a private key that cannot decrypt the sample) are shown as errors you must resolve before connecting. If the bucket doesn't contain any logs yet, you can still connect: Vantage shows a notice that the bucket looks empty and runs the sample-object and decryption checks once logs arrive. Then click **Connect**. Vantage confirms the source and immediately scans your recent gateway logs, from the first day of the previous calendar month through today, to detect which providers and provider accounts appear in the bucket. You are taken to a **Scanning gateway logs** page that refreshes on its own; a large bucket can take several minutes.
A success message confirms the source is connected and scanning has begun. When the scan finishes, a **Review** action appears for the source. See the [Troubleshooting](#troubleshooting) section for any errors that are displayed.
When the scan finishes, select **Review** for the source. This opens the **Manage** tab of the source's details page. The review screen has one row per enrichable connected cost integration, grouped by provider, and shows each row's **Valid rows** and **Invalid rows** counts. Providers found in your logs that you have not connected a cost integration for appear as non-selectable rows. The **Notes** column shows **Success** when rows were found, **No rows found** when none were, and flags such as gateway logs missing `resource_account_id` (the `Metadata.resourceAccountId` value after decryption) or **Account identifiers not found: …** when account IDs could not be matched to a cost integration. Logs found for unsupported providers appear in a separate banner, not the Notes column. If more than 75% of the scanned rows failed validation, a warning ("N% of scanned log rows failed validation") suggests confirming that your objects use the expected `YYYYMMDD/*.log.gz` format and contain provider, model, usage, and status data.
Choose which connected cost integrations should receive token enrichment from this bucket, then select **Confirm**. Vantage enriches costs for the selected integrations on each provider's next data refresh. You can change the selection later from the source's **Manage** tab.
## Manage Cloudflare AI Gateway Enrichment Sources
Manage your connected buckets from the **Cloudflare AI Gateway** integration page. The sources table lists each bucket with its AWS account, creation date, and **Status** (for example, **Pending** before an import starts, **Importing** while one runs, **Stable** once all imports succeed, **Warning** if only some imports fail, **Error** if a scan or all imports fail, or **Paused** if the source is stopped). A shared-bucket warning icon appears next to the bucket name when sibling integrations require `resourceAccountId`; error details appear beneath the status.
Select the **bucket name** to open that source's details page, which has two tabs:
* **Import History**, the default tab, shows every enrichment run for the source. See [View Import History](#view-import-history).
* **Manage** is where you choose which cost integrations receive enrichment. See [Choose Which Integrations Are Enriched](#choose-which-integrations-are-enriched).
A **Review** button appears in the row while scan results are waiting on your confirmation, and a **Resume** button appears for stopped sources; both open the **Manage** tab. The row's ellipses (**...**) menu contains **Stop** for sources that are not paused.
### Choose Which Integrations Are Enriched
After a scan finishes, select **Review** on the source to choose which connected cost integrations receive enrichment (see [Step 2](#step-2-connect-the-source-in-vantage)). To change that selection later, select the bucket name and open the **Manage** tab. The Manage tab lists each provider integration with its import status (for example, **Stable**, **Pending**, **Importing**, **Warning**, **Error**, **Paused**, or **Unenriched**), and for a provider with multiple accounts shows a count like *2 of 3 accounts enabled*. It lets you enable or disable enrichment per integration. Disabling an integration here stops going-forward enrichment for it but leaves its existing enriched history in place.
### View Import History
In the sources table, select the **bucket name** to open that source's details page, which shows the **Enrichment Runs** table for that bucket.
The **Enrichment Runs** table lists one row per provider cost integration and billing period that ran enrichment, newest first, with columns for the **Integration** (and its account), **Status**, **Tokens Kept**, **Log Lines Kept**, **Bill Match**, **Billing Period**, and **Last Enriched At**. Lifecycle changes appear as their own rows: **Added** when enrichment is first enabled for an integration, and **Paused** or **Resumed** when you stop, disable, resume, or re-enable it.
The three percentages look similar but measure different things at different stages, so a low number in one column means something very different from a low number in another:
| Metric | Stage | Counts | A Low Value Means |
| - | - | - | - |
| **Tokens Kept** | Join | Tokens | Your logs were read fine, but the usage in them did not line up with your provider bill. |
| **Log Lines Kept** | Log Scan | Log lines | Vantage could not read or index many of your log lines, usually because records are malformed or missing required fields. |
| **Bill Match** | Join | Provider cost rows | Many provider cost rows received no logged usage at all, so they passed through unsplit. Often your logs cover only part of your traffic. |
A low percentage does not change your totals. Usage Vantage cannot attribute stays on a **leftover** row, the unallocated remainder of the original cost row, so the enriched rows always add back up to what the provider billed.
Select the **Tokens Kept** percentage on any run to open **Token Metrics**, which breaks that run down by disposition across the two stages and lets you view sample records for anything that did not make it through.
Full reference for the Import History screen: every column and status, how to read the three percentages, the Log Scan and Join dispositions with a fix for each, sample record fields, and a troubleshooting table.
### Stop a Source
To stop a source, click the ellipses (**...**) next to the row and select **Stop**, then confirm in the **Stop enrichment source** dialog. This is a soft deactivation, not a hard delete: Vantage stops enriching new cost data for that bucket, but your existing enriched history is left unchanged, and the source stays visible in the list so you can bring it back at any time.
Stopping a source does not re-import or roll back already-enriched costs. Going-forward enrichment simply pauses for that bucket until you resume it.
### Resume a Source
To resume a stopped source, select **Resume** in its row. Resuming restarts going-forward enrichment for the integrations that were active when you stopped the source (integrations you had already disabled individually stay disabled) and opens the **Manage** tab so you can adjust the selection. A stopped bucket cannot be re-added through the connect wizard; use **Resume** instead.
## View Enriched Costs on Cost Reports
Once enrichment runs, a single provider cost line is split into multiple rows, each carrying enrichment tags. You can filter and group by these tags anywhere tags are supported: [Cost Reports](/cost_reports), [Virtual Tags](/tagging), [Budgets](/budgets), and [Cost Alerts](/cost_alerts).
Because enrichment splits (allocates) your provider costs, enrichment tags behave like Vantage's [cost allocation tags](/tagging#cost-allocation-tags): you can build a Virtual Tag on them, but a cost can be allocated only once, so an enrichment tag can belong to only [one allocation chain](/tagging#virtual-tag-allocation-rules).
### Enrichment Tag Reference
| Tag key | Description | Example value |
| - | - | - |
| *Your metadata keys* | Each safe scalar entry in a record's `Metadata` (Cloudflare saves up to five per request) becomes a tag on the enriched rows for that usage slice, with the key normalized to snake\_case. | `team`, `purpose`, `environment` |
| `gateway`, `cached`, `rate_limited` | Gateway request context promoted from the top-level `Gateway`, `Cached`, and `RateLimited` fields. (`Endpoint` becomes `vntg:ai:endpoint` instead of a bare `endpoint` tag.) | `gateway=my-gateway` |
| `vntg:ai:model` | The normalized model identifier that generated the cost, derived from the cost row. Vantage adds it to every enriched row. | `vntg:ai:model=gpt-5.2-2025-12-11` |
| `vntg:ai:model_provider` | The provider family inferred from the model (for example, OpenAI or Anthropic), added automatically alongside `vntg:ai:model` when the family is recognized. | `vntg:ai:model_provider=OpenAI` |
| `vntg:ai:token_type` | The token kind the enriched row covers: `input`, `output`, `cache_read`, or `cache_write`. Added automatically to every enriched row. | `vntg:ai:token_type=input` |
| `vntg:ai:service_tier`, `vntg:ai:provider_region`, `vntg:ai:endpoint` | Promoted from the matching log fields when present and renamed under the prefix, so you can group and allocate by them too. | `vntg:ai:service_tier=default` |
| *Provider's existing tags* | Any tags Vantage already puts on the provider's cost rows are preserved on the enriched rows. If one of these shares a key with a slice tag, the enrichment value wins. | — |
Your own metadata keys are normalized to snake\_case and, unless they are reserved, appear without a provider prefix. The fields Vantage derives and adds itself, such as the model identifier, carry a `vntg:ai:` prefix (for example, `vntg:ai:model`); this keeps them distinct from your keys and consistent with the AI tags Vantage applies to provider costs. Because a key like `team` is not provider-namespaced, it lines up across OpenAI, Anthropic, and Azure, so you can group your entire AI stack by one `team` tag.
Two normalization rules are worth knowing when you choose metadata key names:
* **Keys are lowercased and snake\_cased before they become tags.** So `userEmail`, `UserEmail`, and `user_email` all collapse to `user_email`, and any keys that normalize to the same string are merged into one tag.
* **Keys that normalize to a Vantage-managed name are re-emitted under `vntg:ai:` instead of staying bare.** Those names are `model`, `provider_region`, `service_tier`, `user_email`, `user_name`, `user_id`, `endpoint`, and `api_key_id` (and `resource_account_id` and `is_batch`, which are dropped rather than tagged). For example, the `user` key in the Use Cases table below stays bare as `user`, but a `userId` key would silently move to `vntg:ai:user_id`.
* **A metadata key can overwrite a gateway-context tag.** The `gateway`, `cached`, and `rate_limited` tags come from the top-level gateway fields, but a metadata key that normalizes to one of those names replaces the gateway-derived value. Avoid reusing those names in your metadata.
* **`Metadata.timestamp` does double duty.** It is used to pick the billing day and, because it is not a reserved key, also becomes a `timestamp` tag. Since a timestamp is high-cardinality, avoid emitting it as metadata unless you want it as a tag.
Enrichment tags behave like any other provider tag in the console:
* **To group:** open the **Group By** menu, select **Tag**, and choose the tag key, for example `vntg:ai:model`, or one of your own keys such as `team`.
* **To filter:** open the **Filters** menu, click **New Rule**, select **Tag**, choose the **Tag Key**, then pick an operator and one or more values.
The tag keys appear in the **Tag Key** dropdown once enriched costs exist. If you use a handful of keys often, mark them as [preferred tags](/tagging#preferred-tags) so they sort to the top of these menus.
Enriched rows retain the provider's existing tags and add the Vantage-managed `vntg:ai:*` tags (such as `vntg:ai:model`); split rows also carry the tags from their usage slice. When a slice tag and an existing tag use the same key, the enrichment value wins. The leftover row (usage not covered by logs) keeps the provider's existing tags and the applicable `vntg:ai:*` tags but carries none of the slice tags. Request identifiers and `resourceAccountId` are never turned into tags.
In the example below, a Cost Report splits OpenAI spend by the `team` and `purpose` metadata attached at the gateway, alongside `vntg:ai:model`, so the same model can be compared across teams and workloads. The chart legend also shows a **Not tagged with team - Not tagged with purpose** series: that is the leftover row described above, covering the portion of the bill your gateway logs did not account for.

## Troubleshooting
Most errors are displayed when you click **Check Permissions** or **Connect**. The tables below list the messages you may see, their cause, and how to resolve them. Expand a section for the relevant category.
| Message | Cause and fix |
| - | - |
| `Vantage cannot determine the location for bucket {bucket}. Grant s3:GetBucketLocation to the cross-account role.` | Add `s3:GetBucketLocation` to the cross-account role. |
| `Vantage cannot list objects under s3://{bucket}/{prefix}. Grant s3:ListBucket for the configured prefix.` | Add `s3:ListBucket` scoped to the bucket (and prefix, if used). |
| `Vantage cannot read object s3://{bucket}/{key}. Grant s3:GetObject to the cross-account role.` | Add `s3:GetObject` (and `s3:GetObjectAcl`) for the bucket. |
| `Vantage cannot decrypt KMS-encrypted object s3://{bucket}/{key}. Grant kms:Decrypt to the cross-account role.` | The bucket uses SSE-KMS. Grant `kms:Decrypt` for the encrypting key. |
| `Vantage could not assume the AWS cross-account role. Verify that the role exists, its trust policy allows Vantage to call sts:AssumeRole, and the configured external ID matches.` | Vantage cannot assume your [cross-account IAM role](/connecting_aws#how-vantage-connects-with-aws). Confirm the role still exists, its trust policy allows Vantage's `sts:AssumeRole`, and the external ID matches. |
Confirm the permissions were deployed in the **AWS account that owns the bucket**, and that the bucket ARN in the policy matches the connected bucket.
| Message | Cause and fix |
| - | - |
| `The uploaded private key could not decrypt the Cloudflare sample object.` | The private key does not match the public key configured for Logpush encryption in Cloudflare. Provide the private key that pairs with the configured public key. |
| `The Cloudflare sample object is not valid gzip JSON Lines.` | The sampled object is not gzip-compressed JSON Lines, or is not an encrypted Cloudflare Logpush file. Confirm the Logpush job writes `*.log.gz` objects. |
| `Vantage cannot read the Cloudflare sample object.` | Vantage could list the bucket but was denied reading the sample object. Confirm `s3:GetObject` (and `kms:Decrypt` for SSE-KMS) on the bucket. |
| `Cloudflare decryption private key ...` | The pasted value is not a valid PEM-encoded RSA private key. Paste the full PEM key, including the `BEGIN`/`END` lines. |
| Message | Cause and fix |
| - | - |
| `Bucket {bucket} does not exist or could not be found.` | The bucket does not exist or is not reachable by the role. Verify the name and account. |
| `No objects matching YYYYMMDD/*.log.gz were found in s3://{bucket}/{prefix}. Vantage expects files in that date layout.` | The bucket has no `.log.gz` objects under the expected `YYYYMMDD` path yet, or they use a different layout. Confirm the Logpush destination path, write a test record, and re-check. |
| `Vantage scanned 3000 objects in s3://{bucket}/{prefix} but could not find a matching log file. Use a dedicated bucket or a more specific prefix.` | Vantage scanned many objects without finding a matching log file. Point the source at a dedicated bucket or a more specific prefix so logs are found quickly. |
| `Permission check timed out. The bucket may be large, or logs may not use the expected date layout.` | The permission check did not finish in time. Narrow the source to a dedicated bucket or prefix, confirm the `YYYYMMDD/*.log.gz` layout, then re-check. |
| `Bucket {names} could not be found for your account.` | The selected bucket is not in Vantage's synced inventory. Newly created buckets can take up to 24 hours to appear. |
| `Bucket {name} is paused. Resume it from the table below instead of reconnecting.` | The bucket already has a stopped source. Use **Resume** in the sources table instead of connecting it again. |
| `Buckets cannot be configured more than once: {names}.` | You selected a bucket that is already connected as a source. Manage the existing source from the sources table instead. |
| `Connect an AWS, Anthropic, Azure, GCP, or OpenAI cost integration before connecting Cloudflare AI Gateway Enrichment.` | No enrichable cost integration exists. Connect a supported provider first. |
**Pending** means Vantage has not run an enrichment import for this source yet. Enrichment runs during each provider's regular cost ingestion, so a newly connected source shows **Pending** until the next data refresh of a provider it enriches. See the [provider data refresh documentation](/provider_data_refresh) for per-provider timing. If the status is still **Pending** after that refresh, check the following:
* If a **Review** button appears in the source's row, the scan finished and is waiting on you: select **Review**, choose the cost integrations to enrich, then select **Confirm** (see [Step 2](#step-2-connect-the-source-in-vantage)).
* If you already confirmed, open the source's **Manage** tab and confirm that at least one integration is enabled.
* Confirm your Logpush job is still delivering logs to the bucket under the `YYYYMMDD/*.log.gz` layout.
Enrichment can only split costs by dimensions present in your logs. Costs pass through without allocation splits when any of the following is true:
* There is no active Cloudflare AI Gateway source for the account, or the logs have not been ingested for that billing period.
* The cost row's model or token type could not be matched to a logged request for that provider, date, and token kind.
* Records were skipped during ingestion because the decrypted `Metadata` was missing or not an object, the `Provider` was blank or unsupported, the model was blank or could not be matched to your provider cost data, the request was not successful (a missing or empty response body, a non-2xx status, a rate-limited request, or a response error), or no usage value was a positive integer.
Confirm the request went to a supported provider, carries a matching model, and has at least one positive usage count.
Enrichment tags appear in the console as regular provider tags. To confirm what was enriched:
* **Check coverage in Import History:** Open the source's [Import History](/llm_enrichment_import_history) and review **Tokens Kept** (the share of your logged tokens Vantage attached to a cost row) and **Bill Match** (the share of eligible provider cost rows that received logged usage) for each integration and billing period.
* **Check a Cost Report:** Filter to the provider, then group by one of your own tag keys. Costs from requests that carried that key show its values. The leftover row (the portion of the bill your usage did not cover) and any usage sent without that key appear as **Not tagged with** the key name.
Totals should not change. Splits are additive and always sum to the original cost row to the cent, even when multiple sources are connected. If a total appears different, this is not expected behavior; contact [Vantage Support](mailto:support@vantage.sh).
### KMS-Encrypted Buckets
If the bucket you connect is encrypted with AWS Key Management Service (KMS), **Check Permissions** reports a decryption error until Vantage can read the objects. Either remove encryption on the bucket, or grant the cross-account role `kms:Decrypt` for the encrypting key and allow that role in the KMS key policy.
The CloudFormation, CLI, and Terraform options in [Step 2](#step-2-connect-the-source-in-vantage) grant S3 read access only, so KMS access must be added separately. This is distinct from Cloudflare Logpush log encryption, which Vantage handles with the private key you provide.
## Use Cases
Each row below shows example metadata to emit on your gateway requests and what that attribution enables in Vantage. The key names are examples; you choose your own, and Vantage surfaces whatever metadata you send. All rows assume logs are delivered to a connected bucket.
| Use Case | Emit in metadata | What It Enables |
| - | - | - |
| Chargeback by team | `team` | Group a [Cost Report](/cost_reports) by `team` for per-team LLM chargeback, or roll `team` values into a business hierarchy with a [Virtual Tag](/tagging). |
| Per-user attribution on shared keys | `user` | Attribute spend to the individual who made each request even when many callers share one API key, which the provider bill cannot break apart. |
| Per-feature or per-workflow spend | `feature`, `workflow` | Compare cost per product feature or workflow (for example, `summarization` vs. `classification`). |
| Model and effort mix | `mode`, `effort` | Spot macro patterns (which models and effort levels dominate spend) and outliers to guide defaults. The `vntg:ai:model` tag is added automatically, so you do not need to emit it. |
| Environment separation | `environment` | Filter non-production inference out of showback reports, or budget each environment (`production`, `staging`) separately. |
## Frequently Asked Questions
OpenAI, Anthropic, Amazon Bedrock, Azure OpenAI, Google Vertex AI, Google AI Studio, Cloudflare Workers AI, xAI, ElevenLabs, and Baseten. Azure support covers direct Azure integrations; Azure CSP billing accounts are not supported.
No. This integration enriches the costs of the model providers your gateway proxies, not Cloudflare's own billing. You only need a supported model-provider cost integration and an AWS integration for the account that owns the log bucket. The [Cloudflare cost integration](/connecting_cloudflare) is separate and optional.
Not for traffic captured by Cloudflare AI Gateway; native enrichment removes the need to transform those logs into the common schema yourself. [Custom LLM Enrichment](/custom_llm_enrichment) remains the right choice for non-Cloudflare sources, mixed pipelines, and teams that already emit the Token Cost Allocation Specification from their own collectors.
You need the **Organization Owner** or **Integration Owner** role to connect the source. Viewing the enriched costs does not require a special role; the resulting tags follow the same access rules as other cost data. See [Role-Based Access Control](/rbac).
Read-only access to the bucket you connect: `s3:GetObject`, `s3:ListBucket`, `s3:GetBucketLocation`, and `kms:Decrypt` for KMS-encrypted objects (generated policies may also include `s3:GetObjectAcl`). The policy attaches to your existing cross-account role; no new role is created. See [Step 2: Connect the Source in Vantage](#step-2-connect-the-source-in-vantage).
No. Vantage does not use a Cloudflare API token for this integration, does not modify your gateway configuration, and does not write to the connected S3 bucket; it only reads the encrypted log objects. This path is separate from the [Cloudflare cost integration](/connecting_cloudflare), which imports Cloudflare platform spend (such as Workers) through the Cloudflare API.
Cloudflare AI Gateway Logpush encrypts the `Metadata`, `RequestBody`, and `ResponseBody` fields of each record with your public key. Vantage decrypts those fields with the matching private key you provide so it can read the provider, model, token counts, and your custom metadata. The private key is stored securely and used only for decryption.
No. Splits are additive and always sum to the original cost row. Existing provider-level reports continue to show the same totals; enrichment only makes new dimensions available on the underlying rows.
No. Enrichment is metadata-only. To read request identifiers, the provider and model, usage counts, and the custom metadata you emit, Vantage transiently decrypts each record's encrypted fields (including the request and response bodies) in memory, but it extracts only those values. Prompt and completion text are never collected, stored, or written to a Vantage-owned artifact.
# Commitments
Source: https://docs.vantage.sh/commitments
View and manage your cloud provider financial commitments, such as Reserved Instances, Savings Plans, and committed use discounts.
The Commitments screen provides a centralized inventory of all your cloud financial commitments, including [Reserved Instances](https://handbook.vantage.sh/aws/concepts/reserved-instances/), [Savings Plans](https://handbook.vantage.sh/aws/concepts/savings-plans/), Google Cloud spend-based committed use discounts (CUDs), and contract commitments. You can view commitment details—such as status, type, term, and expiration—across AWS, Azure, GCP, and Vercel from a single table.
Use the Commitments screen to audit your current commitments, identify upcoming expirations, and understand your commitment portfolio before using other financial-planning workflows such as AWS [Financial Commitment Reports](/financial_commitment_reports) or AWS [Savings Planner](/savings_planner).
## Supported Providers
The Commitments screen automatically syncs and displays financial commitments from connected AWS, Azure, GCP, and Vercel integrations. The following commitment types are supported.
| Provider | Commitment Types |
| - | - |
| AWS | Savings Plans, Reserved Instances |
| Azure | Savings Plans, Reserved Instances |
| GCP | Spend-based Committed Use Discounts |
| Vercel | Contract Commitments |
For AWS, Reserved Instance commitments include service-specific commitments such as EC2, RDS, ElastiCache, OpenSearch, and Redshift Reserved Instances. AWS Savings Plans include Compute and EC2 Instance Savings Plans.
## Requirements
To view commitments on this screen, you need at least one of the following integrations:
* An [AWS integration](/connecting_aws) with access to **Savings Plans** and **Reserved Instances**.
* An [Azure integration](/connecting_azure) with the permissions described in [Optional Azure Reservations and Savings Plans](/connecting_azure#optional-azure-reservations-and-savings-plans).
* A [GCP integration](/connecting_gcp). Spend-based committed use discounts are read from the `cud_subscriptions_export` table in the connected BigQuery dataset. See [GCP](/commitments#gcp) for details.
* A [Vercel integration](/connecting_vercel) connected via the Vantage Vercel Community Integration.
Vantage automatically syncs your commitments once the integration is connected. Azure reservations and Savings Plans sync even when the workspace has only Azure commitments. GCP spend-based committed use discounts sync daily after the CUD metadata export table is available. If you don't see your commitments, ensure that your integration is properly configured and that Vantage has had time to complete the initial sync.
The Commitments screen supports AWS, Azure, GCP, and Vercel. [Financial Commitment Reports](/financial_commitment_reports) and [Savings Planner](/savings_planner) are currently AWS-only.
## View Commitments
From the top navigation, click **Financial Planning**.
On the left navigation, click **Commitments**. A table of all your financial commitments is displayed. By default, commitments are sorted by **Status** so that active commitments appear first.
### Commitment Table Columns
The table displays the following columns for each commitment.
| Column | Description |
| - | - |
| **Provider** | The cloud provider icon (e.g., AWS, Azure, GCP, or Vercel). |
| **Status** | The current status of the commitment: **Active**, **Pending**, or **Retired**. For GCP, active commitments are shown as **Active** and expired commitments as **Retired**. Pending Google Cloud commitments are not synced. |
| **Type** | The commitment type: **Savings Plan**, **Reserved Instance**, **Committed Use Discount** (for GCP), or **Commitment** (for Vercel contracts). |
| **Service** | The service the commitment covers (e.g., Compute, EC2, RDS). For AWS Savings Plans, this is the coverage type, such as Compute or EC2. For AWS Reserved Instances, the specific service is displayed, such as EC2, RDS, or ElastiCache. For GCP spend-based committed use discounts, this is the committed product, with a trailing `CUD` or `CUD - N Year` suffix removed (for example, Cloud SQL). For Vercel, this is displayed as **Vercel**. |
| **Account** | The account name associated with the commitment, displayed with a provider icon. For GCP, this is the billing account ID. |
| **Description** | Additional details, such as the instance type for Reserved Instances. |
| **Instance Count** | The number of instances covered by the commitment. This field applies to Reserved Instances and is empty for GCP committed use discounts. |
| **Term** | The commitment term length, in years (e.g., 1 or 3). |
| **Payment Type** | The payment option for the commitment (e.g., No Upfront, Partial Upfront, or All Upfront). For GCP spend-based committed use discounts, this is **Hourly**. |
| **Region** | The region associated with the commitment, if applicable. |
| **Purchase Date** | The date the commitment was purchased. |
| **Expiration Date** | The date the commitment expires. |
| **Commitment** | The commitment amount, in dollars. For AWS and Azure Savings Plans, and for GCP spend-based committed use discounts, this is the hourly commitment rate. Monthly GCP amounts (`$/mo`) are converted to an hourly rate using 730 hours per month. For Vercel, this is the total contract commitment cost. |
| **Commitment Cost** | The total cost over the commitment's full term, calculated as the hourly rate multiplied by the number of hours in the term. For example, a $10/hr one-year commitment shows $87,600. This calculation also applies to GCP spend-based committed use discounts. |
#### FOCUS 1.3 Columns
The following columns are aligned with the [FOCUS 1.3](https://focus.finops.org/) specification for representing commitment data in a standardized format. These columns are hidden by default. To display them, click **Manage Columns** and toggle the columns you want to show.
| Column | Description |
| - | - |
| **Billing Currency** | The currency used for billing the commitment (e.g., USD). For AWS and GCP commitments, this defaults to USD. |
| **Contract Commitment Category** | The category of the commitment. Savings Plans are categorized as **Spend**, and Reserved Instances are categorized as **Usage**. This column is empty for GCP committed use discounts. |
| **Contract Commitment ID** | A unique identifier for the commitment, derived from the commitment ARN or contract ID. For GCP, this is the subscription instance ID. |
| **Contract Commitment Quantity** | The committed quantity. For Savings Plans, this is the hourly dollar commitment. For Reserved Instances, this is the instance count. This column is empty for GCP committed use discounts. |
| **Contract Commitment Unit** | The unit of measurement for the commitment quantity: **Dollars** for Savings Plans or **Instances** for Reserved Instances. This column is empty for GCP committed use discounts. |
| **Contract ID** | The contract identifier associated with the commitment. |
| **Contract Period Start** | The start date of the commitment contract period. |
| **Contract Period End** | The end date of the commitment contract period. |
### Filter Commitments
Use the filter bar above the table to narrow down commitments. The following filters are available:
| Filter | Description |
| - | - |
| **Status** | Filter by **Pending** (purchased but not yet active), **Active** (currently in effect), or **Retired** (expired or cancelled). All statuses are shown by default. |
| **Provider** | Filter by cloud provider (e.g., AWS, Azure, GCP, Vercel). |
| **Commitment Type** | Filter by **Savings Plan** or **Reserved Instance**. GCP committed use discounts are included when you filter **Provider** to **GCP**. |
| **Service** | Filter by the service or coverage type (e.g., Compute, EC2, RDS). Options are dynamically populated based on your commitments. |
| **Account** | Filter by account name. For GCP, filter by billing account ID. |
| **Term** | Filter by commitment term length (e.g., 1 Year, 3 Year). |
| **Payment Type** | Filter by payment option (e.g., No Upfront, Partial Upfront, All Upfront, or Hourly). |
| **Region** | Filter by the region associated with the commitment. |
You can combine multiple filters to narrow results. For example, filter by **Active** status, **Savings Plan** type, and a specific **Account** to see only active Savings Plans for a particular account.
### Customize Columns
To show or hide columns, click the column selector icon on the top right of the table (i.e., click **Manage Columns**). Toggle the columns you want to display. Column preferences apply to your current session. FOCUS 1.3 columns are hidden by default and can be enabled from this menu.
## Export Commitments
You can export your commitments as a CSV file. The export respects any active filters and includes only the columns currently visible in the table.
From the top right of the Commitments table, click the download icon.
The **Export Commitments** modal is displayed. Select one or more email recipients from the list of Vantage users in your organization.
Click **Export**. A CSV is generated and emailed to the selected recipients with a download link. It may take a few minutes for the email to be sent.
To include FOCUS 1.3 columns in your export, enable them via **Manage Columns** before exporting. Only visible columns are included in the CSV.
## Provider-Specific Details
### AWS
Vantage syncs the following commitment types from AWS:
* **Savings Plans**: Including Compute Savings Plans and EC2 Instance Savings Plans. Savings Plans provide flexible pricing in exchange for a commitment to a consistent amount of usage (measured in dollars per hour) for a one- or three-year term.
* **Reserved Instances**: Including EC2, RDS, ElastiCache, OpenSearch, and Redshift Reserved Instances. Reserved Instances provide a discount compared to On-Demand pricing in exchange for a commitment to use a specific instance type in a specific region for a one- or three-year term.
For a detailed overview of the differences between AWS Savings Plans and Reserved Instances, see the [Vantage Cloud Cost Handbook](https://handbook.vantage.sh/aws/concepts/savings-plans/).
### Azure
Vantage syncs the following commitment types from Azure:
* **Savings Plans**: Azure Savings Plans provide discounted rates on compute usage in exchange for committing to spend a fixed hourly amount for one or three years.
* **Reserved Instances**: Azure Reservations provide discounted rates by committing to one- or three-year plans for multiple products, including virtual machines, storage, and databases.
To sync Azure commitments to this page, complete the additional permission steps in [Optional Azure Reservations and Savings Plans](/connecting_azure#optional-azure-reservations-and-savings-plans).
If your Azure integrations are missing the required Reservations Reader or Savings Plan Reader RBAC scopes, a warning banner is displayed at the top of the Commitments page with a link to the configuration steps.
### GCP
Vantage syncs spend-based committed use discounts (CUDs) from Google Cloud. These commitments provide discounted rates in exchange for committing to a consistent amount of spend for a one- or three-year term. Resource-based CUDs are not included. The commitment type is displayed as **Committed Use Discount** in the table.
Vantage syncs these commitments daily from the latest snapshot of the `cud_subscriptions_export` table in the BigQuery dataset connected to your [GCP integration](/connecting_gcp). Enable Google's [Committed use discounts (CUD) metadata export](https://docs.cloud.google.com/billing/docs/how-to/export-data-bigquery-setup) so that table is available. If the table is missing, GCP commitments are not synced.
Active commitments are shown as **Active**. Expired commitments are shown as **Retired**. Pending Google Cloud commitments are not synced.
If your commitments are stored in a different table than `cud_subscriptions_export`, contact [support@vantage.sh](mailto:support@vantage.sh).
### Vercel
Vantage syncs contract commitments from Vercel. These commitments represent contractual agreements between your organization and Vercel, typically associated with Enterprise or Pro plans. Vercel contract commitments are synced daily and include details such as the commitment amount, term, and status. The commitment type is displayed as **Commitment** in the table.
## Example Workflow: Audit, Analyze, and Optimize
The Commitments screen is a starting point for understanding your commitment portfolio. From there, you can use other Financial Planning features to analyze the cost impact of those commitments and plan future purchases. The following workflow walks through a typical example.
Start on the **Commitments** screen. Filter by **Status** to see only **Active** commitments. Review the list to understand what you currently have in place—note the services covered, terms, expiration dates, and hourly commitment amounts. Then, filter for **Retired** commitments to see which commitments have recently expired and may need to be renewed.
Since the table is sorted by **Status** by default (with active commitments first), look for active commitments that are expiring soon. These represent potential gaps in coverage that could lead to increased On-Demand spend if not renewed or replaced.
If you use AWS, navigate to **[Financial Commitment Reports](/financial_commitment_reports)** to see the actual cost impact of your commitments. Create a report to review your **coverage** (how much of your On-Demand usage is offset by commitments) and **effective savings rate** (the overall discount you're achieving). Use the **Group By** options to break down costs by commitment type, service, or account to identify where coverage is strong and where gaps exist.
If you use AWS and your coverage is low or commitments are expiring, navigate to **[Savings Planner](/savings_planner)** and create a savings model. The Savings Planner shows your on-demand vs. committed spend over the past six months, with projections for the next 12 months. Add potential Savings Plans with different hourly commitments, terms, and payment types to see how each option would affect your future coverage and savings.
Check **[Cost Recommendations](/cost_recommendations)** for Vantage-generated suggestions on new Reserved Instance or Savings Plan purchases based on your actual usage patterns. You can also use **[Autopilot](/autopilot)** to automate Savings Plan purchases.
# Anthropic
Source: https://docs.vantage.sh/connecting_anthropic
Connect Anthropic to Vantage to track Claude cost and usage from both the Claude API and Claude.ai.
Vantage ingests Anthropic cost and usage data from two independent data sources. You can connect either source on its own or connect both for a complete view of your Anthropic spend:
* **Claude API**: programmatic Claude usage accessed through the Claude API (`api.anthropic.com`), broken down by operation (e.g., Input Token Cache Writes or Output Tokens) and model (e.g., Claude Sonnet 4). Connected with an **Admin API key**.
* **Claude.ai**: Claude.ai product usage, including Claude Chat, Claude Code, Claude Cowork, Office Agents, Claude in Chrome, and Claude Design. Connected with a **Claude Enterprise Analytics API key**.
[Usage data](/usage_based_reporting) is available for both data sources, measured in tokens. When both are connected, Vantage tags every row with an `anthropic:billing_source` value (`admin` or `analytics`) so you can filter, group, and allocate costs by data source. See [Anthropic Reporting Dimensions](#anthropic-reporting-dimensions) for details.
To attribute Anthropic spend to teams, users, applications, and features by your own per-request dimensions, see [Custom LLM Enrichment](/custom_llm_enrichment), which joins per-request token telemetry you deliver to S3 with your Anthropic costs.
**Limitations:**
* This integration supports only usage and cost data exposed through Anthropic's own APIs. It does not support Claude hosted on other clouds, such as Amazon Bedrock (see [AWS Bedrock LLM Enrichment](/aws_bedrock_enrichment)) or Google Cloud Vertex AI. Claude.ai consumer (Pro) and Team plans are not supported by the Claude Enterprise Analytics API; that data source requires a Claude Enterprise plan.
* Anthropic's APIs do not currently surface tax information. As a result, tax is not included in the cost data reported by Vantage for Anthropic usage.
## Anthropic Data Sources
The table below summarizes the two data sources, what each captures, and what you need to connect them. In Cost Reports, you can filter by the `anthropic:billing_source` tag to see which data source is associated with a given cost row.
| Data Source | What It Captures | Key | Requirement | `anthropic:billing_source` |
| - | - | - | - | - |
| Claude API | Direct API cost and usage by workspace, API key, model, and token type | Admin API key (`sk-ant-admin`) | Organization Admin role | `admin` |
| Claude.ai | Claude.ai product cost and usage by user, product, model, and token type | Claude Enterprise Analytics API key (with `read:analytics` scope) | Claude Enterprise plan and Primary Owner role | `analytics` |
The two data sources fill the shared dimensions differently. On Claude API rows, **Account** is the Anthropic workspace and **Resource** is the API key. On Claude.ai rows, **Account** is the account name you set at connect and **Resource** is the user. **Product** appears only on Claude.ai rows. Filter on the `anthropic:billing_source` tag to keep a report focused on one data source.
## Anthropic Permissions
Vantage cannot perform cost-incurring actions and only ever reads cost and usage data from Anthropic.
### Claude API Permissions
Anthropic requires an Admin API key to access the [Usage and Cost API](https://docs.anthropic.com/en/api/usage-cost-api), which includes extra permissions (see the [full list here](https://platform.claude.com/docs/en/manage-claude/admin-api#how-the-admin-api-works)). Vantage only reads from this endpoint and never performs other actions. All Admin API keys have revocable read-write access, with no option for finer permission scoping. We recommend submitting a feature request to Anthropic, and Vantage will adopt fine-grained permissions if they become available.
### Claude Enterprise Analytics API Permissions
Anthropic requires a Claude Enterprise Analytics API key with the `read:analytics` scope to access the Claude Enterprise Analytics API. Only a **Primary Owner** on a **Claude Enterprise** account can enable Analytics API access and create this key. Vantage only reads cost and usage data from this endpoint.
Vantage stores only usage metadata (e.g., token consumption). No user content (prompts or responses) is ingested from either data source.
## Connect Your Anthropic Account
You can connect the Claude API, Claude.ai, or both. Each data source has its own key and its own connection flow in Vantage.
### Prerequisites
* You must have a Vantage **Organization Owner** or **Integration Owner** role to add or remove this integration. See the [Role-Based Access Control](/rbac) documentation for details.
* For the **Claude API**, you need to be an Organization Admin in the Claude Console to generate an Admin API key.
Admin keys are not available for individual accounts. You will need to set up your organization by navigating to **Console > Settings > Organization** first. See the [Claude documentation](https://platform.claude.com/docs/en/manage-claude/admin-api) for details.
* For **Claude.ai**, you must be on a **Claude Enterprise** plan and be a **Primary Owner** to enable Analytics API access and create a Claude Enterprise Analytics API key.
* Create a free Vantage account, then follow the steps below to integrate Anthropic costs.
If your organization restricts access to the provider by IP address, add the following Vantage IP addresses to your provider's allowlist:
### Connect the Claude API
Use this data source to track programmatic Claude usage from the Claude API.
Navigate and log in to the [Claude Console](https://console.anthropic.com/dashboard).
On the bottom left of the console, click your username, then select **Organization settings**.
On the left navigation, click **Admin keys**.
Click **Create admin key**.
It's best practice to use a dedicated key for Vantage and rotate it per your organization's security policy.
Enter a name for your key and click **Add**.
Copy the newly created key. Admin keys start with `sk-ant-admin`.
From the top navigation in Vantage, click **Settings**.
On the left navigation, select **Integrations** > **Anthropic**.
The Anthropic integration page is displayed. Ensure you are on the **Connect** tab.
In the **Claude API** section, click **Add Admin API Key** and paste your newly generated Admin API key.
Click **Connect Account**.
### Connect Claude.ai
Use this data source to track Claude.ai product usage, including Claude Chat, Claude Code, Claude Cowork, Office Agents, Claude in Chrome, and Claude Design. You must be the **Primary Owner** on your account to create a key.
In [Claude.ai](https://claude.ai), navigate to **Analytics** > **API keys**.
Under **Analytics API**, turn on the **Access** toggle to enable Analytics API access for your organization.
Click **+ Create key** to generate a new Claude Enterprise Analytics API key. Ensure the key includes the `read:analytics` scope.
Copy the newly created key and store it securely. It will not be shown again.
From the top navigation in Vantage, click **Settings**.
On the left navigation, select **Integrations** > **Anthropic**.
Ensure you are on the **Connect** tab. In the **Claude Enterprise (claude.ai)** section, click **Add Analytics API Key**.
Paste your Claude Enterprise Analytics API key. Then enter your **Organization ID** (found in your [Claude.ai account settings](https://claude.ai/new#settings/account)) and an **Account Name** to label this connection in Vantage.
The Analytics API does not expose an account name, so the **Account Name** you enter is used to identify this connection in the Vantage UI and as the **Account** dimension on Claude.ai cost rows.
Click **Connect Account**.
After you connect a data source, the integration status changes to **Importing** within the Vantage console, indicating that Vantage is actively importing your Anthropic cost data. Vantage backfills data across the range supported by Anthropic's APIs using paginated requests. The Claude Enterprise Analytics API exposes Claude.ai usage data starting **January 1, 2026**; data from earlier dates is not available. See the [Integration Status](/vantage_account#integration-status) documentation for details on integration statuses.
As soon as costs are processed, they will be available on your **All Resources** Cost Report. If you remove an Anthropic integration from Vantage, all costs associated with that Anthropic API key are removed from the Vantage console.
### Next Steps - Manage Workspace Access
Once the import is complete and the integration status changes to **Stable**, you can select which workspaces each integration is associated with. See the [Workspaces](/workspaces#manage-workspace-provider-integrations) documentation for information.
## Data Refresh
See the [provider data refresh documentation](/provider_data_refresh) for information on when data for each provider refreshes in Vantage. Both Anthropic data sources refresh once daily.
## Anthropic Reporting Dimensions
On Anthropic [Cost Reports](/cost_reports), you can filter and group across several dimensions. The values available for each dimension depend on the data source, as shown below.
| Dimension | Claude API | Claude.ai |
| - | - | - |
| Billing Account (Organization) | Connection description | Organization ID (entered at connect) |
| Account (Workspace) | Anthropic workspace | Account Name (entered at connect) |
| Service | Model (e.g., Claude Sonnet 4, Claude Opus 4.1) | Model (e.g., Claude Sonnet 4, Claude Opus 4.1) |
| Category | Cost type (e.g., tokens, web\_search) | Claude.ai product (e.g., Claude Code, Claude Cowork) |
| Subcategory | Token type (e.g., cache\_read\_input\_tokens, output\_tokens) | Token type (e.g., cache\_read\_input\_tokens, output\_tokens) |
| Resource ID | API key ID | User email |
| Region | Inference geography (e.g., the geographic region where inference ran) | Inference geography (e.g., the geographic region where inference ran) |
| Charge Type | Usage | Usage (and Discount, when applicable) |
In addition, Anthropic costs include the following provider tags, which are automatically created by Vantage and available for filtering and grouping alongside any [Virtual Tags](/tagging) you create. The **Source** column indicates which data source populates each tag.
| Tag | Description | Source |
| - | - | - |
| `anthropic:billing_source` | The data source the row came from (`admin` or `analytics`) | Both |
| `anthropic:model` | The model name (e.g., claude-3-5-haiku-20241022) | Both |
| `anthropic:context_window` | The context window range (e.g., 0-200k) | Both |
| `anthropic:api_key_created_by_email` | The email of the user who created the API key, when available | Claude API only |
| `anthropic:api_key_created_by_name` | The name of the user who created the API key, when available | Claude API only |
| `anthropic:workspace_name` | The name of the workspace associated with the API key, when available | Claude API only |
| `anthropic:product` | The Claude.ai product (e.g., claude\_code, cowork) | Claude.ai only |
| `anthropic:user_id` | The user ID associated with the usage | Claude.ai only |
| `anthropic:user_email` | The email of the user associated with the usage | Claude.ai only |
| `anthropic:user_name` | The name of the user associated with the usage | Claude.ai only |
| `anthropic:inference_geo` | The inference geography for the usage | Both |
| `anthropic:speed` | The service speed tier for the usage | Both |
| `anthropic:user_deleted` | Set to `true` when the associated user has been deleted | Claude.ai only |
Vantage also applies [Managed AI Tags](/managed_ai_tags) to Anthropic costs. This is a normalized `vntg:ai:` schema shared across all AI providers, so you can analyze AI spend with consistent dimensions. The **Claude API** data source emits `vntg:ai:model`, `vntg:ai:model_provider`, `vntg:ai:provider_region`, `vntg:ai:service_tier`, `vntg:ai:inference_speed`, and `vntg:ai:token_type`; the **Claude.ai** data source additionally emits `vntg:ai:user_email`, `vntg:ai:user_name`, and `vntg:ai:user_id`. See [Managed AI Tags](/managed_ai_tags) for the full schema.
### View Anthropic Spend by User or Developer Email
For **Claude.ai** spend, connect the **Claude Enterprise (claude.ai)** data source with a Claude Enterprise Analytics API key. Claude.ai cost rows use the user's email as the **Resource ID** and include the `anthropic:user_email` tag, so you can group a Cost Report by **Resource** or filter and group by the `anthropic:user_email` tag.
For **Claude API** spend attributed to an API key, Vantage adds the `anthropic:api_key_created_by_email` and `anthropic:api_key_created_by_name` tags when Anthropic provides the corresponding user metadata. Filter or group by these tags to analyze costs by the user who created the key. These tags identify the key creator, who may differ from the person or service that used the key. Rows that are not attributed to an API key do not include creator tags.
## Active Resources
Vantage syncs the following Anthropic [active resources](/active_resources), available in [resource reports](/active_resources). All are synced from the **Claude API** integration (Admin API key); connecting only Claude.ai does not sync any active resources.
* **API Keys**: Claude API keys in your organization.
* **Users**: members of your organization.
* **Models**: Claude models available to your organization.
# Anyscale
Source: https://docs.vantage.sh/connecting_anyscale
Learn how to integrate Vantage with Anyscale.
Vantage integrates with Anyscale using a [platform API key](https://docs.anyscale.com/administration/organization/user-auth#api-keys). Vantage ingests cost and usage data using the [Aggregated Instance Usage API](https://docs.anyscale.com/reference/aggregated-instance-usage). This data is normalized and displayed in reports, where it can be filtered and grouped by organization, project, cloud provider, and more. Usage data is available for Anyscale consumption, measured in credits.
All Anyscale platform API keys have revocable read-write access, with no option for finer permission scoping. We recommend submitting a feature request to Anyscale, and Vantage will adopt fine-grained permissions if they become available.
## How Costs Are Calculated
Vantage ingests your Anyscale consumption, measured in credits, from the Aggregated Instance Usage data. The cost displayed in Cost Reports is calculated as the number of credits consumed multiplied by the rate per credit you configured when connecting the integration.
### Prerequisites
* You must have a Vantage **Organization Owner** or **Integration Owner** role to add or remove this integration. See the [Role-Based Access Control](/rbac) documentation for details.
* You need to be an [Organization Owner](https://docs.anyscale.com/administration/organization/permissions#org-owner) to generate a platform API key in the Anyscale console.
* Create a free Vantage account, then follow the steps below to integrate Anyscale costs.
If your organization restricts access to the provider by IP address, add the following Vantage IP addresses to your provider's allowlist:
### Create the Connection
Service accounts are available in Anyscale but currently only have collaborator permissions. At this time, personal API keys are recommended for integrations.
#### Step 1 - Obtain an Anyscale API Key
The CLI method allows you to create API keys with custom expiry periods or permanent keys that don't expire, making it ideal for long-term integrations. For more information, see the [Anyscale CLI configuration documentation](https://docs.anyscale.com/reference/quickstart-cli#authenticate-the-anyscale-cli).
Install the Anyscale CLI by running:
```bash theme={null}
pip install anyscale
```
Authenticate using the CLI. You can use either:
* `--no-expire` to create a permanent API key that never expires
* `--expire-in-days=` to set a custom expiry period
For example, to create a permanent key:
```bash theme={null}
anyscale login --no-expire
```
Or to create a key that expires in 90 days (you'll need to update the key in Vantage when it expires):
```bash theme={null}
anyscale login --expire-in-days=90
```
A new browser window opens to confirm authentication. Once approved, the CLI stores the access token in `~/.anyscale/credentials.json`. For more details, see the [Anyscale CLI authentication documentation](https://docs.anyscale.com/reference/quickstart-cli#authenticate-the-anyscale-cli).
Retrieve your API key. You can access the file using one of these methods:
* **Using the command line**: Open a terminal and run:
```bash theme={null}
cat ~/.anyscale/credentials.json
```
Or on macOS/Linux, you can open it in a text editor:
```bash theme={null}
open ~/.anyscale/credentials.json
```
* **Using Finder (macOS)**: Press `Cmd+Shift+G` in Finder, then type `~/.anyscale` and press Enter. Open the `credentials.json` file.
* **Using File Explorer (Windows)**: Navigate to `%USERPROFILE%\.anyscale\credentials.json` in File Explorer.
The API key will be in the `cli_token` field in the JSON file.
The console UI method creates API keys with a maximum expiry of 30 days, requiring you to update the token every 30 days to maintain the integration. For more information, see the [Anyscale API keys documentation](https://docs.anyscale.com/administration/organization/user-auth#api-keys).
Log in to the [Anyscale console](https://console.anyscale.com/).
On the top right, click your user icon, then select **API keys**.
Click **+ Create**, then copy the newly created key.
#### Step 2 - Add the Key to Vantage
From the top navigation in Vantage, click **Settings**.
On the left navigation, select **Integrations** > **Anyscale**.
The Anyscale integrations page is displayed. Ensure you are on the **Connect** tab.
At the bottom of the page, click **Add API Key** and paste your API key.
Enter the **rate per Anyscale credit**. Vantage multiplies your consumed Anyscale credits by this rate to calculate the cost shown in reports. Set this to match your negotiated per-credit price with Anyscale so the dollar amounts are accurate.
Click **Connect Account**.
After adding your integration, you will see the status of your integration change to **Importing** within the Vantage console. This status indicates that Vantage is actively importing your Anyscale cost data. The integration will fetch historical data up to your account's configured retention period. See the [Integration Status](/vantage_account#integration-status) documentation for details on integration statuses.
As soon as costs are processed, they will be available on your **All Resources** Cost Report. If you decide to remove your Anyscale integration from Vantage, all costs associated with your Anyscale API key will be removed from the Vantage console.
#### Next Steps - Manage Workspace Access
Once the import is complete and the integration status changes to **Stable**, you can select which workspaces this integration is associated with. See the [Workspaces](/workspaces#manage-workspace-provider-integrations) documentation for information.
## Data Refresh
See the [provider data refresh documentation](/provider_data_refresh) for information on when data for each provider refreshes in Vantage.
## Anyscale Reporting Dimensions
On Anyscale [Cost Reports](/cost_reports), you can filter across several dimensions:
* Billing Account (Organization)
* Account (Project)—displays human-readable project names
* Service (e.g., Instances)
* Category (e.g., customer\_hosted)
* Subcategory (e.g., k8s)
* Resource ID (Resource ID)
* Charge Type (e.g., Usage)
* Tags: Includes [Virtual Tags](/tagging) created in Vantage for this provider. The following provider tags are automatically created by Vantage from Anyscale data and are available for filtering and grouping:
* `anyscale:cloud_id`: The cloud ID associated with the cost, allowing you to filter and group costs by cloud.
* `anyscale:workspace_id`: The workspace ID associated with the cost, allowing you to filter and group costs by workspace.
* `anyscale:cloud_provider`: The cloud provider (e.g., AWS, GCP, Azure), allowing you to filter and group costs by cloud provider.
* `anyscale:instance_type`: The instance type used, allowing you to filter and group costs by instance type.
* `anyscale:user_email`: The user email associated with the cost when present in the source data, allowing you to filter and group costs by user email.
* `anyscale:user_id`: The user ID associated with the cost when present in the source data, allowing you to filter and group costs by user ID.
Vantage also applies [Managed AI Tags](/managed_ai_tags) to Anyscale costs. This is a normalized `vntg:ai:` schema shared across all AI providers, so you can analyze AI spend with consistent dimensions. For Anyscale, the following keys are emitted: `vntg:ai:user_email` and `vntg:ai:user_id`. See [Managed AI Tags](/managed_ai_tags) for the full schema.
# AWS
Source: https://docs.vantage.sh/connecting_aws
Learn how to integrate Vantage with AWS.
Vantage has a few options to connect to AWS, including CloudFormation, the AWS CLI, a Terraform module, and the AWS IAM Console.
## How Vantage Connects with AWS
Vantage understands security concerns and aims to provide as secure a connection as possible with your AWS accounts. Vantage uses a mechanism called a *Cross-Account IAM Role* to interact with services in your AWS account. AWS has [publicly documented](https://aws.amazon.com/blogs/apn/securely-accessing-customer-aws-accounts-with-cross-account-iam-roles/) this method and officially recommends it as the preferred method of doing any cross-account interactions on AWS. Numerous internal AWS services and systems also leverage this method.
This means that Vantage **never** needs access credentials, account logins, or passwords for AWS.
### AWS Permissions
When you create a Cross-Account IAM Role using the provided CloudFormation template, or via Terraform, you provide Vantage with various permissions. Vantage only collects metadata about your infrastructure and never attempts to read sensitive information from the underlying services. Our CloudFormation template is public, and you can audit the template's [list of permissions](https://vantage-public.s3.amazonaws.com/vantage-integration-combined-latest.json).
To surface additional AWS rightsizing and idle [cost recommendations](/cost_recommendations#aws-recommendations) in Vantage, enable [AWS Compute Optimizer](https://docs.aws.amazon.com/compute-optimizer/latest/ug/account-opt-in.html) directly in AWS for the accounts you connect to Vantage.
### AWS GovCloud Environments
Vantage supports ingesting costs for infrastructure in [GovCloud](https://aws.amazon.com/govcloud-us/details/) environments. Note that at this time, we are unable to sync active resources from GovCloud regions into the [Active Resources](/active_resources#view-active-resources) screen in Vantage; however, you can still view costs by resource in [Cost Reports](/cost_reports). You also have access to all other Vantage functionality.
### AWS China Regions
AWS China operates as an isolated region, separate from standard AWS regions, meaning Vantage cannot directly access CURs from AWS China due to this isolation. However, you can still ingest AWS China cost data into Vantage by setting up a process to copy CUR files from AWS China to a standard AWS region.
At this time, [cost recommendations](/cost_recommendations) and [active resources](/active_resources) are not available for AWS China regions.
[This process](/connecting_aws#create-a-connection) creates an S3 bucket in `us-east-1`. This bucket will serve as the destination for your AWS China CUR files.
Create a process that copies CUR files from AWS China to the S3 bucket created by Vantage. You can use various methods to automate this transfer, such as:
* AWS Lambda function triggered on new CUR file creation
* Scheduled cron job or script
* Other data transfer tools
The key requirement is that CUR files from AWS China are regularly copied to the Vantage S3 bucket in `us-east-1`.
Allow the copy process to write to the Vantage S3 bucket. The IAM role created during the standard Vantage integration should have the necessary permissions for the bucket.
Once CUR files are being copied to the Vantage S3 bucket, Vantage will automatically ingest and process the data.
#### Multi-Currency Setup
If you have AWS China costs in a different currency than your standard AWS costs, you'll need to set up separate integrations and workspaces to properly track costs in each currency. For additional information on currency management, see the [Currency Conversion](/vantage_account#currency-conversion) documentation.
```mermaid theme={null}
graph LR
A[AWS CUR 1] -->|Copy Process| B[S3 Bucket A us-east-1]
C[AWS CUR 2] -->|Copy Process| D[S3 Bucket B us-east-1]
B --> E[AWS Integration A]
D --> F[AWS Integration B]
E --> G[Workspace 1 Currency A]
F --> H[Workspace 2 Currency B]
```
* S3 Bucket A: For your first group of CUR files
* S3 Bucket B: For your second group of CUR files in the other currency
* AWS Integration A: Connected to S3 Bucket A
* AWS Integration B: Connected to S3 Bucket B
Follow the [integration steps](/connecting_aws#create-a-connection).
* Workspace 1: Associated with AWS Integration A (Currency A)
* Workspace 2: Associated with AWS Integration B (Currency B)
See the [Workspaces documentation](/workspaces#manage-workspace-provider-integrations) for details on creating and managing workspaces.
This setup ensures that costs in different currencies are properly separated and reported in their respective workspaces.
If your organization restricts access to the provider by IP address, add the following Vantage IP addresses to your provider's allowlist:
## Create a Connection
You must have a Vantage **Organization Owner** or **Integration Owner** role to add or remove this integration. See the [Role-Based Access Control](/rbac) documentation for details.
**Understanding Cost Explorer vs. CUR Data**
When you first connect AWS to Vantage using one of the below methods, you'll see historical cost data immediately. This data comes from AWS Cost Explorer. However, to filter, group, or organize costs by resource, account, tag, or other dimensions, Vantage requires Cost and Usage Report (CUR) data.
**Key differences:**
* **Cost Explorer data**: Provides high-level cost totals but lacks the granular detail needed for filtering and grouping.
* **CUR data**: Contains detailed line-item data that enables filtering, grouping, and resource-level cost analysis.
**What this means for you:**
* Vantage will experience [a delay](/connecting_aws#aws-data-ingestion-delay) in receiving all your cost data until the first Cost and Usage Report (CUR) is received from AWS. Once the first CUR is received, you'll be able to filter and group costs.
* The first CUR contains only the current month's data. To view historical data with full filtering capabilities, you must [backfill your CUR](/connecting_aws#backfilling-aws-cur-for-previous-reporting-periods).
Without CUR backfill, you'll see historical cost totals but won't be able to filter or group that historical data by account, resource, tag, or other dimensions.
Navigate to the [Vantage Integrations](https://console.vantage.sh/settings/integrations) page, and create a new AWS connection. On the AWS connection page, you will see a few options to connect.
* **AWS Console:** Click the purple **Connect Vantage via AWS Console** button to directly log in to AWS. You will be directed to CloudFormation to create the necessary stack that will contain prefilled parameters. Click the checkbox for "I acknowledge that AWS CloudFormation might create IAM resources.", and click "Create Stack". Once the deployment is complete, you will see the stack status as `CREATE_COMPLETE`.
* **AWS CLI:** Click the **More Connection Options** dropdown and select **Connect via AWS CLI**. The CLI commands needed to create a connection are provided on this screen.
* **Terraform:** Click the **More Connection Options** dropdown and select **Connect via AWS Terraform**. Instructions for how to connect using the Terraform module are provided on this screen. See the [section below](/connecting_aws#connect-with-terraform) for more details.
* **AWS IAM Console:** Click the **More Connection Options** dropdown and select **Connect via AWS IAM Console**. Instructions are provided on this screen. See the [section below](/connecting_aws#connect-by-manually-creating-an-iam-role) for more details.
* **CloudFormation StackSet for Multiple Member Accounts:** Click the **Connect via CloudFormation StackSet** button. The necessary commands to create this connection are displayed. See the next section for more information.
If you already have an S3 bucket that receives CUR files and do not want Vantage to create a new one, see [Connect with an Existing S3 Bucket](/connecting_aws#connect-with-an-existing-s3-bucket).
After you create your integration between AWS and Vantage, you can view the status of your connection on the [AWS Settings page](https://console.vantage.sh/settings/aws). This page has four tabs:
* **Manage:** Lists each connected AWS account and its integration status. Click an account to manage its workspace assignments, update its IAM role, or remove the connection.
* **Connect:** Displays the connection workflow described above, so you can add additional AWS accounts at any time.
* **VPC Flow Logs:** Manages the VPC Flow Logs that Vantage ingests for [Network Flow Reports](/network_flow_reports#manage-existing-integrations). This tab is only displayed once at least one AWS account is connected.
* **Model Invocation Logs:** Manages the Amazon Bedrock Model Invocation Logs that Vantage ingests for [AWS Bedrock LLM Enrichment](/aws_bedrock_enrichment). This tab is only displayed once at least one AWS account is connected.
On an AWS account's **Manage Connection** page, the **Integration Status** panel displays validation results for Vantage's access to the account and its billing data. Click **Run Checks** to validate the connection on demand. See [Connection Validation Checks](/vantage_account#connection-validation-checks) for status details.
### Connecting Multiple AWS Accounts
You can connect multiple AWS accounts to Vantage; however, we strongly advise that you connect your **root or management** AWS account first. When you connect the root account, you can see all costs for the organization, including linked accounts.
**If you connect only a linked or member account, you will experience the following issues:**
* You will see only costs and costs by resource for that linked account, rather than for your whole organization.
* You will be unable to see costs for the other member accounts in your AWS organization.
* You may not see the full coverage of cost allocation tags from the organization.
* If Reserved Instances (RIs) are purchased in the linked account, those instances will be realized in the linked account first instead of being realized across the organization.
Once you connect your root/management AWS account, Vantage will profile all member accounts present in the organization. Vantage will be able to show you accrued costs from all member accounts in the organization, as well as Active Resources that are present in that *root AWS account*.
#### Unlinking Member Accounts
By default, all member accounts are linked to the management account and inherit its [workspace](/workspaces) assignments. If you need to assign a member account to a different workspace—for example, to isolate a business unit's costs—you can unlink it from the management account.
Navigate to the [AWS Settings](https://console.vantage.sh/settings/aws) page.
Select the member account you want to unlink. On the account's settings page, the **Workspace Access** section displays a message: "To assign this account to separate workspaces, you must first unlink it from the management account." Workspace checkboxes are disabled while the account is linked.
Click **Unlink from Management Account**. The workspace checkboxes become editable, and you can assign the member account to any workspace independently.
Unlinking a member account separates it from the management account's workspace assignments. Costs for the unlinked account will no longer automatically appear in the same workspaces as the management account. Ensure that you assign the unlinked account to the appropriate workspaces after unlinking.
#### StackSet Prerequisites
To leverage StackSets, you must enable your organization's access to operate a service-managed StackSet. You'll need to enable this setting in the AWS Management Console. If you don't have this setting enabled and attempt to run a StackSet command, you'll see the following error:
`An error occurred (ValidationError) when calling the CreateStackSet operation: You must enable organizations access to operate a service managed stack set`
For more information, see [AWS's instructions](https://docs.aws.amazon.com/AWSCloudFormation/latest/UserGuide/stacksets-prereqs.html) for enabling this setting.
#### Connecting via Stackset
If you have multiple member accounts and want to view Active Resources present in those accounts, you use the CloudFormation StackSet that will create one role per AWS member account. You're also welcome to skip this step and add/remove individual AWS accounts from your [account settings](https://console.vantage.sh/settings/aws) whenever you want.
We recommend using StackSets if you have several accounts you want to connect. Using the StackSet will automate the process for all the accounts in your organizational unit. When connecting your account, if you have at least one member account, you will see instructions, specific to your account, on how to connect your member accounts using StackSets.
Vantage publishes StackSet templates at stable `-latest` URLs and updates the template contents in place. If you manage the StackSet with the AWS CLI or CloudFormation, run the update with the same template URL. CloudFormation will fetch the current template contents.
If you manage the StackSet with Terraform's `aws_cloudformation_stack_set` resource, using `template_url` may not show a plan change because the URL stays the same. To have Terraform detect Vantage template updates, fetch the template contents, such as with Terraform's `http` data source, and pass the fetched contents to `template_body`.
### Connect with Terraform
During onboarding, instead of following the CloudFormation process, you can use the Vantage Terraform module. See the [Terraform documentation](/terraform#vantage-terraform-integrations-module-for-aws) for more information.
The CUR bucket defaults to `us-east-1` and can also be provisioned in `ap-southeast-1`, `eu-west-1`, `eu-west-2`, or `us-west-2` using the `cur_bucket_region` variable (requires module version 1.1.0 or above). The AWS provider region must match `cur_bucket_region`. See the [Terraform documentation](/terraform#vantage-terraform-integrations-module-for-aws) for an example.
When `cur_bucket_name` is set, the module manages a legacy CUR 1.0 report by default. Set `upgrade_to_cur_2 = true` to replace it with a CUR 2.0 Data Export. CUR 2.0 support requires version 5.48.0 or newer of the HashiCorp AWS provider.
### Connect with an Existing S3 Bucket
If you already have an S3 bucket that receives Cost and Usage Report (CUR) files, for example, a bucket you share with other vendors, you can connect Vantage to that bucket instead with the existing-bucket CloudFormation template:
```
https://vantage-public.s3.amazonaws.com/vantage-integration-existing-latest.json
```
You deploy this template with the AWS CLI, using the parameter values from the **Connect via AWS CLI** command in the Vantage console.
The existing-bucket template:
* Creates the Vantage Cross-Account IAM Role with the same permissions as the [standard template](https://vantage-public.s3.amazonaws.com/vantage-integration-combined-latest.json).
* By default, replaces the bucket's bucket policy with a single statement that lets that role perform `s3:GetObject` and `s3:GetObjectAcl` on the bucket's objects.
* Notifies Vantage with the role ARN and bucket ARN so the connection is created in your account.
The template does not:
* Create the bucket, a lifecycle rule, or a CUR. The bucket must already receive the report files.
* Change the bucket's S3 event notifications. The Vantage SNS topic ARN is returned as the `NotificationTopicArn` stack output so you can add it separately (see below).
On the [AWS connection page](https://console.vantage.sh/settings/aws) in the Vantage console. Ensure you are on the **Connect** tab, and click **More Connection Options** > **Connect via AWS CLI**. Copy the `aws cloudformation create-stack` command. It contains the `VantageID`, `VantageHandshakeID`, `VantageIamRole`, `VantagePingbackArn`, `VantageDomain`, and `VantageNotificationTopicArn` parameter values for your organization.
Make the following changes before running the command:
* Replace the `--template-url` value with `https://vantage-public.s3.amazonaws.com/vantage-integration-existing-latest.json`.
* Remove the `ReportName`, `BucketName`, and `TimeUnit` parameters. They do not exist in this template, and CloudFormation rejects the stack if they are included.
* Add `ParameterKey=ExistingBucketName,ParameterValue=`.
* Optionally, add `ParameterKey=ManageBucketPolicy,ParameterValue=false` to leave your current bucket policy unchanged. See the parameter descriptions below.
Keep the remaining Vantage parameters, `--capabilities CAPABILITY_IAM`, and `--region` as provided.
Run the edited command with credentials for the AWS account that owns the bucket. When the stack reaches `CREATE_COMPLETE`, the connection appears on the [AWS Settings page](https://console.vantage.sh/settings/aws) in Vantage.
To let Vantage know when new report files arrive, add an S3 event notification on the bucket that publishes to the `NotificationTopicArn` stack output for the event type `s3:ObjectCreated:*` with the suffix filter `.gz`.
The template accepts the following parameters in addition to the standard Vantage parameters:
* `ExistingBucketName`: The name of the bucket that already receives your report files. The stack does not create or delete this bucket.
* `ManageBucketPolicy`: Defaults to `true`. When `true`, the stack replaces the bucket's entire bucket policy with the Vantage read statement. Statements for other vendors, SSL-only access, and anything else on that policy are removed. Set it to `false` on the first deploy to leave the current bucket policy unchanged. On the first deploy, `false` writes no bucket policy. The role still has an IAM policy allowing `s3:GetObject` on the bucket, but a bucket policy that denies that role, or that is required because the bucket is in another account, will block reads. The bucket policy resource uses `DeletionPolicy: Retain`. Setting `ManageBucketPolicy` to `false` after the stack has written a policy leaves that policy on the bucket and does not restore the previous one. Deleting the stack also leaves the policy in place.
* `VantageNotificationTopicArn`: The Vantage SNS topic for CUR upload events, prefilled by the console's CLI command. The stack returns it as the `NotificationTopicArn` output and does not subscribe the bucket to it.
Saving an S3 event notification configuration on the bucket replaces every existing event notification on that bucket, including notifications to other topics, queues, and Lambda functions. CloudFormation can only configure S3 event notifications on a bucket the stack creates, so this template does not add one. Skip that step if existing notifications must stay.
Objects already landing in the bucket must be gzip-compressed CUR data that Vantage can ingest.
### Connect by Manually Creating an IAM Role
If you want to create IAM roles manually or use another tool to manage your infrastructure, you can create the necessary cross-account role.
If you decide to use this integration method, ensure you’ve set up a Cost and Usage Report (CUR) in your account so that Vantage will be able to pull in and read data from the CUR. After adding the IAM role ARN to Vantage, contact [Vantage Support](mailto:support@vantage.sh) with your CUR configuration.
On the AWS connection page in the Vantage console, click **More Connection Options** > **Connect via AWS IAM Console**.
You will be presented with a **Trust Relationship** and an **Inline Policy** that is required for the role. Follow the steps provided in the Vantage console to set up the role. Keep this tab open as you will need to submit the **[ARN](https://docs.aws.amazon.com/IAM/latest/UserGuide/reference-arns.html)** of the role to complete the connection.
After creating the role in IAM, return to the onboarding page in Vantage and add the **ARN** of the created role to the **Cross account arn** field at the bottom of the connection workflow pop-up window. Then, click **Connect** to complete the connection.
After creating your connection, you will see the status of your integration change to **Importing** within the Vantage console. This status indicates that Vantage is actively importing your AWS cost data. See the [Integration Status](/vantage_account#integration-status) documentation for details on integration statuses.
### Next Steps - Manage Workspace Access
Once the import is complete and the integration status changes to **Stable**, you can select which workspaces this integration is associated with. See the [Workspaces](/workspaces#manage-workspace-provider-integrations) documentation for information.
## CUR Format
Vantage supports both AWS Legacy CUR and CUR 2.0 formats. AWS Console and AWS CLI onboarding create a CUR 2.0 Data Export by default. The Terraform AWS integration module continues managing legacy CUR 1.0 by default unless you set `upgrade_to_cur_2 = true`. Vantage automatically converts CUR 2.0 rows, which use snake\_case column names instead of slash-separated camelCase, to legacy format for processing.
When creating a CUR 2.0 export in AWS Data Exports, ensure the query is configured to select **all columns**. If only a subset of columns is selected, Vantage may not have the data it needs to process your costs.
For Amazon Bedrock caller attribution, enable **Include caller identity (IAM principal) allocation data** on the CUR 2.0 export. This adds IAM principal data to the export so Vantage can surface the calling IAM user, role, or assumed-role ARN, along with any activated IAM principal tags. See the [AWS IAM principal cost allocation documentation](https://docs.aws.amazon.com/awsaccountbilling/latest/aboutv2/iam-principal-cost-allocation.html) for AWS setup details. For finer-grained, per-request Bedrock attribution by team, customer, feature, and other dimensions, see [AWS Bedrock LLM Enrichment](/aws_bedrock_enrichment), which joins Model Invocation Logs to your CUR costs using `requestMetadata`.
**Parquet CUR Format**
Vantage recommends **CSV/GZIP** for Cost and Usage Reports. Parquet, including Snappy Parquet, is also supported for both legacy CUR and CUR 2.0 when you need to reuse an existing Parquet report shared with other vendors. Contact [Vantage Support](mailto:support@vantage.sh) to enable Parquet ingestion for your integration. To connect Vantage to the bucket that already holds that report, see [Connect with an Existing S3 Bucket](/connecting_aws#connect-with-an-existing-s3-bucket).
## AWS Data Ingestion Delay
Vantage creates both an IAM role and a [Cost and Usage Report (CUR)](https://docs.aws.amazon.com/cur/latest/userguide/cur-create.html) integration when onboarding to AWS. While an IAM role is created within a minute, and historical cost data from Cost Explorer can be populated almost immediately, it can take AWS up to 24 hours to deliver the first CUR to Vantage. As a result, only partial data will be present until this first CUR is received.
The first CUR contains only the current month's data. To analyze historical data with full filtering and grouping capabilities, you must [backfill your CUR](/connecting_aws#backfilling-aws-cur-for-previous-reporting-periods).
This delay will impact a few features in the Vantage console:
* [Active Resources](/active_resources) will initially show only hourly and monthly rates. Once the first CUR is received, you can see actual accrued costs per resource, broken down by cost category and subcategory.
* [Cost Reports](/cost_reports) will show line-item data per service initially but will not be able to show *costs by resource* until the first CUR is received.
* Both [Autopilot](/autopilot/) and [Savings Planner](/savings_planner/) are unavailable until the first CUR is received.
Once Vantage receives its first CUR, this functionality will automatically be made available, and Vantage will alert you via email. Ultimately, this is a limitation imposed by AWS, and all Vantage features will become active once the data is received.
## Data Refresh
See the [provider data refresh documentation](/provider_data_refresh) for information on when data for each provider refreshes in Vantage.
## Backfilling AWS CUR for Previous Reporting Periods
The first CUR that's sent to Vantage contains only the current month's data. Without backfilling, you'll see historical cost totals from Cost Explorer, but you won't be able to filter, group, or analyze that historical data by account, resource, tag, or other dimensions.
Backfilling your CUR enables you to:
* Filter and group historical costs by account, resource, tag, region, and other dimensions
* View resource-level cost details for past months
* Perform detailed cost allocation and analysis on historical data
* Get a complete picture of your AWS spending trends with full granularity
Without backfill, your historical data will be limited to high-level totals only, which significantly limits your ability to analyze past spending patterns.
To backfill your CUR, contact AWS Support and open a ticket for AWS to backfill your CUR. For more information, see the [AWS documentation on backfilling CUR data](https://docs.aws.amazon.com/cur/latest/userguide/troubleshooting.html#backfill-data). Follow the steps below.
The backfilled CUR should be a daily CSV file with resource IDs enabled.
From your AWS root/management account, use the top search bar to search for and navigate to **Data Exports**.
A table of data exports is displayed. Observe the **Export Name** column. You should see the CUR export that was created by Vantage when the integration was set up. Take note of the values in the **Export Name** and **S3 Bucket** columns.
Open a ticket with [AWS Support](https://docs.aws.amazon.com/cur/latest/userguide/billing-get-answers.html) to backfill the Vantage export. You can use the sample email template below when creating your request.
*Subject: Request for Backfilling AWS CUR Data Export*
**\[Insert your organization name]** needs help backfilling a CUR Data Export per the below requirements:
* Please backfill the existing **\[Insert Vantage CUR Data Export name]** report from the **\[Insert export's S3 bucket name]** S3 bucket.
* We need historical data for the following period: **\[Insert start date]** to **\[Insert end date]**.
* This should be a daily CSV file with resource IDs enabled.
Once the historical data is successfully backfilled into the above CUR Data Export, please send us a notification or confirmation.
Thank you,
**\[Insert your name]**
Once AWS Support completes your request, please email [support@vantage.sh](mailto:support@vantage.sh) to re-ingest the backfilled CUR Data Export.
## Update the Vantage AWS Integration
Occasionally, Vantage will modify the permission sets it uses to access billing and resource data on AWS. When this happens, you can update your integration.
Navigate to the [**Integrations** page](https://console.vantage.sh/settings/integrations) of the Vantage console.
From the **AWS** tile, click **Manage**.
The **Account** list is displayed. Click **Manage** for the cloud account that you want to update. (For AWS organizations with multiple accounts, this will usually be the Management account.)
Click **Update Vantage via AWS Console** to perform the update, or click **More Update Options** for command-line and other deployment methods.
## Reporting Dimensions
On AWS [Cost Reports](/cost_reports), you can filter across several dimensions:
* Account (AWS account name)
* Category (e.g., EC2 Data Transfer)
* Tag/Not Tagged (includes AWS tags and [virtual tags](/tagging) created in Vantage for this provider). The following additional tags are available for filtering and grouping. Most are automatically created by Vantage from AWS data, while some are other AWS-managed tags that Vantage exposes:
* `aws:accountId`: The AWS account ID associated with the cost, allowing you to filter and group costs by account. Use the separate Account dimension for the full name.
* `aws:invoiceId`: The AWS invoice ID when present in the source data, allowing you to filter and group costs by invoice ID.
* `aws:instanceTypeFamily`: The instance type family (e.g., m5, c5, r5) when present in the source data, allowing you to filter and group costs by instance family. This enables instance family group-by options in Financial Cost Reports (FCRs).
* `aws:organizations:*`: AWS Organization tags are prefixed with `aws:organizations:` followed by the tag key. These tags allow you to filter and group costs by [AWS Organization tags](https://docs.aws.amazon.com/organizations/latest/userguide/orgs_tagging.html) applied to accounts.
* `aws:costCategory:*`: AWS Cost Category tags are prefixed with `aws:costCategory:` followed by the cost category name. These tags allow you to filter and group costs by [AWS Cost Categories](https://docs.aws.amazon.com/awsaccountbilling/latest/aboutv2/manage-cost-categories.html) configured in your account.
* `aws:Operation`: The line item operation (e.g., `RunInstances`, `GetObject`) from the CUR, allowing you to filter and group costs by the specific API operation or usage type that generated the charge.
* `aws:UsageType`: The usage type (e.g., `USW2-BoxUsage:m5.xlarge`) from the CUR, providing granular detail on how a service was consumed.
* `aws:LineItemDescription`: The line item description from the CUR, showing the human-readable pricing detail for each charge.
* `aws:instanceType`: The specific instance type (e.g., `m5.xlarge`) when present in the CUR, allowing you to filter and group costs by exact instance type.
* `aws:operatingSystem`: The operating system (e.g., `Linux`, `Windows`) when present in the CUR, allowing you to filter and group costs by OS.
* `aws:licenseModel`: The license model (e.g., `No License required`, `Bring your own license`) when present in the CUR.
* `aws:databaseEngine`: The database engine (e.g., `PostgreSQL`, `MySQL`) when present in the CUR, allowing you to filter and group costs by database engine.
* `aws:cacheEngine`: The Amazon ElastiCache cache engine (e.g., `Redis`, `Memcached`) when present in the CUR, allowing you to filter and group ElastiCache costs by cache engine.
* `aws:deploymentOption`: The deployment option (e.g., `Single-AZ`, `Multi-AZ`) when present in the CUR.
* `aws:physicalProcessor`: The physical processor (e.g., `Intel Xeon Platinum 8175`, `AMD EPYC 7R13`, `AWS Graviton2`) when present in the CUR, allowing you to filter and group costs by processor type.
* `aws:LegalEntity`: The legal entity (e.g., `Amazon Web Services, Inc.`) associated with the line item when present in the CUR, allowing you to filter and group costs by legal entity.
* `aws:IamPrincipal`: The caller ARN from the CUR 2.0 `line_item_iam_principal` column (e.g., `arn:aws:sts::123456789012:assumed-role/my-role/...`, `arn:aws:iam::123456789012:user/my-user`), allowing you to filter and group supported costs by user, role, or assumed-role ARN. Only available for accounts using CUR 2.0 with IAM principal allocation data.
* `aws:iamPrincipal:*`: IAM principal or session tags from CUR 2.0 (e.g., `aws:iamPrincipal:team`, `aws:iamPrincipal:cost-center`) when those tags are activated for cost allocation in AWS. These tags are available for filtering and grouping supported costs, such as Amazon Bedrock usage attributed by IAM principal.
* Custom `requestMetadata` keys, plus `vntg:ai:operation`, `vntg:ai:inference_scope`, and `vntg:ai:principal_id`: Enrichment tags available when [AWS Bedrock LLM Enrichment](/aws_bedrock_enrichment) is enabled. These split Amazon Bedrock costs by the per-request metadata your application attaches, along with the calling IAM principal and how the model was invoked. See the [AWS Bedrock LLM Enrichment](/aws_bedrock_enrichment#view-enriched-costs-on-cost-reports) documentation for the full tag reference.
* `aws:ecs:serviceName` and `aws:ecs:clusterName`: AWS-managed ECS tags that appear when [ECS-Managed Tags](https://docs.aws.amazon.com/AmazonECS/latest/developerguide/ecs-using-tags.html#managed-tags) are enabled. These tags allow you to filter and group costs by ECS service and cluster names. See the [ECS-Managed Tags](/cost_reports#amazon-elastic-container-service-ecs-managed-tags) section for more information.
* Subcategory (e.g., EC2 DataTransfer-In-Bytes)
* Resource (specific resource IDs)
* Region (e.g., US East (Ohio))
* Charge Type (e.g., Usage)
* Billing Account (AWS billing account name)
* Marketplace (Toggle to show only Marketplace purchases or excluded)
* Service (e.g., AWS CloudTrail)
Vantage also applies [Managed AI Tags](/managed_ai_tags) to Amazon Bedrock cost rows. This is a normalized `vntg:ai:` schema shared across all AI providers, so you can analyze AI spend with consistent dimensions. On Bedrock rows, the following keys are emitted: `vntg:ai:model`, `vntg:ai:raw_model`, `vntg:ai:model_provider`, `vntg:ai:provider_region`, `vntg:ai:service_tier`, `vntg:ai:token_type`, and `vntg:ai:principal_id` (the IAM principal, when your AWS costs use CUR 2.0 with IAM principal allocation data). These tags apply only to Bedrock AI usage; other AWS costs are unaffected. See [Managed AI Tags](/managed_ai_tags) for the full schema.
## View Amazon CloudWatch Metrics on Cost Reports
You can import Amazon CloudWatch metrics as business metrics to view alongside Cost Reports. See the [Business Metrics](/business_metrics#import-from-amazon-cloudwatch) documentation for more information.
## VPC Flow Logs: Network Flow Reports
For network-enabled resources, Network Flow Reports provide visibility by source and destination to the flows within your network that are driving costs. See the [Network Flow Reports documentation](/network_flow_reports) for information on how to enable these reports and view data transfer costs for AWS services.
## Model Invocation Logs: AWS Bedrock LLM Enrichment
If you use Amazon Bedrock, Vantage can attribute your Bedrock spend to teams, applications, customers, and features by reading your Bedrock Model Invocation Logs from S3 and splitting Bedrock cost rows by the `requestMetadata` your application attaches, alongside [Managed AI Tags](/managed_ai_tags) such as `vntg:ai:principal_id` and `vntg:ai:operation`. This reuses your existing cross-account IAM role—extended with read-only access to the log buckets—rather than a new connection. See the [AWS Bedrock LLM Enrichment documentation](/aws_bedrock_enrichment) for setup, permissions, and how to view enriched costs.
# Azure
Source: https://docs.vantage.sh/connecting_azure
Learn how to integrate Vantage with Azure.
Vantage integrates with your Azure account using an Active Directory [service principal](https://learn.microsoft.com/en-us/azure/active-directory/fundamentals/service-accounts-principal).
To attribute Azure AI spend to teams, users, applications, and features by your own per-request dimensions, see [Custom LLM Enrichment](/custom_llm_enrichment), which joins per-request token telemetry you deliver to S3 with your Azure costs.
## Before You Begin: Review Azure Billing Account Types
Microsoft offers different billing account types based on your organization’s setup. The way that you'll complete your Azure integration with Vantage depends on which account type you have.
To determine your billing account type, follow the steps in the [Azure documentation](https://learn.microsoft.com/en-us/azure/cost-management-billing/manage/view-all-accounts#check-the-type-of-your-account).
If your organization uses a Microsoft Customer Agreement (MCA), Enterprise Agreement (EA), or Azure Cloud Solution Provider (CSP), follow the specific integration steps linked below.
If you are on another account type such as Pay as You Go, use the instructions on this page to integrate your account with Vantage.
Follow the specific integration steps for Microsoft Customer Agreement (MCA) accounts.
Follow the specific integration steps for Enterprise Agreement (EA) accounts.
Follow the specific integration steps for Azure Cloud Solution Provider (CSP) accounts.
## Azure GovCloud
Azure Government Cloud requires additional manual configuration by the Vantage team. Customers cannot currently enable this through the UI. If you need to connect an Azure Government Cloud subscription, contact [Vantage Support](mailto:support@vantage.sh) and provide the following information after integrating:
* Your Azure Government Cloud tenant ID
* The billing account ID associated with the GovCloud tenant (`/providers/Microsoft.Billing/billingAccounts/`). Note: Subscription-based GovCloud accounts may not have a billing account ID.
**Azure CSP accounts are not supported for Azure Government Cloud.** Azure CSP integrations rely on the Microsoft Cost Management and Billing API, which is not available for Azure Government Cloud subscriptions. If you have an Azure CSP account with Government Cloud subscriptions, you will not be able to integrate these subscriptions with Vantage.
## Connect Your Azure Account (Non-MCA, EA, or CSP Account)
This service principal is assigned access to individual [subscriptions](https://learn.microsoft.com/en-us/azure/cloud-adoption-framework/ready/landing-zone/design-area/resource-org-subscriptions).
The service principal is granted [Reader](https://learn.microsoft.com/en-us/azure/role-based-access-control/built-in-roles#reader) permissions. It does **not** have permissions—nor will it ever attempt—to make any changes to your infrastructure.
Instructions are provided below for you to connect via the [Azure CLI](/connecting_azure#connect-via-the-azure-cli) or the [Azure portal](/connecting_azure#connect-via-the-azure-portal).
If your organization restricts access to the provider by IP address, add the following Vantage IP addresses to your provider's allowlist:
### Connect via the Azure CLI
#### Prerequisites
* You must have a Vantage **Organization Owner** or **Integration Owner** role to add or remove this integration. See the [Role-Based Access Control](/rbac) documentation for details.
* The below commands are run via the [Azure CLI](https://learn.microsoft.com/en-us/cli/azure/?view=azure-cli-latest). Ensure you have access to Azure CLI and can create service principals and manage their permissions.
* [Create a free Vantage account](https://console.vantage.sh/signup), then follow the steps below to integrate Azure costs.
#### Step 1 - Create an Azure Service Principal
Create a service principal using the following command:
```bash theme={null}
az ad sp create-for-rbac -n "vantage"
```
You should see output similar to the below output:
```json theme={null}
{
"appId": "2d218f0f5-7ad5-4a12-abc7-bad2889d6407",
"displayName": "vantage",
"password": "8zkj3~yswKd433U12SHrvp22UoA6tOOOkZ_BYar2",
"tenant": "1050a480-ef60-43d7-b8db-224aad100b60"
}
```
Record the `appId`, `password`, and `tenant` as you will enter these credentials into the Vantage console.
#### Step 2 - Grant the Service Principal Permissions
Grant permissions to the `appId` from the service principal created above. The scope is a subscription. Ensure you replace `` with the `appId`. Replace `` with your subscription ID.
```bash theme={null}
az role assignment create --assignee --role Reader --scope "/subscriptions/"
```
If you also want Azure Reservations and Azure Savings Plans to appear on the [Commitments](/commitments) page, continue to [Optional Azure Reservations and Savings Plans](#optional-azure-reservations-and-savings-plans). Otherwise, skip to the [Save the Credentials in Vantage](/connecting_azure#save-credentials) section to complete the connection with Vantage.
### Connect via the Azure Portal
#### Prerequisites
* You must have a Vantage **Organization Owner** or **Integration Owner** role to add or remove this integration. See the [Role-Based Access Control](/rbac) documentation for details.
* The below instructions are for connecting using the Azure portal. If you already completed the steps via the Azure CLI, skip to the [Save the Credentials in Vantage](/connecting_azure#save-credentials) section. You should have access to set up service principals and grant those service principals permissions.
* [Create a free Vantage account](https://console.vantage.sh/signup), then follow the steps below to integrate Azure costs.
#### Step 1 - Create a New Application Registration
From the main page of the Azure portal, search for and navigate to **Microsoft Entra ID**.
In the left navigation, under **Manage**, select **App registrations**.
Click **+ New registration**.

The **Register an application** screen is displayed. For **Name**, enter *vantage*.
Leave all other settings as their defaults and click **Register**.

The app details are displayed. Record the **Application (client) ID** and **Directory (tenant) ID** to use later.

#### Step 2 - Generate a Client Secret
On the same page, next to the **Client credentials** field, click **Add a certificate or secret**. (You can also access the **Certificates and secrets** screen from the left navigation menu.)
Click **+ New client secret**.
The **Add a client secret** pane is displayed. For **Description**, enter a description, such as *vantage-secret*.

For **Expires**, select an expiration option for the secret.
If this secret expires, you will need to supply Vantage with a new secret *before* the expiration date. See the [Update Your Client Secret](/connecting_azure#update-your-client-secret) section for instructions on how to update your credentials.
Click **Add**.
The newly created secret is displayed. Copy the secret's **Value** to add to the Vantage console later. This value will be displayed only one time.
#### Step 3 - Grant the Service Principal Permissions
From the top navigation, search for and navigate to **Subscriptions**.
Open the subscription for which you will be assigning permissions.
On the left navigation, click **Access control (IAM)**.
Click **Add role assignment**.

On the **Add role assignment** screen, select **Reader**. Then, click **Next**.

For **Assign access to**, select **User, group, or service principal**.
Click **+ Select members**. The **Select members** tab is displayed on the right. Search for the *vantage* app you created before. Select the listed app, then click **Select**.

Click **Next** > **Review + assign**.
If you also want Azure Reservations and Azure Savings Plans to appear on the [Commitments](/commitments) page, continue to [Optional Azure Reservations and Savings Plans](#optional-azure-reservations-and-savings-plans). Otherwise, skip to the [Save the Credentials in Vantage](/connecting_azure#save-credentials) section to complete the connection with Vantage.
### Save the Credentials in Vantage
After you complete the steps for connecting via the Azure CLI or Azure portal, follow the steps below to add the Azure tenant ID, service principal App ID, and service principal password/secret in Vantage.
Navigate to the [Integrations page](https://console.vantage.sh/settings/integrations) in the Vantage console, and add an Azure integration.
On the Azure integration page, click **Add Credentials**.
Add the **Azure AD Tenant ID**, **Service Principal App ID**, and **Service Principal Password** you previously obtained, then click **Connect Account**.
After clicking **Connect Account**, you will see the status of your integration change to **Importing** within the Vantage console. This status indicates that Vantage is actively importing your Azure cost data. See the [Integration Status](/vantage_account#integration-status) documentation for details on integration statuses. On initial connection, Vantage imports the previous six months of Azure cost data. From that point forward, each new month is added as it is billed, so your available history grows over time up to your account's [data retention](/vantage_account#data-retention) period. Because Vantage stores its own copy of your cost data, months Vantage has already imported remain available even after Azure's billing APIs stop returning them.
## Optional Azure Reservations and Savings Plans
Regular Azure integrations can import cost data without any additional commitment-specific permissions. If you also want Azure Reservations and Azure Savings Plans to appear on the [Commitments](/commitments) page, complete the steps below to grant Vantage access to the Azure commitment APIs.
This guidance applies to [Standard Azure](/connecting_azure), [Azure MCA](/connecting_azure_mca), and [Azure EA](/connecting_azure_ea) integrations. It does **not** apply to [Azure CSP](/connecting_azure_csp), which uses a different integration flow.
Assign the following roles to the *vantage* service principal you created during the initial integration setup:
* **Reservations Reader** (tenant or reservation scope) so Vantage can call `Microsoft.Capacity/reservationOrders` and list reservations.
* **Savings Plan Reader** (tenant scope, e.g., `/providers/Microsoft.BillingBenefits`) so Vantage can call `Microsoft.BillingBenefits/savingsPlanOrders` and list savings plans.
Run the following commands using the Azure CLI. Replace `` with the Application (client) ID of the app registration you created for Vantage.
```bash theme={null}
az role assignment create --assignee --role "Reservations Reader" --scope "/providers/Microsoft.Capacity"
az role assignment create --assignee --role "Savings Plan Reader" --scope "/providers/Microsoft.BillingBenefits"
```
If these permissions are missing, your Azure costs can still appear in [Cost Reports](/cost_reports), but Azure commitments will not sync to [Commitments](/commitments). You may also see a banner on the Commitments page prompting you to add the missing scopes.
If your integration is already connected, add the missing permissions in Azure and wait for the next integration refresh. If commitments still do not appear after the integration returns to **Stable**, contact [support@vantage.sh](mailto:support@vantage.sh).
## Next Steps - Manage Workspace Access
Once the import is complete and the integration status changes to **Stable**, you can select which workspaces this integration is associated with. See the [Workspaces](/workspaces#manage-workspace-provider-integrations) documentation for information.
## Update Your Client Secret
If you need to update your Azure integration's client secret, you can do so from the individual Manage Connection integration page in Vantage.
Navigate to the [Azure Integrations page](https://console.vantage.sh/settings/azure).
Select your Azure integration to access the **Manage Connection** page.
At the top, click **Update Client Secret**.
Enter the new client secret value (not the client secret ID) and save your changes.
Contact [support@vantage.sh](mailto:support@vantage.sh) to request that your integration data be reimported with the new credentials.
## Data Refresh
See the [provider data refresh documentation](/provider_data_refresh) for information on when data for each provider refreshes in Vantage.
## Azure Amortization
Azure stores their actual and amortized billing data in separate tables. Vantage pulls in both tables for you to view either cost types within Cost Reports, with no additional integration steps required. To switch between actual and amortized costs, select **Settings** at the top of any Cost Report, and check or uncheck the **Enabled** checkbox in the Amortization section.
Azure does not show unused reservations within their amortized views. If performing charge back for Azure cost data, ensure you use either actual costs or use Custom Providers to add in unused reservation costs to your amortized Azure views.
## Azure Cost Recommendations
Vantage provides different [cost recommendations](/cost_recommendations) for Azure. Each recommendation includes a potential monthly savings value, which is something that is not shown in Azure Advisor. Savings estimates are displayed in USD.
## Kubernetes and AKS
Vantage supports Kubernetes cost allocation on Azure, including Kubernetes clusters running on VMs or through AKS. Vantage recommends using the [Vantage Kubernetes agent](/kubernetes_agent) to monitor and ingest Kubernetes costs from Azure.
## Troubleshooting
### Missing Subscriptions
If only some of your Azure subscriptions appear in Vantage, the service principal likely has permissions scoped to a single subscription rather than all subscriptions under your billing account.
To resolve this:
* **Use a billing account/billing scope integration (recommended)**: If your organization has a Microsoft Customer Agreement (MCA) or Enterprise Agreement (EA), connect at the billing account (billing scope/enrollment) level instead. This gives Vantage visibility into all subscriptions without managing per-subscription permissions. See [Choosing the Right Azure Integration](#choosing-the-right-azure-integration) below for details.
* **Add additional subscriptions**: For pay-as-you-go customers, repeat the `az role assignment create` command for each subscription you want to import. See [Step 2](#step-2---grant-the-service-principal-permissions) for the CLI command.
The billing account/billing scope visibility described above applies to **cost data only**. To populate the [Active Resources](/active_resources) tab and Azure recommendations, the service principal still needs the built-in **Reader** role at the subscription (or management group) scope, even with an MCA or EA integration. See the [Azure MCA](/connecting_azure_mca#step-6-grant-reader-access-for-active-resources-and-recommendations) and [Azure EA](/connecting_azure_ea#step-6-grant-reader-access-for-active-resources-and-recommendations) documentation for details.
After updating permissions or adding a new integration, navigate to **Settings > Integrations > Azure** in the Vantage console and verify that your integration status changes to **Stable**. New subscriptions may take up to 24 hours to appear after permissions are granted.
If you grant access to an additional subscription after your Azure integration is already connected and you need historical cost data for that subscription, contact [support@vantage.sh](mailto:support@vantage.sh) to request a reimport after the new permissions are in place.
### Integration in Error or Warning State
Azure integrations can occasionally enter an **Error** or **Warning** state. Common causes include:
| Cause | Resolution |
| - | - |
| Expired client secret | Generate a new client secret in Azure and update it in Vantage. See [Update Your Client Secret](#update-your-client-secret). |
| Service principal permissions revoked | Re-grant the service principal Reader access on the affected subscriptions. See the [CLI](#step-2---grant-the-service-principal-permissions) or [portal](#step-3---grant-the-service-principal-permissions) instructions. |
| Transient Azure API errors at month boundaries | These typically resolve within 24–48 hours without action. If the error persists beyond 48 hours, contact [support@vantage.sh](mailto:support@vantage.sh). |
| Subscription moved or deleted | Vantage automatically skips individual subscriptions that are no longer accessible. If the error persists, verify that the service principal still has access to at least one active subscription, or contact [support@vantage.sh](mailto:support@vantage.sh). |
| Pay-as-you-go subscription import failures | In rare instances, some pay-as-you-go subscriptions require a backend configuration change to import successfully. If your integration enters an error state after connecting a pay-as-you-go subscription, contact [support@vantage.sh](mailto:support@vantage.sh) for assistance. |
For a description of each status indicator, see the [Integration Status](/vantage_account#integration-status) documentation.
### Choosing the Right Azure Integration
Vantage supports four Azure integration types. Use the table below to determine which one to configure:
| Integration | Billing Model | Scope | Best For |
| - | - | - | - |
| [Standard Azure](/connecting_azure) | Pay-as-you-go, MOSP | Individual subscriptions | Most Azure customers without an enterprise agreement |
| [Azure MCA](/connecting_azure_mca) | Microsoft Customer Agreement | Billing account | Organizations with an MCA billing account |
| [Azure EA](/connecting_azure_ea) | Enterprise Agreement | Enrollment | Large enterprises with an EA |
| [Azure CSP](/connecting_azure_csp) | Cloud Solution Provider | Partner Center | MSPs in the Microsoft CSP Partner Program |
If you are unsure which billing model your organization uses, check the **Cost Management + Billing** section in the Azure portal. The billing account type is displayed on the overview page.
### Costs Displayed in Wrong Currency
If your Azure costs are billed in a non-USD currency (e.g., INR, EUR, GBP) but appear as USD amounts in Vantage, this is because Vantage displays all costs in USD by default. The underlying amounts are correct, but the currency symbol may not match your billing currency.
To display costs in your billing currency, enable **Currency Conversion** or a **Display Preference** on your workspace:
* **Display Preference**: If your costs are already billed in a non-USD currency, enable a Display Preference to show the correct currency symbol without converting amounts. This is ideal when you want costs to reflect the currency in which they are billed.
* **Currency Conversion**: Convert cost amounts to a different currency using exchange rates. You can choose between a daily rate or an end-of-billing-period rate.
To configure either option, navigate to **Settings > Workspaces**, select your workspace, and update the **Currency Settings** section. See the [Currency Conversion](/vantage_account#currency-conversion) documentation for details.
### Azure Reserved Instance Visibility
Azure Reserved Instance costs are available in Vantage through [Cost Reports](/cost_reports). Azure Reservations and Savings Plans can also appear on the [Commitments](/commitments) page after you add the permissions in [Optional Azure Reservations and Savings Plans](#optional-azure-reservations-and-savings-plans). To view Reserved Instance amortized costs, ensure amortization is enabled on your Cost Report (see [Azure Amortization](#azure-amortization) above).
Azure does not include unused reservations in their amortized billing views. If you need to account for unused reservation costs, use [Custom Providers](/connecting_custom_providers) to supplement your amortized Azure data.
For optimization recommendations based on your Reserved Instance usage, see [Azure Cost Recommendations](/cost_recommendations#azure-recommendations).
## Azure Reporting Dimensions
On Azure [Cost Reports](/cost_reports), you can filter across several dimensions:
* Resource Group (resource group name)
* Category (e.g., Virtual Network IP Addresses)
* Tag/Not Tagged (includes Azure tags and [virtual tags](/tagging) created in Vantage for this provider). In addition, the following provider tags are automatically created by Vantage from Azure data and are available for filtering and grouping:
* `azure:costCenter`: The cost center value from Azure billing data, allowing you to filter and group costs by cost center.
* `azure:resourceGroup`: The resource group name associated with the cost, allowing you to filter and group costs by resource group. Use the separate Resource Group dimension for the full name.
* `azure:InvoiceSectionId`: The invoice section ID when present in the source data, allowing you to filter and group costs by invoice section.
* `azure:InvoiceSectionName`: The invoice section name when present in the source data, allowing you to filter and group costs by invoice section.
* `azure:subscriptionId`: The subscription ID associated with the cost, when present in the source data, allowing you to filter and group costs by subscription ID.
* `azure:subscriptionName`: The subscription name associated with the cost, when present in the source data, allowing you to filter and group costs by subscription name.
* Subcategory (e.g., Virtual Network Standard IPv4 Static Public IP)
* Resource (resource ID)
* Region (e.g., Us East)
* Charge Type (e.g., Usage)
* Subscription (subscription name)
* Marketplace (Toggle to show only Marketplace purchases or excluded)
* Service (e.g., Virtual Machines)
Vantage also applies [Managed AI Tags](/managed_ai_tags) to Azure OpenAI and Foundry cost rows. This is a normalized `vntg:ai:` schema shared across all AI providers, so you can analyze AI spend with consistent dimensions. On those rows, the following keys are emitted: `vntg:ai:model`, `vntg:ai:raw_model`, `vntg:ai:model_provider`, `vntg:ai:provider_region`, `vntg:ai:service_tier`, and `vntg:ai:token_type`. These tags apply only to Azure OpenAI and Foundry AI usage; other Azure costs are unaffected. See [Managed AI Tags](/managed_ai_tags) for the full schema.
# Azure CSP Account
Source: https://docs.vantage.sh/connecting_azure_csp
Learn how to integrate Vantage with Azure CSP.
The Azure Cloud Solution Provider (CSP) integration allows Vantage Managed Service Providers (MSPs) using the Microsoft CSP Partner Program to ingest and visualize their customers’ Azure costs inclusive of CSP-specific discounts and SKUs directly in Vantage, as well as delegate these costs to Vantage Managed Accounts for their customers to consume.
This integration is only available to [Vantage for MSPs](/partners) customers who are in the Azure CSP program.
Partners authenticate via OAuth with secure Azure Service Principals to grant Vantage access to three different sets of APIs used for aggregating and reconciling costs: Azure Partner Center APIs, Azure Graph APIs, and Azure Partner APIs. After authorization, Vantage ingests data from these APIs and reads multiple data sources to reconcile un-billed, billed, and invoiced costs, as well as join SKUs on public rate card costs. Vantage performs necessary reconciliation to switch between billed and unbilled costs as invoicing periods switch over, enabling you to view correct current and future period costs in both discounted costs and public price. Once imported, MSPs can delegate these costs to [managed accounts](/partners#create-a-new-customer-managed-account), create billing rules for re-rating, and create customer-specific Cost Reports and Dashboards using Azure CSP data.
When you configure this integration, Vantage requests access to your Azure Partner Center billing data through OAuth. Vantage does *not* have permissions, nor will it ever attempt, to make any changes to your infrastructure or customer accounts.
## Connect Your Azure CSP Account
### Prerequisites
* You must have a Vantage **Organization Owner** or **Integration Owner** role to add or remove this integration. See the [Role-Based Access Control](/rbac) documentation for details.
* You must be an admin who can grant consent for your organization. Vantage will assume delegated access to the following APIs:
* **Azure Service Management**: `user_impersonation`
* **Microsoft Graph**: `DelegatedAdminRelationship`, `email`, `openid`, `PartnerBill.Read_all`, `profile`, `User.Read`
* **Microsoft Partner**: `user_impersonation`
* **Microsoft Partner Center**: `user_impersonation`
* You must be a Vantage for MSPs customer
If your organization restricts access to the provider by IP address, add the following Vantage IP addresses to your provider's allowlist:
### Create a Connection
To integrate your Azure CSP account with Vantage, follow the below steps:
#### Step 1 - Connect via OAuth
From the top navigation in Vantage, click **Settings**.
On the left navigation, select **Integrations** > **Azure CSP**.
The Azure CSP integrations page is displayed. Ensure you are on the **Connect** tab.
Click **Connect Azure CSP Account**.
You will be redirected to Microsoft to authenticate. Sign in with your Azure Partner Center account credentials.
Review and accept the permissions requested by Vantage. These permissions allow Vantage to read billing and cost data from your Partner Center.
After successful authentication, you will be redirected back to Vantage and taken to the **Manage Connection** page for your Azure CSP integration.
#### Step 2 - Grant Additional Authorization
After the initial OAuth connection, Vantage requires additional authorization to access all necessary billing data.
At the top of the **Manage Connection** page, the **Complete Setup** section is displayed. A green checkmark is displayed next to the first step, indicating you have completed the initial account connection.
Two additional authorizations are required. Click **Authorize** next to the **Grant additional authorization for Vantage to start ingesting costs** step.
You will be redirected to Microsoft to grant the additional permissions via OAuth. After granting the first authorization, you will be returned to the **Manage Connection** page.
Click **Authorize** next to the remaining **Grant additional authorization to accurately reflect all Azure CSP costs** step. You will be redirected to Microsoft again to grant this final permission via OAuth.
After granting all required authorizations, you will be redirected back to the **Manage Connection** page. The **Complete Setup** section will disappear, indicating that your integration is fully configured.
After completing all required authorizations, you will see the status of your integration change to **Importing** within the Vantage console. This status indicates that Vantage is actively importing your Azure CSP cost data. Vantage will begin importing your Azure CSP costs. Upon initial connection, Vantage will ingest historical data up to your account's configured retention period. Note that Public Rate Cards are not available more than six months historically, so Vantage will fall back to what data is returned within the Graph and Partner APIs. See the [Integration Status](/vantage_account#integration-status) documentation for details on integration statuses.
### Next Steps - Workspace Access
Once the import is complete and the integration status changes to **Stable**, you can select which workspaces this integration is associated with. See the [Workspaces](/workspaces#manage-workspace-provider-integrations) documentation for information.
## Azure CSP Reporting Dimensions
On Azure CSP [Cost Reports](/cost_reports), you can filter and group costs by the following dimensions:
* Billing Account (i.e., Azure Customer ID/Tenant ID)
* Account (i.e., Subscription ID/Entitlement ID)
* Service (i.e., Product Name)
* Category (i.e., Meter Category)
* Subcategory (i.e., Meter Name)
* Region
* Resource ID
* Tags (Resource Groups, Cost Centers, and [virtual tags](/tagging) created in Vantage for this provider). In addition, the following provider tags are automatically created by Vantage from Azure data and are available for filtering and grouping:
* `azure:costCenter`: The cost center value from Azure billing data, allowing you to filter and group costs by cost center.
* `azure:resourceGroup`: The resource group name associated with the cost, allowing you to filter and group costs by resource group.
* `azure:InvoiceSectionId`: The invoice section ID when present in the source data, allowing you to filter and group costs by invoice section.
* `azure:InvoiceSectionName`: The invoice section name when present in the source data, allowing you to filter and group costs by invoice section.
* `azure:subscriptionId`: The subscription ID when present in the source data, allowing you to filter and group costs by subscription.
* `azure:subscriptionName`: The subscription name when present in the source data, allowing you to filter and group costs by subscription.
* `azure:orderDate`: The order date from invoice reconciliation data when present, allowing you to filter and group costs by order date.
* `azure:subscriptionStartDate`: The subscription start date from invoice reconciliation data when present, allowing you to filter and group costs by subscription term.
* `azure:subscriptionEndDate`: The subscription end date from invoice reconciliation data when present, allowing you to filter and group costs by subscription term.
* `azure:termAndBillingCycle`: The term and billing cycle (e.g., `1 Year Reservation`, `One-Month commitment for monthly billing`) from invoice reconciliation data when present, allowing you to filter and group costs by commitment term.
* `azure:billingFrequency`: The billing frequency (e.g., `Monthly`) from invoice reconciliation data when present, allowing you to filter and group costs by billing frequency.
## Usage Data
[Usage data](/usage_based_reporting) is available per meter and resource, based on the granularity provided by Azure.
## Data Refresh
Azure CSP data refreshes daily in the Vantage console. See the [provider data refresh documentation](/provider_data_refresh) for information on when data for each provider refreshes in Vantage.
## Partner Earned Credits and Discounts
While partner credits and discounts are not made available directly in the cost dataset, Vantage will perform calculations to add Partner Earned Credit-specific cost rows to your dataset to toggle on and off Credits, as well as discounts where the Unit Cost and Effective Unit Cost are misaligned. Where necessary, Vantage will also join on Public Rate Cards to ensure proper public pricing and discounts are calculated.
## Integration Limitations
* **Cost Recommendations**: Cost recommendations are not available for Azure CSP integrations via the Partner Settings APIs.
* **Active Resources**: Azure does not expose any list or describe resource APIs through Partner Center to provide resource metadata.
* **Amortization of Purchases**: Due to data limitations, one-time purchases (such as Commitments or Marketplace purchases) are not amortized for the Azure CSP integration. If you need to track amortized commitment costs (e.g., Reserved Instances or Azure Hybrid Benefit), you can export that data from the Azure portal and import it into Vantage using a [Custom Provider](/connecting_custom_providers). This lets you visualize amortized costs alongside your CSP data in Cost Reports.
## Migrate from Standard Azure Integration
If you currently have a standard Azure integration but are part of the Microsoft Partner program with a CSP account, it is recommended that you migrate to the Azure CSP integration for more accurate costs. The Azure CSP integration provides access to CSP-specific discounts and SKUs, such as Partner Earned Credits and New Commerce Experience (NCE) Licenses, which are not available in the standard Azure integration.
Add the Azure CSP integration following the steps in this documentation.
Once costs are ingested, analyze the integration costs to ensure they match your current invoices.
After confirming the costs are accurate, you can delete your previous Azure integration.
# Azure EA Account
Source: https://docs.vantage.sh/connecting_azure_ea
Learn how to integrate Vantage with Azure EA.
With the Azure EA integration, you allow the service principal to have access at the billing scope level.
When you configure this integration, the Vantage service principal is granted **enrollment reader** permissions. The service principal does *not* have permissions—nor will it ever attempt—to make any changes to your infrastructure.
You must have a Vantage **Organization Owner** or **Integration Owner** role to add or remove this integration. See the [Role-Based Access Control](/rbac) documentation for details.
To integrate your Azure EA account with Vantage, follow the below steps:
If your organization restricts access to the provider by IP address, add the following Vantage IP addresses to your provider's allowlist:
## Step 1 - Create a New Application Registration
From the main page of the Azure portal, search for and navigate to **Microsoft Entra ID**.
In the left navigation, under **Manage**, select **App registrations**.
Click **+ New registration**.

The **Register an application** screen is displayed. For **Name**, enter *vantage*.
Leave all other settings as their defaults and click **Register**.

The app details are displayed. Record the **Application (client) ID** and **Directory (tenant) ID** to use later.

## Step 2 - Generate a Client Secret
On the same page, next to the **Client credentials** field, click **Add a certificate or secret**. (You can also access the **Certificates and secrets** screen from the left navigation menu.)
Click **+ New client secret**.
The **Add a client secret** pane is displayed. For **Description**, enter a description, such as *vantage-secret*.

For **Expires**, select an expiration option for the secret.
If this secret expires, you will need to supply Vantage with a new secret *before* the expiration date.
Click **Add**.
The newly created secret is displayed. Copy the secret's **Value** to add to the Vantage console later. This value will be displayed only one time.
## Step 3 - Obtain Your Billing Account ID
Navigate to **Cost Management + Billing**.
On the left menu, click **Billing scopes** and select your **EA Billing Account** from the list.
On the left menu, click **Settings** > **Properties**.
Copy your **Billing Account Id** to add to the Vantage console later.
## Step 4 - Assign Enrollment Reader Permission to the Service Principal
You need to have the **billing account owner** role permissions to assign enrollment reader permissions to the service principal. The below steps are based on the [Azure documentation](https://learn.microsoft.com/en-us/azure/cost-management-billing/manage/assign-roles-azure-service-principals).
Navigate to **Microsoft Entra ID**, then select **Enterprise applications**.
From the **All applications** list, select the *vantage* application you previously created.

*Source: Microsoft*
Under **Properties**, copy the **Application ID** and **Object ID**.

*Source: Microsoft*
Open the [*Role Assignments - Put* article](https://learn.microsoft.com/en-us/rest/api/billing/role-assignments/put?view=rest-billing-2019-10-01-preview\&tabs=HTTP) from the Microsoft documentation in a new tab.
Next to the *Create or update a billing role assignment* step, click **Try It**.

*Source: Microsoft*
A login screen is displayed on the right. Using your account credentials, log in to the tenant that you want to assign enrollment reader access.
An API request form is displayed. In the **Parameters** section add the following values:
* `billingAccountName`: Add the **billing account ID** you obtained in step 3.
* `billingRoleAssignmentName`: Generate a unique GUID using [a GUID generator](https://guidgenerator.com/), as suggested by Microsoft.
* `api-version`: Use `2019-10-01-preview`.
In the **Body** section, copy and paste the request body below.
```
{"properties": { "principalId": "", "principalTenantId": "", "roleDefinitionId": "/providers/Microsoft.Billing/billingAccounts//billingRoleDefinitions/24f8edb6-1668-4659-b5e2-40bb5f3a7d7e"}}
```
Update placeholders in the **Body** as follows:
* `principalId`: The **Object ID** you copied at the beginning of this section.
* `principalTenantId`: Your **Directory (tenant) ID** that you copied in step 1.
* `roleDefinitionId`: Replace `` with the **Billing account id** you copied in step 3.
* Note that `24f8edb6-1668-4659-b5e2-40bb5f3a7d7e` is the billing role definition ID for an [EnrollmentReader](https://learn.microsoft.com/en-us/azure/cost-management-billing/manage/assign-roles-azure-service-principals#permissions-that-can-be-assigned-to-the-service-principal).

*Source: Microsoft*
Click **Run**. You should see a `200 OK` response, indicating that the request was successful.
If you receive an error, see the [Troubleshoot section](https://learn.microsoft.com/en-us/azure/cost-management-billing/manage/assign-roles-azure-service-principals#troubleshoot) of the Microsoft article these instructions were based on.
## Step 5 - Add App Registration Credentials to Vantage
Navigate to the [Integrations page](https://console.vantage.sh/settings/integrations) in the Vantage console, and add an Azure EA integration.
On the Azure EA integration page, click **Add Credentials**.
Add the following credentials:
* For **Azure AD Tenant ID**, add the **Directory (tenant) ID** you obtained in step 1.
* For **Service Principal App ID**, add the **Application (client) ID** you obtained in step 1.
* For **Service Principal Password**, add the client secret you obtained in step 2.
* For **Billing Account Id**, add the **Billing Account Id** you obtained in step 3.
Click **Connect Account**.
After completing the connection, you will see the status of your integration change to **Importing** within the Vantage console. This status indicates that Vantage is actively importing your Azure cost data. See the [Integration Status](/vantage_account#integration-status) documentation for details on integration statuses. On initial connection, Vantage imports the previous six months of Azure cost data. From that point forward, each new month is added as it is billed, so your available history grows over time up to your account's [data retention](/vantage_account#data-retention) period. Because Vantage stores its own copy of your cost data, months Vantage has already imported remain available even after Azure's billing APIs stop returning them.
## Step 6 - Grant Reader Access for Active Resources and Recommendations
Steps 1-5 grant **enrollment reader** access, which is sufficient for importing Azure **cost data** into Cost Reports. Enrollment reader does *not* grant access to your resource inventory, so this step is required to use Active Resources and recommendations.
To populate the [Active Resources](/active_resources) tab and Azure [cost recommendations](/connecting_azure#azure-cost-recommendations), the same *vantage* service principal must also be granted the built-in **Reader** role at the **subscription** scope. This is required even when EA billing access is already configured, because Vantage reads your resource inventory through the Azure Resource Manager APIs, which enrollment reader does not cover.
Assign the **Reader** role using the Azure CLI, repeating the command for each subscription you want inventoried:
```bash theme={null}
az role assignment create --assignee --role Reader --scope "/subscriptions/"
```
You can also assign the **Reader** role through the Azure portal by following the [portal instructions](/connecting_azure#step-3-grant-the-service-principal-permissions) from the standard Azure integration.
After granting the **Reader** role:
* Wait for the next daily sync. Resources can take up to \~24 hours to appear. See the [Active Resources](/active_resources) documentation for details.
* Confirm the Azure integration is [assigned to the workspace](/workspaces#manage-workspace-provider-integrations) you're viewing, as resources only appear in workspaces where the integration is enabled.
## Optional Azure Reservations and Savings Plans
Steps 1-5 above are sufficient for importing Azure cost data into Vantage.
If you also want Azure Reservations and Azure Savings Plans to appear on the [Commitments](/commitments) page, continue to [Optional Azure Reservations and Savings Plans](/connecting_azure#optional-azure-reservations-and-savings-plans) and complete the additional permission steps there.
## Update Your Client Secret
If you need to update your Azure EA integration's client secret, see the [Update Your Client Secret](/connecting_azure#update-your-client-secret) section in the main Azure connection documentation for detailed instructions.
## Next Steps - Workspace Access
Once the import is complete and the integration status changes to **Stable**, you can select which workspaces this integration is associated with. See the [Workspaces](/workspaces#manage-workspace-provider-integrations) documentation for information.
# Azure MCA Account
Source: https://docs.vantage.sh/connecting_azure_mca
Learn how to integrate Vantage with Azure MCA.
With the Azure MCA integration, you allow the Vantage service principal to have access at the billing scope level.
When you configure this integration, the Vantage service principal is granted **billing account reader** permissions. The service principal does *not* have permissions—nor will it ever attempt—to make any changes to your infrastructure.
You must have a Vantage **Organization Owner** or **Integration Owner** role to add or remove this integration. See the [Role-Based Access Control](/rbac) documentation for details.
To integrate your Azure MCA account with Vantage, follow the below steps:
If your organization restricts access to the provider by IP address, add the following Vantage IP addresses to your provider's allowlist:
## Step 1 - Create a New Application Registration
From the main page of the Azure portal, search for and navigate to **Microsoft Entra ID**.
In the left navigation, under **Manage**, select **App registrations**.
Click **+ New registration**.

The **Register an application** screen is displayed. For **Name**, enter *vantage*.
Leave all other settings as their defaults and click **Register**.

The app details are displayed. Record the **Application (client) ID** and **Directory (tenant) ID** to use later.

## Step 2 - Generate a Client Secret
On the same page, next to the **Client credentials** field, click **Add a certificate or secret**. (You can also access the **Certificates and secrets** screen from the left navigation menu.)
Click **+ New client secret**.
The **Add a client secret** pane is displayed. For **Description**, enter a description, such as *vantage-secret*.

For **Expires**, select an expiration option for the secret.
If this secret expires, you will need to supply Vantage with a new secret *before* the expiration date.
Click **Add**.
The newly created secret is displayed. Copy the secret's **Value** to add to the Vantage console later. This value will be displayed only one time.
## Step 3 - Obtain Your Billing Account ID
Navigate to **Cost Management + Billing**.
On the left menu, click **Billing scopes** and select your **MCA Billing Account** from the list.
On the left menu, click **Settings** > **Properties**.
Copy your **Billing account id** to add to the Vantage console later.

*Source: Microsoft*
## Step 4 - Assign the Billing Account Reader Role to the Service Principal
From the left menu, select **Access Control (IAM)**.
At the top, click **Add**.
On the right **Add role assignment** pane, select **Billing account reader**.

Under **Users, groups, or apps**, search for and select the *vantage* service principal that was generated when you created the app registration in step 1.
Click **Add**.
## Step 5 - Add App Registration Credentials to Vantage
Navigate to the [Integrations page](https://console.vantage.sh/settings/integrations) in the Vantage console, and add an Azure integration.
On the Azure integration page, click **Add Credentials**.
Add the following credentials:
* For **Azure AD Tenant ID**, add the **Directory (tenant) ID** you obtained in step 1.
* For **Service Principal App ID**, add the **Application (client) ID** you obtained in step 1.
* For **Service Principal Password**, add the client secret you obtained in step 2.
* For **Billing Account Id**, add the **Billing Account Id** you obtained in step 3.
Click **Connect Account**.
After completing the connection, you will see the status of your integration change to **Importing** within the Vantage console. This status indicates that Vantage is actively importing your Azure cost data. See the [Integration Status](/vantage_account#integration-status) documentation for details on integration statuses. On initial connection, Vantage imports the previous six months of Azure cost data. From that point forward, each new month is added as it is billed, so your available history grows over time up to your account's [data retention](/vantage_account#data-retention) period. Because Vantage stores its own copy of your cost data, months Vantage has already imported remain available even after Azure's billing APIs stop returning them.
## Step 6 - Grant Reader Access for Active Resources and Recommendations
Steps 1-5 grant **billing account reader** access, which is sufficient for importing Azure **cost data** into Cost Reports. Billing account reader does *not* grant access to your resource inventory, so this step is required to use Active Resources and recommendations.
To populate the [Active Resources](/active_resources) tab and Azure [cost recommendations](/connecting_azure#azure-cost-recommendations), the same *vantage* service principal must also be granted the built-in **Reader** role at the **subscription** scope. This is required even when MCA billing access is already configured, because Vantage reads your resource inventory through the Azure Resource Manager APIs, which billing account reader does not cover.
Assign the **Reader** role using the Azure CLI, repeating the command for each subscription you want inventoried:
```bash theme={null}
az role assignment create --assignee --role Reader --scope "/subscriptions/"
```
You can also assign the **Reader** role through the Azure portal by following the [portal instructions](/connecting_azure#step-3-grant-the-service-principal-permissions) from the standard Azure integration.
After granting the **Reader** role:
* Wait for the next daily sync. Resources can take up to \~24 hours to appear. See the [Active Resources](/active_resources) documentation for details.
* Confirm the Azure integration is [assigned to the workspace](/workspaces#manage-workspace-provider-integrations) you're viewing, as resources only appear in workspaces where the integration is enabled.
## Optional Azure Reservations and Savings Plans
Steps 1-5 above are sufficient for importing Azure cost data into Vantage.
If you also want Azure Reservations and Azure Savings Plans to appear on the [Commitments](/commitments) page, continue to [Optional Azure Reservations and Savings Plans](/connecting_azure#optional-azure-reservations-and-savings-plans) and complete the additional permission steps there.
## Update Your Client Secret
If you need to update your Azure MCA integration's client secret, see the [Update Your Client Secret](/connecting_azure#update-your-client-secret) section in the main Azure connection documentation for detailed instructions.
## Next Steps - Workspace Access
Once the import is complete and the integration status changes to **Stable**, you can select which workspaces this integration is associated with. See the [Workspaces](/workspaces#manage-workspace-provider-integrations) documentation for information.
# Baseten
Source: https://docs.vantage.sh/connecting_baseten
Learn how to integrate Vantage with Baseten to track AI inference, training, and Model API costs.
Vantage integrates with your Baseten account using an API key to ingest cost and usage data through the Baseten [Billing Usage Summary API](https://docs.baseten.co/reference/management-api/billing/gets-billing-usage-summary-for-a-date-range). Vantage retrieves detailed cost and usage data broken down by product line (Dedicated Inference, Training, and Model APIs), model deployment, instance type, environment, and model. [Usage data](/usage_based_reporting) is available for Baseten, measured in hours for Dedicated Inference and Training, and in tokens for Model APIs.
## Baseten Permissions
Vantage connects to Baseten using an API key and validates access by reading billing usage summary data. Vantage cannot deploy models, trigger inference or training jobs, or perform any actions that incur costs in your Baseten account.
You must be a Team Admin (or organization Admin) to create a Team API key. See the [Baseten API keys](https://docs.baseten.co/organization/api-keys) and [Teams](https://docs.baseten.co/organization/teams) documentation for details. It's best practice to create a dedicated Team API key for Vantage and rotate it according to your organization's security policy.
To access the Baseten Billing Usage Summary API, the Team API key must be created with the **Manage and call all team models** permission level. This grants additional permissions beyond what Vantage uses; however, Vantage only reads data from the Billing Usage Summary API endpoint related to usage, and will never perform any other actions. Baseten does not currently support fine-grained permissions for Team API keys. We recommend submitting a feature request to Baseten for improved permission scoping, and Vantage will adopt fine-grained permissions if this becomes available.
## Connect Your Baseten Account
### Prerequisites
* You must have a Vantage **Organization Owner** or **Integration Owner** role to add or remove this integration. See the [Role-Based Access Control](/rbac) documentation for details.
* You must be a Team Admin (or organization Admin) in Baseten to create a Team API key.
* [Create a free Vantage account](https://console.vantage.sh/signup), then follow the steps below to integrate Baseten costs.
If your organization restricts access to the provider by IP address, add the following Vantage IP addresses to your provider's allowlist:
### Create the Connection
Sign in to the [Baseten console](https://app.baseten.co) and click **API Keys** in the sidebar.
Click **Create API key**.
Give the key a descriptive name, select **Team** as the type, and click **Next**.
Select **Manage and call all team models** as the permission level, then click **Create API key**.
Copy the API key.
Baseten only shows the API key once. Save it securely before closing the dialog.
From the top navigation in Vantage, click **Settings**.
On the left navigation, select **Integrations** > **Baseten**.
The Baseten integrations page is displayed. Ensure you are on the **Connect** tab.
Click **Add API Key** and complete the integration form:
* **API Key**: Paste the Baseten Team API key.
* **Description**: Enter a label to identify this Baseten account or workspace in Vantage. This value is used as the **Organization** dimension in Cost Report filters.
Click **Connect Account**.
After clicking **Connect Account**, you will see the status of your integration change to **Importing** within the Vantage console. This status indicates that Vantage is actively importing your Baseten cost data. Vantage backfills up to six months of historical cost data upon initial connection. See the [Integration Status](/vantage_account#integration-status) documentation for details on integration statuses. You can connect multiple Baseten organizations, each with its own API key, as separate integrations in Vantage.
As soon as costs are processed, they will be available on your **All Resources** Cost Report. If you decide to remove your Baseten integration from Vantage, all costs associated with that Baseten API key will be removed from the Vantage console.
### Next Steps - Manage Workspace Access
Once the import is complete and the integration status changes to **Stable**, you can select which workspaces this integration is associated with. See the [Workspaces](/workspaces#manage-workspace-provider-integrations) documentation for information.
## Data Refresh
See the [provider data refresh documentation](/provider_data_refresh) for information on when data for each provider refreshes in Vantage. Baseten data refreshes once daily.
## Baseten Reporting Dimensions
On Baseten [Cost Reports](/cost_reports), you can filter and group across several dimensions:
* Organization (the description you enter when connecting the integration)
* Service (i.e., the Baseten product line, such as Dedicated Inference, Training, or Model APIs)
* Category (i.e., the model name)
* Subcategory (i.e., the instance type for Dedicated Inference and Training, such as `H100`; or the token type for Model APIs, such as Input Tokens, Cached Input Tokens, or Output Tokens)
* Resource (i.e., the deployment or job ID for Dedicated Inference and Training, or the model name for Model APIs)
* Charge Type (Usage or Credit)
In addition, Baseten costs include the following provider tags, which are automatically created by Vantage and available for filtering and grouping alongside any [Virtual Tags](/tagging) you create:
| Tag | Description |
| - | - |
| `baseten:model_name` | The model name associated with the usage |
| `baseten:deployment` | The deployment name for Dedicated Inference |
| `baseten:instance_type` | The instance type backing a dedicated deployment or training job (e.g., `H100`) |
| `baseten:environment` | The Baseten environment name (e.g., `production`) |
| `baseten:resource_kind` | The billable resource kind for Dedicated Inference (e.g., `MODEL_DEPLOYMENT`) |
| `baseten:resource_id` | The billable resource ID for Training jobs |
| `baseten:kind` | The resource kind for Training jobs |
| `baseten:is_deleted` | Whether the Training resource has been deleted |
| `baseten:chain_id` | The Chain ID when training is associated with a Chain |
| `baseten:chain_deployment_id` | The Chain deployment ID when present |
| `baseten:chain_name` | The Chain name when present |
| `baseten:model_family` | The model family for Model APIs usage (e.g., `ZAI`) |
Vantage also applies [Managed AI Tags](/managed_ai_tags) to Baseten costs. This is a normalized `vntg:ai:` schema shared across all AI providers, so you can analyze AI spend with consistent dimensions. For Baseten, the following keys are emitted: `vntg:ai:model`, `vntg:ai:model_provider`, and `vntg:ai:token_type`. See [Managed AI Tags](/managed_ai_tags) for the full schema.
Historical cost attribution is preserved for deleted or torn-down deployments. The Baseten billing API continues to return deleted resources in the cost breakdown, so spend from a model deployment that has since been torn down still appears in your historical Baseten reports.
# Cartesia
Source: https://docs.vantage.sh/connecting_cartesia
Learn how to integrate Vantage with Cartesia to track voice AI cost and usage.
Vantage integrates with your Cartesia account using an Admin API key to ingest cost and usage data through Cartesia's [credit usage](https://docs.cartesia.ai/api-reference/usage/credits) and [agent usage](https://docs.cartesia.ai/api-reference/usage/agents) APIs. Vantage retrieves model usage broken down by the capability name Cartesia reports (for example, Text-to-Speech or Pro Voice Cloning), measured in credits, and Line agent usage, measured in minutes and reported in US dollars. [Usage data](/usage_based_reporting) is available for Cartesia, measured in credits for model capabilities and in minutes for Line agents.
Cartesia meters two types of usage separately:
* **Model capabilities:** Capabilities such as Text-to-Speech, Pro Voice Cloning, and Localization are metered in credits, which are an entitlement unit rather than US dollars. By default, Vantage reports the credit usage without a dollar amount. To calculate a cost from credit usage, enter a negotiated **Price per 1,000 credits** when connecting (see below).
* **Line agents:** Metered in US dollars and minutes, so Vantage reports their cost directly.
The Cartesia usage APIs cover credit consumption and Line agent usage only. They do not include monthly subscription fees, prepaid balances, or other recurring invoice line items. This integration covers usage billed through Cartesia and reported by Cartesia's usage APIs for the connected Admin API key.
## Cartesia Permissions
Vantage connects to Cartesia using an Admin API key and validates access by reading credit usage data. Vantage cannot generate speech or transcription, deploy voices, or perform any actions that incur costs in your Cartesia account.
Vantage stores only billing metadata (credit counts, Line agent costs, minutes, and call counts). No audio, transcript, or prompt content is ingested or stored.
You must use an **Admin API key** (which begins with `sk_car_admin_`), created by a Cartesia organization admin. Standard generation API keys cannot access the usage endpoints and will not work. It's best practice to create a dedicated Admin API key for Vantage and rotate it according to your organization's security policy.
## Connect Your Cartesia Account
### Prerequisites
* You must have a Vantage **Organization Owner** or **Integration Owner** role to add or remove this integration. See the [Role-Based Access Control](/rbac) documentation for details.
* You must be a Cartesia organization admin to create an Admin API key.
* [Create a free Vantage account](https://console.vantage.sh/signup), then follow the steps below to integrate Cartesia costs.
If your organization restricts access to the provider by IP address, add the following Vantage IP addresses to your provider's allowlist:
### Create the Connection
Go to the [Cartesia dashboard](https://play.cartesia.ai) and sign in as an organization admin.
In the left navigation, under **Manage**, select **API Keys**.
On the **API Keys** page, select the **Admin** tab.
Click **+ Create admin API key**. Enter a name for the key, then immediately copy it.
From the top navigation in Vantage, click **Settings**.
On the left navigation, select **Integrations** > **Cartesia**.
The Cartesia integration page is displayed. Ensure you are on the **Connect** tab.
Click **Add Account** and complete the integration form:
* **Admin API Key**: Paste the Cartesia Admin API key.
* **Description**: Enter a label to identify this Cartesia account or workspace in Vantage. This value is used as the **Account** dimension in Cost Report filters.
* **Credit rate**: Choose how Vantage should report costs for credit-based model usage:
* **Leave unrated** (the default): Vantage reports credit usage without a dollar amount, since Cartesia credits are not US dollars.
* **Use my own negotiated rate**: Enter your **Price per 1,000 credits (USD)** so Vantage can calculate a cost from credit usage. You can add multiple rates with optional start and end dates if your pricing has changed over time. Line agent costs are always reported in US dollars regardless of this setting.
Click **Connect Account**.
After clicking **Connect Account**, you will see the status of your integration change to **Importing** within the Vantage console. This status indicates that Vantage is actively importing your Cartesia cost data. Vantage backfills up to six months of historical cost data upon initial connection. See the [Integration Status](/vantage_account#integration-status) documentation for details on integration statuses. You can connect multiple Cartesia accounts, each with its own Admin API key, as separate integrations in Vantage.
As soon as costs are processed, they will be available on your **All Resources** Cost Report. If you decide to remove your Cartesia integration from Vantage, all costs associated with that Admin API key will be removed from the Vantage console.
### Update Integration Settings
After connecting, you can update an existing Cartesia integration in place from the [Cartesia integration settings page](https://console.vantage.sh/settings/cartesia), without removing and re-adding it:
* **Credit rate**: Add or update your **Price per 1,000 credits (USD)**, or switch between unrated and a negotiated rate. Vantage recalculates the affected credit-based costs from your existing usage data, so you do not need to reconnect. You can enter multiple rates with optional start and end dates if your pricing has changed over time.
* **Admin API Key**: Rotate the Cartesia Admin API key (for example, when your existing key expires) while keeping the integration and its historical cost data intact.
### Next Steps - Manage Workspace Access
Once the import is complete and the integration status changes to **Stable**, you can select which workspaces this integration is associated with. See the [Workspaces](/workspaces#manage-workspace-provider-integrations) documentation for information.
## Data Refresh
See the [provider data refresh documentation](/provider_data_refresh) for information on when data for each provider refreshes in Vantage.
## Cartesia Reporting Dimensions
On Cartesia [Cost Reports](/cost_reports), you can filter and group across several dimensions:
* Account (the description you enter when connecting the integration; also available as **Billing Account** for filtering and grouping)
* Service (i.e., the capability name Cartesia reports for credit usage, such as Text-to-Speech, Pro Voice Cloning, or Localization; or `Line agents` for Line agent usage)
* Category (i.e., `Credits` for model capability usage or `Agents` for Line agent usage)
* Charge Type (Usage)
[Usage data](/usage_based_reporting) is reported in **credits** for model capabilities and in **minutes** for Line agents.
Cartesia costs do not include provider tags or [Managed AI Tags](/managed_ai_tags) at this time. Credit-based model usage is grouped by capability, so individual models, voices, and API keys are not broken out as separate dimensions.
# CircleCI
Source: https://docs.vantage.sh/connecting_circle_ci
Learn how to integrate Vantage with CircleCI.
Vantage uses a personal API token and your organization UUID to ingest cost and usage data through CircleCI's [Usage Export API](https://circleci.com/docs/api/v2/index.html?section=reference#tag/Usage). Vantage converts CircleCI credits into USD using the price per credit that you enter during setup. [Usage data](/usage_based_reporting) is available for CircleCI in Vantage and is measured in Credits.
Vantage uses a personal API token to access CircleCI's Usage Export API and read usage data for your organization. Vantage only reads usage data from CircleCI and cannot make changes to your organization, pipelines, or projects.
CircleCI does not currently offer more fine-grained permission scoping for the personal API token required by this integration. We recommend customers submit a feature request to CircleCI for improved permission scoping, and Vantage will adopt finer-grained permissions if they become available.
You can connect multiple CircleCI organizations by creating multiple integrations in Vantage.
## Connect Your CircleCI Account
### Prerequisites
* You need to be an [Org Admin](https://circleci.com/docs/guides/permissions-authentication/roles-and-permissions-overview/) to generate a personal API token compatible with the createUsageReport API. It’s best practice to use a dedicated token for Vantage and rotate it per your security policy.
* You must have a Vantage **Organization Owner** or **Integration Owner** role to add or remove this integration. See the [Role-Based Access Control](/rbac) documentation for details.
* [Create a free Vantage account](https://console.vantage.sh/signup), then follow the steps below to integrate CircleCI costs.
If your organization restricts access to the provider by IP address, add the following Vantage IP addresses to your provider's allowlist:
### Create the Connection
In CircleCI, click your avatar on the top right and navigate to **User Settings > Personal API Tokens**.
Create a new personal API token and copy the generated value.
In CircleCI, navigate to **Organization Settings > Overview** for the organization that you want to connect.
Copy the **Organization ID**.
From the top navigation in Vantage, click **Settings**.
On the left navigation, select **Integrations** > **CircleCI**.
The CircleCI integrations page is displayed. Ensure you are on the **Connect** tab.
At the bottom of the page, click **Add organization**.
Complete the integration form:
* **CircleCI API token**: Paste the personal API token you created in CircleCI.
* **Organization ID (UUID)**: Paste the organization UUID from CircleCI.
* **Description**: Enter a label to identify this connection in Vantage.
* **Price per credit (USD)**: Enter your effective cost for one CircleCI credit.
Click **Connect Account**.
After clicking **Connect Account**, you will see the status of your integration change to **Importing** within the Vantage console. This status indicates that Vantage is actively importing your CircleCI cost data, including up to six months of historical CircleCI usage data on initial setup. Ongoing retention follows your Vantage data retention settings. See the [Integration Status](/vantage_account#integration-status) documentation for details on integration statuses.
If you remove the integration, all CircleCI costs associated with that organization will be removed from the Vantage console.
### Update Integration Settings
After connecting, you can update an existing CircleCI integration in place from **Settings** > **Integrations** > **CircleCI**, without removing and re-adding it:
* **Price per credit (USD)**: Update your effective cost per CircleCI credit and save the change.
* **CircleCI API token**: Rotate the personal API token (for example, when your existing token expires) while keeping the integration and its historical cost data intact.
### Next Steps - Manage Workspace Access
Once the import is complete and the integration status changes to **Stable**, you can select which workspaces this integration is associated with. See the [Workspaces](/workspaces#manage-workspace-provider-integrations) documentation for information.
## Data Refresh
See the [provider data refresh documentation](/provider_data_refresh) for information on when data for each provider refreshes in Vantage.
## CircleCI Reporting Dimensions
On CircleCI [Cost Reports](/cost_reports), you can filter and group across several dimensions:
* Billing Account (organization name)
* Account (project name)
* Service (e.g., Compute, Storage, Users, Network, DLC, Lease, Lease Overage, IP Ranges)
* Category (for example, the operating system and executor combination)
* Subcategory (resource class)
* Resource (job name)
* Charge Type (Usage)
* Tags: CircleCI does not expose native tags for this integration. You can still use [Virtual Tags](/tagging) in Vantage, and the following provider metadata tags are automatically created by Vantage from CircleCI data and are available for filtering and grouping:
* `circleci:organization_id`: The CircleCI organization UUID associated with the usage line item.
* `circleci:project_id`: The CircleCI project ID associated with the usage line item.
* `circleci:vcs_name`: The version control system name associated with the job.
* `circleci:vcs_url`: The version control repository URL associated with the job.
* `circleci:vcs_branch`: The version control branch associated with the job.
* `circleci:pipeline_id`: The CircleCI pipeline ID associated with the job.
* `circleci:job_build_status`: The job build status associated with the usage line item.
# ClickHouse Cloud
Source: https://docs.vantage.sh/connecting_clickhouse
Learn how to integrate Vantage with ClickHouse Cloud.
Vantage connects to your ClickHouse Cloud account via a read-only API key with the **Billing** and **Service reader** roles to ingest ClickHouse usage, costs, and discounts from ClickHouse's Organization [usageCost API](https://clickhouse.com/docs/cloud/manage/api/usageCost-api-reference). The **Billing** role grants the `control-plane:organization:view-billing` permission that the `usageCost` API requires. Vantage displays ClickHouse Cloud costs and associated [usage metrics](/usage_based_reporting).
The ClickHouse Organizations usageCost API only supports ClickHouse Cloud and Bring Your Own Cloud (BYOC).
You can view usage data for ClickHouse Cloud consumption. Usage is measured by the following subcategories:
* Compute
* Storage
* [Data transfer](https://clickhouse.com/docs/cloud/manage/network-data-transfer) (egress over the internet and cross-region)
* [ClickPipes](https://clickhouse.com/docs/integrations/clickpipes)
Usage is measured in ClickHouse Cloud Credits (CHCs), which is a metering unit used by ClickHouse.
You can learn more about CHCs through [ClickHouse Billing documentation](https://clickhouse.com/docs/en/cloud/manage/jan-2025-faq/billing).
You can integrate multiple ClickHouse Cloud integrations by providing read-only tokens for multiple organizations.
## Connect Your ClickHouse Cloud Account
### Prerequisites
* You must have a Vantage **Organization Owner** or **Integration Owner** role to add or remove this integration. See the [Role-Based Access Control](/rbac) documentation for details.
* Create a free Vantage account, then follow the steps below to integrate ClickHouse Cloud costs.
Vantage cannot perform writes to your ClickHouse Cloud organization. Vantage is only able to see metadata associated with your usage.
### Create the Connection
The below instructions for creating an API key are based on the [ClickHouse documentation](https://clickhouse.com/docs/cloud/manage/openapi).
If you created your Vantage API key before ClickHouse required the `control-plane:organization:view-billing` permission, edit the existing key in ClickHouse Cloud (**Settings** → **API keys**) to include the **Billing** role. You do not need to re-enter your credentials in Vantage as long as the same Key ID and Key Secret remain valid.
In the ClickHouse Cloud console, navigate to the **Settings** menu. Then, select **API keys**.
Click **+ New API key**.

Add the following key details:
* For **API key name**, enter *vantage*.
* For **Expiration date**, select an expiration date. If the key expires, you will need to supply Vantage with a new ClickHouse Cloud API key.
* For **Roles**, select both **Billing** and **Service reader**. The **Billing** role includes the `control-plane:organization:view-billing` permission that ClickHouse's `usageCost` API requires. (You can read more about roles and permissions in the [ClickHouse console roles documentation](https://clickhouse.com/docs/products/cloud/reference/security/console-roles).)
* For **Allow access to this API key from**, select **Anywhere**.
The API key must include the **Billing** role, which grants the `control-plane:organization:view-billing` permission. ClickHouse's `usageCost` API requires this permission; API keys without it fail with a `403 FORBIDDEN` error and data ingestion stops.
**Using ClickHouse Business Metrics?** [ClickHouse Business Metrics](/business_metrics#import-via-clickhouse) let you import a business metric from a saved query in ClickHouse Cloud. Vantage runs that query through a [query API endpoint](https://clickhouse.com/docs/cloud/get-started/query-endpoints), which you grant to this API key from the saved query's **Share** menu. The **Billing** and **Service reader** roles above are sufficient; you do not need an additional role. The database role you select on the endpoint determines which tables the query can read.

Click **Generate API Key**.
If you have any IP restrictions set, ensure you allow the following IP addresses for Vantage:
Copy the newly generated **Key ID** and **Key Secret**.

From the top navigation in Vantage, click **Settings**.
On the left navigation, select **Integrations** and select **ClickHouse Cloud**.
The ClickHouse Cloud integrations page is displayed. Ensure you are on the **Connect** tab.
At the bottom of the page, click **Add API Key** and paste your newly generated API key and secret.
For **Organization ID**, add the ClickHouse Cloud Organization ID that was assigned to your organization during creation. To find this ID:
* From the **Settings** navigation menu, under **Organization**, select your organization and click **Organization details**.
* Copy the value displayed next to **Organization ID** and paste this in the Vantage integration form.

Click **Connect Account**.
After adding your integration, you will see the status of your integration change to **Importing** within the Vantage console. This status indicates that Vantage is actively importing your ClickHouse Cloud cost data. See the [Integration Status](/vantage_account#integration-status) documentation for details on integration statuses.
As soon as costs are processed, they will be available on your All Resources Cost Report. If you decide to remove your ClickHouse Cloud integration from Vantage, all costs associated with your ClickHouse Cloud API key will be removed from the Vantage console.
### Next Steps - Manage Workspace Access
Once the import is complete and the integration status changes to **Stable**, you can select which workspaces this integration is associated with. See the [Workspaces](/workspaces#manage-workspace-provider-integrations) documentation for information.
## Data Refresh
See the [provider data refresh documentation](/provider_data_refresh) for information on when data for each provider refreshes in Vantage.
## Active Resources
ClickHouse Cloud services are synced as active resources and available in [resource reports](/active_resources).
## ClickHouse Cloud Reporting Dimensions
On ClickHouse Cloud [Cost Reports](/cost_reports), you can filter across several dimensions:
* Organization (i.e., billing account)
* Service (e.g., ClickHouse Cloud)
* Category (e.g., datawarehouse or service)
* Subcategory (e.g., specific usage category, like `interRegionTier1DataTransferCHC` or `publicDataTransferCHC`)
* Resource (specific ID for a given ClickHouse cluster)
* Tags: Includes [Virtual Tags](/tagging) created in Vantage for this provider. The following provider tag is automatically created by Vantage from ClickHouse data and is available for filtering and grouping:
* `clickhouse:entityName`: The entity name associated with the cost, allowing you to filter and group costs by entity name.
* Charge Type (e.g., usage)
You can also view credits or discounts for ClickHouse Cloud costs in Cost Reports.
1. At the top of any ClickHouse Cloud Cost Report, click **Settings**.
2. Then, toggle on/off **Credits** and/or **Discounts**.
## View ClickHouse Metrics on Cost Reports
You can import ClickHouse Cloud query results as business metrics to view alongside Cost Reports. ClickHouse business metric imports reuse a connected ClickHouse Cloud integration, but you save the query in ClickHouse Cloud and expose it as a query API endpoint that's shared with the API key you connected to Vantage. See the [Business Metrics](/business_metrics#import-via-clickhouse) documentation for more information.
# Cloudflare
Source: https://docs.vantage.sh/connecting_cloudflare
Learn how to integrate Vantage with Cloudflare.
Vantage connects to Cloudflare using an API token and account ID to ingest self-serve cost and [usage data](/usage_based_reporting) through the [Cloudflare API](https://developers.cloudflare.com/api/). Usage is measured in units such as requests, DNS queries, rows, and operations, depending on the service. You can connect multiple Cloudflare accounts by adding a separate API token for each; every account is tracked independently within Vantage.
This integration supports Cloudflare **self-serve** accounts. Vantage ingests self-serve (non-contract) usage only, and accounts whose subscriptions are entirely contract-based (for example, Enterprise contracts) are not supported. Accounts that mix self-serve and contract subscriptions are supported, and only the self-serve usage is imported. If you connect an account that has no self-serve usage, Vantage displays a message that no data will be imported and retains the integration setup until Enterprise cost data is supported. As a workaround, use [Custom Providers](/connecting_custom_providers) to import contract-only account costs.
## Cloudflare Permissions
Vantage uses your Cloudflare API token to read billing data only. The token requires the **Billing Read** permission. Vantage never creates, modifies, or deletes Cloudflare subscriptions or account settings.
## Connect Your Cloudflare Account
### Prerequisites
* You must have a Vantage **Organization Owner** or **Integration Owner** role to add or remove this integration. See the [Role-Based Access Control](/rbac) documentation for details.
* A Cloudflare self-serve account.
* Access to create a Cloudflare API token with the **Billing Read** permission. It's best practice to use a dedicated token for Vantage and rotate it per your security policy.
* [Create a free Vantage account](https://console.vantage.sh/signup), then follow the steps below to integrate Cloudflare costs.
If your organization restricts access to the provider by IP address, add the following Vantage IP addresses to your provider's allowlist:
### Create the Connection
From the [Cloudflare dashboard](https://dash.cloudflare.com/), click your profile icon in the top right and select **Profile**. Then, in the left menu, click **API Tokens**.
Click **Create Token** and use the **Create Custom Token** option.
Enter a name for the token. Then, under **Permissions**, select **Account**, then **Billing**, then **Read**.
Click **Continue to summary**, then click **Create Token**.
Copy the generated API token.
Find your **Account ID** in the Cloudflare dashboard URL. It's the 32-character ID that follows `dash.cloudflare.com/` (for example, `dash.cloudflare.com/`).
From the top navigation in Vantage, click **Settings**.
On the left navigation, select **Integrations**, then select **Cloudflare**. Ensure you are on the **Connect** tab.
Click **Add API Token**.
Paste your API token and Account ID, enter a **Description** to identify this connection, then click **Connect Account**.
After connecting, the integration status shows **Importing** while Vantage ingests your Cloudflare cost data. Once the import is complete, the status changes to **Stable**. See the [Integration Status](/vantage_account#integration-status) documentation for details.
When the integration is first connected, Vantage ingests up to **six months** of historical Cloudflare cost data. Data is retained according to your Vantage retention period. If you remove the Cloudflare integration from Vantage, all associated costs will be removed from the Vantage console.
### Next Steps - Manage Workspace Access
Once the integration status is **Stable**, you can select which workspaces this integration is associated with. See the [Workspaces](/workspaces#manage-workspace-provider-integrations) documentation for information.
## Data Refresh
See the [provider data refresh documentation](/provider_data_refresh) for information on when data for each provider refreshes in Vantage.
## Cloudflare Reporting Dimensions
On Cloudflare [Cost Reports](/cost_reports), you can filter and group across several dimensions:
* Account (the Cloudflare account ID, displayed using the description you set when connecting the integration)
* Service (e.g., Workers, R2, Cloudflare for SaaS)
* Category (the specific Cloudflare service line item)
* Charge Type (e.g., Usage)
* Tag ([Virtual Tags](/tagging) created in Vantage for this provider; Cloudflare billing data does not supply native tags)
Cloudflare cost and usage data has a single Charge Type, `Usage`. Toggling the discounts setting in [Cost Report](/cost_reports) settings on or off does not change Cloudflare cost data.
# Confluent
Source: https://docs.vantage.sh/connecting_confluent
Learn how to integrate Vantage with Confluent.
Vantage integrates with your Confluent account using a Confluent API key and secret to access the [Billing API](https://docs.confluent.io/cloud/current/billing/overview.html#retrieve-costs-for-a-range-of-dates). This endpoint provides structured cost data, broken down by category (e.g., Kafka or Connect), resource (e.g., Kafka Cluster), and subcategory (e.g., Kafka Storage or Connect Capacity).
Vantage currently supports the following Confluent products:
* Kafka
* Connect
* KSQL
* Audit Logs
* Cluster Links
* Custom Connect
* Support Cloud
## Connect Your Confluent Account
### Prerequisites
* You must have a Vantage **Organization Owner** or **Integration Owner** role to add or remove this integration. See the [Role-Based Access Control](/rbac) documentation for details.
* [Create a free Vantage account](https://console.vantage.sh/signup), then follow the steps below to generate a Confluent API key.
Vantage will never perform write operations and will only read from the Billing API and Organizations API.
If your organization restricts access to the provider by IP address, add the following Vantage IP addresses to your provider's allowlist:
### Create the Connection
Generate an API key, create a service account, then attach the right role to the service account.
#### Step 1 - Generate an API Key and Service Account
Log in to the [Confluent Cloud console](https://confluent.cloud/login).
From the top right of the console, click the hamburger menu.
Under **ADMINISTRATION**, click **API keys**.
Click **+ Add API key**.

For **Select an account for API key**, click **Service account**.
Select an existing service account or create a new one, then click **Next**.

For **Select resource scope for API key**, select **Cloud resource management**. Click **Next**.

Add a name and description for the key, then click **Create API key**.

Copy the displayed key and the secret to add to Vantage. You can also download a copy of the API key from this screen.

#### Step 2 - Add the `BillingAdmin` Role to the Service Account
From the top hamburger menu of the Confluent Cloud console, select **Accounts and access**.
On the **Accounts and access** page, select the **Service accounts** tab, then open the service account you associated with the integration API key.

Click the **Access** tab, then click **View access**.
On the **Resources this service account can access** slideout, click **Edit access**.

Click **+ Add role assignment**. Select the **BillingAdmin** role, then scroll down and click **Add**.

Click **Save**.
#### Step 3 - Add the API Key to the Vantage Console
From the top navigation in Vantage, click **Settings**.
On the left navigation, select **Integrations** and select **Confluent**.
The Confluent integrations page is displayed. Ensure you are on the **Connect** tab.
At the bottom of the page, click **Add API Key** and paste your newly generated **API key** and **API secret**.
Click **Connect Account**.
After adding your integration, you will see the status of your integration change to **Importing** within the Vantage console. This status indicates that Vantage is actively importing your Confluent cost data. See the [Integration Status](/vantage_account#integration-status) documentation for details on integration statuses.
As soon as the costs are processed, they will be available on your **All Resources** Cost Report. If you decide to remove your Confluent integration from Vantage, all costs associated with your Confluent API key will be removed from the Vantage console.
#### Next Steps - Manage Workspace Access
Once the import is complete and the integration status changes to **Stable**, you can select which workspaces this integration is associated with. See the [Workspaces](/workspaces#manage-workspace-provider-integrations) documentation for information.
## Data Refresh
See the [provider data refresh documentation](/provider_data_refresh) for information on when data for each provider refreshes in Vantage.
## Active Resources
Confluent Kafka Clusters are synced as active resources and available in [resource reports](/active_resources).
## Confluent Reporting Dimensions
On Confluent [Cost Reports](/cost_reports/), you can filter costs across several dimensions:
* Category (e.g., Kafka Storage)
* Tag ([virtual tags](/tagging) created in Vantage for this provider)
* Resource (resource service ID)
* Charge Type (e.g., Usage)
* Organization (organization ID)
* Service (e.g., Kafka)
You can also view credits or discounts for Confluent costs in Cost Reports.
1. At the top of any Confluent Cost Report, click **Settings**.
2. Then, toggle on/off **Credits** and/or **Discounts**.
# Coralogix
Source: https://docs.vantage.sh/connecting_coralogix
Learn how to integrate Vantage with Coralogix.
Vantage connects to Coralogix organizations through [gRPC API](https://grpc.io/) calls. After Vantage is authorized to access your Coralogix organization, Vantage will ingest data using the Coralogix [Data Usage Service API](https://coralogix.com/docs/developer-portal/apis/data-management/data-usage-service-api/) endpoints. No access is granted to the Coralogix-connected applications. Vantage can see only usage data related to the connected services.
Vantage supports the Logs, Metrics, and Spans services, as well as the [application and subsystem names](https://coralogix.com/docs/user-guides/account-management/account-settings/application-and-subsystem-names/) for your account. The subsystem name typically refers to the environment (e.g., production, development, or staging). The application name typically refers to the name of the service or applications that send your logs, metrics, and traces. Both the subsystem and application names can be customized, so your values may be different.
## Connect Your Coralogix Account
### Prerequisites
* You must have a Vantage **Organization Owner** or **Integration Owner** role to add or remove this integration. See the [Role-Based Access Control](/rbac) documentation for details.
* You will need to be an [Organization Admin](https://coralogix.com/docs/user-guides/account-management/organization-management/organization-admins/) in Coralogix.
* [Create a free Vantage account](https://console.vantage.sh/signup), then follow the steps below to connect to Coralogix.
If your organization restricts access to the provider by IP address, add the following Vantage IP addresses to your provider's allowlist:
### Create the Connection
Log in to the [Coralogix dashboard](https://dashboard.coralogix.com/).
If you experience issues logging in to your dashboard, your account may be using a different domain. Ensure you use the [correct domain](https://coralogix.com/docs/user-guides/account-management/account-settings/coralogix-domain/) to log in to your dashboard.
On the left, navigate to **Settings**. Under **Users and Teams**, select **API Keys**.
Click **+ Add key** and create a new Team key. Team keys are recommended for production integrations.
You can also use a Personal key; however, Coralogix recommends Team keys for production use. See the [Coralogix API keys documentation](https://coralogix.com/docs/user-guides/account-management/api-keys/api-keys/) for details on key types.
Add a recognizable key name. From the **Role Presets** dropdown, select the **DataUsage** preset. This preset grants the `data-usage:Read` and `data-usage:Manage` permissions required for the Vantage integration.
Click **Create**, then copy and save the generated key. If [API Key Security Settings](https://coralogix.com/docs/user-guides/account-management/api-keys/api-keys/#security) are enabled, you will have a one-time opportunity to view and copy the key.
If you are migrating from a legacy "Alerts, Rules and Tags" API key, you will need to create a new key with the **DataUsage** preset. Adding permissions to existing legacy keys may not work. See the [Coralogix migration guide](https://coralogix.com/docs/user-guides/account-management/api-keys/api-keys/#migrate-legacy-keys-to-custom-api-keys) for details.
Identify your Coralogix [domain](https://coralogix.com/docs/user-guides/account-management/account-settings/coralogix-domain/). You can find this from your Coralogix account URL. Copy the part of the domain after your team's name. For example, if your account URL is `https://test-team.cx498.coralogix.com/`, then copy only `cx498.coralogix.com`.
Navigate to the [Integrations page](https://console.vantage.sh/settings/integrations) in Vantage.
Select **Coralogix** and select the **Connect** tab.
At the bottom of the page, click **Add API Key**.
Enter your previously generated **API Key** and the **Domain** you copied.
Enter a **Description** for this connection. The **Description** is your team name and is also available in your Coralogix domain URL (e.g., in `https://test-team.cx498.coralogix.com/`, use `test-team`).
Click **Connect Account**.
After authorizing the connection, you will see the status of your integration change to **Importing** within the Vantage console. This status indicates that Vantage is actively importing your Coralogix cost data. See the [Integration Status](/vantage_account#integration-status) documentation for details on integration statuses.
Based on limits imposed by Coralogix, the integration includes 90 days of historical Coralogix usage and cost data. Once costs are processed, they will be available on your **All Resources** Cost Report.
### Next Steps - Manage Workspace Access
Once the import is complete and the integration status changes to **Stable**, you can select which workspaces this integration is associated with. See the [Workspaces](/workspaces#manage-workspace-provider-integrations) documentation for information.
## Data Refresh
See the [provider data refresh documentation](/provider_data_refresh) for information on when data for each provider refreshes in Vantage.
## Custom Discounts and Rates
If you have custom rates or discounts negotiated with Coralogix, Vantage can implement these into your cost calculations. Please contact [Vantage Support](mailto:support@vantage.sh) to set up custom rates. When using custom rates, please double-check your calculations and stay on top of any adjustments made to future rates so we can continue to update them accordingly.
## Coralogix Reporting Dimensions
On Coralogix [Cost Reports](/cost_reports/), you can filter costs across several dimensions:
* Service (e.g., Logs, Metrics, Spans)
* Category (subsystem name)
* Subcategory (application name)
* Tag ([virtual tags](/tagging) created in Vantage for this provider)
# Cursor
Source: https://docs.vantage.sh/connecting_cursor
Learn how to integrate Vantage with Cursor.
Vantage uses an Admin API key to ingest cost and usage data through the Cursor [Admin API](https://cursor.com/docs/account/teams/admin-api#endpoints). This API provides structured cost data broken down by model (e.g., GPT 5.1 Codex, Claude 4.5 Opus High Thinking) and token type (e.g., input tokens, output tokens, cache read tokens, cache write tokens), as well as requests to the Cloud Agent. [Usage data](/usage_based_reporting) is available for Cursor, measured in tokens or requests based on the usage type.
Vantage is also available as the official plugin in the [Cursor Marketplace](https://cursor.com/marketplace/vantage). Powered by the [Vantage MCP](/vantage_mcp), it lets you query cloud costs and act on Vantage workflows without leaving the editor.
## Cursor Permissions
Vantage cannot perform cost-incurring actions. Cursor requires an Admin API key to access the Admin API, which includes additional permissions beyond what Vantage uses (see the [full list of permissions here](https://cursor.com/docs/api#available-apis)). Vantage only reads data from the Admin API endpoint related to cost and usage and will never perform any other actions. Unfortunately, Cursor does not currently support more fine-grained permissions for Admin API keys. We recommend customers submit a feature request to Cursor for improved permission scoping, and Vantage will adopt fine-grained permissions if this becomes available. Vantage stores only usage metadata (e.g., token consumption). No user content (prompts or responses) is ingested.
## Connect Your Cursor Account
### Prerequisites
* A Cursor Teams or Enterprise plan is required. The [Admin API](https://cursor.com/docs/account/teams/dashboard#api-endpoints) is not available on individual plans.
* You need to be a Team Administrator to generate a team Admin API key in the Cursor console. **A team key is required, not a user key.** It's best practice to use a dedicated key for Vantage and rotate it per your security policy.
* You must have a Vantage **Organization Owner** or **Integration Owner** role to add or remove this integration. See the [Role-Based Access Control](/rbac) documentation for details.
* [Create a free Vantage account](https://console.vantage.sh/signup), then follow the steps below to integrate Cursor costs.
If your organization restricts access to the provider by IP address, add the following Vantage IP addresses to your provider's allowlist:
### Create the Connection
Navigate to your [Cursor dashboard](https://cursor.com/dashboard).
In the left menu, click **API Keys**.
Select the **Team** tab.
Click **New API Key** and select the **Admin** scope.
Enter a key name, then click **Save**.

Copy the generated team Admin API key that's displayed.
From the top navigation in Vantage, click **Settings**.
On the left navigation, select **Integrations** > **Cursor**.
The Cursor integrations page is displayed. Ensure you are on the **Connect** tab.
At the bottom of the page, click **Add API Key** and paste your previously generated Admin API key.
For **Account Name**, enter a name that will be used to differentiate this Cursor account from others you may add. This name will be displayed in Cost Report filters.
Click **Connect Account**.
After clicking **Connect Account**, you will see the status of your integration change to **Importing** within the Vantage console. This status indicates that Vantage is actively importing your Cursor cost data. The integration will fetch historical data up to your account's configured retention period. See the [Integration Status](/vantage_account#integration-status) documentation for details on integration statuses.
As soon as costs are processed, they will be available on your **All Resources** Cost Report. If you decide to remove your Cursor integration from Vantage, all costs associated with your Cursor Admin API key will be removed from the Vantage console.
### Next Steps - Manage Workspace Access
Once the import is complete and the integration status changes to **Stable**, you can select which workspaces this integration is associated with. See the [Workspaces](/workspaces#manage-workspace-provider-integrations) documentation for information.
## Use Case: Track Token Usage and Allocate Cursor Costs by Team
If your organization uses Cursor across multiple teams, you can use [Virtual Tags](/tagging) in Vantage to allocate Cursor token usage and costs by team, user, or project.
You can start by analyzing Cursor costs at the user level by grouping by **Resource** (which represents user emails) to see individual usage patterns. This allows you to identify which users are consuming the most tokens and understand their usage across different models.

Once you've identified user-level patterns, you can take your analysis further by creating [Virtual Tags](/tagging) to group users by team, department, or project. For example, you may want to track token consumption for the Engineering team to understand their usage patterns across different models. By creating a Virtual Tag with the key `Team` and the value `Engineering`, you can apply a filter to group together Cursor costs filtered by user emails (Resource) associated with engineering team members. You can then analyze token usage by model type (e.g., GPT 5.1 Codex vs. Claude 4.5 Opus High Thinking) and token category (input, output, cache read, cache write) to identify optimization opportunities.
## Data Refresh
See the [provider data refresh documentation](/provider_data_refresh) for information on when data for each provider refreshes in Vantage.
## Comparing Cursor Invoices to Vantage
When reconciling Cursor costs between your Cursor invoice and Vantage, you may notice differences in the total amounts shown. This is expected and can be explained by understanding how Cursor and Vantage categorize usage.
### Understanding Subcategory Filtering
Cursor's invoices typically show **On-Demand Usage**, which represents billable consumption that you are charged for. In Vantage, this aligns most closely with the **Usage-based** subcategory filter.
To compare your Cursor invoice to Vantage:
1. Navigate to your Cursor Cost Report in Vantage.
2. Apply a filter for **Subcategory** = **Usage-based**.
3. Compare this filtered total to the **On-Demand Usage** amount on your Cursor invoice.
By default, Vantage shows all usage, including non-billed subcategories. Filtering to **Usage-based** will give you the closest match to your Cursor invoice.
### Why Vantage May Show Higher Totals
Without applying the **Usage-based** filter, Vantage will display higher totals than your Cursor invoice. This occurs because Vantage ingests and displays all usage categories, including:
* **Usage-based**: Billable, on-demand consumption (matches Cursor invoice)
* **Included in Business**: Usage included in your Cursor plan subscription
* Other non-billed usage types
This comprehensive view allows you to understand your total consumption patterns, not just what you're being billed for. For invoice reconciliation purposes, focus on the **Usage-based** subcategory.
### Accounting for Timing Differences
Even after filtering to **Usage-based**, you may notice small remaining differences between Vantage and your Cursor invoice. These discrepancies are typically due to refresh timing around billing period boundaries:
* Cursor generates invoices based on their billing cycle and cut-off times.
* Vantage refreshes Cursor cost data once daily from the Admin API.
* Data refreshed near the boundary of a billing period may result in minor timing differences.
These timing-related differences are usually small (typically less than 1% of total costs) and will resolve as data continues to sync.
## Cursor Reporting Dimensions
On Cursor [Cost Reports](/cost_reports), you can filter and group across several dimensions:
* Team (the name you assign to the integration when created in Vantage; use **Account** for Group By)
* Service (e.g., GPT 5.1 Codex, Claude 4.5 Opus High Thinking)
* Category (e.g., requests, tokens)
* Subcategory (e.g., Usage-based, Included in Business)
* Resource (user email)
* Charge Type (Usage)
* Tags: Includes [Virtual Tags](/tagging) created in Vantage for this provider. The following provider tags are automatically created by Vantage from Cursor data and are available for filtering and grouping:
* `cursor:max_mode`: Indicates whether the [option](https://cursor.com/docs/context/max-mode) to use maximum context windows for all models is enabled, allowing you to filter and group costs by max mode usage.
* `cursor:user`: The Cursor user email when present in the source data, allowing you to filter and group costs by user email.
* `cursor:cloud_agent_id`: The Cloud Agent run ID when the request is attributed to a Cloud Agent.
* `cursor:automation_id`: The automation ID when the request is attributed to an automation.
* `cursor:conversation_id`: The agent conversation ID when the request is attributed to an agent session.
* `cursor:pr`: The pull request number when the request is attributed to pull request work.
* `cursor:repo`: The repository name when the request is attributed to pull request work.
* `cursor:pr_author`: The pull request author when the request is attributed to pull request work.
* `cursor:service_account`: The service account name (or ID, if no name is available) when the request comes from a service account.
* `cursor:headless`: Indicates whether Cursor reported the request as headless (`true` or `false`).
Vantage also applies [Managed AI Tags](/managed_ai_tags) to Cursor costs. This is a normalized `vntg:ai:` schema shared across all AI providers, so you can analyze AI spend with consistent dimensions. For Cursor, the following keys are emitted: `vntg:ai:model`, `vntg:ai:raw_model`, `vntg:ai:model_provider`, and `vntg:ai:user_email`. See [Managed AI Tags](/managed_ai_tags) for the full schema.
# Custom Providers
Source: https://docs.vantage.sh/connecting_custom_providers
Learn how to integrate Vantage with Custom Providers.
With the Custom Provider integration option in Vantage, you can upload costs from providers that don't expose billing APIs, aren't [yet supported](/getting_started) by Vantage, or originate from custom systems. You can import costs by providing any CSV that adheres to the schema described below or through the [Vantage API](/connecting_custom_providers#api).
## When to Use Custom Providers
Custom Providers are designed for cost data that Vantage cannot automatically ingest from a billing API. Common use cases include:
* **Unsupported SaaS providers** — Import costs from any vendor not listed on the [Supported Providers](/getting_started) page.
* **Internal or on-premises costs** — Track data center, licensing, or infrastructure costs alongside your cloud spend.
* **Supplemental data** — Add costs that a native integration does not surface, such as marketplace purchases, negotiated credits, or manual adjustments.
If Vantage later adds native support for a provider you've been uploading as a Custom Provider, you can connect the official integration and continue using both side by side.
## FinOps FOCUS Schema
FOCUS is an [open-source schema](https://focus.finops.org/) that standardizes cost and usage billing data across different cloud providers. When you add a Custom Provider in Vantage, you use a CSV template format that is a subset of the FOCUS schema. Vantage supports columns from FOCUS 1.1–1.3. The fields in this template provide enough detail for Vantage to correctly render costs and perform cost allocation. With just the minimum required fields, Custom Provider costs are available with other Vantage features, such as [Cost Alerts](/cost_alerts), [Cost Anomaly Alerts](/cost_anomaly_alerts), [Report Notifications](/report_notifications), and [forecasting](/forecasting). See the explainer video below for an introduction to this feature and how FinOps FOCUS is used.
## Review CSV Format
Follow the steps below to create a CSV based on the FOCUS format. You can also use [focus.vantage.sh](https://focus.vantage.sh/), a free web-based tool that converts cost CSVs or PDF invoices from select Cloud, AI, and SaaS providers into CSVs in the FinOps FOCUS format.
To create a Custom Provider in Vantage, create a CSV file for your data that uses the following format. Add your provider's cost and usage data to the file. Note that there is a maximum of 10,000 rows and a file size of 2MB allowed. Each time that you upload additional cost data, you will need to create a separate CSV file for that new dataset.
```
ChargePeriodStart,ChargeCategory,BilledCost,ResourceId,ResourceType,RegionId,ServiceCategory,ServiceName,Tags,BillingAccountId,SubAccountId,RegionName,ServiceSubcategory
2021-01-01,Usage,1.23,resource-id-1,cost_sub_category-1,us-east-1,service-category-1,service-name-1,"{""tag1"":""value1"",""tag2"":""value2""}",123456789012,987654321098,US East (N. Virginia),IaaS
```
Only the following fields are required:
* `ChargeCategory`
* `ChargePeriodStart`
* `BilledCost`
* `ServiceName`
If you want to upload amortized costs, then `ChargePeriodEnd` is also required.
### Data Format
The following table provides details for each field within the template, as well as their Vantage representation on reports. Column names correspond to the [FOCUS Column Library](https://focus.finops.org/focus-columns/?version=v1-2).
| Column Name | Required | Vantage Representation | Data Type | Examples |
| - | - | - | - | - |
| `BillingCurrency` | No | Billing currency costs are displayed in | A currency code, like `GBP`. If you enter a currency code not available in Vantage, an error is displayed on validation. Check that currency conversion is also enabled. See the [Currency Conversion](/vantage_account#currency-conversion) documentation for details. | `JPY`, `AUD`, `USD` |
| `ChargeCategory` | Yes | **Charge Type** filter and grouping option | Valid values are case-sensitive and include: `Credit`, `Discount`, `Fee`, `Refund`, `Tax`, `Usage` | `Usage` |
| `ChargePeriodStart` | Yes | Start date of cost period | Date in `YYYY-MM-DD` or ISO 8601 format | `2024-08-25` |
| `ChargePeriodEnd` | Only for amortized costs | Exclusive end date of cost period. For example, `ChargePeriodStart` of `2024-08-25` and `ChargePeriodEnd` of `2024-08-26` represents one day of costs on August 25. | Date in `YYYY-MM-DD` or ISO 8601 format | `2024-08-26` |
| `ConsumedQuantity` | No | Quantity associated with `ConsumedUnit` | Numeric | `598` |
| `ConsumedUnit` | Only when `ConsumedQuantity` is provided | Unit of usage associated with `ConsumedQuantity` | Alphanumeric | `GB` |
| `BilledCost` | Yes | Cost that's displayed | Positive or negative number values accepted; dollar signs and decimal values are also acceptable. All costs are considered to be in USD. | `1245` or `-456` or `$1.23` or `-$1.23` |
| `BillingAccountId` | No | **Account** filter and grouping option | Alphanumeric | `123456789012` |
| `RegionId` | No | **Region** filter and grouping option | Alphanumeric | `us-east-1` |
| `RegionName` | No | **Region** filter and grouping option. Used as a fallback when `RegionId` is not provided. | Alphanumeric | `US East (N. Virginia)` |
| `ResourceId` | No | **Resource** filter and grouping option | Alphanumeric | `task/3` or `123456` |
| `ResourceType` | No | **Subcategory** filter and grouping option | Alphanumeric | `Large` |
| `ServiceCategory` | No | **Category** filter and grouping option | Alphanumeric | `Task` |
| `ServiceName` | Yes | **Service** filter and grouping option | Alphanumeric | `Compute` |
| `ServiceSubcategory` | No | **Subcategory** filter and grouping option. Used as a fallback when `ResourceType` is not provided. | Alphanumeric | `Database`, `IaaS` |
| `SubAccountId` | No | **Account** filter and grouping option | Alphanumeric | `987654321098` |
| `Tags` | No | **Tags** filter and grouping option | Valid JSON object; array of key/value pairs | `"{""env"":""production""}"` for one tag. `"{""env"":""prod"",""application"":""geo-location""}"` for multiple tags. |
If your CSV includes additional FOCUS 1.2 or 1.3 columns beyond those listed above—such as `AvailabilityZone`, `CommitmentDiscountId`, `EffectiveCost`, `ListCost`, `Provider`, or `Publisher`—Vantage accepts the file without errors but does not use those columns for cost reporting. You do not need to remove extra columns before uploading.
## Upload Custom Provider File
Custom Provider files can be uploaded at any time in the console. The above schema adds a timestamp based on the `ChargePeriodStart` column, so Vantage can place the data in the correct relationship to other costs under a Custom Provider.
Users must have Owner permissions to upload Custom Provider files. If you prefer to use the API rather than the Vantage console, see the [API](/connecting_custom_providers#use-the-api-to-add-a-custom-provider) section below.
Navigate to the [Integrations page](https://console.vantage.sh/settings/integrations) in Vantage.
Select **Custom Provider**. (If you have already added a Custom Provider and are adding another one, ensure you are on the **Connect** tab.)
Optionally, click **Select a File** and upload your formatted CSV file. You can also skip the CSV upload and add cost data later via CSV or the [API](/connecting_custom_providers#use-the-api-to-add-a-custom-provider).
Click **Upload Costs** (or **Skip** if you did not upload a file).
* If your CSV file contains any errors, the **Review** pop-up window is displayed and indicates where the error occurred. See the [Troubleshooting](/connecting_custom_providers#troubleshoot-custom-provider-uploads) section for details on specific errors.

* For error-free files, a message is displayed that indicates your file is okay. Click **Review** to see the first 25 rows of uploaded data.

You can click **Select a File** again if you accidentally uploaded the wrong file.
Enter a **Name** for your Custom Provider. This is the name that will be displayed in report filters. Optionally, enter a **Description**.
Click **Create Custom Provider Integration**.
The **Manage** integration screen is displayed. Initially, the message *Importing and Processing* will be displayed on this screen. You can click the **Import Costs** tab if you want to upload additional cost files.

Once the import is complete and the integration status changes to **Stable**, in the **Workspace Access** section of this screen, select which workspaces this integration is associated with. See the [Workspaces](/workspaces#manage-workspace-provider-integrations) documentation for more information. See the [Integration Status](/vantage_account#integration-status) documentation for details on integration statuses.
Costs will be ingested and processed as soon as you add the integration. Once costs are processed, they will be available on your **All Resources** Cost Report. Vantage aggregates uploaded Custom Provider costs to a daily level.
### Troubleshoot Custom Provider Uploads
When you upload a file that contains errors, the **Review** window is displayed and shows the rows where errors were identified. The first 25 rows are displayed. If you have an error in a row that's not one of the first 25 rows, that row will be displayed at the top, along with all other errors. Some common errors are noted below.
| Issue | Description | Solution |
| - | - | - |
| Improper CSV format | The file format is not a valid CSV or exceeds the 10,000-row limit or 2MB file size max. | Ensure the file is a properly formatted CSV, with no more than 10,000 rows or 2MB in size. |
| Missing required fields | One or more required fields (`ChargeCategory`, `ChargePeriodStart`, `BilledCost`, `ServiceName`) are missing or improperly formatted. An error message noting which rows are missing required field values will be displayed in the **Review** window. | Verify that all required fields are present and correctly formatted. See the [CSV Format](/connecting_custom_providers#review-csv-format) section for details. |
| Invalid values | The file contains invalid values, such as incorrect date formats, invalid numbers, tags that are not formatted as JSON or have missing quotes, or incorrect case-sensitive values for `ChargeCategory`. An error message noting which rows contain invalid values will be displayed in the **Review** window. | Double-check the data in your CSV to ensure dates are in `YYYY-MM-DD` format, numbers are valid, and `ChargeCategory` values match the allowed case-sensitive options (e.g., `Usage`, `Credit`). See the [Data Format](/connecting_custom_providers#data-format) table for details. |
| Improper Vantage permissions | The user attempting the upload does not have the proper permissions. | Ensure you have Owner permissions to upload Custom Provider files. See the [Role-Based Access Control](/rbac) documentation for details. |
| Duplicate file names | You attempt to upload a new costs import file that has the same name as a previous costs upload file. An error message is displayed indicating you already have a file uploaded with the same name. The new file will overwrite the old file. | Ensure each CSV file that you upload is named something different (e.g., `my_provider_costs_8_2024`, `my_provider_costs_9_2024`). |
#### Steps to Resolve File Issues
After you've identified the issues, reopen your CSV file, correct the errors, and save.
On the Custom Provider upload screen, close the **Review** window, click **Select a File**, and upload the corrected version of your CSV file.
After a successful upload, a confirmation message is displayed. You can click **Review** to verify the first 25 rows of your uploaded data to ensure accuracy.
Follow steps 5–8 in the [Upload Custom Provider File](/connecting_custom_providers#upload-custom-provider-file) section to complete the upload process.
## View Custom Provider Costs in Vantage
Once you have uploaded Custom Provider costs, you can query these costs in other Vantage tools. Your Custom Provider will be included in the **Providers** list of filters on [Cost Reports](/cost_reports) and [Saved Filters](/saved_filters).

If you did not provide any information for a particular filter (e.g., `RegionId`), then those filters will be displayed as empty.

## Edit Custom Provider Name and Description
You can edit the name and description of your Custom Provider at any time after creation.
Navigate to the [**Integrations** page](https://console.vantage.sh/settings/custom_providers).
Select your Custom Provider.
On the **Manage** tab, in the **Edit Provider Details** section, update the **Name** or **Description** fields as needed. The name is displayed in report filters, so choose a name that helps you identify the provider.
Click **Update Details** to apply your changes.
## Set a Custom Provider Icon
You can upload a custom icon for a Custom Provider so it is easy to recognize across Vantage. The uploaded icon appears anywhere the provider is shown, including [Cost Reports](/cost_reports), filters, the Overview page, [tags](/tagging), the reporting list, and anomaly alerts. If you do not upload an icon, Vantage shows a default Custom Provider icon.
Navigate to the [**Integrations** page](https://console.vantage.sh/settings/custom_providers) and select your Custom Provider.
On the **Manage** tab, upload an image in the icon section. The icon must be a **JPEG, PNG, or GIF** file no larger than **5 MB**. To change it later, remove the current icon and upload a new one.
## Add Additional Imports
After the initial costs import, you can add additional cost imports.
If you upload a file with the same name as an existing import, your new file will overwrite the original file. Ensure you have different names for each file upload (e.g., `my_provider_costs_8_2024`, `my_provider_costs_9_2024`).
Navigate to the [**Integrations** page](https://console.vantage.sh/settings/custom_providers).
Select your Custom Provider.

Click the **Import Costs** tab. Import your new cost file. Review any errors and correct as needed. Once uploaded, your file will be displayed within the **Imports** section of the **Manage** tab.
## Delete Imported Files
If you want to delete an imported file, the costs will be removed from your Custom Provider.
Navigate to the [**Integrations** page](https://console.vantage.sh/settings/custom_providers).
Select your Custom Provider.
In the **Imports** section of the **Manage** tab, you can view existing imports along with the date the file was imported and who imported the file. Click the trashcan icon next to an import to remove it. If you delete a CSV, the corresponding data will be deleted from the provider.

## Use the API to Add a Custom Provider
To reference a Custom Provider in [VQL](/vql) queries, navigate to the [**Integrations** page](https://console.vantage.sh/settings/custom_providers). Use the displayed **Provider ID** (e.g., `custom_provider:accss_crdntl_123a45bfdaf38765`).
You can also use the API to create and upload costs for a Custom Provider.
Send a `POST` request to the `/integrations/custom_provider` endpoint to create the Custom Provider.
```bash theme={null}
curl --request POST \
--url https://api.vantage.sh/v2/integrations/custom_provider \
--header 'accept: application/json' \
--header 'authorization: Bearer AUTH_TOKEN' \
--header 'content-type: application/json' \
--data '
{
"name": "My Custom Provider",
"description": "Costs for this provider"
}
'
```
On a successful `200` response, a Custom Provider `token` is returned.
```json theme={null}
{
"token": "",
"provider": "custom_costs",
"account_identifier": "My Custom Provider from the API",
"status": "connected",
"workspace_tokens": [],
"created_at": "2024-08-26T14:04:17Z"
}
```
Use the `token` to upload a CSV file via the `/integrations/{integration_token}/costs.csv` endpoint.
```bash theme={null}
curl --request POST \
--url https://api.vantage.sh/v2/integrations//costs.csv \
--header 'accept: application/json' \
--header 'authorization: Bearer TOKEN' \
--header 'content-type: multipart/form-data' \
--form csv='@vendor_costs.csv'
```
If there are any errors, the following `422` response is returned. Fix the errors in your CSV, and upload a new file.
```json theme={null}
{
"errors": [
"Row 1: ChargeCategory must be one of the following: Credit, Discount, Fee, Refund, Tax, or Usage",
"Row 22: Tags must be a valid JSON object",
"Row 27: BilledCost must be a valid number",
"Row 31: ChargePeriodStart must be a valid date"
]
}
```
# Databricks
Source: https://docs.vantage.sh/connecting_databricks
Learn how to integrate Vantage with Databricks.
Vantage connects to your Databricks account using a dedicated Serverless SQL warehouse to query `system` tables within a [Unity Catalog](https://docs.databricks.com/aws/en/data-governance/unity-catalog/get-started)-enabled workspace. Vantage requires only the Data Reader permission to access these system tables and does not have the ability to perform any write actions or administrative changes in your Databricks account.
You can perform the Databricks integration for each Databricks account you have or each region your Databricks account uses. Each integration you perform will collect data for all the workspaces within your Databricks account that are deployed within the same region.
[Usage data](/usage_based_reporting) is available for services that measure consumption, such as usage in DBUs ([Databricks Units](https://docs.databricks.com/aws/en/getting-started/concepts#billing-databricks-units-dbus)) or GBs.
## Databricks System Tables
[System tables](https://docs.databricks.com/aws/en/admin/system-tables/) are a set of Unity Catalog tables that expose operational and billing metadata. For cost monitoring, Vantage uses the following tables:
* `system.billing.usage`: contains SKU-level usage data by workspace.
* `system.billing.list_prices`: provides SKU-level list pricing.
* `system.billing.account_prices`: shows discounted prices for customers on enterprise agreements.
This table is considered to be in [Private Preview](https://docs.databricks.com/aws/en/release-notes/release-types) through Databricks and may require you to work with your Databricks account team to enable it.
If Databricks costs in Vantage appear to reflect list pricing rather than your negotiated enterprise rates, verify that `system.billing.account_prices` is enabled and backfilled in your Databricks account. After this table is available, subsequent ingestions use discounted pricing. Historical cost data that was imported before `account_prices` was available is not automatically updated. Contact [support@vantage.sh](mailto:support@vantage.sh) to request a re-import of prior periods.
* `system.compute.clusters`: contains metadata, like human-readable names, for clusters and custom tagging.
* `system.compute.warehouses`: contains metadata such as warehouse configuration, human-readable warehouse names, and custom tags.
* `system.access.workspaces_latest`: contains human-readable names for workspaces.
If you are migrating from the v1 Databricks integration, see [How to Migrate from the v1 Integration to v2](/connecting_databricks#how-to-migrate-from-the-v1-integration-to-v2) before creating a new connection.
## Connect Your Databricks Account
You can connect to Databricks either [manually](/connecting_databricks#create-the-connection) using the below workflow or using a [Terraform module](/connecting_databricks#connect-via-terraform).
The Serverless SQL Warehouse required for the integration will incur a cost, estimated at approximately \$84/month. Vantage uses the smallest possible Serverless SQL Warehouse to keep these costs minimal.
### Prerequisites
* You must have a Vantage **Organization Owner** or **Integration Owner** role to add or remove this integration. See the [Role-Based Access Control](/rbac) documentation for details.
* You need [account admin](https://docs.databricks.com/en/administration-guide/index.html) privileges in Databricks.
* A [Unity Catalog-enabled](https://docs.databricks.com/aws/en/data-governance/unity-catalog/get-started#how-do-i-know-if-my-workspace-was-enabled-for-unity-catalog) workspace.
* Review [this page](https://docs.databricks.com/aws/en/data-governance/unity-catalog/manage-privileges/) from the Databricks documentation for additional information about permissions with Unity Catalog.
* [Create a free Vantage account](https://console.vantage.sh/signup), then follow the steps below to integrate Databricks costs.
If your organization restricts access to the provider by IP address, add the following Vantage IP addresses to your provider's allowlist:
### Create the Connection
To integrate your Databricks account with Vantage, follow the below steps:
#### Step 1 - Collect Credentials and Open Workspace
Log in to the [Databricks console](https://accounts.cloud.databricks.com/).
From the top right of the console, click your avatar and copy your **Databricks Account ID** for later use.
Click **Workspaces**, then select a Unity Catalog-enabled workspace within your Databricks account.
Copy your **Workspace URL** for later use. Then, open the workspace.
#### Step 2 - Create a Service Principal
From the top right of the workspace, click your avatar and select **Settings**.
On the **Settings** screen, under **Workspace admin**, select **Identity and access**.
Next to **Service principals**, click **Manage**.
Click **Add service principal**.
* On the **Add new service principal** modal, click **Add new**.
* For **Service principal name**, enter *vantage-billing-sp*.
* Click **Add**.
Open the newly created service principal, then select the **Secrets** tab.
Click **Generate secret**.
Enter a secret **Lifetime** of 730 days, then click **Generate**. (When the secret expires, you'll need to create a new one and reconfigure the integration in Vantage with the corresponding secret and client ID.)
Your **Secret** and **Client ID** are displayed. Copy these values for later use.
#### Step 3 - Grant Workspace Entitlements
[Workspace entitlements](https://docs.databricks.com/aws/en/security/auth/entitlements) control how a service principal can access a Databricks workspace and its SQL APIs.
From the top right of the workspace, click your avatar and select **Settings**.
Under **Workspace admin**, select **Identity and access**. Next to **Service principals**, click **Manage**.
Open the **vantage-billing-sp** service principal and enable **Databricks SQL access**. This entitlement is required for Vantage to call the SQL Statement API.
Enable **Workspace access**. This entitlement is recommended.
Without **Databricks SQL access**, authentication may succeed while SQL Statement API requests fail with a `401` or `403` response.
#### Step 4 - Create a Serverless SQL Warehouse and Assign Permissions
From the left navigation menu, under **SQL**, click **SQL Warehouses.**
Click **Create SQL warehouse**, and enter the following information:
* For **Name,** enter *vantage-billing-warehouse*.
* For **Cluster size**, select **2X-Small**.
* For **Type**, select **Serverless**.
Click **Create**.
After the warehouse is created, the **Manage permissions** modal window is displayed. (To access this modal, you can also click **Permissions** on the top right of the screen.)
Search for and select the **vantage-billing-sp** service principal.
Select the **Can Use** permission and click **Add**.
Close the **Manage permissions** modal and copy your warehouse ID, displayed next to the warehouse name, for later use.
#### Step 5 - Grant Data Reader Permissions to the Service Principal
From the top of the left navigation menu, click **Catalog**.
In the **Catalog** menu, expand **My Organization > system**.
Select the `access` schema. On the right, click **Permissions > Grant**.
Enter the following information to create a grant on `system.access`:
* For **Principals**, select the **vantage-billing-sp** service principal.
* For **Privilege presets**, select **Data Reader**.
Click **Confirm**.
Repeat the last two steps and grant Data Reader permissions for the `billing` and `compute` schemas.
#### Step 6 - Add Credentials to Vantage
From the Vantage console, navigate to the [Databricks Settings](https://console.vantage.sh/settings/databricks/) page.
Click the **Connect** tab, then click **Set Up Account**.
On the **Integration** modal screen, enter the following information:
* For **Databricks Account ID**, enter your account ID that you obtained in step 1.
* For **Service Principal OAuth Client ID** and **Service Principal OAuth Client Secret**, add the ID and secret you obtained in step 2.
* For **Workspace URL**, add the URL you obtained in step 1.
* For **SQL Warehouse ID**, add the warehouse ID you obtained in step 4.
Click **Connect Account**.
After clicking **Connect Account**, you will see the status of your integration change to **Importing** within the Vantage console. This status indicates that Vantage is actively importing your Databricks cost data. Vantage will load the previous six months of Databricks usage data. See the [Integration Status](/vantage_account#integration-status) documentation for details on integration statuses.
As soon as costs are processed, they will be available on your **All Resources** Cost Report. If you decide to remove your Databricks integration from Vantage, all costs associated with your Databricks account will be removed from the Vantage console.
## Connect via Terraform
You can also connect your Databricks account using the `terraform-databricks-vantage-integration` module. Follow the steps in the module's [README](https://github.com/vantage-sh/terraform-databricks-vantage-integration) to connect your account.
## Next Steps - Manage Workspace Access
Once the import is complete and the integration status changes to **Stable**, you can select which workspaces this integration is associated with. See the [Workspaces](/workspaces#manage-workspace-provider-integrations) documentation for information.
## Migrate to the New Databricks Billing Integration
This section provides information about v1 and v2 of the Databricks integration in Vantage.
### What's Improved in the New Integration
Previously, Vantage ingested Databricks costs using Databricks billable usage logs (integration released in December 2022). These logs provided SKU-level usage but reflected only list pricing, and enterprise customers had to manually apply discounts in Vantage to approximate their actual costs.
The new integration (released in July 2025) uses the Databricks system tables and provides more accurate, granular cost data. Switching to this integration ensures your cloud cost data in Vantage is more complete, accurate, and reflective of your negotiated Databricks pricing.
Vantage recommends you perform the new integration to receive the most up-to-date billing data from Databricks, as new products will not be added to the former billable usage logs.
### What You Need to Know Before Migrating
Data availability for the new integration depends on:
* Your Databricks account’s creation date
* When system tables were enabled
* How long the data has been retained in your account
Databricks currently provides [one year of free retention](https://docs.databricks.com/aws/en/admin/system-tables/#which-system-tables-are-available), with plans to add configurable retention for system tables; however, backfills of system tables in Databricks will not be supported.
Run this query in your Databricks account to see the oldest full month of data available:
```sql theme={null}
SELECT MIN(usage_date) as oldest_full_month
FROM system.billing.usage
WHERE DAY(usage_date) = 1;
```
If your Vantage retention period extends further back than your available system tables data, you can continue to use the previous Vantage integration to maintain historical continuity.
To ensure data is not double-counted, Vantage will:
* Backfill your new Databricks Vantage integration as far back as the Databricks system tables contain data
* Remove any overlapping data from your old Databricks Vantage integration
### How to Migrate from the v1 Integration to v2
This integration guide provides the steps for migrating from v1 to v2. Keep your v1 integration active while you set up and validate v2, then disable the v1 log delivery after confirming that v2 data is available and accurate.
#### Step 1 - Set Up the v2 Integration
Create a new Databricks integration while your v1 integration remains active. Use one of the following setup methods:
#### Step 2 - Validate v2 Data
After clicking **Connect Account**, you will see the status of your v2 integration change to **Importing** within the Vantage console. Vantage will load the previous six months of Databricks usage data. As soon as costs are processed, they will be available on your **All Resources** Cost Report.
Before disabling v1 log delivery, validate the new integration:
* Wait for the v2 integration to finish importing and change to **Stable**.
* Compare recent month totals between your v1 and v2 Databricks costs.
* If you had manually applied discounts on v1, verify that v2 reflects your negotiated pricing from `system.billing.account_prices`.
* Confirm that Cost Reports, saved filters, Virtual Tags, dashboards, and alerts using Databricks costs still behave as expected.
#### Step 3 - Disable v1 Billable Usage Log Delivery
After v2 is validated, disable the Databricks log delivery configuration that sends v1 billable usage logs to Vantage.
Configure the [Databricks CLI](https://docs.databricks.com/en/dev-tools/cli/install.html) for account-level authentication. Follow the [user-to-machine authentication guide](https://docs.databricks.com/en/dev-tools/cli/authentication.html#u2m-auth) to ensure you have valid credentials.
The commands below assume you have followed Databricks’s instructions and have account-level access. Be sure to use the profile that corresponds with your Databricks account administrator.
Disable the log delivery configuration named `vantage-billable-usage-delivery` using its `config_id`.
```bash theme={null}
# find log delivery with config_name = 'vantage-billable-usage-delivery'
databricks account log-delivery list | jq '.[] | select(.config_name == "vantage-billable-usage-delivery" and .status == "ENABLED")'
# disable log delivery
databricks account log-delivery patch-status \
--json '{ "status": "DISABLED" }'
```
```json theme={null}
{
"account_id": "xxx",
"config_id": "d0bd8965-576c-11f0-8bd2-063fa5ec6fe1",
"config_name": "vantage-billable-usage-delivery",
"creation_time": 1751478531000,
"credentials_id": "d8116e60-094f-4dce-a8e7-21b0f8fe1678",
"delivery_path_prefix": "databricks/23c328cc-d58d-4cba-9b6a-5f1d061cdf69/90d61e57-21e1-482d-ad62-f98904e47a4b",
"delivery_start_time": "2025-01",
"log_delivery_status": {
"last_attempt_time": "2025-07-29T12:57:06Z",
"last_successful_attempt_time": "2025-07-29T12:57:06Z",
"message": "All logs were successfully delivered.",
"status": "SUCCEEDED"
},
"log_type": "BILLABLE_USAGE",
"output_format": "CSV",
"status": "ENABLED",
"storage_configuration_id": "341a1551-0822-40d6-b6d0-9fbc3f78e906",
"update_time": 1753857212000
},
```
Once disabled, Databricks stops pushing data to a bucket, and it will no longer trigger any data ingests to Vantage.
#### Step 4 - Remove or Retain the v1 Integration in Vantage
To view your v1 Databricks integration in Vantage, navigate to the [Integrations page](https://console.vantage.sh/settings/databricks). The integration is displayed with the label `V1 - Read Only`, and you’ll be unable to make updates to that integration in Vantage.
If you need to update any manually applied Databricks discounts on a v1 integration, contact [support@vantage.sh](mailto:support@vantage.sh).
After v1 log delivery is disabled, you can remove the v1 integration from Vantage if you no longer need any remaining historical data that exists only on v1. If you still need that history for reporting continuity, leave the v1 integration in read-only mode.
If you decide to remove your Databricks integration from Vantage, all costs associated with that integration will be removed from the Vantage console.
If you have multiple Databricks accounts, repeat these migration steps for each account ID.
#### Step 5 - Manage Workspace Access
Once the v2 import is complete and the integration status changes to **Stable**, you can select which workspaces this integration is associated with. See the [Workspaces](/workspaces#manage-workspace-provider-integrations) documentation for information.
## Data Refresh
See the [provider data refresh documentation](/provider_data_refresh) for information on when data for each provider refreshes in Vantage.
## Databricks Reporting Dimensions
On Databricks [Cost Reports](/cost_reports), you can filter across several dimensions:
* Billing Account (e.g., Organization)
* Linked Account (e.g., Workspace)
* Service (e.g., Jobs Compute)
* Charge Type (e.g., Usage)
* Category (e.g., Photon)
* Subcategory (e.g., Serverless)
* Resource ID (specific ID for a given Databricks resource)
* Tags (Tags from Databricks, see section below, and [Virtual Tags](/tagging) created in Vantage)
### Databricks Tags
The Tag filter contains values like job\_id, which can be used to view costs for specific Databricks jobs. Vantage gets tags from `identity_metadata`, `usage_metadata`, and `custom_tags` from `system.billing.usage`; `workspace_name` from `system.access.workspaces_latest`; `cluster_name`, `tags`, and `driver_instance_pool_id` from `system.compute.clusters`; and `warehouse_channel`, `warehouse_type`, `warehouse_name` from `system.compute.warehouses`. Below is a list of tags Vantage ingests.
* `cluster_id`
* `job_id`
* `warehouse_id`
* `instance_pool_id`
* `node_type`
* `job_run_id`
* `notebook_id`
* `dlt_pipeline_id`
* `endpoint_name`
* `endpoint_id`
* `dlt_update_id`
* `dlt_maintenance_id`
* `metastore_id`
* `run_name`
* `job_name`
* `notebook_path`
* `central_clean_room_id`
* `source_region`
* `destination_region`
* `app_id`
* `app_name`
* `private_endpoint_name`
* `budget_policy_id`
* `run_as`
* `sql_warehouse_own_by`
* `created_by`
* `workspace_name`
* `cluster_name`
* `cluster_own_by`
* `clusterNodeType`
* `warehouse_name`
* `warehouse_channel`
* `warehouse_type`
* `driver_instance_pool_id`
## Access Vantage via Databricks MCP Catalog
The [Vantage MCP](/vantage_mcp) is available in the Databricks Marketplace and [Model Context Protocol (MCP) Catalog](https://www.databricks.com/blog/accelerate-ai-development-databricks-discover-govern-and-build-mcp-and-agent-bricks), which makes it easy to integrate cloud cost intelligence directly into your Databricks AI workflows.
* Gain unified visibility into Databricks costs alongside AWS, Azure, GCP, and other cloud services
* Analyze cost drivers, usage patterns, and trends with automated reporting and FinOps insights
* Apply Virtual Tags in Vantage to allocate Databricks costs by team, environment, or business unit and ask questions about how these costs are allocated
Review the [Databricks documentation](https://docs.databricks.com/aws/en/generative-ai/mcp/) for information on how to use MCP servers in Databricks. You need an active Vantage account with a Databricks integration (follow the instructions above). You also need a [Vantage API key](/vantage_account#create-an-api-token) to use as your bearer token.
Log in to the Databricks console, and navigate to the **Databricks Marketplace**.
Use the **Product** filter to filter by **MCP servers**.
Select **Vantage** and click **Install**.
Enter a **Connection name**, your Vantage token, and accept the provided terms.
Click **Install**.
# Datadog
Source: https://docs.vantage.sh/connecting_datadog
Learn how to integrate Vantage with Datadog.
Vantage uses a read-only Datadog OAuth token to pull data from the [usage metering endpoint](https://docs.datadoghq.com/api/latest/usage-metering/). The usage metering API provides hourly, daily, and monthly usage across multiple facets of Datadog. This API is available to all Pro and Enterprise customers.
For Datadog business metrics, Vantage also requires access to Datadog metrics. See the [Datadog business metrics](/business_metrics#import-from-datadog) documentation for details.
Usage is only accessible for [parent-level organizations](https://docs.datadoghq.com/account_management/multi_organization/).
For documentation about connecting to Vantage from Datadog, see the [Vantage Integration page](https://docs.datadoghq.com/integrations/vantage/) in Datadog's documentation.
Looking to connect Datadog to the [Vantage FinOps Agent](/vantage_finops_agent)? See the [Datadog MCP](/datadog_mcp) documentation. The Datadog MCP Connector reuses this same Datadog OAuth application, and you may be prompted to reconnect/reauthorize to grant any additional scopes required for the agent to read live telemetry (metrics, logs, monitors, events) alongside billing and usage data.
## Connect Your Datadog Account
### Prerequisites
* You must have a Vantage **Organization Owner** or **Integration Owner** role to add or remove this integration. See the [Role-Based Access Control](/rbac) documentation for details.
* When connecting your Datadog account, you must be a [Datadog Admin](https://docs.datadoghq.com/account_management/rbac/?tab=datadogapplication#datadog-default-roles) who is able to authorize the following scopes: `billing_read`, `usage_read`, `metrics_read`, `timeseries_query`, `logs_read_data`, `logs_read_index_data`, `logs_read_workspaces`, `monitors_read`, `apm_read`, `dashboards_read`, `mcp_read`, `incident_read`, `events_read`, and `llm_observability_read`.
See the [Datadog documentation](https://docs.datadoghq.com/account_management/rbac/permissions/) for more information on roles.
* [Create a free Vantage account](https://console.vantage.sh/signup), then follow the steps below to integrate Datadog costs.
If your organization restricts access to the provider by IP address, add the following Vantage IP addresses to your provider's allowlist:
### Create the Connection
From the Vantage console, navigate to the [Integrations page](https://console.vantage.sh/settings/integrations).
Select **Datadog** and add a connection.
You will be brought to the Datadog login screen and guided through the Datadog OAuth flow for adding your Datadog account.
After authorizing the connection with Vantage, you will see the status of your connection change to **Importing** within the Vantage console. This status indicates that Vantage is actively importing your Datadog cost data. See the [Integration Status](/vantage_account#integration-status) documentation for details on integration statuses.
Once connected, Vantage will ingest six months of historical Datadog costs.
### Next Steps - Manage Workspace Access
Once the import is complete and the integration status changes to **Stable**, you can select which workspaces this integration is associated with. See the [Workspaces](/workspaces#manage-workspace-provider-integrations) documentation for information.
## Data Refresh
See the [provider data refresh documentation](/provider_data_refresh) for information on when data for each provider refreshes in Vantage.
## Update the Datadog Integration
Sometimes an update is required to use new Vantage features related to Datadog. Navigate to the [Manage Integration](https://console.vantage.sh/settings/datadog?manage=true) page for your Datadog integration. If you need to update the integration, the **Update Required** button is displayed in the **Status** column. Click the button to access the OAuth integration workflow and reconnect your integration.

## Datadog Reporting Dimensions
Within [Cost Reports](/cost_reports/), Vantage will show cost data for at least the following services.
* APM
* Application Security Management
* Audit Trail
* CI Visibility
* Cloud Cost Management
* Cloud Security Management
* Cloud Security Posture Management
* Cloud Workload Security
* Containers
* Continuous Profiler
* Database Monitoring
* Error Tracking
* Incident Management
* Infrastructure Monitoring
* LLM Observability
* Log Management
* Metrics
* Network Monitoring
* Network Performance Monitoring
* Observability Pipeline
* Real User Monitoring
* Sensitive Data Scanner
* Security Information and Event Management
* Serverless Monitoring
* Synthetic Monitoring
* Universal Service Monitoring
* Workflow Automation
On Datadog [Cost Reports](/cost_reports), you can filter across several dimensions:
* Organization (organization name)
* Category (e.g., APM ingested spans). At the Category and Subcategory levels, you can access information such as how much Datadog spend is covered by committed-use discounts or which individual Datadog container is contributing to overall Logging costs.
* Tag/Not Tagged (includes Datadog tags and [virtual tags](/tagging) created in Vantage for this provider). The following additional tag is available for filtering and grouping:
* `datadog:organization:name`: The human-readable organization name associated with the cost, allowing you to filter and group multi-org Datadog costs by organization name.
* Subcategory (e.g., Commitment or On Demand)
* Charge Type (e.g., Usage)
* Service (e.g., Database Monitoring)
### Datadog Cost Tags (Usage Attribution Tags)
This feature is only available if you have a Datadog Enterprise plan with usage tags enabled.
You can have up to three tag keys per organization enabled for [usage attribution](https://docs.datadoghq.com/account_management/billing/usage_attribution/) in Datadog. Once enabled, Datadog begins breaking down the usage by any number of tag values for these keys. This allows you to see usage for specific services allocated to a specific key/value pair.
The following Datadog services support Datadog cost tags:
* APM
* Container Services
* CI Pipeline
* Fargate
* Infrastructure Hosts
* Invocations
* Lambda
* Logs
* NPM
* Spans
* Synthetic Tests
* Time Series
To use these tags within Vantage:
Open any [Cost Report](/cost_reports).
Click **Filters**, and select **Datadog** for the provider.
Click **New Rule** > **Tag**.
You can also **Group By** a specific tag key on a Datadog Cost Report. The following filter operators are supported:
* Tagged with key
* Tagged with Key where the value: is, is not, contains, does not contain
* Not Tagged
* Not Tagged with Key
If you just applied your first Datadog tag key and value, it can take up to 48 hours for the tag to appear in Vantage. Tags are not applied retroactively.
#### Usage-Based Cost Allocation
Vantage assigns Datadog cost to tags using **usage** data from Datadog's [usage attribution](https://docs.datadoghq.com/account_management/billing/usage_attribution/) API. For each cost category (e.g., `logs_ingested`), Vantage matches the cost to a corresponding usage key in your usage attribution export and splits the cost across tag values based on each value's share of usage.
Vantage tries several usage keys and patterns when matching cost categories to usage data, so when your usage is tagged (e.g., by `team`), that data is used to split the cost. As a result, more cost appears under the correct tags and less is left as untagged, giving you better visibility by team and other dimensions in [Cost Reports](/cost_reports) and [Virtual Tags](/tagging) without changing your total Datadog spend.
Because Vantage allocates cost using **usage-level** tag data, you may see differences when comparing against Datadog's own "cost by tag" exports, which may only attribute cost where the **cost itself** is directly tagged. This difference is methodological—total spend remains the same, but Vantage may attribute more cost to named tags and show less as untagged.
## Datadog Pricing in Vantage
For certain services, Datadog prices based on the 95th to 99th percentile (p95/p99) of usage rather than *daily* usage. For example, APM is billed on the [99th percentile](https://docs.datadoghq.com/account_management/billing/apm_tracing_profiler/#apm-hosts-with-dynamic-scaling-containers-fargate-and-no-indexed-spans) of the number of hosts you have running at any given time. In Vantage, Datadog costs are realized on the first day of the month. As the month progresses, you might notice that costs retroactively increase or decrease based on your usage.
Because these costs are always realized on the first of the month, when you compare previous periods for services that price on the p95/p99 of usage, you’ll always have the same comparison dates. For services that do not price on p95/p99, Vantage shows costs realized per day, when the accompanying usage data is available.
In the below visual example, a Cost Report is filtered to all Datadog costs. The date grouping is set to **Daily**. If you select a service row in the table, that service is isolated on the graph, and you can see how the service is priced. In this example, Log Management has accrual data and prices daily; whereas, Containers is priced based on the p95/p99 of usage, and costs are realized on the first of the month.

## View Datadog Metrics on Cost Reports
You can import Datadog metrics as business metrics to view alongside Cost Reports. See the [Business Metrics](/business_metrics#import-from-datadog) documentation for more information.
## Datadog Host Costs
For cloud resources that have the Datadog agent installed, Vantage can associate Datadog per-host fees along with the primary cloud resources from AWS, Azure, and Google Cloud that drive those costs. See the [Active Resources](/active_resources#datadog-host-costs) documentation for details on how to view these costs.
# DigitalOcean
Source: https://docs.vantage.sh/connecting_digitalocean
Learn how to integrate Vantage with DigitalOcean to track Droplet, backup, snapshot, and other infrastructure costs.
Vantage integrates with your DigitalOcean account using a personal access token to ingest cost data through the DigitalOcean [Billing API](https://docs.digitalocean.com/reference/api/reference/billing/). Vantage reads daily billing insights to retrieve day-over-day costs broken down by service (such as Droplets, Droplet Backups, and Droplet Snapshots), Droplet size, region, and SKU, so you can track DigitalOcean spend alongside your other cloud costs before the month-end invoice is finalized.
## DigitalOcean Permissions
Vantage connects to DigitalOcean using a personal access token scoped to **Billing** (`billing:read`) and validates access by reading the daily invoice preview. Vantage cannot create, modify, or destroy Droplets, or perform any actions that incur costs in your DigitalOcean account.
It's best practice to create a dedicated token for Vantage and rotate it according to your organization's security policy.
## Connect Your DigitalOcean Account
### Prerequisites
* You must have a Vantage **Organization Owner** or **Integration Owner** role to add or remove this integration. See the [Role-Based Access Control](/rbac) documentation for details.
* You need access to a DigitalOcean team that can create personal access tokens.
* [Create a free Vantage account](https://console.vantage.sh/signup), then follow the steps below to integrate DigitalOcean costs.
If your organization restricts access to the provider by IP address, add the following Vantage IP addresses to your provider's allowlist:
### Create the Connection
Open the DigitalOcean [Generate New Token](https://cloud.digitalocean.com/account/api/tokens/new) page.
Give the token a descriptive name and set **Expiration** to **No expiration**.
Under **Scopes**, select **Custom Scopes**.
Under **Custom Scopes**, select **Billing** (`billing:read`).
Generate the token and copy it.
DigitalOcean only shows the token once. Save it securely before closing the page.
From the top navigation in Vantage, click **Settings**.
On the left navigation, select **Integrations** > **DigitalOcean**.
The DigitalOcean integrations page is displayed. Ensure you are on the **Connect** tab.
Click **Add API Token** and complete the integration form:
* **API Token**: Paste the DigitalOcean personal access token.
* **Description**: Enter a label to identify the DigitalOcean team or account this token belongs to.
Click **Connect Account**.
After clicking **Connect Account**, you will see the status of your integration change to **Importing** within the Vantage console. This status indicates that Vantage is actively importing your DigitalOcean cost data. On initial connection, Vantage backfills historical cost data according to your account's retention window; because DigitalOcean's billing insights API only returns data on or after **December 1, 2025**, months before that date are not available. See the [Integration Status](/vantage_account#integration-status) documentation for details on integration statuses. You can connect multiple DigitalOcean teams, each with its own token, as separate integrations in Vantage.
As soon as costs are processed, they will be available on your **All Resources** Cost Report. If you decide to remove your DigitalOcean integration from Vantage, all costs associated with that DigitalOcean token will be removed from the Vantage console.
### Next Steps - Manage Workspace Access
Once the import is complete and the integration status changes to **Stable**, you can select which workspaces this integration is associated with. See the [Workspaces](/workspaces#manage-workspace-provider-integrations) documentation for information.
## Data Refresh
See the [provider data refresh documentation](/provider_data_refresh) for information on when data for each provider refreshes in Vantage. DigitalOcean data refreshes once daily. Because Vantage reads daily billing insights, in-month costs update daily and may differ from the finalized month-end invoice.
## DigitalOcean Reporting Dimensions
On DigitalOcean [Cost Reports](/cost_reports), you can filter and group across several dimensions:
* Account (the DigitalOcean team URN, such as do:team:...)
* Service (i.e., the DigitalOcean product derived from the SKU, such as Droplets, Droplet Backups, Droplet Snapshots, Droplet Custom Images, Volume Snapshots)
* Category (i.e., the Droplet size parsed from the line-item description, such as s-2vcpu-4gb; blank for line items without a size, such as snapshots, backups, custom images, and taxes)
* Region (i.e., the DigitalOcean region, such as nyc3)
* Charge Type (Usage or Tax)
In addition, DigitalOcean costs include the following provider tag, which is automatically created by Vantage and available for filtering and grouping alongside any [Virtual Tags](/tagging) you create:
| Tag | Description |
| - | - |
| `digital_ocean:sku` | The native DigitalOcean SKU for the line item (e.g., 1-DR-DROPL-0BKUP) |
# Elastic
Source: https://docs.vantage.sh/connecting_elastic
Learn how to integrate Vantage with Elastic Cloud.
Vantage connects to your Elastic Cloud account using a billing API key. Vantage uses the [Elastic Cloud Billing API](https://www.elastic.co/docs/api/doc/cloud-billing/) (including the [Billing Costs Analysis API](https://www.elastic.co/docs/api/doc/cloud/group/endpoint-billingcostsanalysis)) to ingest cost and usage data for your Elastic organizations. Vantage displays Elastic Cloud costs and associated [usage metrics](/usage_based_reporting), such as Hours (Elasticsearch), Gigabytes (Data Transfer), and API Calls (Storage), in line with other infrastructure costs.
You can connect multiple Elastic integrations by adding separate API keys; each integration can include one or more Elastic organizations that the API key can access. To create an API key, you must have the **Organization Owner** or **Billing Admin** role in Elastic. The longest expiration for an Elastic API key is one year, so you will need to rotate the key in Vantage when it expires. It's best practice to use a dedicated API key for Vantage and rotate it per your security policy.
This integration is for **Elastic Cloud** only. It is not compatible with self-hosted Elastic (Elastic Cloud Enterprise).
## Connect Your Elastic Cloud Account
### Prerequisites
* You must have a Vantage **Organization Owner** or **Integration Owner** role to add or remove this integration. See the [Role-Based Access Control](/rbac) documentation for details.
* An Elastic Cloud account with access to create API keys with billing permissions.
* [Create a free Vantage account](https://console.vantage.sh/signup), then follow the steps below to integrate Elastic Cloud costs.
Vantage cannot perform writes to your Elastic Cloud organization. Vantage uses the [Billing Admin](https://www.elastic.co/docs/deploy-manage/users-roles/cloud-organization/user-roles) role to read cost and usage data only; it cannot manage organization or deployment settings.
If your organization restricts access to the provider by IP address, add the following Vantage IP addresses to your provider's allowlist:
### Create the Connection
Log in to the [Elastic Cloud console](https://cloud.elastic.co/login).
Click your user avatar on the top right. Select **Organization**.
Select the **API Keys** tab.

Create a new API key:
* Enter a name.
* Set the expiration (max one year). If the key expires, you'll need to update the integration in Vantage with a new API key.
* For **Assign roles**, select the **Billing Admin** permissions.
Click **Create API key** and copy the API key.
In Vantage, from the top navigation click **Settings**.
On the left navigation, select **Integrations** and select **Elastic**. Ensure you are on the **Connect** tab.
On the Elastic integrations page, click **Add API Key**.
Enter a **Description** (e.g., a name for this connection) and paste the API key. Click **Connect Account**.
If you are an AWS GovCloud user, check the **Uses AWS GovCloud** box and select your region from the dropdown. This ensures Vantage uses the relevant APIs for GovCloud.
After connecting, the integration status will show **Importing** while Vantage ingests your Elastic cost data. Once the import is complete, the status changes to **Stable**. See [Integration Status](/vantage_account#integration-status) for details.
When the integration is first connected, Vantage ingests up to **six months** of historical Elastic cost data. Data is retained according to your Vantage retention period. If you remove the Elastic integration from Vantage, all associated costs will be removed from the Vantage console.
### Next Steps - Manage Workspace Access
Once the integration status is **Stable**, you can choose which workspaces can use this integration. See [Workspaces](/workspaces#manage-workspace-provider-integrations) for how to manage workspace provider integrations.
## Data Refresh
See the [provider data refresh documentation](/provider_data_refresh) for when Elastic data refreshes in Vantage.
## Elastic Reporting Dimensions
On [Cost Reports](/cost_reports), you can filter and group Elastic costs by:
* **Organization** (Account/Billing Account) – Elastic organization ID (each organization accessible by the API key is synced as an account)
* **Service** – Normalized service name (e.g., Elastic Cloud, Elasticsearch, Kibana, Data Transfer, Storage, Synthetics, APM, Machine Learning; serverless products may appear with a "Serverless" suffix)
* **Category** – Cost type from Elastic (e.g., capacity, data\_in, data\_out, storage\_bytes)
* **Subcategory** – Product kind from Elastic (e.g., elasticsearch, kibana, apm)
* **Region** – Derived from the line item SKU when available (e.g., aws-us-east-2, azure-eastus)
* **Resource** – When daily cost breakdown is available, deployment or resource name may appear
* **Charge Type** – e.g., Usage
* **Tag** – [Virtual Tags](/tagging) created in Vantage for this provider (Elastic does not supply tags in billing data)
# ElevenLabs
Source: https://docs.vantage.sh/connecting_elevenlabs
Learn how to integrate Vantage with ElevenLabs to track voice AI cost and usage.
Vantage integrates with your ElevenLabs account using a read-only API key to ingest cost and usage data through the ElevenLabs [Usage Analytics API](https://elevenlabs.io/docs/api-reference/workspace/usage/get-usage-by-product-over-time). Vantage retrieves detailed cost and usage data broken down by model (e.g., Eleven Turbo v2, Eleven Multilingual v2), product type (e.g., Text to Speech, Speech to Text, Conversational AI), and voice. [Usage data](/usage_based_reporting) is available for ElevenLabs, measured in credits.
Vantage imports cost and usage from the ElevenLabs [Usage Analytics API](https://elevenlabs.io/docs/overview/administration/usage-analytics). That API covers credit consumption and usage-based charges only. It does **not** include monthly or annual subscription fees, seat fees, or other recurring invoice line items. Included plan credits can still appear as usage when they are consumed.
## ElevenLabs Permissions
Vantage cannot perform cost-incurring actions and only ever reads cost and usage data from ElevenLabs. The API key you provide requires **Workspace Analytics** access, which lets Vantage import your usage and cost data. Optionally, you can grant **Voices (read)** access so Vantage can enrich the voice IDs returned by the API with human-readable voice names. Vantage cannot create voices, initiate generation requests, or perform any action that incurs costs in your ElevenLabs account.
Vantage stores only billing metadata (e.g., credit counts, model usage, and costs). No voice audio or text content is ingested or stored.
Due to ElevenLabs API restrictions, Vantage can query a limited number of dimensions at a time from the Usage Analytics API. If ElevenLabs lifts this limitation for your account, Vantage will add further granularity to the available data. Contact your ElevenLabs account team to raise this request.
## Connect Your ElevenLabs Account
### Prerequisites
* You must have a Vantage **Organization Owner** or **Integration Owner** role to add or remove this integration. See the [Role-Based Access Control](/rbac) documentation for details.
* You must have access to create API keys in ElevenLabs, with **Workspace Analytics** access. It's best practice to use a dedicated key for Vantage and rotate it per your organization's security policy.
* [Create a free Vantage account](https://console.vantage.sh/signup), then follow the steps below to integrate ElevenLabs costs.
### Create the Connection
Navigate to the [ElevenLabs API keys](https://elevenlabs.io/app/developers/api-keys) page and click **+ Create Key**.
On the **Create API Key** slideout, scroll down to the **Administration** section, and select **Access** next to **Workspace Analytics**. This permission is required for the integration to work.
If you enable the **Restrict Keys** toggle to limit which IPs can use this key, add each of the following Vantage IPs to the allowed list so Vantage can reach the ElevenLabs API. Add each IP address individually:
Optionally, under the **Endpoints** section, grant **Voices** read access. This is not required, but it allows Vantage to enrich the voice IDs returned in API responses with voice names.
Click **Create Key** and copy your newly generated key.
From the top navigation in Vantage, click **Settings**.
On the left navigation, select **Integrations** > **ElevenLabs**.
The ElevenLabs integration page is displayed. Ensure you are on the **Connect** tab.
Click **Add API Key** and paste your previously generated API key.
For **API environment**, choose the region that matches your ElevenLabs account. Use **Global** for standard accounts, or select **EU**, **India**, or **Singapore** for Enterprise data residency.
For **Description**, enter any descriptor to identify this integration, such as your name or workspace. This value is used as the **Organization** dimension in Cost Report filters.
For **Credit rate**, choose how Vantage should calculate reported costs:
* **Use ElevenLabs' public rate**: Vantage uses the API-reported costs directly, which track ElevenLabs' rates automatically. This is the default.
* **Use my own negotiated rate**: enter your **Price per 1,000 credits (USD)** to calculate costs from credit usage. Select this if you have custom or enterprise pricing.
Click **Connect Account**.
After clicking **Connect Account**, you will see the status of your integration change to **Importing** within the Vantage console. This status indicates that Vantage is actively importing your ElevenLabs cost data. Vantage backfills up to six months of historical cost data upon initial connection. See the [Integration Status](/vantage_account#integration-status) documentation for details on integration statuses. You can connect multiple ElevenLabs accounts, each with its own API key, as separate integrations in Vantage.
As soon as costs are processed, they will be available on your **All Resources** Cost Report. If you decide to remove your ElevenLabs integration from Vantage, all costs associated with your ElevenLabs API key will be removed from the Vantage console.
### Next Steps - Manage Workspace Access
Once the import is complete and the integration status changes to **Stable**, you can select which workspaces this integration is associated with. See the [Workspaces](/workspaces#manage-workspace-provider-integrations) documentation for information.
## Data Refresh
See the [provider data refresh documentation](/provider_data_refresh) for information on when data for each provider refreshes in Vantage. ElevenLabs data refreshes once daily.
## ElevenLabs Reporting Dimensions
On ElevenLabs [Cost Reports](/cost_reports), you can filter and group across several dimensions:
* Organization (the description you enter when connecting the integration; use **Billing Account** for filtering and grouping)
* Service (i.e., the model name, such as Eleven Turbo v2 or Eleven Multilingual v2)
* Category (i.e., the product type, such as Text to Speech, Speech to Text, or Conversational AI)
* Resource (i.e., the voice name when **Voices (read)** access is granted, otherwise the voice ID)
* Charge Type (Usage)
In addition, ElevenLabs costs include the following provider tags, which are automatically created by Vantage and available for filtering and grouping alongside any [Virtual Tags](/tagging) you create:
| Tag | Description |
| - | - |
| `elevenlabs:model` | The model identifier associated with the usage (e.g., eleven\_turbo\_v2) |
| `elevenlabs:product_type` | The ElevenLabs product type (e.g., tts, stt) |
| `elevenlabs:voice_id` | The voice ID associated with the usage |
| `elevenlabs:voice_name` | The voice name, populated when **Voices (read)** access is granted |
| `elevenlabs:voice_category` | The voice category, populated when **Voices (read)** access is granted |
Vantage also applies [Managed AI Tags](/managed_ai_tags) to ElevenLabs costs. This is a normalized `vntg:ai:` schema shared across all AI providers, so you can analyze AI spend with consistent dimensions. For ElevenLabs, the following keys are emitted: `vntg:ai:model` and `vntg:ai:model_provider`. See [Managed AI Tags](/managed_ai_tags) for the full schema.
# Fastly
Source: https://docs.vantage.sh/connecting_fastly
Learn how to integrate Vantage with Fastly.
Vantage integrates with your Fastly account through a read-only API token. Fastly API tokens are free for you to create, and adding them to the Vantage console takes only a few minutes.
## Connect Your Fastly Account
### Prerequisites
* You must have a Vantage **Organization Owner** or **Integration Owner** role to add or remove this integration. See the [Role-Based Access Control](/rbac) documentation for details.
* [Create a free Vantage account](https://console.vantage.sh/signup), then follow the steps below to create a Fastly API token.
If your organization restricts access to the provider by IP address, add the following Vantage IP addresses to your provider's allowlist:
Navigate and log in to the [Fastly console](https://www.fastly.com/).
On the [**API tokens** page](https://manage.fastly.com/account/personal/tokens), re-enter your password if prompted. Then, click **+ Create Token**.
Enter the following token details:
* For **Name**, enter something relevant, like *VantageReadOnlyToken*.
* For **Type**, select **Automation token**.
* If the **Role** option is displayed, select **Billing**.
* For **Scope**, select **Read-only access (`global:read`) — Read account information configuration and stats**. Ensure all other options remain unchecked. Vantage will never attempt to make changes to your Fastly infrastructure.
* For **Access**, select **All Services on YOUR\_ORGANIZATION\_NAME**.
* For **Expiration**, select **Never expire**.

Click **Create Token**, and re-enter your password if prompted. Fastly will generate your API token. Copy this token for the next steps.
### Create the Connection
From the Vantage console, navigate to the [Fastly Settings page](https://console.vantage.sh/settings/fastly).
Click **Add API Token**, then paste the API token you just generated.
Click **Connect Account**.
After clicking **Connect Account**, you will see the status of your integration change to **Importing** within the Vantage console. This status indicates that Vantage is actively importing your Fastly cost data. Vantage will automatically begin ingesting and visualizing your costs. It should take about an hour for cost data to populate. See the [Integration Status](/vantage_account#integration-status) documentation for details on integration statuses.
### Next Steps - Manage Workspace Access
Once the import is complete and the integration status changes to **Stable**, you can select which workspaces this integration is associated with. See the [Workspaces](/workspaces#manage-workspace-provider-integrations) documentation for information.
## Data Refresh
See the [provider data refresh documentation](/provider_data_refresh) for information on when data for each provider refreshes in Vantage.
## Fastly Reporting Dimensions
On Fastly [Cost Reports](/cost_reports), you can filter across several dimensions:
* Account (account name)
* Category (e.g., CDN Data Transfer)
* Subcategory (e.g., CDN Requests)
* Resource (service resource ID)
* Region (e.g., USA)
* Charge Type (e.g., Usage)
* Service (e.g., CDN)
* Tag ([virtual tags](/tagging) created in Vantage for this provider)
# Fireworks AI
Source: https://docs.vantage.sh/connecting_fireworks_ai
Learn how to integrate Vantage with Fireworks AI to track serverless inference, dedicated deployment, and training costs.
Vantage integrates with your Fireworks AI account using an API key to ingest cost and usage data through Fireworks AI's [billing summary API](https://docs.fireworks.ai/accounts/exporting-usage-and-costs). Vantage retrieves daily rated cost and usage data broken down by product (Serverless Inference, Serverless Training API, Dedicated Training API, On Demand Deployments, and Managed Training), the model bucket or accelerator type driving each charge, and the usage category (for example, LLM input tokens or GPU-hours). [Usage data](/usage_based_reporting) is available for Fireworks AI, measured in tokens for inference and training, and in GPU-hours for on-demand deployments and the Dedicated Training API.
## Fireworks AI Permissions
Vantage connects to Fireworks AI using an API key and validates access by listing the Fireworks accounts associated with that key. Vantage cannot deploy models, trigger inference or training jobs, or perform any actions that incur costs in your Fireworks AI account.
It's best practice to create a dedicated API key for Vantage and rotate it according to your organization's security policy. Vantage does not ingest prompt or response content from Fireworks AI. Only billing metadata, such as token and GPU-hour consumption, is stored.
## Connect Your Fireworks AI Account
### Prerequisites
* You must have a Vantage **Organization Owner** or **Integration Owner** role to add or remove this integration. See the [Role-Based Access Control](/rbac) documentation for details.
* You need access to a Fireworks AI account that can create API keys.
* [Create a free Vantage account](https://console.vantage.sh/signup), then follow the steps below to integrate Fireworks AI costs.
If your organization restricts access to the provider by IP address, add the following Vantage IP addresses to your provider's allowlist:
### Create the Connection
Sign in to the [Fireworks AI dashboard](https://app.fireworks.ai/).
On the left navigation, click **Settings** > **API Keys**.
Click **Create API Key** > **API Key**.
Give the key a descriptive name, then click **Generate Key**. You can optionally set an expiration date. If the key expires, Vantage can no longer refresh your Fireworks AI cost data, so you will need to generate a new key and update it in Vantage before then.
Copy the API key.
Fireworks AI only shows the API key once. Save it securely before closing the dialog.
From the top navigation in Vantage, click **Settings**.
On the left navigation, select **Integrations** > **Fireworks AI**.
The Fireworks AI integrations page is displayed. Ensure you are on the **Connect** tab.
Click **Add API Key** and complete the integration form:
* **API Key**: Paste the Fireworks AI API key.
* **Description**: Enter a label to identify this Fireworks AI connection in Vantage. This value is used as the **Organization** dimension in Cost Report filters. Fireworks accounts accessible with this key are connected automatically.
Click **Connect Account**.
After clicking **Connect Account**, you will see the status of your integration change to **Importing** within the Vantage console. This status indicates that Vantage is actively importing your Fireworks AI cost data. Vantage backfills up to six months of historical cost data upon initial connection. See the [Integration Status](/vantage_account#integration-status) documentation for details on integration statuses. You can connect multiple Fireworks AI accounts, each with its own API key, as separate integrations in Vantage.
As soon as costs are processed, they will be available on your **All Resources** Cost Report. If you decide to remove your Fireworks AI integration from Vantage, all costs associated with that Fireworks AI account will be removed from the Vantage console.
Vantage shows gross rated usage cost from Fireworks AI's billing summary. Credits, discounts, taxes, and invoice adjustments are not currently exposed by Fireworks AI's billing summary API, so costs in Vantage may differ from your final Fireworks AI invoice. If you have negotiated pricing you'd like reflected, contact [support@vantage.sh](mailto:support@vantage.sh).
### Next Steps - Manage Workspace Access
Once the import is complete and the integration status changes to **Stable**, you can select which workspaces this integration is associated with. See the [Workspaces](/workspaces#manage-workspace-provider-integrations) documentation for information.
## Data Refresh
See the [provider data refresh documentation](/provider_data_refresh) for information on when data for each provider refreshes in Vantage. Fireworks AI data refreshes once daily.
## Fireworks AI Reporting Dimensions
On Fireworks AI [Cost Reports](/cost_reports), you can filter and group across several dimensions:
* Organization (the description you enter when connecting the integration)
* Service (i.e., the Fireworks AI product, such as Serverless Inference, Serverless Training API, Dedicated Training API, On Demand Deployments, or Managed Training)
* Category (i.e., the model bucket, accelerator type, or base model name driving the charge, such as `GLM 5.2` or `NVIDIA_B200_180GB`)
* Subcategory (i.e., the usage category, such as `LLM input tokens (uncached)`, `LLM output tokens`, or `On-demand deployment GPU-hours`)
* Charge Type (Usage)
In addition, Fireworks AI costs include the following provider tag, which is automatically created by Vantage and available for filtering and grouping alongside any [Virtual Tags](/tagging) you create:
| Tag | Description |
| - | - |
| `fireworks:is_turbo` | Whether Managed Training usage used turbo fine-tuning |
Vantage also applies [Managed AI Tags](/managed_ai_tags) to Fireworks AI costs. This is a normalized `vntg:ai:` schema shared across all AI providers, so you can analyze AI spend with consistent dimensions. For Fireworks AI, the following keys are emitted: `vntg:ai:model`, `vntg:ai:model_provider`, and `vntg:ai:token_type`. See [Managed AI Tags](/managed_ai_tags) for the full schema.
# Google Cloud
Source: https://docs.vantage.sh/connecting_gcp
Learn how to integrate Vantage with Google Cloud.
Vantage uses a [service account](https://cloud.google.com/iam/docs/service-accounts) to integrate with your GCP account. Vantage requests extremely basic and limited permissions for GCP. During the integration process, you will grant the service account access *only* to the specific BigQuery dataset that contains your billing data. Vantage runs the queries that extract your billing data in its own Google Cloud project and absorbs the associated query and compute costs. As a result, you only need to grant the Vantage service account read access to your billing dataset. You do not need to grant permission to run BigQuery jobs in your own project.
To attribute Vertex AI Gemini and Marketplace Claude spend to teams, users, applications, and features by your own per-request dimensions, see [Custom LLM Enrichment](/custom_llm_enrichment), which joins per-request token telemetry you deliver to S3 with your Google Cloud costs.
## Prerequisites
Before you start the integration process, you will need to complete the following prerequisites:
* Create a project to store your Cloud Billing export data.
* Create a BigQuery dataset to store your Cloud Billing export data.
* Enable Cloud Billing export.
* You must have a Vantage **Organization Owner** or **Integration Owner** role to add or remove this integration. See the [Role-Based Access Control](/rbac) documentation for details.
See the [GCP Cloud Billing export](/enabling_gcp_billing_export/) instructions for details on how to complete the above steps. Then, return to this page to complete the rest of the integration process.
If your organization enforces domain restrictions, you can add the following Google Cloud organization ID to allow Vantage access: `421856710303`. If you instead need the customer ID, use `C03l99qsz`.
If your organization restricts access to the provider by IP address, add the following Vantage IP addresses to your provider's allowlist:
**If you have a pre-existing Cloud Billing export** set up, ensure your configuration adheres to the requirements below before moving further.
* Your project is linked to the same Cloud Billing account that the Cloud Billing export is enabled on.
We recommend you create a dedicated project to store all Cloud Billing data, rather than using an existing project.
* Detailed Billing Export is enabled, *not* Standard Billing Export.
* The BigQuery dataset and table are deployed to either **US (multiple regions in United States)** or **EU (multiple regions in European Union)**.
* If you have multiple Cloud Billing accounts, you will need to enable Cloud Billing exports on each account.
If your GCP billing data is typically displayed in a currency other than USD, Vantage will convert it to USD using the `currency_conversion_rate` field in the Cloud Billing export data.
## Create a Connection
Open a new browser tab, and navigate to the [Vantage GCP Settings page](https://console.vantage.sh/settings/gcp). You should see your customer-specific service account displayed at the top of the integration page. Keep this page open.
**Previously required the BigQuery Job User role.** Vantage used to run billing queries inside your project, which required you to grant the Vantage service account the **BigQuery Job User** role. Vantage now runs these queries in its own project and covers the cost, so this role is no longer required for the billing extract. If you connected GCP before this change, removing the **BigQuery Job User** grant from your project will not affect your billing imports. We recommend removing it so the service account keeps only the access Vantage needs.
### Step 1 - Grant the Vantage Service Account Permission to Access the BigQuery Dataset
Go back to [BigQuery](https://console.cloud.google.com/bigquery), and complete the steps below to grant the Vantage service account permission to access the BigQuery dataset.
At the top of the BigQuery console, ensure the project that you set up to contain your billing data is selected.
In the **Classic Explorer** panel, select your project to expand it.
Select the **three vertical dots** next to the dataset name, then click **Open**. The **Dataset info** will be displayed on the right. *Keep this screen open as you will need to obtain your project ID and dataset name in the [Add Your GCP Configuration Information to the Vantage Console](/connecting_gcp#step-3-add-your-gcp-configuration-information-to-the-vantage-console) step.*
Select the three vertical dots next to the dataset name again, then click **Share** > **Manage permissions**.

*In this example, **project-id-123456** is the project and **all\_billing\_data** is the dataset.*
On the **Share permissions** panel that appears on the right, click **+ Add principal**.
In the **New principals** field, under **Add principals**, search for and select the Vantage service account.
Copy the full name of your service account from the Vantage console into the search field to search for it.
In the **Role** field, under **Assign roles**, search for and select **BigQuery Data Viewer**.

Click **Save**.
**Using GCP BigQuery Business Metrics?** [GCP BigQuery Business Metrics](/business_metrics#import-via-gcp-bigquery) let you import a business metric by running SQL against your BigQuery data. Unlike the billing extract, these metric queries run in *your* project, so they require the Vantage service account to have the **BigQuery Job User** role on the project that runs the query, in addition to the **BigQuery Data Viewer** role on each referenced dataset. If you use this feature, grant **BigQuery Job User** on the query project and **BigQuery Data Viewer** on each dataset the query references.
**Using VPC Service Controls?** If your organization protects BigQuery with a [VPC Service Controls](/connecting_gcp#vpc-service-controls) perimeter, granting the roles above is not sufficient. You must also add a perimeter exception so the Vantage service account can read your billing dataset from the Vantage project. See the [VPC Service Controls](/connecting_gcp#vpc-service-controls) section below. Ordinary VPC or Shared VPC networking does not require any changes.
### Step 2 - Grant the Vantage Service Account Permissions to Access Active Resources
To enable [active resources](/active_resources), you must grant the Vantage GCP service account permissions *at the organization level*. This allows Vantage to gather data on active resources across your organization. For a list of all supported GCP active resources, see the [GCP Supported Services](/gcp_supported_services) documentation.
**Choosing your permission approach:**
The **Viewer role** (Simple) is the quickest option and covers all services with a single built-in role. However, it grants broad read access across GCP, including the ability to read BigQuery table contents and Cloud Storage object contents.
The **custom role** (Minimal Permissions) grants only the specific permissions Vantage needs to list resource metadata. Choose this option if your organization has security requirements that prohibit broad read access.
Grant the built-in **Viewer** role to the Vantage service account at the organization level.
Open a new tab in GCP, and navigate to **IAM & Admin**.
On the top left of the screen, switch to your organization.
Click **+ Grant access**.

In the **New principals** field, under **Add principals**, paste the value for your Vantage service account.
This value is the one displayed on the [Vantage GCP Integration page](https://console.vantage.sh/settings/gcp) you opened earlier and have used for other permissions.
Under **Assign roles**, click **Basic** and select the **Viewer** role from the **Role** list. This adds the role needed for active resources.

Click **Save**.
Create a custom IAM role with only the permissions required for Vantage to list active resource metadata. This role does **not** grant access to BigQuery table contents, Storage object contents, or Secret Manager secret values.
**Troubleshooting missing permissions:** If you notice that active resources for a specific GCP service are not appearing in Vantage, the custom role may be missing a required permission. Contact Vantage support with the service name, and we'll provide the specific IAM permission to add. You can update an existing custom role by editing the YAML file and running `gcloud iam roles update` instead of `create`.
Create a file named `vantage-active-resources-role.yaml` with the following content:
```yaml vantage-active-resources-role.yaml theme={null}
title: Vantage Active Resources Viewer
description: Read-only access to resource metadata for Vantage active resources sync
stage: GA
includedPermissions:
- resourcemanager.projects.list
- resourcemanager.projects.get
- resourcemanager.folders.get
- compute.instances.list
- compute.disks.list
- storage.buckets.list
- bigtable.instances.list
- dataflow.jobs.list
- bigquery.datasets.get
- logging.sinks.list
- cloudsql.instances.list
- spanner.instances.list
- appengine.applications.get
- appengine.services.list
- datastore.databases.list
- run.services.list
- container.clusters.list
- redis.instances.list
- cloudfunctions.functions.list
- alloydb.clusters.list
- alloydb.instances.list
- alloydb.backups.list
- secretmanager.secrets.list
```
Create the custom role at the organization level. Replace `ORG_ID` with your GCP organization ID:
```bash theme={null}
gcloud iam roles create vantageActiveResourcesViewer \
--organization=ORG_ID \
--file=vantage-active-resources-role.yaml
```
Grant the custom role to the Vantage service account. Replace `ORG_ID` with your GCP organization ID and `VANTAGE_SERVICE_ACCOUNT` with the service account from the [Vantage GCP Integration page](https://console.vantage.sh/settings/gcp):
```bash theme={null}
gcloud organizations add-iam-policy-binding ORG_ID \
--member="serviceAccount:VANTAGE_SERVICE_ACCOUNT" \
--role="organizations/ORG_ID/roles/vantageActiveResourcesViewer"
```
### Step 3 - Add Your GCP Configuration Information to the Vantage Console
Go back to your browser tab that has BigQuery open. Then, in another tab, go back to the [Vantage GCP Integration page](https://console.vantage.sh/settings/gcp) to complete the integration process.
At the bottom of the Vantage GCP Integration page, click **Add Project Info**. A pop-up is displayed, which requires your Billing account ID, the project ID for the project that hosts the BigQuery dataset, and the BigQuery dataset name.
To obtain your **Billing Account ID**:
* Go to [**GCP Billing**](https://console.cloud.google.com/billing).
* Copy the value for your billing account, displayed in the **Account ID** column. It will look something like `1234AB-123456-7ABC12`.

To obtain your **Project ID hosting BigQuery dataset** and **BigQuery Dataset Name**:
* In the **Dataset info** screen of BigQuery (previously opened in step 3 of the [BigQuery permissions](/connecting_gcp#step-1-grant-the-vantage-service-account-permission-to-access-the-bigquery-dataset) section), observe the value on the **Dataset ID** line (ensure you are on the **Details** tab).

* Copy everything before the period. For example, in **project-id-123456.all\_billing\_data**, copy only **project-id-123456**. Paste this in the **Project ID hosting BigQuery dataset** field in Vantage.
* Copy everything after the period and paste it in the **BigQuery Dataset Name** field in Vantage. (For example, in **project-id-123456.all\_billing\_data**, copy **all\_billing\_data**.)

Click **Connect Account**.
It typically takes a few hours for data to start appearing. Cloud Billing data is added retroactively for the current and previous month when detailed usage cost data is configured. Full data for the current and previous month can take 24–48 hours to fully propagate.
After creating your connection, you will see the status of your integration change to **Importing** within the Vantage console. This status indicates that Vantage is actively importing your GCP cost data. See the [Integration Status](/vantage_account#integration-status) documentation for details on integration statuses.
### Next Steps - Manage Workspace Access
Once the import is complete and the integration status changes to **Stable**, you can select which workspaces this integration is associated with. See the [Workspaces](/workspaces#manage-workspace-provider-integrations) documentation for information.
## VPC Service Controls
Most customers do not need to complete this section. It applies only if your organization uses [VPC Service Controls](https://cloud.google.com/vpc-service-controls/docs/overview) (VPC-SC) to place a security perimeter around BigQuery.
Ordinary VPC or Shared VPC networking does **not** affect this integration. BigQuery is an API service rather than a resource inside your network, so standard VPC configuration, even a project-wide VPC, requires no changes. Only a VPC Service Controls perimeter requires the exceptions below.
Because Vantage runs billing queries from its own Google Cloud project, a VPC-SC perimeter around your billing project will block Vantage even though the **BigQuery Data Viewer** grant is still valid. To allow access, add the following two rules to your perimeter:
* An **ingress** rule that lets the Vantage service account read your billing export (`bigquery.tables.getData`).
* An **egress** rule that lets query results flow to the BigQuery job in the Vantage query project (`bigquery.jobs.create`).
Replace the placeholders before applying:
* `VANTAGE_SERVICE_ACCOUNT_EMAIL`: the service account displayed on the [Vantage GCP Integration page](https://console.vantage.sh/settings/gcp).
* `VANTAGE_QUERY_PROJECT_NUMBER`: the Vantage query project number. Contact [Vantage support](mailto:support@vantage.sh) to obtain this value.
```yaml ingress.yaml theme={null}
# ingress.yaml - lets the Vantage service account read your billing export
- ingressFrom:
identities:
- serviceAccount:VANTAGE_SERVICE_ACCOUNT_EMAIL
sources:
# Vantage submits queries from outside Google Cloud, so a
# project-pinned source will not match. Identity pinning above is
# the effective control; an IP-based access level for Vantage's
# egress IPs can be substituted if you require source restrictions.
- accessLevel: "*"
ingressTo:
resources:
- "*"
operations:
- serviceName: bigquery.googleapis.com
methodSelectors:
- permission: bigquery.tables.getData
```
```yaml egress.yaml theme={null}
# egress.yaml - lets query results flow to the BigQuery job in
# Vantage's query project (VPC-SC checks jobs.create on the target)
- egressFrom:
identities:
- serviceAccount:VANTAGE_SERVICE_ACCOUNT_EMAIL
egressTo:
resources:
- projects/VANTAGE_QUERY_PROJECT_NUMBER
operations:
- serviceName: bigquery.googleapis.com
methodSelectors:
- permission: bigquery.jobs.create
```
## Data Refresh
See the [provider data refresh documentation](/provider_data_refresh) for information on when data for each provider refreshes in Vantage.
## Reporting Dimensions
On GCP [Cost Reports](/cost_reports), you can filter across several dimensions:
* Project (project name)
* Category (e.g., Cloud Functions Invocations (2nd Gen))
* Subcategory (e.g., Compute Engine - E2 Custom Instance Ram running in Americas - this will most often be the same as Category, but in cases where the Category is Other, the Subcategory will provide more detail, such as a SKU description as shown here)
* Label/Not Labeled (includes GCP labels and [virtual tags](/tagging) created in Vantage for this provider). In addition, the following provider tags are automatically created by Vantage from GCP data and are available for filtering and grouping when the GCP folder tag feature is enabled:
* `gcp:folder:id`: The GCP folder ID associated with the project, allowing you to filter and group costs by folder ID.
* `gcp:folder:name`: The GCP folder name associated with the project, allowing you to filter and group costs by folder name.
* `gcp:folder`: The combined folder ID and name (format: `id/name`), allowing you to filter and group costs by folder.
* `gcp:project_id`: The GCP project ID associated with the line item, allowing you to filter and group costs by project ID.
* `gcp:project_name`: The human-readable GCP project name, allowing you to filter and group costs by project name.
* `gcp:invoice_month`: The GCP invoice month (format: `YYYYMM`), allowing you to filter and group costs by invoice month.
* `gcp:sku`: The GCP SKU ID for the line item, allowing you to filter and group costs by individual SKU.
* Resource (resource ID)
* Region (e.g., Us East1)
* Charge Type (e.g., Usage)
* Billing Account (billing account ID)
* Marketplace (Toggle to show only Marketplace purchases or excluded)
* Service (e.g., Cloud Build)
Vantage also applies [Managed AI Tags](/managed_ai_tags) to Vertex AI Gemini and Marketplace Claude cost rows. This is a normalized `vntg:ai:` schema shared across all AI providers, so you can analyze AI spend with consistent dimensions. On those rows, the following keys are emitted: `vntg:ai:model`, `vntg:ai:raw_model`, `vntg:ai:model_provider`, `vntg:ai:provider_region`, and `vntg:ai:token_type`. These tags apply only to Vertex AI Gemini and Marketplace Claude usage; other Google Cloud costs are unaffected. See [Managed AI Tags](/managed_ai_tags) for the full schema.
## Reconcile Vantage With GCP Invoice Totals
If you compare a GCP invoice to a Vantage Cost Report and the totals do not line up exactly, the difference is usually caused by how the data is grouped rather than by missing costs.
Use the following workflow to match a GCP invoice more closely:
* Filter the report to the relevant **Billing Account**.
* Group or filter by the `gcp:invoice_month` provider tag to align the report with GCP's invoice month.
* When validating a single invoice month with a date-based Cost Report, include the last day of the previous month and the first day of the following month. Vantage bins GCP costs in UTC using `usage_start_time`, while GCP invoice views may reflect a different local timezone.
* Review your report's **Cost Settings** to confirm whether credits, discounts, refunds, and taxes are included. You may need to enable these settings in Vantage to match the invoice totals shown in GCP.
* If you recently connected the integration, allow 24–48 hours for the current and previous month to fully propagate before comparing totals.
If you manage several billing accounts and want more readable labels in reports, create [Virtual Tags](/tagging) that map each billing account ID to a friendly name.
## View GCP BigQuery Metrics on Cost Reports
You can import GCP BigQuery SQL query results as business metrics to view alongside Cost Reports. BigQuery business metric imports reuse a connected GCP detailed billing integration, but the service account must have **BigQuery Job User** on the job project and **BigQuery Data Viewer** on each dataset referenced in your query. See the [Business Metrics](/business_metrics#import-via-gcp-bigquery) documentation for more information.
# GitHub
Source: https://docs.vantage.sh/connecting_github
Learn how to integrate Vantage with GitHub.
Vantage ingests GitHub costs through the [GitHub Enhanced Billing API](https://docs.github.com/en/rest/billing/enhanced-billing). With this integration, you can programmatically grant Vantage access to GitHub billing data for multiple organizations.
## Supported Services
Vantage supports the following GitHub services:
* Actions
* Large File Storage
* Copilot
* Codespaces
* Shared Storage
* Packages
* In addition to these services, you can also use existing Vantage tagging capabilities to track the underlying compute costs for self-hosted runners that run on a virtual machine, such as an EC2 instance, or in Kubernetes.
## Migrate to the New GitHub Billing Integration
Previously, Vantage ingested GitHub costs using a Vantage-owned billing manager account that customers added to their GitHub Organization or Enterprise (released in September 2024). This approach required users to manually invite a billing email address, which had limitations, such as incompatibility for organizations who use SSO authentication.
The second version of this integration (released in March 2025) uses the GitHub Enhanced Billing API. Any Vantage customer that is using GitHub services today and has been migrated to the Enhanced Billing API can use the new integration. GitHub started migrating customers to their new billing platform in [September 2024](https://docs.github.com/en/enterprise-cloud@latest/billing/using-the-new-billing-platform/automating-usage-reporting), with all accounts being migrated by the [end of March 2025](https://github.blog/changelog/2024-09-24-enhanced-billing-platform-for-enterprises/). See the [Prerequisites](/connecting_github#prerequisites) section below for instructions on how to validate if you’ve been migrated.
For customers on the first version of the Vantage integration, Vantage does not have a way of migrating to the new integration on your behalf. You will need to install the [Billing - vantage-sh](https://github.com/apps/billing-vantage-sh) application in your organization to use the new GitHub integration. See the [Create the Connection](/connecting_github#create-the-connection) section below for instructions on how to complete this new integration.
## How Vantage Integrates with GitHub
The Vantage–GitHub integration requires the [Billing - vantage-sh](https://github.com/apps/billing-vantage-sh) GitHub application added to your GitHub organization. Once installed, Vantage can access cost and usage data through the [Enhanced Billing /usage API](https://docs.github.com/en/enterprise-cloud@latest/billing/using-the-new-billing-platform/automating-usage-reporting), which provides structured cost data for GitHub Actions, such as build minutes by user and repo, as well as the associated infrastructure used to perform the build.
You can see cost and usage, such as per-repository billing for Actions, Copilot UserMonths, Copilot AI Credits with the `AICredits` usage unit, and GigabyteHours of Shared Storage. To allocate the infrastructure costs for your self-hosted runners, you can create a Cost Report that includes both GitHub costs and the related EC2 or EKS costs, based on tags or labels.
GitHub started moving Copilot plans to usage-based billing on June 1, 2026. Vantage ingests Copilot AI Credits through the existing GitHub integration, and these usage records are available under the GitHub Copilot AI Credits category in Cost Reports. See GitHub's [usage-based billing announcement](https://github.blog/news-insights/company-news/github-copilot-is-moving-to-usage-based-billing/) for details.
As noted in the [GitHub documentation](https://docs.github.com/en/rest/billing?apiVersion=2022-11-28), access to the GitHub Enhanced Billing APIs requires `"Administration" organization permissions (read)`.
Vantage has configured an IP address allow list for the Vantage GitHub app. If your organization or enterprise has IP address allow lists enabled, you can selectively inherit the App's IP allow list when installing it, which will automatically add Vantage's IP addresses to your organization's allow list. Alternatively, you can manually add the IP addresses below to your organization's allowlist.
## Connect Your GitHub Account
Follow the steps in this section to install the Billing - vantage-sh GitHub application and ingest GitHub costs into Vantage.
### Prerequisites
You must be a GitHub **Organization Owner** to install the Billing - vantage-sh GitHub application. You must also have been migrated to the GitHub Enhanced Billing API. The new GitHub Enhanced Billing platform is available to:
* All enterprise accounts, and their organizations, created after June 2, 2024
* Enterprises that participated in the public preview program
* Enterprises that have received a notice 30 days before their migration (see the [GitHub blog](https://github.blog/changelog/2024-09-24-enhanced-billing-platform-for-enterprises/))
To validate that you have been moved to the Enhanced Billing Platform:
* Navigate to `https://github.com/enterprises/{name}/billing` (for Enterprise accounts) or `https://github.com/organizations/{name}/billing` (for Organization accounts), and you should see the new billing platform.
* You can also navigate to `https://github.com/enterprises/{name}/settings/billing` (for Enterprise accounts) or `https://github.com/organizations/{name}/settings/billing` (for Organization accounts). You should see a warning at the top of the page, indicating that the page has been deprecated.

* You must have a Vantage **Organization Owner** or **Integration Owner** role to add or remove this integration. See the [Role-Based Access Control](/rbac) documentation for details.
* [Create a free Vantage account](https://console.vantage.sh/signup), then follow the steps below to connect to GitHub.
### Create the Connection
To complete the integration, you will add the application to your organization and set up the Vantage integration in the console.
From the top navigation in Vantage, click **Settings**.
On the left navigation, select **Integrations** and select **GitHub**.
The GitHub integrations page is displayed. Ensure you are on the **Connect** tab.
At the bottom of the page, click **Connect GitHub Account**.
You will be asked to authorize the app for your organization.

Click **Authorize Billing - vantage-sh**. You will be brought to a screen where you can select your organization for the integration. Select your organization to complete the integration.
If you are part of an Enterprise, you will have to select multiple organizations.

After completing the OAuth flow, you will see the status of your integration change to **Importing** within the Vantage console. This status indicates that Vantage is actively importing your GitHub cost data. See the [Integration Status](/vantage_account#integration-status) documentation for details on integration statuses.
When following the integration setup, Vantage will request 180 days of historical usage data from GitHub. The cost and usage data ingested from the [GitHub Enhanced Billing APIs](https://docs.github.com/en/rest/billing) starts the day that GitHub migrates you to this new standard. Any historical data prior to this is accessible only via the [previous form](/connecting_github#previous-integration-pre-march-2025) of the GitHub integration. As soon as costs are processed, they will be available on your **All Resources** Cost Report. If you decide to remove your GitHub integration from Vantage, all costs associated with your connected GitHub Organizations will be removed from the Vantage console.
### Next Steps - Manage Workspace Access
Once the import is complete and the integration status changes to **Stable**, you can select which workspaces this integration is associated with. See the [Workspaces](/workspaces#manage-workspace-provider-integrations) documentation for information.
### Previous Integration (Pre-March 2025)
Any historical data you previously ingested into Vantage (prior to March 2025) is accessible only via the previous form of the GitHub integration. Once GitHub migrates you to the Enhanced Billing API, the previous Vantage GitHub integration will stop receiving updated data, as Vantage is no longer able to retrieve the CSV that was being used for cost and usage data.
You can leave your previous integration connected to Vantage for historical billing data if you want to retain this information. On the integration settings page in Vantage, any new integrations have the `API` label displayed next to their name in the list.

## Data Refresh
See the [provider data refresh documentation](/provider_data_refresh) for information on when data for each provider refreshes in Vantage.
## GitHub Reporting Dimensions
On GitHub [Cost Reports](/cost_reports/), you can filter costs across several dimensions:
* Organization (e.g., Organization Name)
* Service (e.g., Actions, Copilot, Packages)
* Category (e.g., Actions)
* Subcategory (e.g., Actions Linux)
* Resource (e.g., Repository Name)
* Charge Type (e.g., Usage)
* Tags: Includes [Virtual Tags](/tagging) created in Vantage for this provider. The following tags are also available for filtering and grouping:
* `owner`: The organization name, allowing you to filter and group costs by organization.
* `repo`: The repository name when present in the source data, allowing you to filter and group costs by repository.
# Grafana Cloud
Source: https://docs.vantage.sh/connecting_grafana
Learn how to integrate Vantage with Grafana Cloud.
Vantage connects to your Grafana Cloud account via a customer-generated read-only token attached to a cloud access policy, which allows Vantage to ingest Grafana Cloud usage costs. Vantage displays Grafana Cloud costs and associated [usage metrics](/usage_based_reporting), like GB of Traces, Log Retention GB-Month, or number of Incident Response and Management Users, directly in line with other infrastructure costs.
You can integrate multiple Grafana Cloud integrations by providing read-only tokens for multiple organizations.
## Connect Your Grafana Cloud Account
### Prerequisites
* You must have a Vantage **Organization Owner** or **Integration Owner** role to add or remove this integration. See the [Role-Based Access Control](/rbac) documentation for details.
* [Create a free Vantage account](https://console.vantage.sh/signup), then follow the steps below to integrate Grafana Cloud costs.
Vantage cannot perform writes to your Grafana Cloud organization. Vantage is only able to see metadata associated with your usage.
### Create the Connection
Navigate to [grafana.com](https://grafana.com/) and log in to your account.
On the left, under **SECURITY**, select **Access Policies**.

At the top of the page, click **Create access policy**.
For **Display name** and **Name**, enter *vantage*.
For **Realms**, select **all stacks**, or select individual stacks if you want only certain stacks associated with the integration.
Under **Scopes**, add the `billing-metrics:read` and `orgs:read` scopes. (You may need to search for these scopes in the **Add scope** search box below the checklist.)

If you have any IP restrictions on this instance, ensure you allow the following IP addresses for Vantage:
Click **Create**.
The new access policy is created. On the access policy tile, click **Add token**.
Give the token a name and select an expiration date. If the key expires, you will need to update your integration in Vantage with a new API token.
Click **Create**, then copy the new token.
From the top navigation in Vantage, click **Settings**.
On the left navigation, select **Integrations** and select **Grafana Cloud**.
The Grafana Cloud integrations page is displayed. Ensure you are on the **Connect** tab.
At the bottom of the page, click **Add API Key** and paste your newly generated token.
For **Organization slug**, enter the organization name that appears in your Grafana organization URL (e.g., in `https://grafana.com/orgs/vantagesh`, enter only `vantagesh`).
Click **Connect Account**.
After clicking **Connect Account**, you will see the status of your integration change to **Importing** within the Vantage console. This status indicates that Vantage is actively importing your Grafana Cloud cost data. See the [Integration Status](/vantage_account#integration-status) documentation for details on integration statuses.
As soon as costs are processed, they will be available on your All Resources Cost Report. If you decide to remove your Grafana Cloud integration from Vantage, all costs associated with your Grafana Cloud API key will be removed from the Vantage console.
### Next Steps - Manage Workspace Access
Once the import is complete and the integration status changes to **Stable**, you can select which workspaces this integration is associated with. See the [Workspaces](/workspaces#manage-workspace-provider-integrations) documentation for information.
## Data Refresh
See the [provider data refresh documentation](/provider_data_refresh) for information on when data for each provider refreshes in Vantage.
## Grafana Costs on Cost Reports
Due to Grafana’s billing process, billing data for the current month becomes available only on the 1st of the following month. Grafana Cloud costs are not amortized across the month; therefore, it is recommended that you view Grafana costs and usage using the **Monthly** date binning.

### Grafana Cloud Billed Through AWS Marketplace
If you purchase your Grafana Cloud subscription through the AWS Marketplace, the same usage can appear in Vantage from two sources:
* The direct Grafana Cloud integration described above.
* Your AWS Cost and Usage Report (CUR), where the Grafana Cloud subscription appears as Marketplace charges on the AWS provider.
Vantage does not automatically deduplicate costs across providers, so leaving both sources unfiltered will double-count your Grafana spend on the All Resources Cost Report and any cross-provider Cost Reports.
To avoid double-counting, exclude AWS Marketplace charges that correspond to your Grafana Cloud subscription from your AWS-scoped reports.
## Grafana Reporting Dimensions
On Grafana [Cost Reports](/cost_reports), you can filter across several dimensions:
* Service (e.g., Metrics, Traces, Logs)
* Category (Specific usage category, like Hosted Metrics Usage or Hosted Logs Usage)
* Organization
* Account ID (Grafana stack)
* Tags ([Virtual Tags](/tagging) created in Vantage)
* Charge Type (e.g., usage)
# Kubernetes
Source: https://docs.vantage.sh/connecting_kubernetes
Learn how to integrate Vantage with Kubernetes.
Vantage allows you to see in-cluster costs for Kubernetes clusters, including seeing costs by Container, Service, Namespace and Label. Vantage supports any type of Kubernetes deployment (e.g., EKS, GKE, self-managed). This allows teams to easily understand how their shared clusters are being utilized and how to account for cluster costs across teams and applications.
The [Vantage Kubernetes agent](/kubernetes_agent) is the recommended integration point for ingesting Kubernetes costs into Vantage. Note that a primary provider (e.g., AWS, Azure, GCP, OKE, or on-premises) is required to connect Kubernetes costs.
## How the Integration Works
Vantage looks at pod lifecycle data and the underlying nodes that pods run on. By joining the lifecycle data of each pod (along with the greater of either the reserved or actual CPU/memory prescribed) with the specific rate information of the underlying node, Vantage allocates subcategories of the node (vCPU, memory, GPU, storage, etc.) to the pod. The lifecycle of the EC2 instance is also automatically determined (On-Demand, Spot, Reserved, Savings Plans, EDP, etc.). This allows you to see costs by the following dimensions:
* By container name
* By Kubernetes service
* By Kubernetes namespace
* By Kubernetes label
Vantage automatically profiles your clusters for all existing Services, Namespaces, and Labels to be available for you in the Vantage console as dimensions for filtering and reporting.
## Enable Kubernetes Costs
You must have a Vantage **Organization Owner** or **Integration Owner** role to add or remove this integration. See the [Role-Based Access Control](/rbac) documentation for details.
To get started, follow the instructions for setting up the [Vantage Kubernetes agent](/kubernetes_agent).
After setting up the Kubernetes agent, you will see the status of your integration change to **Importing** within the Vantage console. This status indicates that Vantage is actively importing your Kubernetes cost data. See the [Integration Status](/vantage_account#integration-status) documentation for details on integration statuses.
## Manage Workspace Access
Once the import is complete and the integration status changes to **Stable**, you can select which workspaces this integration is associated with. See the [Workspaces](/workspaces#manage-workspace-provider-integrations) documentation for information.
## Data Refresh
See the [provider data refresh documentation](/provider_data_refresh) for information on when data for each provider refreshes in Vantage.
## Reporting Dimensions
On Kubernetes [Cost Reports](/cost_reports), you can filter across several dimensions:
* Account (associated account name)
* Tag (includes Kubernetes grouping names and values, for example, namespace, and [virtual tags](/tagging) created in Vantage for this provider)
* Region (e.g., Westus2)
* Charge Type (e.g., Usage)
* Cluster (cluster name)
Node labels collected by the agent are also available as tags in the format `node:xyz`. This includes NVIDIA GPU labels, such as `node:nvidia.com/mig.strategy` and `node:nvidia.com/gpu.count` on [MIG-partitioned nodes](/kubernetes#nvidia-multi-instance-gpu-mig-accounting).
## Troubleshooting
If you've installed the Vantage Kubernetes agent but costs are not yet visible in Cost Reports, check the following:
| Symptom | Possible Cause | Resolution |
| - | - | - |
| No Kubernetes costs appear | Agent recently installed | Kubernetes cost data is refreshed once daily. Allow up to 24 hours for initial data to appear. |
| Costs appear but are delayed | Cloud provider data lag | Kubernetes costs depend on the underlying infrastructure provider (AWS, Azure, GCP) making their billing data available. A one-day delay in the cloud provider's Cost and Usage Report causes a similar delay in Kubernetes costs. |
| Costs appear for some clusters but not others | Agent not installed on all clusters | Verify the agent is deployed on each cluster you want to monitor. Check agent status on the [Integrations](https://console.vantage.sh/settings/integrations) page. |
| Integration shows Error or Warning state | Agent connectivity or permissions issue | Verify that the agent pod is running (`kubectl get pods -n vantage`) and can reach the Vantage API. See the [Kubernetes agent](/kubernetes_agent) documentation for setup requirements. |
| Expected labels or namespaces are missing | Labels not yet processed or not applied at the pod level | New labels are picked up as part of daily cost processing and can take up to 24 hours to appear. Vantage uses pod-level labels as the primary source (along with namespace labels, node labels, PVC labels, and annotations). Labels applied only to higher-level objects like Deployments or StatefulSets without propagating to pods are not captured. |
A primary provider integration (e.g., AWS, Azure, GCP, OKE, or on-premises) must be connected before Kubernetes costs can be allocated. If you have not yet connected your cloud provider, see the [Getting Started](/getting_started) documentation.
# Linode from Akamai Connected Cloud
Source: https://docs.vantage.sh/connecting_linode
Learn how to integrate Vantage with Linode.
Vantage uses a read-only API key to ingest Linode costs and discounts as invoices become available. Vantage also uses service-specific APIs to enrich cost data with additional resource-specific metadata.
Vantage cannot and will not perform writes to your Linode account and can see only metadata associated with your usage.
With the Vantage–Linode integration, you can track costs for Kubernetes Clusters, Linode Instances, Node Balancers, Object Storage, Images, and Storage Volumes.
## Linode Kubernetes Clusters
You can install the Vantage Kubernetes Agent on Linode Kubernetes Clusters to see detailed insights into real-time cluster resource utilization, efficiency, and cost allocation. See the [agent documentation](/kubernetes_agent) for details on how to set up the agent.
## Connect Your Linode Account
### Prerequisites
* You must have a Vantage **Organization Owner** or **Integration Owner** role to add or remove this integration. See the [Role-Based Access Control](/rbac) documentation for details.
* [Create a free Vantage account](https://console.vantage.sh/signup), then follow the steps below to connect to Linode.
You can create multiple Linode integrations by providing read-only API keys for multiple accounts.
If your organization restricts access to the provider by IP address, add the following Vantage IP addresses to your provider's allowlist:
### Create the Connection
These instructions are a condensed version of the instructions on Linode’s [documentation](https://techdocs.akamai.com/cloud-computing/docs/manage-personal-access-tokens).
Log in to [Akamai Cloud Manager](https://cloud.linode.com/).
Navigate to your Linode profile's [API token page](https://cloud.linode.com/profile/tokens). You can also access this page by selecting your user profile at the top. Then, under **My Profile**, select **API Tokens**.

Click **Create Personal Access Token**.
Enter the following information:
* For **Label**, enter something that identifies this token, such as *Vantage Integration*.
* For **Expiry**, select **Never**.
* For **Access**, select **Read Only** for all items except VPCs. For **VPCs**, select **No Access**.

Click **Create Token**. Your Personal Access Token is displayed once. Copy this token to use in your Vantage integration.
From the top navigation in **Vantage**, click **Settings**.
On the left navigation, select **Integrations** and select **Linode**.
The Linode integrations page is displayed. Ensure you are on the **Connect** tab.
At the bottom of the page, click **Add API Key**.
For **API key**, add your previously generated Personal Access Token.
For **Description**, you can use your name or any other descriptor here to identify that you've added this integration. Use this description to differentiate this Linode account from others you may add.
Click **Connect Account**.
After clicking **Connect Account**, you will see the status of your integration change to **Importing** within the Vantage console. This status indicates that Vantage is actively importing your Linode cost data. See the [Integration Status](/vantage_account#integration-status) documentation for details on integration statuses.
As soon as costs are processed, they will be available on your All Resources Cost Report. If you decide to remove your Linode integration from Vantage, all costs associated with your Linode API token will be removed from the Vantage console.
### Next Steps - Manage Workspace Access
Once the import is complete and the integration status changes to **Stable**, you can select which workspaces this integration is associated with. See the [Workspaces](/workspaces#manage-workspace-provider-integrations) documentation for information.
## Data Refresh
See the [provider data refresh documentation](/provider_data_refresh) for information on when data for each provider refreshes in Vantage.
## Linode Reporting Dimensions
On Linode [Cost Reports](/cost_reports/), you can filter costs across several dimensions:
* Category (e.g., Linode Instance - Compute)
* Subcategory (e.g., Linode Instance - Dedicated 16GB)
* Tag ([Virtual Tags](/tagging) created in Vantage for this provider)
* Resource (e.g., specific resource names)
* Charge Type (e.g., Usage or Discount)
* Service (e.g., Node Balancer)
You can also view credits, discounts, refunds, and taxes for Linode costs in Cost Reports.
At the top of any Linode Cost Report, click **Settings**.
Then, toggle on/off these options.
## Active Resources
The following Linode resources are synced as active resources and available in [Resource Reports](/active_resources).
* Linode Instances
* Linode Kubernetes Clusters
* Volumes
* Object Storage
* Images
* NodeBalancers
# Modal
Source: https://docs.vantage.sh/connecting_modal
Learn how to integrate Vantage with Modal to track serverless compute costs.
Vantage integrates with your Modal account using a token ID and token secret to ingest cost data through Modal's [billing report](https://modal.com/docs/reference/cli/billing). Vantage retrieves workspace billing data broken down by Modal object (for example, Apps), environment, compute resource (such as CPU, Memory, or a GPU type), and any tags associated with those objects.
## Modal Permissions
Vantage uses your Modal token ID and token secret to read workspace billing data only. Vantage cannot deploy functions, trigger executions, or perform any actions that incur costs in your Modal account.
It's best practice to create a dedicated Modal token for Vantage and rotate it according to your organization's security policy.
## Connect Your Modal Account
### Prerequisites
* You must have a Vantage **Organization Owner** or **Integration Owner** role to add or remove this integration. See the [Role-Based Access Control](/rbac) documentation for details.
* You need access to a Modal workspace that can create API tokens.
* [Create a free Vantage account](https://console.vantage.sh/signup), then follow the steps below to integrate Modal costs.
If your organization restricts access to the provider by IP address, add the following Vantage IP addresses to your provider's allowlist:
### Create the Connection
Navigate to your [Modal token settings](https://modal.com/settings/tokens).
Create a new token, then copy the generated **Token ID** and **Token Secret**.
Modal only shows the token secret once. Save it securely before closing the dialog.
From the top navigation in Vantage, click **Settings**.
On the left navigation, select **Integrations** > **Modal**.
The Modal integrations page is displayed. Ensure you are on the **Connect** tab.
Click **Add Token** and complete the integration form:
* **Token ID**: Paste the Modal token ID.
* **Token Secret**: Paste the Modal token secret.
* **Description**: Enter a label to identify this Modal workspace in Vantage. This value is used as the **Billing Account** dimension in Cost Report filters.
Click **Connect Account**.
After clicking **Connect Account**, you will see the status of your integration change to **Importing** within the Vantage console. This status indicates that Vantage is actively importing your Modal cost data. Vantage backfills up to six months of historical cost data upon initial connection. Ongoing retention follows your Vantage data retention settings. See the [Integration Status](/vantage_account#integration-status) documentation for details on integration statuses. You can connect multiple Modal workspaces, each with its own token, as separate integrations in Vantage.
As soon as costs are processed, they will be available on your **All Resources** Cost Report. If you decide to remove your Modal integration from Vantage, all costs associated with that Modal token will be removed from the Vantage console.
### Next Steps - Manage Workspace Access
Once the import is complete and the integration status changes to **Stable**, you can select which workspaces this integration is associated with. See the [Workspaces](/workspaces#manage-workspace-provider-integrations) documentation for information.
## Data Refresh
See the [provider data refresh documentation](/provider_data_refresh) for information on when data for each provider refreshes in Vantage. Modal data refreshes once daily.
## Modal Reporting Dimensions
On Modal [Cost Reports](/cost_reports), you can filter and group across several dimensions:
* Billing Account (the description you enter when connecting the integration; use **Billing Account** for filtering and grouping)
* Account (the Modal environment name, such as `main`)
* Service (for example, `App`)
* Category (the compute resource that generated the cost, such as `CPU`, `Memory`, or a GPU type, like `H100`, `B200`, etc.)
* Resource (the Modal App; shown as the App name while the App is active, or the Modal object ID such as `ap-...` once the App is no longer active)
* Charge Type (Usage)
In addition, Modal costs include the following tags, available for filtering and grouping alongside any [Virtual Tags](/tagging) you create:
| Tag | Description |
| - | - |
| `modal:description` | Created by Vantage from the Modal object description in the billing report (for example, the App name) |
| `` | Any tags you have applied to the Modal object in your workspace, passed through with their original key names (for example, `team`) |
## Active Resources
Vantage syncs your Modal Apps as [Active Resources](/active_resources), so you can view currently active Apps and their costs in Resource Reports. Each Modal App resource includes metadata such as its name, environment, and status, along with the tags applied to it in Modal. Active resources are synced at least once every 24 hours.
In Cost Reports, the **Resource** for a Modal App is displayed as the App's name while the App is active. Apps that are no longer active aren't synced as Active Resources, so their costs show the raw Modal object ID (such as `ap-...`) instead.
# MongoDB Atlas
Source: https://docs.vantage.sh/connecting_mongodb-atlas
Learn how to integrate Vantage with MongoDB Atlas.
Vantage integrates with your MongoDB account using the [Invoices API](https://www.mongodb.com/docs/atlas/reference/api-resources-spec/#tag/Invoices). To see [Active Resources](/active_resources) for your MongoDB Atlas account, Vantage uses the [Clusters API](https://www.mongodb.com/docs/atlas/reference/api-resources-spec/#tag/Clusters) and the [Projects API](https://www.mongodb.com/docs/atlas/reference/api-resources-spec/#tag/Projects).
## Connect Your MongoDB Atlas Account
### Prerequisites
* To create an API key for Vantage to ingest costs, you must be an **Organization Owner** inside the MongoDB Atlas console.
* To add the API key to relevant projects to use Active Resource inventories inside Vantage, you must be a **Project Owner** in the MongoDB Atlas console.
For more information on user roles in MongoDB Atlas, see the [MongoDB Atlas documentation](https://www.mongodb.com/docs/atlas/reference/user-roles/).
* You must have a Vantage **Organization Owner** or **Integration Owner** role to add or remove this integration. See the [Role-Based Access Control](/rbac) documentation for details.
* [Create a free Vantage account](https://console.vantage.sh/signup), then follow the steps below to integrate MongoDB Atlas costs.
### Step 1 - Review the Vantage Integration Page
Navigate to the [MongoDB Atlas Settings](https://console.vantage.sh/settings/mongo) page in the Vantage console. Then, click **Add API Key**.
You will need to add your **Organization ID**, **Public API key**, and **Private API key**. Detailed steps for obtaining each of these items are provided below. Leave this tab open so you can go back and populate these fields as you obtain each value.

### Step 2 - Obtain Organization ID
In a new browser tab, navigate to the [MongoDB Atlas console](https://account.mongodb.com/account/login).
At the top of the page, click the **Organization** dropdown menu, and select your organization.
On the left menu, click **Organization Settings**.
Your **Organization ID** will be displayed at the top. Copy the **Organization ID**. Then, go back to your Vantage browser tab and paste your ID into the **Organization ID** field.

### Step 3 - Create an Organization API Key
Next, you'll create an API key and grant it read-only permissions to your invoices and, optionally, to cluster-level cost data.
From the left navigation menu, click **Applications**.
Select the **API Keys** tab, then click **Create API Key** (or click **Add new** > **API Key** at the top if you already have created one).

On the **Create API Key** screen, configure the following details:
* For **Description**, enter a name, like *Vantage Integration*.
* For **Organization Permissions**, select **Organization Billing Viewer** and **Organization Read Only**.

Click **Next**. Your public and private keys are displayed. Copy the keys and paste them into the **Public API key** and **Private API key** fields in Vantage.
If your organization requires an IP Access List for access control, you will need to add each of the following IPs to the **API Access List** section. Add each IP address individually:

At the bottom, click **Done**.
If you want to have Vantage ingest per-cluster resource data from MongoDB Atlas, then proceed to the next section. Otherwise, back in the Vantage console, click **Add Key**.
### Step 4 - Grant Project Access for Active Resources
On the left navigation menu, under **Identity & Access**, select **All Projects** to see your list of Atlas projects. Select your project from the list.

On the left menu, select **Project Identity & Access**.
Click **Invite to Project**.

Search for and select the Vantage Integration API key to add it to the project.
Grant the Vantage Integration API key **Project Read Only** access. Then, click **Invite to Project**. Repeat this process for any other projects where you want to see resource-level costs.

Back in the Vantage console, click **Add Key**.
After clicking **Add Key**, your MongoDB Atlas integration status should automatically update to **Importing** within the Vantage console. This status indicates that Vantage is actively importing your MongoDB Atlas cost data. If you've successfully granted project access for active resources, your Active Resources view will begin populating with cost data. See the [Integration Status](/vantage_account#integration-status) documentation for details on integration statuses.
### Next Steps - Manage Workspace Access
Once the import is complete and the integration status changes to **Stable**, you can select which workspaces this integration is associated with. See the [Workspaces](/workspaces#manage-workspace-provider-integrations) documentation for information.
## Set Custom Rates
If you have negotiated pricing with MongoDB, set a unit price multiplier to adjust the MongoDB Atlas costs shown in Vantage. Vantage multiplies MongoDB Atlas costs by the rate you enter. The default rate is `1.0` (no adjustment). For example, a rate of `0.8` reflects a 20% discount.
Navigate to the [MongoDB Atlas Settings](https://console.vantage.sh/settings/mongo) page and select your integration.
In the **Custom rates** section, enter a value in the **Unit price multiplier** field. To apply a rate only to a specific period, select a **Date range**. Leave the date range blank for a rate that applies to all billing periods.
If your pricing changed over time, click **Add rate** to add another row with its own rate and date range.
Click **Save**. Cost Reports are updated shortly after saving.
When you configure multiple rates:
* Each rate must be greater than 0, and each start date must be on or before its end date.
* Date ranges can't overlap.
* A rate without a date range can't be combined with other rates.
* Only one rate can have an open start date, and only one rate can have an open end date.
## Data Refresh
See the [provider data refresh documentation](/provider_data_refresh) for information on when data for each provider refreshes in Vantage.
## MongoDB Atlas Reporting Dimensions
On MongoDB Atlas [Cost Reports](/cost_reports), you can filter across several dimensions:
* Project (project name when available, otherwise project ID)
* Category (Atlas Cluster - Atlas Instance M2)
* Tag (includes MongoDB tags and [virtual tags](/tagging) created in Vantage for this provider)
* Provider Tag (`mongo:group_name`, the Atlas project name from invoice data)
* Resource (service resource ID)
* Charge Type (e.g., Usage)
* Organization (organization name)
* Service (e.g., REALM)
Credits are not displayed for MongoDB Atlas costs in Vantage. The MongoDB Atlas provider API does not make credit information available for retrieval.
## Active Resources
MongoDB Atlas clusters are synced as active resources and available in [resource reports](/active_resources).
# New Relic
Source: https://docs.vantage.sh/connecting_new_relic
Learn how to integrate Vantage with New Relic.
Vantage integrates with your New Relic account using [NerdGraph](https://docs.newrelic.com/docs/apis/nerdgraph/get-started/introduction-new-relic-nerdgraph/), New Relic's GraphQL API. It accesses the API using an API token.
## Connect Your New Relic Account
### Prerequisites
* You must have a Vantage **Organization Owner** or **Integration Owner** role to add or remove this integration. See the [Role-Based Access Control](/rbac) documentation for details.
* [Create a free Vantage account](https://console.vantage.sh/signup), then follow the steps below to generate a New Relic API token and obtain your Account ID.
If your organization restricts access to the provider by IP address, add the following Vantage IP addresses to your provider's allowlist:
Log in to your New Relic account. Then, follow the instructions in the [New Relic documentation](https://docs.newrelic.com/docs/apis/intro-apis/new-relic-api-keys/#overview-keys) to create a **User key**.
Once you've created a new **User key**, you will see the key in your **API keys** list. Click the ellipses next to the key in the list and select **Copy key**. You will need this value for completing the integration with Vantage.
To obtain your Account ID, follow the instructions provided in the [New Relic documentation](https://docs.newrelic.com/docs/accounts/accounts-billing/account-structure/account-id/). Copy the value for your Account ID.
### Create the Connection
Navigate to the [New Relic Settings](https://console.vantage.sh/settings/new_relic) page in the Vantage console.
Click **Add Connection**.
Paste your **New Relic Account ID** and **New Relic API Key** you previously obtained into the provided fields.
Complete the additional fields based on the specific pricing for your account. This can include the per-gigabyte ingestion rate, amount of free ingestion per month, core and full platform user pricing, and any free user seats. For more information on New Relic pricing, see the [New Relic documentation](https://docs.newrelic.com/docs/accounts/accounts-billing/new-relic-one-pricing-billing/new-relic-one-pricing-billing/).
Click **Connect Account**.
After clicking **Connect Account**, you will see the status of your integration change to **Importing** within the Vantage console. This status indicates that Vantage is actively importing your New Relic cost data. Vantage will automatically begin ingesting and visualizing your costs. See the [Integration Status](/vantage_account#integration-status) documentation for details on integration statuses.
### Next Steps - Manage Workspace Access
Once the import is complete and the integration status changes to **Stable**, you can select which workspaces this integration is associated with. See the [Workspaces](/workspaces#manage-workspace-provider-integrations) documentation for information.
## Data Refresh
See the [provider data refresh documentation](/provider_data_refresh) for information on when data for each provider refreshes in Vantage.
## New Relic Reporting Dimensions
On New Relic [Cost Reports](/cost_reports), you can filter across several dimensions:
* Account (account name)
* Category (e.g., New Relic Users - CoreUsers)
* Tags: Includes [Virtual Tags](/tagging) created in Vantage for this provider. The following provider tag is automatically created by Vantage from New Relic data and is available for filtering and grouping:
* `newrelic.source`: The source of the cost data when present in the source data, allowing you to filter and group costs by source.
* Charge Type (e.g., Usage)
* Service (e.g., New Relic Ingestion)
# OpenAI
Source: https://docs.vantage.sh/connecting_openai
Connect OpenAI to Vantage to track cost and usage from both the OpenAI Platform and OpenAI Codex.
Vantage ingests OpenAI cost and usage data from two independent data sources. You can connect either source on its own or connect both for a complete view of your OpenAI spend:
* **OpenAI Platform**: programmatic OpenAI usage accessed through the [OpenAI Platform Costs API](https://platform.openai.com/docs/api-reference/usage/costs), broken down by operation (e.g., Chat and Completions, Images, or Embeddings) and model (e.g., gpt-4o). Connected with a read-only **Admin API key**.
* **OpenAI Codex**: Codex usage from a ChatGPT workspace, broken down by Codex client (e.g., Codex CLI, Codex Web, or Codex VS Code), model, and token type. Connected with a **Codex Analytics API key** and workspace ID.
[Usage data](/usage_based_reporting) is available for both data sources, measured in tokens. Vantage tags every row with an `openai:billing_source` value (`admin` for OpenAI Platform or `codex_analytics` for OpenAI Codex), so you can filter, group, and allocate costs by data source. See [OpenAI Reporting Dimensions](#openai-reporting-dimensions) for details.
Codex Analytics is available only for **OpenAI Enterprise** customers with a ChatGPT Enterprise workspace. The OpenAI Platform data source has no such requirement.
To attribute OpenAI spend to teams, users, applications, and features by your own per-request dimensions, see [Custom LLM Enrichment](/custom_llm_enrichment), which joins per-request token telemetry you deliver to S3 with your OpenAI Platform costs.
## OpenAI Data Sources
The table below summarizes the two data sources, what each captures, and what you need to connect them. In Cost Reports, you can filter by the `openai:billing_source` tag to see which data source is associated with a given cost row.
| Data Source | What It Captures | Key | Requirement | `openai:billing_source` |
| - | - | - | - | - |
| OpenAI Platform | API cost and usage by operation, model, project, and API key | Admin API key (`sk-admin-`) | OpenAI Organization Owner | `admin` |
| OpenAI Codex | Codex cost and usage by client, model, token type, speed, and user | Codex Analytics API key (scoped to `codex.enterprise.analytics.read`) and workspace ID | OpenAI Enterprise account with a ChatGPT Enterprise workspace that has Codex Analytics API access | `codex_analytics` |
The two data sources fill the shared dimensions differently. On OpenAI Platform rows, **Account** is the project and **Resource** is the API key ID. On OpenAI Codex rows, **Billing Account (Organization)** is the workspace ID, **Account** is the account name you set at connect, and **Resource** is the user's email. **Service** is an operation on Platform rows and a Codex client on Codex rows. Filter on the `openai:billing_source` tag to keep a report focused on one data source.
This integration covers OpenAI costs billed directly by OpenAI. OpenAI models accessed through **Azure OpenAI** are captured under your [Azure](/connecting_azure) cost integration instead.
## OpenAI Permissions
Vantage cannot perform cost-incurring actions and only ever reads cost and usage data from OpenAI.
### OpenAI Platform Permissions
OpenAI requires a read-only Admin API key to access the [Costs API endpoint](https://platform.openai.com/docs/api-reference/usage/costs). The Costs endpoint is not available to non-admin API keys. Vantage only reads from this endpoint and never performs any action that incurs costs. You must be an *Organization Owner* in your OpenAI organization to create an Admin key.
### OpenAI Codex Permissions
Codex Analytics is available only for **OpenAI Enterprise** customers with a ChatGPT Enterprise workspace. OpenAI requires a dedicated Codex Analytics API key scoped to `codex.enterprise.analytics.read` to access the [Codex Analytics API](https://developers.openai.com/codex/enterprise/analytics-api). The key's Platform organization must match the organization associated with the ChatGPT workspace you connect. Vantage reads only aggregated Codex analytics data for that workspace; it does not ingest prompts, generated code, or raw audit-event content, and it cannot run Codex tasks or change workspace settings.
Vantage stores only usage metadata (e.g., token consumption). The imported daily aggregates can include user email and user ID, which Vantage uses for Resource and tag-based reporting.
## Connect Your OpenAI Account
You can connect the OpenAI Platform, OpenAI Codex, or both. Each data source has its own key and its own connection flow in Vantage. Both appear under the **OpenAI** provider in Cost Reports.
### Prerequisites
* You must have a Vantage **Organization Owner** or **Integration Owner** role to add or remove this integration. See the [Role-Based Access Control](/rbac) documentation for details.
* For the **OpenAI Platform**, you must be an *Organization Owner* in your OpenAI organization to create a read-only Admin key.
* For **OpenAI Codex**, you must be an **OpenAI Enterprise** customer with a ChatGPT Enterprise workspace that has Codex Analytics API access, and be able to provision a dedicated Codex Analytics API key whose Platform organization matches the organization associated with the workspace.
* [Create a free Vantage account](https://console.vantage.sh/signup), then follow the steps below to integrate OpenAI costs.
If your organization restricts access to the provider by IP address, add the following Vantage IP addresses to your provider's allowlist:
### Connect the OpenAI Platform
Use this data source to track programmatic OpenAI usage from the Platform Costs API.
Navigate to the [Admin Keys](https://platform.openai.com/settings/organization/admin-keys) page of the OpenAI console, and log in using your company email.
At the top, click **+ Create new Admin key**.
For **Name**, add an identifiable name, like *Vantage Integration*.

For **Permissions**, select **Read only**.
Click **Create admin key** and copy the generated key. Admin keys start with `sk-admin-`.
Navigate to the **Connect** tab of the [OpenAI Settings](https://console.vantage.sh/settings/open_ai?connect=true) page in the Vantage console. In the **OpenAI Platform** section, click **Add Admin API Key**.
The **New OpenAI Account** modal is displayed. For **API key**, paste your previously generated Admin Key. For **Description**, enter any descriptor to identify that you've added this integration, such as your name.

Click **Connect Account**.
### Connect OpenAI Codex
Use this data source to track Codex usage across clients like Codex CLI, Codex Web, and Codex VS Code. You connect a single ChatGPT workspace per integration; connect multiple workspaces as separate integrations if needed.
Codex Analytics is available only for **OpenAI Enterprise** customers. Confirm your organization is on OpenAI Enterprise before you begin; Codex Analytics is not available for non-Enterprise plans.
Log in to the [OpenAI Admin Console](https://admin.openai.com/), then go to **Credentials** > **Admin keys**.
Click **Create new admin key**. Select the ChatGPT workspace you want Vantage to report on.
The key's Platform organization must match the organization associated with the ChatGPT workspace you plan to connect.
Enter a **Name**, then set **Permissions** to **Restricted** or **Custom**.
Enable the **Codex Analytics: Read** (the `codex.enterprise.analytics.read` scope).
Click **Create admin key**, then copy the key.
It's best practice to use a dedicated key for Vantage, store it in your organization's secret-management system, and rotate it according to your security policy.
From the **Workspace details** in the [ChatGPT Admin Console](https://chatgpt.com/admin), copy your **Workspace ID**.
Navigate to the **Connect** tab of the [OpenAI Settings](https://console.vantage.sh/settings/open_ai?connect=true) page in the Vantage console. In the **OpenAI Codex** section, click **Add Analytics API Key**.
The **New OpenAI Codex Account** modal is displayed. Paste your **Codex Analytics API Key**, enter your **Codex Workspace ID**, and enter an **Account Name** to label this connection in Vantage.
The Analytics API does not expose an account name, so the **Account Name** you enter is used to identify this connection in the Vantage UI and as the **Account** dimension on Codex cost rows.
Click **Connect Account**.
After you connect a data source, the integration status changes to **Importing** within the Vantage console, indicating that Vantage is actively importing your OpenAI cost data. On initial connection, Vantage backfills OpenAI Platform costs and imports up to the most recent 90 days of Codex data available from the Analytics API. See the [Integration Status](/vantage_account#integration-status) documentation for details on integration statuses.
As soon as costs are processed, they will be available on your **All Resources** Cost Report. If you remove an OpenAI integration from Vantage, all costs associated with that OpenAI key are removed from the Vantage console.
### Next Steps - Manage Workspace Access
Once the import is complete and the integration status changes to **Stable**, you can select which workspaces each integration is associated with. See the [Workspaces](/workspaces#manage-workspace-provider-integrations) documentation for information.
## Data Refresh
See the [provider data refresh documentation](/provider_data_refresh) for information on when data for each provider refreshes in Vantage. Both OpenAI data sources refresh once daily.
## OpenAI Reporting Dimensions
On OpenAI [Cost Reports](/cost_reports), you can filter and group across several dimensions. The values available for each dimension depend on the data source, as shown below.
| Dimension | OpenAI Platform | OpenAI Codex |
| - | - | - |
| Billing Account (Organization) | Organization | Workspace ID |
| Account | Project | Account Name (entered at connect) |
| Service | Operation (e.g., Chat and Completions, Images, Embeddings) | Codex client (e.g., Codex CLI, Codex Web, Codex VS Code) |
| Category | Model (e.g., gpt-4o) | Model |
| Subcategory | Token type (e.g., input, output, cached input) | Token type (uncached input, cached input, output) |
| Resource ID | API key ID | User email |
| Charge Type | Usage | Usage |
When OpenAI Platform appends billing qualifiers to a line item, the token type is retained ahead of the qualifier in the **Subcategory**, such as "input, long context".
In addition, OpenAI costs include the following provider tags, which are automatically created by Vantage and available for filtering and grouping alongside any [Virtual Tags](/tagging) you create. The **Source** column indicates which data source populates each tag.
| Tag | Description | Source |
| - | - | - |
| `openai:billing_source` | The data source the row came from (`admin` for OpenAI Platform or `codex_analytics` for OpenAI Codex) | Both |
| `openai:api_key_id` | The OpenAI API key ID associated with the usage | OpenAI Platform only |
| `openai:owner_name` | The name of the OpenAI API key's owner, when available | OpenAI Platform only |
| `openai:owner_email` | The email of the OpenAI API key's owner, when available | OpenAI Platform only |
| `openai:endpoint_type` | The endpoint type for the usage (e.g., `regional`), when applicable | OpenAI Platform only |
| `openai:client_id` | The Codex client that generated the usage (e.g., `CODEX_CLI`) | OpenAI Codex only |
| `openai:model` | The model name associated with the usage | OpenAI Codex only |
| `openai:speed` | The service speed tier for the usage | OpenAI Codex only |
| `openai:user_email` | The email of the user associated with the usage | OpenAI Codex only |
| `openai:user_id` | The stable user ID associated with the usage | OpenAI Codex only |
| `openai:cost_attribution` | Set to `unattributed` on reconciliation rows for spend not attributable to a specific user | OpenAI Codex only |
Vantage also applies [Managed AI Tags](/managed_ai_tags) to **OpenAI Platform** costs. This is a normalized `vntg:ai:` schema shared across supported AI providers, so you can analyze AI spend with consistent dimensions. OpenAI Platform rows can include `vntg:ai:model`, `vntg:ai:raw_model`, `vntg:ai:model_provider`, `vntg:ai:provider_region`, `vntg:ai:service_tier`, `vntg:ai:token_type`, `vntg:ai:user_id`, and `vntg:ai:api_key_id`. OpenAI Codex rows currently use the provider-specific `openai:` tags listed above and do not receive Managed AI Tags. See [Managed AI Tags](/managed_ai_tags) for the full schema.
[Usage data](/usage_based_reporting) is available for OpenAI, measured in tokens, when usage enrichment data is available.
**Notes on OpenAI Codex costs:**
* Codex client- and token-type dollar amounts are allocation estimates. Vantage allocates OpenAI's model-level estimated costs across clients and token types so the resulting rows reconcile to OpenAI's imported model-level estimated cost. Model-level estimated cost and speed originate from OpenAI's model breakdown.
* Tax is not included. OpenAI's Codex Analytics API reports estimated cost that does not include tax.
### View OpenAI Codex Spend by User
For **OpenAI Codex** spend, cost rows use the user's email as the **Resource ID** and include the `openai:user_email` tag, so you can group a Cost Report by **Resource** or filter and group by the `openai:user_email` tag. The stable user identifier is also available as the `openai:user_id` tag. Codex spend that OpenAI reports at the workspace level but does not attribute to a specific user appears on a reconciliation row tagged `openai:cost_attribution` = `unattributed`.
# Oracle Cloud
Source: https://docs.vantage.sh/connecting_oracle
Learn how to integrate Vantage with Oracle Cloud.
Vantage uses a read-only IAM user and API key to read from a [Cost and Usage Reports object storage bucket](https://docs.oracle.com/en-us/iaas/Content/Billing/Concepts/usagereportsoverview.htm). When connecting to Oracle, you will be required to create a Vantage-specific IAM user and upload a generated RSA public key to that user. That user must then be granted access to read objects from the [Cost and Usage Report tenancy](https://docs.oracle.com/en-us/iaas/Content/Billing/Concepts/usagereportsoverview.htm#policy).
## Connect Your Oracle Cloud Account
### Prerequisites
* You must have a Vantage **Organization Owner** or **Integration Owner** role to add or remove this integration. See the [Role-Based Access Control](/rbac) documentation for details.
* The integration process uses the [Oracle Cloud Infrastructure CLI](https://docs.oracle.com/en-us/iaas/Content/API/Concepts/cliconcepts.htm). Ensure you have access to the CLI before proceeding.
* [Create a free Vantage account](https://console.vantage.sh/signup), then follow the steps below to integrate Oracle Cloud Infrastructure costs.
If your organization restricts access to the provider by IP address, add the following Vantage IP addresses to your provider's allowlist:
### Create the Connection
Navigate to the [Oracle Settings](https://console.vantage.sh/settings/oracle/) page in the Vantage console.
A set of instructions is displayed, which will walk you through how to create an IAM user and group, add an IAM policy, and obtain your Tenancy ID and User ID. This series of commands grants Vantage permission to ingest cost and usage information from your Oracle Cloud account through an API key. All commands need to be performed using the Oracle Cloud Infrastructure CLI.
At the bottom of the setup screen, click **Add Connection**. Paste your **Tenancy** and Vantage **User ID**. Then, select your **Home Region**.
Click **Connect Account**.
After clicking **Connect Account**, you will see the status of your integration change to **Importing** within the Vantage console. This status indicates that Vantage is actively importing your Oracle Cloud cost data. It usually takes less than an hour to ingest Oracle costs. See the [Integration Status](/vantage_account#integration-status) documentation for details on integration statuses.
### Next Steps - Manage Workspace Access
Once the import is complete and the integration status changes to **Stable**, you can select which workspaces this integration is associated with. See the [Workspaces](/workspaces#manage-workspace-provider-integrations) documentation for information.
## Data Refresh
See the [provider data refresh documentation](/provider_data_refresh) for information on when data for each provider refreshes in Vantage.
## Oracle Cloud Reporting Dimensions
On Oracle [Cost Reports](/cost_reports), you can filter across several dimensions:
* Compartment
* Category (e.g., MYSQL - MySQL Database Service - Standard - AMD E4 - Memory)
* Tag/Not Tagged (includes Oracle tags and [virtual tags](/tagging) created in Vantage for this provider)
* Resource (resource ID)
* Region (e.g., Us Ashburn 1)
* Charge Type (e.g., Usage)
* Tenancy (tenancy OCID)
* Service (e.g., MYSQL)
# PlanetScale
Source: https://docs.vantage.sh/connecting_planetscale
Learn how to integrate Vantage with PlanetScale.
Vantage integrates with PlanetScale billing data via the PlanetScale Invoices API. Vantage connects to PlanetScale organizations through an OAuth flow, handled within the PlanetScale app. Vantage supports multiple PlanetScale organization integrations. All organizations are ingested after you connect via the OAuth flow and do not need to be individually added. After authorizing Vantage access to your PlanetScale organizations, Vantage will begin to ingest data using the PlanetScale Organizations, Invoices, and Databases endpoints.
The required PlanetScale scopes to connect are:
* User access
* `read_organizations`
* Organization access
* `read_organization`
* `read_invoices`
* `read_databases`
No access is granted to the actual databases themselves. Vantage can see only metadata related to the databases.
The Invoices endpoint provides structured cost data, broken down by service (e.g., Database or Support), category (e.g., PS-10, PS-20), and resource (e.g., the specific database). All credentials are encrypted.
Vantage supports Databases and Support services, as well as the following services for Branches:
* PS-10
* PS-20
* PS-40
* PS-80
* PS-160
* PS-320
* PS-400
## Connect Your PlanetScale Account
### Prerequisites
* You must have a Vantage **Organization Owner** or **Integration Owner** role to add or remove this integration. See the [Role-Based Access Control](/rbac) documentation for details.
* You will need the [Organization Admin role](https://planetscale.com/docs/concepts/access-control) in PlanetScale to complete the connection.
* [Create a free Vantage account](https://console.vantage.sh/signup), then follow the steps below to connect to PlanetScale.
If your organization restricts access to the provider by IP address, add the following Vantage IP addresses to your provider's allowlist:
### Create the Connection
From the Vantage console, navigate to the [Integrations page](https://console.vantage.sh/settings/integrations).
Select **PlanetScale**, then click **Connect PlanetScale Account**.
You will be brought to the PlanetScale login screen. Log in to your account and select the organizations you want to connect with.
Click **Authorize access**.
After you authorize a connection, on the [PlanetScale Settings](https://console.vantage.sh/settings/planetscale/) page, you will see the status of your connection change to **Importing**.
After authorizing the connection, you will see the status of your integration change to **Importing** within the Vantage console. This status indicates that Vantage is actively importing your PlanetScale cost data. See the [Integration Status](/vantage_account#integration-status) documentation for details on integration statuses.
Once costs are processed, they will be available on your **All Resources** Cost Report.
### Next Steps - Manage Workspace Access
Once the import is complete and the integration status changes to **Stable**, you can select which workspaces this integration is associated with. See the [Workspaces](/workspaces#manage-workspace-provider-integrations) documentation for information.
## Data Refresh
See the [provider data refresh documentation](/provider_data_refresh) for information on when data for each provider refreshes in Vantage.
## PlanetScale Reporting Dimensions
On PlanetScale [Cost Reports](/cost_reports/), you can filter costs across several dimensions:
* Category (e.g., PS-10, PS-20)
* Tag ([virtual tags](/tagging) created in Vantage for this provider)
* Resource (e.g., database name)
* Charge Type (e.g., Usage)
* Organization (organization ID)
* Service (e.g., Database or Support)
You can also view credits or discounts for PlanetScale costs in Cost Reports.
At the top of any PlanetScale Cost Report, click **Settings**.
Then, toggle on/off **Credits** and/or **Discounts**.
## Active Resources
PlanetScale databases are synced as active resources and available in [resource reports](/active_resources).
# Redis
Source: https://docs.vantage.sh/connecting_redis
Learn how to integrate Vantage with Redis.
Vantage connects to Redis using an Account API Key and a User API Key to ingest cost data through the Redis REST API. [Usage data](/usage_based_reporting) is available for Redis and is measured in units such as Month or Hour, depending on service and usage category. You can connect multiple Redis accounts by providing separate API keys for each. Each account will be tracked independently within Vantage.
## Redis Permissions
Vantage uses your Redis API keys to generate and download cost reports only. Vantage does not create, modify, or delete Redis databases, subscriptions, or account settings.
## Connect Your Redis Account
### Prerequisites
* You must have a Vantage **Organization Owner** or **Integration Owner** role to add or remove this integration. See the [Role-Based Access Control](/rbac) documentation for details.
* You must be an Account Owner in order to create API Keys in Redis.
* You should use a dedicated user with the Viewer role in order to create User API keys. The Vantage integration will still work with any role higher than Viewer, such as Owner, but this is not recommended.
* It's best practice to create a dedicated User API Key for Vantage and rotate it according to your security policy.
* [Create a free Vantage account](https://console.vantage.sh/signup), then follow the steps below to integrate Redis costs.
### Create the Connection
#### Step 1 - Get Redis API Keys
Log in to the [Redis console](https://app.redislabs.com/).
From the left navigation, open **Access Management** and select the **API Keys** tab.
If Redis shows an **Enable API** button for your account, click it to enable REST API access.

In the **API account key** section, copy the **Account API Key**.
In the **API user keys** section, click **Add** to create a new User API Key.

Enter a key name and select the user the key should be associated with.
The selected user should have an **Owner** or **Viewer** role so the key can be used to generate cost reports.
Click **Create**, then copy the generated **User API Key**.
Redis only shows the User API Key value once. Save it securely before closing the dialog.
If you use a CIDR allow list on the User API Key, you will need to add each of the following Vantage IPs to ensure connectivity:
#### Step 2 - Add the Keys to Vantage
From the top navigation in Vantage, click **Settings**.
On the left navigation, select **Integrations** > **Redis**.
The Redis integrations page is displayed. Ensure you are on the **Connect** tab.
At the bottom of the page, click **Add API Keys**.
Enter the following values:
* **Description**: A friendly name for this Redis connection
* **Account API Key**: The Redis account key
* **User API Key**: The Redis user key
Click **Connect Account**.
After clicking **Connect Account**, the integration status changes to **Importing** while Vantage ingests your Redis cost data. When the integration is first connected, Vantage ingests up to **six months** of historical Redis cost and usage data. See the [Integration Status](/vantage_account#integration-status) documentation for details.
As soon as costs are processed, they will be available on your **All Resources** Cost Report. If you remove the Redis integration from Vantage, all associated Redis costs will be removed from the Vantage console.
### Next Steps - Manage Workspace Access
Once the import is complete and the integration status changes to **Stable**, you can select which workspaces this integration is associated with. See the [Workspaces](/workspaces#manage-workspace-provider-integrations) documentation for information.
## Data Refresh
See the [provider data refresh documentation](/provider_data_refresh) for information on when data for each provider refreshes in Vantage.
## Redis Reporting Dimensions
On Redis [Cost Reports](/cost_reports), you can filter and group across several dimensions:
* Billing Account (the Redis account name shown in billing data)
* Account (the Redis account ID)
* Service (e.g., Redis Pro, Redis Essentials)
* Category (e.g., Databases)
* Subcategory (e.g., Caching)
* Region (e.g., us-east-1)
* Resource (the Redis resource or subscription name associated with the charge)
* Charge Type (e.g., Usage, Purchase, Adjustment, Discount)
* Tags: Includes native Redis tags, [Virtual Tags](/tagging) created in Vantage for this provider, and the following provider tags that Vantage automatically creates from Redis billing data:
* `redis_cloud:charge_description`: The billing line-item description
* `redis_cloud:resource_type`: The type of billed Redis resource
* `redis_cloud:resource_id`: The underlying Redis resource ID when present
* `redis_cloud:resource_name`: The Redis resource name when present
* `redis_cloud:availability_zone`: The availability zone when present in the source data
* `redis_cloud:billing_period_start`: The start date of the billing period
# Snowflake
Source: https://docs.vantage.sh/connecting_snowflake
Learn how to integrate Vantage with Snowflake.
Vantage integrates with your Snowflake account through a secure, read-only user that has access to Snowflake usage tables. Optionally, you can create a specific schema for the Vantage user.
Vantage requires read-only access to the following tables:
* [`SNOWFLAKE.ORGANIZATION_USAGE.WAREHOUSE_METERING_HISTORY`](https://docs.snowflake.com/en/sql-reference/functions/warehouse_metering_history.html)
* Returns hourly credit usage for both Virtual Warehouse credit usage and Cloud Services credit usage per warehouse, for all warehouses in your account. Data is retained for one year.
* [`SNOWFLAKE.ACCOUNT_USAGE.QUERY_HISTORY`](https://docs.snowflake.com/en/sql-reference/account-usage/query_history.html)
* Query history with various dimensions, including total elapsed time, warehouse used, data bytes scanned, etc. Data is retained for one year.
* [`SNOWFLAKE.ORGANIZATION_USAGE.USAGE_IN_CURRENCY_DAILY`](https://docs.snowflake.com/en/sql-reference/organization-usage/usage_in_currency_daily.html)
* Returns the daily credit usage and usage in currency format for an organization.
As a best practice, it is suggested you create a schema specifically for the `vantage` user. Note, however, that this is optional. See the [steps below](/connecting_snowflake#snowflake-schema-for-vantage) for details on how to create this schema.
This page covers connecting Snowflake so Vantage can ingest Snowflake costs. [Snowflake Data Sharing](/snowflake_data_sharing) goes the other direction: it gives your Snowflake warehouse read-only SQL access to your Vantage cost data through a Secure Data Share.
## Connect Your Snowflake Account
### Prerequisites
* You must have a Vantage **Organization Owner** or **Integration Owner** role to add or remove this integration. See the [Role-Based Access Control](/rbac) documentation for details.
* [Create a free Vantage account](https://console.vantage.sh/signup), then follow the steps below to integrate Snowflake costs.
### Snowflake IP Allowed List
If your Snowflake cluster uses an IP allowlist for access control, you will need to add the following IPs to that allowlist:
### Snowflake Schema for Vantage
After creating the below schema, you can add the required views to that schema and grant the `vantage` user access to the schema.
The below commands are based on the Snowflake [documentation](https://community.snowflake.com/s/article/Solution-Grant-access-to-specific-views-in-SNOWFLAKE-ACCOUNT-USAGE-to-custom-roles).
From the top navigation in Vantage, click **Settings**.
On the left navigation, select **Integrations** and select **Snowflake**.
The Snowflake integrations page is displayed. Ensure you are on the **Connect** tab.
Copy the code that's provided under **Create Vantage User and Role** to Snowflake. This SQL creates a user named `vantage`, a role named `vantage`, and a warehouse named `vantage`. It also grants the necessary permissions.
Vantage automatically generates an [RSA public key](https://docs.snowflake.com/en/user-guide/key-pair-auth) for you to use when creating the Vantage user and role. You need to copy the code directly from the Vantage integration page to add the RSA key.
If your security policy requires periodic credential rotation, or if you ever need to replace this key, you can [rotate Snowflake RSA keys](#rotate-snowflake-rsa-keys) later from the Vantage console without recreating the integration.
```sql Sample of code. Copy directly from Vantage console to get RSA key. theme={null}
USE role accountadmin;
CREATE DATABASE vantage;
CREATE ROLE vantage;
CREATE USER vantage;
GRANT ROLE vantage to user vantage;
GRANT ROLE vantage to role accountadmin;
CREATE WAREHOUSE vantage;
GRANT ALL ON WAREHOUSE vantage TO ROLE vantage;
ALTER USER vantage SET DEFAULT_WAREHOUSE=vantage, DEFAULT_ROLE=vantage;
ALTER USER vantage SET password='';
ALTER USER vantage SET RSA_PUBLIC_KEY='{YOUR_RSA_KEY_GENERATED_BY_VANTAGE}';
```
Copy the next code block to set up the Vantage-specific schema to read billing and usage data from your account.
```sql theme={null}
USE WAREHOUSE vantage;
DROP VIEW IF EXISTS VANTAGE.PUBLIC.QUERY_HISTORY;
CREATE VIEW VANTAGE.PUBLIC.QUERY_HISTORY AS
SELECT QUERY_ID, QUERY_TEXT, WAREHOUSE_SIZE, QUERY_PARAMETERIZED_HASH, USER_NAME, WAREHOUSE_ID, WAREHOUSE_NAME, ROLE_NAME, TOTAL_ELAPSED_TIME, END_TIME, QUERY_TAG
FROM SNOWFLAKE.ACCOUNT_USAGE.QUERY_HISTORY;
DROP VIEW IF EXISTS VANTAGE.PUBLIC.WAREHOUSE_METERING_HISTORY;
CREATE VIEW VANTAGE.PUBLIC.WAREHOUSE_METERING_HISTORY AS
SELECT START_TIME, CREDITS_USED_COMPUTE, WAREHOUSE_ID, WAREHOUSE_NAME, ACCOUNT_LOCATOR, ORGANIZATION_NAME, REGION
FROM SNOWFLAKE.ORGANIZATION_USAGE.WAREHOUSE_METERING_HISTORY;
DROP VIEW IF EXISTS VANTAGE.PUBLIC.USAGE_IN_CURRENCY_DAILY;
CREATE VIEW VANTAGE.PUBLIC.USAGE_IN_CURRENCY_DAILY AS
SELECT USAGE_DATE, USAGE_IN_CURRENCY, ACCOUNT_NAME, ACCOUNT_LOCATOR, ORGANIZATION_NAME, REGION, CURRENCY, USAGE_TYPE
FROM SNOWFLAKE.ORGANIZATION_USAGE.USAGE_IN_CURRENCY_DAILY;
GRANT USAGE ON SCHEMA vantage.public TO ROLE vantage;
GRANT USAGE ON DATABASE vantage TO ROLE vantage;
GRANT SELECT ON ALL VIEWS IN SCHEMA vantage.public TO ROLE vantage;
```
Test your setup in Snowflake.
```sql theme={null}
USE role vantage;
SELECT * FROM vantage.public.query_history LIMIT 1;
```
At the bottom of the Vantage console Snowflake integration page, click **Add Connection**.
Add the following information to the form:
* **Server URL**: In the format `..snowflakecomputing.com`.
* **Database**: The name of the database the usage views are in (e.g., `vantage`).
* **Schema**: The name of the schema the usage views are in (e.g., `public`).
* **Username** set for the `vantage` user.
Click **Connect Account**.
After adding your integration, you will see the status of your integration change to **Importing** within the Vantage console. This status indicates that Vantage is actively importing your Snowflake cost data. It may take several hours to populate within Vantage depending on the query volume of your warehouse. See the [Integration Status](/vantage_account#integration-status) documentation for details on integration statuses.
As soon as costs are processed, they will be available on your All Resources Cost Report. If you decide to remove your Snowflake integration from Vantage, all costs associated with your Snowflake integration will be removed from the Vantage console.
On a Snowflake connection's **Manage Connection** page, the **Integration Status** panel displays validation results for authentication, warehouse access, required views, and data availability. Click **Run Checks** to validate the connection on demand. See [Connection Validation Checks](/vantage_account#connection-validation-checks) for status details.
### Next Steps - Manage Workspace Access
Once the import is complete and the integration status changes to **Stable**, you can select which workspaces this integration is associated with. See the [Workspaces](/workspaces#manage-workspace-provider-integrations) documentation for information.
## Rotate Snowflake RSA Keys
You can rotate the RSA key pair for an existing Snowflake integration from the Vantage console. This lets you add and test a secondary key before replacing the primary key that Vantage uses to connect to Snowflake.
Before you begin, make sure you have permission to manage integrations in Vantage and a Snowflake role that can run `ALTER USER` for the Snowflake user configured on the Vantage integration.
Copy the SQL commands directly from your Vantage console. The examples below show the shape of each command, but Vantage generates keys that are unique to each Snowflake connection.
In Vantage, navigate to your Snowflake integration:
* From the top navigation, click **Settings**.
* On the left navigation, select **Integrations** and select **Snowflake**.
* Click the Snowflake connection you want to rotate.
In the **Secondary Keys** section, click **Create Secondary Key Set**. Vantage creates a new secondary RSA key pair and displays a **Key Rotation** checklist.
Copy the first generated SQL command from Vantage and run it in Snowflake. This adds the new public key as the user's secondary public key.
```sql theme={null}
ALTER USER vantage SET RSA_PUBLIC_KEY_2='{SECONDARY_PUBLIC_KEY_GENERATED_BY_VANTAGE}';
```
If your Vantage integration uses a Snowflake username other than `vantage`, use the username shown in the Vantage-generated command.
In Vantage, click **Test Connection** to verify that the secondary key works. The connection test may take a few minutes. Wait for it to complete before continuing.
When the test succeeds, Vantage refreshes the page and enables **Promote Secondary Keys**. If the test fails, leave the primary key unchanged and follow the [troubleshooting guidance](#snowflake-rejected-the-secondary-key) below.
Copy the next generated SQL command from Vantage and run it in Snowflake. This makes the validated secondary key the primary public key in Snowflake.
```sql theme={null}
ALTER USER vantage SET RSA_PUBLIC_KEY='{SECONDARY_PUBLIC_KEY_GENERATED_BY_VANTAGE}';
```
Copy the generated cleanup command from Vantage and run it in Snowflake. This removes the secondary public key from the Snowflake user.
```sql theme={null}
ALTER USER vantage UNSET RSA_PUBLIC_KEY_2;
```
In Vantage, click **Promote Secondary Keys**. This updates Vantage to use the validated secondary private key as the primary key and clears the temporary secondary key set.
If you click **Create Secondary Key Set** again before promotion, Vantage replaces the previous unpromoted secondary key set. Run the latest SQL commands shown in the console.
## Data Refresh
See the [provider data refresh documentation](/provider_data_refresh) for information on when data for each provider refreshes in Vantage.
## View Snowflake Metrics on Cost Reports
You can import Snowflake SQL query results as business metrics to view alongside Cost Reports. Snowflake business metric imports reuse a connected Snowflake integration, but the configured Snowflake role must have `SELECT` access to the metric tables or views referenced in your query. See the [Business Metrics](/business_metrics#import-from-snowflake) documentation for more information.
## Troubleshoot Snowflake Errors
Common integration errors are described below.
### Promote Secondary Keys Is Disabled
The **Promote Secondary Keys** button is disabled until the secondary key passes the Vantage connection test. Complete the **Test Connection** step first. The test may take a few minutes; while it is running, Vantage shows a progress indicator and waits for the result.
If the test times out, click **Test Connection** again. If it continues to time out, confirm that Snowflake is reachable from the Vantage IPs in the [Snowflake IP Allowed List](#snowflake-ip-allowed-list), then contact [support@vantage.sh](mailto:support@vantage.sh) for assistance.
### Snowflake Rejected the Secondary Key
If the Vantage connection test returns `Snowflake rejected the secondary key.`, Snowflake rejected authentication with the secondary RSA key. The most common causes are:
* The generated `RSA_PUBLIC_KEY_2` command was not run in Snowflake.
* The public key was copied incompletely or modified before being pasted into Snowflake.
* The command was run for a different Snowflake user than the one configured in Vantage.
* The command was run in a different Snowflake account than the one connected to Vantage.
* A Snowflake network policy is blocking Vantage.
To resolve the issue:
In Vantage, copy the latest command from step 1 of the **Key Rotation** checklist.
In Snowflake, run the copied command again for the user shown in the command.
Confirm your Snowflake network policy allows the Vantage IPs listed in the [Snowflake IP Allowed List](#snowflake-ip-allowed-list).
Click **Test Connection** in Vantage again.
### Connection Fails After Promoting Keys
If the Snowflake connection fails after you promote secondary keys in Vantage, confirm that you first ran the generated `ALTER USER ... SET RSA_PUBLIC_KEY='...'` command in Snowflake. Vantage should only be promoted after Snowflake's primary public key has been updated to the new key.
If Snowflake was not updated first, create a new secondary key set in Vantage and repeat the [key rotation process](#rotate-snowflake-rsa-keys) using the latest generated SQL commands.
### `query_history` Column Count Mismatch
Snowflake occasionally makes changes to the queries/tables that get used for cost and usage attribution, causing the views in Vantage to then be based on an old query. You may see an error in the Vantage console, similar to the below error:
```text theme={null}
View definition for 'VANTAGE.PUBLIC.QUERY_HISTORY' declared 66 column(s), but view query produces 77 column(s).
```
To fix the issue, replace the three `Vantage` views in Snowflake and ensure the `vantage` user is granted permission on those views.
After you've completed the below steps, contact [support@vantage.sh](mailto:support@vantage.sh) to reimport your Snowflake data.
```sql theme={null}
USE WAREHOUSE vantage;
DROP VIEW IF EXISTS VANTAGE.PUBLIC.QUERY_HISTORY;
CREATE VIEW VANTAGE.PUBLIC.QUERY_HISTORY AS
SELECT QUERY_ID, QUERY_TEXT, WAREHOUSE_SIZE, QUERY_PARAMETERIZED_HASH, USER_NAME, WAREHOUSE_ID, WAREHOUSE_NAME, ROLE_NAME, TOTAL_ELAPSED_TIME, END_TIME, QUERY_TAG
FROM SNOWFLAKE.ACCOUNT_USAGE.QUERY_HISTORY;
DROP VIEW IF EXISTS VANTAGE.PUBLIC.WAREHOUSE_METERING_HISTORY;
CREATE VIEW VANTAGE.PUBLIC.WAREHOUSE_METERING_HISTORY AS
SELECT START_TIME, CREDITS_USED_COMPUTE, WAREHOUSE_ID, WAREHOUSE_NAME, ACCOUNT_LOCATOR, ORGANIZATION_NAME, REGION
FROM SNOWFLAKE.ORGANIZATION_USAGE.WAREHOUSE_METERING_HISTORY;
DROP VIEW IF EXISTS VANTAGE.PUBLIC.USAGE_IN_CURRENCY_DAILY;
CREATE VIEW VANTAGE.PUBLIC.USAGE_IN_CURRENCY_DAILY AS
SELECT USAGE_DATE, USAGE_IN_CURRENCY, ACCOUNT_NAME, ACCOUNT_LOCATOR, ORGANIZATION_NAME, REGION, CURRENCY, USAGE_TYPE
FROM SNOWFLAKE.ORGANIZATION_USAGE.USAGE_IN_CURRENCY_DAILY;
GRANT USAGE ON SCHEMA vantage.public TO ROLE vantage;
GRANT USAGE ON DATABASE vantage TO ROLE vantage;
GRANT SELECT ON ALL VIEWS IN SCHEMA vantage.public TO ROLE vantage;
```
### `Invalid username or password` Error
If your Snowflake integration shows an `Invalid username or password` error in the Vantage console, the cause is almost always a username or RSA public key issue, not a password issue.
Snowflake returns the `Invalid username or password` message for several underlying authentication failures, including:
* `JWT_TOKEN_INVALID_PUBLIC_KEY_FINGERPRINT_MISMATCH` — the RSA public key configured in Snowflake does not match the public key generated by Vantage.
* `INCOMING_REQUEST_BLOCKED` — Snowflake rejected the signed JWT, typically due to a key mismatch or a network policy.
* A `vantage` user that does not exist in your Snowflake account.
A public key mismatch can occur if:
* The public key was manually modified in Snowflake.
* The integration was recreated in Vantage, generating a new public key.
* The public key was incorrectly copied during initial setup.
To resolve this issue:
Navigate to your Snowflake integration in Vantage:
* From the top navigation, click **Settings**
* On the left navigation, select **Integrations** and select **Snowflake**
* Click on your Snowflake connection to open the **Manage Connection** page
Copy the **Primary Public Key** from the Vantage console. This is the RSA public key that Vantage generated for your integration.
In Snowflake, update the `vantage` user's RSA public key to match the one from Vantage:
```sql theme={null}
USE role accountadmin;
ALTER USER vantage SET RSA_PUBLIC_KEY='{YOUR_RSA_KEY_GENERATED_BY_VANTAGE}';
```
Replace `{YOUR_RSA_KEY_GENERATED_BY_VANTAGE}` with the exact public key copied from the Vantage console.
Verify the connection is working. The error should be resolved once the public keys match.
The public key must match exactly between Vantage and Snowflake. Ensure you copy the entire key from the Vantage console without any modifications or extra characters.
If you continue to encounter errors after following these steps, contact [support@vantage.sh](mailto:support@vantage.sh) for assistance.
## Snowflake Reporting Dimensions
On Snowflake [Cost Reports](/cost_reports), you can filter across several dimensions:
* Account (account name)
* Category (e.g., Data Cloud Data Transfer)
* Metadata (e.g., `environment is staging`)
* Region (e.g., AWS EU West 1)
* Organization (organization name)
* Service (e.g., Data Cloud)
* Tags: Includes [Virtual Tags](/tagging) created in Vantage for this provider. The following tags are also available for filtering and grouping. These are derived from columns in the Snowflake usage views Vantage reads (e.g., `QUERY_HISTORY`), not from Snowflake object tags.
* `user`: The user who ran the query (from `USER_NAME`), allowing you to filter and group costs by user.
* `warehouse`: The warehouse name (from `WAREHOUSE_NAME`), allowing you to filter and group costs by warehouse.
* `role`: The role name when present (from `ROLE_NAME`), allowing you to filter and group costs by role.
* `query_tag`: The session query tag when present (from the `QUERY_TAG` column in query history). This can be a single value or, if set as JSON (e.g., `ALTER SESSION SET query_tag = '{"team":"eng"}'`), parsed into tag key/value pairs for filtering and grouping.
* Charge Type (e.g., Usage)
## Active Resources
Snowflake queries are synced as active resources and available in [resource reports](/active_resources).
# SpaceXAI
Source: https://docs.vantage.sh/connecting_spacexai
Learn how to integrate Vantage with SpaceXAI (formerly xAI) to track Grok and SpaceXAI API inference costs.
Vantage integrates with your SpaceXAI (formerly xAI) account using a Management key to ingest cost and usage data through the SpaceXAI [Management API billing usage endpoint](https://docs.x.ai/developers/rest-api-reference/management/billing). Vantage retrieves cost and usage data broken down by model and SKU (for example, `grok-4.3` and `grok-4.3 Priority`), billable unit type, and API key. [Usage data](/usage_based_reporting) is available for SpaceXAI, measured in the provider's billable unit types, such as prompt, completion, cached, and reasoning text tokens.
## SpaceXAI Permissions
Vantage connects to SpaceXAI using a Management key and validates access by reading team billing and usage data. Vantage cannot run inference, deploy models, or perform any actions that incur costs in your SpaceXAI account.
You must use a **Management key**, not an inference API key. Inference API keys from the API Keys page cannot access the billing endpoints. It's best practice to create a dedicated Management key for Vantage and rotate it according to your organization's security policy.
## Connect Your SpaceXAI Account
### Prerequisites
* You must have a Vantage **Organization Owner** or **Integration Owner** role to add or remove this integration. See the [Role-Based Access Control](/rbac) documentation for details.
* You need access to the SpaceXAI Console with permission to create a Management key that can read team billing and usage data.
* [Create a free Vantage account](https://console.vantage.sh/signup), then follow the steps below to integrate SpaceXAI costs.
### Create the Connection
Sign in to the [SpaceXAI Console](https://console.x.ai).
From the bottom left, select the **Settings** icon, then click **Management Keys**.
Click **Create management key**.
Do not use an inference API key from the **API Keys** page. Only a Management key can read the billing endpoints Vantage uses.
Name the key. For **Access**, set **Billing** to **Read only**.
If your organization enforces IP restrictions, use the **Allowed IP addresses** section on this screen to add each of the following Vantage IPs so Vantage can reach the SpaceXAI Management API. Add each IP address individually:
Click **Save** and copy the newly created management key.
From the top navigation in Vantage, click **Settings**.
On the left navigation, select **Integrations** > **SpaceXAI**.
The SpaceXAI integrations page is displayed. Ensure you are on the **Connect** tab.
Click **Add Account** and complete the integration form:
* **Management Key**: Paste the SpaceXAI Management key.
* **Description**: Enter a label to identify this SpaceXAI account or workspace in Vantage. This value is used as the **Organization** dimension in Cost Report filters.
Click **Connect Account**.
After clicking **Connect Account**, you will see the status of your integration change to **Importing** within the Vantage console. This status indicates that Vantage is actively importing your SpaceXAI cost data. Vantage backfills up to six months of historical cost data upon initial connection. See the [Integration Status](/vantage_account#integration-status) documentation for details on integration statuses. You can connect multiple SpaceXAI accounts, each with its own Management key, as separate integrations in Vantage.
As soon as costs are processed, they will be available on your **All Resources** Cost Report. If you decide to remove your SpaceXAI integration from Vantage, all costs associated with that Management key will be removed from the Vantage console.
### Next Steps - Manage Workspace Access
Once the import is complete and the integration status changes to **Stable**, you can select which workspaces this integration is associated with. See the [Workspaces](/workspaces#manage-workspace-provider-integrations) documentation for information.
## Data Refresh
See the [provider data refresh documentation](/provider_data_refresh) for information on when data for each provider refreshes in Vantage. SpaceXAI data refreshes once daily.
## SpaceXAI Reporting Dimensions
On SpaceXAI [Cost Reports](/cost_reports), you can filter and group across several dimensions:
* Organization (the description you enter when connecting the integration)
* Service (the model or SKU, such as `grok-4.3`, `grok-4.3 Priority`, `Speech-to-Text`, or `File Storage`)
* Category (the billable unit type, such as `Prompt text tokens`, `Completion text tokens`, `Cached prompt text tokens`, or `Reasoning text tokens`)
* Resource (the SpaceXAI API key ID associated with the usage; an all-zero ID indicates unattributed usage, such as File Storage)
* Charge Type (Usage)
SpaceXAI costs do not include provider-specific tags. You can still filter and group by any [Virtual Tags](/tagging) you create.
Vantage does apply [Managed AI Tags](/managed_ai_tags) to SpaceXAI costs. This is a normalized `vntg:ai:` schema shared across all AI providers, so you can analyze AI spend with consistent dimensions. For SpaceXAI, the following keys are emitted: `vntg:ai:model`, `vntg:ai:raw_model`, `vntg:ai:model_provider`, `vntg:ai:service_tier`, `vntg:ai:token_type`, and `vntg:ai:api_key_id`. See [Managed AI Tags](/managed_ai_tags) for the full schema.
# Temporal Cloud
Source: https://docs.vantage.sh/connecting_temporal
Learn how to integrate Vantage with Temporal Cloud.
Vantage connects to Temporal Cloud through a [service account](https://docs.temporal.io/cloud/service-accounts), with the [Finance Admin role](https://docs.temporal.io/cloud/users#account-level-roles), using an associated API key for the service account. After authorizing Vantage access to your Temporal Cloud account, Vantage ingests cost and usage data using Temporal's [Cloud Billing API](https://docs.temporal.io/cloud/billing-api). All credentials are encrypted.
You can connect multiple Temporal Cloud integrations by providing API keys for multiple accounts.
## How Temporal Cloud Costs Are Calculated
Vantage uses Temporal Cloud Billing API data to calculate costs for supported billing periods. The Cloud Billing API provides billing report data with contracted costs, pricing quantities, charge descriptions, billing periods, and namespace-level attribution.
For Cloud Billing API data, Vantage uses the cost amounts returned by Temporal instead of estimating costs from manually configured rates. This means negotiated pricing reflected in Temporal's billing report is represented automatically in Vantage. If Temporal includes credits, discounts, or adjustments in its billing report, they appear as standard cost line items. See the [Cost Reports](/cost_reports#credits-discounts-refunds-and-taxes) documentation for how credits, discounts, refunds, and taxes can be shown or hidden in reports.
Temporal Cloud Billing API data is imported for the current calendar month and previous calendar month, where available. On the first day of a month, current-month data may not yet be available, so the previous month may be the first complete Cloud Billing API period shown in Vantage.
Existing customers who connected Temporal Cloud before Cloud Billing API support may have older historical periods that were imported through the legacy Usage API estimate model. See the [Migrate to Cloud Billing Data](/connecting_temporal#migrate-to-cloud-billing-data) section for details.
## Connect Your Temporal Cloud Account
### Prerequisites
* You must have a Vantage **Organization Owner** or **Integration Owner** role to add or remove this integration. See the [Role-Based Access Control](/rbac) documentation for details.
* You need the [Account Owner](https://docs.temporal.io/cloud/users#account-level-roles) role in Temporal Cloud to complete this integration.
The Finance Admin role has the same permissions as Account Read-only users, with additional permissions to view billing information and update payment information. Vantage will never perform any actions to change your payment method. It's recommended that you submit a feature request to Temporal Cloud for improved permission scoping, and Vantage will adopt fine-grained permissions if this becomes available.
* Create a free Vantage account, then follow the steps below to integrate Temporal Cloud costs.
If your organization restricts access to the provider by IP address, add the following Vantage IP addresses to your provider's allowlist:
### Create the Connection
To create an integration with Temporal Cloud and Vantage, create a service account and an API key for that service account.
#### Step 1 - Create a Service Account
The below instructions are based on the [Temporal Cloud documentation](https://docs.temporal.io/cloud/service-accounts#create-a-service-account).
In Temporal Cloud, navigate to **[Settings > Identities](https://cloud.temporal.io/settings/identities)**.
At the top, click **Create Service Account**.

Enter an **Identity Name**, such as *vantage\_integration*.
Add an optional description to identify this account.
For **Account Level Role**, select **Finance Admin**.
For **Namespace Permissions**, set the access for each namespace to **Read-Only**.

If additional namespaces are added after you create this service account, and you want them included in your integration, you will need to go back and update the permissions to account for these new namespaces.
Click **Create Service Account**. Once created, you will be prompted to create an API key for the service account.
#### Step 2 - Create an API Key for the Service Account
The below instructions are based on the [Temporal Cloud documentation](https://docs.temporal.io/cloud/api-keys).
After you create the service account, you will be prompted to create an API key. You can also create an API key for the service account at any time. Navigate to **[Settings > API keys](https://cloud.temporal.io/settings/api-keys)**.
Click **Create API Key**.

Under **Create an API key for**, select **Service Account**.
For **Mapped to Identity**, search for and select the service account you just created.
Give the API key a **Name** and optional **Description**.
For **Expiry Date**, select a date for when the key should expire.
At this time, Temporal Cloud API keys can be configured to be valid for up to 2 years, after which you'll need to rotate your Temporal Cloud API key in the Vantage console.

Click **Generate API Key** and copy the newly generated key.
#### Step 3 - Add Your API Key to Vantage
From the top navigation in Vantage, click **Settings**.
On the left navigation, select **Integrations** > **Temporal Cloud**.
The Temporal Cloud integrations page is displayed. Ensure you are on the **Connect** tab.
At the bottom of the page, click **Add API Key** and paste your newly generated API key. Optionally, add a **Description** to identify this integration.
Click **Connect Account**.
Vantage validates the API key before saving the integration. If the key is invalid, expired, or does not have the required Temporal Cloud role, Vantage displays an error and does not create the integration.
After clicking **Connect Account**, you will see the status of your integration change to **Importing** within the Vantage console. This status indicates that Vantage is actively importing your Temporal Cloud cost data. See the [Integration Status](/vantage_account#integration-status) documentation for details on integration statuses.
After the integration is complete, Vantage imports Temporal Cloud Billing API data for the current calendar month and previous calendar month, where available. Vantage will retain cost and usage data to match your retention period for all providers. As soon as costs are processed, they will be available on your All Resources Cost Report. If you remove your Temporal Cloud integration from Vantage, all costs associated with your Temporal Cloud API key will be removed from the Vantage console.
#### Next Steps - Manage Workspace Access
Once the import is complete and the integration status changes to **Stable**, you can select which workspaces this integration is associated with. See the [Workspaces](/workspaces#manage-workspace-provider-integrations) documentation for information.
## Migrate to Cloud Billing Data
This section applies to customers who connected Temporal Cloud before Vantage supported Temporal's Cloud Billing API.
### What's Improved with Cloud Billing Data
Previously, Vantage ingested Temporal Cloud costs using the Usage endpoint of the [Temporal Cloud Operations API](https://docs.temporal.io/ops), which returned raw consumption metrics (Actions and Storage usage) rather than billed costs. Vantage estimated costs by multiplying that usage by custom rates configured in Vantage for Actions, Active Storage, and Retained Storage. By default, Vantage applied Temporal's public pricing and the base Actions rate (under 5M per month); for higher Actions volumes without a private rate card, blended rates could be calculated by dividing total costs by usage. Actions rates were measured in millions of Actions and storage rates in Gigabyte-Hours. Because these were usage-based estimates, they did not account for Actions included in your plan, taxes, discounts, credits, committed spend, or [Plan Costs](https://docs.temporal.io/cloud/pricing#base_plans).
Cloud Billing Data uses Temporal's [Cloud Billing API](https://docs.temporal.io/cloud/billing-api) instead. For supported billing periods, Vantage uses Temporal-provided billing amounts rather than custom-rate estimates, giving a more complete view that includes contracted pricing and charge details from Temporal's billing reports. Custom rates do not apply to Cloud Billing API periods; if you still see custom rates on an existing integration, they apply only to older legacy periods. For those legacy periods, you can still use the [Custom Providers](/connecting_custom_providers) integration with [cost allocation](/tagging#cost-allocation-tags) to represent costs outside of usage costs.
### What You Need to Know Before Migrating
You do not need to create a second Temporal Cloud integration. The migration happens on your existing Temporal Cloud connection.
After Cloud Billing Data is enabled, Vantage re-imports the current and previous calendar month using Temporal's Cloud Billing API, where available. Older periods remain based on the previous Usage API estimate model unless reprocessed. For example, enabling Cloud Billing Data on June 25, 2026:
| Billing Period | Data Source |
| - | - |
| June 2026 (current month) | Cloud Billing API |
| May 2026 (previous month) | Cloud Billing API |
| April 2026 and earlier | Legacy Usage API estimates |
Cloud Billing API costs continue to appear under **Temporal Cloud** in Cost Reports. The migration changes the source of the cost data, but it does not create a separate provider or service. You may notice differences between older estimated periods and newer Billing API periods because newer data no longer relies on custom rates configured in Vantage.
### How to Migrate from the Usage API Integration
Navigate to the Temporal Cloud [settings page](https://console.vantage.sh/settings/temporal).
Select your existing Temporal Cloud integration from the list.
On the Manage Connection page, click the toggle to enable **Cloud Billing Data**.
Wait for Vantage to import Cloud Billing API data for supported billing periods. Your Cost Reports will continue to show costs under **Temporal Cloud**.
If your existing API key has expired or no longer has the required Temporal Cloud role, the Cloud Billing Data import will fail. Rotate the API key on your Temporal Cloud integration to resolve this. See the [Temporal API key documentation](https://docs.temporal.io/cloud/api-keys) for details on creating or rotating API keys.
## Use Case: Associate Temporal Cloud Namespaces with Infrastructure Costs Using Virtual Tags
If your teams are running workloads across Temporal Cloud and other infrastructure providers, you can use [Virtual Tags](/tagging) in Vantage to group and analyze total application costs.
For example, you may want to track the total costs for the Payments team, which operates multiple workloads in Temporal Cloud. By creating a Virtual Tag with the key `Team` and the value `Payments`, you can apply a filter to group together things like Temporal Cloud costs filtered by the `payments-prod` and `payments-staging` namespaces.
You can view all namespaces using the **Resource** filter/grouping criteria on a Cost Report.
See the following example in the [FinOps as Code repository](https://github.com/vantage-sh/finops-as-code/tree/main/terraform/temporal-costs) for steps on how to set up a tagging schema for teams and namespaces using the Vantage Terraform provider.
## Data Refresh
See the [provider data refresh documentation](/provider_data_refresh) for information on when data for each provider refreshes in Vantage.
## Temporal Cloud Reporting Dimensions
On Temporal Cloud [Cost Reports](/cost_reports), you can filter across several dimensions:
* Organization (e.g., Temporal Cloud billing account name, billing account ID, or the description set when connecting the integration)
* Service (e.g., Temporal Cloud)
* Charge Type (e.g., Usage; Discount when provided by Temporal)
* Category (e.g., Actions, Storage, Other)
* Subcategory (e.g., Actions, Active Storage, Retained Storage)
* Resource ID (e.g., namespace or Temporal resource ID)
* SKU (e.g., Temporal SKU ID)
* Tags: Includes Temporal Cloud tags (such as `$tmprl_project`), [Virtual Tags](/tagging) created in Vantage, and the following provider tags that Vantage automatically creates from Temporal billing data:
* `temporal:resource_type`: The Temporal resource type associated with the charge, such as `Namespace`, allowing you to filter and group costs by resource type.
* `temporal:resource_id`: The Temporal resource ID associated with the charge, allowing you to filter and group costs by the underlying Temporal resource.
Temporal tags included in the Cloud Billing API report, such as `$tmprl_project`, are also available as Cost Report tags using their original tag keys.
# Twilio
Source: https://docs.vantage.sh/connecting_twilio
Learn how to integrate Vantage with Twilio.
Vantage connects to Twilio via a [Standard API key](https://www.twilio.com/docs/iam/api-keys#types-of-api-keys) to ingest cost and usage data through the [Usage Records API](https://www.twilio.com/docs/usage/api/usage-record). After authorizing Vantage access to your Twilio account, Vantage will begin ingesting data using the Usage API. All credentials are encrypted. You can connect multiple Twilio integrations by providing API keys for multiple accounts. [Usage data](/usage_based_reporting) is also available for Twilio, such as quantity of Phone Numbers or number of SMS messages.
Vantage has access to all Twilio API resources, except for [API key](https://www.twilio.com/docs/iam/api-keys/key-resource-v1) and [Account](https://www.twilio.com/docs/iam/api/account) resources. Vantage will never perform any write actions to your account. Although Twilio has scoping for API keys, usage and billing APIs are not included. We recommend customers submit a feature request to Twilio for improved permission scoping, and Vantage will adopt fine-grained permissions if this becomes available.
## Connect Your Twilio Account
### Prerequisites
* You must have a Vantage **Organization Owner** or **Integration Owner** role to add or remove this integration. See the [Role-Based Access Control](/rbac) documentation for details.
* You must have an Administrator or Developer role in Twilio to create an API key.
* Create a free Vantage account, then follow the steps below to integrate Twilio costs.
### Twilio Account Limitations
If you create an API key in your top-level main account, Vantage includes all cost data incurred in any subaccounts that roll up to the top-level main account. When you view usage on a report, it will appear as if the costs were incurred in the parent account.
If you want to specifically capture the subaccount, you can create an API key specifically for that subaccount, and connect the subaccount as its own integration.
Ideally, you could provide a single API key for an Organization, and Vantage could capture subaccount-level granularity, but this is unfortunately a limitation of Twilio's APIs. Contact your Twilio CSM to ask for enhancements to the Billing and Usage APIs.
If your organization restricts access to the provider by IP address, add the following Vantage IP addresses to your provider's allowlist:
### Create the Connection
Follow the steps below to create a connection with Twilio.
#### Step 1 - Create a Twilio Standard API Key
Log in to the [Twilio console](https://console.twilio.com/). Ensure you are logged in to your main Twilio account. (See the [section above](/connecting_twilio#twilio-account-limitations) for information on limitations between main and subaccounts.)
On the **Account Dashboard**, your **Account SID** is displayed in the **Account Info** section. Copy the **Account SID** to use in the next section when connecting to Vantage.

At the top of the console, click **Admin** > **Account management**.

On the left navigation menu, under **Keys & Credentials**, click **API keys & tokens**.
Click **Create API key**.

On the **Create new API key** page, add the following information:
1. Enter a **Friendly name**, like *vantage.*
2. Select a **Region**.
3. For **Key type**, select **Standard**.
At the bottom, click **Create**.

Copy the **SID** (i.e., the string identifier for the API key) and **Secret**.

#### Step 2 - Add Credentials to Vantage
From the top navigation in Vantage, click **Settings**.
On the left navigation, select **Integrations** > **Twilio**.
The Twilio integrations page is displayed. Ensure you are on the **Connect** tab.
At the bottom of the page, click **Add API Key:**
* For **API Key**, paste the API key SID you just obtained in the last step.
* For **API Secret**, paste the API secret you just obtained in the last step.
* For **Account SID**, paste the **Account SID** you obtained in step 2 of the last section.
* For **Account Name**, add a name that will be used for the Billing Account filter in Cost Reports. It's recommended that you use your account name as displayed in the Twilio console (see example image below). This name must be unique across all Twilio integrations in Vantage.

*For example, the account name here would be "My first Twilio account."*
* Optionally, add a **Description** to identify this integration.
Click **Connect Account**.
After clicking **Connect Account**, you will see the status of your integration change to **Importing** within the Vantage console. This status indicates that Vantage is actively importing your Twilio cost data. Vantage will load the previous six months of Twilio usage data. See the [Integration Status](/vantage_account#integration-status) documentation for details on integration statuses.
As soon as costs are processed, they will be available on your **All Resources** Cost Report. If you decide to remove your Twilio integration from Vantage, all costs associated with your Twilio API token will be removed from the Vantage console.
#### Next Steps - Manage Workspace Access
Once the import is complete and the integration status changes to **Stable**, you can select which workspaces this integration is associated with. See the [Workspaces](/workspaces#manage-workspace-provider-integrations) documentation for information.
## Data Refresh
See the [provider data refresh documentation](/provider_data_refresh) for information on when data for each provider refreshes in Vantage.
## Twilio Reporting Dimensions
On Twilio [Cost Reports](/cost_reports), you can filter across several dimensions:
* Billing Account (the name of Twilio account entered at time of integration)
* Account (account ID of the account your Standard API key is created in)
* Service (e.g., SMS & MMS)
* Charge Type (e.g., Usage)
* Category (e.g., sms-messages-carrierfees)
* Tags ([Virtual Tags](/tagging) created in Vantage)
# Vercel
Source: https://docs.vantage.sh/connecting_vercel
Learn how to integrate Vantage with Vercel.
Vantage connects to Vercel through a Vercel Community Integration to ingest cost and usage data. Vantage retrieves data using the Vercel [FOCUS Billing Charges API](https://docs.vercel.com/docs/rest-api/reference/endpoints/billing/list-focus-billing-charges) and [FOCUS Contract Commitments API](https://docs.vercel.com/docs/rest-api/reference/endpoints/billing/list-focus-contract-commitments), allowing you to track costs across Vercel services such as Functions, Delivery Network, and Observability. [Usage data](/usage_based_reporting) is available for Vercel, measured in units such as Gigabytes, Events, and Invocations, depending on the service.
The Vercel integration requires a Vercel [Enterprise](https://vercel.com/docs/plans/enterprise) or [Pro](https://vercel.com/docs/plans/pro) plan. The [Billing Role](https://vercel.com/docs/rbac/access-roles#billing-role) needed to install the integration is only available on these plans. Accounts with the [Owner role](https://vercel.com/docs/rbac/access-roles#owner-role) can also install the integration.
## Vercel Permissions
The Vantage application uses the `read:billing` scope and cannot deploy, modify, or delete projects, settings, or resources in Vercel. The integration requires the following permissions:
* **Read**
* Installation
* Team
* User
* Billing
* Projects
* **Read and Write**
* Integration Resources
For more information on integration permissions, see the [Vercel documentation](https://vercel.com/docs/integrations/install-an-integration/manage-integrations-reference).
## Connect Your Vercel Account
### Prerequisites
* You must have the [Owner role](https://vercel.com/docs/rbac/access-roles#owner-role) or [Billing role](https://vercel.com/docs/rbac/access-roles#billing-role) in Vercel to install the Vantage community integration.
* Your Vercel account must be on an [Enterprise](https://vercel.com/docs/plans/enterprise) or [Pro](https://vercel.com/docs/plans/pro) plan.
* You must have a Vantage **Organization Owner** or **Integration Owner** role to add or remove this integration. See the [Role-Based Access Control](/rbac) documentation for details.
* [Create a free Vantage account](https://console.vantage.sh/signup), then follow the steps below to integrate Vercel costs.
If your organization restricts access to the provider by IP address, add the following Vantage IP addresses to your provider's allowlist:
### Create the Connection
From the top navigation in Vantage, click **Settings**.
On the left navigation, select **Integrations** > **Vercel**.
The Vercel integrations page is displayed. Ensure you are on the **Connect** tab.
At the bottom of the page, click **Connect with Vercel**.
The Vercel integration page opens in a new window. Click **Connect Account**.
* Select a Vercel team to install the integration on.
* Select all or specific projects.
* Review the permissions and click **Connect Account** to authorize the integration.

Once complete, you can return to the Vantage console.
After completing the authorization, you will see the status of your integration change to **Importing** within the Vantage console. This status indicates that Vantage is actively importing your Vercel cost data. Vercel provides up to one year of historical data through the Billing APIs, and Vantage will ingest this data and retain it to match your retention period. See the [Integration Status](/vantage_account#integration-status) documentation for details on integration statuses.
As soon as costs are processed, they will be available on your **All Resources** Cost Report. If you decide to remove your Vercel integration from Vantage, all costs associated with that community integration will be removed from the Vantage console.
### Next Steps - Manage Workspace Access
Once the import is complete and the integration status changes to **Stable**, you can select which workspaces this integration is associated with. See the [Workspaces](/workspaces#manage-workspace-provider-integrations) documentation for information.
### Edit Project Access
You can specify which projects to include in a team's integration via Vercel's Manage Access UI. To add or remove specific projects:
In the top navigation of your Vercel dashboard, select **Integrations**.
Select the Vantage integration.
On the top right, click **Manage Access**.
Edit the projects the integration has access to and click **Save**.
## Data Refresh
See the [provider data refresh documentation](/provider_data_refresh) for information on when data for each provider refreshes in Vantage.
## Vercel Reporting Dimensions
On Vercel [Cost Reports](/cost_reports), you can filter and group across several dimensions:
* Billing Account (Team)
* Account (Project ID)
* Service (e.g., Vercel Functions, Delivery Network, Observability)
* Category (e.g., Function Invocations)
* Charge Type (e.g., Usage)
* Region (e.g., `iad1`)
* Tags: Includes [Virtual Tags](/tagging) created in Vantage for this provider. The following provider tags are automatically created by Vantage from Vercel data and are available for filtering and grouping:
* `vercel:region_name`: The human-readable region name (e.g., Washington, D.C., USA), allowing you to filter and group costs by region name.
* `vercel:ProjectName`: The Vercel project name, allowing you to filter and group costs by project.
## Vercel Commitments
If your Vercel account has contract commitments (typically associated with Enterprise plans), Vantage will automatically sync these commitments and display them on the [Commitments](/commitments) screen. Vercel commitments are synced daily and include details such as the commitment amount, term, purchase date, and expiration date.
## Active Resources
At this time, there are no active resources for Vercel within Vantage. Vercel billing data is exposed on a project/service basis and not on a per-resource basis.
# Cost Alerts
Source: https://docs.vantage.sh/cost_alerts
Set up automated cost alerts in Vantage to monitor spending changes with customizable thresholds.
Cost Alerts automatically detect and notify you of cost increases—whether by percentage or fixed amount—across customizable time periods, like day-over-day, month-over-month, or quarter-over-quarter. These alerts are based on each binned group within a Cost Report. At this time, only increases are supported for Cost Alerts.
You can receive notifications via email, Slack, Microsoft Teams, or Jira issues. Cost Alert email notifications display amounts using your workspace's configured [currency](/vantage_account#currency-conversion), including the correct currency symbol and formatting.
Cost Alerts are best for **gradual ramps, sustained growth, and any case where you know the exact threshold you want to monitor**. For unexpected single-day spikes that you didn't know to set a threshold for, use [Cost Anomaly Alerts](/cost_anomaly_alerts) instead. See [Anomaly Detection vs. Other Alert Types](/cost_anomaly_alerts#anomaly-detection-vs-other-alert-types) for a side-by-side comparison.
If you want to use Slack, Teams, or Jira, you will need to configure the corresponding integration with Vantage. See the [Slack](/slack), [Microsoft Teams](/microsoft_teams), or [Jira](/jira) integration documentation for details. For Slack and Microsoft Teams, you can create either a Slack integration or a Microsoft Teams integration, but not both. Once you have completed the integration steps, complete the below instructions to configure Cost Alerts.
## How Cost Alerts Work
Cost Alerts run after Vantage refreshes the Cost Report data associated with the alert. For each selected report, Vantage evaluates the report's filtered costs over the selected comparison interval and creates an alert event when a grouping crosses your configured threshold.
```mermaid theme={null}
flowchart TD
CostReport["Cost Report refreshes"] --> Groupings["Evaluate each report grouping"]
Groupings --> Threshold["Compare current interval to previous interval"]
Threshold --> AlertEvent["Create Cost Alert event"]
AlertEvent --> Annotation["Add Cost Report annotation"]
AlertEvent --> Notifications["Send configured external notifications"]
```
Important evaluation details:
* Alerts use the Cost Report's filters, settings, and current grouping. If the report is grouped by **Region**, Vantage evaluates each region independently.
* If a report is ungrouped, Vantage evaluates costs by provider and service.
* Percentage-based alerts trigger when the percentage increase meets or exceeds your threshold. If you configure a **Minimum Dollar Threshold**, the dollar increase must also meet that minimum.
* Dollar-based alerts trigger when the absolute increase meets the dollar threshold, including for new groupings that did not have previous-period spend.
* Percentage-based alerts do not trigger for new groupings that have no previous-period spend, because there is no baseline for calculating a percentage increase.
* Vantage ignores changes smaller than one cent to avoid alerts caused by rounding or precision changes.
To create or edit Cost Alerts, you need permission to create or edit cost alerts and access to the selected Cost Reports. See the [Permissions Reference](/rbac_permissions#notifications-and-alerts) for role details.
## Create a Cost Alert
Cost Alerts can be created in two ways—either directly from a Cost Report or via the Notifications page.
* **From a Cost Report:** From the top right of a report, click the ellipses button (**...**), then select **Create Cost Alert**.
* **From the Notifications page:** Click the bell icon from the top right of the console, which displays the Cost Alerts dashboard, then click **Configure Cost Alert**.
On the **Cost Alerts** screen:
Enter a **Title** for your alert.
For **Cost Change Threshold**, select **%** or **\$** and enter the dollar-based or percentage-based change threshold for the alert. Percentage thresholds accept values as low as 0.01%, so you can monitor sub-1% changes on high-spend reports.
For percentage-based alerts, you can also set an optional **Minimum Dollar Threshold**. When set, the alert will only trigger if the percentage threshold is exceeded *and* the dollar amount of the change meets the minimum. For example, you can alert on changes greater than 10%, but only when the change is at least \$50.
For **Comparison Interval**, select how you want Vantage to evaluate changes in cost over time. This determines the time periods that will be compared to detect changes. All timestamps of costs are in UTC.
* **Day over Day:** Compares today's costs to yesterday's. Useful for catching sharp, immediate changes.
* **Week over Week:** Compares the current week (Sunday to Saturday) to the previous one. Ideal for spotting trends in weekly cycles.
* **Month over Month:** Compares the current month (1st to end of month) to the previous month. Identify longer-term shifts.
* **Quarter over Quarter:** Compares costs across standard calendar quarters. Useful for high-level budget tracking and executive reporting.
Select the **Cost Report(s)** you want this alert to apply to. You can select up to 10 reports per alert.
If you create the alert from within a Cost Report, that report will be pre-selected here. You can still add up to 9 additional reports.
Select your notification preferences:
* **Email:** Select which Vantage users should receive alert emails.
* **Slack or Microsoft Teams:** Select the channels where alerts should be posted.
* **Jira:** Select the appropriate projects and provide any additional details required for issue creation.
* You can choose not to send external notifications. In this case, alerts will only appear as annotations within the selected Cost Reports. See the [View Cost Alerts](/cost_alerts#view-cost-alerts) section for details on annotations.
Click **Save Alert**.
## View Cost Alerts
Alerts are delivered as soon as Vantage updates the data for the Cost Report associated with your Cost Alert. When a Cost Alert is triggered, Vantage performs two actions:
* Sends any configured notifications to external services (email, Slack, Teams, or Jira).
* Adds an [annotation](/annotations#cost-alert-annotations) directly to the relevant Cost Report, shown in the image below as a pink line on the graph. When you click the line, the **Annotations** subpanel is displayed on the right with details about the alert. If you delete a Cost Alert or remove a Cost Report from it, any annotations linked to that alert will also be removed from the affected Cost Reports.
If your cost data is retroactively updated by a cloud provider and meets one of your alert criteria, it may trigger a retroactive alert. If an alert has already been created and retroactive cost data causes it to no longer be valid, Vantage will persist the annotation in the Cost Report.
Alerts are evaluated based on the groupings within a Cost Report:
* For example, if a report is grouped by **Region**, and you’ve set an alert to trigger on day-over-day changes of 15% or more, Vantage will evaluate each region individually.
* If your Cost Report is ungrouped, your Cost Alerts will be indexed based on provider (e.g., Azure) and service (e.g., Azure Storage).
* You will be alerted for new groupings in your Cost Report for any dollar-based Cost Alerts. You will not be alerted for new groupings for percent-based Cost Alerts.

In the above visual example, the cost for **eu-west-2** increased by 15%, and the corresponding alert is triggered. An annotation is added to the report showing:
* The alert title
* The grouping that triggered the alert (eu-west-2)
* The change amount (+15%)
* The comparison interval (day over day)
### View External Alert Notifications
External alert notifications include details about the alert, such as the Cost Alert title, the grouping that triggered the alert, the comparison interval, and the amount of change. Each notification also includes a direct link to the relevant Cost Report for further investigation.
Notifications display two date fields:
* **Detected On:** The date when Vantage detected and created the alert event. This may differ from the "Occurred On" date because cost data can be retroactively updated by cloud providers, or there may be a delay between when costs occur and when they're processed and available in Vantage for alert evaluation.
* **Occurred On:** The date when the cost change actually occurred (the date of the cost data that triggered the alert). This represents when the costs were accrued in your cloud provider.


## Best Practices for Cost Alerts
When setting up Cost Alerts, it’s important to configure them in a way that provides meaningful insights. Below is a table outlining common configurations that may lead to a high volume of alerts and suggestions on how to optimize them.
| **Alert Configuration** | **Potential Issue** | **Best-Practice Configuration** |
| - | - | - |
| Day-over-day alerts on volatile costs (e.g., on-demand compute costs) | Frequent notifications due to normal fluctuations | Use weekly or monthly evaluation periods instead to track stable trends |
| Connecting alerts to reports that filter on a very broad scope (e.g., all accounts, all services) | Potentially generates excessive alerts for each service or dimension, depending on how often your costs fluctuate | Narrow the scope of the Cost Report to specific accounts, regions, services, or Virtual Tags. Consider using longer-term evaluation periods |
| Low percentage thresholds (e.g., 0.01–10%) | Small fluctuations can trigger frequent alerts | Set thresholds at >10% to focus on meaningful changes, or add a minimum dollar threshold to filter out low-dollar fluctuations |
| Static dollar thresholds that are too low | Minor cost changes may trigger alerts | Configure alerts for significant cost shifts (e.g., >$500 instead of $50) |
By following these best practices, you can ensure that Cost Alerts provide actionable insights without receiving unnecessary notifications.
## Troubleshooting
Cloud providers can publish or revise billing data after the usage date. Vantage evaluates Cost Alerts when Cost Report data refreshes, so the **Detected On** date can be later than the **Occurred On** date. The Cost Report annotation appears on the date when the cost change occurred.
Dollar-based alerts compare the current interval's cost to the previous interval's cost. If a new grouping appears and its increase meets your dollar threshold, Vantage can trigger an alert even though that grouping did not previously appear on the report.
Percentage-based alerts need a previous-period cost to calculate the percentage increase. If the previous cost is zero or missing, Vantage does not create a percentage-based alert for that new grouping. Use a dollar-based Cost Alert if you want to catch new spend as soon as it appears.
If you set a **Minimum Dollar Threshold**, both conditions must be true: the percentage increase must meet the percentage threshold, and the dollar increase must meet the minimum dollar threshold. Vantage also ignores changes smaller than one cent.
Cost Alerts can be saved without external delivery channels. In that case, the alert event appears only as an annotation on the associated Cost Report. Add email recipients, Slack or Teams channels, or Jira delivery if you want external notifications.
## Cost Alerts Examples
Cost Alerts are most effective when they help you catch unexpected cost increases before they become budget issues. Below are a few example use cases, along with how to configure your Cost Reports and alerts for each scenario. Consider the following guidance when deciding between a percentage-based or dollar-based alert.
| **Alert Type** | **Use Case** |
| - | - |
| Percentage-Based Alerts | You're tracking lower-cost services where changes in spend may still indicate scaling, regressions, or misconfigurations. It can also be useful for automating detection of trends for your spend over longer durations. |
| Dollar-Based Alerts | Small fluctuations in usage could regularly trigger percentage-based alerts without reflecting real concern. Dollar-based thresholds help filter for material, static changes. |
### Percentage-Based Alerts
Use percentage-based alerts to spot relative changes in cost. For example, this type of alert can be useful when monitoring lower-spend resources that may not trigger a dollar-based alert, but are still scaling faster than expected. For example, you want to see any monthly percentage-based changes in data transfer, greater than 20%, for a production mobile app. You also want to avoid noisy alerts from small dollar fluctuations, so you set a minimum dollar threshold of \$50.
You set up the following Cost Report and corresponding alert:
* **Cost Report Filters:**
* Provider: AWS
* Category = EC2, Data Transfer
* Tags (either from your provider or [virtual tags](/tagging)): Environment = Production, Application = Mobile App
* **Cost Alert Config:**
* Change type = Percentage
* Threshold = 20%
* Minimum Dollar Threshold = \$50
* Comparison Interval = Month over Month
With this configuration, the alert will only trigger when data transfer costs increase by more than 20% *and* the dollar amount of the increase is at least $50. This prevents alerts from firing on small absolute changes—for example, a 25% increase from $10 to \$12.50 would not trigger the alert. When the alert does fire, a spike in data transfer costs could mean increased user traffic, but it might also indicate misconfigured services or traffic routing. Engineering can use this signal to check for inefficiencies or unintended data egress.
### Dollar-Based Alerts
Use dollar-based alerts for high-cost services where even small percentage changes represent substantial spend or where you need to be aware of material spend. For example, your team has a specific quarterly budget for storage. You want to be alerted weekly if S3 Storage increases by \$2,000 compared to the previous week.
You set up the following Cost Report and corresponding alert:
* **Cost Report Filters:**
* Provider: AWS
* Category = S3, Storage
* **Cost Alert Config:**
* Change type = Dollar
* Threshold = \$2,000
* Comparison Interval = Week over Week
S3 is typically a predictable storage cost. When the alert is triggered, this could indicate a failure to archive old data or a misconfigured data pipeline that is potentially duplicating files. By using Cost Alerts to catch these changes weekly, your team can take corrective action before costs keep accruing ongoing overages.
## Related References
* To compare Cost Alerts with anomaly detection, report notifications, Budget Alerts, and the FinOps Agent, see [Anomaly Detection vs. Other Alert Types](/cost_anomaly_alerts#anomaly-detection-vs-other-alert-types).
* To configure Jira delivery for Cost Alerts, see [Jira: Cost Alerts](/jira#cost-alerts).
* To manage Cost Alerts programmatically, see the [Vantage API reference](/api) and the [Terraform Cost Alert resource](/terraform_docs/resources/cost_alert).
* To create or inspect Cost Alerts with the Vantage MCP server, see [Vantage MCP](/vantage_mcp).
# Anomaly Detection
Source: https://docs.vantage.sh/cost_anomaly_alerts
Detect and alert on unusual cloud cost spikes with Vantage's machine learning–powered anomaly detection.
Cost anomalies notify teams of unexpected daily cost spikes so engineers can fix misconfigurations or runaway workloads before they become expensive. Vantage automatically detects anomalies on every [Cost Report](/cost_reports) and lets you send alerts via email, Slack, Microsoft Teams, or Jira.
Anomaly Detection is one of several ways Vantage notifies you about cost changes. For a side-by-side comparison with [Cost Alerts](/cost_alerts), [Report Notifications](/report_notifications), [Budget Alerts](/budgets#budget-alerts), and the [FinOps Agent](/vantage_finops_agent), see [Anomaly Detection vs. Other Alert Types](#anomaly-detection-vs-other-alert-types).
## How Anomaly Detection Works
Anomaly detection runs on every Cost Report in your account. For each report, Vantage:
1. Groups the report's filtered cost data into time series by **provider**, **service**, and **cost category** (for example, **AWS > Amazon EC2 > Data Transfer** or **Azure > Virtual Machines > Compute**).
2. Trains a machine learning forecast on each series using up to the most recent **6 months** of daily cost data for that report. (Newer accounts train on whatever history is available. Each series needs more than 12 days of data before it can be evaluated.)
3. Flags days where the actual cost exceeds the forecast's upper bound as candidate anomalies.
4. Applies noise filters to remove tiny or expected fluctuations (see [Noise Filters Applied to Candidates](#noise-filters-applied-to-candidates)).
5. Records each surviving anomaly on the Cost Report and, when configured, sends an external notification the first time the anomaly's trend exceeds your Alert Threshold.
```mermaid theme={null}
flowchart TD
Report[Cost Report's filtered daily costs]
Report --> Series["Group by series: provider × service × cost category"]
Series --> Forecast["ML forecast on up to 6 months"]
Forecast --> Upper{"Day exceeds forecast upper bound?"}
Upper -->|No| Normal[Not an anomaly]
Upper -->|Yes| Filters{"Passes all noise filters?"}
Filters -->|No| Suppressed[Suppressed]
Filters -->|Yes| Record[Anomaly recorded]
```
See [What Counts as an Anomaly](#what-counts-as-an-anomaly) for the exclusion and noise-filter rules.
To get started with cost anomaly detection and alerts, you can also view a video demo on [Vantage University](/vantage_university_observability) .
## What Counts as an Anomaly
Two things determine whether a daily cost spike becomes a recorded anomaly: whether the underlying line item is in scope for detection at all, and whether the candidate survives Vantage's noise filters. Both rules are intentional and uniform across all accounts to keep the anomalies list actionable rather than noisy.
### Excluded from Detection
To keep the model focused on usage signals, Vantage excludes a few categories of line items from detection entirely:
| Excluded | Why | Matched by |
| - | - | - |
| Marketplace charges across AWS, Azure, and GCP | Marketplace purchases are not usage-driven and would skew the forecast. | The `AWS Marketplace` and `Marketplace` category labels. |
| Datadog commitment line items | These are flat, predictable charges that obscure usage spikes. | The Datadog `Commitment` cost subcategory. |
| Reservation and Savings Plan fees, upfront purchases, and amortized fees | These are commitment-driven charges rather than usage signals. | The `Purchase`, `SavingsPlanRecurringFee`, `SavingsPlanUpfrontFee`, `Fee`, `RIFee`, and `AmortizedFee` charge types. |
Detection uses the same cost amount the report displays, with the excluded fee types above removed. Discounts, credits, refunds, tax, and amortization all follow the report's settings.
### Noise Filters Applied to Candidates
After the model identifies a candidate anomaly (a day where cost exceeds the forecast's upper bound), Vantage applies several noise filters before recording it:
| Filter | A candidate is suppressed when... |
| - | - |
| Static floor | The cost on the anomalous day is below **\$5**. |
| Report-level threshold | The cost on the anomalous day is below **0.5%** of the report's total daily cost. The threshold scales with the report's size, so the same dollar increase that surfaces on a narrow report may be suppressed on a broad one. |
| Recent average | The cost on the anomalous day is **not more than 20% above** the trailing 7-day average for that series (a series gradually trending up will not be flagged). |
| Not increasing day-over-day | The cost on the anomalous day is **not greater** than the previous day. |
| Back-to-back suppression | Another anomaly was already detected for the same (provider, service, cost category) series in the **previous 7 days**. |
| Insufficient history | The series has **12 days or fewer** of data in the training window. |
These filters mean that the same underlying cost spike can surface as an anomaly on a narrower Cost Report and be suppressed on a broader one. See the [FAQ](#frequently-asked-questions) for examples.
## Anomaly Detection vs. Other Alert Types
Vantage offers several ways to notify you about cost changes. Choose based on whether you want unsupervised outlier detection, fixed thresholds, or scheduled summaries.
| Feature | What it does | When it fires | Best for |
| - | - | - | - |
| **Cost Anomaly Alerts** | ML forecast per provider, service, and cost category on a Cost Report; flags days that exceed the forecast's upper bound. | After Vantage refreshes the report and detects the anomaly. | Catching unexpected, single-day spikes you didn't know to set a threshold for. |
| [Cost Alerts](/cost_alerts) | Fixed-threshold comparisons (day-over-day, week-over-week, month-over-month, quarter-over-quarter) per binned grouping on a Cost Report. | Whenever a grouping crosses your configured % or \$ threshold. | Gradual ramps, recurring patterns, or any case where you know the exact threshold you want to monitor. |
| [Report Notifications](/report_notifications) | Scheduled digests of Cost Reports or dashboards. | Daily, weekly, or monthly on a fixed schedule. | Routine spend reviews regardless of whether anything is anomalous. |
| [Budget Alerts](/budgets#budget-alerts) | Notify when actual spend reaches a percentage of a budget on its budget period. | When actual spend crosses the configured percentage. | Tracking spend against a target. |
| [FinOps Agent](/vantage_finops_agent) | On-demand AI investigation of a specific anomaly, cost report, or question. | When you trigger it (for example, by clicking **Investigate Anomaly** in a Slack notification). | Root-causing an alert after it fires, not scheduled detection. |
For a complete delivery matrix (which alert types support which channels), see [Alert Notifications](#alert-notifications) below.
## View Cost Anomalies
To view cost anomalies for a Cost Report, navigate to that report and select the **Anomalies** tab on the top left of the report.

Anomalies are considered **Active** for the first 7 days after they occur. Once that window passes, they automatically move to an **Archived** state. Historical anomalies remain visible in the Cost Report.
The **Anomaly Detected** column shows the date the cost anomaly occurred. Alerts are sent **only the first time** a given anomaly is detected. If the same (provider, service, cost category) series remains elevated for several days, you will not receive duplicate alerts in that window.
## Take Action on an Anomaly
From the **Anomalies** tab, click the link in the **Category** column to open the anomaly in its Cost Report.
The bar for the anomalous day is visually highlighted. Hover over it to view details. If Vantage identified a single resource as the likely cause, the resource is shown alongside the anomaly category (for example, *Compute for production-cluster*). When the Cost Report is grouped so that the attributed resource appears as a row, that row is also marked. In the top right of the report header, click **Manage Anomaly**.
Select one of the following actions:
* **Create an Issue**: Open a new [issue](/issues) pre-populated with a link back to this Cost Report and anomaly. Assign it to yourself or a teammate.
* **Mark as Archived**: Move the anomaly out of the Active list.
* **Ignore**: Remove the anomaly from the list entirely. You can provide optional feedback about why you ignored it.

**Ignoring, archiving, or creating an issue for an anomaly does not train, tune, or suppress the detection model.** The model has no feedback loop from these actions. Detection always re-runs on the report's filtered cost data within the last 6 months, with the excluded charge types and categories listed above removed.
### Resource Attribution
Vantage attempts to identify the resource responsible for an anomaly. When one is identified, the resource is appended to the anomaly's category (for example, *Compute for production-cluster*) and, if the Cost Report is grouped so that the resource appears as a row, that row is also marked. Attribution is best-effort:
* Vantage attributes **at most one** resource per anomaly. The resource is selected when a single resource accounts for **more than 50%** of the cost change in the affected (provider, service, cost category) series.
* When no single resource exceeds the 50% threshold, no resource is attributed. The anomaly may instead be caused by multiple resources, by a category without resource-level granularity, or by a provider that does not expose per-resource identifiers.
* When a resource is attributed, it is a directional starting point for investigation rather than a definitive root cause. Inspect groupings and drilldowns on the Cost Report to confirm.
## Configure Cost Anomaly Alerts
Anomaly alerts can be delivered to email, Slack, Microsoft Teams, and Jira. To use Slack, Teams, or Jira, first configure the [Slack](/slack), [Microsoft Teams](/microsoft_teams), or [Jira](/jira) integration. (Slack and Microsoft Teams are mutually exclusive: you can connect one or the other, not both.)
To receive alerts for any detected cost anomalies on a Cost Report:
From the top of the **Anomalies** tab on a Cost Report, click **Configure Alert**.
Select email recipients from your Vantage users.
Enter an **Alert Threshold** (dollar amount). See [Understanding the Alert Threshold](#understanding-the-alert-threshold) below.
**(Optional)** If you have Slack, Microsoft Teams, or Jira configured, select channels or a Jira project in the corresponding fields.
Click **Save**.
To change recipients or the threshold, click **Configure Alert** again and update the settings.
At this time, you cannot configure an anomaly alert for a specific [resource](/active_resources). To monitor a particular workload, create a Cost Report filtered to its tag, account, region, or service and configure an alert on that report.
### Understanding the Alert Threshold
The **Alert Threshold** is a notification threshold, not a detection sensitivity. It does not change which anomalies Vantage detects. It only controls which detected anomalies are sent externally.
Vantage compares the threshold against an anomaly's **trend** value, where:
```
trend = anomaly amount − trailing 7-day average for that series
```
If `trend >= threshold`, the alert is delivered to the configured recipients. Anomalies below the threshold are still recorded on the **Anomalies** tab. They just don't fire an external notification.
Two threshold behaviors to be aware of:
* **A blank Alert Threshold has no filtering effect.** If you leave the field empty when you configure an alert, Vantage sends a notification for **every** detected anomaly with a positive trend, which can result in a high volume of alerts on a busy Cost Report. Enter a dollar amount that represents a deviation worth acting on.
* **Lowering the threshold afterward does not backfill notifications.** The threshold is evaluated when an anomaly is first processed for alerting. Anomalies that were already evaluated and skipped will not be sent if you later lower the threshold. Only newly detected anomalies are compared against the updated value.
## Alert Notifications
When an anomaly fires above your Alert Threshold, Vantage sends a single notification per delivery channel. Notifications include the report title, the affected service and cost category, and the trend amount. Notifications also display amounts in your workspace's configured [currency](/vantage_account#currency-conversion).
### Delivery Channels
Cost Anomaly Alerts support email, Slack, Microsoft Teams, and Jira. The matrix below also covers the other Vantage alert types so you can quickly compare.
| Alert Type | Email | Slack | Microsoft Teams | Jira | Configured From |
| - | :-: | :-: | :-: | :-: | - |
| [Cost Anomaly Alerts](/cost_anomaly_alerts) | Yes | Yes | Yes | Yes | A Cost Report's **Anomalies** tab > **Configure Alert** |
| [Cost Alerts](/cost_alerts) | Yes | Yes | Yes | Yes | A Cost Report's **...** menu > **Create Cost Alert**, or **Notifications** > **Cost Alerts** > **Configure Cost Alert** |
| [Budget Alerts](/budgets#budget-alerts) | Yes | Yes | Yes | Yes | A Budget's **Manage** tab > **Manage Alerts** > **Configure Alert** |
| [Report Notifications](/report_notifications) (Cost Reports) | Yes | Yes | Yes | — | The **Notifications** page > **New Notification** > **Cost Report Notification**, or a Cost Report's **...** menu > **Create Report Notification** |
| [Dashboard Notifications](/report_notifications#set-up-dashboard-notifications) | Yes | — | — | — | The **Notifications** page > **New Notification** > **Dashboard Notification** |
Slack and Microsoft Teams are mutually exclusive at the integration level: you can connect either Slack or Microsoft Teams, not both. See the [Slack](/slack) and [Microsoft Teams](/microsoft_teams) integration docs for setup. Jira delivery requires the [Jira integration](/jira).
### Detected On vs. Occurred On
Slack notifications surface two dates:
* **Occurred On**: the date the costs were accrued in your cloud provider.
* **Detected On**: the date Vantage detected the anomaly.
These dates can differ when:
* The cloud provider released or updated the billing data for **Occurred On** after the fact. Some providers refine the previous day's data over the next 24–48 hours.
* A series only became anomalous once additional history filled in around it. The model evaluates each day in the context of the surrounding days; a spike on day N may not look anomalous until day N+2's data is available.
If a Slack alert arrives several days after the Occurred On date, that's almost always one of the two scenarios above rather than a delivery delay.
## Investigate Anomalies with the FinOps Agent
If the [FinOps Agent](/vantage_finops_agent) is enabled for your account, anomaly notifications sent to Slack include an **Investigate Anomaly** button. Clicking it starts a guided investigation: the Agent fetches the anomaly, queries the surrounding daily costs, gathers resource details, and posts a structured summary back in the Slack thread.
Vantage Slack notifications also include the report token and anomaly tokens as metadata, so the Agent has full context when responding to follow-up questions in the same thread. See [Investigate Cost Anomalies](/vantage_finops_agent#investigate-cost-anomalies) for details.
## Frequently Asked Questions
The default All Resources Cost Report covers your full account spend. The detector's [report-level noise threshold](#what-counts-as-an-anomaly) is **0.5% of the report's total daily cost**, which means a service-level spike that is significant on its own can fall below the threshold once it's compared to your entire daily cloud bill.
If you want anomaly coverage for a specific provider, service, tag, account, or team, create a narrower Cost Report scoped to those filters and configure an alert on that report. Each report runs its own detection, so the same spike that's suppressed on All Resources can surface on a focused report.
A few reasons a narrow Cost Report can fail to flag a spike that looks obvious by eye:
* **The series has limited history in the report's scope:** Each (provider, service, cost category) series needs more than 12 days of data within the report's 6-month training window to be evaluated.
* **Prior spikes have widened the forecast's upper bound:** If the same series spiked previously, the forecast's upper bound is wider in response to that volatility, so a new spike of similar size can fall inside the widened range without being flagged. Recurring monthly or quarterly spikes can become "expected" to the model.
* **One of the [noise filters](#what-counts-as-an-anomaly) suppressed it:** Most commonly, the new value is not more than 20% above the trailing 7-day average, the day-over-day change wasn't positive, or another anomaly was already detected in the previous 7 days.
If you believe a real anomaly is being missed, [contact support](mailto:support@vantage.sh) with the report token and the affected date.
Anomaly Detection is built around **daily outliers**. If costs ramp up smoothly over weeks or months without any single day standing out, no day on its own is anomalous and the detector does not flag the trend.
For gradual ramps and sustained growth, [Cost Alerts](/cost_alerts) are the right tool. Cost Alerts let you compare day-over-day, week-over-week, month-over-month, or quarter-over-quarter changes against a percentage or dollar threshold you choose.
The anomaly amount is the net cost change **within the Cost Report's filters**. A spike that contributes \$3,000 to one report can contribute \$8 to another report whose filters exclude most of the underlying costs. Both numbers are correct for their respective scope.
If you follow an anomaly link and the amount looks unexpected, check whether you're viewing it on the report it was detected on or on a different report. Anomalies are scoped to the report that detected them.
Anomaly detection is not perfectly deterministic. Detection runs on its own schedule per Cost Report, and two runs that fall on different days see slightly different cost windows—one extra day at the end and one fewer day at the start—which can shift what each run considers anomalous.
For two workspaces with the same integrations, expect minor day-by-day differences in counts. The underlying anomalies surface in both reports over time.
Each anomaly is evaluated in isolation against your Alert Threshold. Vantage does not sum across consecutive days. If a \$60 anomaly is detected on day 1 with a \$100 threshold, no alert fires. If costs continue to climb on day 2, back-to-back suppression typically prevents a new anomaly from being detected in the same series for 7 days.
For threshold-based monitoring of sustained cost growth, use [Cost Alerts](/cost_alerts) with a comparison interval (day-over-day, week-over-week, month-over-month, or quarter-over-quarter).
The Alert Threshold is evaluated when an anomaly is first processed for alerting. Once a detected anomaly has been evaluated against the threshold—even if it was below the threshold and no notification was sent—it is marked as processed and will not be re-evaluated.
Lowering the threshold only affects anomalies that are **newly detected** after the change. To monitor sustained cost growth that may have already been detected, use a [Cost Alert](/cost_alerts) with a comparison interval instead.
No. The detection model has no feedback loop from these actions. Ignoring or archiving an anomaly only changes what you see on the **Anomalies** tab; the model will still evaluate the same (provider, service, cost category) series with the same logic the next time detection runs.
A series's recent variance directly affects how wide the forecast's expected range is. When the same series has spiked repeatedly at a similar magnitude, the forecast's upper bound widens to reflect that variability, and a new spike of similar size can fall inside the wider range without being flagged as an outlier.
If you want to monitor a recurring increase regardless of whether the model considers it expected, use a [Cost Alert](/cost_alerts) with a month-over-month threshold.
Anomaly detection trains on up to the most recent **6 months** of the Cost Report's filtered data, regardless of how much history you have imported. Newer accounts train on whatever is available, and each (provider, service, cost category) series needs more than 12 days of data to be evaluated.
Vantage preserves anomaly history within your account's cost retention window so older anomalies remain searchable on the Cost Report. Two cleanup rules apply:
* **Recent anomalies that are no longer detected are removed.** When detection re-runs, anomalies from roughly the last 3 months that are no longer present in the report's data (for example, after a backfill correction or filter change) are deleted. Older anomalies are preserved as history.
* **Anomalies past your account's cost retention window are deleted.** Anything outside the retention window is removed during cleanup.
## Troubleshooting
A few common causes:
* **The spike is suppressed by a [noise filter](#what-counts-as-an-anomaly):** Most commonly, the spike is below \$5, below 0.5% of the report's total daily cost, or not more than 20% above the trailing 7-day average for that series.
* **The series doesn't have enough history:** A series needs more than 12 days of data within the 6-month training window before it is evaluated.
* **The report is broad and the spike is small relative to the total.** Create a narrower Cost Report scoped to the affected provider, service, tag, or account, and check the Anomalies tab on that report.
* **The series is already volatile:** Past spikes or high variance widen the forecast's expected range, so a new spike can fall inside the wider range and not register as an outlier.
In Slack, compare the **Detected On** and **Occurred On** dates in the notification (see [Detected On vs. Occurred On](#detected-on-vs-occurred-on) for why they can differ). Microsoft Teams notifications show a single date, so this comparison isn't available there. In both cases, the delay is most often caused by the underlying provider releasing or updating billing data after the fact, or by a series only becoming anomalous once additional surrounding days were available to evaluate.
If you believe the delay is not explained by either case, [contact support](mailto:support@vantage.sh) with the report token, anomaly date, and the date the alert was received.
Vantage attributes at most one resource per anomaly, and only when that resource accounts for more than 50% of the cost change in the affected (provider, service, cost category) series. When multiple resources contribute, or when the cost category contains resources moving in opposite directions, the heuristic can attribute a misleading resource (or none).
Treat the attributed resource as a starting point. Use the Cost Report's groupings and drilldowns (for example, group by resource ID, region, or a tag) to confirm what actually drove the spike.
Anomalies are point-in-time records. The link can become stale when:
* The Cost Report's filters were changed after the anomaly was detected.
* A [Virtual Tag](/tagging) that the report depends on was updated.
* The underlying provider data was reprocessed or corrected.
The anomaly was valid at the time it was detected. To investigate a current spike, open the Cost Report directly and inspect the relevant date range.
The alert amount is the anomaly's **trend** value: the cost on the anomalous day minus the trailing 7-day average for that series. It is not the day-over-day delta and it is not the total cost for the day. Use it as a measure of how much the day deviated from recent normal, not as the spike's absolute size.
If you want to monitor the day-over-day or week-over-week dollar increase directly, use a [Cost Alert](/cost_alerts) instead.
# Cost Recommendations
Source: https://docs.vantage.sh/cost_recommendations
Get personalized cost optimization recommendations from Vantage to reduce cloud spending across providers.
Vantage monitors your connected providers and shows cost recommendations as your infrastructure evolves and changes. You can implement these recommendations to lower your bill.
Cost recommendations are currently available for AWS, Azure, GCP, Datadog, and Kubernetes.
## Types of Recommendations
Your available recommendations depend on what services and resources are running in your account. In general, there are three types of recommendations:
Based on your connected providers, enriched in Vantage
Created by Vantage using proprietary analysis
Recommends migrating to alternative providers
## View Cost Recommendations
From the top navigation, click **Recommendations**.
The screen displays tabs for viewing recommendations: **Ready for Review**, **In Progress**, **Completed**, and **Archived**. See the [Recommendation Tabs](#recommendation-tabs) section below for details about each tab.
At the top of the page, summary widgets display key metrics about your recommendations. See the [Recommendations Summary Widgets](#recommendations-summary-widgets) section below for details.
In addition, you'll see filters for Date Range, Account, Billing Account, Region, Provider, [Tag](/tagging), and Minimum Savings (to show only recommendations above a monthly savings threshold).
* Select a filter and choose one or more options to filter the results.
* Click **Reset Filter** on any filter dropdown to remove your current filter.
When you apply filters to create a specific view of recommendations, the URL updates to reflect those filters. You can share this URL with team members, and they will see the same filtered view when they access it.
Recommendation categories are shown in a list format, with each category displaying:
* The number of associated resources (Recommendation Count)
* The total potential savings if you act on all resources for that recommendation
Financial commitment recommendations, such as AWS Savings Plans, AWS Reserved Instances, and Datadog Commitments, do not display recommendation counts since they are not based on individual resources.
At the top of the page, you can save your current filter configuration as a saved view for quick access later. See the [Saved Views](#saved-views) section below for details.
### Recommendations Summary Widgets
At the top of the Cost Recommendations page, summary widgets display key metrics about your recommendations.
#### Potential Savings
The **Potential Savings** widget shows the total monthly savings amount if you implement all active recommendations. This value is calculated by summing the potential savings from each individual recommendation across all recommendation types.
The widget is displayed only when the total potential savings exceeds \$5 per month.
#### Savings Rate
When available, a **Savings Rate** badge appears below the Potential Savings value, showing the percentage of your previous month's tracked spend that could be saved by implementing all active recommendations. This is calculated by dividing the total potential savings by your organization's previous month's tracked spend.
$$
\text{Savings Rate} = \frac{\text{Potential Savings}}{\text{Previous Month's Tracked Spend}} \times 100\%
$$
The savings rate is only displayed when it provides meaningful context. It's hidden if:
* The rate exceeds 90% (indicating the previous month's spend may not be representative of current spend)
* The rate is below 5% and total savings are less than \$20,000
#### Savings Realized
The **Savings Realized** widget shows the total savings that have been realized from Autopilot-managed financial commitments (AWS Compute Savings Plans and Reserved Instances). This metric calculates the difference between what you would have paid for on-demand usage versus what you actually paid for the commitments managed through Autopilot, providing a cumulative view of savings over time.
The Savings Realized widget is only displayed when the realized savings amount is greater than \$0.
#### Daily Recommendation Count Chart
A bar chart displays the number of recommendations detected each day over the selected time period. This visualization helps you understand when new recommendations were identified and track trends over time.
The chart automatically adjusts the level of detail based on the available space. When the window is resized to a smaller size or when viewing longer time periods, the chart groups multiple days together into buckets. For example, instead of showing individual days, it may display "85 recommendations across 2 days" for a specific date range.
You can click any bar in the chart to filter the recommendations list below, showing only recommendations detected during that date or date range. If you click a bar representing a single day, the list filters to that day. If you click a bar representing multiple days (a bucket), the list filters to that date range. This makes it easy to focus on recommendations from a specific time period.
### Recommendation Tabs
The Recommendations page organizes recommendations into different tabs based on their status.
The **Ready for Review** tab (default view) displays all active recommendations that are available for you to review and act upon. These are recommendations that have been identified but have not yet been approved or archived.
The **In Progress** tab shows financial commitment recommendations (e.g., AWS Savings Plans, RDS Reserved Instances, etc.) that you have approved to be purchased by Vantage through [Autopilot](/autopilot), but the purchase has not yet been completed.
When you approve a financial commitment recommendation in Autopilot, it moves from **Ready for Review** to **In Progress**. The recommendation remains in this tab while Vantage processes the purchase on your behalf. Each recommendation in this tab displays:
* Monthly savings amount
* Recommendation details (instance type, region, quantity, etc.)
* Approver name
* Date approved
The **Completed** tab shows financial commitment recommendations that have been successfully purchased (or where the purchase attempt failed) through Autopilot. Once a recommendation in the **In Progress** tab has been purchased by Vantage, it moves to the **Completed** tab.
Each recommendation in this tab displays the same information as the In Progress tab, allowing you to track which recommendations have been fully processed and are now active in your AWS account.
The **Archived** tab displays recommendations that have been archived. Archived recommendations are excluded from the total savings potential displayed at the top of the Recommendations page. See the [Archive Recommendations](#archive-recommendations) section below for details on how to archive recommendations.
### Saved Views
Saved Views allow you to save and quickly access specific filter configurations on the Recommendations page. This makes it easy to return to commonly used views without manually reapplying filters each time.
#### Default View
The **All Recommendations** view is the default view that displays all recommendations without any filters applied. This view cannot be deleted, and it's always available in the view selector.
#### Create a Saved View
Apply the filters you want to save (Date Range, Account, Billing Account, Region, Provider, and/or Tag).
From the top right, click **Save As New**.
Enter a name for your saved view in the dialog that appears, then click **Save**.
You'll be redirected to your newly saved view, which will display the name you entered in the view selector.
#### Navigate Between Saved Views
At the top of the Recommendations page, click the view selector dropdown to see all available views.
Select the view you want to access from the list. The page will update to show recommendations with that view's saved filter configuration.
To return to the default view, select **All Recommendations** from the dropdown.
You can search for saved views by typing in the view selector dropdown. This is helpful when you have many saved views.
#### Modify Filters on a Saved View
When you're viewing a saved view, you can modify the filters to temporarily change what's displayed. When you make changes, the **Save** button becomes enabled, allowing you to:
* **Save changes to the current view:** Click **Save** to update the saved view with your current filter configuration.
* **Save as a new view:** Click the dropdown arrow next to **Save** and select **Save As New** to create a new saved view with the current filters, leaving the original view unchanged.
If you navigate away from a saved view without saving your changes, those changes will be lost and the view will return to its saved filter configuration.
#### Add Saved Recommendation Views to Dashboards
You can add saved recommendation views to [dashboards](/dashboards) as widgets to visualize your cost optimization recommendations alongside other cost data. Saved recommendation views can be displayed as either charts or tables on dashboards. See the [Dashboards](/dashboards) documentation for more information on adding widgets to dashboards.
The **All Recommendations** default view cannot be added to dashboards. You must create a saved view first before you can add it to a dashboard as a widget.
### View Recommendation Categories
For recommendation categories, you can take the following actions:
* **View individual resources:** If a recommendation category includes multiple resources, click the category tile to expand and view details for each resource. Each resource shows the detection date, resource-specific savings, and a description of the recommended remediation action. Click a resource link to view its detailed [Active Resource](/active_resources) view.
When you navigate to an Active Resource Report from a filtered view of the Recommendations page, your filters are applied to the Active Resource view as well, with the exception of Date Detected filters. Note that Active Resource Reports do not respect the Archived status of recommendations, so all resources are shown regardless of whether they are archived.
* **View Resource Report:** For recommendations with associated resources, the **View Resource Report** button is displayed on the recommendation category tile. Click this button to see a Resource Report that includes all affected resources. Each resource is listed with the past 30 days of accrued costs, savings if you follow the recommendation, and the recommended action. Additional metadata is also displayed. Specific remediation steps are provided at the top of the Resource Report in a recommendation card. This card contains a description of the recommendation and a remediation workflow, which can include CLI commands, links to provider console actions, a list of manual steps, and references to relevant Vantage blogs. Vantage also provides additional context on recommendation Resource Reports by displaying custom metadata columns relevant to the recommendation. CLI commands can be copied and run directly in your terminal to act on the recommendation.
* **View in Autopilot:** For some recommendations (such as financial commitments, like Savings Plans, Reserved Instances, or cross-provider migration recommendations), the **View in Autopilot** button is displayed instead. Click this button to view the recommendation details in Autopilot.
* **Details:** For financial commitment recommendations (Reserved Instances for RDS, Redshift, ElastiCache, and OpenSearch; Compute Savings Plans; and Database Savings Plans), a **View Details** button is displayed on individual recommendation items. Click this button to open a slideout panel that provides detailed information about the recommendation, including:
* Instance details (instance type, region, adjustable number of instances) for Reserved Instances, or commitment details (hourly commitment, term length, payment type, savings percentage) for Savings Plans
* Status badge and monthly savings amount
* Date the recommendation was detected
* Coverage history chart showing On-Demand usage versus committed usage over the past 60 days (Reserved Instances and Compute Savings Plans)
* [Coverage level options](/autopilot#review-coverage-recommendations) for Savings Plans, allowing you to select a coverage level based on your risk tolerance
* Purchase options table displaying available term lengths, payment types, upfront costs, and monthly savings for each option (Reserved Instances)
* Ability to approve purchases directly from the slideout (when using the [FinOps Agent](/vantage_finops_agent))
* Ability to archive the recommendation
The slideout supports deep linking, allowing you to share direct links to specific recommendations. When you open a recommendation's details, the URL updates to include the recommendation token, making it easy to bookmark or share specific recommendations with your team.
Slideouts for Compute Savings Plans and Database Savings Plans are disabled if you do not have Autopilot or the FinOps Agent enabled. When disabled, hovering over the **View Details** button displays a tooltip indicating that Autopilot or the FinOps Agent must be enabled to view the recommendation details.
Other recommendations may not display a button if they have no associated active resources and no Autopilot link. In these cases, the recommendation description may contain links to the [Cloud Cost Handbook](https://handbook.vantage.sh/) for additional information. You can also use the archive functionality to manage the recommendation.
### Archive Recommendations
To archive recommendations, you have two options:
* **Archive an entire recommendation set:** Click the **Archive** icon (arrow pointing down) at the end of the recommendation category tile. This archives all recommendations in that set (e.g., all identified Kubernetes Workload Rightsizing recommendations).
* **Archive a specific resource recommendation:** Expand the recommendation category tile and click the **Archive** icon next to that resource.
Archived recommendations are moved to the **Archived** tab. Archived recommendations are excluded from the total savings potential displayed at the top of the Recommendations page. Only active recommendations contribute to the savings metrics.
You must be an Organization Owner, Integration Owner, or Organization Editor to archive recommendations. See the [Permissions Reference](/rbac_permissions) for more information about permissions.
## Frequently Asked Questions
If you are currently on a trial, the specific recommendations are blurred; however, the total amount of potential savings is displayed. After you activate a Vantage subscription, these recommendations are fully visible. As you make changes to your infrastructure, the recommendations are automatically updated. Recommendations are refreshed once a day.
Recommendations are updated daily based on your resource usage patterns and configurations. The "Date Detected" field shows when each specific recommendation was first identified.
Date Detected reflects when Vantage first identified the specific recommendation type for a resource. The date remains unchanged if only the savings amount changes while the recommendation type stays the same. However, if the recommendation type changes (for example, from rightsizing to deletion), the Date Detected updates to reflect when the new recommendation was first detected.
As an example, you have a GP3 EBS volume that receives a rightsizing recommendation on day 0. On day 1, the recommended throughput decreases, but it's still a rightsizing recommendation, so the Date Detected remains day 0. On day 7, Vantage detects that this volume is now idle and recommends deletion instead. The Date Detected updates to day 7 to reflect when the deletion recommendation was first detected.
Vantage started tracking detection date for any recommendation that was not tracked previously. Examples of this include:
* DynamoDB Provisioned Capacity Mode
* EBS Generational Modernization
* CloudWatch Log Retention
* S3 Intelligent Tiering Recommendations
* Azure Unattached Disk
* Unused Datadog Metrics
Each of these recommendations will have launch dates based on when Vantage added Date Detected to these resources in October 2025.
There is no limit to how long recommendations will be retained. As long as the recommendation is valid, it will be retained indefinitely.
If a recommendation is no longer valid, Vantage will remove it from the Recommendations page, regardless of whether it is a currently active recommendation or an archived recommendation.
Filtering recommendations helps you focus on specific subsets of your infrastructure. Use filters to:
* **Filter by Tag:** Focus on recommendations for resources tagged with specific values, such as filtering by `environment=production` to see only production recommendations, or by `team=engineering` to view recommendations relevant to a specific team. This is particularly useful for organizations with multiple teams, projects, or environments, allowing you to prioritize recommendations based on business context.
* **Filter by Provider, Account, or Region:** Narrow recommendations to specific cloud providers, accounts, or regions to align with your team's responsibilities or focus areas.
* **Filter by Date Range:** Review recommendations detected within a specific time period to track new optimization opportunities or review historical recommendations.
Combining multiple filters allows you to create highly targeted views of recommendations, making it easier to prioritize and act on cost optimization opportunities that are most relevant to your current needs.
Some AWS recommendations depend on [AWS Compute Optimizer](https://docs.aws.amazon.com/compute-optimizer/latest/ug/what-is-compute-optimizer.html). To surface these recommendations in Vantage, enable Compute Optimizer directly in AWS for the account you connected to Vantage. If you use AWS Organizations, you can opt in from the management account and include all member accounts.
After Compute Optimizer is enabled, AWS needs enough CloudWatch metric data and resource-specific information to generate recommendations. It can take up to 24 hours after opt-in, and recommendations appear only for resources that meet AWS's [Compute Optimizer resource requirements](https://docs.aws.amazon.com/compute-optimizer/latest/ug/requirements.html).
## Provider-Specific Recommendations
The recommendations that are available for [AWS](/cost_recommendations#aws-recommendations), [Azure](/cost_recommendations#azure-recommendations), [GCP](/cost_recommendations#gcp-recommendations), [Datadog](/cost_recommendations#datadog-recommendations), [Cloudflare](/cost_recommendations#cloudflare-recommendations), and [Kubernetes](/cost_recommendations#kubernetes-rightsizing-recommendations) in Vantage are based on the granularity of data exposed by each provider. Notes for these providers are provided below.
### AWS Recommendations
Vantage provides comprehensive cost optimization recommendations for AWS across multiple categories including financial commitments, rightsizing, idle resource identification, storage optimizations, generational upgrades, extended support management, and cross-provider migration opportunities. Click on each category below to view all available recommendation types.
To surface additional AWS rightsizing and idle recommendations in Vantage, enable [AWS Compute Optimizer](https://docs.aws.amazon.com/compute-optimizer/latest/ug/what-is-compute-optimizer.html) directly in AWS. If you use AWS Organizations, you can opt in from the management account and include all member accounts. After opt-in, AWS needs enough usage metrics to generate recommendations, and recommendations may take up to 24 hours to appear.
Vantage identifies opportunities to reduce costs through AWS financial commitments including Savings Plans and Reserved Instances across multiple services.
By default, Vantage will use 1 year, No Upfront as the purchase configuration for Reserved Instances and Savings Plans. If you have set a [default Savings Plan configuration](/autopilot#configuration-screen) using Autopilot, Vantage will override previous configurations and use this for your recommendations.
| Recommendation Type | Description |
| - | - |
| Compute Savings Plan | Vantage will look at your AWS infrastructure on a weekly basis and provide Savings Plan recommendations tailored to your actual usage of EC2, Fargate, and Lambda. |
| Database Savings Plan | Vantage analyzes your database usage across Amazon RDS, Aurora, DynamoDB, ElastiCache (Valkey), DocumentDB, Neptune, Keyspaces, Timestream, and AWS Database Migration Service to provide Database Savings Plan recommendations. Database Savings Plans automatically apply savings across a broad range of managed database services, regardless of instance family, size, engine, or region, delivering up to \~35% cost reduction for serverless workloads and meaningful savings on provisioned database usage. Database Savings Plans are only available with 1-year terms. |
| RDS Reserved Instance | Vantage will recommend Reserved Instances for RDS with specific Reserved Instances to purchase. |
| ElastiCache Reserved Instance | Vantage will recommend Reserved Instances for ElastiCache with specific Reserved Instances to purchase. |
| OpenSearch Reserved Instance | Vantage will recommend Reserved Instances for OpenSearch with specific Reserved Instances to purchase. |
| Redshift Reserved Instance | Vantage will recommend Reserved Instances for Redshift with specific Reserved Instances to purchase. |
| DynamoDB Reserved Capacity | Vantage will recommend purchasing DynamoDB Reserved Capacity for better savings on DynamoDB usage. |
| Unused AWS Commitments | Vantage will identify unused financial commitments, such as Reserved Instances or Savings Plans that are not being utilized. |
Vantage surfaces AWS Compute Optimizer recommendations for over-provisioned compute, storage, database, and serverless resources that can be rightsized for cost savings while maintaining performance.
| Recommendation Type | Description |
| - | - |
| Amazon EC2 Rightsizing | Vantage surfaces AWS Compute Optimizer recommendations for EC2 instances that can be rightsized to offer savings. See more information below. |
| EBS Volume Rightsizing | Vantage surfaces AWS Compute Optimizer recommendations for EBS volumes that can be rightsized to offer savings. |
| Lambda Function Rightsizing | Vantage surfaces AWS Compute Optimizer recommendations for Lambda functions that can be rightsized to offer savings. |
| ECS Task Rightsizing | Vantage surfaces AWS Compute Optimizer recommendations for ECS tasks that can be rightsized to offer savings. |
| RDS Instance Rightsizing | Vantage surfaces AWS Compute Optimizer recommendations for RDS instances that can be rightsized to offer savings. |
Vantage identifies unused or idle resources that are incurring costs without providing value, helping you clean up unnecessary infrastructure. Some idle resource recommendations are sourced from AWS Compute Optimizer when it is enabled.
| Recommendation Type | Description |
| - | - |
| Idle EC2 Instances | Vantage surfaces AWS Compute Optimizer recommendations for EC2 instances that are idle and can be stopped or terminated. |
| Idle RDS Instances | Vantage surfaces AWS Compute Optimizer recommendations for RDS instances that are idle and can be stopped or terminated. |
| Idle or Unattached EBS Volumes | Vantage surfaces AWS Compute Optimizer recommendations for EBS volumes that are idle or not attached to any instance. |
| Idle ECS Services | Vantage surfaces AWS Compute Optimizer recommendations for ECS services on Fargate that are idle and can be removed. |
| Unattached AWS IP Addresses | Vantage will identify Elastic IP addresses that are not attached to any resource. |
| Idle NAT Gateway | Vantage surfaces AWS Compute Optimizer recommendations for NAT Gateways that are idle and can be removed. |
| Unused Amazon Workspace | Vantage will identify Amazon Workspaces that are unused. |
| Stranded Amazon Workspace | Vantage will identify Amazon Workspaces that are stranded and can be cleaned up. |
| Stale EBS Snapshot | Vantage will identify EBS snapshots older than 60 days that can be deleted to reduce storage costs. |
Vantage recommends storage tier optimizations and modernization opportunities to reduce storage costs while maintaining data accessibility.
| Recommendation Type | Description |
| - | - |
| EBS Modernization | Vantage will identify EBS volumes using GP2 that can be migrated to GP3 for cost savings. |
| Transition Amazon S3 Buckets to Intelligent Tiering | Vantage will identify S3 buckets that can benefit from Intelligent-Tiering to reduce storage costs. See the [S3 Intelligent-Tiering Recommendations](#s3-intelligent-tiering-recommendations) section for details. |
Vantage identifies instances running on older generations that can be upgraded to newer generations for better performance and cost efficiency.
| Recommendation Type | Description |
| - | - |
| EC2 Generational Upgrade | Vantage will identify EC2 instances that can be upgraded to newer generations for better performance and cost efficiency. |
| RDS Generational Upgrade | Vantage will identify RDS instances that can be upgraded to newer generations for better performance and cost efficiency. |
| OpenSearch Generational Upgrade | Vantage will identify OpenSearch instances that can be upgraded to newer generations for better performance and cost efficiency. |
Vantage identifies resources currently incurring extended support costs or approaching extended support windows, helping you plan for upgrades or migrations.
| Recommendation Type | Description |
| - | - |
| EKS Extended Support | Vantage will identify EKS clusters that are currently incurring extended support costs. |
| EKS Upcoming Extended Support | Vantage will identify EKS clusters that will enter extended support within the next three months. |
| ElastiCache Extended Support | Vantage will identify ElastiCache for Redis clusters that are currently incurring extended support costs. |
| ElastiCache Upcoming Extended Support | Vantage will identify ElastiCache for Redis clusters that will enter extended support within the next three months. |
| OpenSearch Extended Support | Vantage will identify OpenSearch/Elasticsearch domains that are currently incurring extended support costs. |
| OpenSearch Upcoming Extended Support | Vantage will identify OpenSearch/Elasticsearch domains that will enter extended support within the next three months. |
| RDS Extended Support | Vantage will identify RDS instances that are currently incurring extended support costs. |
| RDS Upcoming Extended Support | Vantage will identify RDS instances that will enter extended support within the next three months. |
Vantage identifies opportunities to implement lifecycle policies that automatically manage resource retention and reduce long-term storage costs.
| Recommendation Type | Description |
| - | - |
| CloudWatch Log Retention | Vantage will identify CloudWatch log groups that can benefit from retention policies to reduce costs. |
#### Rightsizing Recommendations
If you have resources that are over-allocated in terms of vCPU and GB of RAM, you may be paying more than needed. Rightsizing recommendations can help you save significantly by identifying rightsizing opportunities and providing specific reasons to rightsize, such as over-provisioned CPU. Vantage surfaces AWS Compute Optimizer rightsizing recommendations for EC2, RDS, EBS, ECS, and Lambda resources. Rather than providing a single suggestion, Vantage shows several viable rightsizing options for a resource, each with projected savings and utilization tradeoffs. This allows teams to select the most appropriate option based on workload patterns and operational preferences.
Each recommendation includes existing utilization metrics, up to three recommendations, potential savings, performance risk, migration effort, and projected CPU utilization. If you want memory metrics collected and displayed for EC2, AWS requires this to be collected via an agent, either a native [CloudWatch Agent](https://docs.aws.amazon.com/compute-optimizer/latest/ug/ec2-metrics-analyzed.html#cw-agent) or [supported third-party agent](https://docs.aws.amazon.com/compute-optimizer/latest/ug/external-metrics-ingestion.html).
To view a rightsizing recommendation:
On the **Cost Recommendations** screen, click **View Resources** to view each identified resource instance that is recommended for rightsizing.
Select a resource from the list.
The [Active Resources](/active_resources) screen is displayed. Select the **Rightsizing** tab. The tab includes recommended sizes for migration (e.g., "Migrate to m5.large"), the potential monthly savings, performance risk (0 being lowest, 4 being highest), migration effort (ranging from very low to very high), and projected CPU utilization.
Click **Compare Pricing** to explore an instance pricing comparison via [ec2instances.info](https://instances.vantage.sh/). This pricing comparison evaluates the current instance type used against the proposed instance type from the recommendation.

#### S3 Intelligent-Tiering Recommendations
The **Transition Amazon S3 Buckets to Intelligent Tiering** recommendation suggests enabling [S3 Intelligent-Tiering](https://docs.aws.amazon.com/AmazonS3/latest/userguide/intelligent-tiering.html) on buckets where it can reduce storage costs.
Vantage flags a bucket when all of the following are true:
* The bucket uses only S3 Standard storage. Buckets that already have data in Standard-IA, Glacier, or Intelligent-Tiering are skipped.
* The bucket's monthly list-price storage cost is greater than \$10.
* The bucket has no lifecycle rule that expires all objects in 30 days or fewer. This gate only applies to an enabled rule that covers the whole bucket. A rule scoped to a prefix, tag, or object size does not disqualify the bucket, since it only covers part of the bucket.
To estimate savings, Vantage reprices the bucket's Standard storage at Intelligent-Tiering Infrequent Access list rates and takes the difference:
$$
\text{Estimated Savings} = \text{Standard Storage Monthly Cost} - \text{Intelligent-Tiering Infrequent Access Monthly Cost}
$$
Both values use list rates, and this estimate assumes all of the bucket's data would sit in the Infrequent Access tier.
The estimated savings only reflect storage repricing. Intelligent-Tiering monitoring and transition fees are not subtracted from this number. These fees are shown on the bucket's [Storage Summary](/active_resources#s3-storage-summary) tab.
### Azure Recommendations
Vantage provides cost optimization recommendations for Azure focusing on financial commitments, rightsizing, idle resource identification, storage optimizations, and generational upgrades. Click on each category below to view all available recommendation types.
Vantage identifies opportunities to reduce costs through Azure Reserved Instances and Savings Plans across compute, storage, database, and analytics services.
| Recommendation Type | Description |
| - | - |
| Azure Compute Reserved Instance | Suggestions for instances with on-demand usage that could be converted to Reserved Instances for better savings. |
| Azure Compute Savings Plan | Vantage will identify potential savings from purchasing Compute Savings Plans. |
| Azure Blob Storage Commitment | Vantage will suggest purchasing Reserved Instances that can save on Blob v2 and Datalake storage Gen2 costs. |
| Azure SQL Database Reserved Instance | Vantage will suggest purchasing Reserved Instances that can save on your pay-as-you-go costs. |
| Azure SQL PaaS DB Reserved Instance | Vantage will suggest purchasing Reserved Instances that can save on your pay-as-you-go costs. |
| Azure Files Financial Commitment | Vantage will suggest purchasing Reserved Instances that can save on your on-demand costs. |
| Azure App Service Reserved Instance | Vantage will suggest purchasing Reserved Instances that provide a reduced rate. |
| Azure Cosmos DB Reserved Instance | Vantage will suggest purchasing Reserved Instances that provide a reduced rate. |
| Azure Managed Disk Reserved Instance | Vantage will suggest purchasing Reserved Instances that can save on your managed disk on-demand costs. |
| Azure Dedicated Host Reserved Instance | Vantage will suggest purchasing Reserved Instances that can save on your Azure Dedicated Host on-demand costs. |
| Azure VMware Solution Reserved Instance | Vantage will suggest purchasing Reserved Instances that can save on your Azure VMware Solution on-demand costs. |
| Azure Data Explorer Reserved Instance | Vantage will suggest purchasing Reserved Instances that can save on your Azure Data Explorer on-demand costs. |
Vantage analyzes Virtual Machine and Virtual Machine Scale Set utilization to identify over-provisioned resources that can be rightsized for cost savings.
| Recommendation Type | Description |
| - | - |
| Azure VM Rightsizing | Vantage will suggest VM instances that can be rightsized to offer savings. Suggestions will be made available through the Active Resource page's Rightsizing tab as well. |
| Azure VMSS Optimization | Vantage will identify underutilized Virtual Machine Scale Sets that can be rightsized or shut down to offer savings. |
Vantage identifies unused Azure resources that are incurring costs without providing value.
| Recommendation Type | Description |
| - | - |
| Unattached Azure Disk | Disks that have not been attached to a VM in the last 30 days. |
Vantage identifies managed disks that can move to a different storage type for more predictable costs.
| Recommendation Type | Description |
| - | - |
| Azure Disk Standard SSD Billing Cap | Vantage will identify managed disks on Standard HDD (`Standard_LRS` or `Standard_ZRS`) that can benefit from Standard SSD billing caps by upgrading to Standard SSD (`StandardSSD_LRS` or `StandardSSD_ZRS`). Azure does not provide a savings estimate for this recommendation, so Vantage does not include it in potential savings. |
Vantage identifies Virtual Machines running on older generations that can be upgraded to newer generations for better performance and cost efficiency.
| Recommendation Type | Description |
| - | - |
| Azure VM Generational Upgrade | Vantage will identify Azure VM instances that can be upgraded to newer generations for lower cost and better performance. |
### GCP Recommendations
Vantage provides cost optimization recommendations for GCP focusing on rightsizing, idle resource identification, and financial commitments for Compute Engine and Google Kubernetes Engine (GKE). Click on each category below to view all available recommendation types.
Vantage analyzes Compute Engine instance utilization to identify over-provisioned resources that can be rightsized for cost savings.
| Recommendation Type | Description |
| - | - |
| GCP Compute Rightsizing | Vantage will identify GCP Compute instances that are overprovisioned and can be rightsized to offer savings. For example, *We have identified 2 Compute instances for rightsizing that offer savings.* See the next section for details on viewing resource-specific rightsizing recommendations. |
Vantage identifies unused or idle GCP resources that are incurring costs without providing value, helping you clean up unnecessary infrastructure.
| Recommendation Type | Description |
| - | - |
| Idle GKE Clusters | Vantage will identify Google Kubernetes Engine clusters that are idle—clusters with little or no workload activity—and recommend scaling them down or deleting them. See the section below for details. |
Vantage identifies opportunities to reduce costs through GCP Compute Commitments for predictable workloads.
| Recommendation Type | Description |
| - | - |
| GCP Compute Financial Commitment | Vantage will identify potential savings from purchasing Compute Commitments. For example, *We have found that your account could save by purchasing Compute Commitments.* |
#### GCP Compute Rightsizing Recommendations
If you have GCP Compute instances that are overprovisioned, rightsizing recommendations are available. Recommendations are also provided in the case of idle instances.
Each recommendation includes potential monthly savings as well as the number of instances identified for rightsizing.
1. On the **Cost Recommendations** screen, click **View Resources** to view each identified resource that is recommended for rightsizing.
2. Select a resource from the list.
3. The [Active Resources](/active_resources) screen is displayed. Select the **Rightsizing** tab. The tab includes a recommended size for migration (e.g., "Migrate from e2-medium to e2-small."). Any available idle resource recommendations are also displayed (e.g., "Stop idle VM idle-instance-1."). The potential monthly savings for taking action on these recommendations are also displayed.
#### GCP Idle GKE Cluster Recommendations
Vantage surfaces idle Google Kubernetes Engine (GKE) cluster recommendations sourced from the [GCP Diagnosis Recommender](https://cloud.google.com/recommender/docs/insights/gke-diagnosis-insights). Clusters with little or no workload activity are flagged so you can scale them down or delete them to reduce idle compute, networking, and control plane costs.
1. On the **Cost Recommendations** screen, click **View Resources** next to the Idle GKE Clusters recommendation to see each identified cluster.
2. Select a cluster from the list.
3. On the [Active Resources](/active_resources) screen, select the **Idle GKE Cluster** tab to view the recommended remediation (for example, deleting the cluster or reducing its node pool) along with the potential monthly savings.
### Datadog Recommendations
Vantage provides cost optimization recommendations for Datadog focusing on financial commitments and identifying unused resources. Click on each category below to view all available recommendation types.
Vantage identifies opportunities to reduce costs through Datadog committed use discounts based on your actual usage patterns.
| Recommendation Type | Description |
| - | - |
| Datadog Financial Commitment | Vantage provides recommendations about making commitments for Datadog services where [committed use discounts](https://handbook.vantage.sh/datadog/committed-use-discounts/) are offered. These recommendations are based on your actual usage of Datadog services to assist with making the right commitment. |
Vantage identifies unused Datadog resources that are incurring costs without providing value.
| Recommendation Type | Description |
| - | - |
| Unused Custom Metrics | Vantage identifies unused custom metrics that are no longer providing value to reduce observability costs. See the section below for details. |
#### Unused Custom Metrics
Vantage identifies unused custom metrics that are no longer providing value to reduce observability costs. These recommendations help teams identify metrics that may have been created for projects that have ended or are no longer tied to dashboards, monitors, notebooks, or Service Level Objectives (SLOs).
Vantage monitors custom metrics across connected Datadog accounts and surfaces metrics that are going unused with no required configuration changes. Vantage flags metrics with:
* No queries in the past 30 days
* No associations with dashboards, monitors, notebooks, or SLOs
Each unused custom metric is shown under [Active Resources](/active_resources#datadog-custom-metrics) with metadata such as tags, creation date, and indexed volume before taking action.
From the **Cost Recommendations** screen, click **View Resources** next to the Datadog unused metrics recommendation to see each identified unused custom metric.
Select a metric from the list to view detailed information, including:
* Metric name and description
* Associated tags and metadata
* Indexed volume and cost information
* Whether the metric has been queried recently
* Whether the metric is referenced by any dashboards, monitors, notebooks, or SLOs
Click the **Metric Cleanup** tab to see recommended actions for remediation.

Vantage calculates the associated cost and savings estimate for each metric by finding the proportion of the metric volume to all ingested volume, and applies that proportion to the ingested timeseries metric costs.
**Understanding Datadog Custom Metrics Billing**
Datadog bills for custom metrics in two ways:
* **Ingested costs**: You are billed for the data that is sent to Datadog.
* **Indexed costs**: You are billed based on the average indexed volume over the billing period for a metric, which includes the number of unique tags associated with the metric.
Savings from removing unused metrics are based on indexed costs, meaning the metric is available for querying. It's important to track metrics since users can easily add tags to metrics, which increases the indexed volume and associated costs.
### Cloudflare Recommendations
Vantage provides cross-provider recommendations that suggest migrating from AWS services to Cloudflare to reduce costs. These recommendations are based on your actual usage and spending patterns. Click on the category below to view all available recommendation types.
Vantage identifies opportunities to migrate from AWS services to Cloudflare services that may offer better pricing models for specific use cases.
| Recommendation Type | Description |
| - | - |
| CloudFront to Cloudflare CDN | Vantage will identify when you have significant costs from AWS CloudFront and recommend migrating to Cloudflare CDN. Cloudflare offers self-service plans with flat-rate pricing (Free, \$20/month, and \$200/month) with no bandwidth caps rather than metered pricing. Customers who spend more than \$200/month on CloudFront can cap their CDN delivery costs by switching to Cloudflare. |
| S3 to Cloudflare R2 | Vantage will identify when you have significant S3 egress costs and recommend migrating to Cloudflare R2. Cloudflare R2 offers zero egress fees and competitive storage pricing, making it an attractive alternative for workloads with high outbound data transfer. |
### Kubernetes Rightsizing Recommendations
Without proper resource allocation, Kubernetes clusters can become overprovisioned, leading to wasted resources and idle costs. Vantage provides Kubernetes rightsizing recommendations to help you identify affected resources.
These recommendations are focused on [managed workloads](https://kubernetes.io/docs/concepts/workloads/controllers/) within Kubernetes clusters. For Kubernetes Node rightsizing recommendations, you can utilize the recommendations against the node types themselves, such as EC2 Rightsizing Recommendations, and filter for the Node Label within the Active Resource report of the recommendation.
For a full guide on understanding rightsizing and how to rightsize Kubernetes resources, see the following article in the [Cloud Cost Handbook](https://handbook.vantage.sh/kubernetes/kubernetes-rightsizing/).
#### View Kubernetes Rightsizing Recommendations
Rightsizing recommendations require version 1.0.24 or later of the Vantage Kubernetes agent. See the [Kubernetes agent documentation](/kubernetes_agent#upgrade-agent) for information on how to upgrade the agent. Once the upgrade is complete, the agent will begin uploading the data needed to generate rightsizing recommendations. After the agent is upgraded or installed, recommendations will become available within 48 hours. This step is required to ensure there is enough data to make a valid recommendation. Historical data is not available before the agent upgrade, so it is recommended that you recognize cyclical resource usage patterns, such as a weekly spike when you first review recommendations.
From the **Cost Recommendations** screen, click **View resources** to view each identified Kubernetes workload that is recommended for rightsizing.
Select a workload from the list. The workload is displayed within the [Active Resources](/active_resources) screen.
Select the **Rightsizing** tab. A section for each container that's identified for rightsizing is included.
* Each recommendation includes a high-fidelity graph of CPU and RAM used within the container in the past month, usage statistics for mCPU and memory, and recommendations for how to rightsize your configuration. The chart includes a per-day average usage. For single-point datasets or when viewing today's data, point markers are displayed to ensure visibility. The table provides a 30-day **Average**, an **Average Max Memory** (the average of each window's maximum usage), and a **Highest Peak** (the single highest CPU and memory value observed over the lookback period). The Average Max Memory and Highest Peak values differ because the former smooths out individual spikes, while the latter captures the true peak.
mCPU refers to milliCPU, which is a fractional representation of CPU, where 1 CPU is equal to 1000 milliCPU. **Current Configuration** comes from the currently configured requests for the pod template within the controller spec. This is collected by the Kubernetes agent hourly and updated when the cost data is imported, roughly once per 24 hours.
* The **Potential Monthly Savings** are also provided to indicate your estimated savings once these recommendations are implemented on your Kubernetes resources.
If a container shows zero CPU and memory usage over the lookback period, Vantage displays the message: "This container appears to be unused. Decommissioning it will result in \$X in savings per pod per hour." This indicates that the container's resource requests are allocated but no usage has been recorded. Consider verifying whether the container is still needed before decommissioning.
#### How Vantage Calculates Kubernetes Rightsizing Recommendations
Vantage takes the following steps to calculate Kubernetes rightsizing recommendations.
* Controllers running below an efficiency level of 80% over the last 30 days are identified.
* Efficiency is calculated as the percentage of the average CPU or memory utilization divided by the amount allocated for that resource.
* CPU usage is determined using `container_cpu_usage_seconds_total`, converted from CPU seconds to cores using $\frac{(\text{current} - \text{previous})}{\text{elapsed}}$.
* Memory usage is determined using `container_memory_working_set_bytes`.
* The Vantage agent scrapes metrics at scheduled intervals based on your `pollingInterval` (default to 60 seconds), whereas Prometheus defaults to a 15-second interval. This can smooth out short-term resource usage spikes.
* The agent reports on an hourly interval, capturing three values—average, min, and max—for both CPU and memory:
* **Average:** $\frac{\sum \text{datapoints}}{\text{count(datapoints)}}$
* **CPU (Average):** $\text{avg\_over\_time}(\text{irate}(\text{container\_cpu\_usage\_seconds\_total[1m]})[1h])$
* **Memory (Average):** $\text{avg\_over\_time}(\text{container\_memory\_working\_set\_bytes[1h]})$
* **Min:** $\min(\text{datapoints})$
* **CPU (Min):** $\text{min\_over\_time}(\text{irate}(\text{container\_cpu\_usage\_seconds\_total[1m]})[1h])$
* **Memory (Min):** $\text{min\_over\_time}(\text{container\_memory\_working\_set\_bytes[1h]})$
* **Max:** $\max(\text{datapoints})$
* **CPU (Max):** $\text{max\_over\_time}(\text{irate}(\text{container\_cpu\_usage\_seconds\_total[1m]})[1h])$
* **Memory (Max):** $\text{max\_over\_time}(\text{container\_memory\_working\_set\_bytes[1h]})$
* The lookback period for recommendations is 30 days, aggregating data by workload controller (e.g., Deployment).
* The target amount is calculated by dividing the average usage by the efficiency target of 80%. For example, if your average usage is 100, and the efficiency target is 80%, then Vantage determines the right size to be $\frac{100}{.8}$, or $125$.
* This target amount might exceed the maximum observed usage, which is acceptable to provide room for potential spikes in resource usage. This also prevents containers from being terminated due to resource exhaustion.
* The following values are produced for each container within a workload over the lookback period:
* `avg`: The average usage across all pods of a workload.
* `min`: The average minimum usage across all pods (not the absolute minimum).
* `max`: The average maximum usage across all pods (not the absolute maximum).
* For memory, the average memory value is the average of all recorded average memory usage values over the lookback period. The max memory value is the average of all recorded max memory usage values.
* Every minute, the agent queries node metrics from the Kubernetes control plane, tracking both the total memory used and the highest recorded memory usage. These values are then aggregated over the hour.
* A similar methodology is used for CPU, where `container_cpu_usage_seconds_total` is used to track CPU usage per second, and averages/max values are derived accordingly.
* Savings is the difference between current configuration and target configuration multiplied by a standard hourly base rate.
* For Deployments and StatefulSets, these savings are further multiplied by the number of replicas configured for each controller.
* The calculated amount of savings must be at least \$5 to be considered for rightsizing recommendations.
If you make a configuration change to a pod, the Vantage Kubernetes agent will upload the new configuration for the pod within the hour that it is available. Vantage reruns recommendations once the next Kubernetes ingestion is processed, which is every 24 hours.
# Cost Reports
Source: https://docs.vantage.sh/cost_reports
Learn how to configure Cost Reports in Vantage to analyze and optimize your cloud infrastructure spending across multiple providers.
By default, Vantage provides you with a Cost Report, named **All Resources**, that will show you all costs across all your connected cloud service accounts. You can create as many Cost Reports as you'd like and filter your costs across several dimensions. As you create Cost Reports, they will be displayed on the [Overview](/overview) page. Each report will automatically generate a [forecast](/forecasting).
To get started with Cost Reports, you can also watch these video demos on [Vantage University](/vantage_university_cost_reporting) .
If you want to create a custom table with specific columns, computed values, or calculations that are not available in Cost Reports, try [Canvas](/canvas).
## Create a Cost Report
From the top navigation, click **Reporting**.
On the left menu, select **Cost Reports**.
On the top right, click **+ New**. A new, unfiltered Cost Report is displayed.
From the top left of the graph, click **Filters**.
Click **+ Add a Filter** and select your desired filter criteria.
From the top right of the graph, use the date picker to select the date range for the report. You can select a date range that encompasses both previous and future dates, up to 6 months ahead. For more information on future forecast dates, see the [Forecasting](/forecasting) documentation.
For month- and week-based date ranges, an **Include Current Month** (or **Include Current Week**) toggle is available in the datepicker. By default, the toggle is on and the date range includes the current partial period—for example, "Last 3 Months" on March 24 shows January 1 through March 24. Turn the toggle off to constrain the range to only complete periods—"Last 3 Months" then shows December 1 through February 28. This toggle is hidden for day-based ranges like "Last 7 Days."
By default, the Cost Report compares the selected dates to the same previous period. For example, the default comparison date for March 12–March 18 is February 12–18. For relative ranges, such as **Last 7 Days**, the comparison range automatically advances with the report's selected dates so it continues to cover the immediately preceding period. To select a **custom comparison**:
* Open the date picker menu.
* In the left column, select **Custom**.
* On the calendar section, select your desired date range. (The current month is selected by default.)
* Under **Comparing to Previous Period**, select the first date period field and select a custom comparison period.
* Click **Apply**.
* You can also enable or disable the previous period comparison on a report. Click the toggle next to the Previous Period on the Date Picker to toggle this setting on or off.
Select one of the following date bins:
* **Cumulative:** Displayed as a line, pie, or area chart on the graph, along with a forecast for line and area charts, if available. Also available as ungrouped bar charts.
* **Daily, Weekly, Monthly, or Quarterly:** Displayed as a bar (multi-bar and stacked options), line, or area chart, with date ranges binned on the bottom axis and a forecast, if available.
Quarters are based on the below ranges:
* Q1: January 1–March 31
* Q2: April 1–June 30
* Q3: July 1–September 30
* Q4: October 1–December 31
You can perform additional filter and analysis operations on your Cost Report. See the following sections for additional instructions:
### Save a Cost Report
After you apply all desired filters to the report, you can save your changes and name the report.
From the top right of the graph, click **Save As New** to create a new Cost Report with your changes, or **Save Changes** to modify the current report.
Enter a name, then click **Save**.
If you update the date range, date bin (e.g., **Last 30 Days**), or grouping, you can also permanently save these changes. Once saved, the new date range, date bucket, and grouping will persist on the [Overview](/overview) page. If you save a report that includes only changes to filter sets, the report will be displayed on the Overview page with the last six months of costs.
If you want to create a new report based on an existing report, open the existing report and click **Save as New** on the top right of the screen. You can then further refine your report criteria on the new report.
#### Save as Default
On the default **All Resources** Cost Report, users with the [Organization Owner](/rbac#understanding-rbac-roles) role can save the current settings as the workspace default. This changes the baseline view that all users in the workspace see when they open the All Resources report.
The **Save as Default** option appears in the split save button dropdown on the default report. It is disabled until you change at least one of the following settings from the current default:
* Chart type (e.g., line, bar, area)
* Date bucket (e.g., daily, monthly, cumulative)
* Date interval (e.g., last 3 months, last 30 days)
* Include Current Month/Week toggle
* Credits, discounts, refunds, and tax settings
* Amortization
* Start and end dates (for custom date ranges)
Once you change a setting, the option becomes active. Click **Save as Default** and confirm in the modal to apply. The updated defaults persist for all users in the workspace.
**Save as Default** is only available on the workspace's default All Resources report. It does not appear on custom reports or new unsaved reports.
### Organize Cost Reports
#### Cost Report Folders
You can organize your Cost Reports in folders and separate them by team or group. See the [Folders](/folders) documentation for more information.
#### Dashboards
Cost Reports can be displayed as a group on a dashboard. The dashboard has options to display all reports by the same date range. See the [Dashboards](/dashboards) documentation for more information.
### Anomalies, Forecasts, and Annotations
Cost Reports have several other features, including [anomaly detection](/cost_anomaly_alerts), [forecasts](/forecasting), and [annotations](/annotations). See the linked documentation for more information about these features.
### Forecasts Tab
The **Forecasts** tab on Cost Reports provides a dedicated interface for analyzing and comparing different forecast types—Baseline, Dynamic, and Scenario Model forecasts. This tab displays tabular views of each forecast type, historical differential analysis, and allows you to select which forecast to display on the chart. See the [Forecasting](/forecasting) documentation for more details.
## Filter Cost Reports
On the **Filters** menu, click **Select a provider** and choose from any of your connected providers (AWS, Azure, etc.), or select **All Providers** to filter across every connected provider in a single filter set.
When you select **All Providers**, the labels shown in the filter dropdown depend on which providers you have connected:
* If you have one provider connected, or every connected provider uses the same label for a dimension, the dropdown shows that label.
* If your connected providers use different labels for the same dimension, the dropdown falls back to AWS-style labels (for example, **Billing Account** appears in place of Azure's **Subscription** or Oracle's **Tenancy**).
If you can't find a provider-specific label you're expecting:
1. Open the [Data Dictionary](/data_dictionary) and find your provider's section.
2. In the **Filter** column, find the label you're looking for and note its **API Field Name** (for example, Azure **Subscription** maps to `costs.provider_account_id`).
3. Look up that same API Field Name in the [AWS section](/data_dictionary#aws) to find the AWS-style label (for example, `costs.provider_account_id` is **Billing Account** on AWS).
4. In the **All Providers** filter dropdown, select that label and enter your value.
* When you select a single provider, costs are filtered to all costs for that provider. Within the table, costs are grouped by provider service (e.g., Amazon Relational Database Service), in descending order of **Accrued Costs**.
* To view available filter options, click **New Rule**. A list of filter options is displayed (e.g., Account). Filter options vary per provider. When **All Providers** is selected, only filter options that exist for every provider (e.g., Service, Account, Region, Tag) are available.
* Each filter includes options for exact matching and fuzzy matching. For example, in the image below, you can select **is**, **is not**, **contains**, **does not contain**, **starts with**, and **ends with** for the **Resource** filter. This set of options can vary per selected filter. Select a matching option, then select a filter value (e.g., where **Service** is **Amazon Relational Database Service** + **Amazon Elastic Compute Cloud - Compute**).

To continue filtering the report, perform any of the following actions:
* To add another value for that filter, click the **+** icon next to the first value.
* To remove a selected filter value, click the trashcan icon next to the value.
* To add more filter criteria, click **New Rule**. The graph is updated to display costs that match the first filter criteria *and* the second filter criteria.
* To add a separate filter set, click **+ Add a Filter**. You can also use this option to add costs from another provider. The graph is updated to display costs that match the first filter set *or* the second filter set.
* To remove a filter set, click the trashcan icon at the top of a filter set.
When filtering by **Category**, **Subcategory**, or **Resource**, the dropdown includes an **All** option. Select this option to filter across all services for the selected provider, without scoping to a specific service. In [VQL](/vql_cost_report#costs-by-specific-category), use `costs.service = '*'` as the service value to achieve the same result.
Filter values on Cost Reports are case-sensitive, except where you explicitly opt in to case-insensitive matching. Use the [**Flexible Match**](#flexible-match) operator on tag filters to ignore differences in case, whitespace, underscores, and hyphens. For other filter types, enter values exactly as they appear in your provider's billing data (for example, `ExtendedSupport`, not `extendedsupport` or `Extended Support`).
### Filter by Usage Unit
Use the **Usage Unit** filter to compare costs or consumption that share the same unit of measure, such as **Hours**, **GB-Months**, **Requests**, or **Tokens**. This prevents a report from combining values that cannot be meaningfully compared.
The filter works with individual providers, [Custom Providers](/connecting_custom_providers), and **All Providers**. Vantage displays it only when the selected provider context contains at least two distinct, non-empty usage units. If the context contains zero or one unit, the filter is omitted because it would not further narrow the report.
To apply the filter, select a provider, click **New Rule**, and select **Usage Unit**. Choose a matching operator and one or more available units. Unit labels are normalized for consistent spelling and capitalization; for example, variations of `hrs` and `Hours` display as **Hours**. Saved reports and [Saved Filters](/saved_filters) preserve the selected Usage Unit rule.
For usage quantities rather than costs, set the report's Y axis to **Usage**. See [Usage-Based Reporting](/usage_based_reporting) for details.
### Flexible Match
The flexible match operator in Vantage helps you work with inconsistent tag naming conventions. When filtering a Cost Report, you can select the flexible match operator to ignore differences in case, whitespace, underscores, and hyphens. This allows a single filter to match many tag value variations without creating multiple filters or manually normalizing tags.
For example, your organization tags workloads by team, but the tag values vary: one service might use `teamA`, another `team-a`, and a third `Team A`. Instead of creating separate filters for each variant, use the flexible match operator as shown in the image below.

Vantage automatically normalizes and matches all variations, as well as matching any future iterations that are created of the `Team A` string.
To exclude values, use the **does not flexible match** operator.
### Percent-Based Cost Allocation
With percent-based cost allocation, you can filter Cost Reports to show back shared resources, like support costs or multi-tenant databases, to the team or department that uses them. As filters are set in a Cost Report, Vantage will query for costs that meet all those conditions.
To set percent-based cost allocation:
From the **Filters** menu, select your desired filter criteria. For example, select the **AWS** provider option and filter by **Service** for only RDS costs.
Click the **Add Cost Allocation** button on the filter set and enter a value between 1 and 100%. The set percentage will be applied to all the matching costs and represented accordingly in the Cost Report.

When percent-based cost allocation is set as a filter, forecasts will be produced in aggregate for all set conditions, and the percentage allocation will be applied to that forecast.
### Amazon Elastic Container Service (ECS)-Managed Tags
If you want to view Amazon Elastic Container Service (ECS) cluster tags, you need to enable ECS-Managed Tags. See the [AWS documentation](https://docs.aws.amazon.com/AmazonECS/latest/developerguide/ecs-using-tags.html#managed-tags) for more information.
### AWS Organization Tags
You can filter and group by [AWS Organization Tags](https://docs.aws.amazon.com/organizations/latest/userguide/orgs_tagging.html) in Cost Reports. Create a filter for **Tag**. For the **Tag Key**, these tags are displayed like `aws:organizations:tag`.
### Network Costs
For resources that generate network traffic costs (e.g., NAT Gateways), a **Network Costs** button is displayed in the Cost Report list. See the [Network Flow Reports documentation](/network_flow_reports) for details on network costs.
In the below example, this Cost Report is grouped by **Service** and **Resource**. The **Network Costs** button is displayed next to NAT Gateway resources.

### Amazon Bedrock LLM Enrichment Tags
If you enable [AWS Bedrock LLM Enrichment](/aws_bedrock_enrichment), Amazon Bedrock cost rows are split by the per-request `requestMetadata` your application attaches, plus [Managed AI Tags](/managed_ai_tags) such as `vntg:ai:model`, `vntg:ai:principal_id`, `vntg:ai:operation`, and `vntg:ai:inference_scope`. Filter or group a Cost Report by these tags (for example, `tag:vntg:ai:model`, `tag:vntg:ai:principal_id`, or a custom key such as `tag:team`) to attribute Bedrock spend to teams, applications, customers, and features. See the [AWS Bedrock LLM Enrichment documentation](/aws_bedrock_enrichment#view-enriched-costs-on-cost-reports) for the full tag reference.
### LLM Token Allocation Enrichment Tags
If you enable the [Custom LLM Enrichment](/custom_llm_enrichment) integration, model-provider cost rows are split by the per-request `tags` you deliver in your telemetry, plus a `vntg:ai:model` tag. Filter or group a Cost Report by these tags (for example, `tag:vntg:ai:model` or a custom key such as `tag:team`) to attribute LLM spend to teams, users, applications, and features. See the [Custom LLM Enrichment documentation](/custom_llm_enrichment#view-enriched-costs-on-cost-reports) for the full tag reference.
### Edit Filters as VQL
You can view and edit your Cost Report filters as [VQL (Vantage Query Language)](/vql) directly in the console. This is useful for making precise adjustments to complex filters, copying filter logic between reports, or reusing VQL across the API, Terraform, and Virtual Tags.
From the **Filters** menu, click **View as VQL** to see the current filter as a VQL query. Click **Edit VQL** to modify the query directly, then click **Apply** to update the filter. See the [VQL documentation](/vql#edit-vql-in-the-console) for details.
### Saved Filters
You can create and use **Saved Filters** to apply commonly used filters across multiple reports. Review the [Saved Filters documentation](/saved_filters) for more information.
## Configure Report Groups
With the **Group By** option, you can select one or more dimensions to group by. If you select a grouping option, both the Cost Report table and graph will include costs aggregated by the selected groupings. Once the report is saved, the report’s corresponding [Overview](/overview) widget will be updated as well.
You can group by the following dimensions:
* Account (e.g., member account on AWS, project on GCP)
* Billing Account
* Region
* Service (e.g., Amazon S3, Azure VMs)
* Resource
* Provider (e.g., AWS, GCP, Azure)
* Category
* Subcategory
* Charge Type (see the [section below](/cost_reports#charge-type-grouping-category) for definitions)
* Tagged (e.g., see whether resources are or are not tagged)
* Tag (includes [virtual tags](/tagging))
* Usage Unit (e.g., Hours, GB-Months, Requests)
After a Cost Report has been grouped, each grouping is displayed as a column in the table below the graph. On the graph itself, group labels are displayed with dashes between each grouping, such as `production - Acme - nat-123456`.
In the **Spend** view, **Usage Unit** is an optional grouping that you can add or remove like other groupings. When you set the Y axis to **Usage**, Vantage automatically selects and locks **Usage Unit** so quantities with different units are never combined. Switching back to **Spend** unlocks the grouping so it can be removed.
When you group by **Resource**, some cost line items may appear as **No Resource**. This means the cloud provider's billing data does not include a resource identifier for those costs. Common examples include tax line items, support charges, account-level fees (such as Enterprise Support or Shield Advanced subscriptions), certain data transfer costs, and some marketplace subscription fees. The same behavior applies to other grouping dimensions—for example, costs without a region will appear as **No Region**, and costs without a tag will appear as **Not tagged with \{tag name}**.
When grouping by tags that use [cost allocation](/tagging#cost-allocation-tags) (Business Metrics-Based, Cost-Based, or Percent-Based allocation tags), allocations that are individually less than 0.01% of the total are automatically grouped together and displayed as **other allocations (≤ 0.01%/each)**. This helps simplify reports by consolidating many small allocations into a single category. See the [Small Allocation Grouping](/tagging#small-allocation-grouping) section in the Tagging documentation for more details.

To sort the table by multiple columns in the table, press **Shift + Click** on the column headers.
### Charge Type Grouping Category
The Charge Type grouping includes costs separated by items like usage, discounts, EDP discounts, and taxes. Expand the section below to view the associated providers and definitions for each charge type.
| Charge Type | Provider | Definition |
| - | - | - |
| adjustment | GCP | GCP adjustments due to reasons like goodwill or SLA violations |
| AllocatedAmortizedDiscount | AWS | Savings from commitment-based pricing (Savings Plans/RIs) allocated to the account consuming the commitment. Appears as a negative amount, reducing the effective cost from on-demand pricing to the commitment rate. |
| AllocatedAmortizedFee | AWS | Savings Plans and Reserved Instances that have been amortized and allocated to an account with usage. This value can appear as a negative cost in the payer account because it is subtracted from the payer account and added to a member account. |
| AmortizedCredit | Via [Custom Providers](/connecting_custom_providers) | Credit charges that span multiple billing days, amortized across the covered period. Visible when amortization is enabled. |
| AmortizedDiscount | AWS | The discount portion of a commitment fee (Reserved Instance or Savings Plan upfront fee) that has been spread across the billing period. Represents the difference between the gross and net amortized upfront commitment cost. Visible when amortization and discounts are both enabled. |
| AmortizedFee | AWS | Amortized Savings Plan and Reserved Instance purchases |
| AmortizedPurchase | Azure | Azure reservation and Savings Plan purchases from the amortized cost dataset. Visible when amortization is enabled. |
| AmortizedRefund | Via [Custom Providers](/connecting_custom_providers) | Refund charges that span multiple billing days, amortized across the covered period. Visible when amortization is enabled. |
| AmortizedTax | AWS | Tax charges (such as AWS Marketplace or Enterprise Support tax) that span multiple billing days, amortized across the covered period |
| AmortizedUsage | AWS, Azure | Usage charges in the amortized cost view. For AWS, commitment-covered usage (Savings Plans/RIs) rewritten to gross cost when blended commitment discounts are enabled. For Azure, usage charges from the amortized cost dataset, where reservation and Savings Plan purchases are spread across the usage period. |
| Bundled Discount | AWS | Discounted usage for one product/service based on the usage of another product/service |
| Credit | AWS | Any AWS credits that were applied to your bill |
| COMMITTED\_USAGE\_DISCOUNT | GCP | Compute Engine resource-based committed use discounts |
| COMMITTED\_USAGE\_DISCOUNT\_DOLLAR\_BASE | GCP | Spend-based committed use discounts |
| DISCOUNT | Any provider | Discounts applied by a provider for your usage |
| DistributorDiscount | AWS | Discounts through the [AWS Distribution Resellers Program](https://aws.amazon.com/partners/programs/distribution-resellers/) |
| Enterprise Discount Program Discount | AWS | Discounts applied through the [AWS Enterprise Discount Program (EDP)](https://aws.amazon.com/pricing/enterprise/) |
| Fee | AWS | Upfront annual fees paid for subscriptions, such as the fee paid for All Upfront subscriptions. Also used for AWS Marketplace and Support fees. |
| FeeTax | AWS | Tax related to "Fee" type charges, such as AWS Marketplace tax |
| FEE\_UTILIZATION\_OFFSET | GCP | Credit that offsets Committed Use Discount (CUD) fee SKUs when commitments are fully utilized, resulting in zero net cost for the fee SKU |
| FREE\_TIER | GCP | Credits applied related to GCP Free Tier usage |
| Monthly Minimum Fee | Fastly | Minimum fee for [Fastly](https://www.fastly.com/pricing) |
| PartnerEarnedCredit | Azure | Credits earned by [Cloud Solution Provider (CSP)](https://learn.microsoft.com/partner-center/billing/partner-earned-credit) partners for managing customer Azure resources. Visible when credits are included. |
| Private Rate Discount | AWS | AWS discount based on private pricing rates |
| PROMOTION | GCP | GCP promotional credits related to items like marketing promotions |
| Purchase | Azure | Azure Marketplace purchases |
| Refund | AWS | Negative charges, indicating money refunded by AWS |
| regular | GCP | GCP regular charges |
| RESELLER\_MARGIN | GCP | Discounts for [GCP Reseller Program](https://cloud.google.com/marketplace/docs/partners/resell/reseller-incentives) |
| Reserved Instance Discounted Spend | AWS | The rate for instances benefiting from Reserved Instance (RI) benefits |
| Reserved Instance Fee | AWS | Monthly recurring fees for Reserved Instance subscriptions |
| RiVolumeDiscount | AWS | Volume discounts for large Reserved Instance purchases |
| RoundingAdjustment | Azure | Small adjustments for rounding differences in Azure billing calculations |
| rounding\_error | GCP | GCP cost type for rounding errors |
| Savings Plan Discounted Spend | AWS | On-demand costs covered by your Savings Plan, offsetting corresponding Savings Plan negation items |
| Savings Plan Negation | AWS | Offset costs through your Savings Plan benefit associated with covered usage items |
| Savings Plan Recurring Fee | AWS | Hourly recurring charges associated with a No Upfront or Partial Upfront Savings Plan |
| Savings Plan Upfront Fee | AWS | One-time upfront fee from purchasing All Upfront or Partial Upfront Savings Plans |
| Solution Provider Program Discount | AWS | Discounts through the [AWS Solution Provider Program](https://aws.amazon.com/partners/programs/solution-provider/) |
| SppDiscount | AWS | Solution Provider Program discount (internal charge type name used in billing rules) |
| SUBSCRIPTION\_BENEFIT | GCP | Credits earned after purchase of long-term subscriptions |
| SUSTAINED\_USAGE\_DISCOUNT | GCP | Credit for running certain Compute Engine resources for a large portion of the month |
| Tax/tax | AWS, GCP | Taxes applied, such as sales tax |
| UnamortizedCredit | Via [Custom Providers](/connecting_custom_providers) | The original lump-sum credit charge before amortization. Visible when amortization is disabled. |
| UnamortizedDiscount | AWS | The discount portion of an unamortized commitment fee (Reserved Instance or Savings Plan). Visible when amortization is disabled and discounts are included. |
| UnamortizedFee | AWS, via [Custom Providers](/connecting_custom_providers) | The original lump-sum fee charge before amortization. For AWS, Savings Plan recurring fees shown as unamortized when blended commitment discounts are enabled. Visible when amortization is disabled. |
| UnamortizedPurchase | Azure | Azure reservation and Savings Plan purchases from the actual (unamortized) cost dataset. Visible when amortization is disabled. |
| UnamortizedRefund | Via [Custom Providers](/connecting_custom_providers) | The original lump-sum refund charge before amortization. Visible when amortization is disabled. |
| UnamortizedSppDiscount | AWS | Unamortized Solution Provider Program discount |
| UnamortizedTax | Via [Custom Providers](/connecting_custom_providers) | The original lump-sum tax charge before amortization. Visible when amortization is disabled and taxes are included. |
| UnamortizedUsage | Azure | Usage charges from the actual (unamortized) cost dataset, where reservation and Savings Plan purchases are shown as lump sums rather than spread over time. Visible when amortization is disabled. |
| UnusedReservation | Azure | Cost of [unused Azure reservation](https://learn.microsoft.com/azure/cost-management-billing/reservations/understand-reserved-instance-usage-ea) capacity. Represents reservation hours that were paid for but not utilized. Visible when amortization is enabled. |
| UnusedSavingsPlan | Azure | Cost of [unused Azure Savings Plan](https://learn.microsoft.com/azure/cost-management-billing/savings-plan/utilization-cost-reports) capacity. Represents Savings Plan commitment that was paid for but not utilized. Visible when amortization is enabled. |
| Usage | Any provider (for GCP, see "regular") | Charges for usage at regular or on-demand rates |
Each AWS discount type in the table above (such as Bundled Discount, Enterprise Discount Program Discount, and Private Rate Discount) also has amortized and unamortized variants that use the internal charge type name with a prefix—for example, `EdpDiscount` becomes `AmortizedEdpDiscount` or `UnamortizedEdpDiscount`.
* **Amortized variants** (e.g., `AmortizedEdpDiscount`) appear when amortization and discounts are both enabled. These represent the discount amount on fee rows (such as Marketplace or Enterprise Support charges) that have been spread across the billing period.
* **Unamortized variants** (e.g., `UnamortizedEdpDiscount`) appear when amortization is disabled and discounts are included. These represent the discount amount on unamortized fee or commitment rows, such as Reserved Instance fees or Savings Plan recurring fees.
The discount types with these variants are: `EdpDiscount`, `BundledDiscount`, `SppDiscount`, `RiVolumeDiscount`, `PrivateRateDiscount`, and `DistributorDiscount`.
To identify Savings Plan or Reserved Instance waste over time, create a Cost Report grouped by **Charge Type** with [amortization](/cost_reports#amortization) enabled and filter to show only `AmortizedFee` and `AllocatedAmortizedFee`. `AmortizedFee` represents your total commitment cost, while `AllocatedAmortizedFee` represents the portion allocated to accounts with actual usage. A gap between the two indicates unused commitment capacity. You can also use [Financial Commitment Reports](/financial_commitment_reports) to view coverage and utilization trends.
### Other Grouping Category
By default, the top five groups of costs by amount are displayed on the graph. In addition, the Other Costs category is displayed as an aggregation of all remaining costs. To add more costs to the graph and table, click the down arrow next to **Other Costs**. The number of other costs is displayed. Click **Show X More Items** to add additional cost groups to the report.

## Drill Down in Costs Table
Within the table below the graph, you can drill down into your report to create precise filtering and grouping views. When you click a drilldown icon on a row, Vantage automatically adds filters matching the values in that row and adds a grouping dimension to the report, allowing you to explore your costs in more detail.
Drilldown functionality is available in both the **Cumulative** and **By Date** views of the cost table. The drilldown options available depend on whether the report is currently ungrouped or has grouping criteria applied.
### Starting from an Ungrouped Report
When a Cost Report is ungrouped (i.e., the **Group By** dropdown is set to **Ungrouped**), two drilldown icons are displayed next to each service in the table:
* **Costs by Category** icon (shapes icon): Click to view costs broken down by category for that service. This adds a filter for the selected service and groups the report by **Category**.
* **Costs by Resource** icon (chip icon): Click to view costs broken down by individual resources for that service. This adds a filter for the selected service and groups the report by **Resource ID**. This option is only available for providers that support resource-level cost data, such as AWS.
In the example below, clicking the **Costs by Category** icon (shapes icon) next to EC2 breaks down the service costs by category, such as Data Transfer and Compute Instance.
Once you click a drilldown icon, the report becomes grouped and the drilldown options change. The next drilldown icon in Vantage's standard sequence then appears, allowing you to continue drilling down further. For example, after clicking **Costs by Category**, the report is grouped by **Category** and the **Costs by Subcategory** icon appears next to each category, allowing you to drill down to subcategory-level detail. You can also use the drilldown menu to choose from other available grouping dimensions, as explained in the next section.
### Starting from a Grouped Report
When you manually apply grouping criteria to a Cost Report (e.g., set the **Group By** field to **Service**), the following drilldown options are available:
* **Quick drilldown icon**: A single icon is displayed that represents the next grouping dimension in Vantage's standard drilldown sequence. For example, if you group by **Account**, the quick drilldown icon will drill down by **Billing Account**. Hover over the icon to see what grouping it will apply.
* **Drilldown menu**: A dropdown menu (filter list icon) appears next to the quick drilldown icon, allowing you to choose any available grouping dimension to drill into, rather than using the automatically determined next grouping.
Select **Usage Unit** from the drilldown menu to add it as a grouping while applying the row's existing values as filters.
When you click either the quick drilldown icon or select an option from the drilldown menu, Vantage:
* Adds filters matching the values in that row (e.g., the specific service, category, or other grouping values)
* Adds the selected grouping dimension to the report
* Displays the new grouping as a column in the table
In the below example:
* The report is filtered to **AWS** costs and grouped by **Service**.
* On the line item for **Elastic Compute Cloud - Compute**, click the quick drilldown icon (which drills down by **Category**).
* A filter for line items matching only the **Elastic Compute Cloud - Compute** service is added in the **Filters** menu.
* The report is now also grouped by **Category**.
* The **Category** column appears in the table.
* You can continue to click the quick drilldown icon on subsequent rows to drill deeper into your costs. Each click adds filters for the selected row and applies the next grouping in Vantage's standard sequence. For example, if you click the quick drilldown icon on the **EC2 > Data Transfer** line item:
* The **Data Transfer** category filter is applied in the **Filters** menu.
* The report is automatically grouped by **Subcategory** (the next grouping in the sequence after Category).
* **Subcategory** is also displayed as a column in the table.
* You can also use the **Drilldown menu** (the filter list icon) to choose which grouping dimension to drill into next, rather than using the automatically determined next grouping. In the below example, you select the **Region** option for the **EC2 > Data Transfer > EU-DataTransfer-Out-Bytes** line item. In the resulting report, **EC2 > Data Transfer > EU-DataTransfer-Out-Bytes** is broken down with individual line items per region.
* The additional filter for the **EU-DataTransfer-Out-Bytes** subcategory is added to the **Filters** menu.
* The report is now also grouped by **Region** (the selected grouping).
* **Region** is now a column in the table.
### Navigating Drilldown History
After drilling down into your costs, you can use the back button in your browser to navigate back to the previous drilldown level. This allows you to easily move between different levels of detail without losing your place in the report.
### Tagging Drilldown
When a tag is a [nested tag](/tagging#nested-virtual-tags), you can drill down into its values to view all subtags.
In the example below, the report is grouped by the nested tag **Business Units**. This tag contains two values—**Core Production** and **Core Development**—each made up of other tags.

Click the drilldown tagging icon to the left of a tag name to reveal its nested values. For example, **Core Production** is the parent tag, with **Business Unit Applications** subtags **app1** and **app2**. The Cost Report table then shows costs associated with these lower-level tags.

## Billing Code Descriptions
AWS practitioners who are having trouble understanding AWS billing codes present in Cost Reports can find descriptions of each billing code, other variations of that billing code, and other services that use the same billing code within Cost Reports. When you view any AWS Cost Report grouped by **Provider, Service, Category, and Subcategory**, you can hover over any subcategory line item and a tooltip with a link to [cur.vantage.sh](https://cur.vantage.sh/) is provided that takes you to a page with details for that billing line item.
[cur.vantage.sh](https://cur.vantage.sh/) is a free utility that gives cloud practitioners simple definitions of billing codes for every AWS service. The site has a distinct page for each AWS service (e.g., S3 or EC2) that clusters together similar billing codes for that service, as there may be separate or distinct billing codes for each individual region.

## Adjust Chart Visualization
You can adjust the chart to show as one of the below options. To toggle these options, click one of the corresponding buttons on the top right of the chart.

* **Stacked Bar**: Segmented bars stacked on top of each other. Each bar shows cumulative total with different colors for each grouping (e.g., when grouped by provider, one bar for AWS, one for Azure, etc.). Available with Daily, Weekly, Monthly, or Quarterly date bins.
* **Multi-Bar**: Separate bars for each segment side-by-side for easy comparison across categories at each time point. Available with Daily, Weekly, Monthly, or Quarterly date bins.
You can also see a cumulative view of bar charts when they are ungrouped. The cumulative view is not available for grouped bar charts.
**Best for**: Comparing values across different groupings.
* Cost trends over time as connected data points. Individual lines for each group. Available with Daily, Weekly, Monthly, Quarterly, and Cumulative date bins.
**Best for**: Identifying trends, seasonal patterns, and growth trajectories.
* Filled areas under lines, stacked on top of each other. Total cost height with colored areas showing each group's contribution. Available with Daily, Weekly, Monthly, Quarterly, and Cumulative date bins.
**Best for**: Visualizing both individual costs and proportions to total.
* Proportional breakdown at a single point in time. Circular chart with slices sized by cost grouping. Available with Cumulative date bin only.
**Best for**: Understanding cost distribution and identifying largest cost drivers.
## Configure the X Axis
By default, Cost Reports display the date on the X axis with costs segmented by provider, service, or other dimensions. You can also configure the X axis to show different dimensions, giving you more control over how costs are grouped and visualized.
The configurable X axis is compatible with bar charts—both multi-bar and stacked bar charts. If you want to change the chart type, you’ll be asked to confirm the change. If you proceed, the grouping will reset to by date.
When you change the X axis to a non-date dimension, any existing Group By settings will be removed, and you will be unable to set additional Group By settings, as the chart will now be grouped by time period. In addition, [annotations](/annotations) will not show in the chart itself; however, you can view your existing annotations by clicking on the **Annotations** icon in the top right of a Cost Report.
To configure the X axis:
Apply any desired filters to the chart.
Filters apply as normal. For example, you can filter a Cost Report to only AWS, then set the X axis to "Team" to compare team costs within AWS. The segmentation will always adjust to reflect the chosen X axis.
At the top of any Cost Report, select the **Chart Settings** dropdown.
Select your desired **X Axis Group By** dimension from the dropdown.
* **Date** (default)
* **Billing Account**
* **Linked Account**
* **Region**
* **Service**
* **Resource ID**
* **Provider**
* **Cost Category**
* **Cost Subcategory**
* **Charge Type**
* **Tagged Status**
* **Tag Key** (any available tag)
When you select a non-date dimension, the chart will update to show that dimension on the X axis, with date becoming the segmentation within the chart based on your selected date bin.
The maximum number of groupings on an X axis is 10 for multi-bar charts and 20 for stacked charts. All remaining items after these limits are aggregated into an "Other" bar. You can't select multiple dimensions (e.g., provider *and* tag) to display on the X axis. The X axis group order is descending based on cumulative spend. When you select **Count** for the **Y-Axis**, Vantage locks the **X-Axis** to **Date**.
## Count Reporting
Count is a **Y-Axis** display type for Cost Reports that shows how many distinct **Group By** values have a nonzero cost in each date bin. **Cost** shows how much you spent, **Usage** shows how much of a provider-reported unit you consumed, and **Count** shows how many grouped items contributed to that spend. Count values are displayed as whole numbers.

For example, you can:
* Group by **Resource** to count resources.
* Group by **Service** to count services.
* Group by a `model` tag to count models.
* Group by a `user` or `seat` tag to count tagged users or seats.
To inspect your current resource inventory and its metadata instead of a count trend, use [Resource Reports](/active_resources).
The selected date bin determines how Vantage deduplicates values. For example, a resource that contributes cost on multiple days within the same monthly bin is counted once for that month. If you change the report to daily bins, that resource is counted once on each day it contributes cost.
For AWS, Count requires detailed Cost and Usage Report (CUR) data. Historical cost totals sourced from AWS Cost Explorer while CUR data is importing or backfilling are excluded from Count. As a result, **All Costs** can show spend for a date bin that has no Count value. See [Backfilling AWS CUR for Previous Reporting Periods](/connecting_aws#backfilling-aws-cur-for-previous-reporting-periods).
When you select multiple **Group By** dimensions, Count measures each distinct combination of those dimensions. For example, grouping by **Service** and **Region** counts each unique service and region combination, rather than counting services and regions separately.
To view a report by Count:
Open a Cost Report and apply the filters and **Group By** dimensions for the items you want to count.
Select a daily, weekly, monthly, or quarterly date bin. Count does not support the cumulative date bin.
At the top of the report, open the **Chart Settings** menu. For the **Y-Axis**, select **Count**.
Vantage sets the **X-Axis** to **Date** and the table to **By Date**. You cannot select a custom X-axis dimension, the cumulative table view, or a pie chart while Count is selected.
Save the report.
### Read Count Results
The chart displays Count on the primary axis and **All Costs** on the secondary axis. Use both series to compare changes in the number of grouped items with changes in spend. Count supports stacked bar, multi-bar, line, and area charts. Count charts do not display previous-period Count series, forecasts, or budget lines.
The **By Date** table displays the following values:
* The grouping columns identify the unique value or combination represented by each row.
* Each date column shows `1` when that row's grouping combination has a nonzero cost in that date bin. Otherwise, it shows `0`.
* The **Total** row shows the number of distinct grouping combinations with nonzero cost in each date bin.
* **Accrued Count** adds the date-bin values across the selected range.
**Accrued Count** is not a period-wide count of unique items. It sums each item's appearances across the displayed date bins. For example, one resource that contributes cost in each of 30 daily bins has an Accrued Count of 30. If you use one monthly bin for the same period, that resource contributes 1.
The Count table does not include Cost columns. Use the chart's **All Costs** series to compare Count with spend, or switch the **Y-Axis** to **Cost** to view cost values in the table.
To download Count values, see [Export Cost Reports](#export-cost-reports).
## Configure Report Settings
### Credits, Discounts, Refunds, and Taxes
By default, all Cost Reports include discounts and taxes. You can optionally enable credits and refunds, too.
* **Credits:** Credits are often promotional codes redeemed for services or trials on your account.
* **Discounts:** Discounts can include programs like the AWS Enterprise Discount program. Discounts are often negotiated with the cloud provider and based on usage. You might see discounts reflected as negative values in the Cost Report table. You can follow the below best practices for analyzing Cost Reports with discounts:
* If you remove the **Discount** setting, you can view usage and costs *before* the discount was applied.
* Group or filter the Cost Report by **Charge Type**. This grouping displays costs separated by items like usage, discounts, EDP discounts, and taxes.
* **Refunds:** Any associated refunds.
* **Taxes:** Any associated taxes.
To configure these options:
Above the Cost Report graph, click **Cost Settings**.
Select an option to toggle on/off any of the included costs (e.g., discounts, etc.).
### Amortization
By default, all Cost Reports show upfront fees, such as fees for Reserved Instances, Savings Plans, Marketplace purchases, and Support, amortized day by day for the period of the fee.
In addition, Vantage uses committed use attribution for linked accounts. By default, you will see fees for Reserved Instances and Savings Plans assigned to the AWS account that *benefited* from the discount—not the account that purchased the commitment.
For more information about this logic, see the following [Vantage blog post](https://www.vantage.sh/blog/vantage-launches-committed-use-float-cost-attribution).
In contrast to AWS Cost Explorer, which displays fees associated with the account responsible for the commitment or purchase, Vantage provides a comprehensive view by showing fees based on the account where the benefits were realized.
#### Disabling Amortization
You can toggle a Cost Report to not amortize upfront fees if you want to view the upfront fees on the day they were incurred.
From the top of any Cost Report, click **Cost Settings**.
Under **Amortization**, uncheck **Enabled**.

#### AWS Blended Commitment Discounts
AWS Blended Commitment Discounts provide a way to evenly spread commitment-based discounts (from Savings Plans and Reserved Instances) to all eligible usage. Vantage calculates an effective savings rate per AWS service and applies it proportionally—so all teams and workloads receive consistent discounts, regardless of where AWS originally applied them.
To enable blended commitment discounts for your AWS integration, contact [support@vantage.sh](mailto:support@vantage.sh).
Customers who use AWS [discount sharing](https://docs.aws.amazon.com/awsaccountbilling/latest/aboutv2/ri-turn-off.html) across accounts can experience uneven distribution of Savings Plan and Reserved Instance discounts. Savings Plans apply discounts from the highest discount usage type to the lowest until the committed amount is consumed. This means that workloads with lower savings rates—such as Windows instances or workloads outside of US regions—rarely see discounts without purchasing dedicated Savings Plans in the accounts that consume them.
**How Vantage calculates blended discounts**
When enabled, Vantage computes an effective savings rate per AWS service across your entire commitment portfolio. For eligible usage, the blended discount amount is:
$\text{Blended Discount} = \text{Gross Usage Cost} \times \text{Effective Savings Rate (per service)}$
This rate is then applied proportionally to all eligible usage for that service, creating even discounts across all teams and workloads.
**What changes in your Cost Reports**
When you view a Cost Report with amortization and discounts enabled:
* Eligible commitment-covered usage is represented as `AmortizedUsage` at its **gross cost** (the on-demand price).
* A separate `AllocatedAmortizedDiscount` row is added as a **negative amount**, representing the blended savings.
* For eligible categories, separate discount line items (such as EDP or Private Rate Card discounts) are consolidated into the blended discount rather than shown individually.
The sum of `AmortizedUsage` and `AllocatedAmortizedDiscount` equals the net effective cost for that usage.
**What does not change**
* **Commitment fees:** Reserved Instance fees and Savings Plan recurring fees pass through as unamortized fees with any associated discounts shown as unamortized discounts.
* **Non-commitment fees:** Fees that span multiple days—such as Enterprise Support or Marketplace charges—continue to be amortized across the billing period as they are today.
* **Unamortized costs:** Unamortized costs, such as upfront fees or monthly commitment fees, are not affected.
* **Non-eligible usage:** For usage that is not eligible for commitment-based discounts, discount rows are still emitted individually.
* **Kubernetes efficiency:** For Kubernetes-related services, Vantage also computes and attaches a discounted rate based on the blended savings rate so that [Kubernetes efficiency](/kubernetes) calculations remain consistent.
This feature applies to all Cost Reports and Workspaces for the enabled AWS integration. It cannot be selectively applied to specific reports.
### Vantage vs. Cost Explorer
If you notice your costs in Vantage differ from what you see in Cost Explorer, this could be for many reasons, including:
* **Amortization logic:** As noted above, Vantage uses a different amortization logic from Cost Explorer.
If you want to align the view in Vantage to Cost Explorer, disable amortization in Vantage and compare the numbers to unblended costs in Cost Explorer.
* **EC2-Other:** In Cost Explorer, this cost category comprises many subcategories (e.g., Data Transfer). In Vantage, EC2-Other is reallocated into direct line items. For example, if you filter for NAT gateway expenditures, the charges initially categorized under transit or egress in EC2-Other are assigned to the individual resource that created the charge.
For more tips on reviewing your cost data against Cost Explorer, see [the following blog post](https://www.vantage.sh/blog/analyze-aws-cost-data).
### Usage-Based Reporting
Cost Reports provide three Y-axis display types: **Cost**, **Usage**, and [**Count**](#count-reporting). Usage-Based Reporting shows infrastructure consumption in non-monetary metrics, such as virtual machine running hours, stored gigabytes of data, and read/write units consumed. See the [Usage-Based Reporting](/usage_based_reporting) documentation for details.
## Comparative Cost Reporting
### Side-by-Side Comparison Charts
Create comparative Cost Reports by configuring the X axis to show different groupings (like region, service, or team) and using multi-bar charts. This displays current and previous period costs side-by-side for each grouping, making it easy to compare spending across different categories.

To create a comparative report:
Create a Cost Report with a multi-bar chart visualization.
Configure the X axis to group by your desired dimension (e.g., region, service).
The chart will automatically show current period and previous period bars for each grouping, allowing you to compare costs across different categories.
### Update the Costs Table
To compare costs day by day, week by week, month by month, or quarter by quarter on Cost Reports, click the **By Date** option above the cost table. A view of costs with the same date binning selected for the graph is displayed. To switch back to the previous, current, and percent change view, select **Cumulative**.

When you view the **By Date** option, a **Total Costs** row is displayed at the top of the table.
## Export Cost Reports
You can export Cost Reports as **CSV** or **PDF** files to share with other Vantage users. You can also create an export that includes both file formats. Reports with [Configurable X Axis settings](/cost_reports#configure-the-x-axis) can be exported just like any other report.
Export a Cost Report that matches your current filters, dimensions, and date range. To change dimensions, update the underlying report before exporting.
Use the Cost Report export flow when you want a point-in-time CSV (including CSVs in the FOCUS schema) or PDF file that matches the current report view. If you need recurring automation or want to retrieve cost data directly into your own systems, use the [Vantage API](/api) instead.
PDF exports include the following elements:
* Cost Report title
* Date range
* Link at the top to the associated Cost Report in Vantage
* Accrued costs represented in the Cost Report
* Color-coded legend for the Cost Report groupings
* Graphical representations of your Cost Report (supports all Vantage chart types)

If your Cost Report has any associated business metrics, budgets, or a forecast, these elements will also be displayed.
An example export, with groupings of Service **Category** and Service **Subcategory**, is shown below. You can also export grouped Cost Reports and the groupings will be respected in the downloaded CSV.

To export a Cost Report:
Open any Cost Report.
From the top right, click the download icon (looks like an arrow with a line below it).
The **Export Data** modal is displayed. Select any relevant **Groupings**, which will be expressed as additional columns in CSV exports and in the chart legend of PDF exports.
The columns can be any combination of groupings from the following list:
* Provider (e.g., AWS, GCP, New Relic)
* Service (e.g., EC2, EBS)
* Region (e.g., us-east-1)
* Service category (e.g., Storage, Compute)
* Service subcategory (e.g., m5.large, StandardTier)
* Charge Type (e.g., Usage)
* Account (e.g., AWS member account, GCP project)
* Billing Account (e.g., billing account name)
* Resource ID (e.g., S3 bucket ARN, MongoDB Atlas cluster name)
* Usage Unit (e.g., `GB-Mo`, `Hrs`)—adds a column for the unit of measure. This grouping is automatically selected when the report is in [usage view](/usage_based_reporting).
* Tag key, which will be included as an additional column in the export, in the following format: `Tag:` (e.g., `Tag:Project`).
For **File Format**, select **CSV**, **PDF**, or both.
Enter the email addresses that should receive the export. You can select existing Vantage users or enter any email address that belongs to your organization's verified domain.
The export email contains a link to download the report from the Vantage console, which requires signing in. Recipients who open the report must therefore be Vantage users. This makes it possible to send the export to a distribution list on your verified domain, as long as the people who ultimately download it have Vantage accounts.
Select a date range and date bin for the export.
For the **Date Bin** export option, when you select **Week**, the week in the export will begin on Monday, UTC. When you select **Month**, the month in the export will begin on the first of the month, UTC.
For the **Schema** option, select one of the following:
* **Vantage**: The default export schema.
* **FOCUS**: The [FinOps Foundation FOCUS](https://focus.finops.org/) schema.
* **Comparison**: Exports the current period, previous period, change (\$), and change (%) for each grouping. This option is only available when previous period comparison is enabled on the report.
For a Count report, the **Vantage** schema exports whole-number Count values for the selected groupings and date bins instead of cost values. The **FOCUS** and **Comparison** schemas continue to export cost data.
If your Cost Report has an associated [business metric](/business_metrics), a separate toggle is displayed at the bottom of the export modal. This allows you to export unit costs alongside your cost data as a separate CSV file.
Click **Export**.
When the export is finished generating, you'll receive an email with a link to download the exported data from the Vantage console, typically within a few minutes. The link requires signing in to Vantage and expires after 90 days. Large date ranges may take longer.
If you select both PDF and CSV, you'll be sent a link to download a ZIP folder containing both files. All PDF exports come in the landscape orientation to optimize the layout of the chart.
## Frequently Asked Questions
A `$0` value for a previous month usually means cost data has not finished importing for that period. This can happen when a new integration is still backfilling historical data, or when an existing integration has entered an error state. Check your [integration status](/vantage_account#integration-status) to confirm all connected providers show a **Stable** status. If a provider shows **Importing**, it is still completing its initial data import. If a provider shows **Error** or **Warning**, review the integration settings to resolve the issue. See the [provider data refresh documentation](/provider_data_refresh) for expected refresh timing per provider.
Cost Reports compare the selected date range to the same previous period by default. If the comparison period had unusually high or low spending (such as a one-time purchase or a month with partial data), the current month's change percentage may appear misleading. Open the date picker and review the **Comparing to Previous Period** dates to confirm the comparison range is correct. You can also select a custom comparison period for a more accurate baseline.
Several settings affect how costs are calculated. Check the following on your Cost Report by clicking **Cost Settings** at the top:
* **Amortization**: When enabled, upfront payments (such as Reserved Instances) are spread across the commitment period. Your provider's console may show actual costs instead.
* **Credits, Discounts, Refunds, and Tax**: Vantage includes or excludes these based on your report settings. Toggle these options to match what your provider's billing console displays.
* **Data freshness**: Provider cost data refreshes on a schedule that varies by provider. See the [provider data refresh documentation](/provider_data_refresh) for expected timing.
Open the **Filters** menu on a Cost Report and add a **Category**, **Subcategory**, or **Resource** rule. By default, these filters are scoped to a specific service. To search across all services for a provider, select **All Categories**, **All Subcategories**, or **All Resources** from the filter dropdown. Filter values are case-sensitive.
Available values vary by provider. For example, AWS subcategories are usage type descriptors like `DataTransfer-Out-Bytes`, while Datadog subcategories distinguish `Commitment` from `On Demand`.
When you query costs with a `cost_report_token`, the API starts from that Cost Report's saved settings and applies any request-level overrides. The report's saved **Y-Axis** determines whether results aggregate by cost, usage, or count. To use a different aggregation for a specific request, pass `settings[aggregate_by]` with `cost`, `usage`, or `count`.
To drill into an unexpected increase, try the following:
1. On your Cost Report, add a **Group By** for **Resource** to identify which specific resources drove the spike.
2. Adjust the date bin to **Daily** to pinpoint the exact date the increase started.
3. For AWS networking costs, use [Network Flow Reports](/network_flow_reports) to investigate traffic patterns that may explain increases in services like NAT Gateway or data transfer.
A filter set that uses **All Providers** queries data from every connected provider, so it has more data to scan than a single-provider filter. Vantage still narrows the query to the relevant billing data for your organization, but you can keep these reports fast by:
* Adding specific filter rules (e.g., a particular account, service, or region) to reduce the amount of data scanned.
* Using exact-match operators (`is`, `is one of`) instead of partial-match operators (`contains`, `starts with`, `flexible match`) where possible.
* Creating one filter set per provider when you only care about two or three providers, rather than using **All Providers**.
## Starred By Me
If you want to save your favorite Cost Reports or [folders](/folders) to a convenient location, you can *star* specific resources.
From the [All Cost Reports](https://console.vantage.sh/reporting) screen, select the checkbox next to one or more Cost Reports.
Above the list, click **Star**. A star icon will be displayed next to the report.
To access all starred reports, navigate to the [**Starred By Me**](https://console.vantage.sh/reporting?starred=true) screen, also accessible from the left Reporting navigation pane.
# Custom LLM Enrichment
Source: https://docs.vantage.sh/custom_llm_enrichment
Attribute LLM spend to teams, users, applications, and features by delivering your own per-request token telemetry to an S3 bucket that Vantage reads and joins to your provider costs.
Contact Sales (or [support@vantage.sh](mailto:support@vantage.sh)/your account team) to enable LLM Enrichment for your account and discuss availability.
Vantage reads your own per-request LLM usage logs from an S3 bucket and joins them to your model-provider costs. Each record describes one model call: the provider, model, token counts, and the allocation `tags` you attach. Vantage splits each matching cost row into enriched rows by token share and adds your `tags` to each row. This surfaces spend the provider bill never itemized, so you can filter and group it in [Cost Reports](/cost_reports), [Virtual Tags](/tagging), [Budgets](/budgets), and [Cost Alerts](/cost_alerts). Because you emit the telemetry yourself, this works with or without an AI gateway, even when applications share one API key the bill cannot break apart.
The **Custom LLM Enrichment** integration enriches costs for Vantage's native model-provider integrations: **OpenAI**, **Anthropic**, **AWS Bedrock**, **Google Cloud** (Vertex AI Gemini and Marketplace Claude), and **Azure**. You deliver one telemetry stream in the **Token Cost Allocation Specification**, a single, provider-agnostic schema, and Vantage routes each record to the matching provider's costs.
**Using Amazon Bedrock?** Connect [AWS Bedrock LLM Enrichment](/aws_bedrock_enrichment) instead. It reads the Model Invocation Logs AWS already writes for you, so there is no telemetry to emit or maintain in your own applications. Reach for Custom LLM Enrichment for Bedrock only when your Bedrock traffic runs through an AI gateway that already emits per-request telemetry, or when you want one stream to cover several providers at once.
Do not enable both for the same AWS account. Both features allocate the same Bedrock cost rows, so running them together counts the same usage twice in the token pool: your totals still reconcile, but each source's slices receive a diluted share and the attribution becomes misleading.
Custom LLM Enrichment is complementary to [Managed AI Tags](/managed_ai_tags): Managed AI Tags normalize the fields your providers already report into a shared `vntg:ai:` schema, while Custom LLM Enrichment enriches costs with per-request dimensions the provider bill leaves out. Enriched rows also carry `vntg:ai:` tags (including gateway-derived keys such as `vntg:ai:endpoint` and `vntg:ai:service_tier`) as described in [Enrichment Tag Reference](#enrichment-tag-reference).
Enrichment is metadata-only. Vantage reads the provider, model, token counts, and the allocation `tags` you choose to emit. Vantage does not collect or store your prompt or completion content, and it is never written to a Vantage-owned artifact. This data is not used to train any models.
## How It Works
Your application (or the gateway in front of it) emits one JSON record per LLM request in the [Token Cost Allocation Specification](#step-1-emit-telemetry-in-the-common-schema). You write those records to an S3 bucket you own, and Vantage joins them to your provider costs during that provider's cost ingestion.
See [How LLM Enrichment works](/llm_enrichment#how-it-works) for the shared indexing, join, split, and tag pipeline.
### How Telemetry Matches Provider Costs
Provider bills typically aggregate many requests into token-usage line items, so Vantage does not match one telemetry record to one provider request. Instead, Vantage groups your records into daily usage buckets and joins those buckets to compatible provider cost rows.
Every provider uses the following base fields. The first four form the initial match; `resource_account_id` then scopes the result to the correct account.
| Telemetry field | Match method | Matched bill dimension | How Vantage uses it |
| - | - | - | - |
| `timestamp` | Exact match by UTC date | Billing date | Converts the request time to a UTC billing date. |
| `provider` | Exact match after normalization | Cost provider | Routes the record only to costs from the corresponding provider integration. |
| `model` | Provider-normalized match | Model or SKU identity | Normalizes the provider's model identifier and matches it to the model represented by the cost row. |
| `usage.*` | Exact match by token kind | Billed token category or SKU | Maps each positive token count to a billing usage kind: input, output, cache read, or cache write. Each kind matches separately. Input can be reported as an explicit uncached count or as a total input count that Vantage derives uncached input from; both resolve to the same input kind. |
| `resource_account_id` | Scope after the initial match | Provider account, project, or subscription | Restricts telemetry to costs from the same provider-native account. Include it when one bucket supplies telemetry for multiple integrations of the same provider. |
Some providers use additional fields to qualify the model match or to scope the result. Each row lists every provider the field applies to.
| Provider(s) | Telemetry field | Match method | Matched bill dimension | Matching behavior |
| - | - | - | - | - |
| OpenAI, Azure OpenAI | `service_tier` | Model qualifier with controlled fallback | Billing service tier (Azure: data-zone, regional, or global meter scope) | Keeps separately billed tiers distinct. OpenAI allows a compatible fallback when an exact tier is unavailable; Azure maps the tier to its meter scope. |
| OpenAI, Azure OpenAI | `model` snapshot or alias | Normalized model fallback | Billed model | Exact model matches are preferred; dated snapshots and their normalized short aliases can match when an exact counterpart is unavailable. |
| OpenAI | `endpoint` | Model qualifier with controlled fallback | Default or regional endpoint class | Regional telemetry matches regional-endpoint costs first. Telemetry without an endpoint retains compatibility with eligible costs. |
| OpenAI, Anthropic | `api_key_id` | Scope after the initial match | Provider API key or actor identity | Restricts telemetry to cost rows carrying the same provider-native identity. |
| Anthropic, Google Cloud Marketplace Claude | `tags.context_window` or `tags["anthropic:context_window"]` | Model qualifier with model-only fallback | Billed context window | Set the value to `0-200k` or `200k-1M` when known. If omitted, Vantage can share model-level telemetry across that model's window-specific cost rows. |
| Azure OpenAI, AWS Bedrock | `service_tier: "batch"` (the `is_batch` boolean is also accepted) | Model qualifier | Batch meter or token SKU | Keeps batch usage separate from non-batch usage. Prefer `service_tier`, which is also surfaced as a tag. |
| AWS Bedrock | `provider_region` | Model qualifier with wildcard fallback | Billed Region | Bedrock prices the same model differently per Region. |
| AWS Bedrock | `operation` | Model qualifier with wildcard fallback | Streaming or non-streaming inference | Bedrock prices streaming and non-streaming inference separately. |
| AWS Bedrock | `inference_scope` | Model qualifier with wildcard fallback | Global or regional inference profile | Bedrock prices global and regional inference profiles separately. If omitted, Vantage infers the scope from an inference-profile prefix on the model identifier. |
| AWS Bedrock | `identity_id`, `identity.id`, `identity_arn`, or `identity.arn` | Scope after the initial match | IAM principal | Restricts telemetry by principal when comparable identity data is present in CUR 2.0. |
For AWS Bedrock, `provider_region`, `operation`, and `inference_scope` are optional qualifiers rather than requirements. When your telemetry omits one, Vantage treats it as a wildcard that matches any value on the cost side, and it matches exactly qualified telemetry first so the wildcard only absorbs costs that nothing else claimed. Sending these fields produces more precise attribution when you run the same model across Regions, inference profiles, or streaming and non-streaming calls.
### How Cost Rows Are Split
Vantage splits each matching provider cost row into enriched rows, allocated proportionally by token share. Splits are additive, so the enriched rows always reconcile to the original total: usage your logs do not cover stays on a **leftover** row, and cost rows with no matching usage pass through unsplit. Enabling enrichment never changes your totals.
See the allocation formula, a worked example, and how leftover rows keep totals reconciled.
### Data Freshness and Backfill
Enrichment runs as part of each provider's existing cost ingestion, so it follows that provider's refresh cadence. Recent days are reprocessed within a rolling three-day window so late-arriving logs are picked up. See the [provider data refresh documentation](/provider_data_refresh) for per-provider timing.
A billing period is enriched whenever it is processed while an active source exists, for as long as the matching logs remain in your bucket. Late-arriving logs for recent days are picked up automatically within the rolling three-day window. For older periods, Vantage re-enriches a day when the set of log objects for that day changes (files are added or removed) or when a full rebuild is triggered; replacing the contents of an existing object under the same key does not, on its own, re-trigger enrichment. Re-enrichment reads the already-normalized cost data, so it does not require a full cost re-import.
## Prerequisites
Before you begin, make sure:
* An active cost integration exists for at least one supported provider: [OpenAI](/connecting_openai), [Anthropic](/connecting_anthropic), [AWS](/connecting_aws), [Google Cloud](/connecting_gcp), or [Azure](/connecting_azure).
* An active [AWS integration](/connecting_aws) (cross-account IAM role) exists for the account that owns the telemetry bucket. Vantage reads the bucket through this role, so it is required even when the costs you enrich come only from OpenAI, Anthropic, Google Cloud, or Azure.
* You have an S3 bucket you own where you write (or will write) your telemetry.
* You have a Vantage **Organization Owner** or **Integration Owner** role. See [Role-Based Access Control](/rbac).
## Set Up Custom LLM Enrichment
Setup has two steps: [emit your telemetry in the common schema to S3](#step-1-emit-telemetry-in-the-common-schema) and [connect the source in Vantage](#step-2-connect-the-source-in-vantage), where you grant Vantage read access to the bucket and then review which providers Vantage detected. If you don't already produce these logs, the cold-start demo below turns an OpenAI or Anthropic API key into spec-conformant `YYYY/MM/DD/*.jsonl.gz` records you can deliver to S3, a fast way to see enrichment work before you instrument production traffic.
### Step 1: Emit Telemetry in the Common Schema
Records follow the Token Cost Allocation Specification. Write one JSON object per request as newline-delimited JSON (JSONL), gzip-compressed, under a date-partitioned path:
```text theme={null}
s3:////YYYY/MM/DD/*.jsonl.gz
```
* Use the request timestamp's UTC date for the `YYYY/MM/DD` partition.
* Place the logs at the bucket root or under any prefix (subfolder); keep the `YYYY/MM/DD` date structure at the end of the path.
* Write one record per line; do not wrap records in an outer JSON array.
* Batch many records into larger gzipped files rather than writing one object per request.
* Vantage reads these logs from the connected bucket when importing provider cost data; logs are not pushed directly to Vantage.
A single record looks like this:
```json theme={null}
{
"event_id": "ail_3EG...", // stable per-request dedup key
"timestamp": "2026-05-26T17:59:06.235207Z", // UTC, explicit Z
"provider": "openai", // provider identity, separate from model
"model": "gpt-5.2-2025-12-11", // model as reported by the provider
"resource_account_id": "proj_abc123", // provider-native account (e.g. OpenAI project)
"provider_region": "us-east-1", // provider region
"service_tier": "default", // provider processing tier; use "batch" for batch requests
"endpoint": "default", // default or regional
"api_key_id": "key_abc123", // OpenAI key id or Anthropic actor email, never the secret sk-...
"usage": { // at least one positive token count required
"input_tokens": 2129,
"uncached_input_tokens": 1557,
"output_tokens": 112,
"cache_read_input_tokens": 572,
"cache_write_input_tokens": 0
},
"tags": { // arbitrary allocation dimensions
"team": "growth",
"purpose": "summarization"
}
}
```
The sections below define each part of the record: [Core fields](#core-fields) are required on every record, [Usage fields](#usage-fields) carry the token counts (at least one must be a positive integer), [Optional fields](#optional-fields) add context and extra allocation dimensions, [Tagging guidance](#tagging-guidance) explains how `tags` and top-level metadata become cost dimensions, and [Record validity](#record-validity) covers what makes a record count.
#### Core Fields
These fields are required on every record.
| Field | Type | Requirement | Description |
| - | - | - | - |
| `event_id` | String | **Required** | Stable, unique identifier for the request. Vantage uses it to deduplicate records; it is not available as an allocation dimension. |
| `timestamp` | String | **Required** | Request time as an ISO 8601 timestamp in UTC with an explicit `Z` suffix. Determines the billing day the record joins to. |
| `provider` | String | **Required** | AI provider that handled the request. Kept separate from `model` so a provider's costs only match that provider's telemetry. *See the accepted values below.* |
| `model` | String | **Required** | Model identifier as reported by the provider, keeping any provider-specific prefixes (for example, Bedrock's `anthropic.` or Vertex's `models/`). This is the default join key against your provider cost data. |
| `usage` | Object | **Required** | Token counts for the request. At least one [usage field](#usage-fields) must be a positive integer. |
Set `provider` to the identity that matches your cost integration.
| Provider | Accepted `provider` values |
| - | - |
| OpenAI | `openai` |
| Anthropic | `anthropic` |
| AWS Bedrock | `aws`, `bedrock` (prefer [AWS Bedrock LLM Enrichment](/aws_bedrock_enrichment)) |
| Google Cloud | `gcp`, `gemini`, `google`, `vertex` |
| Azure | `azure` |
Vantage normalizes model identifiers on both sides so gateway logs and provider billing join even when they differ. For example, OpenAI billing always uses dated model names (`gpt-5.2-2025-12-11`) while your logs may use dated or undated names (`gpt-5.2`); Vantage prefers the dated form and normalizes undated names to match.
#### Usage Fields
The `usage` object is required. At least one field below must be a positive integer; no single field is always required, so include the counts that describe the request.
| Field | Description |
| - | - |
| `input_tokens` | Total input tokens, including cached tokens. Used to derive uncached input when neither explicit uncached field is present. |
| `non_cache_input_tokens` | Explicit uncached input token count. Preferred over `uncached_input_tokens` and `input_tokens` when present. |
| `uncached_input_tokens` | Explicit uncached input token count. Used when `non_cache_input_tokens` is absent. |
| `output_tokens` | Tokens generated by the model. |
| `cache_read_input_tokens` | Input tokens read from a cache. Missing values are treated as zero during uncached-input derivation. |
| `cache_write_input_tokens` | Input tokens written to a cache. Missing values are treated as zero during uncached-input derivation. |
Emit whichever input field your gateway reports. `non_cache_input_tokens`, `uncached_input_tokens`, and `input_tokens` all resolve to the same input token kind, so you do not need to send more than one. When neither explicit uncached field is present, Vantage derives uncached input as:
```text theme={null}
max(0, input_tokens - cache_read_input_tokens - cache_write_input_tokens)
```
#### Optional Fields
These fields are optional. Include the ones present on each request to improve matching and add allocation dimensions. `resource_account_id` is recommended when one bucket carries logs for multiple integrations of the same provider.
If you connect more than one integration for the same provider (for example, two OpenAI accounts) and your telemetry does not include `resource_account_id`, Vantage cannot tell which integration each record belongs to, and those integrations' costs will not be enriched.
| Field | Type | Requirement | Description |
| - | - | - | - |
| `status` | String | Optional | Request status. Omit or leave it blank for successful requests, or set it to `success` (case-insensitive). Records with any other status are skipped. |
| `resource_account_id` | String | Recommended | Provider account that generated the usage (OpenAI project or organization, Anthropic workspace or organization, AWS usage account, Azure subscription, or Google Cloud project). Include it when one bucket supplies logs for multiple integrations from the same provider so Vantage matches each request to the correct costs. Must be top-level; `tags.resource_account_id` is ignored. |
| `service_tier` | String | Optional | Provider processing tier, and the preferred way to signal batch processing. Used for matching OpenAI and Azure OpenAI costs; for Azure OpenAI and AWS Bedrock, a case-insensitive value of `batch` separates batch from non-batch usage. Surfaced as the `vntg:ai:service_tier` tag. |
| `is_batch` | Boolean | Optional | Whether the request used batch processing. Still accepted for matching Azure OpenAI and AWS Bedrock costs, but `service_tier: "batch"` is preferred because `is_batch` is not surfaced as a tag on enriched rows. |
| `endpoint` | String | Optional | Endpoint class used for the request. Use `default` or `regional`. For OpenAI, enables matching regional-endpoint cost line items when present. A top-level value overrides `tags.endpoint`. |
| `api_key_id` | String | Optional | Provider-native API key identifier. For OpenAI, the `key_...` id from the usage or admin API (never the secret `sk-...` key); for Anthropic Analytics, the actor email associated with the request. Must be top-level. Supports grouping and allocation, and for OpenAI and Anthropic direct imports enables matching costs already split by API key. |
| `identity_id` | String | Optional | AWS (Bedrock) only. IAM principal that made the request (also accepts nested `identity.id`, or legacy `identity_arn` / `identity.arn`). Surfaced as the `vntg:ai:principal_id` tag regardless of your CUR format. When your AWS costs also use [CUR 2.0 with caller identity (IAM principal) allocation data enabled](/connecting_aws#cur-format), Vantage additionally matches by principal so a cost row only draws from invocations by that caller. |
| `provider_region` | String | Optional | Provider Region for the request. For AWS (Bedrock), used to match costs, because Bedrock prices the same model differently per Region. For other providers, available as a grouping and allocation dimension. |
| `operation` | String | Optional | AWS (Bedrock) only. API operation that served the request. Accepts `InvokeModel`, `Converse`, `InvokeModelWithResponseStream`, `ConverseStream`, or the normalized values `inference` and `streaming`. Separates streaming from non-streaming inference, which Bedrock prices separately. Unrecognized values are treated as though the field were omitted. |
| `inference_scope` | String | Optional | AWS (Bedrock) only. Whether the request used a global or regional inference profile. Use `global` or `regional`. If omitted, Vantage infers the scope from an inference-profile prefix on the model identifier (for example, `global.anthropic...` or `us.anthropic...`). |
| `request_id` | String | Optional | Gateway request identifier. Useful for troubleshooting, but not used to match telemetry to costs or added to allocation dimensions. |
| `provider_request_id` | String | Optional | Request identifier assigned by the provider. Useful for troubleshooting, but not used to match telemetry to costs or added to allocation dimensions. |
| `tags` | Object | Optional | Custom key/value dimensions for grouping, filtering, and allocating costs. Prefer stable keys with a limited set of values, such as `team`, `environment`, and `purpose`. Custom tags do not affect matching, except `context_window` or `anthropic:context_window` for Anthropic and Google Cloud Marketplace Claude. |
#### Tagging Guidance
These rules govern how your `tags` and top-level metadata become cost dimensions, and which values to keep out of `tags`.
* Top-level `service_tier`, `is_batch`, `provider_region`, `endpoint`, `api_key_id`, `operation`, and `inference_scope` values override fields with the same names inside `tags`.
* `resource_account_id` must be top-level and cannot be supplied through `tags`.
* To signal batch processing, set `service_tier` to `batch` rather than sending `is_batch`. Both are accepted for matching, but only `service_tier` is surfaced as a tag you can group and filter on; `is_batch` is used for matching and then dropped.
* For Anthropic and Google Cloud Marketplace Claude, set `tags.context_window` or `tags["anthropic:context_window"]` to `0-200k` or `200k-1M` when you know the request's context window. This value participates in matching; other custom tags do not.
* Keep `request_id`, `provider_request_id`, `flow_run_id`, and similar request identifiers out of `tags`, since they are high-cardinality and are not used as allocation dimensions.
* Avoid dimensions with very high cardinality or personally identifiable information (for example, email addresses or conversation identifiers) unless operationally necessary.
Never include API key values, credentials, secrets, or other sensitive authentication material in any field or tag.
#### Record Validity
For a record to be counted, it must describe a successful request with usage Vantage can match to your costs. A record is skipped when:
* A required field (`event_id`, `timestamp`, `provider`, `model`, or `usage`) is missing, or the `timestamp` is blank or cannot be parsed.
* The `provider` is blank or not a supported value, or the `model` is blank or cannot be matched to your provider cost data.
* The `status` is set to anything other than `success` (omit it or leave it blank for successful requests).
* No `usage` field contains a positive integer.
### Step 2: Connect the Source in Vantage
In Vantage, go to the [Integrations page](https://console.vantage.sh/settings/integrations) and, under **LLM Enrichment**, add **Custom LLM Enrichment**, then select the S3 bucket that holds your telemetry. The connect screen walks you through granting read access and validating it, and connecting then scans your recent logs so you can review which providers were found.
You can connect one or more buckets per account. After you connect a bucket, Vantage scans your recent logs and you choose which of your supported provider cost integrations should receive enrichment from that bucket; you can change that selection later from the source's **Manage** tab. Provider cost integrations you connect *after* setting up a source are not enriched automatically; open the source's **Manage** tab and enable the new integration there.
Connecting reuses your existing [AWS cross-account IAM role](/connecting_aws#how-vantage-connects-with-aws), adding read-only access to the bucket that holds your telemetry. It does not create a new role or require new credentials.
Select the S3 bucket that receives your telemetry.
If your bucket does not appear in the list, it may not be synced into Vantage's inventory yet. Newly created buckets can take up to 24 hours to appear.
Deploy in the **AWS account that owns the telemetry bucket**, and make sure the bucket ARN in the policy matches the bucket you connect in Vantage. A mismatch is the most common cause of an `access denied` result when you check permissions.
The connect screen offers three ways to grant access, each prefilled for your account:
The connect screen provides a CloudFormation quick-create link that opens the AWS Console with the stack name, template URL, and parameters prefilled. Acknowledge that CloudFormation may create IAM resources, then create the stack.
The stack applies the [Vantage-published template](https://vantage-public.s3.amazonaws.com/vantage-integration-custom-llm-enrichment.json) with two parameters:
* `VantageCrossAccountRole`: the name of your existing Vantage cross-account IAM role.
* `CustomLlmEnrichmentBuckets`: a comma-separated list of telemetry bucket ARNs, each as `arn:aws:s3:::your-bucket/*`.
Deploy the stack in the account that owns the bucket, not necessarily your management/payer account.
The connect screen provides a ready-to-run `aws cloudformation create-stack` command using the same template and parameters as the Console method:
```bash theme={null}
aws cloudformation create-stack \
--stack-name CustomLLMEnrichmentSourceAccess- \
--template-url https://vantage-public.s3.amazonaws.com/vantage-integration-custom-llm-enrichment.json \
--capabilities CAPABILITY_IAM \
--region us-east-1 \
--parameters \
ParameterKey=VantageCrossAccountRole,ParameterValue= \
ParameterKey=CustomLlmEnrichmentBuckets,ParameterValue=arn:aws:s3:::your-bucket/*
```
Run the command with credentials for the AWS account that owns the bucket. For multiple buckets, pass a comma-separated list of ARNs as a single `ParameterValue`.
If you manage your Vantage integration with the [`vantage-sh/vantage-integration/aws`](https://registry.terraform.io/modules/vantage-sh/vantage-integration/aws/latest) module, add the telemetry read permissions through the module's `additional_inline_policies` argument:
```hcl main.tf theme={null}
module "vantage-integration" {
source = "vantage-sh/vantage-integration/aws"
additional_inline_policies = [
{
name = "CustomLLMEnrichmentSource-"
policy = jsonencode({
Version = "2012-10-17",
Statement = [
{
Action = ["s3:GetObject", "s3:GetObjectAcl"],
Resource = ["arn:aws:s3:::your-bucket/*"],
Effect = "Allow"
}
]
})
}
]
}
```
This attaches the policy to your existing cross-account role; it does not create a new role. Bucket listing and location come from the base role, so only object read is added here. See the [Terraform documentation](/terraform#vantage-terraform-integrations-module-for-aws) for base module setup.
Whichever method you use, Vantage needs the following read-only access to validate and ingest telemetry:
| Permission | When it is needed |
| - | - |
| `s3:GetObject` | Read the telemetry objects in the bucket you connect. |
| `s3:ListBucket` | List objects under the log path to find your telemetry. |
| `s3:GetBucketLocation` | Resolve the bucket's Region. |
| `kms:Decrypt` | The bucket or objects are encrypted with AWS KMS (SSE-KMS). Without it, Vantage cannot read KMS-encrypted objects. |
Your existing Vantage cross-account role already grants `s3:ListBucket` and `s3:GetBucketLocation`. The grant above adds only object read on the telemetry bucket (`s3:GetObject`, and the generated policy always includes `s3:GetObjectAcl`).
The CloudFormation, CLI, and Terraform options above grant S3 read access only. If your telemetry bucket uses SSE-KMS encryption, you must grant `kms:Decrypt` separately. See [KMS-Encrypted Buckets](#kms-encrypted-buckets).
Click **Check Permissions**. Vantage validates that it can resolve the bucket Region, list objects, and read a sample object. It also samples recent objects to verify the `YYYY/MM/DD/*.jsonl.gz` layout, gzip compression, and that records match the common schema. Blocking problems (for example, objects that are not under the date layout, uncompressed `.jsonl` logs, or sampled records missing required fields) are shown as errors you must resolve before connecting. Nonblocking findings still let you connect: an empty bucket is shown as a notice, while sibling integrations whose sampled logs omit `resource_account_id` produce a warning. Then click **Connect**. Vantage confirms the source and immediately scans your recent gateway logs, from the first day of the previous calendar month through today, to detect which providers and provider accounts appear in the bucket. You are taken to a **Scanning gateway logs** page that refreshes on its own; a large bucket can take several minutes.
A success message confirms the source is connected and scanning has begun. When the scan finishes, a **Review** action appears for the source. See the [Troubleshooting](#troubleshooting) section for any errors that are displayed.
When the scan finishes, select **Review** for the source. This opens the **Manage** tab of the source's details page. The review screen has one row per enrichable connected cost integration, grouped by provider, and shows each row's **Valid rows** and **Invalid rows** counts. Providers found in your logs that you have not connected a cost integration for appear as non-selectable rows. The **Notes** column shows **Success** when rows were found, **No rows found** when none were, and flags such as gateway logs missing `resource_account_id` or **Account identifiers not found: …** when account IDs could not be matched to a cost integration. Logs found for unsupported providers appear in a separate banner, not the Notes column. If more than 75% of the scanned rows failed validation, a warning ("N% of scanned log rows failed validation") suggests confirming that your objects use the common-schema `YYYY/MM/DD/*.jsonl.gz` format and include the required fields (`provider`, `model`, `usage`, and `status`).
Choose which connected cost integrations should receive token enrichment from this bucket, then select **Confirm**. Vantage enriches costs for the selected integrations on each provider's next data refresh. You can change the selection later from the source's **Manage** tab.
## Manage Custom LLM Enrichment Sources
Manage your connected buckets from the **Custom LLM Enrichment** integration page. The sources table lists each bucket with its AWS account, creation date, and **Status** (for example, **Pending** before an import starts, **Importing** while one runs, **Stable** once all imports succeed, **Warning** if only some imports fail, **Error** if a scan or all imports fail, or **Paused** if the source is stopped). A shared-bucket warning icon appears next to the bucket name when sibling integrations require `resource_account_id`; error details appear beneath the status.
Select the **bucket name** to open that source's details page, which has two tabs:
* **Import History**, the default tab, shows every enrichment run for the source. See [View Import History](#view-import-history).
* **Manage** is where you choose which cost integrations receive enrichment. See [Choose Which Integrations Are Enriched](#choose-which-integrations-are-enriched).
A **Review** button appears in the row while scan results are waiting on your confirmation, and a **Resume** button appears for stopped sources; both open the **Manage** tab. The row's ellipses (**...**) menu contains **Stop** for sources that are not paused.
### Choose Which Integrations Are Enriched
After a scan finishes, select **Review** on the source to choose which connected cost integrations receive enrichment (see [Step 2](#step-2-connect-the-source-in-vantage)). To change that selection later, select the bucket name and open the **Manage** tab. The Manage tab lists each provider integration with its import status (for example, **Stable**, **Pending**, **Importing**, **Warning**, **Error**, **Paused**, or **Unenriched**), and for a provider with multiple accounts shows a count like *2 of 3 accounts enabled*. It lets you enable or disable enrichment per integration. Disabling an integration here stops going-forward enrichment for it but leaves its existing enriched history in place.
### View Import History
In the sources table, select the **bucket name** to open that source's details page, which shows the **Enrichment Runs** table for that bucket.
The **Enrichment Runs** table lists one row per provider cost integration and billing period that ran enrichment, newest first, with columns for the **Integration** (and its account), **Status**, **Tokens Kept**, **Log Lines Kept**, **Bill Match**, **Billing Period**, and **Last Enriched At**. Lifecycle changes appear as their own rows: **Added** when enrichment is first enabled for an integration, and **Paused** or **Resumed** when you stop, disable, resume, or re-enable it.
The three percentages look similar but measure different things at different stages, so a low number in one column means something very different from a low number in another:
| Metric | Stage | Counts | A Low Value Means |
| - | - | - | - |
| **Tokens Kept** | Join | Tokens | Your logs were read fine, but the usage in them did not line up with your provider bill. |
| **Log Lines Kept** | Log Scan | Log lines | Vantage could not read or index many of your log lines, usually because records are malformed or missing required fields. |
| **Bill Match** | Join | Provider cost rows | Many provider cost rows received no logged usage at all, so they passed through unsplit. Often your logs cover only part of your traffic. |
A low percentage does not change your totals. Usage Vantage cannot attribute stays on a **leftover** row, the unallocated remainder of the original cost row, so the enriched rows always add back up to what the provider billed.
Select the **Tokens Kept** percentage on any run to open **Token Metrics**, which breaks that run down by disposition across the two stages and lets you view sample records for anything that did not make it through.
Full reference for the Import History screen: every column and status, how to read the three percentages, the Log Scan and Join dispositions with a fix for each, sample record fields, and a troubleshooting table.
### Stop a Source
To stop a source, click the ellipses (**...**) next to the row and select **Stop**, then confirm in the **Stop enrichment source** dialog. This is a soft deactivation, not a hard delete: Vantage stops enriching new cost data for that bucket, but your existing enriched history is left unchanged, and the source stays visible in the list so you can bring it back at any time.
Stopping a source does not re-import or roll back already-enriched costs. Going-forward enrichment simply pauses for that bucket until you resume it.
### Resume a Source
To resume a stopped source, select **Resume** in its row. Resuming restarts going-forward enrichment for the integrations that were active when you stopped the source (integrations you had already disabled individually stay disabled) and opens the **Manage** tab so you can adjust the selection. A stopped bucket cannot be re-added through the connect wizard; use **Resume** instead.
## View Enriched Costs on Cost Reports
Once enrichment runs, a single provider cost line is split into multiple rows, each carrying enrichment tags. You can filter and group by these tags anywhere tags are supported: [Cost Reports](/cost_reports), [Virtual Tags](/tagging), [Budgets](/budgets), and [Cost Alerts](/cost_alerts).
Because enrichment splits (allocates) your provider costs, enrichment tags behave like Vantage's [cost allocation tags](/tagging#cost-allocation-tags): you can build a Virtual Tag on them, but a cost can be allocated only once, so an enrichment tag can belong to only [one allocation chain](/tagging#virtual-tag-allocation-rules).
### Enrichment Tag Reference
| Tag key | Description | Example value |
| - | - | - |
| *Your `tags` keys* | Every key in a record's `tags` becomes a tag on the enriched rows for that usage slice. | `team`, `purpose`, `environment` |
| `vntg:ai:model` | The normalized model identifier that generated the cost, derived from the cost row. Vantage adds it to every enriched row. | `vntg:ai:model=gpt-5.2-2025-12-11` |
| `vntg:ai:model_provider` | The provider family inferred from the model (for example, OpenAI, Anthropic, Google, xAI), added automatically alongside `vntg:ai:model` when the family is recognized. | `vntg:ai:model_provider=OpenAI` |
| `vntg:ai:token_type` | The token kind the enriched row covers: `input`, `output`, `cache_read`, or `cache_write`. Added automatically to every enriched row. | `vntg:ai:token_type=input` |
| `vntg:ai:service_tier`, `vntg:ai:provider_region`, `vntg:ai:api_key_id`, `vntg:ai:endpoint`, `vntg:ai:operation`, `vntg:ai:inference_scope` | Promoted from the matching top-level telemetry fields when present and renamed under the prefix, so you can group and allocate by them too. | `vntg:ai:service_tier=default` |
| `vntg:ai:principal_id` | AWS (Bedrock) only. The normalized IAM principal that made the request, added when your telemetry includes `identity_id` (or `identity_arn`). | `my-role/session-name` |
| *Provider's existing tags* | Any tags Vantage already puts on the provider's cost rows are preserved on the enriched rows. If one of these shares a key with a slice `tag`, the enrichment value wins. | — |
Your own `tags` keys appear exactly as you emit them, with no provider prefix. The fields Vantage derives and adds itself, such as the model identifier, carry a `vntg:ai:` prefix (for example, `vntg:ai:model`); this keeps them distinct from your keys and consistent with the AI tags Vantage applies to provider costs. For example, on enriched OpenAI costs you would see `vntg:ai:model` with values like `gpt-5.2-2025-12-11`, and your own keys such as `team` with values like `growth`, not `openai:model` or `openai:team`. Because your key is just `team` (not provider-namespaced), the same key lines up across OpenAI, Anthropic, Azure, and the other providers, so you can group your entire AI stack by one `team` tag. Consistent key naming matters: `team` and `Team` are two different keys.
Enrichment tags behave like any other provider tag in the console:
* **To group:** open the **Group By** menu, select **Tag**, and choose the tag key, for example `vntg:ai:model`, or one of your own keys such as `team`.
* **To filter:** open the **Filters** menu, click **New Rule**, select **Tag**, choose the **Tag Key**, then pick an operator and one or more values.
The tag keys appear in the **Tag Key** dropdown once enriched costs exist. If you use a handful of keys often, mark them as [preferred tags](/tagging#preferred-tags) so they sort to the top of these menus.
Enriched rows retain the provider's existing tags and add the Vantage-managed `vntg:ai:*` tags (such as `vntg:ai:model`); split rows also carry the `tags` from their usage slice. When a slice `tag` and an existing tag use the same key, the enrichment value wins. The leftover row (usage not covered by telemetry) keeps the provider's existing tags and the applicable `vntg:ai:*` tags but carries none of the slice `tags`. Request identifiers (`event_id`, `request_id`, `provider_request_id`, `flow_run_id`) and `resource_account_id` are never turned into tags.
## Troubleshooting
Most errors are displayed when you click **Check Permissions** or **Connect**. The tables below list the messages you may see, their cause, and how to resolve them. Expand a section for the relevant category.
| Message | Cause and fix |
| - | - |
| `Vantage cannot determine the location for bucket {bucket}. Grant s3:GetBucketLocation to the cross-account role.` | Add `s3:GetBucketLocation` to the cross-account role. |
| `Vantage cannot list objects under s3://{bucket}/{prefix}. Grant s3:ListBucket for the configured prefix.` | Add `s3:ListBucket` scoped to the bucket (and prefix, if used). |
| `Vantage cannot read object s3://{bucket}/{key}. Grant s3:GetObject to the cross-account role.` | Add `s3:GetObject` (and `s3:GetObjectAcl`) for the bucket. |
| `Vantage cannot decrypt KMS-encrypted object s3://{bucket}/{key}. Grant kms:Decrypt to the cross-account role.` | The bucket uses SSE-KMS. Grant `kms:Decrypt` for the encrypting key. |
| `Vantage could not assume the AWS cross-account role. Verify that the role exists, its trust policy allows Vantage to call sts:AssumeRole, and the configured external ID matches.` | Vantage cannot assume your [cross-account IAM role](/connecting_aws#how-vantage-connects-with-aws). Confirm the role still exists, its trust policy allows Vantage's `sts:AssumeRole`, and the external ID matches. |
Confirm the permissions were deployed in the **AWS account that owns the bucket**, and that the bucket ARN in the policy matches the connected bucket.
| Message | Cause and fix |
| - | - |
| `Bucket {bucket} does not exist or could not be found.` | The bucket does not exist or is not reachable by the role. Verify the name and account. |
| `No objects matching YYYY/MM/DD/*.jsonl.gz were found in s3://{bucket}/{prefix}. Vantage expects files in that date layout.` (or `No objects were found in s3://{bucket}/{prefix}.`) | The bucket has no `.jsonl.gz` objects under the expected `YYYY/MM/DD` path yet, or they use a different layout. Write a test record in the expected layout and wait for delivery, then re-check. |
| `Vantage scanned 3000 objects in s3://{bucket}/{prefix} but could not find a matching log file. Use a dedicated bucket or a more specific prefix.` | Vantage scanned the first objects under the path without finding a matching log file. Point the source at a dedicated bucket or a more specific prefix so telemetry is found quickly. |
| `Permission check timed out. The bucket may be large, or logs may not use the expected date layout.` | The permission check did not finish in time. Narrow the source to a dedicated bucket or prefix, confirm the `YYYY/MM/DD/*.jsonl.gz` layout, then re-check. |
| `Bucket {names} could not be found for your account.` | The selected bucket is not in Vantage's synced inventory. Newly created buckets can take up to 24 hours to appear. |
| `Connect an AWS, Anthropic, Azure, GCP, or OpenAI cost integration before checking Custom LLM enrichment permissions.` (the Connect action shows `...before connecting Custom LLM enrichment.`) | No enrichable cost integration exists. Connect a supported provider first. |
**Pending** means Vantage has not run an enrichment import for this source yet. Enrichment runs during each provider's regular cost ingestion, so a newly connected source shows **Pending** until the next data refresh of a provider it enriches. See the [provider data refresh documentation](/provider_data_refresh) for per-provider timing. If the status is still **Pending** after that refresh, check the following:
* If a **Review** button appears in the source's row, the scan finished and is waiting on you: select **Review**, choose the cost integrations to enrich, then select **Confirm** (see [Step 2](#step-2-connect-the-source-in-vantage)).
* If you already confirmed, open the source's **Manage** tab and confirm that at least one integration is enabled.
* Confirm your telemetry is still arriving in the bucket under the `YYYY/MM/DD/*.jsonl.gz` layout.
Enrichment can only split costs by dimensions present in your telemetry. Costs pass through without allocation splits when any of the following is true:
* There is no active Custom LLM Enrichment source for the account, or the telemetry has not been ingested for that billing period.
* The cost row's model or token type could not be matched to a logged request for that provider, date, and token kind.
* Records were skipped during ingestion because a required field was missing or invalid, the `provider` was blank or unsupported, the `model` was blank or could not be matched to your provider cost data, the `status` was not successful, or no `usage` value was a positive integer.
Confirm your records set `provider` to an [accepted value](#step-1-emit-telemetry-in-the-common-schema), carry a matching `model`, and include at least one positive usage count.
Enrichment tags appear in the console as regular provider tags. To confirm what was enriched:
* **Check coverage in Import History:** Open the source's [Import History](/llm_enrichment_import_history) and review **Tokens Kept** (the share of your logged tokens Vantage attached to a cost row) and **Bill Match** (the share of eligible provider cost rows that received logged usage) for each integration and billing period.
* **Check a Cost Report:** Filter to the provider, then group by one of your own tag keys. Costs from requests that carried that key show its values. The leftover row (the portion of the bill your usage did not cover) and any usage sent without that key appear as **Not tagged with** the key name.
Totals should not change. Splits are additive and always sum to the original cost row to the cent, even when multiple sources are connected. If a total appears different, this is not expected behavior; contact [Vantage Support](mailto:support@vantage.sh).
### KMS-Encrypted Buckets
If the bucket you connect is encrypted with AWS Key Management Service (KMS), **Check Permissions** reports a decryption error until Vantage can read the objects. Either remove encryption on the bucket, or grant the cross-account role `kms:Decrypt` for the encrypting key and allow that role in the KMS key policy.
The CloudFormation, CLI, and Terraform options in [Step 2](#step-2-connect-the-source-in-vantage) grant S3 read access only, so KMS access must be added separately.
## Use Cases
Each row below shows example `tags` to emit on your telemetry and what that attribution enables in Vantage. The key names are examples; you choose your own, and Vantage surfaces whatever `tags` you send. All rows assume telemetry is delivered to a connected bucket.
| Use Case | Emit in `tags` | What It Enables |
| - | - | - |
| Chargeback by team | `team` | Group a [Cost Report](/cost_reports) by `team` for per-team LLM chargeback, or roll `team` values into a business hierarchy with a [Virtual Tag](/tagging). |
| Per-user attribution on shared keys | `user` | Attribute spend to the individual who made each request even when many callers share one API key, which the provider bill cannot break apart. |
| Per-feature or per-workflow spend | `feature`, `workflow` | Compare cost per product feature or workflow (for example, `summarization` vs. `classification`). |
| Model and effort mix | `mode`, `effort` | Spot macro patterns (which models and effort levels dominate spend) and outliers to guide defaults. The `vntg:ai:model` tag is added automatically, so you do not need to emit it. |
| Environment separation | `environment` | Filter non-production inference out of showback reports, or budget each environment (`production`, `staging`) separately. |
## Frequently Asked Questions
OpenAI, Anthropic, AWS Bedrock, Google Cloud (Vertex AI Gemini and Marketplace Claude), and Azure. You deliver one telemetry stream in the common schema, and Vantage routes each record to the matching provider's costs based on its `provider` value. Azure support covers direct Azure integrations; Azure CSP billing accounts are not supported.
For Amazon Bedrock, use the native [AWS Bedrock LLM Enrichment](/aws_bedrock_enrichment) integration instead, which reads the Model Invocation Logs AWS writes for you. Do not enable both for the same AWS account. They allocate the same Bedrock cost rows, so the same usage is counted twice in the token pool and each source's slices receive a diluted, misleading share.
You need the **Organization Owner** or **Integration Owner** role to connect the source. Viewing the enriched costs does not require a special role; the resulting tags follow the same access rules as other cost data. See [Role-Based Access Control](/rbac).
Read-only access to the bucket you connect: `s3:GetObject`, `s3:ListBucket`, `s3:GetBucketLocation`, and `kms:Decrypt` for KMS-encrypted objects (generated policies may also include `s3:GetObjectAcl`). The policy attaches to your existing cross-account role; no new role is created. See [Step 2: Connect the Source in Vantage](#step-2-connect-the-source-in-vantage).
No. You emit the telemetry yourself, so this works for direct-to-provider traffic (for example, calling OpenAI or Anthropic APIs directly) as well as traffic behind a gateway. The only requirement is that you write common-schema records to S3.
No. Splits are additive and always sum to the original cost row. Existing provider-level reports continue to show the same totals; enrichment only makes new dimensions available on the underlying rows.
No. Enrichment is metadata-only. The telemetry stream carries request identifiers, the provider and model, usage counts, and the allocation `tags` you choose to emit. Prompt and completion text are never collected or stored.
# Dashboards
Source: https://docs.vantage.sh/dashboards
Create customizable dashboards in Vantage to visualize and compare cloud cost data across multiple reports.
Dashboards contain widgets, like reports. You can apply date range and period filters (e.g., display daily costs) to all reports on the dashboard. A consistent date range across all reports on the dashboard can help with cost comparison between different reports. Once a dashboard is created, you can customize the widgets on your dashboard according to your preferences.
To get started with dashboards, you can also watch these video demos on [Vantage University](/vantage_university_cost_reporting) .
You can add the following widget types to dashboards:
## Create a Dashboard
From the top navigation, click **Reporting**.
On the left menu, select **Dashboards**. All existing dashboards are displayed within this view.
Click **New Dashboard**. At the top of the page, you can rename your dashboard. Select the pencil icon and enter a new name.
Add widgets to the dashboard using the empty-state picker or the **Add Widget** menu. See [Add Widgets](/dashboards#add-widgets) below.

## Add Widgets
You can add widgets to a dashboard from the empty-state picker (shown when a dashboard has no widgets) or from the **Add Widget** menu at the top of any dashboard.
On the dashboard, click **Add Widget** (or, on an empty dashboard, use the widget picker in the center of the screen).
Select the widget type you want to add:
* **Report:** Display cost or usage data from any existing report as a chart or table.
* **Free Text:** Add notes, context, or section headers. See [Add a Free Text Widget](/dashboards#add-a-free-text-widget).
For report widgets, select the report to display. New widgets are added at the bottom of the dashboard.
At this time, you cannot add widgets from the Overview page, such as **Provider Summary**.
For each report widget, click the widget title to open the underlying report.
Dashboards have a limit of 50 widgets. Free Text widgets count toward this limit.
## Add a Free Text Widget
Free Text widgets let you add titles, descriptions, and section context to a dashboard so it tells a story rather than just displaying a list of reports.
On the dashboard, click **Add Widget** > **Free Text** (or select **Free Text** from the empty-state picker).
A panel opens on the right side of the screen with a rich text editor. Use the formatting toolbar to style your content. Supported formatting includes:
* Bold, italic, underline, and strikethrough
* Heading 1 and Heading 2
* Bullet and numbered lists
* Blockquotes and inline code
* Links
The Free Text editor is a rich text editor, not Markdown. Use the toolbar controls to format your text.
Click **Add Widget** to place the Free Text widget on the dashboard. You can resize and reposition it like any other widget using [Customize Layout](/dashboards#customize-layout).
Free Text widgets are not included in [PDF exports](/dashboards#export-dashboards).
## Customize a Dashboard
After a dashboard has widgets, you can customize the data it shows and how it's laid out.
### Filter by Date Range and Period
You can apply a consistent date range and period across all reports on the dashboard.
* To change the date range of all displayed reports, click the date picker on the right of the screen and select a date range. If you have edit access to the dashboard, your changes are saved automatically.
* To change the date grouping, click the date bin menu (**Choose Period**) on the top right. Select **Cumulative**, **Daily**, **Weekly**, or **Monthly**. If you have edit access to the dashboard, your changes are saved automatically.
* To clear your date and filter changes and return to the dashboard's saved settings, click **Clear Filters**.
### Edit Widget Settings
You can edit a widget's settings directly from the dashboard, without navigating away to the underlying report. From any widget, click the edit icon to open the widget settings slideout on the right side of the screen. The following settings are available:
* **Widget Title:** Edit the title shown on the widget in the **Widget Title** field. This does not change the name of the associated report.
* **Visualization Type:** Display the widget as a **Chart** or a **Table**. The widget updates automatically.
* **Table View:** For Cost Report widgets displayed as a table, choose **Cumulative**, **Daily**, or **By period**. **By period** displays each time period (bin) as its own column, making period-over-period comparisons easier to read. When the table is wider than its widget, the **Accrued Costs** column remains visible as you scroll horizontally.
* **Chart Legend:** For widgets displayed as a chart, choose to **Show** or **Hide** the legend.
The visualization types available depend on the widget type:
| Widget Type | Chart View | Table View |
| - | - | - |
| Cost Reports | | |
| Usage Reports | | |
| Resource Reports | | |
| Kubernetes Efficiency Reports | | |
| Financial Commitment Reports | | |
| Saved Recommendation Views | | |
Resource Reports and summary-style widgets are displayed as tables only. **Canvas** and **Free Text** widgets do not have visualization settings.
### Customize Layout
You can resize and reorder widgets to control how your dashboard is laid out. Both actions happen in **Customize Layout** mode.
From the top right of a dashboard, click **Customize Layout**.
**Resize a widget** by dragging the resize handles on its edges and corners. Widgets snap to a 12-column grid, so a widget can span anywhere from a portion of a row up to the full dashboard width. Give your most important widgets more space to draw the viewer's eye. Larger widgets show more of their data (for example, more series in a chart or more historical columns in a table), while smaller widgets reflow their content to fit.
**Reorder a widget** by dragging it to a new position on the grid. Other widgets shift to make room.
When you are finished, click **Done customizing layout** to save your changes.
Existing dashboards keep their current widget layout. Resize handles and reordering are available in **Customize Layout** mode without changing your saved layout until you make an edit.
### Duplicate or Delete a Widget
You can duplicate or delete a widget from the widget settings slideout. Duplicating creates a copy with the same report and display settings, inserted directly after the original.
From any widget on a dashboard, click the edit icon to open the widget settings slideout.
In the slideout header, click the ellipses (**...**) menu, then select:
* **Duplicate:** Add a copy of the widget immediately after the original. You can then edit its [name or display settings](/dashboards#edit-widget-settings) independently.
* **Delete:** Remove the widget from the dashboard.
Duplicating a widget is useful when you want to show the same report with different display settings (e.g., one as a chart and one as a table) on the same dashboard.
## Add a Saved Filter to a Dashboard
You can use [saved filters](/saved_filters) to apply consistent filter logic to multiple Cost Reports on a dashboard. If you have a dashboard of high-level Cost Reports (e.g., filtered only to connected providers or services), and you want to further filter a dashboard to a team or specific category, you can use saved filters on dashboards to quickly apply this logic.
From the top right of any dashboard, click the **Apply a Saved Filter** dropdown menu.
Select one or more saved filters. The filter logic is applied across all Cost Reports on the dashboard.
When you add a saved filter to a dashboard, if a preexisting filter on a Cost Report and the saved filter use the same provider (e.g., both use AWS), "AND" logic is used between each filter set (i.e., show costs where the preexisting filter AND saved filter are true). If the preexisting filter and saved filter use different providers, "OR" logic is used between each filter set.
## Set a Default Dashboard
You can set a default dashboard that's displayed when a user logs in to Vantage and visits `console.vantage.sh`, instead of the [Overview](/overview) screen. This default dashboard can be set for a team or by an individual user. When the user logs in to Vantage, they will be redirected to that dashboard, and will be in the [workspace](/workspaces) that is associated with that dashboard.
* If a user is a member of a team with a configured default dashboard and also has a personal dashboard configured, the personal dashboard is displayed.
* If a user is a member of two different teams with configured default dashboards, the user will see the default dashboard of the first team they were added to.
A user with [Organization Owner](/rbac) permissions can set a default dashboard for a team.
From the top navigation, click **Settings**.
From the left navigation, under **General Settings**, click **Teams**.
Under **Default Dashboard**, select the dashboard that should be displayed when a member of the team visits `console.vantage.sh`. If you want to remove the default dashboard and display the Overview page instead, select **None**.
Click **Save**.
From the top navigation, click **Settings**.
From the left navigation, under **Personal Settings**, click **Profile**.
Under **Default Home Page**, select **A specific dashboard**, then choose the dashboard that should be displayed when you visit `console.vantage.sh`. To use a different home page instead, select **Agent** or **Overview page**.
Click **Save**.
A user can also select their personal default dashboard from any existing dashboard. At the top right of the dashboard, click the ellipses. Click **Set as Default Dashboard** and confirm.
## Save a Dashboard to Favorites
To save a dashboard to your favorites, navigate to the [Dashboards](https://console.vantage.sh/dashboards) page, then click the star icon to the right of the dashboard's name. Access your starred dashboard from the **Starred By Me** screen in the left navigation. Dashboards you create are also displayed on the **Created By Me** screen.
## Share a Dashboard
From the top of any dashboard, click the ellipses (**...**) icon, then click **Copy URL**. A link is added to your clipboard where you can share the dashboard with any Vantage user in your organization who has access to view the dashboard. Each widget on the dashboard also has a **Copy Link** option, with a unique link.
## Export Dashboards
You can create visual exports of any dashboard to share with stakeholders outside of Vantage. Dashboard exports are sent via email and include all widgets that can be added to dashboards.
* For table widgets, Vantage displays the first 12 rows to ensure readability and consistent layout across pages
* For more granular exports of tables, use [CSV exporting for each report](/cost_reports#export-cost-reports)
* Dashboards have a limit of 50 widgets, and the PDF will generate with the same number
* [Free Text](/dashboards#add-a-free-text-widget) widgets are not included in PDF exports
* Dashboard exports use the date range currently displayed on screen (from the date picker), even if you haven't saved it to the dashboard
From any dashboard, click the ellipses icon in the top right corner.
From the dropdown, select **Export as PDF**.
Select the emails for any users you want to send the dashboard to.
Click **Export**. Vantage will generate a multi-page PDF with one widget per page. The export preserves chart filters, formatting, and the date range currently displayed on screen at the time of export.
## Dashboard Notifications
You can send automated email notifications of a dashboard to stakeholders on a daily, weekly, or monthly basis. Dashboard notifications include a snapshot of the dashboard at the time the email is sent. See the [Report Notifications](/report_notifications#set-up-dashboard-notifications) docs for more information about setting up dashboard notifications.
## Delete a Dashboard
To delete a dashboard, navigate to the [Dashboards](https://console.vantage.sh/dashboards) page, then click the ellipses to the right of the dashboard's name. Click **Delete**.
# Data Dictionary
Source: https://docs.vantage.sh/data_dictionary
Explore Vantage's normalized data dictionary to understand field mappings across cloud providers.
Each provider that Vantage integrates with makes different fields available in their billing data. This data is normalized into the fields below. These fields are queryable via the [Vantage API](/api) and used when constructing [VQL](/vql) statements.
Each provider table contains four columns: Filter, API Field Name, Data Type, and Example Value.
* *Filter* is the friendly name displayed on Cost Report filters in the Vantage console.
* *API Field Name* is the fully-qualified field reference used in API requests and VQL queries (for example, `costs.account_id` or `tags.name`). Use this exact value when writing VQL.
* *Data Type* indicates the type of data accepted for the field.
* *Example Value* is a representative value to give you a sense of what the field actually contains. This is illustrative, and your data may use different values.
## Usage Unit
**Usage Unit** is a shared field across cost providers. It identifies the unit used to measure a line item's consumption, such as hours, storage, requests, or tokens.
| Filter | API Field Name | Data Type | Example Value |
| - | - | - | - |
| Usage Unit | `costs.usage_unit` | string | `Hours`, `GB-Hours`, `Requests`, `Tokens` |
The **Usage Unit** filter is available for individual providers, Custom Providers, and **All Providers** when the selected provider context contains at least two distinct, non-empty units. If the context contains zero or one unit, Vantage omits the filter because it would not further narrow the report. See [Supported Providers](/usage_based_reporting#supported-providers) for the providers that populate usage data and examples of their units.
Vantage normalizes Usage Unit labels in the console for consistent spelling and capitalization. When querying with [VQL](/vql_cost_report#filter-by-usage-unit), use the exact underlying value shown by **View as VQL**. See [Usage-Based Reporting](/usage_based_reporting#understand-usage-units) for more information.
## Provider Field Values
Each cost provider also has a normalized name within the API. The `provider` field is part of the `costs` namespace.
| Provider | API Field Name | Link to Provider Fields |
| - | - | - |
| AWS | `aws` | [View AWS Fields](/data_dictionary#aws) |
| Anthropic | `anthropic` | [View Anthropic Fields](/data_dictionary#anthropic) |
| Anyscale | `anyscale` | [View Anyscale Fields](/data_dictionary#anyscale) |
| Azure | `azure` | [View Azure Fields](/data_dictionary#azure) |
| Baseten | `baseten` | [View Baseten Fields](/data_dictionary#baseten) |
| Cartesia | `cartesia` | [View Cartesia Fields](/data_dictionary#cartesia) |
| CircleCI | `circle_ci` | [View CircleCI Fields](/data_dictionary#circleci) |
| ClickHouse Cloud | `clickhouse` | [View ClickHouse Cloud Fields](/data_dictionary#clickhouse-cloud) |
| Cloudflare | `cloudflare` | [View Cloudflare Fields](/data_dictionary#cloudflare) |
| Confluent | `confluent` | [View Confluent Fields](/data_dictionary#confluent) |
| Coralogix | `coralogix` | [View Coralogix Fields](/data_dictionary#coralogix) |
| Custom Providers | *See note* | [View Custom Provider Fields](/data_dictionary#custom-providers) |
| Databricks | `databricks` | [View Databricks Fields](/data_dictionary#databricks) |
| Datadog | `datadog` | [View Datadog Fields](#datadog) |
| DigitalOcean | `digital_ocean` | [View DigitalOcean Fields](/data_dictionary#digitalocean) |
| Elastic | `elastic` | [View Elastic Fields](#elastic) |
| ElevenLabs | `eleven_labs` | [View ElevenLabs Fields](#elevenlabs) |
| Fastly | `fastly` | [View Fastly Fields](#fastly) |
| Fireworks AI | `fireworks_ai` | [View Fireworks AI Fields](#fireworks-ai) |
| GitHub | `github` | [View GitHub Fields](#github) |
| Google Cloud | `gcp` | [View GCP Fields](/data_dictionary#google-cloud) |
| Grafana Cloud | `grafana` | [View Grafana Cloud Fields](/data_dictionary#grafana-cloud) |
| Kubernetes | `kubernetes` | [View Kubernetes Fields](/data_dictionary#kubernetes) |
| Linode | `linode` | [View Linode Fields](/data_dictionary#linode) |
| MongoDB Atlas | `mongo` | [View MongoDB Atlas Fields](/data_dictionary#mongodb-atlas) |
| Modal | `modal` | [View Modal Fields](/data_dictionary#modal) |
| New Relic | `new_relic` | [View New Relic Fields](/data_dictionary#new-relic) |
| OpenAI | `open_ai` | [View OpenAI Fields](/data_dictionary#openai) |
| Oracle Cloud | `oracle` | [View Oracle Cloud Fields](#oracle-cloud) |
| PlanetScale | `planetscale` | [View PlanetScale Fields](#planetscale) |
| Redis | `redis_cloud` | [View Redis Fields](#redis) |
| Snowflake | `snowflake` | [View Snowflake Fields](#snowflake) |
| SpaceXAI | `xai` | [View SpaceXAI Fields](/data_dictionary#spacexai) |
| Temporal Cloud | `temporal` | [View Temporal Cloud Fields](/data_dictionary#temporal-cloud) |
| Twilio | `twilio` | [View Twilio Fields](#twilio) |
| Cursor | `cursor` | [View Cursor Fields](#cursor) |
| Vercel | `vercel` | [View Vercel Fields](#vercel) |
To reference a [Custom Provider](/connecting_custom_providers) in VQL queries, navigate to the [**Integrations** page](https://console.vantage.sh/settings/custom_providers). Use the displayed **Provider ID** (e.g., `custom_provider:accss_crdntl_123a45bfdaf38765`).
## AWS
| Filter | API Field Name | Data Type | Example Value |
| - | - | - | - |
| Account | `costs.account_id` | string | `123456789` |
| Billing Account | `costs.provider_account_id` | string | `abcd1234` |
| Category | `costs.category` | string | `Data Transfer` |
| Charge Type | `costs.charge_type` | string | `Usage` |
| Marketplace | `costs.marketplace` | boolean | `true` |
| Provider | `costs.provider` | string | `aws` |
| Region | `costs.region` | string | `us-east-1` |
| Resource | `costs.resource_id` | string | `arn:aws:rds:us-east-1:123456789:db:primary-01` |
| Service | `costs.service` | string | `Amazon Relational Database Service` |
| Subcategory | `costs.subcategory` | string | `DataTransfer-Out-Bytes` |
| Tag | `tags.name` | string | `environment` (provider tag; virtual tag keys also supported) |
| Tag Value | `tags.value` | string | `production` |
Vantage also applies [Managed AI Tags](/managed_ai_tags) to supported AI provider costs: a normalized `vntg:ai:` tag schema (for example, `vntg:ai:model`, `vntg:ai:model_provider`, and `vntg:ai:token_type`) that is available as `tags.name` values so you can analyze AI spend with consistent dimensions across providers.
When [AWS Bedrock LLM Enrichment](/aws_bedrock_enrichment) is enabled, the per-request `requestMetadata` keys your application attaches are available as `tags.name` values on enriched Amazon Bedrock cost rows, alongside `vntg:ai:` tags such as `vntg:ai:principal_id`, `vntg:ai:operation`, and `vntg:ai:inference_scope`.
When [Custom LLM Enrichment](/custom_llm_enrichment) is enabled, the per-request `tags` you deliver (plus `vntg:ai:` tags such as `vntg:ai:model`) are available as `tags.name` values on enriched model-provider cost rows.
## Anthropic
Anthropic costs come from two data sources—the Claude API (Admin API key) and Claude.ai (Claude Enterprise Analytics API)—that share the same fields but populate them differently. See the [Anthropic integration](/connecting_anthropic#anthropic-reporting-dimensions) documentation for a full per-source breakdown. Use the `anthropic:billing_source` tag (`admin` or `analytics`) to distinguish the two.
| Filter | API Field Name | Data Type | Example Value |
| - | - | - | - |
| Account | `costs.account_id` | string | Anthropic workspace (Claude API); account name you set at connect (Claude.ai) |
| Category | `costs.category` | string | `tokens` (Claude API); Claude.ai product, e.g. `Claude Code` (Claude.ai) |
| Charge Type | `costs.charge_type` | string | `Usage` (`Discount` may also appear for Claude.ai) |
| Organization | `costs.provider_account_id` | string | Connection description (Claude API); Organization ID entered at connect (Claude.ai) |
| Provider | `costs.provider` | string | `anthropic` |
| Region | `costs.region` | string | Inference geography (both data sources) |
| Resource | `costs.resource_id` | string | `apikey_01EXAMPLEKEYxxxxxxxxxxxx` (Admin API key ID) or a user email (Claude.ai) |
| Service | `costs.service` | string | `Claude Sonnet 4` (model; both data sources) |
| Subcategory | `costs.subcategory` | string | `cache_read_input_tokens` |
| Tag | `tags.name` | string | `anthropic:api_key_created_by_email`, `anthropic:api_key_created_by_name`, `anthropic:workspace_name`, and more (non-exhaustive; see the [full tag list](/connecting_anthropic#anthropic-reporting-dimensions)). Virtual tag keys also supported. |
| Tag Value | `tags.value` | string | `developer@example.com` |
## Anyscale
| Filter | API Field Name | Data Type | Example Value |
| - | - | - | - |
| Category | `costs.category` | string | `customer_hosted` |
| Charge Type | `costs.charge_type` | string | `Usage` |
| Organization | `costs.provider_account_id` | string | `org_EXAMPLE000000000000000000` |
| Project | `costs.account_id` | string | `prj_EXAMPLE000000000000000000` |
| Provider | `costs.provider` | string | `anyscale` |
| Resource | `costs.resource_id` | string | `prodjob_EXAMPLE0000000000000000` |
| Service | `costs.service` | string | `Instances` |
| Subcategory | `costs.subcategory` | string | `k8s` |
| Tag | `tags.name` | string | `anyscale:cloud_provider` (provider tag; virtual tag keys also supported) |
| Tag Value | `tags.value` | string | `AWS` |
## Azure
| Filter | API Field Name | Data Type | Example Value |
| - | - | - | - |
| Category | `costs.category` | string | `GRS Data Stored` |
| Charge Type | `costs.charge_type` | string | `Usage` |
| Provider | `costs.provider` | string | `azure` |
| Region | `costs.region` | string | `eastus` |
| Resource | `costs.resource_id` | string | `/subscriptions/.../resourceGroups/my-rg/providers/Microsoft.Compute/virtualMachines/my-vm` |
| Resource Group | `costs.account_id` | string | `my-resource-group` |
| Service | `costs.service` | string | `Virtual Machines` |
| Subcategory | `costs.subcategory` | string | `D4ds v5` |
| Subscription | `costs.provider_account_id` | string | `Dev` |
| Tag | `tags.name` | string | `environment` (provider tag; virtual tag keys also supported) |
| Tag Value | `tags.value` | string | `production` |
### Azure CSP
Azure CSP reporting dimensions differ slightly from standard Azure integrations.
| Filter | API Field Name | Data Type | Example Value |
| - | - | - | - |
| Account (Subscription/Entitlement ID) | `costs.account_id` | string | `Production-Subscription - 00000000-0000-0000-0000-000000000000` |
| Billing Account (Azure Customer ID/Tenant ID) | `costs.provider_account_id` | string | `Example Customer - Example Reseller - 00000000-0000-0000-0000-000000000000` |
| Category | `costs.category` | string | `Azure DNS` |
| Charge Type | `costs.charge_type` | string | `Usage` |
| Provider | `costs.provider` | string | `azure_csp` |
| Region | `costs.region` | string | `eastus` |
| Resource | `costs.resource_id` | string | `/providers/Microsoft.Network/privateDnsZones/example.com` |
| Service | `costs.service` | string | `NCE License` |
| Subcategory | `costs.subcategory` | string | `Private Zone` |
| Tag | `tags.name` | string | `azure:costCenter` (provider tag; virtual tag keys also supported) |
| Tag Value | `tags.value` | string | `Engineering` |
## Baseten
| Filter | API Field Name | Data Type | Example Value |
| - | - | - | - |
| Category | `costs.category` | string | `my-fine-tuned-model` |
| Charge Type | `costs.charge_type` | string | `Usage` |
| Organization | `costs.provider_account_id` | string | User-defined description set when connecting the integration |
| Provider | `costs.provider` | string | `baseten` |
| Resource | `costs.resource_id` | string | `wpjk5e9` (deployment or job ID) |
| Service | `costs.service` | string | `Dedicated Inference` |
| Subcategory | `costs.subcategory` | string | `H100` (instance type) or `Input Tokens` (Model APIs) |
| Tag | `tags.name` | string | `baseten:model_name` (provider tag; virtual tag keys also supported) |
| Tag Value | `tags.value` | string | `my-fine-tuned-model` |
## Cartesia
| Filter | API Field Name | Data Type | Example Value |
| - | - | - | - |
| Account | `costs.account_id` | string | User-defined description set when connecting the integration |
| Category | `costs.category` | string | `Credits` (model capability usage) or `Agents` (Line agent usage) |
| Charge Type | `costs.charge_type` | string | `Usage` |
| Organization | `costs.provider_account_id` | string | User-defined description set when connecting the integration |
| Provider | `costs.provider` | string | `cartesia` |
| Service | `costs.service` | string | `Text-to-Speech` (capability name Cartesia reports) or `Line agents` |
## CircleCI
| Filter | API Field Name | Data Type | Example Value |
| - | - | - | - |
| Account | `costs.account_id` | string | `my-project` |
| Category | `costs.category` | string | `linux docker` |
| Charge Type | `costs.charge_type` | string | `Usage` |
| Organization | `costs.provider_account_id` | string | `My Organization` |
| Provider | `costs.provider` | string | `circle_ci` |
| Resource | `costs.resource_id` | string | `build` |
| Service | `costs.service` | string | `Compute` |
| Subcategory | `costs.subcategory` | string | `medium` |
| Tag | `tags.name` | string | `circleci:vcs_branch` (provider tag; virtual tag keys also supported) |
| Tag Value | `tags.value` | string | `main` |
## ClickHouse Cloud
| Filter | API Field Name | Data Type | Example Value |
| - | - | - | - |
| Category | `costs.category` | string | `datawarehouse` |
| Charge Type | `costs.charge_type` | string | `usage` |
| Organization | `costs.provider_account_id` | string | User-defined description set when connecting the integration |
| Provider | `costs.provider` | string | `clickhouse` |
| Resource | `costs.resource_id` | string | `prod-service-east` |
| Service | `costs.service` | string | `ClickHouse Cloud` |
| Subcategory | `costs.subcategory` | string | `publicDataTransferCHC` |
| Tag | `tags.name` | string | `clickhouse:entityName` (provider tag; virtual tag keys also supported) |
| Tag Value | `tags.value` | string | `cloud-cost-report` |
## Cloudflare
| Filter | API Field Name | Data Type | Example Value |
| - | - | - | - |
| Account | `costs.provider_account_id` | string | The Cloudflare account ID (displayed using the description set when connecting the integration) |
| Category | `costs.category` | string | `Workers Paid` |
| Charge Type | `costs.charge_type` | string | `Usage` |
| Provider | `costs.provider` | string | `cloudflare` |
| Service | `costs.service` | string | `Workers` |
| Tag | `tags.name` | string | `team` (virtual tag) |
| Tag Value | `tags.value` | string | `data-engineering` |
## Confluent
| Filter | API Field Name | Data Type | Example Value |
| - | - | - | - |
| Category | `costs.category` | string | `CONNECT_NUM_TASKS` |
| Charge Type | `costs.charge_type` | string | `Usage` |
| Organization | `costs.account_id` | string | User-defined description set when connecting the integration |
| Provider | `costs.provider` | string | `confluent` |
| Resource | `costs.resource_id` | string | `env-12345/lcc-abcde/MyConnector_0` |
| Service | `costs.service` | string | `Kafka` |
| Tag | `tags.name` | string | `team` (virtual tag) |
| Tag Value | `tags.value` | string | `data-engineering` |
## Coralogix
| Filter | API Field Name | Data Type | Example Value |
| - | - | - | - |
| Category | `costs.category` | string | `us-east-1-prod-example-app` |
| Charge Type | `costs.charge_type` | string | `Usage` |
| Provider | `costs.provider` | string | `coralogix` |
| Service | `costs.service` | string | `High Logs Data` |
| Subcategory | `costs.subcategory` | string | `us1cbd21` |
| Tag | `tags.name` | string | `team` (virtual tag) |
| Tag Value | `tags.value` | string | `data-engineering` |
## Cursor
| Filter | API Field Name | Data Type | Example Value |
| - | - | - | - |
| Account | `costs.account_id` | string | User-defined description set when connecting the integration |
| Billing Account | `costs.provider_account_id` | string | User-defined description set when connecting the integration |
| Category | `costs.category` | string | `requests` |
| Charge Type | `costs.charge_type` | string | `Usage` |
| Provider | `costs.provider` | string | `cursor` |
| Resource | `costs.resource_id` | string | `developer@example.com` |
| Service | `costs.service` | string | `Claude 4.5 Sonnet Thinking` |
| Subcategory | `costs.subcategory` | string | `Usage-based` |
| Tag | `tags.name` | string | `cursor:user` (provider tag; virtual tag keys also supported) |
| Tag Value | `tags.value` | string | `developer@example.com` |
## Custom Providers
Available fields are based on what you've uploaded for this Custom Provider. See the [Custom Providers](/connecting_custom_providers) documentation for details.
| Filter | API Field Name | Data Type | Example Value |
| - | - | - | - |
| Category | `costs.category` | string | `Task` |
| Charge Type | `costs.charge_type` | string | `Usage` |
| Provider | `costs.provider` | string | `custom_provider:` |
| Region | `costs.region` | string | `us-east-1` |
| Resource | `costs.resource_id` | string | `task/3` |
| Service | `costs.service` | string | `Compute` |
| Subcategory | `costs.subcategory` | string | `Large` |
| Tag\* | `tags.name` | string | `env` |
| Tag Value\* | `tags.value` | string | `production` |
*\* Regular and virtual tags associated with this provider*
## Databricks
| Filter | API Field Name | Data Type | Example Value |
| - | - | - | - |
| Account | `costs.account_id` | string | `acct-a123bc4` |
| Category | `costs.category` | string | `Photon` |
| Charge Type | `costs.charge_type` | string | `Usage` |
| Cluster | `costs.resource_id` | string | `1234-567890-1234567` |
| Provider | `costs.provider` | string | `databricks` |
| Service | `costs.service` | string | `Jobs Compute` |
| Tag | `tags.name` | string | `job_id` (provider tag; virtual tag keys also supported) |
| Tag Value | `tags.value` | string | `12345` |
## Datadog
| Filter | API Field Name | Data Type | Example Value |
| - | - | - | - |
| Charge Type | `costs.charge_type` | string | `Usage` |
| Organization | `costs.account_id` | string | `My Company` |
| Provider | `costs.provider` | string | `datadog` |
| Service | `costs.service` | string | `Log Management` |
| Tag | `tags.name` | string | `service` (provider tag; virtual tag keys also supported) |
| Tag Value | `tags.value` | string | `prod-api` |
## DigitalOcean
| Filter | API Field Name | Data Type | Example Value |
| - | - | - | - |
| Account | `costs.provider_account_id` | string | `do:team:11111111-2222-3333-4444-555555555555` (DigitalOcean team URN) |
| Category | `costs.category` | string | `s-2vcpu-4gb` (Droplet size; blank for line items without a size, such as snapshots, backups, custom images, and taxes) |
| Charge Type | `costs.charge_type` | string | `Usage` |
| Provider | `costs.provider` | string | `digital_ocean` |
| Region | `costs.region` | string | `nyc3` |
| Service | `costs.service` | string | `Droplets` |
| Tag | `tags.name` | string | `digital_ocean:sku` (provider tag; virtual tag keys also supported) |
| Tag Value | `tags.value` | string | `1-DR-DROPL-0BKUP` |
## Elastic
| Filter | API Field Name | Data Type | Example Value |
| - | - | - | - |
| Account | `costs.account_id` | string | `123456789` |
| Category | `costs.category` | string | `capacity` |
| Charge Type | `costs.charge_type` | string | `Usage` |
| Organization | `costs.provider_account_id` | string | `123456789` |
| Provider | `costs.provider` | string | `elastic` |
| Region | `costs.region` | string | `aws-us-east-2` |
| Service | `costs.service` | string | `Elasticsearch` |
| Subcategory | `costs.subcategory` | string | `elasticsearch` |
| Tag | `tags.name` | string | `team` (virtual tag) |
| Tag Value | `tags.value` | string | `data-engineering` |
## ElevenLabs
| Filter | API Field Name | Data Type | Example Value |
| - | - | - | - |
| Category | `costs.category` | string | `Text to Speech` |
| Charge Type | `costs.charge_type` | string | `Usage` |
| Organization | `costs.provider_account_id` | string | User-defined description set when connecting the integration |
| Provider | `costs.provider` | string | `eleven_labs` |
| Resource | `costs.resource_id` | string | `Tiffany - Realistic Conversations` |
| Service | `costs.service` | string | `Eleven Turbo v2` |
| Tag | `tags.name` | string | `elevenlabs:model` (provider tag; virtual tag keys also supported) |
| Tag Value | `tags.value` | string | `eleven_turbo_v2` |
## Fastly
| Filter | API Field Name | Data Type | Example Value |
| - | - | - | - |
| Account | `costs.account_id` | string | `My Company` |
| Category | `costs.category` | string | `HTTP Request` |
| Charge Type | `costs.charge_type` | string | `Usage` |
| Provider | `costs.provider` | string | `fastly` |
| Region | `costs.region` | string | `USA` |
| Resource | `costs.resource_id` | string | `Staging` |
| Service | `costs.service` | string | `CDN` |
| Subcategory | `costs.subcategory` | string | `Requests` |
| Tag | `tags.name` | string | `team` (virtual tag) |
| Tag Value | `tags.value` | string | `data-engineering` |
## Fireworks AI
| Filter | API Field Name | Data Type | Example Value |
| - | - | - | - |
| Category | `costs.category` | string | `GLM 5.2` |
| Charge Type | `costs.charge_type` | string | `Usage` |
| Organization | `costs.provider_account_id` | string | User-defined description set when connecting the integration |
| Provider | `costs.provider` | string | `fireworks_ai` |
| Service | `costs.service` | string | `Serverless Inference` |
| Subcategory | `costs.subcategory` | string | `LLM input tokens (uncached)` |
| Tag | `tags.name` | string | `fireworks:is_turbo` (provider tag; virtual tag keys also supported) |
| Tag Value | `tags.value` | string | `true` |
## GitHub
| Filter | API Field Name | Data Type | Example Value |
| - | - | - | - |
| Category | `costs.category` | string | `Actions` |
| Charge Type | `costs.charge_type` | string | `Usage` |
| Organization | `costs.provider_account_id` | string | `your-org` |
| Provider | `costs.provider` | string | `github` |
| Resource | `costs.resource_id` | string | `your-org/your-repo` |
| Service | `costs.service` | string | `Actions` |
| Subcategory | `costs.subcategory` | string | `Actions Linux` |
| Tag | `tags.name` | string | `repo` (provider tag; virtual tag keys also supported) |
| Tag Value | `tags.value` | string | `your-repo` |
## Google Cloud
| Filter | API Field Name | Data Type | Example Value |
| - | - | - | - |
| Billing Account | `costs.provider_account_id` | string | `000000-000000-000000` |
| Category | `costs.category` | string | `Network Inter Zone Data Transfer Out` |
| Charge Type | `costs.charge_type` | string | `regular` |
| Label | `tags.name` | string | `environment` (provider tag; virtual tag keys also supported) |
| Label Value | `tags.value` | string | `production` |
| Project | `costs.account_id` | string | `my-project-123456` |
| Provider | `costs.provider` | string | `gcp` |
| Region | `costs.region` | string | `us-east4` |
| Resource | `costs.resource_id` | string | `//compute.googleapis.com/projects/.../instances/example-instance` |
| Service | `costs.service` | string | `Compute Engine` |
## Grafana Cloud
| Filter | API Field Name | Data Type | Example Value |
| - | - | - | - |
| Account (Stack) | `costs.account_id` | string | `your-stack.grafana.net` |
| Category | `costs.category` | string | `Hosted Traces Usage` |
| Charge Type | `costs.charge_type` | string | `usage` |
| Organization | `costs.provider_account_id` | string | User-defined description set when connecting the integration |
| Provider | `costs.provider` | string | `grafana` |
| Service | `costs.service` | string | `Traces` |
| Tag | `tags.name` | string | `team` (virtual tag) |
| Tag Value | `tags.value` | string | `data-engineering` |
## Kubernetes
| Filter | API Field Name | Data Type | Example Value |
| - | - | - | - |
| Account | `costs.account_id` | string | sandbox |
| Charge Type | `costs.charge_type` | string | `Usage` |
| Cluster | `costs.service` | string | `production-cluster` |
| Grouping | `tags.name` | string | `vntg:category` (provider tag; virtual tag keys also supported) |
| Grouping Value | `tags.value` | string | `cpu` |
| Provider | `costs.provider` | string | `kubernetes` |
| Region | `costs.region` | string | `Westus2` |
## Linode
| Filter | API Field Name | Data Type | Example Value |
| - | - | - | - |
| Category | `costs.category` | string | `Compute` |
| Charge Type | `costs.charge_type` | string | `Usage` |
| Provider | `costs.provider` | string | `linode` |
| Resource | `costs.resource_id` | string | `node_balancer-000000` |
| Service | `costs.service` | string | `Node Balancer` |
| Subcategory | `costs.subcategory` | string | `Dedicated 64GB` |
| Tag | `tags.name` | string | `team` (virtual tag) |
| Tag Value | `tags.value` | string | `data-engineering` |
## MongoDB Atlas
| Filter | API Field Name | Data Type | Example Value |
| - | - | - | - |
| Category | `costs.category` | string | `ATLAS_AWS_INSTANCE_M10` |
| Charge Type | `costs.charge_type` | string | `Usage` |
| Organization | `costs.provider_account_id` | string | `000000000000000000000000` |
| Project | `costs.account_id` | string | `Project 0` (project name when available, otherwise project ID) |
| Provider | `costs.provider` | string | `mongo` |
| Resource | `costs.resource_id` | string | `my-cluster` |
| Service | `costs.service` | string | `Atlas Cluster` |
| Tag | `tags.name` | string | `environment` (provider tag; virtual tag keys also supported) |
| Tag Value | `tags.value` | string | `production` |
## Modal
| Filter | API Field Name | Data Type | Example Value |
| - | - | - | - |
| Account | `costs.account_id` | string | `main` (the Modal environment name) |
| Billing Account | `costs.provider_account_id` | string | User-defined description set when connecting the integration |
| Category | `costs.category` | string | `CPU` (the compute resource, e.g., `CPU`, `Memory`, or a GPU type) |
| Charge Type | `costs.charge_type` | string | `Usage` |
| Provider | `costs.provider` | string | `modal` |
| Resource | `costs.resource_id` | string | `ap-gw9cozapglMWKKNQJtCYyD` |
| Service | `costs.service` | string | `App` |
| Tag | `tags.name` | string | `modal:description` (provider tag; virtual tag keys also supported) |
| Tag Value | `tags.value` | string | `vantage-billing-smoke-test` |
## New Relic
| Filter | API Field Name | Data Type | Example Value |
| - | - | - | - |
| Account | `costs.account_id` | string | `my-account` |
| Category | `costs.category` | string | `New Relic Users - CoreUsers` |
| Charge Type | `costs.charge_type` | string | `Usage` |
| Provider | `costs.provider` | string | `new_relic` |
| Service | `costs.service` | string | `New Relic Ingestion` |
| Tag | `tags.name` | string | `team` (virtual tag) |
| Tag Value | `tags.value` | string | `data-engineering` |
## OpenAI
| Filter | API Field Name | Data Type | Example Value |
| - | - | - | - |
| Account (Project) | `costs.account_id` | string | `my-project` |
| Billing Account (Organization) | `costs.provider_account_id` | string | `My Company` |
| Category | `costs.category` | string | `gpt-4o` |
| Charge Type | `costs.charge_type` | string | `Usage` |
| Provider | `costs.provider` | string | `open_ai` |
| Service | `costs.service` | string | `Chat and Completions` (OpenAI Platform) or `Codex CLI` (OpenAI Codex) |
| Subcategory | `costs.subcategory` | string | `input` |
| Tag | `tags.name` | string | `openai:billing_source`, `openai:api_key_id`, `openai:owner_name`, or, for OpenAI Codex, `openai:client_id`, `openai:model`, `openai:user_email` (provider tags; virtual tag keys also supported) |
| Tag Value | `tags.value` | string | `svc-production` |
OpenAI cost data spans two data sources, the OpenAI Platform and OpenAI Codex, under the `open_ai` provider. Use the `openai:billing_source` tag (`admin` for OpenAI Platform or `codex_analytics` for OpenAI Codex) to distinguish the two. See the [OpenAI integration documentation](/connecting_openai#openai-reporting-dimensions) for the full list of dimensions and tags per data source.
## Oracle Cloud
| Filter | API Field Name | Data Type | Example Value |
| - | - | - | - |
| Category | `costs.category` | string | `Block Volume - Backup` |
| Charge Type | `costs.charge_type` | string | `Usage` |
| Compartment | `costs.account_id` | string | `prod-ops` |
| Provider | `costs.provider` | string | `oracle` |
| Region | `costs.region` | string | `Us Ashburn 1` |
| Resource | `costs.resource_id` | string | `ocid1.volumebackup.oc1.us-ashburn-1.aaaaaaaaEXAMPLEVOLUME` |
| Service | `costs.service` | string | `BLOCK_STORAGE` |
| Tag | `tags.name` | string | `Oracle-Tags.CreatedBy` (provider tag; virtual tag keys also supported) |
| Tag Value | `tags.value` | string | `developer@example.com` |
| Tenancy | `costs.provider_account_id` | string | `ocid1.tenancy.oc1..aaaaaaaaEXAMPLETENANCY` |
## PlanetScale
| Filter | API Field Name | Data Type | Example Value |
| - | - | - | - |
| Category | `costs.category` | string | `Database` |
| Charge Type | `costs.charge_type` | string | `Usage` |
| Organization | `costs.account_id` | string | User-defined description set when connecting the integration |
| Provider | `costs.provider` | string | `planetscale` |
| Resource | `costs.resource_id` | string | `xxxxxxxxxxxx/my-database` |
| Service | `costs.service` | string | `Database` |
| Tag | `tags.name` | string | `team` (virtual tag) |
| Tag Value | `tags.value` | string | `data-engineering` |
## Redis
| Filter | API Field Name | Data Type | Example Value |
| - | - | - | - |
| Account | `costs.account_id` | string | `My Account` |
| Billing Account | `costs.provider_account_id` | string | `My Billing Account` |
| Category | `costs.category` | string | `Databases` |
| Charge Type | `costs.charge_type` | string | `Usage` |
| Provider | `costs.provider` | string | `redis_cloud` |
| Region | `costs.region` | string | `us-east-1` |
| Resource | `costs.resource_id` | string | `my-redis-cluster` |
| Service | `costs.service` | string | `Redis` |
| Subcategory | `costs.subcategory` | string | `Caching` |
| Tag | `tags.name` | string | `environment` (provider tag; virtual tag keys also supported) |
| Tag Value | `tags.value` | string | `production` |
## Snowflake
| Filter | API Field Name | Data Type | Example Value |
| - | - | - | - |
| Account | `costs.account_id` | string | `XXX00000` |
| Category | `costs.category` | string | `Compute` |
| Charge Type | `costs.charge_type` | string | `Usage` |
| Organization | `costs.provider_account_id` | string | `XXXXXXX` |
| Provider | `costs.provider` | string | `snowflake` |
| Region | `costs.region` | string | `AWS Us East 1` |
| Service | `costs.service` | string | `Compute` |
| Tag | `tags.name` | string | `warehouse` (provider tag; virtual tag keys also supported) |
| Tag Value | `tags.value` | string | `COMPUTE_WH` |
## SpaceXAI
| Filter | API Field Name | Data Type | Example Value |
| - | - | - | - |
| Category | `costs.category` | string | `Prompt text tokens` (the billable unit type) |
| Charge Type | `costs.charge_type` | string | `Usage` |
| Organization | `costs.provider_account_id` | string | User-defined description set when connecting the integration |
| Provider | `costs.provider` | string | `xai` |
| Resource | `costs.resource_id` | string | `1a2b3c4d-...` (the SpaceXAI API key ID; an all-zero ID indicates unattributed usage) |
| Service | `costs.service` | string | `grok-4.3` (model or SKU) |
## Temporal Cloud
| Filter | API Field Name | Data Type | Example Value |
| - | - | - | - |
| Account | `costs.account_id` | string | `a2dd6` |
| Category | `costs.category` | string | `Actions`, `Storage`, `Other` |
| Charge Type | `costs.charge_type` | string | `Usage`, `Discount` |
| Organization | `costs.provider_account_id` | string | Temporal Cloud billing account name, billing account ID, or user-defined description set when connecting the integration |
| Provider | `costs.provider` | string | `temporal` |
| Resource ID | `costs.resource_id` | string | `payments-prod.a2dd6` |
| Service | `costs.service` | string | `Temporal Cloud` |
| SKU | `costs.sku` | string | `business-actions` |
| Subcategory | `costs.subcategory` | string | `Actions`, `Active Storage`, `Retained Storage` |
| Tag Name | `tags.name` | string | `$tmprl_project`, `temporal:resource_type`, `team` (provider tags; virtual tag keys also supported) |
| Tag Value | `tags.value` | string | `project-id`, `Namespace`, `data-engineering` |
## Twilio
| Filter | API Field Name | Data Type | Example Value |
| - | - | - | - |
| Account | `costs.provider_account_id` | string | User-defined description set when connecting the integration |
| Billing Account | `costs.account_id` | string | `ACxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxx` |
| Category | `costs.category` | string | `sms-messages-carrierfees` |
| Charge Type | `costs.charge_type` | string | `Usage` |
| Provider | `costs.provider` | string | `twilio` |
| Service | `costs.service` | string | `SMS & MMS` |
| Tag Name | `tags.name` | string | `team` (virtual tag) |
| Tag Value | `tags.value` | string | `data-engineering` |
## Vercel
| Filter | API Field Name | Data Type | Example Value |
| - | - | - | - |
| Account (Project) | `costs.account_id` | string | `vantage-docs` |
| Billing Account (Team) | `costs.provider_account_id` | string | `team_EXAMPLE000000000000000000` |
| Category | `costs.category` | string | `Vercel Functions` |
| Charge Type | `costs.charge_type` | string | `Usage` |
| Provider | `costs.provider` | string | `vercel` |
| Region | `costs.region` | string | `iad1` |
| Service | `costs.service` | string | `Compute` |
| Tag | `tags.name` | string | `vercel:ProjectId` (provider tag; virtual tag keys also supported) |
| Tag Value | `tags.value` | string | `prj_EXAMPLE000000000000000000` |
# Datadog MCP
Source: https://docs.vantage.sh/datadog_mcp
Connect the Datadog MCP to the Vantage FinOps Agent to join live Datadog telemetry with your Vantage cost data in a single conversation.
The Datadog MCP Connector links the [Vantage FinOps Agent](/vantage_finops_agent) to your Datadog organizations through Datadog's [MCP server](https://docs.datadoghq.com/mcp_server/). Once connected, the Agent can pull live Datadog telemetry, like metrics, logs, monitors, dashboards, APM, events, and more, and reason over it alongside the Vantage cost, allocation, anomaly, and recommendation data it already understands.
The Datadog MCP Connector is the first of several [MCP Connectors](/vantage_finops_agent#mcp-connectors) for the FinOps Agent. It is available to all Vantage customers using the FinOps Agent, in the [Vantage console](https://console.vantage.sh/agent), Slack, and [Canvas](/canvas).
## How the Connection Works
The Datadog MCP is an **organization-wide** connector. An **Organization Owner** or **Integration Owner** connects Datadog once, and it is then available to everyone in your organization through the Agent. Unlike the user-authorized connectors (GitHub, Linear, and Notion), there is no per-user authorization step and no **MCP Settings** or **Organization Settings** tabs; you connect Datadog organizations directly from the **Datadog MCP** page.
Because Datadog is not a user-authorized connector, it is managed only by roles that can manage integrations and does not appear on the Integrations page for Organization Editors or Organization Viewers. See [Role-Based Access Control](/rbac) for details.
## Prerequisites
Before you start, make sure you have:
* The [FinOps Agent](/vantage_finops_agent) enabled in Vantage. The Datadog MCP settings page prompts you to enable it first if it is not already on.
* A Vantage role that can manage integrations, such as **Organization Owner** or **Integration Owner**. See [Role-Based Access Control](/rbac) for details. Once the connector is configured, all Vantage users in your organization can use it through the Agent.
* A Datadog user who is an [Admin](https://docs.datadoghq.com/account_management/rbac/?tab=datadogapplication#datadog-default-roles) able to authorize the required OAuth scopes, including the [`mcp_read`](https://docs.datadoghq.com/account_management/rbac/permissions/#mcp) permission, plus the standard Datadog permissions for the underlying resources the Agent will query.
Usage is only accessible for [parent-level organizations](https://docs.datadoghq.com/account_management/multi_organization/). The Datadog MCP Connector is read-only. The FinOps Agent can retrieve data from Datadog but cannot create, modify, or delete any Datadog resources.
## Permissions and Data Access
The Datadog MCP Connector reuses the same Datadog OAuth application as the [Datadog cost integration](/connecting_datadog).
| Scope | Why Vantage needs it |
| - | - |
| `billing_read`, `usage_read` | Read billing and usage metering data (shared with the cost integration). |
| `metrics_read`, `timeseries_query` | Query metrics and time-series data such as CPU, memory, and request counts. |
| `logs_read_data`, `logs_read_index_data`, `logs_read_workspaces` | Read log data and log indexes for investigations. |
| `monitors_read` | Read monitor definitions and status. |
| `apm_read` | Read APM (application performance) data. |
| `dashboards_read` | Read dashboard definitions. |
| `mcp_read` | Authorize access to the Datadog MCP server. |
| `incident_read` | Read incident data. |
| `events_read` | Read events such as deployments and resource changes. |
| `llm_observability_read` | Read LLM Observability data. |
Vantage stores only the data that is explicitly written into your FinOps Agent conversation responses; no ancillary Datadog data is collected or stored outside of your conversation, and data retrieved through the connector is not used to train any models.
Data retrieved through the Datadog MCP is read-only and scoped to your conversation. Datadog API usage generated by FinOps Agent queries counts against your Datadog plan limits. Refer to your Datadog agreement for details.
## Available Tools
The FinOps Agent connects to Datadog's hosted MCP server and chooses the right tools automatically based on your question. The connector is **read-only**, so the Agent can retrieve data but cannot create, modify, or delete Datadog resources. Available functionality includes:
* **Metrics and time series**: query metrics such as CPU, memory, and request counts.
* **Logs**: search and read log data and log indexes.
* **Monitors**: read monitor definitions and status.
* **Dashboards**: read dashboard definitions.
* **APM and traces**: read application performance data.
* **Events**: read events such as deployments and resource changes.
* **Incidents**: read incident data.
* **LLM Observability**: read LLM Observability data.
## Connect the Datadog MCP
From the top navigation in Vantage, click **Settings**. On the left navigation, select **Integrations**, then find the **MCP Connectors** section and select **Datadog MCP**.
If the page shows a banner asking you to enable the FinOps Agent, open the [FinOps Agent settings page](https://console.vantage.sh/settings/finops_agent) and enable it first, then return to the Datadog MCP page.
On the **Datadog MCP** page, click **Connect Datadog**. Vantage redirects you to Datadog to complete the OAuth flow.
Sign in to Datadog as an Admin and authorize the requested scopes (see [Permissions and Data Access](#permissions-and-data-access)). After you approve, Datadog redirects you back to Vantage and the connection status changes to connected.
Back in Vantage, confirm the Datadog MCP shows as connected. You can now ask the FinOps Agent Datadog-aware questions in the console or in Slack.
If you previously connected Datadog only for cost ingestion, your existing connection may not include the extended agent scopes. In that case the Datadog MCP page prompts you to reconnect to grant the additional scopes (such as `mcp_read`). Reconnect from the **Datadog MCP** page rather than the standard [Datadog cost integration](/connecting_datadog) page.
You can connect multiple Datadog organizations, based on the organizations the connecting user has access to. After authorizing your first organization, add more by returning to the **Datadog MCP** page and using the **Datadog organization** dropdown at the top to select another organization. When you select a newly added organization, Vantage prompts you to reconnect to grant the [required scopes](#permissions-and-data-access).
## Example Use Cases
Once the Datadog MCP is connected, the FinOps Agent decides when to reach for Datadog tools based on the question you ask. It can call Datadog tools in the same turn it uses Vantage tools, combining cost data with live telemetry. The examples below come from real FinOps Agent conversations.
For prompting best practices and more copy-paste examples, see the [FinOps AI Prompt Guide](/finops_ai_prompt_guide).
### Correlate Deployments with a Cost Increase
Ask the Agent to connect a cost spike to infrastructure activity. It loads the anomaly investigation skill, pulls Vantage cost anomalies, retrieves Datadog deployment and resource-change events, and correlates them on a timeline.
Did any recent deployments cause my AWS costs to increase?
In this flow, the Agent runs a multi-step investigation across both Vantage and Datadog:
The Agent loads the anomaly investigation skill and identifies your default workspace using Vantage tools.
It lists active Vantage cost anomalies and, at the same time, retrieves recent deployment and resource-change events from Datadog.
It queries daily costs around the spike and aggregates Datadog events by day to line up cost increases with deployment activity.
It returns a structured summary tying specific anomalies (for example, EBS and EC2 increases) to a surge in resource-change events on the same dates.
```md Example response expandable theme={null}
AWS Cost Increase & Deployment Correlation Analysis
Yes, there is a strong correlation between recent deployments and your AWS cost
increases. Starting around May 27-28, a surge in infrastructure resource changes
coincided with cost spikes across multiple AWS services.
Cost anomalies detected (deduplicated):
| Service | Category | Current Daily | 7-Day Avg | Increase |
|-------------|------------------------|---------------|-----------|----------|
| AmazonEC2 | Compute Instance | $8,420 | $5,890 | +43% |
| EBS | Storage | $2,310 | $1,095 | +111% |
| EBS | Provisioned Throughput | $1,240 | $325 | +282% |
| CloudWatch | API Request | $410 | $299 | +37% |
| AmazonS3 | Other | $560 | $386 | +45% |
Deployment activity (from Datadog) — resource changes by day:
| Date | Resource Changes | Notable |
|--------|------------------|------------------|
| May 25 | 2 | Baseline |
| May 27 | 1,219 | Large spike |
| May 29 | 6,716 | Peak activity |
| May 30 | 3,954 | Sustained high |
Root cause: Kubernetes workload scaling in the temporal-etl namespace drove the
EBS and EC2 anomalies, with new ECS task definitions deployed for production-core.
The spike peaked May 29-30 and has been gradually declining.
```
### Validate Rightsizing with Utilization Data
Ask the Agent to find expensive, underutilized resources. It pulls Vantage rightsizing recommendations and cost data, then cross-references Datadog CPU and memory utilization to confirm which instances are oversized.
Which EC2 instances have the highest cost but lowest utilization?
```md Example response expandable theme={null}
EC2 Instances: High Cost, Low Utilization
Combining Vantage rightsizing recommendations with Datadog utilization:
| Instance | Current Type | Max CPU % | State | Savings/mo | Recommended |
|-----------------------|---------------------|-----------|----------|------------|--------------|
| i-0aaaa1111bbbb2222 | c5.xlarge (4 vCPU) | 3.15% | Running | $412.00 | t3.large |
| i-0cccc3333dddd4444 | c5.large (2 vCPU) | 11.09% | Stopped | $388.00 | t3.medium |
| i-0eeee5555ffff6666 | t3.large (2 vCPU) | 10.06% | Running | $640.00 | t3.medium |
| i-0aaaa7777bbbb8888 | c5.2xlarge (8 vCPU) | ~100% peak| Running | $910.00 | r6i.large |
The first three instances are strong downsizing candidates given sustained low CPU.
The last instance peaks near 100%, so validate its workload pattern before resizing.
```
### Verify an Unused Resource Before Acting
Before deleting or downsizing a resource Vantage flags as unused, ask the Agent to confirm it is truly idle in Datadog.
Vantage says this resource is unused. Is it receiving any traffic or compute load in Datadog over the last 30 days?
### Correlate Cost and Performance
Ask open-ended questions that require both cost context from Vantage and performance context from Datadog in one answer.
Our AWS data transfer costs jumped this week. Which services or hosts in Datadog show increased network throughput over the same period?
## Troubleshooting
Enable the [FinOps Agent](/vantage_finops_agent) first from the [FinOps Agent settings page](https://console.vantage.sh/settings/finops_agent), then return to **Settings** > **Integrations** > **MCP Connectors** > **Datadog MCP**.
Your Datadog connection is missing the extended agent scopes (for example, `mcp_read`). Reconnect from the **Datadog MCP** page and authorize all requested scopes as a Datadog Admin. This is common if Datadog was originally connected only for cost ingestion.
Confirm the Datadog MCP shows as connected and that your question requires Datadog context. The Agent prefers Vantage tools for pure cost questions and reaches for Datadog when telemetry (metrics, logs, monitors, events) is needed. Try phrasing the request to explicitly ask for utilization, metrics, or events.
The Datadog OAuth grant may have been revoked or expired. Reconnect Datadog from the **Datadog MCP** page. If the issue persists, verify the connecting user is a Datadog Admin and that the Vantage app has not been removed in Datadog.
The Datadog MCP server is not available for GovCloud customers, so the Datadog MCP Connector cannot be used in those environments.
The Datadog tools are no longer available to the FinOps Agent. Previous conversations retain their historical responses based on your data retention period, but the Agent can no longer call Datadog after it is disconnected.
# Vantage Docs MCP
Source: https://docs.vantage.sh/docs_mcp
Use the MCP server to search the Vantage documentation using AI tools.
These docs are available via a Model Context Protocol (MCP) server. Use this integration to find relevant guides, setup steps, and implementation details directly from your AI assistant with links back to the docs.
The Docs MCP is also able to answer questions about the [Vantage Terraform provider](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
Some ways you can use the Vantage Docs MCP include:
* Find setup steps (e.g., connecting AWS, Azure, GCP)
* Locate VQL examples for common questions
* Ask how to create a Terraform resource for Vantage features, like Cost Reports or Anomaly Alerts
* Understand feature behavior (alerts, dashboards, forecasting, etc.)
* Pull exact page links to share in Slack, tickets, or PRs
You can use the Vantage Docs MCP along with the [Vantage MCP](/vantage_mcp) to query your costs and see how to create monitoring resources, like alerts and reports. See the [Use Case section](/docs_mcp#use-case-discover-anomalies-and-set-up-monitoring) for a sample workflow.
The [Vantage FinOps Agent](/vantage_finops_agent) uses the Vantage Docs MCP to answer questions about Vantage features and documentation directly in Slack. The Agent can help you understand how to use Vantage, find setup steps, and locate documentation—all without requiring you to set up an MCP client. If you prefer to use your own AI tools (like Claude, Cursor, or Goose) with the Vantage Docs MCP, you can configure them using the instructions on this page.
## Server URL
* **Vantage Docs MCP server**: `https://docs.vantage.sh/mcp`
* **Available tool**: `search`
The `search` tool returns contextual results with titles and direct links to the matching documentation pages.
## Quick Installation
From any docs page, open the contextual menu next to the page title and select one of the following options:
* **Copy page**: Lets you copy the current docs page in Markdown format to paste as context for an AI agent.
* **Connect to Cursor**: Opens the **Tools & Integrations** setup screen in Cursor to add the Vantage docs as a new integration.
## Connect the Server to Your Tools
See the [Model Context Protocol guide](https://modelcontextprotocol.io/docs/tutorials/use-remote-mcp-server#connecting-to-a-remote-mcp-server) for more details.
Go to Claude **Settings** > **Connectors** (`https://claude.ai/settings/connectors`).
Select **Add custom connector**, then enter:
* Name: `Vantage Docs`
* URL: `https://docs.vantage.sh/mcp`
Save the connector. Open a new chat and ask what tools are available for the Vantage Docs MCP. You should see the `search` tool as an available tool.
See the [Claude Code docs](https://docs.anthropic.com/en/docs/claude-code/mcp#installing-mcp-servers) for details.
```bash theme={null}
claude mcp add --transport http vantage-docs https://docs.vantage.sh/mcp
```
```bash theme={null}
claude mcp list
```
See the [Cursor docs](https://docs.cursor.com/en/context/mcp#installing-mcp-servers) for details.
Press Command + Shift + P and search for **Open MCP settings**.
Click **New MCP Server**. In `mcp.json`, add the following:
```json mcp.json icon="brackets-curly" theme={null}
{
"mcpServers": {
"VantageDocs": {
"url": "https://docs.vantage.sh/mcp"
}
}
}
```
In a new chat, ask: "What tools do you have available?" You should see *Search Vantage - Search the Vantage knowledge base for documentation and guides* under the Vantage Docs server.
Run the following command in your terminal:
```bash theme={null}
codex mcp add VantageDocs -- npx -y mcp-remote "https://docs.vantage.sh/mcp"
```
This command adds the Vantage Docs MCP server to your Codex configuration.
Start Codex. You can now use the Vantage Docs MCP as context for your prompts and projects.
## Example Prompts
* "Where do I find steps to connect Azure EA and what permissions are needed?"
* "What's the VQL to filter costs by a specific charge type?"
* "How do I configure cost anomaly alerts and what thresholds are supported?"
* "Link me to the page describing the Vantage MCP tools."
* "How do I export GCP billing data for Vantage?"
## Use Case - Discover Anomalies and Set Up Monitoring
You're investigating recent cost issues and want to set up proper monitoring to prevent future surprises.
Ask your AI tool (connected to both MCP servers):
> *Check for any cost anomalies in our AWS costs from the last 30 days, particularly focusing on services that had unusual spending patterns.*
Your assistant uses the Vantage MCP's `list-anomalies` tool and finds several anomalies in EC2 and S3 services.
Now ask for the setup documentation:
> *Search the Vantage docs for how to configure cost anomaly alerts and set up Jira integration for automatic issue creation when anomalies are detected.*
Your assistant uses the Vantage Docs MCP `search` tool and finds:
* Cost anomaly alerts configuration steps
* Jira integration setup process
* Alert threshold configuration options
Based on the provided guidance, you can now:
* Configure anomaly alerts with appropriate thresholds
* Set up Jira integration to automatically create tickets
* Create dashboards to monitor the affected services
* Set up Slack notifications for immediate awareness
## Use Case - Troubleshooting Terraform Syntax
You encounter a Terraform syntax error and ask your AI tool (connected to the Vantage Docs MCP) how to fix the issue.
> *I am getting some issues with the below Terraform code:*
```hcl theme={null}
resource "vantage_dashboard" "multi_cloud_monitoring" {
title = "AWS & Azure Cost Monitoring Dashboard"
workspace_token = var.workspace_token
# Multi-Cloud Overview Widget
widgets {
widgetable_token = vantage_cost_report.multi_cloud.token
title = "Multi-Cloud Overview"
}
}
```
> *The following error is returned:*
```
│ Error: Unsupported block type
│
│ on main.tf line 257, in resource "vantage_dashboard" "multi_cloud_monitoring":
│ 257: widgets {
│
│ Blocks of type "widgets" are not expected here. Did you mean to
│ define argument "widgets"? If so, use the equals sign to assign
│ it a value.
```
Your AI assistant uses the Vantage Docs MCP to find the correct syntax and provides the fix:
The issue is with the syntax for the widgets block. In the Vantage Terraform provider, widgets should be defined as an argument (using =) with a list of objects, not as a block (using ).
Here's the corrected code:
```hcl theme={null}
resource "vantage_dashboard" "multi_cloud_monitoring" {
title = "AWS & Azure Cost Monitoring Dashboard"
workspace_token = var.workspace_token
# Multi-Cloud Overview Widget
widgets = [
{
widgetable_token = vantage_cost_report.multi_cloud.token
title = "Multi-Cloud Overview"
}
]
}
```
**Key changes:**
* Changed `widgets {` to `widgets = [`
* Wrapped the widget configuration in `{ }` as an object
* Enclosed it in `[ ]` to make it a list (since you can have multiple widgets)
* Closed with `]` instead of `}`
If you want to add more widgets to the dashboard, you can simply add more objects to the list:
```hcl theme={null}
widgets = [
{
widgetable_token = vantage_cost_report.multi_cloud.token
title = "Multi-Cloud Overview"
},
{
widgetable_token = vantage_cost_report.aws_services.token
title = "AWS Services Breakdown"
}
]
```
This syntax follows the Terraform convention where repeatable nested structures are defined as lists of objects when using the = assignment syntax.
With the syntax error fixed, you can now deploy your Terraform configuration:
```bash theme={null}
# Initialize and validate
terraform init
terraform validate
# Plan the deployment
terraform plan
# Apply the configuration
terraform apply
```
The dashboard will now deploy successfully with the correct widgets syntax, and you'll have a multi-cloud monitoring dashboard in your Vantage console.
## Troubleshooting
This server exposes only `search` for docs lookup. For interacting with Vantage data via tools, see the [Vantage MCP](/vantage_mcp).
Ensure you're using the correct URL: `https://docs.vantage.sh/mcp`.
# Configure GCP Billing Exports
Source: https://docs.vantage.sh/enabling_gcp_billing_export
Learn how to configure GCP billing exports as a prerequisite to the Vantage and Google Cloud integration.
The below documentation is a streamlined version of [Google Cloud Platform's official documentation](https://cloud.google.com/billing/docs/how-to/export-data-bigquery-setup).
## Prerequisites
Before you begin, ensure you have the following permissions configured. See the [Google Cloud Platform documentation](https://cloud.google.com/billing/docs/how-to/export-data-bigquery-setup#required_permissions) for information on how to configure these permissions.
* User with permission to create a project
* User with permission to create a BigQuery dataset
* User with permission to modify Billing settings
## Create a Billing Export
### Step 1 - Select or Create a Project
Before you enable Cloud Billing data exports, you will need to create a project to store the data. If you have multiple Cloud Billing accounts, you will need to enable Cloud Billing exports individually on each account.
**RECOMMENDATION**
We recommend you create a dedicated project to store all Cloud Billing data, rather than using an existing project.
The project needs to be linked to the same Cloud Billing account that you plan to enable the Cloud Billing data export on. If you need help assigning a project to a Cloud Billing account, follow the [Cloud Billing documentation](https://cloud.google.com/billing/docs/how-to/modify-project#confirm_billing_is_enabled_on_a_project).
### Step 2 - Create a BigQuery Dataset
In the GCP console, navigate to [BigQuery](https://console.cloud.google.com/bigquery), and follow the steps below to create a BigQuery dataset.
From the **Project** dropdown list at the top of the BigQuery console, select the project you set up for your Cloud Billing data export.
In the **Classic Explorer** panel, click the **three vertical dots** (next to your project ID).
Click **Create dataset**.
Configure your dataset:
* Enter a **Dataset ID**. We recommend an ID that spans projects, such as *all\_billing\_data*, rather than a project-specific ID.
* For **Location type**, select either **US (multiple regions in United States)** or **EU (multiple regions in European Union)**. One of these two options is required to enable detailed usage cost data.
* Click **Advanced options**. Set **Encryption** to **Google-managed encryption key**.
Customer-managed key encryption is not supported for exporting Cloud Billing data records to BigQuery.
* Leave the **Enable table expiration** checkbox unchecked to ensure that data never expires.
Click **Create dataset**. You should see the dataset displayed in the **Explorer** panel, under your project.
### Step 3 - Enable Cloud Billing Export to the BigQuery Dataset
Still in BigQuery, click the hamburger menu (three horizontal lines) at the top left of the console, and select **Billing**.
In the left menu under **Cost management**, select **Billing export**.
Ensure you are on the **BigQuery export** tab. (This tab should be selected by default). Then, under **Detailed usage cost**, click **Edit settings**.
Configure the following settings:
* From the **Projects** list, select the project you set up to contain your billing data.
* For **Dataset**, select the dataset that you set up to contain your exported Cloud Billing data (e.g., **all\_billing\_data**).
Click **Save**.
## Next Steps - Complete Your Vantage-GCP Integration
Your Cloud Billing data will start to be stored in the BigQuery dataset you created. To continue connecting your GCP account to Vantage, complete the [Create a GCP Connection](/connecting_gcp#create-a-connection) instructions.
It typically takes a few hours for data to start appearing. Cloud Billing data is added retroactively for the current and previous month when detailed usage cost data is configured. Full data for the current and previous month can take 24–48 hours to fully propagate.
# Financial Commitment Reports
Source: https://docs.vantage.sh/financial_commitment_reports
Track and analyze AWS financial commitments with Vantage.
A *financial commitment* is an agreement made with a cloud provider to spend a certain amount of money over a designated timeframe (e.g., one or three years) in return for a discounted rate on services. Examples of financial commitments include AWS [Reserved Instances](https://handbook.vantage.sh/aws/concepts/reserved-instances/) and [Savings Plans](https://handbook.vantage.sh/aws/concepts/savings-plans/). Other discounts include the [AWS Enterprise Discount Program (EDP)](https://aws.amazon.com/pricing/enterprise/) and [Spot Instances](https://handbook.vantage.sh/aws/services/ec2-pricing/#on-demand-vs-spot).
Vantage financial commitment reports provide a unified view of all your AWS financial commitments, with the ability to filter or create custom aggregations and groupings. Financial commitment reports track Savings Plans, Reserved Instances, Spot Instance usage, and EDP discounts for AWS costs.
This feature is currently available only for AWS, with plans to expand to Azure and GCP in the future.
If you use Azure with a non-CSP billing account (such as Pay-As-You-Go, MCA, or EA), you can view Azure Reservations and Azure Savings Plans on the [Commitments](/commitments) page after completing the [Optional Azure Reservations and Savings Plans](/connecting_azure#optional-azure-reservations-and-savings-plans) steps. These steps do not apply to Azure CSP integrations.
## Requirements
Financial Commitment Reports require an **AWS integration** with **Cost and Usage Reports (CUR)** [enabled](/connecting_aws#create-a-connection). The reports become available after the first CUR delivery/import has been successfully processed—that is, after at least one CUR file has been delivered to and ingested from the S3 bucket Vantage reads from. If you see **"Data is Processing"**, Vantage is still waiting for that first successful CUR import. For backfilling past months, see [Backfilling AWS CUR for previous reporting periods](/connecting_aws#backfilling-aws-cur-for-previous-reporting-periods).
## Understand Discounted Coverage and Effective Savings Rate
Financial commitment reports in Vantage help you understand your overall *discounted coverage* and *effective savings rate*. These metrics are described in detail below.
### Coverage
Coverage is the percentage of On-Demand usage offset by financial commitments, such as Reserved Instances and Savings Plans.
Coverage can be calculated as:
$$
\frac{Covered\ Use}{Covered\ Use+On–Demand\ Use}
$$
Here, Covered Use refers to the gross On-Demand equivalent of usage covered by commitments (i.e., what that usage would have cost at On-Demand rates without discounts). On-Demand Use reflects actual On-Demand spend.
Spot usage is excluded from this calculation as it is not eligible for committed usage discounts.
As a basic example, an app uses two Reserved Instances. The app also uses three On-Demand instances of the same size.
* The two Reserved Instances cover \$120 in gross On-Demand equivalent usage.
* The three On-Demand instances account for \$180 in gross On-Demand usage.
$$
\frac{\$120}{\$120+\$180} = 40\%\ coverage
$$
With this lower coverage percentage, the app’s developers could consider purchasing more Reserved Instances, instead of On-Demand instances, and realize greater savings.
### Effective Savings Rate
Effective savings rate measures the impact of purchased financial commitments as well as discounts, refunds, and credits. If you use financial commitments with higher discounts, you’ll improve your effective savings rate. The effective savings rate can be calculated as follows.
$$
1 - \frac{Discounted\ Spend}{On–Demand\ Equivalent\ Spend}
$$
As an example, an app uses a large-sized Reserved Instance, with a one-year no upfront commitment. It costs \$0.20 per hour. The app used the Reserved Instance for 90% of the month (i.e., 657 hours, when using a value of 730 hours for the month).
* The Reserved Instance costs a total of \$146 for this month (\$0.20 x 730 hours).
* The On-Demand equivalent of this instance costs a total of \$164.25 for the month (\$0.25 per hour x 657 hours).
$$
1- \frac{\$146}{\$164.25} = 11.11\%\ effective\ savings
$$
## Create a Financial Commitment Report
Before you create a report, you can view a list of all your active (and expired) Savings Plans and Reserved Instances on the [Commitments](/commitments) screen.
Navigate to the **[Financial Commitment Reports](https://console.vantage.sh/financial_planning/financial_commitment_reports)** screen. All existing reports are displayed. From this screen, you can edit and delete existing reports.
To create a new report, click **New Report**.
To filter costs, click the **Filters** button on the top left of the graph.
* The **AWS costs where...** tile is displayed. Click **+ New Rule**.
* For **Category**, select an available filter category.
You can filter by service (e.g., Amazon EC2), account, billing account, commitment type (e.g., On-Demand), commitment ARN, charge type (e.g., Spot Usage), category (e.g., Compute Instance), subcategory (e.g., AP-Requests-Tier1), instance type (e.g., m5.large), region, and tag.
If you want to see the discount impact of a single Savings Plan or Reserved Instance, use the **Commitment ARN** filter.
* Two additional dropdown menus are displayed. Select **is**, **is not**, **contains**, or **does not contain** based on your desired filter criteria, then select one or more corresponding values from the second dropdown menu. For Tag, the Tag Key dropdown is displayed before the operator dropdown.
* Click **Save**.
You can optionally edit your existing rules or add additional filter criteria.
* To edit the rule you just created, select the rule, make your changes, and then click **Save**.
* If you want to add a rule to filter multiple criteria, such as filter by certain services and another rule to filter by certain regions, click **+ New Rule**. Add the additional criteria and save.
* To add a separate rule set, click **+ New Filter**. This rule set will be displayed as **Or AWS costs where...** in a new rule section.
* To delete a rule set, click the trashcan icon on the top right of the rule set.
Above the rule set(s), click **Apply**. The graph will update with your existing filter criteria.
To save the report, click **Save as New.** Enter a report name, and click **Save**. (To edit this name, click the pencil icon in the breadcrumbs above the chart, next to the report's name.)
You can edit the filter criteria on a report at any time. Remember to click **Save** once you are done making changes.
### Apply Aggregations to Reports
You have the option to further drill down into your costs:
* Above the graph, click the **Group By** dropdown menu. Select one or more grouping options. You can group by charge type, commitment type, commitment ARN, service, account, billing account, region, category, subcategory, instance type, and tag.
For a detailed breakdown of the **Charge Type** grouping, see the [Cost Reports](/cost_reports#charge-type-grouping-category) documentation.
* To adjust the date binning, click the data bin menu on the top right of the graph. Select either **Daily**, **Weekly**, or **Monthly**. **Hourly** granularity is available as an opt-in feature. See the [section below](/financial_commitment_reports#hourly-reporting) for details.
* To change the date range, click the date menu on the top right of the graph and adjust the date range.
You can historically view back as far as your account’s retention period. By default, this period is six months.
### Hourly Reporting
To enable this feature, contact [support@vantage.sh](mailto:support@vantage.sh).
With hourly granularity, you can analyze your financial commitment coverage and utilization, by the hour, for any 14-day period within your data retention. Once this feature is enabled in your account, you may need to update your AWS Cost and Usage Report (CUR) settings. If your CUR is currently set to daily aggregation (the Vantage default), you must [reconnect your AWS integration](/connecting_aws#create-a-connection) with a new CUR configured to use an hourly time unit.
You can check the time unit of your existing CUR in one of two ways:
* Navigate to the [AWS integration settings](https://console.vantage.sh/settings/aws) page and look at the **Cost Aggregation** column next to your AWS integration.
* Navigate to the [Services](https://console.vantage.sh/services) Active Resources page.
* Select **CUR Report Definitions**.
* Select a listed report.
* Under the metadata box on the right, check the **Time Unit** field.
From the date bin dropdown menu, select **Hourly**. The X-axis of the chart displays both days and hours for the report you are viewing. When you switch to hourly binning, you will automatically be switched to a 14-day period with the same end date as the date period you are currently viewing.
If you're viewing costs at an hourly granularity and select a date range longer than 14 days, Vantage will display a warning that your view will switch to daily granularity.
### Commitment Eligibility Filter
You can also adjust the report to include only costs that are eligible for Reserved Instances and Savings Plan commitments. Click **On-Demand Costs:** and select one of the following options:
* **All Costs:** Display all costs that are relevant to financial commitments, excluding marketplace purchases, tax, and free tier usage. All AWS services are included in this view.
* **Commitment-Eligible Costs:** This option is the default option. Only costs that are eligible for Reserved Instances and Savings Plans are displayed. With this option, you can choose whether to include all your On-Demand AWS costs in the effective savings rate calculation or only those costs eligible for potential coverage by Savings Plans and Reserved Instances. This option includes the following services:
* Amazon EC2
* AWS Lambda
* Amazon SageMaker
* Amazon RDS
* Amazon Aurora
* Amazon DynamoDB
* Amazon ElastiCache
* Amazon DocumentDB
* Amazon Neptune
* Amazon OpenSearch
* Amazon EKS
* Amazon ECS
## Review the Report
By default, financial commitment reports are grouped by Charge Type (e.g., Savings Plan Discounted Spend, Spot Usage). Groupings are represented by each colored section of the bar chart. Hover over any bar to get a breakdown of costs. The breakdown is also provided in the table below the chart.
Costs in the graph are [unblended](https://www.vantage.sh/blog/analyze-aws-cost-data#decoding-blended-unblended-and-amortized-costs).
You can sort the table by any of the date or grouping columns.
The chart contains two axes: the left axis measures costs, and the right axis measures the coverage and effective savings rate. The cost axis shows positive and negative values (i.e., discounts are represented as negative dollar values).
Trend lines are displayed to illustrate the change in coverage and effective savings rate over time. Hover over any line to get a point-in-time view of each metric and associated costs.
Above the chart, the following values are displayed for the report’s lookback period:
* **Total Savings:** The total amount saved by using your financial commitments and other discounts.
* **Effective Savings Rate:** The percentage discount across all usage. (See the [section above](/financial_commitment_reports#effective-savings-rate) for a more in-depth explanation of this metric.)
* **Coverage:** The percentage of total spending that is covered by financial commitments. (See the [section above](/financial_commitment_reports#coverage) for a more in-depth explanation of this metric.)
### Export the Report
You can export a Financial Commitment Report's table to CSV from the report page. Vantage generates the file and emails it to the recipients you select, the same way [Cost Report exports](/cost_reports#export-cost-reports) are delivered.
## Add a Financial Commitment Report to a Dashboard
You can add financial commitment reports to a dashboard so that teams can see the coverage related to their resources. See the [Dashboards](/dashboards) documentation for more information on how to create and add reports to dashboards.
# Folders
Source: https://docs.vantage.sh/folders
Organize Cost Reports and Resource Reports with Vantage Folders.
If your organization has many Cost Reports or [Resource Reports](/active_resources), you can create folders to separate reports for different groups, like business units or cost centers. You can also move reports between folders and nest folders within each other to create complex organizational structures. Folders are available for both Cost Reports and Resource Reports.
## Create a Folder
From the top navigation, click **Reporting**.
On the left menu, select **Cost Reports**.
On the top right, click the down arrow next to **+ New**.
Select **New Folder**.
Enter a name for the folder, then click **Create**.
The new folder is displayed in the Cost Report list. Select the folder to open it.
At the top of the folder, click the down arrow next to **+ New**. You can create a new Cost Report inside the folder or a sub-folder within that folder.
## Move Cost Reports and Folders
To move one or more folders or Cost Reports from the All Cost Reports screen:
From the All Cost Reports screen, select the checkbox next to one or more Cost Reports or folders.
At the top of the report list, click **Move**.
Select any listed folder, then click **Move Here**.
When you move a folder into another folder, it becomes a subfolder. Consequently, any reports or folders contained within the moved folder will move along with it.
To move one or more Cost Reports or subfolders out of a folder and back to the main All Cost Reports screen:
From the current folder, select the checkbox next to one or more Cost Reports or folders.
At the top of the report list, click **Move**.
The **Moving...** modal is displayed. Click **\< Back** until **All Reports (currently selected)** is displayed at the top.
Click **Move Here**.
## Create a Dashboard from a Folder
You can create a [dashboard](/dashboards) made up of all the reports within a folder.
Navigate to any folder.
At the top, click **Dashboard**. A dashboard containing all included reports is displayed.
If you want to save the dashboard, click **Save As New**. This saved dashboard will be shareable and available within the main **Dashboards** screen.
## Starred By Me
If you want to save your favorite Cost Reports to a convenient location, you can *star* specific reports. See the [Starred By Me](/cost_reports#starred-by-me) documentation for details.
# Forecasting
Source: https://docs.vantage.sh/forecasting
Use Vantage's cost forecasting to predict future cloud spending across all your connected cloud providers.
For every [Cost Report](/cost_reports), Vantage generates a forecast that projects where your costs are expected to be by the end of the current month. You can also view projected costs several months ahead. Vantage uses a time-series model to generate these forecasts and will run through all available data ingested into the platform on a per-service basis (e.g., EC2, RDS). These costs are forecasted into the future, taking into account seasonality or one-off spikes.
Vantage offers three types of forecasts:
* **Baseline Forecast**: A time-series forecast based purely on historical cost trends, accounting for seasonality and one-off spikes. This is the default forecast type for all Cost Reports.
* **Dynamic Forecast**: A forecast that you create by uploading projected values of [business metrics](/business_metrics) (such as subscribers, API requests, or transactions) that influence your underlying costs. This forecast type analyzes historical correlations between costs and business metrics to create more accurate projections that align with your business growth expectations.
* **Scenario Model Forecast**: A forecast that you build by combining the Baseline Forecast with one or more [Scenario Models](/scenario_models) that represent known future costs, credits, or trends (such as committed-use discounts, planned credits, or large one-time charges). Use Scenario Model forecasts to model different scenarios, like conservative and aggressive growth plans, on the same Cost Report.
Dynamic Forecasts and Scenario Model Forecasts are both *custom forecasts*. A custom forecast can use a business metric, one or more Scenario Models, or both. When you select both, Vantage uses the Dynamic Forecast as the base and applies the Scenario Model adjustments on top.
The following table summarizes when to use each forecast type:
| Forecast Type | Inputs | Best For | Availability |
| - | - | - | - |
| Baseline | Historical costs only | Steady-state forecasting on any Cost Report | All customers |
| Dynamic | Historical costs + projected [business metrics](/business_metrics) | Aligning forecasts with business growth drivers like subscribers or API requests | Enterprise customers |
| Scenario Model | Historical costs + user-defined [Scenario Models](/scenario_models) | Reflecting known future costs, credits, or discounts in your forecasts | Enterprise customers |
Dynamic forecasting and Scenario Model forecasting are available to Enterprise customers only. Baseline forecasting is available to all Vantage customers.
## Baseline Forecast
To view a baseline forecast on a Cost Report, create a new Cost Report and save it. After you create a new Cost Report, a message is displayed that indicates the forecast is generating. The processing time depends on the amount of data contained in the filtered report, but it usually takes less than 10 minutes.
If you add additional filters to an existing report, you need to save the report again for the new forecast to generate. Forecasts are generated based on *saved* data.
The forecast for the rest of the current month is displayed, by default, on the chart. Forecasts are available on line charts and bar charts. On line charts, forecasts are available for all date binning options. For bar charts, you can view forecasts for day, week, and month date binnings.
The forecast includes an upper-expected band and a lower-expected band, with a median forecast that is in the middle of these two ranges. This forecast is updated daily as new cost data arrives.
To view a forecast for an extended period, open the date picker to the top right of the chart.
On the left, under **Forecast Periods**, select either **Next Month**, **Next 3 Months**, or **Next 6 Months**.
Click **Apply**. Change to either the bar or line chart view to see a forecast.
In the below example image, bars for future months are light purple. Error bars are present for future months to represent the upper and lower bounds of the forecast. When a date bin (day, week, or month) spans both past and future dates, the bar is partially purple to indicate the portion that is forecasted. For example, in this report binned weekly, the bar for January 19, 2026 is partially purple because that week includes both past and future dates; only the future portion of that week's bar appears in purple. You can hover over any future date to see the forecasted min, max, and median. Total forecasted costs are displayed above the chart, next to currently accrued costs. Forecasts are also present in grouped bar charts.
In the below example image, the light-purple area is the forecast range, with upper and lower bounds. The dark-purple dotted line represents the median forecast for that month. Hover over any future date to see the forecast median and the previous period's costs. Total forecasted costs are displayed above the chart, next to currently accrued costs.
### View Service Forecasts
In addition to aggregate forecasts on Cost Reports, you can also view a per-service cost forecast. On any Cost Report, select a row from the table. An individual forecast is displayed for the selected service.
## Dynamic Forecast
Dynamic forecasting is available to Enterprise customers only.
Dynamic forecasting lets you align your cloud cost forecasts with the projected growth of your business. By uploading future projections of [business metrics](/business_metrics) that influence your underlying costs, such as expected subscriber growth, application requests during a product launch, or compute-intensive test volumes, Vantage incorporates these projections into its forecasting model to create more accurate, business-aligned cost predictions.
You can use a Dynamic Forecast on its own or as the base for a custom forecast that also includes one or more [Scenario Models](#scenario-model-forecasts).
### How Dynamic Forecasting Works
Dynamic forecasting uses machine learning to learn how your business metrics correlate with costs by analyzing historical data. Vantage combines historical business metrics with your projected business metrics into a continuous time series. It then analyzes historical cost data alongside historical business metric values to learn correlation patterns and how changes in your metrics relate to changes in costs.
Your forecasted business metric values are then incorporated into the forecasting model, which generates future cost predictions by applying the learned correlations to your projected metrics while accounting for baseline cost trends, seasonal patterns, and service-specific scaling factors.
This process runs separately for each cloud service (EC2, RDS, S3, etc.) to account for how different services respond differently to business metric changes, and forecasts are constrained to date ranges where both historical and forecasted metrics exist, with label filters applied when specified.
Example use cases are noted below.
A SaaS company is launching a new feature and expects a 200% increase in API requests over the next three months. They have a business metric tracking API requests per day. By uploading projected API request values for the launch period, their cost forecast automatically adjusts to reflect the anticipated increase in compute and data transfer costs associated with the traffic spike.
An e-commerce platform expects 100% year-over-year growth in subscribers during the holiday season. They upload projected subscriber counts for November and December. Their cost forecast now reflects the expected increase in infrastructure costs needed to support the growing user base, helping the finance team plan for capital-intensive months.
A health technology company runs compute-intensive tests that significantly impact cloud costs. They have projections of the quantity of tests they will run each month, labeled by test type. By uploading these projections, their cost forecasts reflect known increases in testing volume, ensuring the finance team is aware of particularly capital-intensive months.
### Create a Dynamic Forecast
Follow the steps in the [Forecasted Metrics section](/business_metrics#forecasted-metrics) of the *Business Metrics* page to create a business metric, upload historical data, upload forecasted metrics, and assign it to a Cost Report.
Navigate to the associated Cost Report and click the **Forecasts** tab. The **Forecasts** tab displays a side-by-side comparison table showing forecasted costs by month for each forecast type:
* **Baseline**: The default time-series forecast based on historical trends
* **Dynamic (based on a business metric)**: Forecasts that incorporate projected business metric values (one for each business metric assigned to the report)
Use the **Default Forecast** dropdown at the top to select which forecast type you want to display on the Cost Report chart. If you have multiple business metrics assigned to a Cost Report, you'll see a separate dynamic forecast for each one. You can select which business metric forecast to use as your primary forecast from the dropdown menu.
On this tab, if no forecasts are available yet, you'll see a "Generating Forecast" message asking you to check back once they're done. If only business metric forecasts are still generating, a blue alert banner will indicate which forecast is being generated (e.g., "Generating User Sessions Forecast: Check back once cost data has been processed"). In the forecast table, zero values or periods with no forecast are displayed as a "-" (dash).
### Label Filters and Dynamic Forecasts
If you have applied a label filter for a business metric on a Cost Report, Vantage will use the same label filter when applying projected business metrics to your forecast, as long as your forecasted metrics include the same label structure as your historical data. See the [Labeled Business Metrics](/business_metrics#labeled-business-metrics) section for more information about using labels.
### Update Dynamic Forecasts
Any time you update your forecasted business metrics, Vantage automatically recalculates all associated forecasts. All Cost Reports using that business metric will reflect the updated projections within approximately 10 minutes. You don't need to manually refresh or regenerate forecasts.
## Scenario Model Forecasts
Scenario Model forecasting is available to Enterprise customers only.
Forecasts built from Scenario Models let you define how your future costs should behave by combining the Baseline Forecast with [Scenario Models](/scenario_models), reusable components that represent known future costs, credits, or trends. Typical use cases include modeling upcoming committed-use discounts, anticipated provider credits (such as AWS MAP credits), large one-time charges, or planned savings from optimization work.
You can create multiple Scenario Model forecasts on the same Cost Report to compare scenarios, such as a conservative forecast and an aggressive growth forecast.
### How Scenario Models Combine
A Scenario Model forecast starts from a **base forecast** and then adjusts it with your Scenario Model amounts, month by month. The base is the [Baseline Forecast](#baseline-forecast) by default, or the [Dynamic Forecast](#dynamic-forecast) if you also pick a business metric on the same forecast (see [Combine Scenario Models with a business metric](#combine-scenario-models-with-a-business-metric)). Each Scenario Model adjusts the forecast in one of two [ways](/scenario_models#create-manually):
* **Dollar Amount models** add or subtract a fixed amount. Each month, the model's amount is added to the forecast, moving the whole forecast (its middle estimate and its high and low range) up or down by that amount. The range stays the same size. Dollar amounts apply to the report's total forecast; if a model is filtered to a specific provider and service, the amount is only applied when that provider or service appears in the report.
* **Percentage models** raise or lower the forecast by a percentage (for example, `+10%` or `-5%`). Because the change is a percentage, the high and low range grows or shrinks along with the forecast. If a model is filtered to a specific provider and service, the percentage only applies to that provider or service's share of the forecast, and the change is reflected in the report total.
When a forecast uses more than one Scenario Model, Vantage applies the **percentage changes first** (in priority order, lowest number first), then adds the **dollar amounts**. If the result would be negative (for example, when credits are larger than the forecast), Vantage stops at `$0` instead of showing a negative number.
Each percentage Scenario Model needs a unique **Priority**, which sets the order they're applied in. Dollar models are applied after percentage models, and their amounts simply add together.
#### Example (Dollar Models)
Suppose the Baseline Forecast on a Cost Report predicts the following for **July 2026**:
* Median: `$42,000`
* Range: `$38,000` to `$46,000`
You attach two dollar-amount Scenario Models to a new forecast on that report:
* **H2 Committed Use Discount**: `$15,000` per month from July through December 2026 (additional committed spend).
* **AWS MAP Credit**: `-$8,000` per month from June through September 2026 (a credit, entered as a negative amount).
Both models cover July, so the July overlay is `$15,000 + (−$8,000) = $7,000`. Vantage adds that overlay to every point in the Baseline Forecast for July:
| Month | Baseline Median | Overlay | Forecast Median | Forecast Range |
| - | - | - | - | - |
| July 2026 | `$42,000` | `+$7,000` | `$49,000` | `$45,000 – $53,000` |
The same math runs for every forecasted month, so months where no Scenario Model period applies are left at the Baseline Forecast value.
#### Example (Multiple Models by Priority)
Selecting several Scenario Models on one forecast shows how percentage and dollar models combine. Suppose the base forecast for a month has a median of `$100,000`, and you attach three models:
* **Q3 Efficiency Program**: `-5%` (Percentage), priority `1`.
* **New Region Uplift**: `+10%` (Percentage), priority `2`.
* **H2 Committed Use Discount**: `+$15,000` (Dollar Amount).
Vantage applies the percentage models first, in priority order, and then adds the dollar model:
| Step | Calculation | Median |
| - | - | - |
| Base forecast | — | `$100,000` |
| Apply `-5%` (priority 1) | `$100,000 × 0.95` | `$95,000` |
| Apply `+10%` (priority 2) | `$95,000 × 1.10` | `$104,500` |
| Add `+$15,000` (dollar) | `$104,500 + $15,000` | `$119,500` |
The same sequence is applied to the upper and lower ends of the forecast range, and the final values never drop below `$0`. Each percentage model must have a unique **Priority** so Vantage applies them in a consistent order.
#### Combine Scenario Models with a Business Metric
When you also select a **business metric** on the forecast, the base becomes the [Dynamic Forecast](#dynamic-forecast) for that business metric instead of the Baseline Forecast. The Scenario Model amounts are then applied on top of the Dynamic base using the same rules above (percentages first by priority, then dollar amounts, and the result never drops below `$0`). If the selected business metric does not have both historical and forecasted values, the forecast cannot be generated.
### Important Details
Keep the following in mind when you build forecasts from Scenario Models:
* **Credits and discounts**: Enter credits, refunds, and planned savings as **negative amounts** on a Scenario Model period.
* **Granularity**: Scenario Model periods are always defined in whole months, and the **Forecasts** tab comparison view displays monthly values.
* **Periods outside the forecast window**: Periods (or portions of periods) that fall entirely before the forecast start date or after the forecast end date are ignored. Partial overlap is clipped to the window.
### Create a Forecast from Scenario Models
Follow these steps to build a new forecast on a Cost Report from one or more Scenario Models:
To build a forecast from Scenario Models, create at least one Scenario Model first. Navigate to **Financial Planning > Scenario Models** and follow the steps in the [Scenario Models](/scenario_models) documentation to create the models that represent your known future costs, credits, or trends. (A forecast can also be created from a business metric alone, without any Scenario Models, as described below.)
On any Cost Report, click the **Forecasts** tab.
Click the **Default Forecast** dropdown and select **Create new forecast**. The **Create New Forecast** panel opens.
Enter a **Forecast Name** (for example, *Conservative FY26 Plan* or *H2 with MAP Credits*). Under **Scenario Models**, select one or more of your existing models to apply to this forecast.
You can optionally also choose a **Business Metric** to base the forecast on a [Dynamic Forecast](#dynamic-forecast) (only business metrics that have both historical and forecasted values for this report are listed). A forecast must include at least one Scenario Model or a business metric.
Each selected Scenario Model appears in a summary list showing its [Net Change](/scenario_models) badge and an **(Expired)** label if all of its periods have ended. Click the remove (**x**) button on a row to drop a model before saving.
Check **Set as default forecast** if you want this forecast to appear as the primary forecast on the Cost Report's **Overview** tab.
Click **Save Forecast**. Vantage will begin generating the forecast. While generation is in progress, the **Forecasts** tab displays a **Generating Forecast** status. Most forecasts complete within approximately 10 minutes. Once generation completes, the new forecast appears in the Forecasts table alongside the Baseline Forecast.
### Model Multiple Scenarios
You can create multiple Scenario Model forecasts on the same Cost Report to model different scenarios side by side. For example, you might build one forecast that reflects only committed discounts and a second forecast that also includes credits expected from a provider-negotiated program. Each forecast is independent and can be applied to the Cost Report individually via the **Default Forecast** dropdown.
### Edit or Delete a Scenario Model Forecast
From the **Forecasts** tab, click the edit icon next to a forecast to update its name or change which Scenario Models are applied. If you change the applied Scenario Models, Vantage automatically reprocesses the forecast; updates typically appear within approximately 10 minutes.
To delete a forecast, use the delete action on the same column. If the deleted forecast was the Cost Report's default forecast, the Cost Report reverts to the Baseline Forecast as the default.
The Baseline Forecast is always available and cannot be deleted from the **Forecasts** tab. A Dynamic forecast is created automatically when you assign a [business metric](/business_metrics#forecasted-metrics) to the Cost Report, and removed when you unassign it. You can also create a forecast from a business metric directly in the **Create New Forecast** panel (with or without Scenario Models); forecasts created this way can be edited or deleted from the **Forecasts** tab.
### Update Scenario Models Attached to a Forecast
Any time you edit a [Scenario Model](/scenario_models#edit-or-delete-a-scenario-model) from its detail page (for example, editing a period or amount), Vantage automatically reprocesses every forecast that references that model, and affected Cost Reports reflect the updated values within approximately 10 minutes. Changes made through a [CSV import](/scenario_models#import-from-a-csv) are applied to the models immediately, and forecasts that reference them are refreshed on the next scheduled forecast run. You don't need to regenerate forecasts manually.
## Compare Forecast Types
The **Forecasts** tab displays a monthly, side-by-side comparison of every forecast available on the Cost Report:
* **Baseline**: The default time-series forecast based purely on historical trends.
* **Dynamic (per business metric)**: One column per business metric assigned to the report, if any.
* **Scenario Model forecasts**: One column per forecast you have built from Scenario Models on the report, labeled with the name you gave it.
Zero values or months with no forecast are displayed as a `-` (dash).
Each column header includes a small icon that indicates the forecast type: the **Baseline** column has no icon, Scenario Model forecasts use a timeline icon, and Dynamic (business metric) forecasts use a calculator icon. In the example below, the **Forecasts** tab compares four forecasts on one Cost Report: the Baseline, two Scenario Model forecasts (`5% MOM increase` and `EDP Discount`), and one Dynamic forecast driven by a business metric (`Forecasted_metrics`).
## Set the Default Forecast
Use the **Default Forecast** dropdown at the top of the **Forecasts** tab to choose which forecast appears on the Cost Report's **Overview** tab. The dropdown lists the Baseline Forecast along with every Dynamic and Scenario Model forecast on the report.
# GCP Services & Regions for Active Resources
Source: https://docs.vantage.sh/gcp_supported_services
Vantage supports a number of GCP services for reporting and viewing active resources.
## Supported Services
Vantage will show 100% of your organization's accrued costs across all services. Vantage also offers per-resource pricing for the following services using custom logic to query APIs for each GCP service. While Vantage supports per-resource pricing for many popular services, some services are not currently supported.
To request new service support on Vantage, email [support@vantage.sh](mailto:support@vantage.sh) with the subject line of *New GCP Service Support*. Include as much information as you can about the data you want to see.
Below is a list of currently supported GCP services for [active resources](/active_resources). Vantage maintains read-only access to the GCP APIs for these resources.
| Service | Description/Supported Resources |
| - | - |
| Cloud AlloyDB | Vantage supports AlloyDB clusters, instances, and backups. |
| Cloud App Engine | Vantage supports App Engine services. |
| Cloud BigQuery | Vantage supports BigQuery datasets. |
| Cloud Bigtable | Vantage supports Bigtable instances. |
| Cloud Compute | Vantage supports Compute Engine instances and disks. |
| Cloud Containers | Vantage supports Container clusters. |
| Cloud Dataflow | Vantage supports Dataflow jobs. |
| Cloud Firestore | Vantage supports Firestore databases. |
| Cloud Functions | Vantage supports Cloud Functions functions. |
| Cloud Logging | Vantage supports Logging buckets. |
| Cloud Run | Vantage supports Run services. |
| Cloud Spanner | Vantage supports Spanner instances. |
| Cloud SQL | Vantage supports SQL instances. |
| Cloud Storage | Vantage supports Storage buckets. |
| Memorystore for Redis | Vantage supports Redis instances. |
| Secret Manager | Vantage supports Secret Manager secrets. |
## Supported Regions
Vantage can sync resources from all GCP regions with external connectivity.
# Quickstart
Source: https://docs.vantage.sh/getting_started
Set up your Vantage account, connect cloud providers, and begin analyzing your infrastructure costs.
**GET STARTED**
For video tutorials, check out [Vantage University](/vantage_university) .
## Step 1 - Create an Account
* To get started, [create a Vantage account](https://console.vantage.sh/signup).
* Optionally, you can upgrade to a paid plan to unlock additional features and track higher amounts of cloud infrastructure costs. View the [Vantage Pricing page](https://www.vantage.sh/pricing) for all pricing and plan details. All paid plans have an option to trial the service before committing to a subscription.
**LANGUAGE SUPPORT**
The Vantage console UI is currently available in English only. However, the [FinOps Agent](/vantage_finops_agent) can answer questions and provide cost analysis in other languages when interacting via Slack.
## Step 2 - Connect Providers
Next, create a data integration between at least one of your providers and Vantage. Detailed integration documentation is linked for each of the providers below.
Vantage integrates with your AWS account through a Cross-Account IAM role, giving Vantage read-only access to an organization's cost data. After the initial sync, you will be able to take advantage of features in Vantage to manage, inspect, and model your AWS spend.
Vantage integrates with your Azure account through a service principal, providing read-only access to your cost data. Vantage supports pay-as-you-go, Microsoft Customer Agreement (MCA), Enterprise Agreement (EA), and Cloud Solution Provider (CSP) billing models.
Vantage integrates with your GCP account through a service account, providing Vantage with read-only access to an organization's cost data. Following the creation of the role with the appropriate permissions, Vantage will initiate the synchronization of cost data and resource metadata.
Vantage allows you to see in-cluster costs for Kubernetes clusters, including seeing costs by container, service, namespace and label. The Vantage Kubernetes agent is the recommended integration point for ingesting Kubernetes costs into Vantage.
Vantage integrates with Anthropic using an Admin API key (Claude API) and a Claude Enterprise Analytics API key (Claude.ai).
Vantage integrates with Anyscale using a platform API key.
Vantage integrates with Baseten using a Team API key to ingest Dedicated Inference, Training, and Model API cost and usage data.
Vantage integrates with Cartesia using an Admin API key to ingest credit-based model usage and Line agent cost and usage data.
Vantage integrates with CircleCI using a personal API token and organization UUID to ingest usage export data and convert credits into cost using your configured price per credit.
Vantage integrates with ClickHouse Cloud via a read-only Developer key.
Vantage integrates with Cloudflare using an API token and account ID to ingest self-serve cost and usage data.
Vantage integrates with your Confluent account through a revocable read/write API key and secret. Confluent API keys are free for you to create—and adding to the Vantage console only takes a few minutes.
Vantage integrates with your Coralogix account through a revocable read-only API key and your Coralogix domain.
Vantage integrates with Cursor using a read-only API key to track usage and costs.
Vantage integrates with your Databricks account using a dedicated Serverless SQL Warehouse to query system tables within a Unity Catalog-enabled workspace.
Vantage integrates with your Datadog account through a read-only Datadog OAuth token. After connecting, Vantage automatically receives read-only access to appropriate cost and usage APIs to begin ingesting Datadog cost data.
Vantage integrates with your DigitalOcean account using a personal access token scoped to Billing to ingest daily Droplet, backup, snapshot, and other infrastructure costs.
Vantage integrates with Elastic Cloud using a Billing Admin API key to ingest cost and usage data for your Elastic organizations.
Vantage integrates with your ElevenLabs account using a read-only API key with Workspace Analytics access to ingest voice AI cost and usage data.
Vantage integrates with your Fastly account through a read-only API token. Fastly API tokens are free for you to create—and adding them to the Vantage console only takes a few minutes.
Vantage integrates with Fireworks AI using an API key to ingest serverless inference, dedicated deployment, and training cost and usage data.
Vantage integrates with GitHub using the Billing - vantage-sh GitHub application.
Vantage integrates with Grafana Cloud via a read-only token attached to a cloud access policy.
Vantage integrates with Linode via a read-only API key. Vantage also uses service-specific APIs to enrich cost data with additional resource-specific metadata.
Vantage integrates with MongoDB Atlas account through read-only use of the Invoices API. To see Active Resources for your MongoDB Atlas account, Vantage uses the Clusters API and the Projects API.
Vantage integrates with Modal using a token ID and token secret to ingest workspace billing data.
Vantage integrates with your New Relic account through the use of New Relic Usage Data via the New Relic GraphQL API.
Vantage integrates with OpenAI via an Admin Key and queries the Costs endpoint of the Usage API.
Vantage connects to Oracle Cloud using a read-only IAM user and API key to read from a Cost and Usage Reports object storage bucket.
Vantage integrates with your PlanetScale account via the PlanetScale Invoices API using an OAuth workflow.
Vantage integrates with Redis using an account key and user key to ingest FOCUS-formatted cost data.
Vantage integrates with your Snowflake account through a secure, read-only user who has access to Snowflake usage tables. Optionally, Vantage can pull from a dedicated schema that you create.
Vantage integrates with SpaceXAI (formerly xAI) using a Management key to ingest Grok and SpaceXAI API cost and usage data.
Vantage integrates with Temporal Cloud using an API key with Finance Admin permissions to ingest Cloud Billing API data.
Vantage integrates with Twilio using a Standard API key.
Vantage integrates with Vercel through a Vercel Community Integration to ingest cost and usage data across services like Functions, Delivery Network, and Observability.
Vantage integrates any of your Custom Providers through a schema based on the FinOps FOCUS specification.
Vantage integrates with your AWS account through a Cross-Account IAM role, giving Vantage read-only access to an organization's cost data. After the initial sync, you will be able to take advantage of features in Vantage to manage, inspect, and model your AWS spend.
Vantage integrates with your Azure account through a service principal, providing read-only access to your cost data. Vantage supports pay-as-you-go, Microsoft Customer Agreement (MCA), Enterprise Agreement (EA), and Cloud Solution Provider (CSP) billing models.
Vantage integrates with your GCP account through a service account, providing Vantage with read-only access to an organization's cost data. Following the creation of the role with the appropriate permissions, Vantage will initiate the synchronization of cost data and resource metadata.
Vantage allows you to see in-cluster costs for Kubernetes clusters, including seeing costs by container, service, namespace and label. The Vantage Kubernetes agent is the recommended integration point for ingesting Kubernetes costs into Vantage.
Vantage integrates with Anthropic using an Admin API key (Claude API) and a Claude Enterprise Analytics API key (Claude.ai).
Vantage integrates with Anyscale using a platform API key.
Vantage integrates with Baseten using a Team API key to ingest Dedicated Inference, Training, and Model API cost and usage data.
Vantage integrates with Cartesia using an Admin API key to ingest credit-based model usage and Line agent cost and usage data.
Vantage integrates with CircleCI using a personal API token and organization UUID to ingest usage export data and convert credits into cost using your configured price per credit.
Vantage integrates with ClickHouse Cloud via a read-only Developer key.
Vantage integrates with Cloudflare using an API token and account ID to ingest self-serve cost and usage data.
Vantage integrates with your Confluent account through an API key and secret.
Vantage integrates with your Coralogix account through a revocable read-only API key and your Coralogix domain.
Vantage integrates with Cursor using a read-only API key to track usage and costs.
Vantage integrates with your Databricks account using a dedicated Serverless SQL Warehouse to query system tables within a Unity Catalog-enabled workspace.
Vantage integrates with your Datadog account through a read-only Datadog OAuth token. After connecting, Vantage automatically receives read-only access to appropriate cost and usage APIs to begin ingesting Datadog cost data.
Vantage integrates with your DigitalOcean account using a personal access token scoped to Billing to ingest daily Droplet, backup, snapshot, and other infrastructure costs.
Vantage integrates with Elastic Cloud using a Billing Admin API key to ingest cost and usage data for your Elastic organizations.
Vantage integrates with your ElevenLabs account using a read-only API key with Workspace Analytics access to ingest voice AI cost and usage data.
Vantage integrates with your Fastly account through a read-only API token. Fastly API tokens are free for you to create—and adding them to the Vantage console only takes a few minutes.
Vantage integrates with Fireworks AI using an API key to ingest serverless inference, dedicated deployment, and training cost and usage data.
Vantage integrates with GitHub using the Billing - vantage-sh GitHub application.
Vantage integrates with Grafana Cloud via a read-only token attached to a cloud access policy.
Vantage integrates with Linode via a read-only API key. Vantage also uses service-specific APIs to enrich cost data with additional resource-specific metadata.
Vantage integrates with MongoDB Atlas account through read-only use of the Invoices API. To see Active Resources for your MongoDB Atlas account, Vantage uses the Clusters API and the Projects API.
Vantage integrates with Modal using a token ID and token secret to ingest workspace billing data.
Vantage integrates with your New Relic account through the use of New Relic Usage Data via the New Relic GraphQL API.
Vantage integrates with OpenAI via an Admin Key and queries the Costs endpoint of the Usage API.
Vantage connects to Oracle Cloud using a read-only IAM user and API key to read from a Cost and Usage Reports object storage bucket.
Vantage integrates with your PlanetScale account via the PlanetScale Invoices API using an OAuth workflow.
Vantage integrates with Redis using an account key and user key to ingest FOCUS-formatted cost data.
Vantage integrates with your Snowflake account through a secure, read-only user who has access to Snowflake usage tables. Optionally, Vantage can pull from a dedicated schema that you create.
Vantage integrates with SpaceXAI (formerly xAI) using a Management key to ingest Grok and SpaceXAI API cost and usage data.
Vantage integrates with Temporal Cloud using an API key with Finance Admin permissions to ingest Cloud Billing API data.
Vantage integrates with Twilio using a Standard API key.
Vantage integrates with Vercel through a Vercel Community Integration to ingest cost and usage data across services like Functions, Delivery Network, and Observability.
Vantage integrates any of your Custom Providers through a schema based on the FinOps FOCUS specification.
**OTHER PROVIDERS**
Vantage will be launching support for additional cloud infrastructure providers in the future. If you have a particular provider that you would like supported, please reach out to [support@vantage.sh](mailto:support@vantage.sh).
## Step 3 - View Ingested Costs and Create Cost Reporting Resources
Once you create some provider integrations, Vantage will automatically begin ingesting billing information for your account. The default landing page in the Vantage console is the [**Overview**](/overview) page. This page serves as an executive-level summary, providing a comprehensive snapshot of the cost metrics that matter most to you. Use the **Explore** bar in the top navigation to quickly access pages, reports, dashboards, and other resources in your current workspace.
## Next Steps - After Your First Integration Imports
After connecting a provider and waiting for the initial import to complete, use the checklist below to get the most out of Vantage.
Navigate to **Settings > Integrations** and confirm your integration shows a **Stable** status. If it shows **Importing**, data is still being backfilled. If it shows **Error** or **Warning**, see the [Integration Status](/vantage_account#integration-status) documentation for troubleshooting steps.
By default, new integrations may not be visible in all workspaces. Navigate to **Settings > Workspaces** to manage which integrations are available in each workspace. See the [Workspaces](/workspaces#manage-workspace-provider-integrations) documentation for details.
Navigate to **Reporting > Cost Reports** and click **+ New** to create a Cost Report. Add filters for the provider you just connected, select a date range, and save the report. See the [Cost Reports](/cost_reports) documentation for a full walkthrough.
Once you have a Cost Report, you can attach a [budget](/budgets) to track spending against a target, or create a [Cost Alert](/cost_alerts) to receive notifications when costs exceed a threshold.
Depending on your use case, consider setting up:
* [Virtual Tags](/tagging) to organize costs without modifying your cloud infrastructure
* [Dashboards](/dashboards) to create a centralized view of multiple Cost Reports
* [Cost Recommendations](/cost_recommendations) to identify optimization opportunities
* [Kubernetes cost monitoring](/kubernetes) if you run containerized workloads
### Upgrading Your Plan
If you signed up for a free account and want to upgrade to a paid plan, navigate to **Settings > Billing** in the Vantage console. For questions about plan activation or billing, contact [support@vantage.sh](mailto:support@vantage.sh).
# GitHub MCP
Source: https://docs.vantage.sh/github_mcp
Connect the GitHub MCP to the Vantage FinOps Agent to work with your GitHub issues, pull requests, and code, and to turn cost recommendations into actionable GitHub issues.
The GitHub MCP Connector links the [Vantage FinOps Agent](/vantage_finops_agent) to GitHub. After an Organization Owner or Integration Owner enables the connector, each user connects their own GitHub account, and the Agent works within the repositories the Vantage GitHub App can access and your own GitHub permissions allow.
The Agent can:
* **Work with GitHub**: search and read issues, pull requests, code, and Actions/workflow runs, and create or update issues on your behalf.
* **Turn recommendations into issues**: locate the Terraform resource behind a rightsizing recommendation and open a GitHub issue with the implementation context your engineers need. This uses the repositories you connect in **Repository Settings**.
The GitHub MCP Connector is one of several [MCP Connectors](/vantage_finops_agent#mcp-connectors) for the FinOps Agent. It is available to all Vantage customers using the FinOps Agent, in the [Vantage console](https://console.vantage.sh/agent), Slack, and [Canvas](/canvas).
The Agent acts only within your own GitHub permissions and the repositories the Vantage GitHub App can access. When you authorize GitHub, you can grant the app access to all of your repositories or only selected ones. If your organization also connects specific repositories in **Repository Settings** (used for the [recommendation-to-issue workflow](#additional-capability-turn-recommendations-into-github-issues)), the Agent treats those as its default focus and may concentrate on them for general questions unless you point it at another repository you can access.
## Capability Overview
Both capabilities are managed from **Settings** > **Integrations** > **MCP Connectors** > **GitHub MCP**.
| Capability | What the Agent can do | Access boundary |
| - | - | - |
| Work with GitHub | Search and read issues, pull requests, code, and Actions; create and update issues on your behalf | The repositories the Vantage GitHub App can access, intersected with your own GitHub permissions |
| Turn recommendations into issues | Locate the Terraform resource behind a rightsizing recommendation and open a GitHub issue with cost and implementation context | The repositories connected in Repository Settings that contain Terraform |
## Prerequisites
Before you start, make sure you have:
* The [FinOps Agent](/vantage_finops_agent) enabled in Vantage. The GitHub MCP settings page prompts you to enable it first if it is not already on.
* A Vantage role that can manage integrations, such as **Organization Owner** or **Integration Owner**, to enable the connector for your organization. See [Role-Based Access Control](/rbac) for details.
* A GitHub account for each Vantage user who wants to use the connector. Each user authorizes their own GitHub account.
The [recommendation-to-issue workflow](#additional-capability-turn-recommendations-into-github-issues) additionally requires a GitHub **Organization Owner** to install the Vantage GitHub App and connect at least one repository that contains Terraform.
## Connect the GitHub MCP
The general GitHub MCP lets the FinOps Agent work with GitHub as you. After your organization enables the connector, each user connects their own GitHub account, and the Agent works within the repositories the Vantage GitHub App can access and your own GitHub permissions allow.
### How the Connection Works
The general GitHub MCP uses a two-part connection model:
1. An **Organization Owner** or **Integration Owner** enables the GitHub MCP for your organization, from the **MCP Settings** tab on the [Integrations page](https://console.vantage.sh/settings/integrations).
2. **Each individual user authorizes their own GitHub account** through OAuth, from the **MCP Settings** tab or when the Agent prompts them mid-conversation. During authorization, you can grant the Vantage GitHub App access to all of your repositories or only selected ones.
The Agent never does more than the connecting user could do directly in GitHub.
Optionally, an Organization Owner or Integration Owner can connect specific repositories in the **Repository Settings** tab (see [Turn recommendations into GitHub issues](#additional-capability-turn-recommendations-into-github-issues)). Connecting repositories is required for that workflow, and it also sets those repositories as the Agent's default focus, so when repositories are connected, the Agent concentrates on them for general questions unless you point it at another repository you can access.
User access tokens are short-lived (8 hours) and refreshed automatically. If a connection lapses or is revoked, the connector shows an authentication error and prompts you to reconnect.
### Settings Tabs
The GitHub MCP settings page has up to three tabs:
* **MCP Settings**: enable the connector for your organization (Organization Owners and Integration Owners), and connect, disconnect, or reconnect your own GitHub account.
* **Repository Settings**: install the Vantage GitHub App and select repositories, and add repository descriptions. Required for the recommendation-to-issue workflow, and it sets the Agent's default repository focus.
* **Organization Settings** (Organization Owners and Integration Owners only): manage organization enablement and see the list of users who have connected.
Once the GitHub MCP is enabled for your organization, any Vantage role (down to Organization Viewer) can connect their own GitHub account. Enabling it also lets **Organization Editors and Organization Viewers** open Settings > Integrations, where they see only the **MCP Connectors** section. Until you connect your own account, GitHub appears as **Not Connected**, like the other connectors—or as **Update Required** if your organization has already connected repositories for the [recommendation-to-issue workflow](#additional-capability-turn-recommendations-into-github-issues). See [Role-Based Access Control](/rbac) for details.
### Permissions and Data Access
The GitHub MCP is scoped so the Agent can **read** across your GitHub context but can only **write** issues. Once connected, the FinOps Agent can:
* **Read** repositories and code, pull requests, and Actions/workflow runs in the repositories you can access.
* **Create and update issues** on your behalf (the only write action).
The Agent does not commit code or open or merge pull requests through the MCP. To turn a recommendation into an actual code change, use the [recommendation-to-issue workflow](#additional-capability-turn-recommendations-into-github-issues), which files an issue an engineer or GitHub Copilot can implement as a pull request.
Access is limited to the repositories the Vantage GitHub App can reach, intersected with the connecting user's own GitHub permissions:
| Permission | Access | Why Vantage needs it |
| - | - | - |
| Repository contents | Read | Read code and repository context to answer questions. |
| Issues | Read and write | Create and update GitHub issues and avoid duplicating issue context. |
| Pull requests | Read | Read pull request context for questions and to attribute merged changes to realized savings. |
| Actions | Read | Read workflow run history to correlate deploys with cost changes. |
| Metadata | Read | Identify repositories and basic organization metadata. |
Vantage uses short-lived tokens when it needs to read repository context or create an issue. Vantage does not persist your source code, and data retrieved through the connector is not used to train any models.
The Agent only creates or updates an issue when you explicitly ask it to, and it searches for an existing issue before opening a new one. All writes are bounded by your own GitHub permissions. In [Canvas](/canvas), the GitHub MCP is read-only, so issue creation is not available there. If a write returns an authorization or scope error, the Agent surfaces it and points you back to the **GitHub MCP** settings page to reconnect rather than retrying.
### Connection Steps
As an **Organization Owner** or **Integration Owner**, click **Settings** in the top navigation. On the left navigation, select **Integrations**, then find the **MCP Connectors** section and select **GitHub MCP**. In the **MCP Settings** tab, enable the connector for your organization.
If the page shows a banner asking you to enable the FinOps Agent, open the [FinOps Agent settings page](https://console.vantage.sh/settings/finops_agent) and enable it first, then return to the GitHub MCP page.
On the **GitHub MCP** page, in the **MCP Settings** tab, click **Connect GitHub**. Vantage redirects you to GitHub to complete the OAuth flow. Every user who wants to use the connector completes this step for their own account. During authorization, you can grant the Vantage GitHub App access to all of your repositories or only selected ones.
Sign in to GitHub and authorize access. After you approve, GitHub redirects you back to Vantage and your connection status changes to connected.
Back in Vantage, confirm the GitHub MCP shows as connected. You can now ask the FinOps Agent GitHub-aware questions in the console or in Slack.
You can also connect GitHub directly from an Agent conversation. When you ask the Agent to do something that needs GitHub and you have not connected yet, it prompts you to authorize your account inline.
To use the [recommendation-to-issue workflow](#additional-capability-turn-recommendations-into-github-issues)—or to set a default set of repositories the Agent focuses on—an **Organization Owner** or **Integration Owner** opens the **Repository Settings** tab and connects repositories. See [Set Up Repository Access](#set-up-repository-access) for the full steps.
### Example Use Cases
Once the GitHub MCP is connected, the FinOps Agent decides when to reach for GitHub tools based on the question you ask. It can call GitHub tools in the same turn it uses Vantage tools.
For prompting best practices and more copy-paste examples, see the [FinOps AI Prompt Guide](/finops_ai_prompt_guide).
Is there an open issue or pull request related to our EKS cluster that might explain this week's cost spike?
Create a GitHub issue in our infrastructure repo summarizing this rightsizing recommendation, including the current and recommended instance type and estimated monthly savings.
Which repository defines the instance type for this resource, and what is the current value in the code?
The Agent can also read closed issues and pull requests, which is useful for tying engineering throughput back to cost. This pairs well with [Canvas](/canvas) for a persistent view.
Over the last 3 months, compare our Cursor spend to the number of pull requests merged in our main app repo, and show a per-PR cost.
Did any deploys or merged pull requests line up with this week's cost spike on our EKS cluster?
## Additional Capability: Turn Recommendations into GitHub Issues
As an additional capability on top of the general connector, the FinOps Agent can locate the Terraform resource behind an AWS rightsizing recommendation and open a GitHub issue with the recommendation summary, resource location, code context, estimated savings, and change instructions. This workflow uses the repositories you connect in **Repository Settings**.
Make sure at least one connected repository contains Terraform infrastructure code. If your Terraform is split across repositories, connect every repository that may contain the resources you want to action.
### Set Up Repository Access
From **Settings** > **Integrations** > **MCP Connectors** > **GitHub MCP**, open the **Repository Settings** tab and start the GitHub App installation.
In GitHub, choose the organization that owns the repositories you want the Agent to use. The person completing this step should be a GitHub **Organization Owner**. If a non-owner starts the flow, GitHub may create an installation request instead of completing the connection. In that case, have an organization owner repeat the connection.
Grant access only to the repositories that contain Terraform code the Agent should inspect.
Select every repository the Agent should consider. At least one repository must be selected. Add a short description for each repository to help the Agent choose the right one when several are available.
After repositories are connected, the connector may display a **Generated Summary** for each repository. Vantage creates this summary from repository metadata, README content, file paths, and your description to help the Agent understand what infrastructure the repository manages. The summary may take a few minutes to appear after saving.
```md theme={null}
Production AWS infrastructure for customer-facing services, including ECS services, RDS databases, load balancers, and autoscaling configuration.
```
```md theme={null}
Shared platform Terraform for networking, IAM, observability, DNS, and organization-wide AWS account baselines.
```
```md theme={null}
Data platform Terraform for Redshift, EMR, Glue, S3 data lakes, and analytics workloads.
```
```md theme={null}
Staging environment Terraform for the commerce application. Mirrors production service names, but uses smaller instance types and reduced capacity.
```
If you are unsure what to write, include the cloud provider, environment, major services, and ownership boundary. Avoid vague descriptions like "Terraform repo" or "infrastructure" because they do not help the Agent distinguish between repositories.
Click **Save Changes**. Once saved, the Agent can use the selected repositories when you ask it to open an issue for a recommendation.
### Workflow Example
The example below shows the full handoff from a FinOps Agent conversation to a GitHub issue, then to an optional GitHub Copilot pull request. In this flow, the Agent starts with a rightsizing recommendation, narrows it to a connected repository, asks you to confirm the resource it found, and creates an issue with the implementation context. The workflow is available in both the console and Slack; the screenshots below show it in Slack.
The Agent surfaces rightsizing recommendations and offers to create a GitHub issue because repository access is configured.
After you ask the Agent to create an issue, it narrows the search to the connected repositories and looks for the Terraform resource it believes should be changed.
The Agent shows the evidence it used, including the repository, file, resource, current value, recommended value, and estimated savings. You confirm before the issue is created.
The resulting GitHub issue includes the recommendation summary, resource location, relevant code snippets, estimated savings, change instructions, and rollout notes.
If your team assigns GitHub Copilot to the issue, Copilot can use the issue context to open a pull request for review. In this example, the pull request changes a Terraform instance type default and includes rollout notes for the infrastructure team.
### What the GitHub Issue Includes
The Agent writes the issue so an engineer or coding agent can start with context instead of rediscovering the recommendation manually. The issue may include:
Repository name, file path, resource address, and relevant code context when available.
The current value, recommended value, and implementation guidance for the update.
Estimated monthly savings and the Vantage recommendation that motivated the issue.
Notes to help your team validate the change, assign ownership, or hand the issue to GitHub Copilot.
### Best Practices
Select the repositories that most clearly map to your initial recommendations. You can add more repositories later from **Settings** > **Integrations** > **MCP Connectors** > **GitHub MCP** > **Repository Settings**.
Descriptions are one of the strongest signals the Agent can use when it needs to choose between multiple infrastructure repositories.
Review the Agent's proposed repository, file, resource, and change before confirming issue creation.
After Vantage creates the issue, use your normal GitHub process for labels, project boards, owners, code review, and Copilot assignment.
## Troubleshooting
Enable the [FinOps Agent](/vantage_finops_agent) first from the [FinOps Agent settings page](https://console.vantage.sh/settings/finops_agent), then return to **Settings** > **Integrations** > **MCP Connectors** > **GitHub MCP**.
An **Organization Owner** or **Integration Owner** must enable the GitHub MCP for your organization before individual users can authorize their accounts. If you do not see the option to connect, ask an administrator to enable it from the [Integrations page](https://console.vantage.sh/settings/integrations).
User access tokens are short-lived and refreshed automatically, but a grant can still expire or be revoked in GitHub. Reconnect your GitHub account from the **GitHub MCP** page to re-authorize.
For the recommendation-to-issue workflow, a GitHub Organization Owner should install the app. If a non-owner starts the flow, GitHub may create an installation request instead of completing the connection.
The recommendation-to-issue workflow requires at least one selected repository. If the repository you need is missing, update the GitHub App installation in GitHub to grant access to that repository, then return to Vantage and select it in **Repository Settings**.
Confirm that the selected repositories contain the relevant Terraform code and that the repository descriptions are specific. If your Terraform is split across repositories, add every likely repository.
## Frequently Asked Questions
Not for general GitHub questions. After you connect your GitHub account, the Agent works within the repositories the Vantage GitHub App can access and your own GitHub permissions allow (during authorization you can grant access to all or only selected repositories). Connecting specific repositories in **Repository Settings** is required for the [recommendation-to-issue workflow](#additional-capability-turn-recommendations-into-github-issues), and it also sets those repositories as the Agent's default focus—so when repositories are connected, the Agent concentrates on them for general questions unless you point it at another repository you can access.
No. At this time, Vantage creates GitHub issues only. Your team can assign the issue to an engineer or to GitHub Copilot in GitHub.
No. Issue creation is user-triggered through the FinOps Agent workflow, and the Agent asks for confirmation before creating the issue.
No. The GitHub MCP Connector is separate from the [GitHub cost integration](/connecting_github), which ingests GitHub cost and usage data into Vantage.
No. Vantage uses short-lived tokens to read repository context when needed. For the recommendations workflow, Vantage stores selected repository metadata, descriptions, and generated summaries, but does not persist your source code.
At this time, the Agent focuses on AWS rightsizing recommendations that can be mapped to Terraform-backed changes. Vantage may expand support over time.
# Guides
Source: https://docs.vantage.sh/guides
Outcome-oriented guides for using Vantage in common FinOps workflows.
Use these guides when you want an opinionated workflow for using Vantage, rather than a feature-by-feature reference.
A four-week plan from first integration to a working FinOps cadence.
Attribute shared and team spend with a practical showback or chargeback model.
Set up role-based access control for teams, workspaces, and large organizations.
Keep tag processing fast as you add providers, values, and nested allocation chains.
Learn what the FinOps Agent can do and how to phrase effective prompts.
Use AI to propose Vantage changes, then manage them with Terraform and code review.
# Chargeback and Showback
Source: https://docs.vantage.sh/guides/chargeback_showback
Build a practical showback or chargeback model in Vantage with Virtual Tags, Cost Reports, Saved Filters, Budgets, and scheduled distribution.
Use this guide to decide whether to start with showback or chargeback, choose the right Vantage allocation method, build reusable reports, and keep ownership current as teams change.
This guide is for FinOps and Finance teams that need to attribute cloud spend to teams, products, business units, or cost centers.
## Step 1: Choose Showback or Chargeback
These two words are often used interchangeably, but they represent different commitments. *Showback* reports each team its share of the bill for visibility. *Chargeback* takes those same numbers and posts them to the team's actual budget or P\&L, which moves money inside your company.
Start with showback unless Finance has already approved the cost centers, allocation rules, and accounting process that will use the numbers.
| | Showback | Chargeback |
| - | - | - |
| What it does | Reports each team its share of spend | Posts that spend to the team's budget |
| Does money move? | No | Yes |
| Goal | Visibility | Budget accountability |
| Tagging needed | Partial coverage is workable | High, reviewed coverage |
| When to use | While validating ownership | Once Finance can act on the output |
The same Virtual Tags and Cost Reports can support both. The difference is whether the report is informational or whether Finance posts the result to a budget, cost center, or P\&L.
## Step 2: Get the Allocation Foundation Right
Allocation depends on the cost data and metadata Vantage receives from your providers.
Two layers matter here:
1. **Provider tags.** These come from AWS, Azure, GCP, and other providers. They determine which tag keys and values Vantage can use from imported provider cost data. To see what Vantage has imported, open **Settings > Tags** and review the keys and values on the **All Tags** tab.
2. **Virtual Tags.** [Virtual Tags](/tagging) standardize inconsistent keys, label costs that lack usable provider tags, and split shared costs across owners inside Vantage without changing cloud resources.
Before you build your allocation structure, set an internal coverage target. Track coverage with the report in [Step 6: Measure Allocation Coverage](#step-6-measure-allocation-coverage-and-close-the-gap).
## Step 3: Choose Your Allocation Method
A Virtual Tag value can relabel matching costs or allocate costs across owners. Choose the method based on how ownership is decided.
| Your situation | Method | Why | Reference |
| - | - | - | - |
| Standardize inconsistent keys, or label resources that cannot be tagged | Custom Value | A static label applied to matching costs. No redistribution. | [Custom Value Tags](/tagging#custom-value-tags) |
| A shared cost should follow each team's actual usage | Cost-Based | Splits the cost in proportion to spend on the underlying service. | [Cost-Based example](/tagging_examples#cost-based-allocation-example) |
| The split is fixed or contractually negotiated | Percent-Based | Splits the cost by fixed percentages you set. | [Percent-Based example](/tagging_examples#percent-based-allocation-example) |
| The cost should follow an external driver like seats or requests | Business Metric-Based | Splits the cost in proportion to a business metric you import or connect. | [Business Metrics example](/tagging_examples#business-metrics-based-allocation-example) |
Use Cost-Based when the split should move with usage. Use Percent-Based when Finance has approved a fixed ratio.
### Custom Value: Standardize and Label
Use Custom Value tags to turn provider-specific filters into one reporting value. For example, one team may use `env`, another `Environment`, and another `environment`. A Custom Value tag, or [Tag Key Collapsing](/tagging#tag-key-collapsing) when you only need to merge keys, gives you one clean key to report on.
Custom Value tags also handle costs that lack usable provider tags. For example, create a Custom Value with an Output Costs Filter scoped by provider, category, service, resource ID, or tag, then give those matching costs a reporting value.
### Cost-Based: Split a Shared Cost by Usage
Use this when a shared charge should land on teams in proportion to how much of the underlying service they used. In a Cost-Based value on your `team` tag:
* **Input Costs Filter:** The usage costs that should determine the split, often filtered to Charge Type `Usage`.
* **Tag Key:** your existing owner tag, such as `team`.
* **Output Costs Filter:** the shared cost you want to split.
If Infrastructure drove 50% of tagged usage, Mobile 20%, and Data 30%, Vantage splits the shared charge 50/20/30 and recomputes that split as usage shifts month to month.
See an example with screenshots in the [Tagging example](/tagging_examples#cost-based-allocation-example) docs.
### Percent-Based: Split a Shared Cost by a Fixed Ratio
Use this for negotiated or contractual splits that should not move with usage, like a Marketplace purchase. In a Percent-Based value on your `team` tag:
* **Output Costs Filter:** Marketplace purchases only.
* **Values and percentages:** `infra` 60, `mobile` 30, `data` 10.
A Percent-Based tag requires at least two values, each percentage must be greater than 0% and less than 100%, and the percentages must total exactly 100%. Vantage shows a running total as you allocate so you can see when you reach 100%.
See an example with screenshots in the [Tagging example](/tagging_examples#percent-based-allocation-example) docs.
### Business Metric-Based: Split by a Real Driver
When a cost should follow something measurable, like seats per business unit or requests per product, connect a [business metric](/business_metrics) and let it drive the split. Vantage allocates each owner its share of the cost in proportion to its share of the metric.
The business metric has to cover the same dates as the costs you are allocating. If your imported metric stops at an earlier month, the recent costs it should split will get no allocation at all. Keep the metric current, especially at year boundaries when a stale import is easy to miss.
See an example with screenshots in the [Tagging example](/tagging_examples#business-metrics-based-allocation-example) docs.
## Step 4: Model Shared Costs Deliberately
Shared costs need explicit allocation rules. Decide the split with Finance before you encode it in Vantage.
| Shared cost | Method | Approach |
| - | - | - |
| Enterprise support fee | Cost-Based or Percent-Based | Split by each team's share of usage, or use a fixed ratio if Finance has approved one. |
| Marketplace purchase | Percent-Based | Use the negotiated ownership split. It does not change with usage. |
| Commitment discounts (Reserved Instances, Savings Plans) | Percent-Based or Cost-Based | Decide with Finance whether commitments are held centrally or pushed to the teams that benefit. |
| Network and data transfer | Custom Value or Cost-Based | Use [Network Flow Reports](/network_flow_reports) to investigate transfer drivers, then label or split remaining shared transfer costs with an agreed Virtual Tag rule. |
| Shared Kubernetes or container clusters | Business Metric-Based or Cost-Based | Split by namespace, label, or another usage driver available in your Kubernetes cost data. |
| LLM / model-provider inference on shared API keys | Tag-Based | Split inference spend per workload instead of allocating it as a shared pool. On Amazon Bedrock, enable [AWS Bedrock LLM Enrichment](/aws_bedrock_enrichment) and stamp `team`, `customer_id`, or `feature` in `requestMetadata`. For every other provider, enable [Custom LLM Enrichment](/custom_llm_enrichment) and emit `team`, `user`, or `feature` in your per-request `tags`. |
Allocate each shared cost once. If the same support fee or Marketplace charge is allocated through two different tags, reports will not reconcile cleanly against the bill.
## Step 5: Build the Report
With your tags in place, create a [Cost Report](/cost_reports) and group by your `team` or business-unit Virtual Tag.
Save that scope as a [Saved Filter](/saved_filters) so the same filter definition can be reused on reports and dashboards. Group per-team reports into [Folders](/folders) so each team has one place to look.
For recurring setup, use the [Vantage API](/api) to create and update Cost Reports, Saved Filters, Virtual Tags, Budgets, and Report Notifications from your team's source of truth.
For a one-off showback, you can also use report-level [Percent-Based Cost Allocation](/cost_reports#percent-based-cost-allocation). Click **Add Cost Allocation** on a filter set and set a showback percentage. This is report-scoped and does not create a reusable tag, so use a Percent-Based Virtual Tag for durable allocation logic.
## Step 6: Measure Allocation Coverage and Close the Gap
Track how much of the bill maps to a known owner. Build an unallocated report and watch it shrink:
Start from a report that shows total cost with no team filter.
Open the Group By menu and select **Tagged**, or filter Tagged Status to untagged, against your primary tag (for example, `team` or `cost-center`). This separates attributed spend from spend that has no owner.
Keep it alongside your team reports so it is easy to check each week.
Read coverage as one minus untagged over total. The largest untagged services tell you where to add the next Custom Value or allocation rule.
## Step 7: Set Team Budgets for Accountability
Once teams own their allocated costs, give each one a [Budget](/budgets) attached to its Cost Report. Start with one budget per team, set the [budget period](/budgets#budget-periods) to match your planning cadence, and review it each period.
## Step 8: Distribute to Stakeholders
Put the numbers in front of the people who own the spend.
* **[Report Notifications](/report_notifications)** send Cost Reports to email, Slack, or Microsoft Teams on a daily, weekly, or monthly cadence, where those channels are configured and available. By default, monthly notifications go out on the second of the month, weekly notifications go out on Mondays, and cost data is delayed two days. Note that notifications do not attach a CSV.
* **[Dashboards](/dashboards)** give each team or executive a single view. Combine them with saved filters for per-team versions.
* **Exports** handle the finance handoff. Export a report as CSV, PDF, or in the FOCUS schema from the [export flow](/cost_reports#export-cost-reports).
* **Recurring data pulls** into another system should use the [Vantage API](/api) rather than the console, since notifications do not carry raw CSV data.
## Step 9: Handle Reorganizations and Ownership Changes
Teams merge, split, and rename. Virtual Tag [time frames](/tagging#virtual-tag-time-frames) let a tag value apply only during a defined date range.
Say a shared cluster belonged to `infrastructure` through June 30, then moved to `platform` on July 1:
* Value `infrastructure`: set the Output Costs Filter for the cluster, enable Set a Time Frame, leave the Start Date empty, and set the End Date to June 30.
* Value `platform`: use the same Output Costs Filter, enable a time frame, and set the Start Date to July 1.
Time frames work at daily granularity by default, and the first matching rule wins. Costs are attributed according to the time frame for their incurred date, so historical periods keep the owner defined for that date range. The worked version is in the [time-bound example](/tagging_examples#time-bound-virtual-tag-example).
## Confirm Your Model Works
Your showback or chargeback model is well established when all of the following are true:
* Allocation coverage is at or above your target.
* Every shared cost has one allocation method.
* Each team has a Cost Report, a saved filter, and a budget.
* Reports are scheduled to the people who own the spend.
* Ownership changes are handled with time frames.
# FinOps AI Prompt Guide
Source: https://docs.vantage.sh/guides/finops_ai_prompt_guide
Learn what the Vantage FinOps Agent can do and how to ask for it in plain language.
The [FinOps Agent](/vantage_finops_agent) is the same agent whether you use it in the [Vantage console](https://console.vantage.sh/agent) or in Slack. This guide shows what the agent can do and how to phrase your prompts so you get useful answers the first time.
Every prompt example on this page is copy-pasteable. Click the **Copy** button on any prompt card and paste it into the agent in the console or in Slack. In Slack, prepend `@Vantage` to the prompt so the agent is notified.
To turn a prompt into a saved, refreshable table report, use [Canvas](/canvas). It applies the same Intent, Scope, and Direction principles covered here, with a [Prompt Library](/canvas#prompt-library) focused on building structured tables.
## What the Agent Can Do
The FinOps Agent is a purpose-built FinOps assistant. Its read and write actions are powered by tools from the [Vantage MCP](/vantage_mcp) (cost data and resource management) and the [Vantage Docs MCP](/docs_mcp) (product knowledge); however, the agent takes this one step further and brings FinOps reasoning, multi-step planning, and awareness of your workspace, RBAC scope, and audit context. For a complete reference of the underlying tools, see the [Vantage MCP Tools table](/vantage_mcp#vantage-mcp-tools).
The sections below organize the agent's capabilities into ten categories. Each accordion explains, in plain language, what you can ask for and provides ready-to-copy prompts.
Ask the agent to summarize, break down, or compare cloud spend across providers, services, accounts, regions, and tags. Useful for ad-hoc cost questions, executive summaries, and identifying drivers of change.
Underlying MCP tools: `query-costs`, `list-costs`, `list-cost-providers`, `list-cost-services`, `get-cost-provider-accounts`, `list-cost-integrations`.
What did we spend on AWS Lambda last month in the Production workspace?
Provide a breakdown of costs by service for Datadog from July 1 to July 31, 2025.
Compare AWS spend in October 2025 vs. September 2025. What were the top three drivers of the change, and which accounts and regions contributed?
Which cost providers and integrations are connected to my Vantage account?
Ask the agent to create, retrieve, list, delete, or forecast [Cost Reports](/cost_reports). The agent generates the [VQL](/vql) filter for you based on a plain-language description and can place reports in a specific [Folder](/folders). You can reference an existing report by pasting its console URL (for example, `https://console.vantage.sh/reports/rprt_xyz789abc123def4`) or by its token (for example, `rprt_xyz789abc123def4`).
Underlying MCP tools: `create-cost-report`, `get-cost-report`, `list-cost-reports`, `delete-cost-report`, `get-cost-report-forecast`, `list-unit-costs`.
Create a Cost Report titled "AWS RDS - October 2025" filtered to AWS RDS for October 2025 and place it in the Infra folder.
List my Cost Reports in the Engineering folder, then show me the filter and groupings on the largest one.
Forecast spend for this Cost Report ([https://console.vantage.sh/reports/rprt\_xyz789abc123def4](https://console.vantage.sh/reports/rprt_xyz789abc123def4)) for the next 90 days and explain what's driving the forecast.
Show me the daily unit costs for this Cost Report (rprt\_xyz789abc123def4) over the last 30 days.
Use the agent to organize Cost Reports into [Folders](/folders) and to assemble [Dashboards](/dashboards) from existing reports, widgets, and saved filters.
Underlying MCP tools: `create-folder`, `update-folder`, `delete-folder`, `list-folders`, `get-folder`, `create-dashboard`, `get-dashboard`, `update-dashboard`, `delete-dashboard`, `list-dashboards`.
Create a folder called "Data Platform Costs" and move these two reports into it: [https://console.vantage.sh/reports/rprt\_xyz789abc123def4](https://console.vantage.sh/reports/rprt_xyz789abc123def4) and [https://console.vantage.sh/reports/rprt\_abc456def789ghi0](https://console.vantage.sh/reports/rprt_abc456def789ghi0)
Create a Dashboard called "Engineering Cost Overview" set to a trailing 30-day window. Can you add these linked reports to it: [https://console.vantage.sh/reports/rprt\_xyz789abc123def4](https://console.vantage.sh/reports/rprt_xyz789abc123def4) and [https://console.vantage.sh/reports/rprt\_abc456def789ghi0](https://console.vantage.sh/reports/rprt_abc456def789ghi0)
Show me my existing Dashboards and Folders. Which Dashboards are most relevant to AWS spend?
Ask the agent to find, explain, and triage [Cost Anomaly Alerts](/cost_anomaly_alerts). It pulls the daily cost data around the spike, identifies attributed resources, and explains what likely changed.
Underlying MCP tools: `list-anomalies`, `get-anomaly`, `update-anomaly`.
Investigate the anomalies on my AWS Costs report from the past 14 days. What's driving each one, and are any of them correlated?
Explain the anomaly on my "AWS Production Costs" report from yesterday. Which service spiked, what's the magnitude, and which resources are attributed?
Ask the agent to surface, explain, and drill into [cost recommendations](/cost_recommendations) such as Savings Plans, Reserved Instances, and rightsizing opportunities.
Underlying MCP tools: `list-recommendations`, `get-recommendation-details`, `get-recommendation-resources`, `get-recommendation-resource-details`.
The agent can surface, explain, and analyze recommendations in both the console and Slack. If your organization has connected the [GitHub MCP](/github_mcp), it can also open a GitHub issue with the exact Terraform changes for a rightsizing recommendation. It cannot itself purchase Savings Plans or Reserved Instances or execute rightsizing changes; those remediations and approvals are handled through the Slack workflow.
List all open AWS cost recommendations, ranked by estimated monthly savings. Which three should I prioritize this week?
Show me the resources affected by rightsizing recommendations, with their current and recommended instance types.
Ask the agent to create and update [Budgets](/budgets), and to create and review [Cost Alerts](/cost_alerts). The agent can compare actual spend against budget targets and set up threshold-based notifications. Budgets can run on a [budget period](/budgets#budget-periods) from weekly up to multi-year, not just monthly.
Underlying MCP tools: `create-budget`, `update-budget`, `delete-budget`, `get-budget`, `list-budgets`, `create-cost-alert`, `get-cost-alert`, `list-cost-alerts`.
Create a monthly Budget of \$50,000 for my Production AWS Costs report (rprt\_xyz789abc123def4) for the rest of the calendar year.
List all Budgets in the Finance workspace and compare actual spend against budget targets. Which are off-track?
Create a weekly Cost Alert that notifies the #finops Slack channel if AWS RDS spend exceeds \$10,000 in any 7-day window.
Ask the agent to explore [tags](/tagging) and tag values across providers and to create [Virtual Tag](/tagging#virtual-tags) configurations that normalize and combine cost attribution across providers.
Underlying MCP tools: `list-tags`, `list-tag-values`, `create-virtual-tag-config`.
What tag keys are available for filtering my AWS costs, and what are the most common values for the `team` tag?
Create a Virtual Tag called `team` that combines the AWS `team` tag and the Kubernetes `organization/team` label. Backfill it to January 2026 and let it override provider-supplied tags.
Show last month's cost grouped by `tag:team` in the Engineering workspace. Which team spent the most?
Ask the agent about specific cloud resources, what workspaces and teams you have access to, and what's been happening in your account.
Underlying MCP tools: `list-provider-resources`, `get-provider-resource`, `list-audit-logs`, `get-myself`, `get-users`, `get-team`, `get-teams`.
Which workspaces do I have access to, and what's my access level in each?
List my AWS EC2 instances in us-east-1 that cost more than \$100 per month, sorted by cost.
Show me details and the cost breakdown for this resource: arn:aws:ec2:us-east-1:123456789012:instance/i-0abcd1234ef567890.
Show me audit log entries from the past 7 days for changes to Cost Reports and Budgets in my workspace.
If your organization has connected the [Datadog MCP](/datadog_mcp), the agent can pull live Datadog telemetry—metrics, logs, monitors, dashboards, APM, and events—and reason over it alongside your Vantage cost data. This is useful for tying cost changes to infrastructure activity, validating rightsizing recommendations against real utilization, and verifying whether a resource is actually idle before acting on it.
The Datadog MCP must be connected from the [Integrations page](https://console.vantage.sh/settings/integrations) by an **Organization Owner** or **Integration Owner**. See the [Datadog MCP](/datadog_mcp) documentation for setup and more examples.
Did any recent deployments cause my AWS costs to increase?
Which EC2 instances have the highest cost but lowest utilization?
Our AWS data transfer costs jumped this week. Which services or hosts in Datadog show increased network throughput over the same period?
If your organization has connected the [GitHub MCP](/github_mcp), the agent can read the issues, pull requests, code, and Actions/workflow runs in the repositories you can access, and create or update issues on your behalf. It does not commit code or open pull requests through the MCP. If a connected repository contains Terraform, the agent can also create GitHub issues for rightsizing recommendations, pre-filled with the resource location, current and recommended values, and estimated savings. The agent acts with your own GitHub permissions and asks you to confirm the matched resource before creating an issue.
An **Organization Owner** or **Integration Owner** enables the GitHub MCP from the [Integrations page](https://console.vantage.sh/settings/integrations); then each user connects their own GitHub account. Connecting specific repositories (through the Vantage GitHub App) is required for the recommendation-to-issue workflow and sets the agent's default repository focus. See the [GitHub MCP](/github_mcp) documentation for setup.
Is there an open issue or pull request related to our EKS cluster that might explain this week's cost spike?
Over the last 3 months, compare our Cursor spend to the number of pull requests merged in our main app repo, and show a per-PR cost.
Create a GitHub issue for this rightsizing recommendation with the Terraform file, resource, current and recommended instance type, and estimated monthly savings.
Which repository defines the instance type for this resource, and what is the current value in Terraform?
If your organization has connected the [Linear MCP](/linear_mcp), the agent can search your issues, projects, and teams and create or update issues on your behalf. This is useful for checking whether optimization work is already tracked, routing a task to the right team, and correlating an initiative's progress with cost trends. Each user connects their own Linear account, and the agent acts with that user's permissions.
An **Organization Owner** or **Integration Owner** enables the Linear MCP from the [Integrations page](https://console.vantage.sh/settings/integrations); then each user connects their own Linear account. See the [Linear MCP](/linear_mcp) documentation for setup.
We have an anomaly on our EKS costs this week. Is there already a Linear issue tracking work on that cluster?
Create a Linear issue for this rightsizing recommendation and include the current instance type, recommended type, and estimated monthly savings.
Which Linear team owns our data platform services? Create an issue there to investigate the Redshift cost increase.
If your organization has connected the [Notion MCP](/notion_mcp), the agent can pull in the pages you have access to—architecture docs, runbooks, and team ownership pages—and draft new pages summarizing a cost investigation. Each user connects their own Notion account, and the agent only sees content that user can access.
An **Organization Owner** or **Integration Owner** enables the Notion MCP from the [Integrations page](https://console.vantage.sh/settings/integrations); then each user connects their own Notion account. See the [Notion MCP](/notion_mcp) documentation for setup.
Our data pipeline costs jumped this month. Pull the architecture doc for the pipeline from Notion and help me figure out which component is driving the increase.
Check our team ownership page in Notion and tell me which team owns the service behind this anomaly.
Draft a Notion page summarizing this month's cost anomaly investigation, including the affected services, root cause, and the optimization actions we agreed on.
Have something to share with the Vantage team? Tell the agent and it will route your feedback directly to us via the `submit-user-feedback` tool.
I have feedback to share: \[describe what worked well, what didn't, or what you'd like to see].
## Prompting Building Blocks
The sections above show what to ask for. The next three sections—**Intent**, **Scope**, and **Direction**—help you phrase prompts so the agent gets you the right answer the first time.
What you want the agent to do—ask a question or take an action.
What data the agent should look at—workspace, provider, time range, groupings.
How you want the answer presented—summary, table, checklist, and so on.
## 1. Intent
Every productive interaction with the FinOps Agent starts with a clear action or question. The agent supports two intent categories: ask the agent questions or ask the agent to perform actions.
### Ask the Agent Questions
You can ask questions about your cloud costs or about Vantage features and functionality.
What drove our AWS EC2 costs last month?
Which Azure services are trending up this week?
Show me any compute-related anomalies for the past week.
Can you explain the difference between Virtual Tags and Saved Filters? When should I use one over the other?
```md Example interaction: cloud costs expandable theme={null}
You:
@Vantage What drove our AWS EC2 costs last month?
The Agent:
EC2 Cost Drivers — Last Month
Scope used: Production Workspace (token wrkspc_a1b2c3d4e5f6g7h8)
Period: 2024-10-01 to 2024-10-31
Filter: AWS provider, service Amazon Elastic Compute Cloud - Compute
Total EC2 Compute Spend: $127,450.23
Key Takeaways
• One AWS account (123456789012) in us-west-2 drove ~94.2% of EC2 compute costs.
• All EC2 compute spend was in us-west-2.
• Other accounts contributed minimal EC2 compute spend.
Breakdown by Account and Region
| AWS Account ID | Region | EC2 Compute Cost (USD) | Share of EC2 | Notes |
|----------------|-----------|------------------------|--------------|----------------------|
| 123456789012 | us-west-2 | $120,058.12 | 94.2% | Primary cost driver |
| 987654321098 | us-west-2 | $6,892.45 | 5.4% | Secondary contributor|
| 555666777888 | us-west-2 | $412.18 | 0.32% | Minor |
| 111222333444 | us-west-2 | $87.48 | 0.07% | Minor |
| 999888777666 | us-west-2 | $0.00 | ~0% | Negligible |
What this means
• The vast majority of EC2 compute cost is concentrated in a single account and single region.
• To refine "what drove cost" further (e.g., by usage type/purchase option, or top instances), we can:
• Group by charge_type to separate On-Demand vs. Savings Plans/RIs and other line items.
• Group by resource_id to identify the top-cost EC2 instances.
• Add tag-based groupings (for example, tag:environment) if you use tags for ownership or workload mapping.
Want deeper detail?
• Do you want me to:
• Break down by purchase option/charge type (On-Demand vs. SP/RI vs. Credits)?
• List the top-cost EC2 instances in that account?
• Run the analysis for a different workspace instead of Production?
• Create a Cost Report you can open in Vantage with this exact filter and date range?
Reply with your preferred next step and, if needed, the workspace name you want analyzed.
```
```md Example interaction: Vantage features expandable theme={null}
You:
@Vantage can you explain the difference between virtual tags and saved filters? when should I use one over the other?
The Agent:
Virtual Tags vs. Saved Filters in Vantage
Short answer: Virtual Tags are standardized, cross-provider dimensions you define in Vantage to improve and normalize tagging. Saved Filters are reusable, named filter sets you apply on top of that data for ad-hoc views in reports and dashboards.
Key Differences:
- Purpose: Virtual Tags normalize and increase tagging coverage without infra changes. Saved Filters bundle filter logic so teams can reuse it without rebuilding it.
- Scope: Virtual Tags apply to all cost data across every workspace and can be used in filters and groupings. Saved Filters apply only to the reports where they are selected.
- Stability: Virtual Tags are foundational and should change rarely, since each change reprocesses your cost data. Saved Filters are lightweight and can change freely.
When To Use Which:
- Use Virtual Tags when you need a dimension you can group by, such as team, cost center, or environment, standardized across AWS, Azure, GCP, and other providers. Use nested Virtual Tags to roll those dimensions up into a hierarchy.
- Use Saved Filters when you need a reusable lens, such as "North America regions" or "production accounts," that you want to apply to many reports without duplicating filter logic.
Recommended Approach:
1. Define Virtual Tags first to create clean, consistent dimensions
2. Use nested Virtual Tags for your allocation hierarchy, and group Cost Reports by those tags
3. Use Saved Filters for ad-hoc lenses on top of that tagged data
```
### Ask the Agent to Perform Actions
You can also ask the agent to create or update Vantage resources, generate Terraform code, or assemble artifacts on your behalf.
Create a Cost Report filtered to AWS Lambda for the last 30 days and put it in the Infra folder.
I have a list of teams in a CSV file (e.g., integrations, security, etc.). I have an AWS tag called `team` with the same value, and a Kubernetes label `organization/team` with the same team name. I want to combine all these costs into one Virtual Tag. Write me a Terraform script to do this.
```md Example interaction: create a report expandable theme={null}
You:
@Vantage can you create a report for me in the Infra folder (fldr_abc123def4567890) that shows me AWS EC2 box usage for October 2025?
The Agent:
Cost Report Created: AWS EC2 Usage (October 2025)
Your report is ready in the Infra folder and focuses on AWS EC2 instance (compute) usage for October 2025.
• Direct link: https://console.vantage.sh/go/rprt_xyz789abc123def4
Report Summary:
- **Title**: AWS EC2 Usage - October 2025
- **Folder**: Infra (fldr_abc123def4567890)
- **Filter**: (costs.provider = 'aws' AND costs.service = 'Amazon Elastic Compute Cloud - Compute')
- **Date Range**: 2025-10-01 to 2025-10-31
- **Aggregate By**: usage
- **Workspace**: Production (wrkspc_def456ghi789jkl0)
Notes:
• This targets the EC2 compute service: Amazon Elastic Compute Cloud - Compute, which matches "EC2 box usage."
• It excludes EC2-related "other" costs (like EBS, NAT, data transfer). If you want those included, I can broaden the filter.
Want any tweaks?
• Groupings: Add by account_id, region, or instance type (if tagged).
• Compare periods: Keep or remove previous-period comparison.
• Scope: Restrict to specific AWS accounts or regions.
```
````md Example interaction: create a Terraform script expandable theme={null}
You:
@Vantage I have a list of teams in a CSV file (e.g., integrations, security, etc.). I have an AWS tag called team with value of the same name and a Kubernetes label of organization/team with a value of the same team name. I want to combine all these costs to one virtual tag. Write me a Terraform script to do this.
The Agent:
Virtual Tag: Combine AWS tag "team" and Kubernetes label "organization/team"
Goal: Create a single, cross-provider Virtual Tag in Vantage (key: team) whose values are sourced from:
• AWS tag: team
• Kubernetes label: organization/team
This lets you group and filter total costs by team across both providers.
How it works
• Creates a Virtual Tag with key team.
• Reads your CSV of team names and generates one Custom Value per team.
• Each value uses a VQL filter that matches:
• AWS costs where ``tags.name = 'team'`` and ``tags.value = ''``
• Kubernetes costs where ``tags.name = 'organization/team'`` and ``tags.value = ''``
Prerequisites
• Vantage Terraform provider installed and configured with a Vantage API token.
• A CSV file (e.g., ``teams.csv``) with a header ``team`` and one team name per row.
• Vantage roles/permissions to manage Virtual Tags.
References:
• https://docs.vantage.sh/terraform_docs/resources/virtual_tag_config
• https://docs.vantage.sh/tagging
• https://docs.vantage.sh/vql
Terraform: Provider and Variables
```hcl
terraform {
required_providers {
vantage = {
source = "vantage-sh/vantage"
version = ">= 0.1.24"
}
}
}
provider "vantage" {
# Or set via environment variable: export VANTAGE_API_TOKEN=...
api_token = var.vantage_api_token
}
variable "vantage_api_token" {
type = string
description = "Vantage API token"
sensitive = true
}
variable "teams_csv_file" {
type = string
description = "Path to CSV with column 'team'"
default = "teams.csv"
}
variable "virtual_tag_key" {
type = string
description = "The Virtual Tag key to create"
default = "team"
}
variable "overridable" {
type = bool
description = "Whether this Virtual Tag should override provider-supplied tags"
default = true
}
# Format: YYYY-MM (month you want to backfill to). Optional but recommended.
variable "backfill_until" {
type = string
description = "Earliest billing month to backfill (e.g., 2024-01)"
default = "2024-01"
}
```
Terraform: Build Values From the CSV and Create the Virtual Tag
```hcl
locals {
# Expect a header 'team' in the CSV
raw_teams = csvdecode(file(var.teams_csv_file))
# Normalize team values (optional: trim and lower for consistency)
team_names = tolist(toset([
for r in local.raw_teams : lower(trimspace(r.team))
if try(length(trimspace(r.team)) > 0, false)
]))
# Build one Virtual Tag value per team with a cross-provider VQL filter
# Matches AWS tag 'team' == OR Kubernetes label 'organization/team' ==
virtual_tag_values = [
for t in local.team_names : {
name = t
filter = "( (costs.provider = 'aws' AND tags.name = 'team' AND tags.value = '${t}') OR (costs.provider = 'kubernetes' AND tags.name = 'organization/team' AND tags.value = '${t}') )"
}
]
}
# Create the Virtual Tag (key = 'team') with CSV-driven values
resource "vantage_virtual_tag_config" "team" {
key = var.virtual_tag_key
overridable = var.overridable
backfill_until = var.backfill_until
# The Vantage provider expects a list of objects for values.
# Each object represents a "Custom Value" with "name" and "filter".
values = local.virtual_tag_values
}
```
Notes:
• The Vantage Terraform provider models nested blocks as list-of-objects (e.g., ``values = [ { name, filter } ]``).
• This configuration uses Custom Value Virtual Tag values. You can extend it later for Cost-Based or Business Metric types if needed.
Example teams.csv
```csv
team
integrations
security
platform
data
```
Usage
1. Save the Terraform and CSV files.
2. Set your Vantage API token:
```bash
export VANTAGE_API_TOKEN="your-token"
```
3. Initialize and apply:
```bash
terraform init
terraform plan
terraform apply
```
4. After processing (usually under an hour), use the new team Virtual Tag on Cost Reports for filtering/grouping.
Tips and caveats
• Avoid double counting in reports: If you're aggregating both AWS and Kubernetes in the same Cost Report, follow guidance to ensure you aren't double counting Kubernetes node costs and Kubernetes agent costs in the same view.
````
***
## 2. Scope
The FinOps Agent needs to know which data to use. Vantage customers often have multiple workspaces, multiple cloud providers, and different access levels. Providing scope upfront can help to eliminate back-and-forth questions.
### Specify a Workspace
If you don't specify a workspace, the agent falls back to the workspace you're currently working in. Understanding this process helps you know what data you're viewing.
Workspaces in Vantage separate your provider integrations into distinct cost views. Different integrations can be associated with different workspaces, so the workspace you query determines which cost data is available. Learn more about [workspaces](/workspaces).
The Agent chooses a workspace in this order:
1. **If you specify one.** If you mention a workspace name or token in your prompt, that workspace is used.
2. **Your current workspace.** Otherwise, the agent uses your active workspace—the one you most recently selected in the Vantage console. There's no separate default setting; to change which workspace the agent falls back to, switch workspaces in the console using the workspace switcher, and the agent will use that one next.
3. **Otherwise, it asks.** If it can't confidently determine which workspace you mean, the agent asks you rather than guessing.
Show me spend for the last 30 days.
```md Example agent response theme={null}
Last 30 Days Spend
• Workspace: Infra
• Date range: 2025-10-14 to 2025-11-13
• Total spend: $253,264.53 USD
Breakdown by Provider
• AWS: $215,235.88
• GCP: $1,497.95
• Kubernetes: $36,530.70
Note: Monthly rows are prorated to the exact date range.
Would you like this broken down by service or account, or run for a different workspace?
```
The agent used the default workspace (Infra). For more specific analysis, scope the prompt explicitly:
Show me AWS EC2 costs for the last 30 days in the Production workspace.
### Specify a Folder
When you create Vantage resources, like reports, you can specify which folder to place them in by providing the [folder](/folders) URL or token (found at the end of the URL).
Create a report in [https://console.vantage.sh/reporting/fldr\_abc123def4567890](https://console.vantage.sh/reporting/fldr_abc123def4567890) showing AWS RDS costs for August 2025.
```md Agent response: created report expandable theme={null}
Cost Report Created: AWS RDS (August 2025)
Your report is ready. You can open it here:
• Report link: https://console.vantage.sh/go/rprt_xyz789abc123def4
• Folder: https://console.vantage.sh/reporting/fldr_abc123def4567890
Report Details
• Title: AWS RDS Costs - August 2025
• Scope: ``costs.provider = 'aws'`` and ``costs.service = 'Amazon Relational Database Service'``
• Date range: 2025-08-01 to 2025-08-31
• Chart type: Line
• Aggregation: Cost over Date
• Settings:
• Discounts: Included
• Tax: Included
• Amortized: Yes
• Credits/Refunds: Excluded
• Previous period comparison: Enabled
Next Steps (Optional)
• Add groupings for more detail (e.g., ``region``, ``account_id``).
• Attach budgets or forecasts to track RDS spend trends beyond August.
• Create a dashboard widget if you want this visible on a central dashboard.
If you’d like, I can:
• Add groupings to this report,
• Create a matching budget,
• Or generate a forecast for upcoming months.
```
### Specify Time Windows
Always include time ranges to avoid ambiguity about which period you're analyzing.
Provide a breakdown of costs by service for Datadog from July 1 to July 31, 2025.
```md Agent response: scoped to time window expandable theme={null}
Datadog Cost Breakdown — Management Workspace (2025-07-01 to 2025-07-31)
Workspace: Management
Provider: Datadog
Period: 2025-07-01 to 2025-07-31
Summary
• Total Datadog spend: $52,847.30
• Costs are aggregated monthly and reflect this workspace's default report settings (here: discounts and tax included, amortization enabled, credits/refunds excluded).
Costs by Service
| Service | Cost (USD) | Share of Total |
|---------|------------|----------------|
| APM | $21,852.18 | 41.35% |
| Infrastructure Monitoring | $15,980.42 | 30.24% |
| Containers | $5,696.94 | 10.78% |
| Log Management | $4,835.53 | 9.15% |
| CI Visibility | $2,737.49 | 5.18% |
| Database Monitoring | $835.00 | 1.58% |
| Real User Monitoring | $581.32 | 1.10% |
| Synthetic Monitoring | $174.40 | 0.33% |
| Serverless Monitoring | $154.02 | 0.28% |
Notes
• Monthly aggregation: Each record represents July 2025; the ``accrued_at`` date refers to the first day of the month.
• Settings applied (from this workspace's default report settings): include_discounts = true, include_tax = true, amortize = true, include_credits = false, include_refunds = false.
If you want these toggled (e.g., exclude tax or include credits), let me know and I'll rerun the breakdown.
```
### Reference Existing Reports
You can reference existing reports by their token or link, and the agent will analyze them.
In this report rprt\_xyz987abc456def789, what was my biggest change in cost from September 2025 to October 2025, and what resources contributed to this?
```md Agent response: breakdown expandable theme={null}
Biggest Month-over-Month Change (Sep 2025 → Oct 2025)
• Largest change: AWS AmazonS3 costs decreased by $87,542.31 (from $245,892.67 in Sep to $158,350.36 in Oct).
• Report link: https://console.vantage.sh/go/rprt_xyz987abc456def789
What resources contributed to this change?
The decrease was concentrated in a single AWS account. Bucket-level resource IDs are not present in this report's data, but the account-level breakdown clearly shows where the change occurred.
AWS AmazonS3 by account:
| AWS Account ID | Sep 2025 | Oct 2025 | Change |
|----------------|----------|----------|--------|
| 987654321098 | $238,450.12 | $152,180.45 | **-$86,269.67** |
| 555444333222 | $5,892.34 | $4,567.89 | -$1,324.45 |
| 111222333444 | $1,550.21 | $1,602.02 | +$51.81 |
• Conclusion: ~98.5% of the S3 decrease was driven by account 987654321098.
Other notable month-over-month movements (context):
• Increases:
- AWS AmazonEC2: +$42,156.78
- AWS RDS: +$28,934.12
- Azure Load Balancer: +$15,678.45
• Decreases:
- Snowflake Data Cloud: -$18,234.56
- Datadog APM: -$12,567.89
Want bucket-level detail? I can try to pull the top S3 buckets by month-over-month change, but the current report data doesn't expose bucket-level resource IDs. If you'd like, I can run a workspace-level query to identify the specific buckets contributing to this change.
```
***
## 3. Direction
Direction helps the agent shape the final output. Use one of the following output formats to control how results are presented.
3–6 bullet highlights with key numbers. Best for stakeholder updates and quick insights.
```md How to request theme={null}
[your question with intent and scope] Give a summary of findings.
```
```md Example response snippet theme={null}
Spend increased 12% MoM; top driver is EC2 in us-east-1 (+$18k).
```
Concise points or steps. Best for action items and next steps.
```md How to request theme={null}
[your question with intent and scope] List the top 5 drivers.
```
```md Example response snippet theme={null}
- EC2 +$18k
- S3 +$6k
...
```
Tabular view with columns. Best for grouped spend/usage data.
```md How to request theme={null}
[your question with intent and scope] Show a table grouped by service and region.
```
```md Example response snippet theme={null}
| Service | Region | Cost (USD) |
|---------|--------|------------|
| EC2 | us-east-1 | $125,450.23 |
| EC2 | us-west-2 | $89,234.56 |
| S3 | us-east-1 | $67,891.12 |
| S3 | us-west-2 | $45,678.90 |
| RDS | us-east-1 | $34,567.89 |
```
Comma-separated rows. Best for spreadsheet import.
```md How to request theme={null}
[your question with intent and scope] Provide CSV for the top 10 services.
```
```md Example response snippet theme={null}
Service,TotalCostUSD
ClickHouse Cloud,18432.55
AmazonEC2,5219.63
AmazonS3,3077.81
AmazonRDS,1693.00
ComputeSavingsPlans,1345.40
AmazonECS,832.11
Amazon Elastic Block Storage (EBS),598.02
Tackle Cloud GTM Platform,414.25
AmazonCloudWatch,328.90
AmazonElastiCache,211.87
```
Side-by-side or delta view. Best for before/after and period-over-period analysis.
```md How to request theme={null}
[your question with intent and scope] Compare last month vs this month and highlight the deltas.
```
```md Example response snippet theme={null}
+12% total, EC2 +22%
```
Markdown checkboxes. Best for runbooks and to-dos.
```md How to request theme={null}
[your question with intent and scope] Output a checklist of fixes.
```
```md Example response snippet theme={null}
- [ ] Tag coverage to 95%
- [ ] Review root user access and remove if unused
- [ ] Enable cost anomaly alerts for all AWS accounts
- [ ] Archive old unused reports to reduce clutter
```
Highlights with brief rationale. Best for root cause storytelling.
```md How to request theme={null}
[your question with intent and scope] Call out anomalies and likely causes.
```
```md Example response snippet theme={null}
EC2 spike tied to ASG scale-out on 11/12.
```
VQL or CLI commands. Best for reproducibility.
```md How to request theme={null}
[your question with intent and scope] Show the VQL you used.
```
```md Example response snippet theme={null}
(costs.provider = 'aws')
```
***
## Putting It All Together
A great prompt usually combines all three building blocks in a single sentence: what you want, what data to use, and how to format the answer. You don't need a special syntax; plain English works.
A good prompt covers, in order:
1. **Intent** — what you want the agent to do (a question or an action).
2. **Scope** — the workspace, providers, services, accounts, regions, tags, time range, and groupings to apply.
3. **Direction** — how you want the answer formatted (summary, table, checklist, code block) and any notes or callouts.
Here's a fully-formed prompt that uses all three:
In the Production workspace, show AWS EC2 and S3 spend for the last 30 days, grouped by service and account ID. Present the result as a table and identify the top 5 cost drivers.
How that maps to the building blocks:
* **Intent:** "Show AWS EC2 and S3 spend" (a question).
* **Scope:** "In the Production workspace", "AWS EC2 and S3", "for the last 30 days", "grouped by service and account ID".
* **Direction:** "as a table", "identify the top 5 cost drivers".
## Ready-to-Use Prompts
Copy and customize these prompts for common FinOps tasks. Each one follows the Intent, Scope, and Direction framework. Replace the values in brackets (such as `[workspace]` or `[time period]`) with your own.
Identify what caused unexpected cost increases.
What caused the cost spike in the \[workspace] workspace \[time period]?
Track spending patterns and identify trends over time.
Show the \[time period] trend for \[service] spend in \[workspace].
Compare actual spending against Budgets and forecasts.
List all Budgets in the \[workspace] workspace and compare against actuals.
Find unusual spending patterns that may indicate issues.
Find anomalies for the last \[days] days in the \[workspace] workspace.
When you receive a Cost Anomaly Alert in Slack, click the **Investigate Anomaly** button to start an automated investigation. You can also ask the agent directly—in either Slack or the console. The agent investigates each anomaly, queries daily costs around the spike, identifies attributed resources, and presents correlations across anomalies.
Investigate the anomalies on my \[report name] report.
```md Example response expandable theme={null}
AWS Cost Anomaly Investigation
Report: AWS Costs (filter: all AWS costs)
Detected: January 16, 2026 | 3 anomalies with a combined increase of ~$156.42
1. Amazon S3 — API Requests (+$72.18) — Largest Spike
| Field | Value |
|-----------------|-------------------------------------------|
| Category | API Request |
| Occurred | Jan 10, 2026 |
| Amount | $198.34 |
| Previous Day | $157.20 (+26.2%) |
| 7-Day Average | $126.16 (+57.2% above baseline) |
Resource: my-data-lake-bucket-441298320517 (S3 bucket, us-west-2, account 441298320517)
Daily API Request Trend:
| Date | S3 API Request Cost |
|--------|---------------------|
| Jan 7 | $124.30 |
| Jan 8 | $131.05 |
| Jan 9 | $157.20 |
| Jan 10 | $198.34 ⬆️ anomaly |
| Jan 11 | $210.77 |
| Jan 12 | $187.63 |
| Jan 13 | $156.41 |
Analysis: The spike on Jan 10 was notable, but costs continued to climb through
Jan 11 ($210.77). This S3 bucket is used for data lake storage. The sustained
increase in API requests suggests either new ETL jobs querying the bucket,
increased data delivery frequency, or a change in access patterns.
2. Amazon GuardDuty (+$51.83)
| Field | Value |
|-----------------|-------------------------------------------|
| Category | GuardDuty |
| Occurred | Jan 12, 2026 |
| Amount | $84.57 |
| Previous Day | $33.19 (+154.8%) |
| 7-Day Average | $32.74 (+158.3% above baseline) |
Daily Trend:
| Date | GuardDuty Cost |
|--------|----------------|
| Jan 7 | $31.42 |
| Jan 8 | $32.18 |
| Jan 9 | $33.70 |
| Jan 10 | $34.25 |
| Jan 11 | $33.19 |
| Jan 12 | $84.57 ⬆️ anomaly |
| Jan 13 | $7.82 (partial day)|
Analysis: GuardDuty costs more than doubled on Jan 12. This typically indicates
a surge in analyzed events — possibly increased VPC Flow Logs, DNS logs, or
CloudTrail events being scanned. This could correlate with the S3 API request
spike generating more CloudTrail events.
3. Amazon CloudWatch — API Requests (+$32.41)
| Field | Value |
|-----------------|-------------------------------------------|
| Category | API Request |
| Occurred | Jan 11, 2026 |
| Amount | $67.92 |
| Previous Day | $38.14 (+78.1%) |
| 7-Day Average | $35.51 (+91.3% above baseline) |
Daily API Request Trend:
| Date | CloudWatch API Cost |
|--------|---------------------|
| Jan 7 | $35.63 |
| Jan 8 | $34.29 |
| Jan 9 | $36.87 |
| Jan 10 | $38.14 |
| Jan 11 | $67.92 ⬆️ anomaly |
| Jan 12 | $52.40 |
| Jan 13 | $48.71 |
Analysis: CloudWatch API costs jumped 78% on Jan 11 and remain elevated
(~$48-52/day vs. the ~$35 baseline). This suggests a new monitoring configuration
or increased GetMetricData calls.
Key Correlations & Recommendations
S3 + GuardDuty + CloudWatch may be linked: The surge in S3 API requests
generates more CloudTrail events, which GuardDuty analyzes and CloudWatch
monitors. Investigate what is driving the increased S3 API activity on the
data lake bucket — this could be the root cause of multiple anomalies.
Action items:
• Investigate S3 API surge — this is the largest and still-growing cost.
Check CloudTrail for unusual access patterns on the data lake bucket.
• Review CloudWatch API usage — the elevated baseline suggests a permanent
config change. Audit recent monitoring changes.
Console links:
• Cost Report: https://console.vantage.sh/go/rprt_abc123def456
```
Group and filter costs using tags for allocation and showback.
Show cost grouped by tag:\[key] for \[time period] in \[workspace].
Deep-dive into existing reports to understand cost changes.
In this report \[report\_token or link], what was my biggest change in cost from \[period 1] to \[period 2], and what resources contributed to this?
## Understand Responses
Because the FinOps Agent relies on an LLM, responses are not always deterministic. The same prompt may return slightly different answers, and results depend heavily on the context you provide. Understanding how responses work helps you verify results and get the most out of the agent when answers look unexpected.
The FinOps Agent uses [Vantage Query Language (VQL)](/vql) to query your cost data. VQL is a SQL-like language for filtering cloud cost data across providers. When the agent answers a cost question, it generates VQL behind the scenes to fetch the data.
You can verify agent responses using the following methods:
* **Compare against Cost Reports**. Use your existing Cost Reports as a source of truth. For example, if you ask about EC2 spend last month, compare the answer against your saved report for that timeframe.
* **Request the VQL query**. Ask the agent to show you the VQL it used. Add "Show the VQL you used" to your prompt or ask in a follow-up message. Review the VQL to understand what data the agent accessed and confirm the filters and groupings align with your intent.
* **Cross-reference between surfaces**. If you receive an unexpected answer in Slack, try the same prompt in the console (or vice versa). Conversations are independent, so you can use one as a sanity check for the other.
## Limitations
Understanding the agent's limitations helps you set appropriate expectations and get the most out of your interactions.
The agent doesn't browse the internet unless a tool explicitly provides that information. It can't fetch live pricing from websites unless you provide it or a tool returns it.
The agent can only access what the [Vantage MCP](/vantage_mcp) and [Vantage Docs MCP](/docs_mcp) tools return, plus anything you share directly in the conversation. All access is scoped to your [RBAC](/rbac) permissions.
The agent can't run commands, deploy code, or change infrastructure outside Vantage. It can suggest provider commands, but you must run them yourself. In the console it can propose changes—for example, opening a GitHub issue with the Terraform edits for a rightsizing recommendation—but it does not execute cost remediations itself; those run through the Slack approval workflow.
The console agent can describe and explain cost recommendations, and—if GitHub is connected—open a GitHub issue with the Terraform changes for a rightsizing recommendation. It cannot itself purchase Savings Plans or Reserved Instances or execute rightsizing changes; those remediations and approvals run through the Slack workflow today.
The agent may misinterpret ambiguous requests. Be specific—provide workspace, time range, and the exact resource or service whenever possible.
The agent only sees the current chat context. It doesn't carry context between Slack and the console, and it doesn't remember previous Slack threads or console conversations unless they're part of the current thread.
The agent currently accepts text-based files, including CSVs. Image analysis and other file formats are not supported today; additional formats are planned.
The agent doesn't access personal data unless you provide it explicitly. It can't read your emails, tickets, or external dashboards without you pasting content or granting access via tools.
# FinOps as Code
Source: https://docs.vantage.sh/guides/finops_as_code
Use AI and Terraform together to manage Vantage configuration at enterprise scale.
The console is the right place to start, but once you have dozens of teams, hundreds of reports, and allocation logic driving chargeback, changes need review, history, and repeatability. FinOps as Code manages your Vantage configuration the same way you manage infrastructure: in version control, through pull requests, with a plan you review before anything changes. The [Vantage Terraform provider](https://registry.terraform.io/providers/vantage-sh/vantage/latest) and [API](/api) are the system of record. AI tools like the [FinOps Agent](/vantage_finops_agent), the [Vantage MCP](/vantage_mcp), or any coding assistant draft the configuration but never apply it on their own.
One rule to remember: **AI proposes, Terraform commits, with a human in the loop.**
This guide shows when FinOps as Code makes sense and several use cases you can adapt. For prompting the FinOps Agent directly, see the companion [FinOps AI Prompt Guide](/guides/finops_ai_prompt_guide).
## When to Use FinOps as Code
The console and code are complements, not competitors. The console is built for exploration and answering questions quickly. Code is built for configuration that has to stay correct over time. Most organizations build something in the console first, then promote it to code once it becomes part of a regular process. (This particular pattern is shown in [Use Case 5](#use-case-5-import-console-resources-into-terraform).)
Use code when a configuration is:
* **Shared:** Cost Reports, Folders, and Dashboards that multiple teams rely on for recurring reviews.
* **Durable:** Anything that should persist beyond the person who created it and remain intact through team changes.
* **Sensitive:** Allocation logic like [Virtual Tags](/tagging) and [Billing Rules](/sql_billing_rules) that reclassifies historical cost and feeds chargeback. These changes deserve a reviewed diff.
* **Repeated:** Work you do the same way every time, like onboarding a new team. Doing it once by hand is fine, but doing it for the fifteenth team is not.
* **Subject to review or audit:** When you need a record of who changed what, when, and why.
* **Created at scale:** Hundreds of teams, accounts, or tag values that are tedious and error-prone to click through.
Stay in the console when work is:
* **Exploratory:** Ad-hoc cost questions, one-off investigations, and "what is driving this?" analysis.
* **A one-off:** A report you need once and will not maintain.
* **A learning exercise:** Trying a feature to understand how it behaves before committing to a pattern.
If you find yourself rebuilding the same console configuration by hand more than twice, that is the signal to move it into code.
## Prerequisites
* A Vantage account with at least one connected provider.
* The [Vantage Terraform provider](https://registry.terraform.io/providers/vantage-sh/vantage/latest) configured with a Read/Write [API token](/api/authentication). If you do not use Terraform, you can manage the same resources through the corresponding [Vantage API](/api) endpoints.
* A Git repo with a Terraform workflow your team already uses for plan and apply.
## Use Cases
Each use case below follows the same shape: a source of truth your organization already maintains, such as a CSV of teams, a YAML org chart, or an export from your identity provider that drives the Vantage configuration. AI drafts the change, you review the plan, and code applies it. This keeps the business logic in one place and scales from five teams to five hundred without changing the workflow.
Create a folder, Cost Report, team, access grant, and budget for every team from one file.
Turn a CSV or YAML mapping into a cross-provider allocation tag.
Merge several source tags into one canonical chargeback dimension, in priority order.
Promote a recurring investigation into a committed, version-controlled report.
Bring resources you already built in the console under Terraform management.
Snapshot your allocation config to Git so you can review every change and roll back.
### Use Case 1: Onboard a New Team
Every time a new team starts up, you need the same handful of Vantage resources: a folder to organize their reports, a Cost Report filtered to their accounts, a team with an access grant so they can see their data, and a budget to track spend. Keep the team definitions in one file, and let Terraform create every resource from it.
```yaml teams.yaml theme={null}
teams:
platform:
workspace_token: wrkspc_abc123
aws_account_ids: ["123456789012"]
monthly_budget_usd: 75000
security:
workspace_token: wrkspc_abc123
aws_account_ids: ["234567890123", "345678901234"]
monthly_budget_usd: 40000
```
Ask your AI assistant to generate the configuration from that file:
Using our existing Vantage Terraform patterns, generate only the HCL to onboard the teams in teams.yaml.
For each team, create a folder, a Cost Report filtered to its AWS accounts, a team, an access grant to its folder, and a monthly budget.
Iterate over the file with for\_each. Do not create new modules or change existing resources. Return only the diff and your assumptions.
It returns one set of resources per team, driven by `for_each`:
```hcl onboarding.tf expandable theme={null}
locals {
teams = yamldecode(file("teams.yaml")).teams
}
resource "vantage_folder" "team" {
for_each = local.teams
title = "${each.key} Costs"
workspace_token = each.value.workspace_token
}
resource "vantage_cost_report" "team" {
for_each = local.teams
title = "${each.key} AWS Costs"
folder_token = vantage_folder.team[each.key].token
filter = "costs.provider = 'aws' AND costs.account_id IN (${join(", ", [for id in each.value.aws_account_ids : "'${id}'"])})"
groupings = "service,region"
}
resource "vantage_team" "team" {
for_each = local.teams
name = each.key
description = "Managed by Terraform"
workspace_tokens = [each.value.workspace_token]
}
resource "vantage_access_grant" "team" {
for_each = local.teams
team_token = vantage_team.team[each.key].token
resource_token = vantage_folder.team[each.key].token
access = "allowed"
}
resource "vantage_budget" "team" {
for_each = local.teams
name = "${each.key} Monthly Budget"
workspace_token = each.value.workspace_token
cost_report_token = vantage_cost_report.team[each.key].token
periods = [
{
start_at = "2026-01-01"
amount = each.value.monthly_budget_usd
}
]
}
```
Review the [VQL](/vql) filter before merging. Team onboarding PRs usually succeed or fail based on whether the filter matches the right accounts, tags, and workspace. Creating teams and access grants through Terraform requires Enterprise RBAC and appropriate permissions. For more on teams and access grants, see the [RBAC setup guide](/guides/rbac_setup).
To onboard a single new team later, add one entry to `teams.yaml` and re-run `terraform plan`. Because every resource is keyed by team name with `for_each`, Terraform creates only the new team's resources and leaves the existing teams untouched. The plan shows additions, not a rebuild.
The exact schema for each resource is in the [Vantage provider docs on the Terraform Registry](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs). `vantage_budget` periods take a `start_at` and `amount`; `end_at` is optional. Add one period per month, or generate periods, to cover the full budget window. Validate generated code against the provider docs before applying.
### Use Case 2: Generate Virtual Tags from a Source-of-Truth File
Allocation is where code review matters most. A [Virtual Tag](/tagging) change can reclassify months of historical cost across every report that groups by that tag. The most maintainable pattern is to keep the mapping that defines the tag, such as teams, accounts, or namespaces, in a file your organization already owns, and generate the tag values from it. The file is the system of record. `terraform plan` recomputes the tag whenever it changes. Start with the list of teams your organization already maintains:
```csv teams.csv theme={null}
team
platform
security
data-platform
core-services
```
This example builds one cross-provider `team` Virtual Tag that normalizes the AWS `team` tag and the Kubernetes `organization/team` label into a single dimension. Terraform reads the CSV and produces one value per team.
```hcl team_tag.tf theme={null}
locals {
teams = csvdecode(file("teams.csv"))
}
resource "vantage_virtual_tag_config" "team" {
key = "team"
overridable = true
backfill_until = "2026-01-01"
values = [
for t in local.teams : {
name = t.team
filter = "(costs.provider = 'aws' AND tags.name = 'team' AND tags.value = '${t.team}') OR (costs.provider = 'kubernetes' AND tags.name = 'organization/team' AND tags.value = '${t.team}')"
}
]
}
```
Or skip writing the HCL and have AI generate it from your file:
Using the Vantage Terraform provider, write a vantage\_virtual\_tag\_config that reads teams.csv (one team per row) and creates a cross-provider "team" Virtual Tag. For each team, generate a value whose VQL matches the AWS tag "team" and the Kubernetes label "organization/team" with that team's name. Return only the HCL.
Before applying, confirm the `backfill_until` date, verify the tag keys match what your providers actually emit, and keep allocation changes in their own PR. Do not bury them alongside unrelated report updates. Because each value adds processing work, review the [Scaling Virtual Tags guide](/guides/scaling_tagging) before generating tags with hundreds of values, and see [tagging examples](/tagging_examples) for more filter patterns.
### Use Case 3: Layered Allocation for Chargeback
Large organizations rarely get a clean allocation dimension from a single source. A team or product name might come from a manually maintained override, a Kubernetes namespace, a provider tag, or a [Business Metric](/business_metrics), and you need one canonical value with a clear order of precedence. You can build this entirely from Virtual Tags: define a few narrow source tags, then merge them into one standardized key using [tag key collapsing](/tagging_examples#tag-key-collapsing-examples), where the first source in the list that has a value wins.
First, define the source tags. Each one captures a single way a `team` value can be derived. Keep them narrow and independent.
```hcl team_sources.tf theme={null}
# Source 1: high-priority manual overrides
resource "vantage_virtual_tag_config" "team_overrides" {
key = "team_overrides"
overridable = true
values = [
{
name = "platform"
filter = "costs.provider = 'aws' AND costs.account_id = '123456789012'"
}
]
}
# Source 2: derive team from Kubernetes namespace
resource "vantage_virtual_tag_config" "team_from_namespace" {
key = "team_from_namespace"
overridable = true
values = [
{
name = "data-platform"
filter = "costs.provider = 'kubernetes' AND tags.name = 'namespace' AND tags.value IN ('data-ingest', 'data-warehouse')"
}
]
}
```
Then collapse the sources into one canonical key. The collapsing tag merges the source keys in priority order—list the most authoritative source first, with a raw provider tag at the bottom as a fallback. In this example, the final `{ key = "team" }` entry is the native provider tag key, not another `vantage_virtual_tag_config` resource.
```hcl team.tf theme={null}
resource "vantage_virtual_tag_config" "team" {
key = "team"
overridable = true
backfill_until = "2026-01-01"
depends_on = [
vantage_virtual_tag_config.team_overrides,
vantage_virtual_tag_config.team_from_namespace,
]
collapsed_tag_keys = [
{ key = "team_overrides" }, # manual overrides win
{ key = "team_from_namespace" }, # then namespace-derived values
{ key = "team" } # finally, the raw provider tag
]
}
```
The result is a single `team` dimension you can group and filter by across providers, with deterministic precedence.
Order is precedence: when more than one source has a value for the same cost, the source higher in the list wins. If one of your sources is a cost-based or Business Metric allocation, mind the depth and per-provider rules for allocation chains (up to three allocated tags deep). The [Scaling Virtual Tags guide](/guides/scaling_tagging) covers precedence, nesting, and processing cost in detail. To manage Business Metrics themselves as code, see [Business Metrics in Terraform](https://www.vantage.sh/blog/business-metric-api-terraform).
#### Manage a Single Virtual Tag Value
Once a `team` tag has dozens or hundreds of values, you often need to change just one. You might fix a filter, retarget a value, or drop a decommissioned team, and doing so should not require rewriting the whole config. Individual values are addressable by token. You can [retrieve](https://docs.vantage.sh/api/virtualtags/get-virtual-tag-config-value-by-token), [update](https://docs.vantage.sh/api/virtualtags/update-virtual-tag-config-value), and [delete](https://docs.vantage.sh/api/virtualtags/delete-virtual-tag-config-value) a single value directly through the API. In Terraform, the `vantage_virtual_tag_config` resource exposes `values[].token`. Each value keeps a stable identifier across applies, so you can reference a specific value without recreating the set.
### Use Case 4: Turn an Investigation into a Durable Report
Someone from finance asks why data transfer costs jumped last month. You dig into it with the [FinOps Agent](/vantage_finops_agent) or a [Vantage MCP](/vantage_mcp) client and find the answer. Then the thread disappears into chat history and the same question comes back next month.
If a question is going to recur, turn the answer into a Terraform-managed Cost Report.
Use the FinOps Agent or a Vantage MCP client to identify the services, accounts, regions, and tags driving the cost change.
Ask AI to turn the investigation into a [VQL](/vql) filter and grouping strategy, and to explain its assumptions rather than creating anything directly.
Based on this cost investigation, write a Vantage VQL filter and suggested groupings for a Cost Report that tracks these costs going forward. Explain your assumptions and return only the filter and groupings; do not create the report.
```hcl data_transfer.tf theme={null}
resource "vantage_cost_report" "aws_data_transfer" {
title = "AWS Data Transfer"
workspace_token = var.workspace_token
filter = "costs.provider = 'aws' AND costs.category = 'Data Transfer'"
groupings = "service,account_id,region"
}
```
Add the report to a [Dashboard](/dashboards) or set up a [Report Notification](/report_notifications) so the stakeholder gets a recurring update without having to ask again.
### Use Case 5: Import Console Resources into Terraform
You do not need to start from scratch. Many teams build their initial reporting structure in the console and only move to Terraform once a resource becomes part of a standing process. Examples include a chargeback report that runs monthly, a Virtual Tag that feeds executive Dashboards, or a team structure that needs to stay in sync with your identity provider.
Copy the token from the console URL (e.g., `rprt_1abc23456c7c8a90`) or query the [API](/api) or a Terraform data source.
```hcl chargeback.tf theme={null}
resource "vantage_cost_report" "monthly_chargeback" {
title = "Monthly Chargeback"
}
```
```bash theme={null}
terraform import vantage_cost_report.monthly_chargeback rprt_1abc23456c7c8a90
```
Run `terraform plan`. The first plan will likely show differences between your HCL and the live resource. Update the configuration until the plan is clean. If the diff is confusing, paste it into your AI assistant:
Here is the terraform plan output for a Vantage resource I just imported. Explain which fields are computed defaults I can ignore and which are real differences I need to set in my configuration to make the plan clean.
Not every Vantage resource supports import. Check the [Vantage provider docs on the Terraform Registry](https://registry.terraform.io/providers/vantage-sh/vantage/latest) and the individual [resource pages](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs) before attempting an import.
### Use Case 6: Version and Roll Back Allocation Config
Your allocation logic—the [Virtual Tags](/tagging) that drive showback and chargeback—is some of the most valuable configuration in Vantage, and the most tedious to reconstruct by hand if a change does not work out. When it lives in code and Git, every version is saved automatically: you can see exactly what changed between any two points in time and return to a known-good version without rebuilding it from memory.
This is the payoff of [importing your resources](#use-case-5-import-console-resources-into-terraform). Once a Virtual Tag is defined in code, Git becomes its version history.
You do not have to hand-write the starting configuration. List your Virtual Tag tokens (from the console URL or the `vantage_virtual_tag_configs` data source), write a Terraform `import` block for each one, and let Terraform generate the HCL for you.
Terraform `import` blocks and `terraform plan -generate-config-out` require Terraform 1.5 or later.
```hcl virtual_tags_import.tf theme={null}
import {
to = vantage_virtual_tag_config.team
id = "vtag_1a2b3c4d5e6f7890"
}
import {
to = vantage_virtual_tag_config.environment
id = "vtag_0987654321fedcba"
}
```
Generate the configuration from the live resources, then reconcile until the plan is clean:
```bash theme={null}
terraform plan -generate-config-out=virtual_tags.tf
```
Terraform writes the current definition of each tag into `virtual_tags.tf`. Reconcile the generated configuration until the plan is clean, then run `terraform apply` to complete the import into state. Commit `virtual_tags.tf` after the import is complete. It is now your baseline version, and the manual work of capturing the existing setup is done once and never again.
From here, every change to allocation goes through a pull request, so Git records what changed, when, and why.
Edit the tag configuration and open a PR. The `terraform plan` in the PR shows the exact before and after of the allocation change.
Tag the merge commit (for example, `vtags-2026-06-01`) so you have named versions to return to.
If a change does not pan out, revert to a previous commit and apply it. Vantage restores the Terraform-defined configuration and reprocesses affected allocation tags. There is nothing to rebuild from the audit log or from memory.
```bash theme={null}
git revert
terraform apply
```
Keep allocation configuration in its own file and its own PRs (see [Guardrails](#guardrails)). A clean, isolated history is what makes a confident rollback possible.
## Using AI Effectively
AI is what makes FinOps as Code fast: it reads your source files, drafts the HCL, and explains its reasoning so that you spend your time reviewing a diff instead of writing boilerplate. To get accurate output:
* **Give it the source of truth and the patterns:** Point the assistant at your CSV/YAML file and an existing resource in your repo so generated code matches your conventions.
* **Ask for a diff and assumptions, not actions:** Have AI return only the HCL changes and the assumptions it made. Keep it from creating or modifying resources directly.
* **Make it validate against the provider docs:** Ask the assistant to check generated code against the [Vantage provider docs on the Terraform Registry](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs). Schemas change (e.g., `vantage_budget` uses `periods`, `vantage_dashboard` uses `widgets`) and a stale example will not apply cleanly.
* **Let the plan be the proof:** A clean `terraform plan` is the real test. If the plan is noisy or fails, feed it back to the assistant and ask it to reconcile.
The [FinOps Agent](/vantage_finops_agent) is especially useful here because it understands your workspace, RBAC scope, and cost data.
## Guardrails
These are worth writing into your team's operating agreement, not just this guide:
* AI never runs `terraform apply`. A human reviews the plan and merges the PR.
* Every PR that touches Vantage resources includes a `terraform plan` output.
* Allocation changes (Virtual Tags, Billing Rules) go in their own PRs, separate from reporting or access changes. These affect historical cost data and should be reviewed with that in mind.
* VQL filters get a dedicated review check. A wrong `costs.account_id` or missing `tags.value` is the most common source of bad reports.
## Frequently Asked Questions
Yes. Most teams build and explore in the console, then move the configuration that becomes a standing process into code. The risk is editing a code-managed resource in the console, which causes drift (see below). Decide per resource where the source of truth lives, and keep code-managed resources out of the console for edits.
The next `terraform plan` will show a diff between your HCL and the live resource, and `terraform apply` will revert the console change to match the code. Treat the plan as a drift detector: if you see unexpected changes, someone edited the resource outside of code. For resources you want to manage in code, make code the only place they are changed.
Pass the Vantage API token through an environment variable or your secrets manager, never commit it. Use a remote, shared [Terraform backend](https://developer.hashicorp.com/terraform/language/backend) so your team works from the same state and avoids drift, and keep `.terraform/` and local state files out of version control.
Yes. Editing a Virtual Tag or Billing Rule reapplies it across the data in its [backfill window](/guides/scaling_tagging), which can reclassify months of cost across every report that uses it. Keep allocation changes in their own PR, set the smallest backfill you actually need, and review the plan with this in mind.
Cost Reports, Folders, Dashboards, Virtual Tags, teams, access grants, budgets, Cost Alerts, Billing Rules for eligible MSP accounts, Business Metrics, and more. See the [Vantage provider docs on the Terraform Registry](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs) for the full list and each resource's schema, and check there before assuming a resource supports [import](#use-case-5-import-console-resources-into-terraform).
## References
* [Vantage Terraform Provider (Terraform Registry)](https://registry.terraform.io/providers/vantage-sh/vantage/latest)
* [Vantage Terraform Resource Docs (Terraform Registry)](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs)
* [VQL Reference](/vql)
* [Virtual Tags](/tagging) and [tagging examples](/tagging_examples)
* [FinOps as Code examples repo](https://github.com/vantage-sh/finops-as-code)
* [Automating cost allocation tags with Terraform](https://www.vantage.sh/blog/terraform-automate-cost-tags)
* [Okta access automation with Terraform](https://www.vantage.sh/blog/okta-terraform)
* [Business Metrics in the API and Terraform](https://www.vantage.sh/blog/business-metric-api-terraform)
# 30-Day Getting Started Playbook
Source: https://docs.vantage.sh/guides/getting_started_playbook
An opinionated four-week plan to take a new Vantage account from first integration to a working FinOps cadence.
Built for the FinOps lead, platform engineer, or finance partner who just signed up. Each week maps practical Vantage tasks to [FinOps Foundation capabilities](https://www.finops.org/framework/capabilities/) and helps build a [Crawl-stage](https://www.finops.org/framework/maturity-model/) foundation across the capabilities covered here. The four weeks run in order, but [FinOps is iterative](https://www.finops.org/framework/phases/). Finishing the playbook starts the next loop, not the end of the work.
Data Ingestion: Connect and See
Allocation: Allocate and Report
Budgeting and Alerts: Govern
Optimization and Enablement: Save with AI
Each step links out to Vantage feature docs, [FinOps Foundation framework](https://www.finops.org/framework/) pages, [Vantage blog](https://www.vantage.sh/blog) posts on real customer patterns, the [Cloud Cost Handbook](https://handbook.vantage.sh/), and companion guides like [Scaling virtual tags](/guides/scaling_tagging) and [FinOps as Code](/guides/finops_as_code). Follow them when you want to go deeper than the week-by-week.
Each week below includes prompts you can run in the [FinOps Agent](/vantage_finops_agent) or [Vantage MCP](/vantage_mcp) to do that week's work. Want a saved, refreshable table instead of a chat answer? Run the same prompts in [Canvas](/canvas). See the [FinOps AI Prompt Guide](/guides/finops_ai_prompt_guide) for more patterns.
Use this as a baseline, not a fixed implementation order. Commercial or Enterprise teams often move at different speeds based on connected providers, access requirements, business goals, and FinOps maturity. Some teams prioritize unit costs early; others need more time on integrations, allocation, dashboards, or optimization.
## Week 1: Connect and See
Every dollar of cloud, SaaS, and AI spend is visible in one Vantage account, with at least one workspace and one shared report.
Connect [AWS](/connecting_aws), [Azure](/connecting_azure), [GCP](/connecting_gcp), or any combination of the three. For AWS, start at the management (payer) account so member accounts inherit. For Azure and GCP, each connection doc covers the right billing scope to start from. Add [Kubernetes](/connecting_kubernetes) via the [agent](/kubernetes_agent) only **after** the underlying cloud provider is connected. Vantage attributes node costs back to AWS, Azure, or GCP.
Then add the SaaS, data, and AI providers you already pay for: [Snowflake](/connecting_snowflake), [Databricks](/connecting_databricks), [Datadog](/connecting_datadog), [OpenAI](/connecting_openai), [Anthropic](/connecting_anthropic), [Cursor](/connecting_cursor), and [GitHub](/connecting_github). Including SaaS and AI from the start, not just IaaS, is the [FinOps Foundation Data Ingestion capability](https://www.finops.org/framework/capabilities/data-ingestion/) in practice.
Watch **Settings > Integrations** until each integration shows **Stable**. See [integration status](/vantage_account#integration-status) for what each state means.
AWS specifically: granular filtering and grouping by resource and tag require the [CUR](/connecting_aws#cur-format) to be ingested. Set expectations with stakeholders. The first CUR can take up to 24 hours to arrive, so those AWS views won't have full detail at the start. See [AWS Data Ingestion Delay](/connecting_aws#aws-data-ingestion-delay) for what's available in the meantime.
Read [workspaces](/workspaces) and pick one of two patterns:
* **One workspace per business unit**: when cost data needs hard separation between groups.
* **One shared workspace**: when everyone should see everything.
A [workspace](/workspaces) is a security boundary; sharing a single report is not.
If your organization needs hard separation between business units or regulated teams, configure RBAC **now**, before users start exploring. Once people have visibility into cost data, taking it back is politically harder than never granting it in the first place.
Follow the [RBAC Setup Guide](/guides/rbac_setup) for the recommended pattern: lock down the Everyone team, create dedicated teams scoped to specific workspaces, and assign provider integrations to the workspaces those teams should see.
Advanced RBAC ([scoped team workspace access](/rbac), [SSO group mapping](/sso#set-up-sso-group-mapping-for-teams)) requires an Enterprise tier account. Single-team accounts and small orgs without separation requirements can skip this step.
In **Settings > People**, click **Invite People** and add your FinOps stakeholders: eng leadership, finance, the executive sponsor, and the engineers who'll act on recommendations. Assign each person an [organization-level role](/rbac) and, if you set up RBAC above, the right team. See [Invite Users to Your Account](/vantage_account#invite-users-to-your-account) for the step-by-step flow.
**For larger orgs, automate team membership.**
* [SSO group mapping](/sso#set-up-sso-group-mapping-for-teams) places users on the right team based on their identity-provider group.
* The [Vantage API](https://docs.vantage.sh/api/teams/add-team-member) and the [Terraform provider](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/resources/team) cover bulk team membership for existing users.
* [Using Terraform to Automate Okta SSO Group Access](https://www.vantage.sh/blog/okta-terraform) walks through an end-to-end setup mapping Okta groups to Vantage teams, folders, and access grants.
In [Cost Reports](/cost_reports), start broad: **Last 30 Days**, group by **Service**, all providers. Save it as **All Spend**. This is your baseline for every conversation that follows.
**Or with AI:**
Create a Cost Report titled "All Spend" grouped by service across all providers for the last 30 days.
Duplicate the **All Spend** report and filter to rows missing your single most important tag (most teams pick `team` or `cost-center`). Save it as **Untagged Spend**. The goal: drive that number toward zero over the next 30 days.
This pattern comes directly from how Vantage customers structure their first governance dashboard. See [Cloud Cost Governance](https://www.vantage.sh/blog/cloud-cost-governance).
**Or with AI:**
Show me last month's spend that has no `team` tag, grouped by service.
Send the **All Spend** and **Untagged Spend** reports to your FinOps stakeholders (eng leadership, finance, executive sponsor) with a one-paragraph note: *"this is what we spend, this is what we can't yet attribute, and here's the plan to fix it."*
This is the start of the [shortened money-feedback loop](https://www.vantage.sh/blog/shortening-money-feedback-loop) and a direct application of the [FinOps Principle](https://www.finops.org/framework/principles/) that *everyone takes ownership for their technology usage*.
### Wrapping Up Week 1
Use the following prompts along with the **Definition of done** below to verify the week's work.
Which cost providers and integrations are connected, and what's the status of each?
List my workspaces, the integrations assigned to each, and the people who have access.
List my saved Cost Reports and confirm "All Spend" and "Untagged Spend" exist.
**Definition of done:** all primary providers **Stable**, one workspace strategy chosen, RBAC configured (if applicable), stakeholders invited, two saved reports (**All Spend** and **Untagged Spend**), one summary note sent.
## Week 2: Allocate and Report
Pick at most three to five keys, typically `team`, `environment`, `application`, `cost-center`, and `business-unit`. Document them in a shared place your engineers will actually read. The recommended flat core set and the rationale for keeping it small are in [Scaling virtual tags](/guides/scaling_tagging).
In **Settings > Tags**, look at which keys your providers already emit. If `team` already exists everywhere with consistent values, use it directly. Don't invent a virtual tag rule when the underlying tag is already correct.
**Or with AI:**
What tag keys are available across my providers, and what are the most common values for the `team` tag?
Pick **Custom Value** or **Tag Key Collapsing** to start ([virtual tags](/tagging), [virtual tag examples](/tagging_examples)). Apply the [Scaling virtual tags](/guides/scaling_tagging) guidance from day one:
* Scope the tag to specific providers, not All Providers.
* Set the smallest backfill window you actually report on.
* Prefer equality operators (`is`, `is one of`) over `flexible match`.
**Or with AI:**
Create a virtual tag called `team` that combines the AWS `team` tag and the Kubernetes `organization/team` label.
Wrap each team's filter (provider, accounts, the `team` virtual tag you just created) into a [saved filter](/saved_filters). Reports and dashboards scoped to that team can reference it, so changes to membership propagate automatically without touching every report.
Group your reports into [folders](/folders) and create a [dashboard](/dashboards) per team. This sets up **showback**, or visibility for each team, which the FinOps Foundation [Invoicing & Chargeback capability](https://www.finops.org/framework/capabilities/invoicing-chargeback/) calls "always required in any FinOps practice." Formal chargeback to accounting cost centers is a separate question, dependent on your org's accounting model.
Import a [business metric](/business_metrics) and attach it to the **All Spend** report. Start simple (cost per GB stored, cost per token); customer-level metrics come later. This is the FinOps Foundation [Unit Economics capability](https://www.finops.org/framework/capabilities/unit-economics/), and a trend on a stable denominator beats raw monthly spend.
Review the **Untagged Spend** report from Week 1 and note the percentage drop. The [FinOps Maturity Model](https://www.finops.org/framework/maturity-model/) sample KPIs are "able to allocate at least 70% of cost to known owner" at Crawl, "at least 85%" at Walk, and "greater than 90%" at Run. Use your primary tag, account structure, or another documented allocation rule to measure known-owner allocation. Don't chase Run yet. Crawl is the right target for now.
### Wrapping Up Week 2
Use the following prompts along with the **Definition of done** below to verify the week's work.
Show last month's cost grouped by `tag:team` and call out which services still have the most untagged spend.
List my dashboards and the reports inside each.
List my business metrics and which Cost Reports they're attached to.
**Definition of done:** at least 70% of cost allocated to a known owner, one dashboard per team, one unit cost in place.
## Week 3: Budget, Alert, and Govern
Nothing surprises you, and every alert has an owner.
Connect [Slack](/slack) or [Microsoft Teams](/microsoft_teams) for notifications.
Cost alerts, anomaly alerts, budget alerts, and report notifications can be delivered to **Slack or Teams, not both**. Pick one.
In [budgets](/budgets), use a standard budget for a flat target and a hierarchical budget (up to 10 levels) when you want a parent budget broken out by team. Each budget runs on a [budget period](/budgets#budget-periods) you choose—from weekly up to multi-year—so you can match your planning cadence. A budget can track dollar spend or a [usage quantity](/budgets#cost-and-usage-budgets)—such as tokens or instance-hours—so you can plan in the same units you're billed or metered in.
**Or with AI:**
Create a monthly Budget of \$50,000 for my AWS production Cost Report for the rest of the calendar year.
Use [cost alerts](/cost_alerts) for threshold and percent-change rules and [cost anomaly alerts](/cost_anomaly_alerts) for ML-detected spikes. Send everything to one Slack or Teams channel for a week before you fan out by team. It's much easier to tune signal-to-noise that way.
**Or with AI:**
Create a Cost Alert that notifies my #finops Slack channel if any provider's spend exceeds 20% of last month's.
From any anomaly, the FinOps Agent's [**Investigate Anomaly** action](/vantage_finops_agent#investigate-cost-anomalies) produces a root-cause summary in Slack. Ask a teammate to try it the first time one fires.
Use [report notifications](/report_notifications) for scheduled digests: daily for the engineering cost channel, weekly digest for finance, monthly summary for execs.
Use [issues](/issues) to track optimization work, and link each issue to the Cost Report that proves the savings. This makes optimization a tracked task with an owner, not an item on a list nobody re-reads.
Already in Jira? The [Jira integration](/jira) can create Jira issues from cost anomaly alerts, budget alerts, cost alerts, and resource reports, including resource reports for cost recommendations. Issue status syncs back into Vantage daily.
A 30-minute Friday review covering: anomaly alerts, budget burn, the top three issues, and the untagged % trend.
Open any saved Cost Report and confirm the [baseline forecast](/forecasting#baseline-forecast) is plausible one, three, and six months out. If you've changed filters this week, re-save the report so the forecast regenerates.
Two forecast types are Enterprise-tier features: [Dynamic forecast](/forecasting#dynamic-forecast), tied to imported business metrics, and [Scenario Model forecast](/forecasting#scenario-model-forecasts), built from your own models of known future costs, credits, or trends.
### Wrapping Up Week 3
Use the following prompts along with the **Definition of done** below to verify the week's work.
List my budgets and cost alerts, and tell me which have fired in the last 7 days.
List my report notifications and what schedule they're on.
**Definition of done:** budgets on the top reports, anomaly alerts wired to one channel, three issues open with owners, weekly review on the calendar.
## Week 4: Optimize and Operate with AI
Book actual savings, put AI in the loop, and turn FinOps from a project into a practice.
This week leans on the [FinOps Agent](/vantage_finops_agent) and [Vantage MCP](/vantage_mcp) to shorten the path from analysis to action. The [FinOps Foundation has highlighted agentic AI use cases](https://www.finops.org/insights/ai-for-finops-agentic-use-cases/) for FinOps teams moving from insight to execution.
Open [cost recommendations](/cost_recommendations) and filter to your highest-impact provider first. Save the result as a [saved view](/cost_recommendations#saved-views), then [add it to a dashboard](/cost_recommendations#add-saved-recommendation-views-to-dashboards) so progress on those recommendations stays visible alongside spend trends. This is the FinOps Foundation [Usage Optimization capability](https://www.finops.org/framework/capabilities/usage-optimization/) in practice; for the over-provisioning patterns to look for across EC2, EBS, RDS, and container services, see [Rightsizing](https://handbook.vantage.sh/aws/concepts/rightsizing/) in the Cloud Cost Handbook.
**Or with AI:**
List my open AWS cost recommendations ranked by estimated monthly savings. Which three should I prioritize this week?
Use [cost recommendations](/cost_recommendations#recommendation-categories) to find idle and orphaned AWS resources such as unattached EBS volumes, unattached EIPs, idle EC2 instances, and idle RDS instances. Then open the related [active resources](/active_resources) or resource reports to inspect the affected resources before taking action. The cheap, no-architecture-change wins often live here.
**Or with AI:**
List my AWS EC2 instances costing more than \$100 per month and flag any that look idle.
If your organization has connected the [Datadog MCP connector](/datadog_mcp), ask the FinOps Agent to confirm utilization with live telemetry before you act, for example *"Which of these EC2 instances show low CPU and memory in Datadog over the last two weeks?"* This verifies a resource is truly idle rather than acting on cost alone.
In [Kubernetes](/kubernetes), open the **Kubernetes efficiency reports** for pod-level rightsizing recommendations. See [How Vantage calculates Kubernetes rightsizing recommendations](/cost_recommendations#how-vantage-calculates-kubernetes-rightsizing-recommendations) for the 80% efficiency target and the formulas behind each recommendation, and [Kubernetes Rightsizing](https://handbook.vantage.sh/kubernetes/kubernetes-rightsizing/) in the Cloud Cost Handbook for the request/limit concepts behind it. If you don't run Kubernetes, swap this step for another sweep through [cost recommendations](/cost_recommendations).
Open [financial commitment reports](/financial_commitment_reports). Financial commitment reports currently support AWS only and require the CUR to be ingested. The [FinOps Maturity Model](https://www.finops.org/framework/maturity-model/) sample KPIs for commitment discount target coverage are "approximately 60%" at Crawl, "greater than 75%" at Walk, and "greater than 80%" at Run. If your commitment coverage is well below 60%, queue a commitments conversation with finance.
The [FinOps Agent](/vantage_finops_agent) and [Vantage MCP](/vantage_mcp) use the same underlying read and write tools, exposed to different audiences. Some teams will have set up one or both earlier; this week, make sure each surface is in front of the people who'd use it.
* **FinOps Agent in Slack** for FinOps practitioners and managers. Pick the channel where your weekly review happens. An Org Owner has to approve any AWS remediation actions ([RBAC permissions](/rbac_permissions)). Run a few opening prompts together with a teammate:
* *"Summarize this week's spend for me."*
* *"Open an issue for the largest active recommendation."*
* *"Investigate the most recent anomaly."*
* **Vantage MCP in the editor** for engineers already in Cursor, Claude Code, or Goose. They can query Vantage from their IDE without context-switching to the console. Try: *"What's the unit cost of the checkout service this month?"*
* **[Canvas](/canvas) in the console** for anyone who wants the agent's answer as a saved, refreshable table instead of a one-off chat reply. Turn the recurring prompts from earlier weeks into durable reports you can re-run. Try: *"Show cost per team by service for the last three months as a table."*
See the [FinOps AI Prompt Guide](/guides/finops_ai_prompt_guide) for more prompt patterns.
If your team doesn't use Terraform, skip this step. The [Vantage API](/api) covers the same resources programmatically if you'd rather script changes another way.
Pick the three to five reports, budgets, or virtual tags you re-edit by hand the most and move them to the [Vantage Terraform provider](/terraform), following [FinOps as Code](/guides/finops_as_code).
Use AI to draft the Terraform, then commit the reviewed configuration through your normal Terraform workflow.
**Or with AI:**
Write me a Terraform script for the virtual tag I just created in the Vantage console.
When using a [service token](/api/authentication#create-a-vantage-api-service-token) with Terraform, assign it to the **Everyone** team. Service tokens on the Everyone team have the permissions needed for organization-level actions like managing provider integrations, creating teams, and managing [virtual tags](/tagging). Tokens on other teams will hit authorization errors for those operations.
Send each persona the matching [Vantage University](/vantage_university) track:
For practitioners owning cost visibility and allocation.
For engineers acting on recommendations.
For finance partners on budgets and forecasting.
As a practical Vantage rollout cadence, start with one module per role per week. This supports the FinOps Foundation [Education & Enablement capability](https://www.finops.org/framework/capabilities/finops-education-enablement/).
Run a 30-minute review with stakeholders covering allocation %, anomaly counts, issues closed and savings booked, and recommendations adopted.
Then pick one [FinOps capability](https://www.finops.org/framework/capabilities/) to advance from [Crawl to Walk](https://www.finops.org/framework/maturity-model/) over the next 30 days, and put it on the roadmap.
### Wrapping Up Week 4
Use the following prompts along with the **Definition of done** below to verify the week's work.
What was my month-over-month change in spend, and what drove it?
What's my current commitment coverage across providers, and where could I improve?
**Definition of done:** at least one optimization booked, a saved recommendations view pinned to a dashboard, the FinOps Agent installed in Slack with at least one teammate using it, one engineer querying via MCP, a written "next 30 days" plan grounded in the [FinOps Foundation capabilities](https://www.finops.org/framework/capabilities/).
The Crawl-stage foundation is the start, not the finish. Pick one [FinOps capability](https://www.finops.org/framework/capabilities/) to advance from [Crawl to Walk](https://www.finops.org/framework/maturity-model/) and rerun the playbook with a sharper focus.
## Frequently Asked Questions
Most of it works on the free tier. The notable exceptions:
* **Automated [FinOps Agent](/vantage_finops_agent) remediation** is for paying accounts.
* **Advanced [RBAC](/rbac)** (locking down the Everyone team, scoped team workspace access) is Enterprise tier.
* **[Dynamic forecast](/forecasting#dynamic-forecast)** tied to imported business metrics is Enterprise.
* **[Scenario Model forecast](/forecasting#scenario-model-forecasts)** built from your own models of known future costs, credits, or trends is Enterprise.
None of those are required to reach the Week 4 outcomes. They're listed where they apply so you can plan around them.
Yes. The pace is suggested, not strict. Many customers finish Week 1 in a couple of days. The 30-day frame is for the **rhythm** (weekly review, anomaly response, monthly capability advancement), not the setup. The [FinOps Foundation Phases](https://www.finops.org/framework/phases/) page is explicit that practitioners cycle quickly through Inform/Optimize/Operate as they mature.
Run the **Definition of done** check at the end of each week. Start at the first week whose checks aren't all green. Most teams who've used Vantage informally for a while are missing pieces of Week 2 (allocation hierarchy, unit cost) or Week 3 (budgets and a real weekly cadence). Both are worth doing properly even if it feels like backtracking.
# RBAC Setup Guide
Source: https://docs.vantage.sh/guides/rbac_setup
Step-by-step guide to setting up role-based access control for large organizations.
This guide is part of the At Scale guides because it is designed for organizations managing access across multiple departments, business units, or workspaces.
Advanced role-based access controls are available only for Enterprise tier accounts.
For organizations with multiple departments or business units, the recommended approach is to **remove all workspace access from the Everyone team** and then create dedicated teams with access scoped to only what each group needs. This guide walks through the process step by step.
Throughout this guide and the [RBAC documentation](/rbac), *Cost Reporting items* refers to the items managed within workspaces, such as Cost Reports, Dashboards, Folders, Saved Filters, Resource Reports, Kubernetes Efficiency Reports, and Financial Commitment Reports.
This guide assumes you are familiar with RBAC concepts like organization-level roles, team-level roles, and workspace access. For an overview, see [Role-Based Access Control](/rbac).
## Before and After
By default, the Everyone team gives all users access to everything.
```mermaid theme={null}
flowchart LR
U1[All Users] --> E1[Everyone Team] -->|Can Edit| WA[All Workspaces]
style U1 fill:#fff,stroke:#999
style E1 fill:#fff,stroke:#999
style WA fill:#f5f5f5,stroke:#6742D6
```
After setup, the Everyone team is locked down and each dedicated team only sees what they need.
```mermaid theme={null}
flowchart TD
FT[Finance Team] -->|Can Edit| FW[Finance Workspace]
O[Org Owners] -.->|Full Access| FW
O -.->|Full Access| EW[Engineering Workspace]
ET[Engineering Team] -->|Can View| EW
E2[Everyone Team] -.-x|No Access| WB[All Workspaces]
style E2 fill:#fff,stroke:#cc0000
style WB fill:#f5f5f5,stroke:#cc0000
style FW fill:#f5f5f5,stroke:#6742D6
style EW fill:#f5f5f5,stroke:#6742D6
style FT fill:#fff,stroke:#6742D6
style ET fill:#fff,stroke:#6742D6
style O fill:#6742D6,color:#fff
```
## Walkthrough
The following steps walk through a typical setup for a large organization. In this example, senior leaders are Organization Owners (who always have full access to everything), while a Finance team manages their own Cost Reports and an Engineering team can only view engineering cost data.
Before configuring teams, create a workspace for each group or department that needs its own set of Cost Reporting items. For example, create a **Finance** workspace and an **Engineering** workspace. See [Workspaces](/workspaces) for instructions on creating and managing workspaces.
Then, [assign provider integrations to each workspace](/workspaces#manage-workspace-provider-integrations). The integrations assigned to a workspace determine what underlying cost data is available there. For example, assign your AWS and Datadog integrations to the Engineering workspace so the engineering team can track infrastructure and observability costs, and assign your Snowflake integration to the Finance workspace so the finance team can monitor data warehouse spend.
Any user who can view a workspace can see all cost data from the integrations assigned to it, including Organization Viewers, who can interactively adjust filters and explore reports without saving. Plan your integration-to-workspace mapping carefully before granting teams access.
Navigate to **Settings > Teams > Everyone** and set workspace access to **No Access** for every workspace. This ensures no user sees anything by default. Access is granted only through designated teams.
After this step, non-Organization Owner users will lose visibility into all Cost Reporting items until you assign them to a team with workspace access. Organization Owners are unaffected and always retain full access.
Assign each user an appropriate organization-level role:
* **Organization Owner**—For administrators and senior leaders who need full visibility and control. Organization Owners always have full access to all workspaces and Cost Reporting items, so they do not need to be placed on any additional team.
* **Integration Owner**—For users who need to manage provider integrations, Virtual Tags, Custom Providers, and Business Metrics but do not need other admin privileges.
* **Organization Editor**—For most day-to-day users who need to create and edit Cost Reporting items.
* **Organization Viewer**—For users who should only have read-only access.
Navigate to **Settings > People**, hover over a user, click the ellipses (**...**), then click **Edit** to set their role. The People page displays each user's **Organization Role** in a dedicated column, making it easy to see role assignments at a glance.
Navigate to **Settings > Teams** and create a team for each group that needs scoped access. For example:
* **Finance**—Finance team members scoped to the Finance workspace.
* **Engineering**—Engineering team members scoped to the Engineering workspace.
You do not need to create a team for Organization Owners—they already have full access to everything. However, if your leadership group wants their own dedicated workspace (e.g., an Executive workspace for sensitive reports), you can create a team for them and scope it to that workspace.
For each team, go to the **Access** tab and set the workspace access level:
| Team | Finance Workspace | Engineering Workspace |
| - | - | - |
| Finance | Can Edit | No Access |
| Engineering | No Access | Can View |
For each team, go to the **Members** tab, click **Add Members**, and assign each member a team-level role:
* **Team Owner**—Can manage the team's Cost Reporting items and control which teams have access to them.
* **Team Editor**—Can create, edit, and delete items the team has access to.
* **Team Viewer**—Can only view items the team has access to.
For example, a Finance analyst with an **Organization Editor** role and a **Team Editor** role on the Finance team will be able to create and edit Cost Reports in the Finance workspace, but will not see anything in the Engineering workspace.
A more complex case: your CFO has an **Organization Owner** role and is also a member of the Finance team. Because Organization Owners always have full access to everything, the CFO can see and edit items in *all* workspaces, not just the Finance workspace. Their Finance team membership doesn't restrict them. If you want to limit any user's visibility to specific workspaces, assign them an **Organization Editor** role instead and rely on team membership to control their access.
If a specific Cost Reporting item needs to be shared outside of its workspace, use **Manage Access** on the item itself. For example, say an executive Dashboard lives in the Finance workspace and you want the Engineering team to see it, without granting them access to the entire Finance workspace. Click the ellipses (**...**) on the dashboard, select **Manage Access**, and set the Engineering team to **Can Access**.
For organizations using SSO, you can [map SSO groups to Vantage teams](/sso#set-up-sso-group-mapping-for-teams) to automate team assignment when users log in. You can also manage teams programmatically via the [Vantage API](https://docs.vantage.sh/api/teams/add-team-member) or the [Vantage Terraform provider](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/resources/team).
## Frequently Asked Questions
Yes. Any user with view access to a workspace can see all cost data from the [integrations assigned to that workspace](/workspaces#manage-workspace-provider-integrations). Organization Viewers can also interactively adjust filters, date ranges, and groupings on Cost Reports to explore the data. These changes are temporary and are not saved. If you have sensitive cost data that should be restricted, assign those integrations only to workspaces that the appropriate teams can access.
Each provider integration (e.g., an AWS account or Datadog connection) is [assigned to one or more workspaces](/workspaces#manage-workspace-provider-integrations). This determines which cost data appears in each workspace. RBAC controls who can access each workspace, so the combination of integration assignment and team workspace access controls who can see what cost data. For example, if your AWS production integration is only assigned to the Finance workspace, only teams with access to the Finance workspace can see that data.
All items remain in their workspaces, nothing is deleted. However, non-Organization Owner users will immediately lose visibility into any item they could previously see through the Everyone team. Make sure you have your teams and workspace access configured before (or immediately after) locking down the Everyone team.
Yes. A user can belong to as many teams as needed. If a user is on multiple teams that have access to the same item, they receive the **highest** permission level from any of those teams. See [Role Precedence](/rbac#role-precedence) for details.
Place them on two different teams: one with **Can Edit** access to the first workspace and another with **Can View** access to the second. Their permissions are evaluated per workspace, so they can edit in one and only view in the other.
Yes. Navigate to **Settings > Teams > Everyone**, go to the **Access** tab, and set the workspace access back to **Can Edit** or **Can View**. All users will immediately regain access through the Everyone team.
No. Organization Owners always have full access to all workspaces and Cost Reporting items, regardless of team configuration. The lockdown only affects users with Organization Editor, Integration Owner, or Organization Viewer roles.
Yes. [API service tokens](/api/authentication#create-a-vantage-api-service-token) created at the team level inherit that team's permissions. A token created for the Finance team will only have access to items the Finance team can see.
**Important:** Service tokens used for organization-level actions—such as managing provider integrations or creating teams—must be assigned to the **Everyone** team. This applies to tokens used by the [Kubernetes agent](/kubernetes_agent) and the [Terraform provider](/terraform). Tokens assigned to other teams will not have the necessary permissions and may encounter authorization errors.
No. You have several options for managing team membership at scale:
* **SSO group mapping**—[Map SSO groups to Vantage teams](/sso#set-up-sso-group-mapping-for-teams) so users are automatically assigned to the correct team when they log in.
* **API**—Use the [Vantage API](https://docs.vantage.sh/api/teams/add-team-member) to programmatically add members to teams.
* **Terraform**—Use the [Vantage Terraform provider](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/resources/team) to manage teams and membership as code.
# Scaling Virtual Tags
Source: https://docs.vantage.sh/guides/scaling_tagging
Keep virtual tag processing fast and predictable as you add providers, values, and nested allocation chains.
How long a virtual tag takes to process is a direct function of how much data it covers and how complex it is. A few configuration choices—backfill window, tag breadth, nesting depth, and virtual tag type—drive that cost, and choosing them well keeps tag changes fast as your account grows.
This guide assumes you are familiar with the [Virtual Tags](/tagging) feature reference and the [tagging examples](/tagging_examples).
## Need Help Designing a Tag?
AI-Assisted Virtual Tagging
Describe the dimension you need to report on. The docs assistant will recommend a tag type, provider scope, and backfill window that keeps processing time low, using the guidance on this page.
## How Vantage Processes Virtual Tags
When you save a virtual tag, Vantage reapplies it across the cost data in its scope, reprocessing each affected billing data import. A few factors determine how much work each save creates:
* **Backfill window:** Billing Period Backfill controls how far back the tag is reapplied. A multi-year backfill covers significantly more data than a few months.
* **Tag breadth:** Each value, each collapsed key, and each filter inside a tag adds to the work required to apply it. More values usually mean more work, but what matters most is how many cost rows (the individual line items in your cost data) fall in scope and, for allocations, how many targets each row splits into. As a result, a small tag that matches a huge number of rows or fans out into many allocation targets can cost more than a larger one. Complex filter operators (`flexible match`, `contains`) also take longer to evaluate than equality.
* **Nesting depth:** When one virtual tag references another, the referenced tag has to be processed first. Every additional level of nesting adds another full run over the data in scope (a "pass").
* **Virtual tag type:** Custom Value and Tag Key Collapsing tags are lightweight: they map or copy values without changing how many cost rows exist. Allocations do more work because they split each matched cost row into multiple rows, one per team, project, or other target the cost is spread across. That added row volume is the real driver. Percent-Based allocations are usually cheap because they split across only a handful of fixed percentages. Cost-Based and Business Metrics-Based allocations also aggregate a driver (spend or a business metric) and can fan each row out across many targets, so they take longest.
Reporting is mostly separate from processing: once a tag is applied, Cost Reports and saved filters read the result directly, so report performance depends largely on filter operators and provider scope. The main exception is allocations: because they split costs into many more rows, a report that groups or filters by an allocated dimension reads more data and can run slower than the same report over the same costs without that grouping. In addition, the more targets the allocation spreads across, the bigger the effect.
The processing work described here is tracked as [Build Hours](/build_hours). Check **Settings > Tags > Build Hours** to see how much compute your tagging configuration uses over time and whether a recent change pushed it up.
## Selecting the Right Virtual Tag Type
Picking the right type for each use case is the choice that has the biggest effect on processing time. The following table lists each type from fastest to slowest to process.
| Type | Use when | Processing time | Example |
| - | - | - | - |
| [Custom Value](/tagging_examples#custom-values-examples) | You are mapping existing cost dimensions (provider tags, accounts, services, resource IDs) to a standardized value. | Low. One lookup per value each time the tag runs. | A `team` tag with one value per team, each scoped to that team's AWS accounts. |
| [Tag Key Collapsing](/tagging_examples#tag-key-collapsing-examples) | Teams have applied semantically identical keys with different spelling or casing (`env`, `Environment`, `environment`) and you want one standardized key. | Low. One lookup per collapsed key each time the tag runs. Values copy through automatically, so you don't have to enumerate them. If a key you're collapsing is itself another virtual tag, it becomes a dependency and adds a pass. | Collapse `env`, `Environment`, and `environment` into a single `environment` virtual tag. |
| [Percent-Based Allocation](/tagging_examples#percent-based-allocation-example) | The split is contractual or pre-negotiated (Marketplace purchases, AWS Shield, support fees with a fixed agreement). | Low, but still an allocation. Cheap because costs split across only a few fixed percentages, not because it skips allocation work. | Marketplace costs split 60/30/10 across Infrastructure, Mobile, and Data. |
| [Cost-Based Allocation](/tagging_examples#cost-based-allocation-example) | A shared cost (support fees, shared infra) should track the proportional spend of teams or projects that actually used the underlying service. | Higher. Aggregates the input costs, then splits each matched row across every team or project it touches, so more targets mean more line items created. | Allocate the monthly AWS Support fee across teams using the `team` tag's share of AWS usage. |
| [Business Metrics-Based Allocation](/tagging_examples#business-metrics-based-allocation-example) | You have a real external driver (CPU seconds per team, seats per business unit, requests per product) and want costs to follow that driver. | Higher. Like cost-based: aggregates the business metric, then fans each matched row out across the targets that carry that metric. | Allocate a shared Kubernetes namespace's cost across teams using a labeled CPU usage metric. |
When the split between teams is fixed (a negotiated chargeback ratio, a contractual percentage), use **Percent-Based** rather than Cost-Based. Same result, much less processing.
## Recommended Hierarchies for Large Organizations
The hierarchies that scale best are flat and intentional. Add nesting only when the relationship is dynamic, that is, when an underlying mapping changes often enough that maintaining it in one place is worth a serial processing pass.
### Start with a Flat Core Set of Tags
For most organizations, a small core set of five flat virtual tag keys covers most reporting needs. Keep each one independent, with no nesting between them, so they don't depend on each other and edits don't cascade across tags.
```mermaid theme={null}
flowchart LR
costs[Provider costs] --> environment["🏷 environment (prod, staging, dev)"]
costs --> team["🏷 team (infra, mobile, data, ...)"]
costs --> costCenter["🏷 cost-center (R&D, G&A, COGS)"]
costs --> application["🏷 application (checkout, search, ...)"]
costs --> businessUnit["🏷 business-unit (core, platform, ...)"]
```
Each of the above tags is a Custom Value tag (or a Tag Key Collapsing tag if your underlying provider tags have casing variations). Build the core set first and resist adding more until you have evidence that a sixth key is needed.
### Nest Only When the Mapping Is Dynamic
The classic case for nesting is `application` → `business-unit`. Applications change ownership across business units more often than business units appear or disappear, and you want one place to update that mapping.
```mermaid theme={null}
flowchart LR
costs[Provider costs] --> applicationTag["🏷 Virtual Tag: application"]
applicationTag --> businessUnitTag["🏷 Virtual Tag: business-unit (references application)"]
businessUnitTag --> reports[Cost Reports]
```
This is a two-level hierarchy. Every time a relevant import is processed, Vantage runs an `application` pass first, then a `business-unit` pass. That is acceptable. A four-level hierarchy—`resource` → `application` → `team` → `business-unit`—usually is not, because each level adds another processing pass. This nesting limit is a performance guideline, not a hard rule. When a chain starts to feel that deep, look for a layer whose mapping is stable enough to inline into its parent.
See the [Nested Virtual Tags Example](/tagging_examples#nested-virtual-tags-example) for the full walkthrough.
### Use Allocation Chains Sparingly for Chargeback
Allocated tags can reference each other in a chain (for example, `Team` → `Sub-Team`), which is useful for layered chargeback. Unlike nesting depth, this is a hard limit: a hierarchy can be up to **three allocated tags deep**. Only allocated tags count toward it, and non-allocated tags (Custom Value, Tag Key Collapsing) don't, so a chain can be more than three levels deep overall as long as no more than three of those levels are allocations. Chaining allocations is also one of the most expensive things you can do to processing time. Each allocation in a chain expands rows on top of the one before it, and matching against an already-allocated tag costs more than matching a regular tag, so every added link multiplies the work. Avoid mixing many independent allocated tags on the same provider since each one redistributes costs into a separate dataset.
* **Allocation chains are per provider:** An AWS allocation chain is independent of a GCP one. You can have a percent-based `Team` allocation on AWS and a separate cost-based allocation on GCP with no conflict. Non-allocated virtual tags (Custom Value, Tag Key Collapsing) can also span providers freely.
* **Within a single provider, allocated tags can reference each other only when they sit in the same chain:** If you already have a `Team` percent-based allocation on AWS and want to add an `Environment` allocation that builds on it (for example, to split costs further within a team), structure `Environment` to chain off `Team`, referencing `Team = Engineering` (or similar) in its Output Costs Filter. If a new allocated tag tries to reference allocated tags from two unrelated AWS chains in one configuration, Vantage rejects the save with the error *"cannot reference tags from different allocation groups within the same provider (aws)."*
Two independent allocated chains can still coexist on the same provider (for example, a `Team` → `Sub-Team` chain and an unrelated `Region` allocation, as in the [Allocation-on-Allocation Example](/tagging_examples#allocation-on-allocation-example)). They just can't be combined on the same Cost Report. If you try, Vantage returns *"Cannot filter or aggregate costs for allocated virtual tags that belong to separate hierarchies."* Analyze each chain in its own report.
```mermaid theme={null}
flowchart LR
awsCostsGood[AWS costs] --> teamGood["🏷 Team (allocated)"]
teamGood --> envGood["🏷 Environment (allocated, references Team only)"]
```
A new allocated tag chains off an existing allocated tag in the same chain.
```mermaid theme={null}
flowchart LR
awsCostsBad[AWS costs] --> teamBad["🏷 Team (allocated)"]
awsCostsBad --> regionBad["🏷 Region (allocated, separate chain)"]
teamBad --> envBad["🏷 Environment (references both Team and Region)"]
regionBad --> envBad
```
A single allocated tag tries to reference allocated tags from two unrelated chains on the same provider.
See the [Allocation-on-Allocation Example](/tagging_examples#allocation-on-allocation-example) for the constraints on combining allocated tags on the same report.
## Best Practices to Keep Processing Time Predictable
The following recommendations are listed roughly in order of impact. The first three have the biggest effect.
Selecting **All Providers** on a filter set is convenient, but it tells Vantage to evaluate that filter against every connected provider's data and makes every provider's processing depend on the tag keys it references. If a tag's logic is only meaningful for AWS, scope its filters to AWS.
Use **All Providers** when the underlying logic really does apply uniformly across every provider you have or will ever connect, for example, a `team` rule that depends only on a `team` tag every provider already emits.
Billing Period Backfill is the top-level multiplier on every tag processing run. Pick the earliest month you actually report on, not the earliest month Vantage has data for. Extending the backfill later is straightforward, but it reprocesses every import in the resulting window, not just the months you added, so it's worth setting deliberately up front.
For a forward-looking tag (a new team, a new chargeback model that starts next quarter), set the backfill to the current month.
Every nested level adds a serial processing pass on every relevant import. Two levels is fine; three is sometimes justified; four or more rarely pays for itself. If you find yourself building a deep chain, ask whether the deepest layer would be more accurate as a flat tag with its own filter set.
Every save reprocesses the imports in scope, and each round reapplies every tag that applies to those imports, not just the tag you changed. To avoid repeating that work, make all intended changes to a tag before saving instead of saving after each tweak. Changes to separate tags still require separate saves.
Filter operators are not equally fast:
* `is` is an exact match Vantage can look up directly (supplying multiple values checks them as a set). Fastest.
* `contains`, `starts with`, and `ends with` scan the text of every value in scope, so they inspect far more data.
* `flexible match` normalizes and pattern-matches every value before comparing, which makes it the slowest.
Use partial matches only when you need to handle inconsistent values you cannot fix upstream. If the variation is in the tag *key* (`env` vs `Environment`), use Tag Key Collapsing instead. It is fast and gives you a single canonical key.
The wrong way to standardize an `environment` tag with three key variations is to create one virtual tag value per environment with three filters each. The right way is to create one virtual tag with three collapsed keys. Collapsing copies values through automatically and stays correct as new values appear at the provider.
Reserve per-value Custom Value filters for when the source-to-target mapping is genuinely many-to-one and would not survive a value being copied through verbatim.
Within a virtual tag, when two rules match the same row, the rule higher in the list takes precedence. Order doesn't change how much work matching takes, but it does decide which value is applied when rules overlap. Put more specific rules above broader ones so the value you actually want is the one that lands on the row.
Cost-Based and Business Metrics-Based allocations aggregate a driver and split each matched row across every target it touches. If the split between teams is a fixed percentage, a Percent-Based allocation is still an allocation but fans out across only those few percentages, so it produces the same result with much less work.
Using 11 narrow virtual tags that each cover a single team takes longer to process and is harder to reason about than one `team` virtual tag with 11 values. Consolidate where possible and keep headroom under the default limits of [50 virtual tags per account and 100 values per tag](/tagging#virtual-tags-limit).
## Anti-Patterns to Avoid
Convenient by default, slow at scale. Scope each tag to the providers whose data its filters actually match.
A forward-looking tag with a longer backfill reprocesses three years of data on every save for no reporting benefit. Set the backfill to the earliest month you actually report on for that tag.
Each level is sequential. Flatten where possible. If a deep chain feels necessary, look for a level whose mapping is stable enough to inline into its parent.
Every save kicks off reprocessing on every relevant import. Stage all your changes (values, filters, ordering, backfill) before saving, especially for tags with wide backfill windows.
`flexible match` is the slowest operator. If the variation is in the *key* rather than the value, use Tag Key Collapsing.
Each allocated tag chain redistributes costs into a separate dataset, and unrelated allocated tags cannot be combined on the same Cost Report. Keep allocated tags inside the same chain when you need them to compose, or use separate reports.
Not sure which of these applies to your tag? [Try the AI assistant at the top of this page.](#need-help-designing-a-tag)
## Frequently Asked Questions
Processing time is roughly proportional to `billing periods in backfill` × `integrations whose data the tag could match` × `values + collapsed keys` × `nested levels`, and for allocated tags it scales further with the number of targets each cost row splits into. A `team` tag with 30 values, a 12-month backfill, and All Providers across 8 integrations does an order of magnitude more work than the same tag scoped to AWS only with a 6-month backfill. Most multi-hour cases are explained by a combination of wide backfill and All Providers scoping—or, for allocations, a split across many targets that expands costs into far more line items.
No. Backfill is per virtual tag. If `business-unit` references `application` and you extend `business-unit`'s backfill to an earlier period, `application` keeps its existing backfill. To align history across a nested chain, extend the backfill on each referenced tag first, wait for processing to complete, then extend the parent.
Yes. When you save a tag that other tags reference, Vantage reprocesses the dependent tags as well, in dependency order. This is why nested chains add latency, as edits to a foundational tag ripple through every level above it. More broadly, reprocessing happens per import: when an import is reprocessed, every virtual tag that applies to it reruns, not just the tag you edited. That's another reason to make all your intended edits to a tag before saving, rather than saving after each tweak.
Yes for processing, and yes at read time when more than one provider is in scope. For tags whose logic genuinely applies to every provider (and every provider you might add), All Providers is the right choice. For tags whose rules will only ever match one or two providers, scoping per provider is faster and stays accurate as you add new providers that should not be in scope.
Order does not change the total amount of matching work, but it does control which rule wins on overlap. Put more specific or higher-priority rules above broader ones so overlapping rules apply the intended value. This is consistent with [Virtual Tag Order](/tagging#virtual-tag-order).
Yes, modestly. Each removed value is one fewer value Vantage has to match each time the tag runs. The bigger wins come from reducing backfill width, tightening provider scope, and flattening hierarchy. Delete-and-consolidate is worth doing alongside those, not instead of them.
Mostly indirectly. By the time a Cost Report runs, virtual tag values are already written into your cost data, so report runtime depends largely on the report's filter operators and provider scope. Equality filters on a single provider read faster than `flexible match` filters across All Providers. The exception is allocations: because they split costs into many more rows, a report that groups or filters by an allocated dimension reads more data and can run slower than the same report without that grouping.
# Enable Hourly Financial Commitment Reports
Source: https://docs.vantage.sh/hourly_fcr
Enable hourly granularity for Financial Commitment Reports in Vantage.
With hourly granularity, you can analyze your financial commitment coverage and utilization, by the hour, for any 14-day period within your data retention.
To enable this feature, contact [support@vantage.sh](mailto:support@vantage.sh).
If your Cost and Usage Report (CUR) is currently set to daily aggregation (the Vantage default), you must [reconnect your AWS integration](/connecting_aws#create-a-connection) with a new CUR configured to use an hourly time unit. This guide walks through how to obtain an hourly AWS Cost and Usage Report using [CloudFormation](/hourly_fcr#enable-via-cloudformation), [Terraform](/hourly_fcr#enable-via-terraform), or through a [manual process](/hourly_fcr#enable-via-manual-deployment).
Vantage will experience a delay in receiving your cost data until the first hourly CUR is received from AWS. This process can take up to 24 hours. In addition, the first hourly CUR that's sent to Vantage contains only the current month's data. Follow the instructions for [backfilling a CUR](/connecting_aws#backfilling-aws-cur-for-previous-reporting-periods) to obtain additional months' data.
## Enable via CloudFormation
From your AWS management account (or account the CUR is deployed in), navigate to **CloudFormation**.
Open the **ConnectToVantage-** stack.
At the top, click **Update Stack** > **Create a change set**.
Select **Use existing template**, then click **Next**.
Make the following changes:
* Update the **ReportName** so that it is unique. It is recommended you append *-hourly* to the existing **ReportName**.
* For **TimeUnit**, change the value from **DAILY** to **HOURLY**. Then, click **Next**.
Check the box at the bottom to acknowledge the changes that are being made. Then, click **Next**.
Review your changes and click **Submit**.
Your change set will be created based on the changes to your resources. This process may take a few minutes. At the top right, click **Execute change set**. (If you are unable to click the **Execute change set** button, click the circular **Refresh** icon below the button.)
CloudFormation processes your changes, which includes deleting the previous CUR definition and creating a new hourly CUR.
## Enable via Terraform
CUR 2.0 support in the Vantage Terraform [AWS integration module](https://registry.terraform.io/modules/vantage-sh/vantage-integration/aws/latest) requires version 5.48.0 or newer of the HashiCorp AWS provider.
Set `cur_report_time_unit` to `HOURLY` and apply your changes. The module manages a legacy CUR 1.0 report by default; set `upgrade_to_cur_2 = true` to replace it with a CUR 2.0 Data Export.
```hcl theme={null}
provider "aws" {
region = "us-east-1"
assume_role {
role_arn = "arn:aws:iam::123456789012:role/admin-role"
}
}
module "vantage-integration" {
source = "vantage-sh/vantage-integration/aws"
# Bucket names must be globally unique. It is provisioned with private acl's
# and only accessed by Vantage via the provisioned cross account role.
cur_bucket_name = "my-company-cur-vantage"
# Optional: granularity of the CUR report: "HOURLY" or "DAILY"
cur_report_time_unit = "HOURLY"
# Opt in to replacing the legacy CUR 1.0 report with CUR 2.0.
upgrade_to_cur_2 = true
}
```
## Enable via Manual Deployment
Log in to AWS, and navigate to the **Billing and Cost Management** console.
From the left navigation menu, under **Cost and Usage Analysis**, select **Data Exports**.
Click **Create** to create a new CUR definition.
Create a Data Export with the following parameters:
* **Export details** section:
* Select **Legacy CUR export**.
* Enter an **Export name** of your choice.
* **Export content** section:
* For **Additional export content**, select **Include resource IDs**.
* For **Data refresh settings**, select **Refresh automatically**.
* **Data export delivery options** section:
* For **Report data time granularity**, select **Hourly**.
* For **Report versioning**, select **Overwrite existing report**.
* For **Compression type**, select **gzip**.
* **Data Export storage settings** section:
* For **S3 bucket**, select the same S3 bucket your existing Vantage CUR uses.
* For **S3 path prefix**, enter *hourly-v1*.
Click **Create Report**.
# Vantage Documentation
Source: https://docs.vantage.sh/index
Read comprehensive guides and tutorials to help you get started with Vantage.
Vantage is a cloud observability and optimization platform that aggregates cloud infrastructure costs across providers to deliver a centralized view into total cloud spend. Vantage has multiple tools for optimizing cloud spend and provides organizations with advanced FinOps workflows and cost governance.
Get started creating an integration with a number of cloud and cloud service providers.
Create your first Cost Report in the Vantage console. Create budgets, forecasts, and annotations all within your Cost Report.
Use the Vantage Terraform provider and modules to automate your cloud cost monitoring infrastructure.
## Additional and Community Resources
Vantage maintains a variety of resources to help make the lives of cloud practitioners easier. All resources below are free to use and open source, when possible.
The Vantage API makes it easy for you to programmatically access and read your cloud pricing data. Automate the management and creation of cost reporting resources, as well as programmatically create reports and filters. View the API docs to get started.
Simplifies the complex task of pricing EC2 instances on AWS. With over a million pricing permutations due to instance types, regions, and availability zones, the site streamlines the process, enabling users to quickly find and compare the best resources for their needs.
Compare LLM prices, specifications, benchmarks, and hosting information in one place. Includes customizable SQL-powered comparison views, model detail pages with pricing calculators, and data refreshed daily from provider APIs.
An open-source set of guides meant to help explain the complex pricing of public cloud infrastructure and service providers in easy-to-understand terms. This guide is hosted on GitHub and is open to anyone to contribute their knowledge to the community.
While the documentation here is meant to help answer any questions, you're also welcome to join our Slack community to add to the discussion and ask questions.
Vantage uses anonymized data from thousands of connected accounts to snapshot industry spending patterns. View our quarterly Cloud Cost Reports to analyze trends over time.
This tool helps you decode AWS Cost and Usage Report (CUR) billing codes for any AWS service. Search for specific services or billing codes to find detailed information about usage types and more.
Read insightful articles related to cloud industry trends and news. Stay up to date on Vantage press releases and product news.
This repository contains tutorials and demos for implementing FinOps as Code in your organization. Practice using the Vantage API and Terraform provider with step-by-step walkthrough tutorials.
**VANTAGE SUPPORT**
If you need help with anything, please feel free to reach out to [support@vantage.sh](mailto:support@vantage.sh).
# Issues
Source: https://docs.vantage.sh/issues
Collaborate on cost optimization with Vantage Issues.
Teams can use issues to coordinate and collaborate in Vantage. Consider the below use case.
> An organization notices a sudden spike or increase in costs related to a certain service. This service has an attached tag related to a particular team. The manager creates an issue on Vantage for the team to investigate the cost anomaly. The manager can quickly see comments and progress from their team and monitor associated costs on the attached Cost Report.
You can create issues, assign them to members in a workspace, and associate issues with a Cost Report. Team members can comment on issues, adjust an issue's category and status, and estimate the potential cost-savings impact associated with the issue.
## Create an Issue
From the top navigation, select **Financial Planning**. Then, on the left navigation, select **Issues**.
All existing issues are displayed. The Issues page has two tabs: Open and Closed.
From the top right of the Issues screen, click **New Issue**.
Add the following items:
* Enter an issue **Title** (required).
* Add an issue description (optional) in the comment box. You can use [Markdown](https://en.wikipedia.org/wiki/Markdown) or the format bar options to format your text. Click **Preview** above the comment box to see the text rendered with associated formats.
* On the right panel, click the gear icon in the **Assignee** (optional) box to add one or more Vantage users.
* For **Categories** (optional), select an option from the list. To add a new category, click **Manage Categories**. The Manage Categories screen is displayed in a new tab. You can add and delete categories from this screen.
* For **Linked Cost Reports** (optional), select an associated [Cost Report](/cost_reports) where the issue was identified.
* For **Estimated Savings Value** (optional), enter a monthly or annual estimated savings based on what you identified as the issue.
Click **Create issue**. The **Status** will now be **Open**. Users can comment on issues as well as close completed issues.
## Close and Reopen Issues
From the **Issues** list, select any issue.
At the bottom of the issue, click **Mark as Resolved**. The issue's **Status** is displayed as **Closed**.
From the Issues list, select the **Closed** tab.
Open any closed issue.
Click **Reopen Issue**. Issue subscribers, including assignees, will receive a notification that the issue was reopened.
## Receive Issue Notifications
You will receive email notifications in the following situations:
* When you're assigned to an issue, unless you created the issue or assigned it to yourself.
* When another user comments on an issue you've been assigned to, commented on, or subscribed to.
* When an issue you are assigned to or subscribed to is closed by another user.
* When an issue you are assigned to or subscribed to is reopened by another user.
To manually subscribe to an issue and receive notifications, open an existing issue. In the **Notifications** box, click **Subscribe**.
## Create Issues via Annotations
Issues are automatically created when you manually add an annotation to a Cost Report. Budget Alert annotations also have corresponding issues. Cost Alert annotations link back to the Cost Alert instead of showing a standard **Go to Issue** action. See the [Annotations documentation](/annotations#view-corresponding-issues) for more information.
# Jira
Source: https://docs.vantage.sh/jira
Learn how to integrate Vantage with Jira for issue tracking and management.
Jira is an issue-tracking and agile project management tool from Atlassian. With the Vantage–Jira integration, you can create Jira issues for Cost Anomalies, Budget Alerts, Cost Alerts, and Resource Reports, including Resource Reports for Cost Recommendations, directly in Vantage. You can also view the progress of the associated Jira issues directly within Vantage.
This integration is specifically for users on Jira Cloud (hosted by Atlassian). Jira Server integrations (self-hosted Jira) are not currently supported.
## How Vantage Connects with Jira
Vantage integrates with Jira via an OAuth workflow. To create an integration, you need to have the following Jira and Vantage roles:
* **Jira:** Jira users must have Admin access to install an application. See the [Atlassian App Integration](https://support.atlassian.com/jira-cloud-administration/docs/integrate-apps/) documentation for additional information.
* **Vantage:** Vantage users must have Organization Owner or Integration Owner access to create Jira issues within Vantage. See the [Role-Based Access Control](/rbac) documentation for information on user roles and permissions.
When you connect your Jira account with Vantage, the following required permissions are automatically requested during the OAuth workflow. No further action is needed on your part to set up these permissions.
| Access Type | Permission | Description |
| - | - | - |
| View | `jira-user`, `jira-work` | - View user information in Jira that the user has access to, including usernames, email addresses, and avatars. - Read Jira project and issue data, search for issues, and objects associated with issues like attachments and worklogs. |
| Update | `jira-work` | Create and edit issues in Jira, post comments as the user, create worklogs, and delete issues. |
At this time, you can integrate only a single Jira workspace into Vantage. In addition, you can integrate only a single Vantage subscription into a Jira workspace.
## Connect to Jira
Follow the steps below to connect to Jira.
From the top navigation of Vantage, click **Settings**.
On the side navigation, click **Integrations**. Any provider integrations are listed on this screen, as well as any connected apps.
Under **Apps**, select **Jira**.
Click **Connect Jira Account**.
If you are not already logged in to Jira, you will be prompted to log in. Once you are logged in to your account, the **App Authorization** Jira screen is displayed. Review the requested app permissions, and click **Accept**.
If you have multiple Jira instances available, you will be sent back to the Vantage console to select which instance you want to integrate. Click **Confirm** to select an instance.
Your Jira account instance will be synced with Vantage. Note that this sync might take some time, and you can monitor the status on the **Connection** page:
* The connection’s status is displayed as either **Connected**, **Syncing,** or **Unstable.** An Unstable status indicates that one of your configurations is no longer valid. For example, you may have deleted an issue type in Jira that is connected to a Vantage anomaly alert, budget alert, or Resource Report.
If you see an **Unstable** connection when you first connect, contact [support@vantage.sh](mailto:support@vantage.sh) for help with triaging this issue.
* At the top of the screen, the **Check for updates** button is displayed. Click this button if you add new projects in Jira, or if you create new issue types in Jira, to ensure they are synced with Vantage. In addition, if you add new users to your Jira instance and need to resync your user list for fields like **Reporter**, click this button to import those new users.
* All your projects will be listed, along with the connected account name.
* In the **Jira Issue Alert Configurations** section, each configured alert is listed along with its status. Click the pencil icon next to the alert to edit the configuration.
* A **Stable** status means the alert is working as expected.
* An **Unstable** status indicates that Vantage can no longer find one or more Jira fields that were previously selected as part of the issue criteria. This may happen if a project, issue type, or field value that Vantage originally imported from Jira has been deleted or is no longer available. To resolve this, edit the alert configuration and update the missing criteria.
### Remove Jira Integration
To remove a Jira integration, navigate to the [Jira Settings](https://console.vantage.sh/settings/jira) screen and click the trashcan icon next to the connected account you want to remove.
When you remove your Jira integration from Vantage:
* All links to your Jira integration will be removed from the Vantage console.
* Any Cost Report annotations that were created from budget alerts will persist in Vantage.
* Any issues that were created will persist in your Jira workspace.
## Create Jira Issues
You can create Jira issues based on Vantage budget alerts, cost anomalies, and Resource Reports. You can select which Jira project you want the issue sent to, as well as the issue type you want to create (e.g., Task, Bug).
At this time, the only way to have a Jira issue associated with an event in Vantage is if the ticket is created in or by Vantage. You cannot link to existing Jira issues.
### Alert Types That Support Jira
The matrix below shows which Vantage alert types support delivery to Jira (and to email, Slack, and Microsoft Teams for cross-reference).
| Alert Type | Email | Slack | Microsoft Teams | Jira | Configured From |
| - | :-: | :-: | :-: | :-: | - |
| [Cost Anomaly Alerts](/cost_anomaly_alerts) | Yes | Yes | Yes | Yes | A Cost Report's **Anomalies** tab > **Configure Alert** |
| [Cost Alerts](/cost_alerts) | Yes | Yes | Yes | Yes | A Cost Report's **...** menu > **Create Cost Alert**, or **Notifications** > **Cost Alerts** > **Configure Cost Alert** |
| [Budget Alerts](/budgets#budget-alerts) | Yes | Yes | Yes | Yes | A Budget's **Manage** tab > **Manage Alerts** > **Configure Alert** |
| [Report Notifications](/report_notifications) (Cost Reports) | Yes | Yes | Yes | — | The **Notifications** page > **New Notification** > **Cost Report Notification**, or a Cost Report's **...** menu > **Create Report Notification** |
| [Dashboard Notifications](/report_notifications#set-up-dashboard-notifications) | Yes | — | — | — | The **Notifications** page > **New Notification** > **Dashboard Notification** |
Slack and Microsoft Teams are mutually exclusive at the integration level: you can connect either Slack or Microsoft Teams, not both. See the [Slack](/slack) and [Microsoft Teams](/microsoft_teams) integration docs for setup. Jira delivery requires the [Jira integration](/jira).
For an explanation of Jira issue types, see the [Jira documentation](https://support.atlassian.com/jira-cloud-administration/docs/what-are-issue-types/).
### Budget Alerts
Budget alerts are automated alerts based on configurable budget thresholds. When you configure Jira delivery for a budget alert, Vantage creates a corresponding Jira issue each time the set budget threshold is reached.
Review the Vantage [Budget Alerts documentation](/budgets#budget-alerts) for more details on budget alerts.
Create a new budget alert. Enter all required budget alert criteria, such as **Threshold**.
Under **Setup App Alerts**, expand the **Jira Alerts** section.
Select the Jira **Project** where you want the issue to be created.
Select an **Issue Type** to indicate the type of Jira issue you want created. The **Issue Type** list is generated based on available issue types within your selected project and Jira instance. Additional required fields will also be displayed for the selected issue type (e.g., Reporter), based on your Jira setup. Any non-required Jira fields will not be displayed, and you can update these fields directly in Jira once the issue is created. Common examples are listed below:
* Bug
* Enter the corresponding bug Sprint ID, if required by your setup
* Story
* Epic
* Subtask
* Enter the Jira Parent task ID (e.g., `SCRUM-39`) for the subtask
* Task
Click **Save**.
Due to a technical limitation at this time, if an issue type requires you to select a team, that issue type will not be available in Vantage.
When a budget alert is triggered, the corresponding issue is generated in Jira. In the below visual example:
* A story issue type was created in Jira based on a budget alert that was triggered in Vantage.
* The **Description** contains the date when the alert was triggered, the associated Cost Report, and the name of the budget.
* An [annotation](/annotations) is added to the associated Vantage Cost Report for the date when the alert was triggered, and a link to the annotation is also provided in the Jira issue's description.
### Cost Anomaly Alerts
Cost anomaly alerts notify teams of excess costs and are identified via Cost Reports. When you configure Jira delivery for a cost anomaly alert, Vantage creates a corresponding Jira issue each time an alert is triggered for an individual service.
Review the Vantage [Cost Anomaly Alerts documentation](/cost_anomaly_alerts#configure-cost-anomaly-alerts) for more details on cost anomaly alerts.
Create a new cost anomaly alert. Enter all anomaly alert criteria, such as **Alert Threshold**.
Under **Setup App Alerts**, expand the **Jira Alerts** section.
Select the Jira **Project** where you want the issue to be created.
Select an **Issue Type** to indicate the type of Jira issue you want created. The **Issue Type** list is generated based on available issue types within your selected project and Jira instance. Additional required fields will also be displayed for the selected issue type (e.g., Reporter), based on your Jira setup. Any non-required Jira fields will not be displayed, and you can update these fields directly in Jira once the issue is created. Common examples are listed below:
* Bug
* Enter the corresponding bug Sprint ID, if required by your setup
* Story
* Epic
* Subtask
* Enter the Jira Parent task ID (e.g., `SCRUM-39`) for the subtask
* Task
Click **Save**.
Due to a technical limitation at this time, if an issue type requires you to select a team, that issue type will not be available in Vantage.
When a cost anomaly alert is triggered for a given service, the corresponding issue is generated in Jira. As shown in the image below, the Jira icon is also displayed to the right of the anomaly, with a link to the corresponding Jira issue.
In Jira, an issue is created, like the example below.
In this example:
* A story issue type was created based on an anomaly alert that was triggered for the Datadog Metrics service.
* The **Description** contains the date when the alert was triggered, the change in the dollar amount that caused this alert, and the associated Cost Report.
* A link to the anomaly is also provided.
### Resource Reports and Cost Recommendations
You can create Jira issues for any [Resource Report](/active_resources) in Vantage. For example, if [Cost Recommendations](/cost_recommendations#view-cost-recommendations) impact specific resources, you can generate a Resource Report to list the affected resources. From there, you can create a corresponding Jira issue in Vantage to assign to a stakeholder, which enables them to address tasks like rightsizing or reconfiguring the affected resources.
Unlike Jira issues related to cost anomalies or budget alerts, you will be creating one issue for the report.
Review the Vantage [Resource Reports documentation](/active_resources) for more details on Resource Reports.
From the top right of a *saved* Resource Report, click the Jira icon.
From the dropdown list, select a **Project**.
Select an **Issue Type** to indicate the type of Jira issue you want created. The **Issue Type** list is generated based on available issue types within your selected project and Jira instance. Additional required fields will also be displayed for the selected issue type (e.g., Reporter), based on your Jira setup. Any non-required Jira fields will not be displayed, and you can update these fields directly in Jira once the issue is created. Common examples are listed below:
* Bug
* Enter the corresponding bug Sprint ID, if required by your setup
* Story
* Epic
* Subtask
* Enter the Jira Parent task ID (e.g., `SCRUM-39`) for the subtask
* Task
Due to a technical limitation at this time, if an issue type requires you to select a team, that issue type will not be available in Vantage.
Click **Create Ticket**.
A new issue will be created within the selected Jira project. The issue contains information on the person who created the issue in Vantage, the Resource Report name, and a link to the Resource Report. For Resource Reports generated from Cost Recommendations, additional information about the report is also provided, like total costs, number of affected resources, and potential monthly savings.
After the issue is created, to access the corresponding Jira issue from the Resource Report, click the Jira icon on the top right of the report.
### Cost Alerts
Cost Alerts automatically detect and notify you of cost increases—whether by percentage or fixed amount—across customizable time periods, like day-over-day, month-over-month, or quarter-over-quarter. When you configure Jira delivery for a Cost Alert, Vantage creates a corresponding Jira issue each time the alert is triggered.
Review the Vantage [Cost Alerts documentation](/cost_alerts) for more details on Cost Alerts.
Create a new Cost Alert. Enter all required alert criteria, such as dollar or percentage **Threshold**.
Under **Setup App Alerts**, expand the **Jira Alerts** section.
Select the Jira **Project** where you want the issue to be created.
Select an **Issue Type** to indicate the type of Jira issue you want created. The **Issue Type** list is generated based on available issue types within your selected project and Jira instance. Additional required fields will also be displayed for the selected issue type (e.g., Reporter), based on your Jira setup. Any non-required Jira fields will not be displayed, and you can update these fields directly in Jira once the issue is created. Common examples are listed below:
* Bug
* Enter the corresponding bug Sprint ID, if required by your setup
* Story
* Epic
* Subtask
* Enter the Jira Parent task ID (e.g., `SCRUM-39`) for the subtask
* Task
Click **Save**.
Due to a technical limitation at this time, if an issue type requires you to select a team, that issue type will not be available in Vantage.
When a Cost Alert is triggered, the corresponding issue is generated in Jira. This issue includes an alert description, along with the date when the alert was triggered, the associated Cost Report, and the name of the Cost Alert. An [annotation](/annotations) is automatically added to the associated Cost Report on the date the alert is triggered, even if Jira notifications are not enabled. If a Jira issue is created as part of the alert, a link to the ticket will also appear in the annotation.
## Jira Issue Statuses in Vantage
You can see a Jira issue's status in Vantage. Issue statuses are updated once a day. Therefore, a change that is made today (e.g., changing an issue's status in Jira from "To Do" to "In Progress") might not be reflected in Vantage until tomorrow.
Next to the Jira icon, a badge is displayed.
| Badge | Description |
| - | - |
|  | The corresponding Jira issue is currently in the Jira "To Do" status. |
|  | The corresponding Jira issue is currently in the Jira "In Progress" status. |
|  | The corresponding Jira issue is currently in the Jira "Done" status. |
|  | Vantage has not received a status update yet from Jira. It can take a day from the time when a corresponding Jira issue was created by Vantage to update this status. |
These status badges are displayed next to the Jira icon in the following locations:
* Next to each cost anomaly with a corresponding Jira issue in the cost anomaly list
* On any Cost Report annotations for Budget Alerts or Cost Alerts that created a Jira issue
* At the top of a Resource Report with a corresponding Jira issue
# Kubernetes Costs and Efficiency Metrics
Source: https://docs.vantage.sh/kubernetes
Learn how to view Kubernetes costs and efficiency metrics in Vantage.
Vantage has two sets of tools for viewing and optimizing Kubernetes costs: viewing Kubernetes costs in [Cost Reports](/cost_reports) and viewing Kubernetes efficiency metrics in the dedicated [Kubernetes page](https://console.vantage.sh/kubernetes) in the console.
* **Kubernetes Cost Reports.** Use Cost Reports to drill into costs by Cluster, Namespace, Service, and Label, as well as combine Kubernetes costs with other providers, such as a database or cache layer.
* **Kubernetes Efficiency Metrics and Reports.** Display the cost efficiency down to the pod level of a cluster. These metrics are useful for rightsizing and cost optimization. You can also create efficiency reports based on these metrics.
## Kubernetes Cost Reports
Kubernetes Cost Reports provide cost visibility by Cluster, Label, Namespace, and Service. They include Kubernetes-specific filters and filter logic. You can combine specific Kubernetes costs with other services. In the below example, the filter includes the costs of a specific service with corresponding RDS database costs.
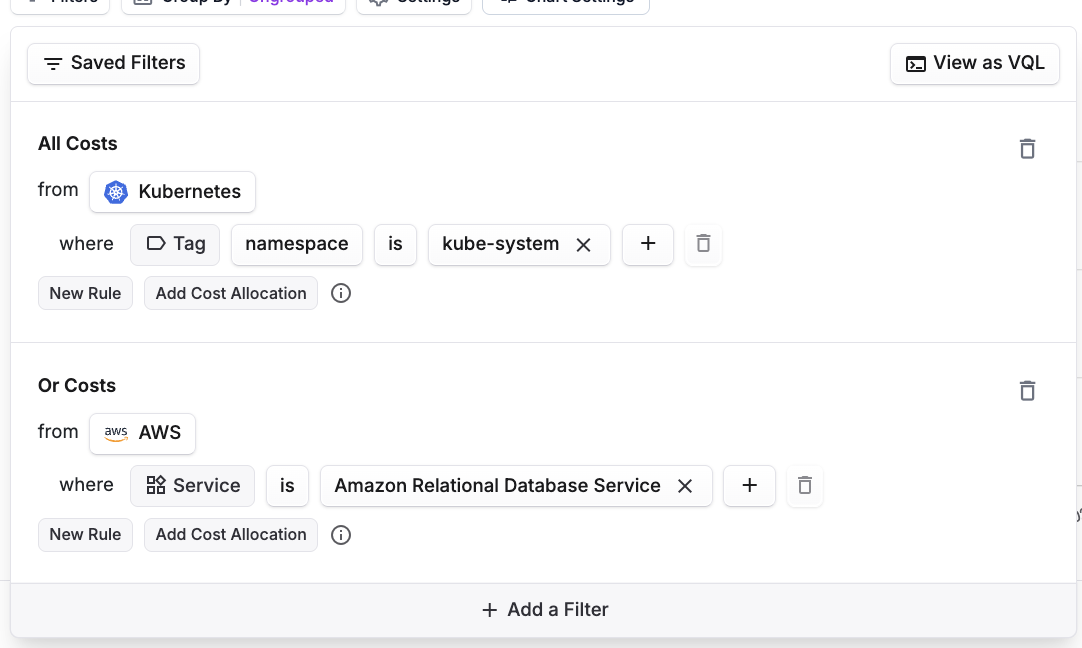
Cost Reports also provide [forecasts](/forecasting). These forecasts are updated daily and provide confidence intervals for what your costs are likely to be for the month.
To avoid double counting costs in Cost Reports when using the Vantage Kubernetes agent alongside your primary cloud provider (e.g., AWS, Azure, GCP), see the [Avoid Double Counting Costs in Cost Reports](/kubernetes#avoid-double-counting-costs-in-cost-reports) section below.
### Additional Kubernetes Filters
Vantage provides advanced filtering and grouping options for Kubernetes Cost Reports and Efficiency Reports. These additional filters help you more accurately allocate and optimize Kubernetes spend.
#### Filter by CPU, RAM, Storage, and GPU
On Kubernetes Cost Reports, you can also group and filter to see costs by CPU, RAM, storage, and GPU. To filter by these categories:
Create a new Kubernetes Cost Report.
Add the following filter:
* For example, to filter by CPU: All costs from **Kubernetes** where **Tag** **vntg:category** is **cpu**
#### Filter by Network Costs
If you have enabled [Kubernetes Network Cost Attribution](/kubernetes_network_costs), pod-level network costs are also available on Cost Reports. To isolate network costs, filter the **Kubernetes** provider by **Category** and select **network** (filtering by the **Tag** **vntg:category** is **network** also works). You can then group by **Subcategory** to break costs down by network destination (Intra-Zone Egress, Intra-Region Egress, Cross-Region Egress, Internet Egress, and more), or group by a [Virtual Tag](/tagging) to roll network spend up to the owning team or application. See the [Kubernetes Network Cost Attribution documentation](/kubernetes_network_costs) for setup and configuration details.
#### Filter by PVC and Node Labels
PVC and Node Labels are [key-value tags](https://kubernetes.io/docs/concepts/overview/working-with-objects/labels/) in Kubernetes. [PVC](https://kubernetes.io/docs/concepts/storage/persistent-volumes/) Labels tag storage for filtering and grouping. [Node](https://kubernetes.io/docs/concepts/architecture/nodes/) Labels tag compute nodes to help with scheduling and analysis. You can use them to help you understand and filter usage by things like team, app, or environment.
In addition to standard Kubernetes metadata, like Cluster, Namespace, and Label, Vantage also supports filtering and grouping by Persistent Volume Claim (PVC) Label and Node Label. These labels are collected by the Vantage Kubernetes agent and appear as [tags](/tagging). These tags are denoted by a tag value of `pvc:xyz` for PVCs and `node:xyz` for Nodes.
Node Labels are collected by default with the Vantage Kubernetes agent. See the [Vantage Kubernetes agent documentation](/kubernetes_agent#optional-enable-collection-of-pvc-labels) for information on how to configure the collection of PVC Labels.
By using PVC labels in reporting, which are applied to volume stores, you can attribute storage usage with Kubernetes workloads by app or team, perform cost allocation for storage, and perform targeted storage optimization. Node Labels are applied to underlying compute hosts and can be used to attribute compute costs based on infrastructure characteristics, track usage across node pools or environments, and identify optimization opportunities.
Kubernetes storage cost rows also include the workload **Namespace** as a tag, so storage spend rolls up to the owning namespace when you group or filter Kubernetes Cost Reports by Namespace.
* PVC Labels are collected from persistent volume claims associated with pods.
* Node Labels are collected from the nodes where pods are scheduled.
In addition to Cost Reports, PVC and Node Labels can also be used in [Virtual Tags](/tagging) to define custom cost allocation dimensions for things like team, environment, application, or storage. Node Labels can also be used in Kubernetes Efficiency Reports; however, PVC Labels cannot be used on these reports.
### Cost Data Source
The costs displayed on these reports come from your integration with the [Vantage Kubernetes agent](/kubernetes_agent). The agent calculates the cost of a running pod by analyzing the CPU, RAM, GPU, as well as storage usage and calculates the cost of each input based on the cost of the underlying infrastructure. When [Kubernetes Network Cost Attribution](/kubernetes_network_costs) is enabled, the agent also attributes per-pod network costs and includes them on these reports.
[Vantage uses a formula](/kubernetes#efficiency-calculations) to divide the cost of a compute instance into CPU, RAM, and GPU and then computes the cost for each type of resource. The cost calculation reflects the exact runtime of each pod, down to the minute. This means if a pod runs for only 5 minutes within an hour, Vantage recognizes only 5 minutes of spend, rather than the full hour. All the cost allocation calculations are done locally in your cluster and make this data available for querying.
Kubernetes costs are not included in monthly tracked infrastructure costs as they're already captured from underlying EKS, GKE, AKS, or OKE costs.
## Kubernetes Efficiency Metrics and Reports
The below sections describe how to view and create Kubernetes Efficiency Metrics and Reports.
### Discounts on Efficiency Reports
CPU/memory rates are based on the underlying instances the pod is scheduled on. In Kubernetes Efficiency Reports, this is the undiscounted rate of the instance. Discounts are not reflected on these reports due to the variable nature of how discounts are applied, making it difficult to make comparisons over time. You can view discounts on Kubernetes [Cost Reports](/cost_reports).
### View Kubernetes Efficiency Metrics
Navigate to the [Kubernetes page](https://console.vantage.sh/kubernetes) in the Vantage console.
On the left navigation menu, select an option to view connected **Clusters**, **Namespaces**, or **Labels**. Each view contains a graph as well as a table with the following headings:
* **Name:** The name of the Cluster, Namespace, or Label you're viewing.
* **Idle Costs:** A dollar value representation of the number of resources requested that are idle.
* **Total Costs:** A dollar value representation of the total cost of the resources.
* **Cost Efficiency:** The ratio of idle costs and total costs.
Filter a cluster's efficiency metrics by date or resource:
* From the top right of the graph, change the date range to see how costs have changed over time.
* From the resource list below each chart, click the icons next to each resource to view different aggregations. Click the **View on chart** button to isolate that specific resource on the chart.
### Create Efficiency Reports
With Kubernetes efficiency reports, you can filter your Kubernetes cost data and create reports based on these filters. You have the option to filter for costs by Cluster, Namespace, Region, or Label.
Labels will include namespace labels and annotations if enabled in your [Vantage Kubernetes agent integration](/kubernetes_agent#enable-collection-of-annotations-and-namespace-labels).
Navigate to the [Kubernetes page](https://console.vantage.sh/kubernetes) in the Vantage console.
On the left navigation menu, select **Efficiency Reports**. All existing Kubernetes efficiency reports will be listed, along with who created the report as well as the date when the report was created.
From the top right of the screen, click **New Report**. Like the efficiency metrics view, a chart/graph with idle costs is displayed. Below the chart, a table is displayed with the following columns: the resource's name, **Idle Costs**, **Total Costs**, and **Cost Efficiency**.
To filter costs, click the **Filters** button on the top left of the chart.
* The **Kubernetes costs where...** tile is displayed. Click **+ New Rule**.
* From the filter dropdown menu, select either **Cluster**, **Namespace**, **Region**, **Category** (cpu, ram, or gpu) or **Label**.
See the [section below](/kubernetes#kubernetes-gpu-idle-costs) for information on how to enable GPU metrics.
You can also filter by Node Labels, which are collected by the Vantage Kubernetes agent and appear as label filters in the format `node:xyz`. Note that PVC Labels are not available for filtering on these reports. Kubernetes Efficiency Reports provide detail into the usage, efficiency, and cost of the underlying compute resources of Kubernetes Workloads. These reports do not include reporting on attached volume storage, where PVC Labels are applied. To report on both compute and storage resources, use Cost Reports.
* Two additional dropdown menus are displayed. Select **is** or **is not** based on your desired filter criteria, then select one or more Clusters, Namespaces, or Labels from the second dropdown menu.
* Click **Save**.
You can optionally edit your existing rule or add additional filter criteria.
* To edit the rule you just created, select the rule, make your changes, and click **Save**.
* If you want to add a rule to filter multiple criteria, such as filter by certain Clusters and another rule to filter by certain Namespaces, click **+ New Rule**. Add the additional criteria and save.
* To add a separate rule set, click **+ New Filter**. This rule set will be displayed as **Or Kubernetes costs where...** on the new tile.
* To delete a rule set, click the trashcan icon on the top right of the rule set.
Above the rule set(s), click **Apply**. The graph will update with your existing filter criteria.
You have the option to further drill down into your costs.
* Above the graph, click the **Aggregate By** dropdown menu. Select either **Idle Costs** or **Total Costs**.
Selecting one of these options will also make those costs the default sort for the table.
* To adjust aggregation dimensions, above the graph, click the **Group By** dropdown menu. Select one or more of the following options: **Cluster**, **Namespace**, **Region**, and specific **Label Key**/**Label Value**.
* To adjust the date binning, select the menu on the top right of the graph. Select either **Daily**, **Weekly**, or **Monthly**.
* To change the date range, click the date picker menu on the top right of the graph and adjust the date range.
To save the report, click **Save as New** and enter a report name. Then, click **Save**. (To edit this name, click the pencil icon in the breadcrumbs above the chart, next to the report's name.)
You can edit the filter criteria on a report at any time. Remember to click **Save** once you are done making changes.
### Add an Efficiency Report to a Dashboard
You can add your efficiency reports to [dashboards](/dashboards). These reports will be displayed on the dashboard, along with other Cost Reports.
From the top navigation, click **Reporting**.
From the side navigation, click **Dashboards**.
Select an existing dashboard, or click **+ New** to create a new dashboard.
* If you are creating a new dashboard:
* Enter a **Name**.
* Under **Add Reports**, find and select your Kubernetes efficiency report.
* Click **Save**.
* If you want to add the report to an existing dashboard:
* From the top right of the existing dashboard, click **Edit**.
* Under **Add Reports**, find your efficiency report.
* Click **Save**.
## Export Kubernetes Efficiency Reports
You can export your Kubernetes Efficiency Report as a CSV file for viewing outside the console.
From the top right of any Kubernetes Efficiency Report, click the download icon (looks like an arrow with a line below it).
Select any **Groupings** that you want added as additional columns in the report (e.g., Cluster, Namespace). In addition, you can specify any **Labels** you want included.
Select a date range and **Date Bin** for the report.
Select or enter the emails for any users who you want to receive an emailed copy of the report.
Email recipients must be users in your Vantage organization.
Click **Export**.
For the **Date Bin** export option, when you select **Week**, the week in the export will begin on Monday, UTC. When you select **Month**, the month in the export will begin on the first of the month, UTC.
When the export is finished generating, you'll receive an email with a link to download the exported data, typically within a few minutes.
### Efficiency Calculations
Pod resource efficiency is defined as the resource utilization versus the resource request over a given time window, prorated based on node uptime. These resource utilization metrics include CPU and RAM. When viewing efficiency, it will be shown as a percentage. 100% means the resource allocation is fully efficient.
Idle costs are defined as the difference between the cost of requested resources (CPU and Memory) and the associated usage of those costs:
$$
\begin{aligned}
\text{idle\_cost} = {} & (\text{cpu\_request\_cost} - \text{cpu\_usage\_cost}) \\
& + (\text{memory\_request\_cost} - \text{memory\_usage\_cost})
\end{aligned}
$$
## Understanding the `__idle__` Namespace in Kubernetes Efficiency Reports
When analyzing Kubernetes costs in Vantage, the `__idle__` namespace represents the unallocated portion of nodes per hour, providing insight into overall cluster efficiency. The `__idle__` namespace is included in total cluster costs.
As of March 2025, the `__idle__` namespace is enabled by default for new integrations. Existing integrations that have not already done so can contact [support@vantage.sh](mailto:support@vantage.sh) to have the namespace enabled.
To view `__idle__` namespace costs, set the report's **Group By** criteria to **Namespace**. In many cases, `__idle__` ranks among the top namespaces in terms of cost. It highlights unused capacity in your cluster and helps identify opportunities for workload optimization.
`__idle__` is calculated as the difference between a node's total capacity and the sum of allocated pod resources. For example, if a node has:
* **Total capacity:** `8 CPU / 16 GB RAM`
* **Pod usage:** `8 CPU / 6 GB RAM`
Then the unallocated resources assigned to `__idle__` are:
$$
\text{Idle RAM} = 16 - 6 = 10 \text{ GB}
$$
The sum of allocated pod costs and `__idle__` costs should closely approximate total compute costs for the cluster. Minor discrepancies may occur due to hourly allocation calculations, such as multiple pods running at different times within an hour. In addition, if a node is fully allocated for a short period but mostly idle throughout an hour, `__idle__` may not reflect partial usage, leading to some variation in reported costs.
## Kubernetes GPU Idle Costs
For each Kubernetes pod, you can view the idle and total costs for NVIDIA GPU usage within a Kubernetes cluster. GPU memory usage is available on Kubernetes efficiency reports as an option for the **Category** filter and is included in the cost efficiency score per pod.
To see overall cluster idle for GPU memory, group your Kubernetes Efficiency Report by namespace. The `__idle__` namespace is displayed, which includes the idle GPU costs.
### How GPU Idle Costs Are Calculated
When an instance includes GPUs, 95% of the cost of the node will be allocated to the memory of the GPU. The number of GPUs requested by the pod will dictate how much of the total memory is allocated to the pod. Idle costs for allocated GPUs are determined by calculating the difference between the total allocated and the total used memory for the pod, down to the container level:
$$
\text{idle\_memory} = \text{total\_allocated\_memory} - \text{used\_memory}
$$
GPU *utilization* is not factored into the efficiency calculation; only GPU memory is tracked. If you have a workload that requires tracking GPU utilization, contact [support@vantage.sh](mailto:support@vantage.sh).
Whole GPU requests and single-strategy NVIDIA MIG device requests are supported. Mixed-strategy MIG is not currently supported. See [NVIDIA Multi-Instance GPU (MIG) Accounting](/kubernetes#nvidia-multi-instance-gpu-mig-accounting) below.
### NVIDIA Multi-Instance GPU (MIG) Accounting
[NVIDIA Multi-Instance GPU (MIG)](https://docs.nvidia.com/datacenter/tesla/mig-user-guide/) partitions a physical GPU into several smaller, isolated GPU devices. Under the `single` MIG strategy, every device on a node is the same size, and a pod still requests `nvidia.com/gpu: 1` even though it receives one MIG device rather than an entire GPU.
Vantage allocates each requested MIG device a proportional share of the physical GPUs your provider bills you for:
$$
\text{gpu\_allocation} = \text{requested\_devices} \times \frac{\text{physical\_gpus}}{\text{mig\_devices}}
$$
`physical_gpus` comes from your provider's instance type metadata. `mig_devices` comes from the `nvidia.com/gpu.count` node label published by GPU Feature Discovery, which reports the number of MIG devices on the node rather than the number of physical GPUs.
For example, a node with one physical GPU partitioned into two MIG devices reports `nvidia.com/gpu.count=2`, so each device is allocated half of the physical GPU:
$$
\text{gpu\_allocation per device} = \frac{1 \text{ physical GPU}}{2 \text{ MIG devices}} = 0.5
$$
If a single pod occupies one of those two devices for 24 hours, Vantage reports:
* **Pod:** `12` GPU-Hours and half the node's GPU cost
* **`__idle__`:** `12` GPU-Hours and the other half
The unoccupied device is unallocated node capacity, so it rolls up into the `__idle__` namespace. If a second pod occupies the other device, each pod reports `12` GPU-Hours and `__idle__` reports none. In both cases, allocated and idle GPU costs reconcile to the node's physical GPU cost. Without MIG accounting, the first pod alone would report `24` GPU-Hours and the node's full GPU cost, leaving no idle GPU capacity to report.
The same ratio applies to nodes with several physical GPUs. For example, a node with 8 physical GPUs partitioned into 16 MIG devices allocates `0.5` physical GPUs per requested device. Discounted GPU costs use the same fractional allocation.
On MIG nodes, the `GPU-Hours` usage unit measures physical GPU-hours, not MIG device-hours. A pod that runs on one of two MIG devices for an hour reports `0.5` GPU-Hours.
#### MIG Accounting Requirements
MIG accounting is applied automatically when all of the following are true:
* The node uses the `single` MIG strategy, published as the `nvidia.com/mig.strategy=single` node label. The `mixed` strategy, where devices on the same node can use different profiles and pods request named resources such as `nvidia.com/mig-1g.10gb`, is not currently supported.
* [GPU Feature Discovery](/kubernetes_agent#step-3-enable-gpu-feature-discovery-for-mig-nodes) publishes the `nvidia.com/gpu.count` and `nvidia.com/gpu.memory` node labels describing the node's MIG devices.
* Vantage can determine the node's physical GPU count from provider pricing data. See [MIG Provider Support](/kubernetes#mig-provider-support).
* The node's physical GPU count is lower than its MIG device count.
Nodes that do not meet all of these conditions keep whole-GPU accounting, where each requested device is treated as one full physical GPU.
#### MIG Provider Support
MIG accounting is supported on Amazon EKS and Azure AKS nodes. Vantage reads the physical GPU count from provider pricing data for the node's instance type, such as the GPU count for an Amazon EC2 instance type in the AWS Cost and Usage Report. It can't use the GPU count the cluster advertises, because on a MIG node that count reflects MIG devices rather than physical GPUs.
Other nodes keep whole-GPU accounting. If you run MIG on other node types, contact [support@vantage.sh](mailto:support@vantage.sh).
MIG accounting adjusts GPU cost allocation, GPU-Hours usage, and `__idle__` GPU capacity. It does not change GPU efficiency. Efficiency continues to compare used GPU memory against the GPU memory allocated to the pod, so efficiency percentages and the per-pod GPU idle cost on Kubernetes Efficiency Reports are unaffected by the allocation above.
To confirm Vantage sees your MIG configuration, open a Kubernetes Cost Report and group by the `node:nvidia.com/mig.strategy` and `node:nvidia.com/gpu.count` tags. The Vantage Kubernetes agent forwards NVIDIA node labels automatically, so they are available as `node:` tags without additional configuration.
### Configure GPU Metrics
The Vantage Kubernetes agent automatically collects GPU usage information via the [NVIDIA DCGM Exporter](https://docs.nvidia.com/datacenter/cloud-native/gpu-telemetry/latest/index.html). The exporter is included as part of the [NVIDIA GPU Operator](https://docs.nvidia.com/datacenter/cloud-native/gpu-operator/latest/overview.html), but it can also be installed independently. The agent scrapes the exporter directly and exposes the configuration for the namespace, service name, port name, and path. The default values are configured for the GPU operator default case.
Vantage supports GPU cost monitoring for Kubernetes workloads. The setup process differs depending on your cloud provider:
* **AWS and Azure**: GPU costs are automatically calculated from native cloud billing data combined with DCGM exporter metrics. See the [Configure GPU Metrics](/kubernetes_agent#configure-gpu-metrics) section in the Kubernetes Agent documentation for setup instructions.
* **Neocloud providers** (DigitalOcean, CoreWeave, Nebius, etc.): GPU costs use annotation-based pricing similar to on-premises clusters. See the [Enable Neocloud GPU Support](/kubernetes_agent#enable-neocloud-gpu-support) section in the agent documentation.
For Azure customers, all GPU-enabled VM families used in AKS are supported, including NC-series (general-purpose), ND-series (deep learning optimized), and NV-series (visualization and graphics workloads). GPU counts are refreshed regularly from Azure APIs to ensure accuracy, and new instance types are added automatically without manual intervention.
### View GPU Costs
GPU costs are available in different reporting surfaces depending on the available allocation, pricing, and usage data:
* **Cost Reports**: Filter and group by cluster, namespace, or labels to view GPU costs alongside other infrastructure costs when GPU allocation and pricing data are available
* **Kubernetes Efficiency Reports**: After GPU metrics are configured, filter by `Category = gpu` to see GPU idle and total costs by cluster, namespace, or pod
* **Virtual Tags**: Use GPU costs for cost allocation and chargeback
GPU costs can appear in Cost Reports even when the `gpu` category is not available in Kubernetes Efficiency Reports. Cost Reports can show GPU costs based on a pod's requested GPU allocation and the underlying billing or pricing data. Kubernetes Efficiency Reports require GPU memory usage metrics from the NVIDIA DCGM Exporter to calculate idle and used GPU memory. If those metrics are not being collected, GPU costs may be omitted from Efficiency Reports until GPU metrics collection is configured.
## Kubernetes Rightsizing Recommendations
Vantage syncs Kubernetes managed workloads as [active resources](/active_resources) in your account. In cases where any of these workloads are identified to be overprovisioned, Vantage provides Kubernetes rightsizing recommendations. On the **Kubernetes Efficiency Reports** screen, a notification is displayed when rightsizing recommendations are available. Click **Review Recommendations** to view identified workloads.
See the [Cost Recommendations](/cost_recommendations#kubernetes-rightsizing-recommendations) documentation for details on how to view this information and rightsize Kubernetes workloads.
## Kubernetes Integration Method: The Vantage Kubernetes Agent
Agent usage data is uploaded several times throughout the day and updated within the Vantage platform nightly. However, Kubernetes costs will not be calculated until the costs from the cluster's corresponding infrastructure provider are available. These costs might encounter delays based on their associated cloud integration's cost data. For instance, if there is a one-day delay in an AWS Cost and Usage Report, the clusters dependent on that data will experience a similar delay. This often takes 48 hours to complete.
## Avoid Double Counting Costs in Cost Reports
When using the Vantage Kubernetes agent alongside your primary cloud provider (e.g., AWS, Azure, GCP), it's important to ensure that costs are not double counted in your Cost Reports. The Kubernetes agent provides granular cost allocation at the pod, namespace, and cluster level, but these costs are derived from the underlying infrastructure costs that are already captured by your primary cloud provider. If you filter both by a primary provider (e.g., AWS) and Kubernetes, those costs will be double counted. Follow the steps below.
The same double-counting applies to network spend if you have enabled [Kubernetes Network Cost Attribution](/kubernetes_network_costs). Pod-level network costs are re-derived from your provider's data transfer and NAT gateway charges. Removing the overlap is only approximate, though: these line items usually aren't tagged with the cluster, so excluding them also removes network spend from non-Kubernetes workloads, while excluding nothing leaves the double count in place. Choose whichever approximation better fits your reporting.
Determine whether your Kubernetes deployment uses:
* Managed Kubernetes Service (i.e., EKS, AKS, GKE, OKE)
* Self-hosted Kubernetes (e.g., EC2 instances, virtual machines, bare metal)
This distinction is important because it determines how costs are reported and what needs to be filtered out.
* Filter by cluster name tags: Cloud providers automatically tag resources with cluster names (e.g., for AWS `aws:eks:cluster-name`)
* Use node label tags: These are applied to [underlying compute hosts](/kubernetes#filter-by-pvc-and-node-labels) and can be used to attribute compute costs based on infrastructure characteristics
* Use customer-applied tags: Rely on [tags](/tagging) you've manually applied to identify Kubernetes nodes
* Use node ARNs or instance IDs: Filter by the specific ARN of the underlying compute instances or by the specific instance IDs running your Kubernetes workloads (Resource ID filter in Cost Reports)
When replacing cloud provider costs with Kubernetes agent costs, include **idle costs** to ensure an accurate comparison:
* The cloud provider bills you for the entire node, regardless of utilization
* The Kubernetes agent breaks down costs by actual usage (pods, namespaces, etc.)
* The [`__idle__` namespace](/kubernetes#understanding-the-idle-namespace-in-kubernetes-efficiency-reports) is the difference between a node's total capacity and the sum of allocated pod resources
* To get a close comparison, include both the allocated costs and the idle costs from the Kubernetes agent
### Troubleshooting Cost Discrepancies
If your costs don't match between the Kubernetes agent and cloud provider data, consider the following options:
* **Check polling intervals**: The agent [polls every 60 seconds by default](/kubernetes_agent#configure-polling-interval), but cloud providers may have different billing granularity. EKS is billed by the second, so short-lived pods may show different costs.
* **Verify instance mapping**: Ensure the `node:provider_id` tag correctly maps Kubernetes nodes to cloud provider instances. You can group by this tag in [Cost Reports](/cost_reports) to cross-reference specific instances. This tag is available for filtering and grouping in Cost Reports (e.g., **where** Tag `node:provider_id` is).
* **Account for storage costs**: Use [PVC labels](/kubernetes#filter-by-pvc-and-node-labels) to track storage costs separately.
* **Consider purchase options**: The Kubernetes agent uses on-demand pricing for consistency, while your actual costs may include Reserved Instances or Savings Plans. This is intentional to provide [apples-to-apples comparisons](/kubernetes#discounts-on-efficiency-reports).
* **Include idle costs**: Ensure you're including the [`__idle__` namespace](/kubernetes#understanding-the-idle-namespace-in-kubernetes-efficiency-reports) when comparing total costs between sources.
# Vantage Kubernetes Agent
Source: https://docs.vantage.sh/kubernetes_agent
Learn how to set up and configure the Vantage Kubernetes agent.
The Vantage Kubernetes agent is the default, recommended configuration to ingest cost and usage data from Kubernetes clusters to Vantage. The agent is a Docker container that runs in your Kubernetes cluster. The agent collects metrics and uploads them to Vantage.
A primary provider (e.g., AWS, Azure, GCP, or Oracle) is required to connect Kubernetes costs. If you have on-premises costs you want to track, see the [Enable On-Premises Support](/kubernetes_agent#enable-on-premises-support) section below.
## Agent Functionality
The Vantage Kubernetes agent relies on native Kubernetes APIs, such as `kube-apiserver` for metadata and `kubelet` for container data. Access to these APIs is controlled via Kubernetes RBAC using a Service Account and ClusterRole included in the Vantage Kubernetes agent [Helm chart](https://github.com/vantage-sh/helm-charts).
Data is periodically collected and stored for aggregation, then sent directly to the Vantage service through an API, with your Vantage API token for authentication. Because the agent does not require dedicated Prometheus pods, it avoids the associated storage costs and scales more easily.
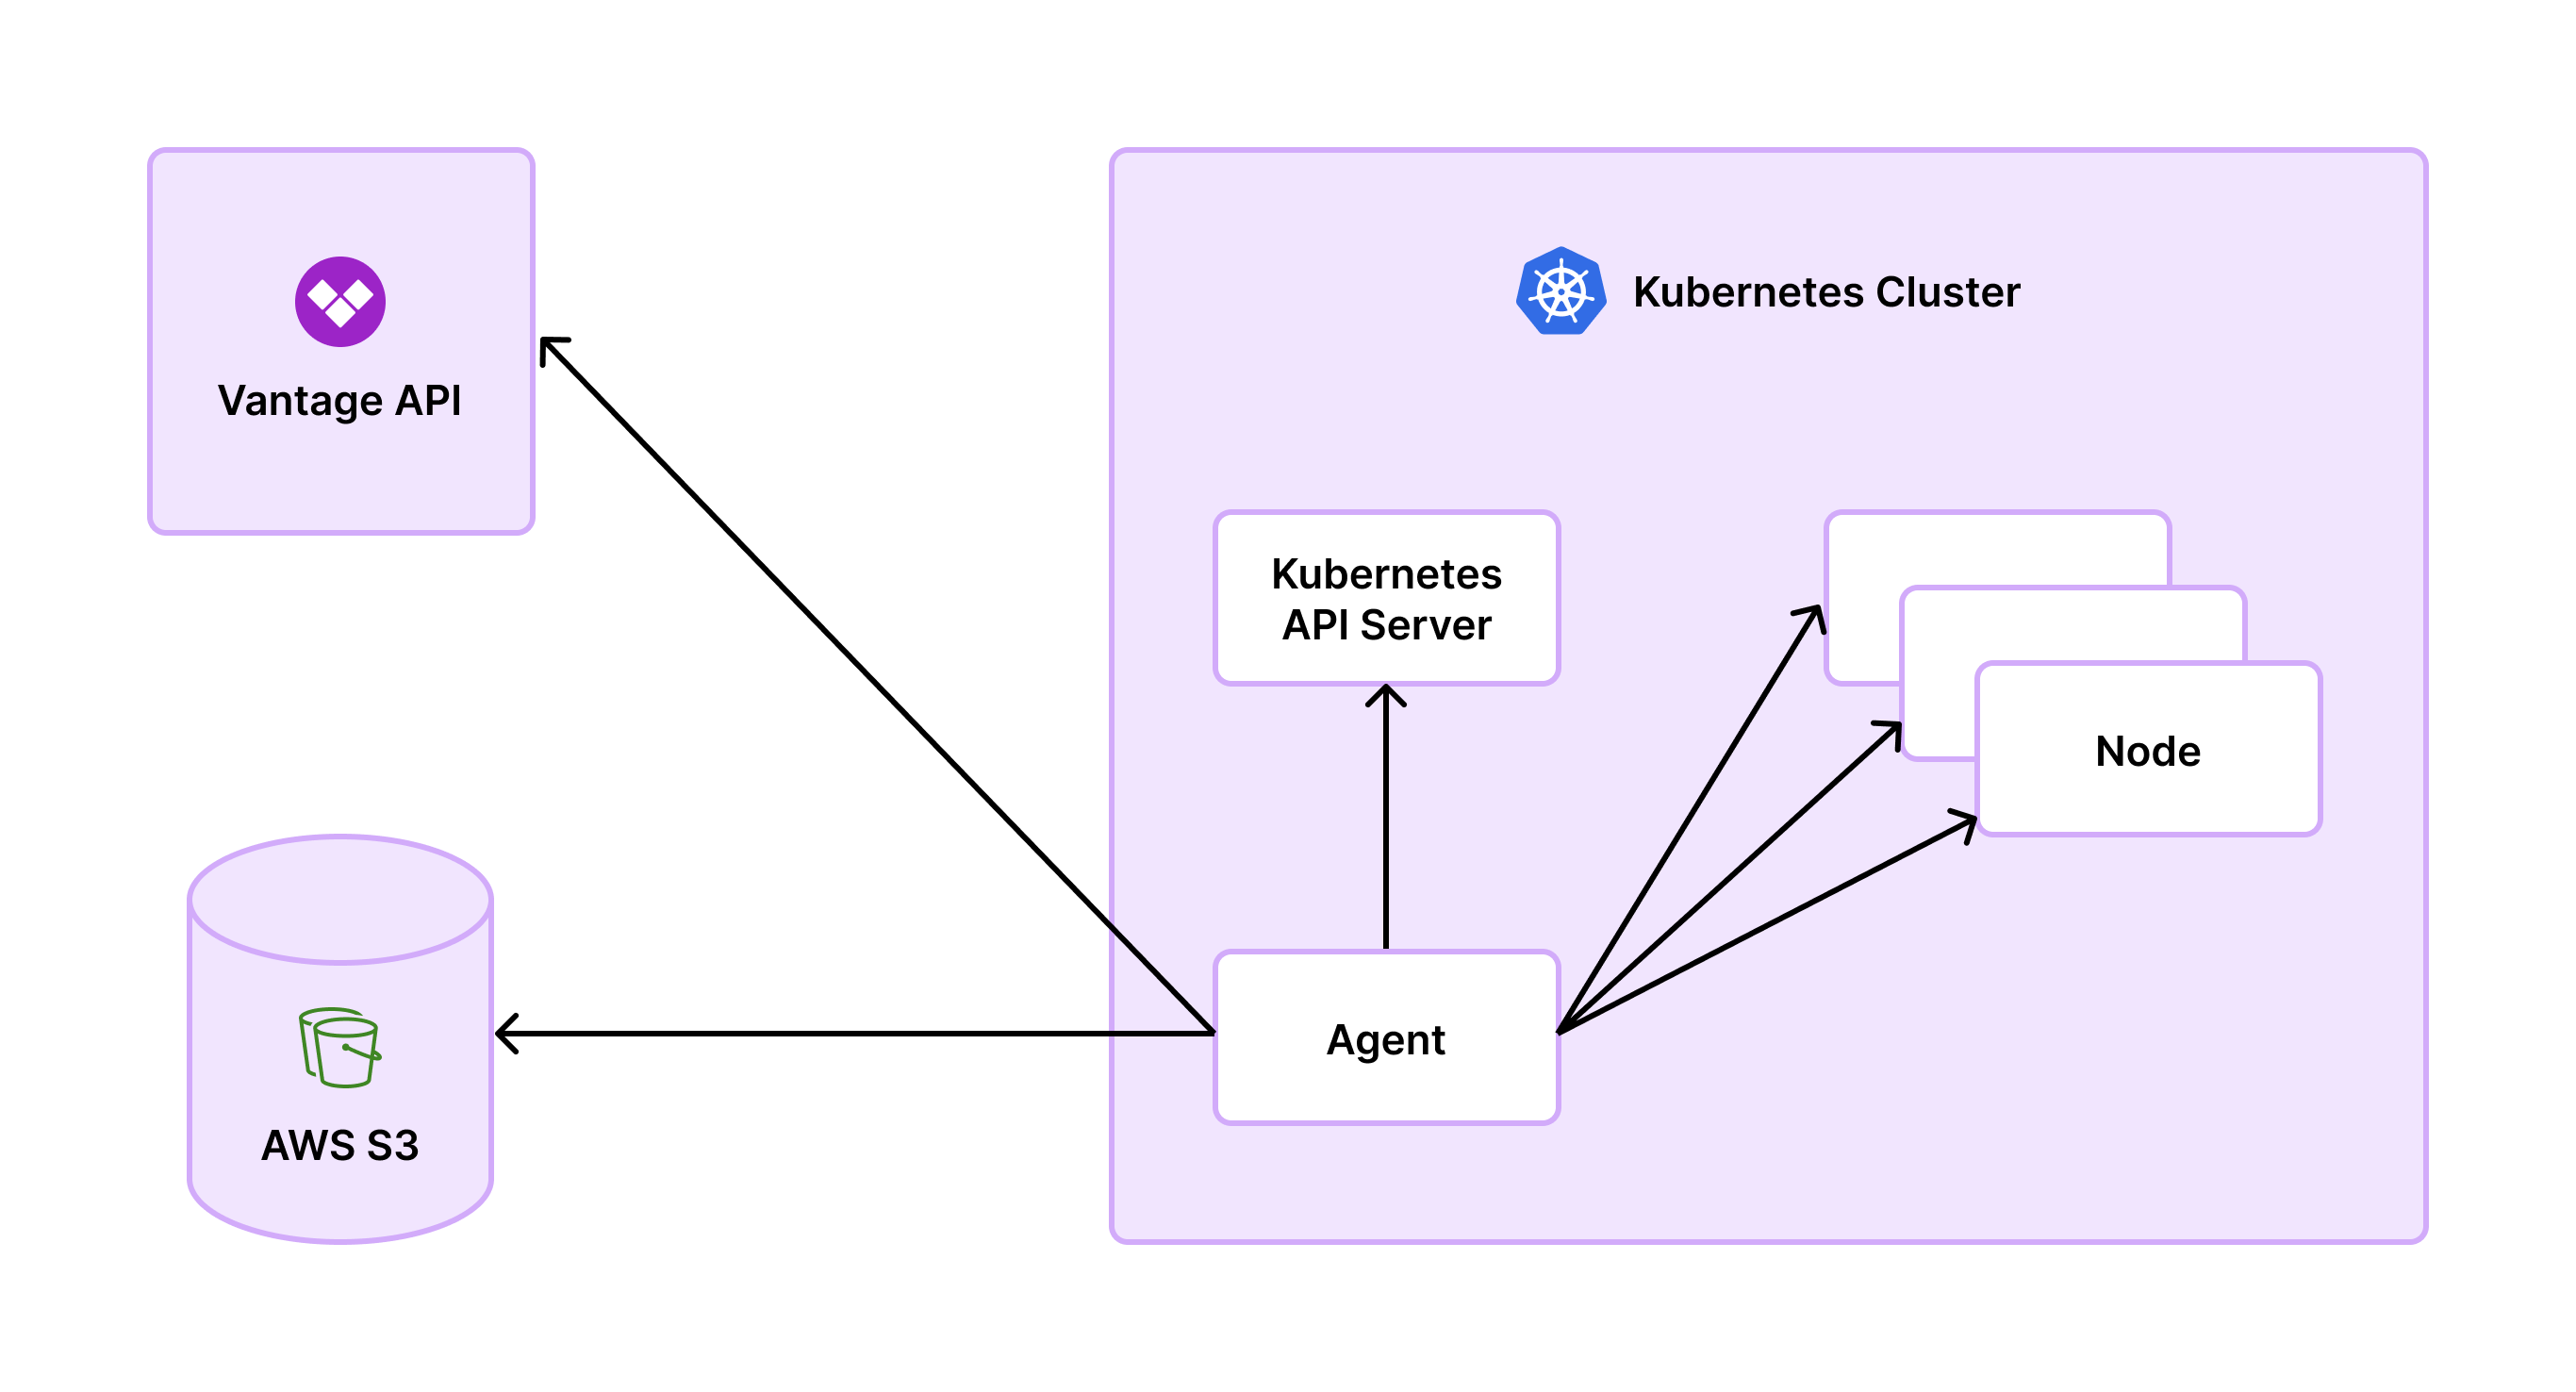
The agent supports GPU cost monitoring and efficiency metrics, including [NVIDIA Multi-Instance GPU (MIG)](/kubernetes#nvidia-multi-instance-gpu-mig-accounting) nodes using the `single` strategy. For detailed information on viewing GPU costs, configuring GPU metrics collection, and supported GPU instance types, see the [Kubernetes GPU documentation](/kubernetes#kubernetes-gpu-idle-costs).
## Service Compatibility
The Vantage Kubernetes agent is compatible with the following services:
* Amazon Elastic Kubernetes Service (EKS)
* Azure Kubernetes Service (AKS)
* Google Kubernetes Engine (GKE)
* Oracle Cloud Infrastructure Container Engine for Kubernetes (OKE)
* Custom rates for on-premises services (see the [Enable On-Premises Support](/kubernetes_agent#enable-on-premises-support) section below)
As long as the cost data for an underlying cluster instance is ingested into Vantage via a cloud integration, it is possible to calculate the corresponding pod costs.
### Google Kubernetes Engine (GKE) Autopilot
For [GKE Autopilot](https://cloud.google.com/kubernetes-engine/docs/concepts/autopilot-overview) users, you don't need to install the agent. These costs will already be present under **Cost By Resource** for the **Kubernetes Engine** service in a [Cost Report](/cost_reports).
## Install Vantage Kubernetes Agent
### Prerequisites
The following prerequisites are required before you install the Vantage Kubernetes agent:
* The [Helm package manager](https://helm.sh/) for Kubernetes
* `kubectl`
* A running Kubernetes cluster
* An already connected primary provider (i.e., [AWS](/connecting_aws), [Azure](/connecting_azure), [GCP](/connecting_gcp), or [Oracle Cloud](/connecting_oracle), or on-premises)
* A [Vantage API token](/api/authentication) with READ and WRITE scopes enabled (it's recommended to use a [service token](/api/authentication#create-a-vantage-api-service-token) rather than a [personal access token](/api/authentication#create-a-vantage-api-personal-access-token))
* **Important:** For Enterprise accounts, the service token should be assigned to the **Everyone** team to obtain Integration Owner access. This is required for organization-level actions such as managing provider integrations, which the Kubernetes agent needs to function properly. Service tokens assigned to other teams will not have the necessary permissions for these organization-level operations.
* **If you do not already have an integration enabled**, navigate to the [Kubernetes Integration page](https://console.vantage.sh/settings/kubernetes?connect=true) in the Vantage console, and click the **Enable Kubernetes Agent** button (you won't need to do this for subsequent integrations)
* Review the section on [Data Persistence](/kubernetes_agent#data-persistence) before you begin
* Review the section on [Naming Your Clusters](/kubernetes_agent#naming-your-clusters)
## Create a Connection
The following steps are also provided in the Vantage Kubernetes agent Helm chart repository. See [the Helm chart repository](https://github.com/vantage-sh/helm-charts/tree/main/charts/vantage-kubernetes-agent) for all value configurations. If you would like to use a manifest-based option instead, see the [section below](/kubernetes_agent#manifest-based-deployment-option).
To set up a *new* Kubernetes agent connection:
Add the repository for the Vantage Kubernetes agent Helm chart.
```bash theme={null}
helm repo add vantage https://vantage-sh.github.io/helm-charts
```
Install the `vantage-kubernetes-agent` Helm chart. Ensure you update the values for `VANTAGE_API_TOKEN` (obtained in the [Prerequisites](/kubernetes_agent#prerequisites) above) and `CLUSTER_ID` (the unique value for your cluster).
```bash theme={null}
helm upgrade -n vantage vka vantage/vantage-kubernetes-agent --install --set agent.token=$VANTAGE_API_TOKEN,agent.clusterID=$CLUSTER_ID --create-namespace
```
### Azure Kubernetes Service (AKS) Connections
If you are creating an AKS connection, you will need to configure the following parameters to avoid AKS-specific errors:
* Set the `VANTAGE_KUBE_SKIP_TLS_VERIFY` environment variable to `true`. This setting is controlled by `agent.disableKubeTLSverify` within the Helm chart. For details, see the [TLS verify error](/kubernetes_agent#tls-verify-error-when-scraping-nodes) section.
* Configure the `VANTAGE_NODE_ADDRESS_TYPES` environment variable, which is controlled by the `agent.nodeAddressTypes` in the Helm chart. In this case, the type to use for your cluster will most likely be `InternalIP`. For configuration details, see the [DNS lookup error](/kubernetes_agent#dns-lookup-error) section.
### Naming Your Clusters
When you name your clusters, ensure the cluster ID adheres to Kubernetes object naming conventions. While the agent does not enforce specific formats, valid characters include:
* Lowercase and uppercase letters (`a-z`, `A-Z`)
* Numbers (`0-9`)
* Periods (`.`), underscores (`_`), and hyphens (`-`)
In addition, when configuring the cluster ID, use a simplified, human-readable name that identifies the cluster. Avoid including full resource paths or unnecessary metadata. The cluster ID should be unique within your environment.
### Enable Collection of Annotations and Namespace Labels
You can optionally enable the collection of annotations and namespace labels.
* **Annotations:** The agent accepts a comma-separated list of annotation keys, called `VANTAGE_ALLOWED_ANNOTATIONS`, as an environment variable at startup. To enable the collection of annotations, configure the `agent.allowedAnnotations` [parameter of the Helm chart](https://github.com/vantage-sh/helm-charts/blob/main/charts/vantage-kubernetes-agent/values.yaml) with a list of annotations to be sent to Vantage. Note there is a max of 10 annotations, and values are truncated after 100 characters.
* **Label Allow List:** The agent [excludes certain labels by default](/kubernetes_agent#default-label-exclusions). To collect a label that is excluded by default, add its key to the allow list. The agent accepts a comma-separated list of label keys, called `VANTAGE_ALLOWED_LABELS`, as an environment variable at startup. Configure the `agent.allowedLabels` [parameter of the Helm chart](https://github.com/vantage-sh/helm-charts/blob/main/charts/vantage-kubernetes-agent/values.yaml) with the label keys you want collected and sent to Vantage. The allow list is additive and matches on the exact key: it only re-includes the listed labels and does not change how any other labels are collected. Note there is a max of 10 labels.
* **Namespace labels:** The agent accepts `VANTAGE_COLLECT_NAMESPACE_LABELS` as an environment variable at startup. To enable the collection of namespace labels, configure the `agent.collectNamespaceLabels` [parameter of the Helm chart](https://github.com/vantage-sh/helm-charts/blob/main/charts/vantage-kubernetes-agent/values.yaml).
#### Default Label Exclusions
To reduce noise, the agent drops common system-generated labels by default. This filter applies to pod, node, controller, PVC, and namespace labels. A label is excluded if its key contains any of the following patterns:
* `kubernetes.io`
* `k8s.io`
* `controller-revision-hash`
* `alertmanager`
* `pod-template-hash`
* `pod-template-generation`
* `eks.amazonaws.com`
* `ebs.csi.aws.com`
Matching is on substring, so a pattern excludes every key that contains it. For example, the `kubernetes.io` pattern excludes `kubernetes.io/arch`, `node.kubernetes.io/instance-type`, and `topology.kubernetes.io/zone`. The one exception is labels under `app.kubernetes.io/*`, such as `app.kubernetes.io/name`, which are always collected.
To collect a label that is excluded by default, add its exact key to the label allow list. For example, to collect the `kubernetes.io/arch` node label:
```bash theme={null}
--set agent.allowedLabels="kubernetes.io/arch"
```
This re-includes only `kubernetes.io/arch`. Other labels that match an excluded pattern remain excluded, and all other pod and node labels continue to be collected as normal.
### Enable On-Premises Support
The Vantage Kubernetes agent supports on-premises Kubernetes clusters by allowing you to define custom cost rates for compute and storage resources. To enable on-premises cost tracking, you can define custom hourly rates for different resource types by adding annotations to your Kubernetes nodes. The agent supports the following annotation keys:
* `ram_gb_hourly_rate` - Cost per GB of RAM per hour
* `gpu_gb_hourly_rate` - Cost per GB of GPU memory per hour
* `vcpu_hourly_rate` - Cost per vCPU per hour
* `storage_gb_hourly_rate` - Cost per GB of storage per hour
Add these annotations to your node metadata as shown in the example below using your own custom rates:
```yaml theme={null}
metadata:
annotations:
ram_gb_hourly_rate: "0.0012"
gpu_gb_hourly_rate: "0.004"
vcpu_hourly_rate: "0.0025"
storage_gb_hourly_rate: "0.0001"
```
Only RAM and CPU are required.
Then, add each of the annotation keys to the [allowed annotation list](/kubernetes_agent#enable-collection-of-annotations-and-namespace-labels) on the agent to capture these custom rate annotations (i.e., `agent.allowedAnnotations="ram_gb_hourly_rate,gpu_gb_hourly_rate,vcpu_hourly_rate,storage_gb_hourly_rate"`).
If a rate annotation is missing, Vantage will skip cost calculation for that specific resource. To maintain accurate visibility, we recommend applying all four annotation keys (ram, vcpu, gpu, storage) consistently across your on-prem nodes. Workload metrics are collected based on your [configured polling interval](/kubernetes_agent#configure-polling-interval) (default: 60 seconds, minimum: 5 seconds), sent to Vantage hourly, and refreshed daily in the console. The agent's [data persistence](/kubernetes_agent#data-persistence) feature retains data for up to 96 hours during connectivity issues.
To view on-prem costs, you can filter by cluster on Cost Reports, Kubernetes Efficiency Reports, and in Virtual Tags. Vantage will also provide [Kubernetes Rightsizing Recommendations](https://docs.vantage.sh/cost_recommendations#view-kubernetes-rightsizing-recommendations) for on-prem workloads. Savings for these recommendations will be driven off of the custom rates you provide.
#### On-Premises Rate Calculation
If you know the total hourly cost of a host but need to derive per-resource rates, you can use the following normalization formula. This approach distributes the total cost proportionally across CPU, RAM, and GPU based on standard cloud pricing ratios.
Multiply each resource quantity by its reference weight:
* CPU: $0.031611 \times \text{vCPU count}$
* RAM: $0.004237 \times \text{GiB}$
* GPU: $0.95 \times \text{GPU count}$
Divide the total hourly host cost by the denominator:
$$
k = \frac{\text{total hourly cost}}{\text{denominator}}
$$
Multiply each reference weight by the normalization factor:
* $vcpu\_hourly\_rate = 0.031611 \times k$
* $ram\_gb\_hourly\_rate = 0.004237 \times k$
* $gpu\_gb\_hourly\_rate = 0.95 \times k$
```text Example: $4/hr host with 64 vCPU, 256 GiB RAM, 8 GPU theme={null}
Denominator:
CPU: 0.031611 × 64 = 2.023104
RAM: 0.004237 × 256 = 1.084672
GPU: 0.95 × 8 = 7.6
Total = 10.707776
Normalization factor:
k = 4 / 10.707776 ≈ 0.3735603
Effective rates:
vcpu_hourly_rate ≈ 0.031611 × 0.3735603 = $0.01181 per vCPU-hour
ram_gb_hourly_rate ≈ 0.004237 × 0.3735603 = $0.001583 per GiB-hour
gpu_gb_hourly_rate ≈ 0.95 × 0.3735603 = $0.35488 per GPU-hour
```
In this example, GPU dominates the denominator, so CPU and RAM rates are pushed lower. This reflects typical GPU cloud pricing where GPU costs represent the majority of the total host cost.
### (Optional) Enable Collection of PVC Labels
This feature is available with Vantage Kubernetes agent `v1.0.30` and later.
By default, Node Labels are collected by the Vantage Kubernetes agent. For PVC Labels, the agent accepts `VANTAGE_COLLECT_PVC_LABELS` as an environment variable at startup. To enable the collection of PVC Labels, set `agent.collectPVCLabels` to `true` in the agent's [Helm chart configuration](https://github.com/vantage-sh/helm-charts/blob/main/charts/vantage-kubernetes-agent/values.yaml). PVC Labels are collected from persistent volume claims associated with pods. Node and PVC Labels are subject to the same [default label exclusions](/kubernetes_agent#default-label-exclusions) as pod labels.
### Manifest-Based Deployment Option
You can use `helm template` to generate a static manifest via the existing repo. This option generates files (YAML) so that you can then decide to deploy them however you want.
Add the repository for the Vantage Kubernetes agent Helm chart.
```bash theme={null}
helm repo add vantage https://vantage-sh.github.io/helm-charts
```
Generate the static manifest.
```bash theme={null}
helm template -n vantage vka vantage/vantage-kubernetes-agent --set agent.token=$VANTAGE_API_TOKEN,agent.clusterID=$CLUSTER_ID
```
### Resource Usage
The limits provided within the Helm chart are set low to support small clusters (approximately 10 nodes) and should be considered the minimum values for deploying an agent.
Estimates for larger clusters are roughly:
* \~1 CPU/1,000 nodes
* \~5 MB/node
For example, a 100-node cluster would be approximately 500 MB and 100 mCPU. These amounts are estimates, which will vary based on pod density per node, label usage, cluster activity, etc. The agent should reach an approximate steady state after about one hour of uptime and can be tuned accordingly after the fact.
To set these options, extend the `--set` flag. You can also include the values using one of the [many options Helm supports](https://helm.sh/docs/chart_template_guide/values_files/):
```
--set agent.token=$VANTAGE_API_TOKEN,agent.clusterID=$CLUSTER_ID,resources.limits.memory=100Mi,resources.requests.memory=100Mi
```
### Configure Polling Interval
To enable a configurable polling interval for the Vantage Kubernetes Agent, specify an `image.tag` when you upgrade. Upgrade and deploy your Helm chart using the following command:
`helm repo update && helm upgrade -n vantage vka vantage/vantage-kubernetes-agent --set agent.pollingInterval={interval},image.tag={special-tag} --reuse-values`
The polling interval defines how frequently the agent will poll pods for utilization information. The polling interval applies to the entire cluster. The default polling period for the agent is 60 seconds, but the agent has allowable periods, including 5 seconds, 10 seconds, 15 seconds, 30 seconds, and 60 seconds.
To set the agent's polling period, configure the `agent.pollingInterval` [parameter of the Helm chart](https://github.com/vantage-sh/helm-charts/blob/main/charts/vantage-kubernetes-agent/values.yaml) with the desired polling period in seconds, such as `--set agent.pollingInterval=30` for a 30-second polling interval. If you enter a polling interval that is not in the list of allowed intervals, the agent will fail to start, and an error message is returned within the response.
To see the current polling period for a cluster, use the `kubectl describe pod/ -n vantage` command. In the Vantage Helm chart, the polling interval is found in the `VANTAGE_POLLING_INTERVAL` environment variable.
There are performance implications on both the Kubernetes API server and the Vantage Kubernetes agent if you shorten the interval for when the Vantage Kubernetes agent polls the pods. Your polling interval should be based on the shortest-lived task within your cluster, and you should note how long it takes for the agent to scrape nodes. You can obtain this information using the `vantage_last_node_scrape_timestamp_seconds` metric provided by the agent.
It is recommended that you monitor system performance and adjust the interval as needed to balance granularity with resource usage.
### Validate Installation
Follow the steps below to validate the agent's installation.
Once installed, the agent's pod should become `READY`:
```bash theme={null}
➜ kubectl -n vantage get pod
NAME READY STATUS RESTARTS AGE
vka-vantage-kubernetes-agent-0 1/1 Running 0 54m
```
Logs should be free of `ERROR` messages:
```bash theme={null}
➜ kubectl -n vantage logs -f vka-vantage-kubernetes-agent-0
{"time":"2023-10-23T22:01:12.065481528Z","level":"INFO","msg":"found nodes","nodes":231}
...
{"time":"2023-10-23T22:01:15.471399742Z","level":"INFO","msg":"finished initializing"}
```
Agent reporting should occur once per hour at the start of the hour and should not generate an `ERROR` log line. It should also attempt a report soon after the initial start:
```bash theme={null}
{"time":"2023-10-23T22:01:00.015243974Z","level":"INFO","msg":"reporting now"}
{"time":"2023-10-23T22:01:01.168390414Z","level":"INFO","msg":"finished reporting"}
{"time":"2023-10-23T22:01:01.169876296Z","level":"INFO","msg":"next report window","start":"2023-10-23T22:00:00Z","end":"2023-10-23T23:00:00Z","sleeping_seconds":3598.830199804}
```
Costs are exported from the cluster hourly and then made available nightly. It's important to note that these costs might encounter delays based on their associated cloud integration's cost data. For instance, if there is a one-day delay in an AWS Cost and Usage Report, the clusters dependent on that data will experience a similar delay.
You can view and manage your Kubernetes integration on the [Kubernetes Integration page](https://console.vantage.sh/settings/kubernetes) in the console. Hover over the integration in the list, and click **Manage**.
### Monitoring
The agent exposes a Prometheus metrics endpoint via the `/metrics` endpoint, exposed by default on port `9010`. This port can be changed via the Helm chart's `service.port` value.
The metrics endpoint includes standard Golang process stats as well as agent-related metrics for node scrape results, node scrape duration, internal data persistence, and reporting.
For users who want to monitor the agent:
`vantage_last_node_scrape_count{result="fail"}` should be low (between 0 and 1% of total nodes). Some failures may occur as nodes come and go within the cluster, but consistent failures are not expected and should be investigated.
`rate(vantage_report_count{result="fail"}[5m])` should be 0. Reporting occurs within the first 5 minutes of every hour and will retry roughly once per minute. Each failure increments this counter. If the agent is unable to report within the first 10 minutes of an hour, some data may be lost from the previous window, as only the previous \~70 data points are retained.
## Upgrade Agent
To see which version of the Kubernetes agent you are running:
From the top navigation, click **Settings**.
On the side navigation, click **Integrations**.
A list of all your provider integrations is displayed. Select the **Kubernetes** integration.
On the **Manage** tab, click the settings button (looks like a cog wheel) next to a specific integration.
Scroll down to the **Clusters** section. Each cluster that is integrated with the agent is listed along with the current agent version and indicates if the agent is out of date.
To upgrade the agent, use the following command:
```
helm repo update && helm upgrade -n vantage vka vantage/vantage-kubernetes-agent --reuse-values
```
The version noted in the console for your agent is updated when cost data is imported nightly.
AKS users should remember to follow the [AKS-specific instructions](/kubernetes_agent#azure-kubernetes-service-aks-connections) again when updating.
## Data Persistence
The agent requires a persistent store for periodic backups of time-series data as well as checkpointing for periodic reporting. By default, the Helm chart configures the agent to use a Persistent Volume (PV), which works well for clusters ranging from tens to thousands of nodes.
The Helm chart sets a default `persist.mountPath` value of `/var/lib/vantage-agent`, which enables PV-based persistence by default. To disable PV persistence, set `persist: null` in your `values.yaml`.
If Persistent Volumes are not supported with your cluster, or if you prefer to centralize persistence, S3 is available as an alternative for agents deployed in AWS. See the [section below](/kubernetes_agent#configure-agent-for-s3-persistence) for details. If you require persistence to a different object store, contact [support@vantage.sh](mailto:support@vantage.sh).
If both a Persistent Volume and an S3 bucket are configured, the agent will prioritize S3.
### Persistent Metrics Recovery
Persistent Metrics Recovery is enabled by default in Kubernetes Agent version v1.0.29. (See the [Upgrade the Agent](/kubernetes_agent#upgrade-agent) section for details on how to upgrade your agent to the latest version.)
Persistent Metrics Recovery ensures hourly Kubernetes metrics are preserved during upload failures. Every hour, the agent generates four report files in the container's temp directory, which are then uploaded to S3. When the agent can't upload an hourly report, for example, due to a Vantage API or S3 outage, it performs the following actions:
* Compresses the reports into a `.tar` archive and moves them to a backup location, either:
* A mounted volume in the container, or
* An S3 bucket [you configure](/kubernetes_agent#configure-agent-for-s3-persistence)
* Retries the upload until successful or until the report is 96 hours old.
* Deletes old reports to manage disk space and avoid unbounded storage use.
If any hourly data is not successfully uploaded within this window, it may still be lost.
This feature does not require additional configuration flags, but it does respect the `PERSIST_DIR` or `PERSIST_S3_BUCKET` environment variables, if provided. If neither is set, the agent will not store hourly backups. For persistence configuration options, see the [section above](/kubernetes_agent#data-persistence).
With Persistent Metrics Recovery, the agent will temporarily hold all four report files in the container's temp directory before uploading, rather than processing them one-by-one. Note that this may result in slightly higher short-term disk usage, but it does not increase memory usage.
The agent emits logs and metrics to indicate when reports are stored, retried, and successfully uploaded. These logs help monitor recovery status and confirm no data loss occurred. To view these logs, run the `kubectl logs ` command.
### Configure Agent for S3 Persistence
The agent uses [IAM roles for service accounts](https://docs.aws.amazon.com/eks/latest/userguide/iam-roles-for-service-accounts.html) to access the configured bucket. The default `vantage` namespace and `vka-vantage-kubernetes-agent` service account names may vary based on your configuration.
Below are the expected associated permissions for the IAM role:
```json theme={null}
{
"Version": "2012-10-17",
"Statement": [
{
"Effect": "Allow",
"Action": [
"s3:GetObject",
"s3:PutObject",
"s3:ListBucket",
"s3:AbortMultipartUpload",
"s3:ListMultipartUploadParts",
"s3:DeleteObject"
],
"Resource": [
"arn:aws:s3:::example-bucket-name/*",
"arn:aws:s3:::example-bucket-name"
]
}
]
}
```
Once permissions are available, you can enable S3 persistence using one of the following:
* **Environment variable**: Set `VANTAGE_PERSIST_S3_BUCKET` in the agent deployment.
* **Helm chart values**:
```
--set persist=null \
--set persistS3.bucket=example-bucket-name
```
The agent will write persisted data to the `$CLUSTER_ID/` prefix within the bucket. Multiple agents can use the same bucket as long as they do not have overlapping `CLUSTER_ID` values. An optional prefix can be prepended with `VANTAGE_PERSIST_S3_PREFIX` resulting in `$VANTAGE_PERSIST_S3_PREFIX/$CLUSTER_ID/` being the prefix used by the agent for all objects uploaded.
### Configure Agent for S3 Persistence on GKE via OIDC Federation
Requires Helm chart version `1.5.0` or later, which introduces the `agent.extraEnv` values field.
The [EKS setup above](#configure-agent-for-s3-persistence) relies on the EKS Pod Identity webhook to inject AWS credentials into the agent pod. GKE has no equivalent webhook, so on GKE you configure the AWS SDK's [web-identity credential provider](https://docs.aws.amazon.com/sdkref/latest/guide/feature-assume-role-credentials.html) directly, using AWS IAM OIDC federation against the GKE cluster's built-in OIDC issuer. The same pattern works on AKS, OKE, and any Kubernetes cluster whose OIDC discovery and JWKS endpoints are reachable from AWS STS.
#### Step 1 - Register the GKE Cluster's OIDC Issuer in AWS IAM
From inside the cluster, capture the issuer URL and confirm its discovery endpoints are publicly reachable (AWS STS fetches them over the internet to validate tokens).
```bash theme={null}
ISSUER=$(kubectl get --raw /.well-known/openid-configuration | jq -r .issuer)
curl -sfL "$ISSUER/.well-known/openid-configuration" | jq .issuer,.jwks_uri
curl -sfL "$(curl -sfL "$ISSUER/.well-known/openid-configuration" | jq -r .jwks_uri)" | jq '.keys | length'
```
Then, in the AWS account that owns the bucket:
Go to **IAM → Identity providers → Add provider → OpenID Connect**.
Set **Provider URL** to the `$ISSUER` value.
Set **Audience** to `sts.amazonaws.com`.
#### Step 2 - Create the IAM Role and Trust Policy
Use the same S3 permissions as the [EKS section](#configure-agent-for-s3-persistence). The trust policy targets the GKE ServiceAccount the agent runs under (by default, `system:serviceaccount:vantage:vka-vantage-kubernetes-agent`).
```json theme={null}
{
"Version": "2012-10-17",
"Statement": [{
"Effect": "Allow",
"Principal": { "Federated": "arn:aws:iam:::oidc-provider/" },
"Action": "sts:AssumeRoleWithWebIdentity",
"Condition": {
"StringEquals": {
":aud": "sts.amazonaws.com",
":sub": "system:serviceaccount:vantage:vka-vantage-kubernetes-agent"
}
}
}]
}
```
Before touching the Vantage agent, verify the federation path works end-to-end with a throwaway `amazon/aws-cli` pod that uses the same ServiceAccount, projected token, and env vars described below and runs `aws sts get-caller-identity && aws s3 ls s3:///`. If that fails, no amount of Helm values will make the agent work — fix the trust policy or OIDC provider first.
#### Step 3 - Configure the Helm Chart
Install or upgrade the agent with values that (a) set the three env vars the AWS SDK's web-identity provider expects, and (b) project a ServiceAccount token with audience `sts.amazonaws.com` into the pod.
```yaml theme={null}
agent:
token:
clusterID:
extraEnv:
- name: AWS_ROLE_ARN
value: arn:aws:iam:::role/vantage-agent-s3
- name: AWS_WEB_IDENTITY_TOKEN_FILE
value: /var/run/secrets/aws-iam/token
- name: AWS_REGION
value:
volumes:
- name: aws-iam-token
projected:
sources:
- serviceAccountToken:
audience: sts.amazonaws.com
expirationSeconds: 3600
path: token
volumeMounts:
- name: aws-iam-token
mountPath: /var/run/secrets/aws-iam
readOnly: true
persist: null
persistS3:
bucket:
prefix:
```
On startup, the AWS SDK reads the projected token, calls `sts:AssumeRoleWithWebIdentity` against the role, caches the temporary credentials, and uses them for all S3 calls. No IAM user access keys are stored in the cluster.
## Configure GPU Metrics
To track GPU utilization and idle costs for your Kubernetes workloads, enable GPU metrics collection in the Vantage Kubernetes agent. This section covers GPU setup for AWS and Azure, which use native cloud billing data combined with DCGM exporter metrics. For neocloud providers (DigitalOcean, CoreWeave, Nebius, etc.) that use annotation-based pricing, see the [Enable Neocloud GPU Support](/kubernetes_agent#enable-neocloud-gpu-support) section below.
### Step 1 - Configure the Agent
Install or upgrade to Vantage Kubernetes [agent version 1.0.26 or later](/kubernetes_agent#upgrade-agent), available as part of Helm Chart version 1.0.34. To collect GPU metrics, set the following parameter to `true` in the agent's [`values.yaml`](https://github.com/vantage-sh/helm-charts/blob/main/charts/vantage-kubernetes-agent/values.yaml): `--set agent.gpu.usageMetrics=true`.
The agent also provides some additional GPU configuration options. The defaults match the operator's defaults. Refer to the [agent's `values.yaml`](https://github.com/vantage-sh/helm-charts/blob/main/charts/vantage-kubernetes-agent/values.yaml) for option configuration details.
Kubernetes Cost Reports can show GPU costs based on requested GPU allocation and the underlying billing or pricing data. Kubernetes Efficiency Reports require GPU memory usage metrics from the [NVIDIA DCGM Exporter](https://docs.nvidia.com/datacenter/cloud-native/gpu-telemetry/latest/index.html). If GPU costs appear in Cost Reports but the `gpu` category is missing from Efficiency Reports, verify that [`agent.gpu.usageMetrics`](https://github.com/vantage-sh/helm-charts/blob/main/charts/vantage-kubernetes-agent/values.yaml) is enabled and that the agent can scrape the DCGM exporter metrics. See [Step 2 - Configure the GPU Operator](/kubernetes_agent#step-2-configure-the-gpu-operator) for DCGM exporter setup guidance.
### Step 2 - Configure the GPU Operator
For net-new installations:
To configure the `dcgm-exporter` to collect custom metrics, retrieve the metrics file and save it as `dcgm-metrics.csv`:
```
curl https://raw.githubusercontent.com/NVIDIA/dcgm-exporter/main/etc/dcp-metrics-included.csv > dcgm-metrics.csv
```
Add the `DCGM_FI_DEV_FB_TOTAL` memory metric to the metrics file.
```
....
# Memory usage
DCGM_FI_DEV_FB_FREE, gauge, Framebuffer memory free (in MiB).
DCGM_FI_DEV_FB_TOTAL, gauge, Framebuffer memory total (in MiB).
DCGM_FI_DEV_FB_USED, gauge, Framebuffer memory used (in MiB).
...
```
Create a `gpu-operator` namespace:
```
kubectl create namespace gpu-operator
```
Create a ConfigMap from the metrics file:
```
kubectl create configmap metrics-config -n gpu-operator --from-file=dcgm-metrics.csv
```
Follow the steps provided in the [NVIDIA GPU Operator installation guide](https://docs.nvidia.com/datacenter/cloud-native/gpu-operator/latest/getting-started.html) to install the operator. Set the following options on the operator:
```
--set dcgmExporter.config.name=metrics-config \
--set dcgmExporter.env[0].name=DCGM_EXPORTER_COLLECTORS \
--set dcgmExporter.env[0].value=/etc/dcgm-exporter/dcgm-metrics.csv
```
Once the operator is installed, the Vantage Kubernetes agent will begin to upload the data needed to calculate the idle costs. The data will be available on efficiency reports within 48 hours as the costs from the infrastructure provider are ingested.
### Step 3 - Enable GPU Feature Discovery for MIG Nodes
If your GPU nodes are partitioned with [NVIDIA Multi-Instance GPU (MIG)](/kubernetes#nvidia-multi-instance-gpu-mig-accounting), Vantage needs the MIG node labels published by [GPU Feature Discovery](https://github.com/NVIDIA/k8s-device-plugin/blob/main/docs/gpu-feature-discovery/README.md#mig-single-strategy) (GFD) to allocate each MIG device a fractional share of its physical GPU. The NVIDIA GPU Operator deploys GFD by default, so this usually only requires confirming that the MIG strategy is set.
[Upgrade the Vantage Kubernetes agent](/kubernetes_agent#upgrade-agent) to the latest version.
Set the `single` MIG strategy on the GPU Operator. See the NVIDIA [GPU Operator with MIG](https://docs.nvidia.com/datacenter/cloud-native/gpu-operator/latest/gpu-operator-mig.html) documentation for how to configure MIG profiles on your nodes.
```
--set mig.strategy=single
```
Confirm GFD publishes the MIG labels on a GPU node:
```
kubectl get node -o jsonpath='{.metadata.labels}' | tr ',' '\n' | grep nvidia.com
```
The output must include `nvidia.com/mig.strategy`, `nvidia.com/gpu.count`, and `nvidia.com/gpu.memory`. Under the `single` strategy, `nvidia.com/gpu.count` reports the number of MIG devices on the node, and `nvidia.com/gpu.memory` reports the memory of one device.
No agent-side configuration is required. The agent forwards NVIDIA node labels automatically, and Vantage applies MIG accounting when those labels and your provider's pricing data support it. See [NVIDIA Multi-Instance GPU (MIG) Accounting](/kubernetes#nvidia-multi-instance-gpu-mig-accounting) for the allocation formula and provider support.
## Enable Neocloud GPU Support
You must be on Vantage Kubernetes Agent version 1.2.0 (Helm Chart v1.4.0) or higher to enable neocloud support.
The Vantage Kubernetes agent supports GPU cost monitoring for neocloud providers (such as DigitalOcean, CoreWeave, Nebius, and other GPU-focused cloud platforms) using the same annotation-based approach as on-premises clusters. This enables you to track, allocate, and optimize GPU-backed workloads running on neocloud Kubernetes clusters.
### Step 1 - Verify DCGM Exporter is Running
The NVIDIA DCGM exporter must be running in your cluster. Many neocloud providers deploy this natively, so you may only need to verify it's running. If your provider hasn't deployed it, you can install it as part of the [NVIDIA GPU Operator](https://docs.nvidia.com/datacenter/cloud-native/gpu-operator/latest/overview.html) or independently. For instructions on installing the DCGM exporter from scratch, see [Step 2 - Configure the GPU Operator](/kubernetes_agent#step-2-configure-the-gpu-operator) in the Configure GPU Metrics section above.
The DCGM exporter must expose the `DCGM_FI_DEV_FB_USED` and `DCGM_FI_DEV_FB_FREE` metrics. The agent currently expects `DCGM_FI_DEV_FB_TOTAL` to be present or the GPU's total memory to be available from the provider. If you're installing the exporter yourself, you can configure it to include `DCGM_FI_DEV_FB_TOTAL` (see the Configure GPU Metrics section).
### Step 2 - Add GPU Rate Annotations to Nodes
Similar to [on-premises clusters](/kubernetes_agent#enable-on-premises-support), you need to define custom GPU cost rates by adding annotations to your Kubernetes nodes. Add the following annotations to your node metadata:
```yaml theme={null}
metadata:
annotations:
gpu_gb_hourly_rate: "0.004"
ram_gb_hourly_rate: "0.0012"
vcpu_hourly_rate: "0.0025"
```
Only RAM and CPU are required for basic cost tracking, but GPU annotations are necessary for GPU cost allocation. If you know the total hourly cost of your host but need to derive per-resource rates, see the [On-Premises Rate Calculation](/kubernetes_agent#on-premises-rate-calculation) section for a normalization formula and examples.
### Step 3 - Configure the Agent
Configure the agent to collect the annotations and enable GPU metrics collection. When installing or upgrading the agent, set the following parameters:
```
--set agent.allowedAnnotations="ram_gb_hourly_rate,gpu_gb_hourly_rate,vcpu_hourly_rate" \
--set agent.gpu.usageMetrics=true
```
This configures the agent to:
* Collect the custom rate annotations from your nodes (via `agent.allowedAnnotations`)
* Enable GPU metrics collection (via `agent.gpu.usageMetrics`)
### Step 4 - Configure DCGM Exporter Connection (Optional)
If your neocloud provider has pre-deployed the DCGM exporter in a non-standard location (different namespace, service name, etc.), you may need to configure the agent to point to the correct exporter location. The agent uses default values that match the standard GPU operator deployment, so you only need to configure this if your provider's exporter is deployed differently. The agent provides configuration options for the namespace, service name, port name, and path where the exporter is available.
Configure these options in the agent's [`values.yaml`](https://github.com/vantage-sh/helm-charts/blob/main/charts/vantage-kubernetes-agent/values.yaml):
* `agent.gpu.exporterNamespace` - The namespace where the GPU exporter is deployed (default: `gpu-operator`)
* `agent.gpu.exporterServiceName` - The service name for the GPU exporter (default: `nvidia-dcgm-exporter`)
* `agent.gpu.exporterPortName` - The port name for the metrics port (default: `gpu-metrics`)
* `agent.gpu.exporterPath` - The path where the metrics endpoint is available (default: `/metrics`)
For example, if your provider deploys the exporter in a different namespace:
```
--set agent.gpu.usageMetrics=true \
--set agent.gpu.exporterNamespace=your-namespace \
--set agent.gpu.exporterServiceName=your-service-name
```
## Network Cost Attribution (Optional)
The Vantage Kubernetes agent can attribute network costs down to the individual pods driving them, so network spend appears in [Cost Reports](/cost_reports) alongside compute, memory, GPU, and storage costs. When enabled, the Helm chart deploys a per-node network collector that reads connection-tracking data and classifies each pod's traffic into billing buckets (intra-zone, intra-region, cross-region, internet egress, and more).
Enable it by setting `agent.networkCost.enabled=true` and providing your cluster's subnet configuration. For prerequisites, subnet configuration for AWS, Azure, and GKE, optional AWS network discovery, viewing costs via filters, and troubleshooting, see the [Kubernetes Network Cost Attribution documentation](/kubernetes_network_costs).
## Common Errors
### Failed to Fetch Presigned URL
A `failed to fetch presigned urls` error can occur for a few reasons, as described below.
#### API Token Error
The below error occurs when the agent attempts to fetch presigned URLs but fails due to an invalid `Authorization` header field value. The error log typically looks like this:
```
{"time":"2023-12-01T00:00:00.000000000Z","level":"ERROR","msg":"failed to fetch presigned urls","err":"Get \"https://api.vantage.sh/internal/integrations/kubernetes_agent/…": net/http: invalid header field value for \"Authorization\""}
```
This issue is typically caused by incorrect or missing API keys.
* Ensure the value for the `VANTAGE_API_TOKEN` (obtained in the [Prerequisites](/kubernetes_agent#prerequisites) above) is valid and properly formatted.
* If you are using a [personal API token](/api/authentication#create-a-vantage-api-personal-access-token), ensure the user associated with the token has an **Owner** role. See the [Role-Based Access Control](/rbac) documentation for details on roles.
* If you are using a service token, ensure the token is assigned to the **Everyone** team. The Everyone team is a default team in Vantage that includes all users in your organization. Service tokens on the Everyone team have the permissions needed for organization-level actions, such as managing provider integrations. Service tokens assigned to other teams will receive authorization errors when attempting these operations. See the [service token](/api/authentication#create-a-vantage-api-service-token) documentation for details on how to set this up.
If necessary, generate a new token and update the configuration.
#### 404 Not Found Error
The below error occurs when the agent attempts to fetch presigned URLs but fails due to the cluster ID potentially including invalid characters. The error log typically looks like this:
```
{"time":"2023-12-01T00:00:00.000000000Z","level":"ERROR","msg":"failed to fetch presigned urls","err":"unexpected response from API: 404 Not Found"}
```
Review the section on [Naming Your Clusters](/kubernetes_agent#naming-your-clusters) for best practices on how to name your clusters. Then, review the cluster ID in your configuration to confirm it is correct and valid. Update the configuration as needed to use a properly formatted cluster ID.
### Failed to Set Up Controller Store—`MissingRegion`
This error occurs when the agent cannot initialize the controller store due to missing or misconfigured AWS region settings. The error log will typically look like:
```
failed to setup controller store failed to open backup: MissingRegion: could not find region configuration
```
This issue arises when the agent's Service Account is not properly configured with AWS IAM roles and permissions. In this case, the agent defaults to local configuration, which lacks the necessary region configuration.
Verify the Service Account configuration:
* Check if the `eks.amazonaws.com/role-arn` annotation is correctly added to the Service Account. Run the following command to inspect the configuration:
```bash theme={null}
kubectl -n vantage get serviceaccount vka-vantage-kubernetes-agent -o yaml
```
* Ensure the Service Account matches the Helm chart settings in the agent's `serviceAccount` configuration block of the [Helm chart values file](https://github.com/vantage-sh/helm-charts/blob/main/charts/vantage-kubernetes-agent/values.yaml). This is a name that you can also set within the file.
Ensure the IAM role is correctly set up:
* Review the [AWS IAM Roles for Service Accounts documentation](https://docs.aws.amazon.com/eks/latest/userguide/iam-roles-for-service-accounts.html) to confirm that the IAM role is configured with the necessary permissions and associated with the Service Account.
Configure S3 persistence:
* See the [Agent S3 persistence setup](/kubernetes_agent#configure-agent-for-s3-persistence) section for details.
The S3 bucket used for persistence must be in the same region as the Kubernetes cluster to minimize latency.
If necessary, recreate the pod:
* If the Service Account appears correct and there's still an issue, delete the agent pod to force a fresh start with the correct configuration:
```bash theme={null}
kubectl -n vantage delete pod -l app.kubernetes.io/name=vantage-kubernetes-agent
```
### DNS Lookup Error
You may receive a DNS Lookup Error that indicates `"level":"ERROR","msg":"failed to scrape node"` and `no such host`.
The agent uses the [node status addresses](https://kubernetes.io/docs/reference/node/node-status/#addresses) to determine what hostname to look up for the node's stats, which are available via the `/metrics/resource` endpoint. This can be configured with the `VANTAGE_NODE_ADDRESS_TYPES` environment variable, which is controlled by the `agent.nodeAddressTypes` in the Helm chart. By default, the priority order is `Hostname,InternalDNS,InternalIP,ExternalDNS,ExternalIP`.
To understand which type to use for your cluster, you can look at the available addresses for one of your nodes. The `type` corresponds to one of the configurable `nodeAddressTypes`.
```
➜ kubectl get nodes -o=jsonpath='{.items[0].status.addresses}'[{"address":"10.0.12.185","type":"InternalIP"},{"address":"ip-10-0-12-185.ec2.internal","type":"InternalDNS"},{"address":"ip-10-0-12-185.ec2.internal","type":"Hostname"}]
```
### EOF Error When Starting
The agent uses local files for recovering from crashes or restarts. If this backup file becomes corrupted, most commonly due to [OOMKill](/kubernetes_agent#resource-usage), the most straightforward approach to get the agent running again is to perform a fresh install or remove the `PersistentVolumeClaim`, `PersistentVolume`, and `Pod`.
An example error log line might look like:
```json theme={null}
{"time":"2023-12-01T00:00:00.000000000Z","level":"ERROR","msg":"failed to setup data store","err":"unexpected EOF"}
```
To uninstall the agent via `helm`, run:
```bash theme={null}
helm uninstall vka -n vantage
```
Then, follow the original installation steps outlined in the above sections.
### TLS Verify Error When Scraping Nodes
The agent connects to each node to collect usage metrics from the `/metrics/resources` endpoint. This access is managed via Kubernetes RBAC, but in some cases, the node's TLS certificate may not be valid and will result in TLS errors when attempting this connection. This most often affects clusters in AKS. To skip TLS verify within the Kubernetes client, you can set the `VANTAGE_KUBE_SKIP_TLS_VERIFY` environment variable to `true`. This setting is controlled by `agent.disableKubeTLSverify` within the Helm chart. This does not affect requests outside of the cluster itself, such as to the Vantage API or S3.
An example error log line might look like:
```
{"time":"2024-02-10T12:00:00.000000000Z","level":"ERROR","msg":"failed to scrape node","err":"Get \"https://10.100.20.20:10250/metrics/resource\": tls: failed to verify certificate: x509: cannot validate certificate for 10.100.20.20 because it doesn't contain any IP SANs","node":"aks-nodepool9ids-1234567-vm0000001"}
```
Once changed, you can validate the change by looking for the scraping summary log line and ensuring no more `ERROR` level messages appear:
```
{"time":"2024-02-10T12:00:00.000000000Z","level":"INFO","msg":"finished scraping metrics from nodes","success":25,"failure":0,"duration_ms":102}
```
### Pod Scheduling Errors
The most common cause for pod scheduling errors is the persistent volume not being provisioned. By default, the agent is deployed as a StatefulSet with a persistent volume for persisting internal state. The state allows the agent to recover from a restart without losing the historical data for the current reporting window. An example error for this case would be present in the events on the `vka-vantage-kubernetes-agent-0` pod and include an error that contains `unbound immediate PersistentVolumeClaims`.
The resolution to this error is based on the cluster's configuration and the specific cloud provider. More information might be present on the persistent volume claim or persistent volume. For Kubernetes clusters on AWS, S3 can be used for [data persistence](/kubernetes_agent#data-persistence).
Additional provider references are also listed here:
* [GCP: Using the Compute Engine persistent disk CSI Driver](https://cloud.google.com/kubernetes-engine/docs/how-to/persistent-volumes/gce-pd-csi-driver)
* [Azure: Container Storage Interface (CSI) drivers on Azure Kubernetes Service (AKS)](https://learn.microsoft.com/en-us/azure/aks/csi-storage-drivers)
* [AWS: Amazon EBS CSI driver](https://docs.aws.amazon.com/eks/latest/userguide/ebs-csi.html)
### Volume Support Error
If you see an error related to `binding volumes: context deadline exceeded`, this means you may not have volume support on your cluster. This error typically occurs when your cluster is unable to provision or attach persistent storage volumes required by your applications. Check your cluster's configuration and ensure the storage provider is properly set up.
### Missing Namespaces in Reports
If certain namespaces are not appearing in your Kubernetes reports, this typically indicates one of two issues:
* **Verify agent installation on all clusters:**
* Ensure the Vantage Kubernetes agent is installed and running on all clusters where you expect to see namespace data
* Check that the agent pod is running in each cluster:
```bash theme={null}
kubectl -n vantage get pod
```
* Verify the agent is properly configured with the correct `CLUSTER_ID` for each cluster. See the [Naming Your Clusters](/kubernetes_agent#naming-your-clusters) section for details
* **Check agent logs for crashes and resource issues:**
* Review the agent logs to ensure the agent is not crashing or running out of memory:
```bash theme={null}
kubectl -n vantage logs -f
```
Replace `` with your agent pod name (e.g., `vka-vantage-kubernetes-agent-0`).
* Look for `ERROR` level messages indicating crashes, out-of-memory (OOM) kills, or repeated failures
* If the agent is crashing or running out of memory, you may need to increase the resource limits. See the [Resource Usage](/kubernetes_agent#resource-usage) section for guidance on scaling resources based on your cluster size
## Active Resources and Rightsizing Recommendations
Rightsizing recommendations require version 1.0.24 or later of the Vantage Kubernetes agent. See the [upgrading section](/kubernetes_agent#upgrade-agent) for information on how to upgrade the agent. Once the upgrade is complete, the agent will begin uploading the data needed to generate rightsizing recommendations. After the agent is upgraded or installed, recommendations will become available within 48 hours. This step is required to ensure there is enough data to make a valid recommendation. Historical data is not available before the agent upgrade, so it is recommended that you observe cyclical resource usage patterns, such as a weekly spike when you first review recommendations.
Vantage syncs Kubernetes managed workloads as [active resources](/active_resources) in your account. In cases where these workloads are identified to be overprovisioned, Vantage provides Kubernetes rightsizing recommendations. See the [Cost Recommendations](/cost_recommendations#kubernetes-rightsizing-recommendations) documentation for details on how to view rightsizing recommendations for Kubernetes workloads.
For a full guide on understanding rightsizing and how to rightsize Kubernetes workloads, see the following article in the [Cloud Cost Handbook](https://handbook.vantage.sh/kubernetes/kubernetes-rightsizing).
### Recommendations Disappear or Stop Updating
If recommendations stop appearing for a cluster that previously had them, work through the following checks:
* **Verify the agent is on a supported version.** Older agent versions can stop submitting the inputs required to generate rightsizing recommendations. Upgrade any cluster running an older agent and wait up to 48 hours for the next refresh. See the [Upgrade the Agent](/kubernetes_agent#upgrade-agent) section.
* **Confirm the cluster is still reporting.** If a cluster has been renamed, replaced, or migrated, its previous `clusterID` may no longer be sending data to Vantage. Verify that each cluster you expect to see recommendations for is still listed on the [Kubernetes integration page](https://console.vantage.sh/settings/kubernetes) and that the agent is healthy. See the [Validate Installation](/kubernetes_agent#validate-installation) section.
If recommendations still do not appear after the next refresh, contact [support@vantage.sh](mailto:support@vantage.sh).
## Uninstall Agent
To uninstall the agent via `helm`, run:
```bash theme={null}
helm uninstall vka -n vantage
```
# Kubernetes Network Cost Attribution
Source: https://docs.vantage.sh/kubernetes_network_costs
Allocate pod-level network costs from the Vantage Kubernetes agent and view them in Cost Reports.
Network Cost Attribution for Kubernetes allocates network spend to the individual pods that drive it. When enabled, the [Vantage Kubernetes agent](/kubernetes_agent) attributes network costs down to the pod level, so they appear in [Cost Reports](/cost_reports) alongside compute, memory, GPU, and storage costs. Each pod's network cost is broken out by destination type, such as intra-zone, intra-region (cross-AZ), cross-region, and internet egress, so you can see not just how much a workload spent on the network, but what type of traffic drove the cost. You can then use [Virtual Tags](/tagging) to roll these costs up to the teams, applications, or business units that generated them.
## How It Works
When network cost collection is enabled, the Vantage Kubernetes agent Helm chart deploys a per-node network collector that runs as a DaemonSet. The collector reads Linux connection-tracking (`conntrack`) data on each node, attributes each pod's traffic, and classifies the transmitted bytes into mutually exclusive [billing buckets](/kubernetes_network_costs#billing-buckets) by destination. The agent pulls these per-pod summaries each report cycle and joins them with your provider's data transfer rates to produce a per-pod network cost.
```mermaid actions={true} placement="top-right" theme={null}
flowchart TB
CT["conntrack (per node)"] -->|"pod byte counts"| COL["Network collector DaemonSet"]
COL -->|"classify by destination"| CLASS["Billing buckets (intra-zone, intra-region, cross-region, internet, S3)"]
CLASS -->|"pulled each cycle"| AGENT["Vantage Kubernetes agent"]
AGENT -->|"priced per pod"| CR["Cost Reports"]
```
The collector does not retain full flow records; it summarizes traffic into cost buckets and reports running totals. There is no flow log storage or query infrastructure to operate, and enabling this feature does not require VPC Flow Logs.
## Network Cost Attribution vs. Network Flow Reports
Network Cost Attribution is different from [Network Flow Reports](/network_flow_reports). Network Flow Reports use VPC Flow Log data to analyze source/destination flows and route classification at the cloud-provider level (answering *"where is my traffic going?"*). Kubernetes Network Cost Attribution allocates pod-level network *cost* using connection-tracking data observed inside the cluster (answering *"which workload owns this network spend?"*). It classifies traffic by destination type (intra-zone, intra-region, cross-region, internet, and more) rather than showing individual destination addresses.
The two features are complementary: use Network Flow Reports when you need to investigate where specific traffic is going, and use Kubernetes Network Cost Attribution when you need to put a per-pod dollar amount on network spend and charge it back to a team.
## Supported Providers
Network Cost Attribution supports the following providers at launch:
* Amazon Elastic Kubernetes Service (EKS)
* Azure Kubernetes Service (AKS)
* Google Kubernetes Engine (GKE)
Collection works on any node where the collector can run within these providers, including IPv6 and dual-stack (IPv4/IPv6) clusters.
The collector reads traffic from Linux connection tracking (conntrack). On clusters where the CNI datapath bypasses kernel netfilter, for example, Cilium with kube-proxy replacement, conntrack sees little or no traffic, so network costs are not attributed. These configurations are not supported at launch.
Oracle Cloud (OKE) and on-premises clusters are not supported at launch. AWS network discovery and S3 path-aware pricing are available on EKS only; other supported providers use manual subnet configuration.
## Prerequisites
Before you enable network cost collection, ensure you meet the following requirements:
* A working [Vantage Kubernetes agent](/kubernetes_agent) integration.
* Vantage Kubernetes [agent version 1.3.3 or later](/kubernetes_agent#upgrade-agent), available as part of Helm chart version 1.9.5 or later. This version includes the network collector, AWS network discovery, and the collector metrics endpoint.
* **Connection-tracking byte accounting must be enabled on every node.** Set the `net.netfilter.nf_conntrack_acct=1` sysctl cluster-wide *before* traffic is generated. When this is off (the default on many node images), the kernel leaves conntrack byte counters at zero, so the collector cannot attribute traffic. Only connections opened after the sysctl is set receive counters.
`nf_conntrack_acct` is a node-level kernel setting that Vantage and the Helm chart cannot enable for you. It's applied through your node configuration, so it's typically handled by whoever manages your cluster's nodes. To check whether it is already on for a node (a value of `1` means it is):
```sh theme={null}
kubectl debug node/ -it --image=busybox -- cat /host/proc/sys/net/netfilter/nf_conntrack_acct
```
After it's enabled, confirm it took effect with the `vantage_collector_conntrack_acct_enabled` metric (see [Monitor the Collector](/kubernetes_network_costs#monitor-the-collector)); the collector also logs a warning at startup when byte accounting is disabled.
* The collector runs as a DaemonSet with host network access and an elevated security context (the `NET_ADMIN` capability) so it can read conntrack for local pods. The Helm chart configures this for you (`hostNetwork: true` and `capabilities.add: ["NET_ADMIN"]`). Its ServiceAccount needs read-only (`get`/`list`/`watch`) access to pods, nodes, and ConfigMaps.
The network collector is opt-in and can be disabled per cluster if your security policy does not permit a privileged, host-network DaemonSet. Nodes where the collector cannot run (for example, Fargate or hybrid nodes without conntrack access) will not report network costs.
## Enable Network Cost Collection
Enable the collector and provide your subnet configuration through the Vantage Kubernetes agent [Helm chart](https://github.com/vantage-sh/helm-charts/blob/main/charts/vantage-kubernetes-agent/values.yaml).
Enable `net.netfilter.nf_conntrack_acct=1` on every node (see [Prerequisites](/kubernetes_network_costs#prerequisites)).
Set `agent.networkCost.enabled=true` and populate `agent.networkCost.subnets` with your cluster's destination CIDRs. See [Configure Subnets](/kubernetes_network_costs#configure-subnets) for how to inventory them. For example:
```yaml theme={null}
agent:
networkCost:
enabled: true
subnets:
- cidr: "10.0.0.0/20"
zone: "us-east-1a"
- cidr: "10.0.16.0/20"
zone: "us-east-1b"
```
Upgrade the agent to apply the changes:
```bash theme={null}
helm repo update && helm upgrade -n vantage vka vantage/vantage-kubernetes-agent --reuse-values \
--set agent.networkCost.enabled=true
```
Allocated network costs begin appearing in your Kubernetes Cost Reports within one full collection cycle (approximately 24 hours).
## Configure Subnets
The collector compares each flow's remote IP with your subnet map to classify it as `in_zone`, `in_region`, or `cross_region`. Populate `agent.networkCost.subnets` with the private destination CIDRs your workloads can reach: cluster subnets, peered networks, private managed services, and overlay pod CIDRs where applicable.
Keep the following guidelines in mind when defining your subnets:
* A `zone` enables same-zone classification. When only a `region` is supplied, all same-region matches are reported as `in_region`. The region is derived from the zone when omitted (for example, `us-east-1a` resolves to `us-east-1`).
* On a dual-stack cluster, add both IPv4 and IPv6 ranges. IP families are matched independently.
* The collector does not assume that an unmatched private address is internet traffic. It reports the traffic as `unknown` until you add the CIDR or an [override](/kubernetes_network_costs#nat-peering-and-overrides).
Use the tabs below to inventory the cluster network for your provider, then add the output to your Helm values.
AWS subnets are Availability Zone scoped. List every IPv4 subnet in a VPC in the same `cidr`/`zone` shape used by the Helm value:
```sh theme={null}
aws ec2 describe-subnets \
--filters "Name=vpc-id,Values=${VPC_ID}" \
--query 'Subnets[].{cidr:CidrBlock,zone:AvailabilityZone}' \
--output yaml
```
Add the results to your Helm values:
```yaml theme={null}
agent:
networkCost:
subnets:
- cidr: "10.0.0.0/20"
zone: "us-east-1a"
- cidr: "10.0.16.0/20"
zone: "us-east-1b"
```
For an EKS cluster that can grant the agent EC2 read permissions, prefer [AWS network discovery](/kubernetes_network_costs#optional-aws-network-discovery-eks). It discovers VPC subnets automatically and also enables S3 egress-path classification, so you don't have to maintain the subnet list by hand.
Azure VNets and their subnets are regional. List a VNet's subnet address prefixes:
```sh theme={null}
az network vnet subnet list \
--resource-group "${RESOURCE_GROUP}" \
--vnet-name "${VNET_NAME}" \
--query '[].{cidr:addressPrefix}' \
--output yaml
```
Obtain the VNet location once and use it for all of its subnets:
```sh theme={null}
az network vnet show \
--resource-group "${RESOURCE_GROUP}" \
--name "${VNET_NAME}" \
--query location \
--output tsv
```
Configure the subnets with the VNet's region, and do not set a `zone`:
```yaml theme={null}
agent:
networkCost:
subnets:
- cidr: "10.30.0.0/20"
region: "eastus"
- cidr: "10.30.16.0/20"
region: "eastus"
```
Do not set a `zone` from an AKS node pool on a subnet entry. Azure availability zones apply to resources, while a VNet subnet is regional; a guessed zone can incorrectly classify same-region traffic as `cross_region`.
For Azure CNI, pod addresses may come from the node subnet or from a separate pod subnet. Add every pod subnet. For kubenet and overlay modes, obtain the pod CIDR from the AKS cluster network profile and add it when workloads can reach remote pod IPs:
```sh theme={null}
az aks show \
--resource-group "${RESOURCE_GROUP}" \
--name "${AKS_CLUSTER}" \
--query 'networkProfile.{podCidrs:podCidrs,podCidr:podCidr}' \
--output yaml
```
GCP subnets are regional, not zonal. List the primary CIDR and its region:
```sh theme={null}
gcloud compute networks subnets list \
--network="${VPC_NETWORK}" \
--format='table(ipCidrRange, region)'
```
Use the regional location (without its URL prefix) in your Helm values, and do not set a `zone`:
```yaml theme={null}
agent:
networkCost:
subnets:
- cidr: "10.20.0.0/20"
region: "us-central1"
- cidr: "10.20.16.0/20"
region: "us-central1"
```
For VPC-native GKE, pod and Service CIDRs are usually secondary IP ranges. Inspect each subnet's secondary ranges and add the pod ranges that are reachable from your workloads:
```sh theme={null}
gcloud compute networks subnets describe "${SUBNET}" \
--region="${REGION}" \
--format='yaml(ipCidrRange, secondaryIpRanges)'
```
Because GCP does not assign a subnet to a single zone, traffic to a configured subnet in the node's region is reported as `in_region`, even if both endpoints happen to be in the same zone.
### Overlay Networks and Pod CIDRs
Overlay networking (for example, Calico, Cilium, kubenet, or GKE VPC-native networking) can allocate pod addresses outside the node's primary VPC/VNet subnet. When a remote pod address does not match an entry in `subnets`, it is classified as `unknown`. Add the relevant pod CIDR with the cluster's zone or region:
```yaml theme={null}
agent:
networkCost:
subnets:
- cidr: "172.20.0.0/16"
region: "us-central1"
```
### NAT, Peering, and Overrides
Use `overrides` to force a bucket for a destination CIDR. Overrides take precedence over subnet entries, and the most-specific CIDR wins. Use them when destination ownership or topology cannot be represented accurately by a zone/region map.
```yaml theme={null}
agent:
networkCost:
overrides:
# A NAT/proxy appliance range that is a real remote destination for pods.
- cidr: "10.40.8.0/24"
bucket: "in_region"
# A CIDR in a peered VPC in another region.
- cidr: "10.80.0.0/16"
bucket: "cross_region"
```
A managed NAT gateway normally source-NATs traffic on its way to a public destination; it is not the remote IP visible in the pod's conntrack flow. Do not add its private address merely to classify ordinary internet egress. The public destination already falls into `internet`. Reserve NAT overrides for cases where a NAT or proxy appliance is itself the remote endpoint. For a same-region peered VPC, prefer a normal `subnets` entry with its actual region rather than a `cross_region` override.
### Validate the Rendered Configuration
After you apply the Helm values, inspect the ConfigMap mounted by the network collector to confirm your configuration rendered correctly:
```sh theme={null}
kubectl -n "${NAMESPACE}" get configmap vantage-network-subnets \
-o jsonpath='{.data.subnets\.yaml}'
```
The rendered document should include both `subnets:` and `overrides:` (the latter may be an empty list).
## Optional AWS Network Discovery (EKS)
On EKS, you can let the agent discover your network topology automatically instead of maintaining subnet lists by hand. Enable it with `agent.networkCost.discovery.enabled=true`.
Discovery has two benefits:
* **Turnkey subnet inventory:** Classification depends on knowing every subnet CIDR in the cluster's VPC(s) and each subnet's zone/region. Maintaining that list by hand is error-prone and drifts whenever someone adds a subnet, AZ, or VPC. Any missed subnet classifies traffic as `unknown` or `internet` instead of the correct bucket. Discovery enumerates all subnets in the tagged VPC(s) directly from the EC2 APIs, so the inventory stays complete and current. With discovery on, the manual subnet list can be as small as `subnets: []` plus any human-only overrides.
* **Accurate S3 egress pricing:** The S3 path-aware buckets exist because the cost of reaching S3 depends on how each source subnet egresses (a gateway VPC endpoint is free; a NAT gateway is not). Discovery resolves each subnet's S3 egress path and fetches the regional S3 prefix lists automatically, so S3 traffic is priced correctly without hand-authored fields.
Discovery requires the following read-only EC2 permissions on the agent's ServiceAccount (via IRSA or EKS Pod Identity):
* `ec2:DescribeSubnets`
* `ec2:DescribeRouteTables`
* `ec2:DescribeManagedPrefixLists`
* `ec2:GetManagedPrefixListEntries`
```hcl theme={null}
# Read-only EC2 permissions the Vantage Kubernetes agent needs for AWS
# network discovery. Attach to the IAM role assumed by the agent's
# ServiceAccount (via IRSA or EKS Pod Identity).
resource "aws_iam_policy" "vantage_network_discovery" {
name = "vantage-k8s-network-discovery"
description = "Read-only EC2 access for Vantage Kubernetes network cost discovery"
policy = jsonencode({
Version = "2012-10-17"
Statement = [
{
Sid = "VantageNetworkDiscovery"
Effect = "Allow"
Action = [
"ec2:DescribeSubnets",
"ec2:DescribeRouteTables",
"ec2:DescribeManagedPrefixLists",
"ec2:GetManagedPrefixListEntries",
]
Resource = "*"
}
]
})
}
# Attach to your existing agent IRSA role.
resource "aws_iam_role_policy_attachment" "vantage_network_discovery" {
role = aws_iam_role.vantage_agent_irsa.name
policy_arn = aws_iam_policy.vantage_network_discovery.arn
}
```
Discovery is fail-closed. If the region cannot be resolved, credentials are missing, or the permission probe fails, the agent logs a warning and leaves discovery off. It does not crash-loop, and classification continues on the manual subnet configuration.
## Billing Buckets
Transmitted bytes are grouped into mutually exclusive buckets. Each bucket is priced by the destination and, for S3-bound traffic, by how the source subnet egresses.
The label in the first column is what appears in Cost Reports. The configuration key is the value you use in a subnet [override](/kubernetes_network_costs#nat-peering-and-overrides).
| Cost Reports Label | Configuration Key | Meaning |
| - | - | - |
| Intra-Zone Egress | `in_zone` | The destination is in the same Availability Zone as the node. |
| Intra-Region Egress | `in_region` | The destination is in the same region (including same-region, cross-AZ traffic). |
| Cross-Region Egress | `cross_region` | The destination is in a different region. |
| Internet Egress | `internet` | Public internet egress. |
| Unclassified Egress | `unknown` | A private destination that does not match any configured subnet or override. Add the missing CIDR to price it correctly. |
| S3 Gateway Endpoint (Free) | `s3_endpoint` | S3 reached through a gateway VPC endpoint. No data-processing or egress charge (free). |
| S3 via NAT Gateway | `s3_nat_gateway` | S3 reached through a managed NAT gateway. Priced as NAT processing plus internet egress. |
| S3 via NAT Instance | `s3_nat_instance` | S3 reached through an EC2 NAT instance. Priced as standard internet egress. |
| S3 via Internet Gateway | `s3_igw` | S3 reached directly through an internet gateway. Priced as standard internet egress. |
The S3 path-aware buckets require [AWS network discovery](/kubernetes_network_costs#optional-aws-network-discovery-eks). Without it, S3 traffic falls through to standard destination matching (often Internet Egress). Rates are blended per-GB rates derived from your provider's actual data transfer charges over the month.
## View Network Costs in Cost Reports
Pod-level network costs appear in [Cost Reports](/cost_reports) under the **Kubernetes** provider, alongside compute, memory, GPU, and storage costs. To isolate network costs, filter the **Kubernetes** provider by **Category** and select **network**. The `vntg:category` tag also works and is the same pattern used for CPU, RAM, GPU, and storage (see [Filter by CPU, RAM, Storage, and GPU](/kubernetes#filter-by-cpu-ram-storage-and-gpu)).
Network costs are not part of [Kubernetes Efficiency Reports](/kubernetes#kubernetes-efficiency-metrics-and-reports). Efficiency Reports measure utilization of provisioned capacity, whereas network traffic is charged per byte and has no notion of idle reserved capacity. Network costs can still surface optimization opportunities, such as cross-AZ traffic, NAT gateway processing, internet egress, or inefficient S3 routing, through Cost Reports.
Create or open a Kubernetes [Cost Report](/cost_reports).
Add a filter: **All costs** from **Kubernetes** where **Category** is **network**. (Filtering by **Tag** **vntg:category** is **network** works too.)
Use the report's [**Group By**](/cost_reports#configure-report-groups) menu to break the network costs down. Group by **Subcategory** to see the destination breakdown (Intra-Zone Egress, Intra-Region Egress, Cross-Region Egress, Internet Egress, and the S3 paths), which shows how a workload's traffic is classified. To roll network costs up to the owning team or application, group by **Tag** and choose the `namespace` tag, a workload label, or a [Virtual Tag](/tagging). On Kubernetes Cost Reports, namespace and labels are surfaced as tags.
Because network costs carry the same pod, namespace, label, and annotation tags as the pod's compute costs, any [Virtual Tag](/tagging) you already use for chargeback will allocate network costs alongside compute, memory, and GPU. For step-by-step chargeback setups—such as mapping costs to a `team` tag or allocating shared costs by usage—see [Virtual Tagging Examples](/tagging_examples).
Kubernetes network costs are re-derived from your cloud provider's data transfer charges (for AWS, the **Data Transfer** and **NAT Gateway** charges already in your Cost and Usage Report). As with compute, reporting on both your primary provider and Kubernetes in the same Cost Report double counts these charges. Removing the overlap is only approximate: data transfer and NAT gateway line items usually aren't tagged with the cluster, so there is no clean way to exclude only the cluster's share. Excluding all of a provider's data transfer and NAT gateway charges also removes network spend from non-Kubernetes workloads, while excluding none leaves the double count in place. Choose whichever approximation better fits your reporting, and see [Avoid Double Counting Costs in Cost Reports](/kubernetes#avoid-double-counting-costs-in-cost-reports) for the compute equivalent.
### Example: Charge Network Costs Back to a Team
Suppose unallocated network spend currently lands on your platform team, and you want each application team to own its network costs alongside compute. If your workloads are labeled with a team identifier (for example, a `team` pod label or the `app.kubernetes.io/part-of` label), you can roll network costs up to that team.
Confirm the label is collected by the agent. Labels matching `app.kubernetes.io/*` are collected by default; to collect a custom label such as `team`, add it to the agent's [allowed labels](/kubernetes_agent#enable-collection-of-annotations-and-namespace-labels). Collected labels appear as tags on Kubernetes cost rows, including network rows.
(Optional) If team names vary across clusters or providers, create a `team` [Custom Value Virtual Tag](/tagging_examples#example-1-cross-provider-tagging) that maps the underlying labels and namespaces to standardized team values.
Open a Kubernetes [Cost Report](/cost_reports) and group by your `team` tag. To view only the network portion, add the filter **where Category is network**; to show each team's full Kubernetes bill, leave the category filter off so network rolls up alongside compute, memory, GPU, and storage.
Each team's row now includes the network costs their workloads drove, so the platform team no longer absorbs unallocated network spend.
## Troubleshooting
If network reporting looks empty or incomplete, check the following in order. The agent and collector expose Prometheus metrics (see [Monitor the Collector](/kubernetes_network_costs#monitor-the-collector)) that correspond to each check.
Confirm a collector is running on every node. A missing collector (from scheduling, a crash loop, or a taint without a matching toleration) means those nodes report no network costs. Add tolerations for any tainted nodes you want network costs from.
If `net.netfilter.nf_conntrack_acct` is not enabled, byte counters stay at zero and no traffic is attributed, even when the collector is healthy. Enable the sysctl cluster-wide, and remember that only connections opened afterward receive counters.
If the agent cannot retrieve reports from a collector, or has not succeeded within your report interval, network data will be stale or missing for that node's pods.
Costs appearing under **Unclassified Egress** (the `unknown` bucket) mean a private destination CIDR is missing from your configuration. Add the subnet (or an [override](/kubernetes_network_costs#nat-peering-and-overrides)), or enable [AWS network discovery](/kubernetes_network_costs#optional-aws-network-discovery-eks) on EKS.
Very short-lived pods may not be captured if your collection interval is coarse. Tune the [Kubernetes polling interval](/kubernetes_agent#configure-polling-interval) based on the shortest-lived workload you need to attribute.
### Monitor the Collector
The agent exposes network metrics on its existing metrics endpoint (default port `9010`), and the network collector exposes its own metrics endpoint (default port `8883`). Point your Prometheus scrape configuration at both. The following series are the most useful for catching silent failures and undercounting in cases where pods look healthy but network data is missing, stale, or incomplete.
| Metric | Component | Type | Labels | Meaning |
| - | - | - | - | - |
| `vantage_network_collectors_discovered` / `vantage_network_collectors_expected` | Agent | gauge | — | Collector coverage. Alert when discovered is less than expected. |
| `vantage_network_pull_failures_total` | Agent | counter | `collector`, `reason` | Failed agent pulls from a collector, by reason. |
| `vantage_network_last_pull_timestamp_seconds` | Agent | gauge | `collector` | Last successful pull from each collector. Use to catch stale pulls. |
| `vantage_network_pods_rejected_total` | Agent | counter | `reason` | Pod summaries dropped instead of attributed (for example, the pod was no longer in the agent's store). Rising values mean some network bytes aren't being allocated to a workload. |
| `vantage_network_unattributed_bytes_total` | Agent | counter | — | Total bytes that could not be attributed to a known pod. Rising values indicate network cost that won't roll up to a workload. |
| `vantage_collector_conntrack_acct_enabled` | Collector | gauge | — | `1` when conntrack byte accounting is enabled, `0` otherwise. |
| `vantage_collector_last_successful_poll_timestamp_seconds` | Collector | gauge | — | Last successful conntrack poll (collector heartbeat). |
| `vantage_collector_subnet_config_load_failure_total` | Collector | counter | `reason` | Failed subnet ConfigMap reloads, by reason. |
| `vantage_collector_conntrack_table_fullness_ratio` | Collector | gauge | — | Conntrack table utilization (current entries ÷ `nf_conntrack_max`). As it approaches `1`, the kernel can drop flows before the collector sees them, undercounting traffic. |
| `vantage_collector_bytes_classified_total` | Collector | counter | `bucket` | Transmitted bytes routed into each billing bucket. |
The following Prometheus alert rules are useful starting points. Tune the stale-pull threshold to match your deployed report interval (the example assumes the default \~1 hour interval).
```yaml theme={null}
groups:
- name: vantage-network-collector
rules:
- alert: VantageNetworkCollectorCoverageGap
expr: vantage_network_collectors_discovered < vantage_network_collectors_expected
for: 10m
annotations:
summary: Network collectors are missing from one or more nodes
- alert: VantageNetworkCollectorConntrackAccountingDisabled
expr: vantage_collector_conntrack_acct_enabled == 0
for: 5m
annotations:
summary: Conntrack byte accounting is disabled on {{ $labels.instance }}
- alert: VantageNetworkCollectorPullStale
expr: time() - vantage_network_last_pull_timestamp_seconds > 5400
for: 15m
annotations:
summary: Agent has not recently pulled from network collector {{ $labels.collector }}
```
# Linear MCP
Source: https://docs.vantage.sh/linear_mcp
Connect the Linear MCP to the Vantage FinOps Agent to bring your issues, projects, and teams into the same conversation as your Vantage cost data.
The Linear MCP Connector links the [Vantage FinOps Agent](/vantage_finops_agent) to your [Linear](https://linear.app) workspace. Once connected, the Agent can search your issues, projects, and teams and create or update issues on your behalf, so a cost finding can turn into tracked engineering work without leaving Vantage.
The Linear MCP Connector is one of several [MCP Connectors](/vantage_finops_agent#mcp-connectors) for the FinOps Agent. It is available to all Vantage customers using the FinOps Agent, in the [Vantage console](https://console.vantage.sh/agent), Slack, and [Canvas](/canvas).
## Prerequisites
Before you start, make sure you have:
* The [FinOps Agent](/vantage_finops_agent) enabled in Vantage. The Linear MCP settings page prompts you to enable it first if it is not already on.
* A Vantage role that can manage integrations, such as **Organization Owner** or **Integration Owner**, to enable the connector for your organization. See [Role-Based Access Control](/rbac) for details.
* A Linear account. Each Vantage user who wants to use the connector authorizes their own Linear account, so there is no required Linear role.
## How the Connection Works
The Linear MCP uses a two-part connection model, and the order matters:
1. **Start here (Organization Owner or Integration Owner):** enable the Linear MCP for your organization once, from the **Organization Settings** tab on the [Integrations page](https://console.vantage.sh/settings/integrations). Until this is done, other users see a prompt to contact an Owner or Integration Owner.
2. **Then, each user:** authorize your own Linear account from the **MCP Settings** tab, or when the Agent prompts you mid-conversation.
Per-user authorization is required because Linear content is scoped to the requesting user (your assigned issues, the teams and projects you can see). The Agent acts with your own Linear permissions and can only take actions you could take directly in Linear.
### Settings Tabs
The Linear MCP settings page has up to two tabs:
* **MCP Settings**: connect, disconnect, or reconnect your own Linear account and view your personal connection status. Every user has this tab.
* **Organization Settings** (Organization Owners and Integration Owners only): enable or disable the Linear MCP for the whole organization and view the list of users who have connected.
Once the Linear MCP is enabled for your organization, any Vantage role (down to Organization Viewer) can connect their own Linear account. Enabling it also lets **Organization Editors and Organization Viewers** open Settings > Integrations, where they see only the **MCP Connectors** section. A connector you have not connected yet shows as **Not Connected**. See [Role-Based Access Control](/rbac) for details.
## Permissions and Data Access
When you authorize Linear, Vantage requests OAuth scopes that let the Agent read and write on your behalf:
| Scope | Why Vantage needs it |
| - | - |
| `read` | Search and view issues, projects, teams, and comments in your Linear workspace. |
| `write` | Create and update issues and add comments on your behalf. |
Once connected, the FinOps Agent can:
* Search and view issues, projects, and teams.
* Create and update issues on your behalf.
* Add comments and collaborate in your Linear workspace.
Write actions are always bounded by your own Linear permissions. Because you authorize your own account, the Agent can only create or change what you could change directly in Linear.
Vantage stores only the data that is explicitly written into your FinOps Agent conversation responses or a [Canvas](/canvas) report; no ancillary Linear data is collected or stored outside of your conversation, and data retrieved through the connector is not used to train any models.
Vantage does not support authenticating to the Linear MCP with a Linear API key or a pre-generated OAuth token. Each user must connect through the standard interactive OAuth flow described below.
## Available Tools
The FinOps Agent connects to Linear's hosted MCP server and chooses the right tools automatically based on your question. Available functionality includes:
* **Find and read**: search and view issues, projects, teams, cycles, and comments.
* **Create and update**: create and update issues and add comments on your behalf.
The Agent only creates or modifies Linear content when you explicitly ask it to. For a write, it first confirms the target (the team and owner) and searches for an existing issue before creating a new one, and all writes are bounded by your own Linear permissions. In [Canvas](/canvas), the Linear MCP is read-only, so write actions are not available there. If a write returns an authorization or scope error, the Agent surfaces it and points you back to the **Linear MCP** settings page to reconnect rather than retrying.
## Connect the Linear MCP
As an **Organization Owner** or **Integration Owner**, click **Settings** in the top navigation. On the left navigation, select **Integrations**, then find the **MCP Connectors** section and select **Linear MCP**. In the **Organization Settings** tab, enable the connector for your organization.
If the page shows a banner asking you to enable the FinOps Agent, open the [FinOps Agent settings page](https://console.vantage.sh/settings/finops_agent) and enable it first, then return to the Linear MCP page.
On the **Linear MCP** page, open the **MCP Settings** tab and click **Connect Linear**. Vantage redirects you to Linear to complete the OAuth flow. Every user who wants to use the connector completes this step for their own account.
Sign in to Linear and authorize the requested access. After you approve, Linear redirects you back to Vantage and your connection status changes to connected.
Back in Vantage, confirm the Linear MCP shows as connected. You can now ask the FinOps Agent Linear-aware questions in the console or in Slack.
You can also connect Linear directly from an Agent conversation. When you ask the Agent to do something that needs Linear and you have not connected yet, it prompts you to authorize your account inline.
## Example Use Cases
Once the Linear MCP is connected, the FinOps Agent decides when to reach for Linear tools based on the question you ask. It can call Linear tools in the same turn it uses Vantage tools, combining cost data with your issue tracking.
For prompting best practices and more copy-paste examples, see the [FinOps AI Prompt Guide](/finops_ai_prompt_guide).
### Triage a Cost Anomaly Against Existing Work
When Vantage surfaces a cost spike, ask the Agent to search Linear for existing issues related to the affected service or team before you open a new one.
We have an anomaly on our EKS costs this week. Is there already a Linear issue tracking work on that cluster?
### Create an Issue From a Recommendation
Ask the Agent to create a Linear issue for a rightsizing recommendation, cost anomaly, or budget overrun, pre-populated with the underlying cost context. Name the target team so the Agent can create the issue without stopping to confirm where it belongs.
Create a Linear issue on the Product team for my top cost optimization recommendation this month, including the resource, current and recommended configuration, and estimated monthly savings.
### Route an Optimization to the Right Team
Ask which Linear team owns a given service or cost center so an optimization task lands with the right owner.
Which Linear team owns our data platform services? Create an issue there to investigate the Redshift cost increase.
### Track an Optimization Initiative
Reference a Linear project for an optimization initiative and ask the Agent to correlate its progress with cost trends in Vantage.
Look at our "Cloud Cost Reduction" Linear project and tell me whether the closed issues line up with the drop in our AWS spend this quarter.
## Troubleshooting
Enable the [FinOps Agent](/vantage_finops_agent) first from the [FinOps Agent settings page](https://console.vantage.sh/settings/finops_agent), then return to **Settings** > **Integrations** > **MCP Connectors** > **Linear MCP**.
An **Organization Owner** or **Integration Owner** must enable the Linear MCP for your organization before individual users can authorize their accounts. If you do not see the option to connect, ask an administrator to enable it from the [Integrations page](https://console.vantage.sh/settings/integrations).
Confirm the Linear MCP shows as connected for your user and that your question requires Linear context. The Agent prefers Vantage tools for pure cost questions and reaches for Linear when you ask about issues, projects, teams, or want to create or update an issue.
Your Linear OAuth grant may have been revoked or expired. Reconnect Linear from the **Linear MCP** page to re-authorize your account.
If you disconnect your own account, the Linear tools are no longer available to the FinOps Agent for you. If an administrator disables the connector for the organization, every user's Linear connection is disconnected. Previous conversations retain their historical responses based on your data retention period, but the Agent can no longer call Linear after it is disconnected.
# LiteLLM Enrichment
Source: https://docs.vantage.sh/litellm_enrichment
Attribute LLM spend to teams, users, applications, and features by running the Vantage collector alongside your LiteLLM proxy, which streams per-request token usage to Vantage and joins it to your provider costs.
Contact Sales (or [support@vantage.sh](mailto:support@vantage.sh)/your account team) to enable LLM Enrichment for your account and discuss availability.
Vantage reads per-request token usage from your [LiteLLM](https://docs.litellm.ai/) proxy and joins it to your model-provider costs. A Vantage **callback** loaded inside your LiteLLM process records one usage event per request (the upstream provider, model, token counts, and the metadata you attach) and hands it to the Vantage **collector**, a sidecar that batches and uploads that usage to Vantage. Vantage splits each matching cost row into enriched rows by token share and adds tags derived from your metadata, so you can filter and group that spend in [Cost Reports](/cost_reports), [Virtual Tags](/tagging), [Budgets](/budgets), and [Cost Alerts](/cost_alerts). Because the telemetry comes from your gateway, this surfaces attribution the provider bill never itemized, even when many applications share one API key.
LiteLLM Enrichment attributes costs for the model providers your proxy routes to and that you have connected as Vantage cost integrations: **OpenAI**, **Anthropic**, **AWS Bedrock**, **Google Cloud** (Vertex AI Gemini and Marketplace Claude), **Azure**, **SpaceXAI**, and **Baseten**. Vantage automatically routes each usage record to the matching provider's costs.
Unlike [Custom LLM Enrichment](/custom_llm_enrichment), [Cloudflare AI Gateway Enrichment](/cloudflare_ai_gateway_enrichment), and [AWS Bedrock LLM Enrichment](/aws_bedrock_enrichment), which read logs you deliver to an S3 bucket you own, LiteLLM Enrichment runs a Vantage-managed collector next to your proxy that pushes usage to Vantage. There is no customer S3 bucket to create and no AWS role to grant.
Enrichment is metadata-only. Vantage reads the provider, model, token counts, and the tags you attach to each request. It does not collect your LiteLLM prompt or completion content or credentials, and no such content is written to a Vantage-owned artifact. This data is not used to train any models.
## How It Works
The Vantage callback runs inside your LiteLLM process and emits one usage record per request to a local Vantage collector over a Unix socket. The collector compacts those records into batches, uploads them to a Vantage-managed bucket using short-lived presigned URLs, and Vantage joins that usage to your provider costs during each provider's cost ingestion.
See [How LLM Enrichment works](/llm_enrichment#how-it-works) for the shared indexing, join, split, and tag pipeline.
### How Cost Rows Are Split
Vantage splits each matching provider cost row into enriched rows, allocated proportionally by token share. Splits are additive, so the enriched rows always reconcile to the original total: usage your logs do not cover stays on a **leftover** row, and cost rows with no matching usage pass through unsplit. Enabling enrichment never changes your totals.
See the allocation formula, a worked example, and how leftover rows keep totals reconciled.
### Data Freshness and Backfill
Enrichment runs as part of each provider's existing cost ingestion, so it follows that provider's refresh cadence. Recent days are reprocessed within a rolling three-day window so late-arriving batches are picked up. See the [provider data refresh documentation](/provider_data_refresh) for per-provider timing.
A billing period is enriched whenever it is processed while an active collector exists, for as long as the matching batches remain available to Vantage. Enrichment begins from when your collector starts uploading usage; it does not backfill spend from before the collector was running. Late-arriving batches for recent days are picked up automatically within the rolling three-day window. Re-enrichment reads the already-normalized cost data, so it does not require a full cost re-import.
## Prerequisites
Before you begin, make sure:
* An active cost integration exists for at least one supported provider: [OpenAI](/connecting_openai), [Anthropic](/connecting_anthropic), [AWS](/connecting_aws), [Google Cloud](/connecting_gcp), [Azure](/connecting_azure), [SpaceXAI](/connecting_spacexai), or [Baseten](/connecting_baseten).
* Your Azure deployments in LiteLLM, if any, use the `azure/` (Azure OpenAI) or `azure_ai/` (Azure AI Foundry) model prefix. Vantage routes usage by the provider LiteLLM reports, so a deployment configured with the `openai/` prefix is reported as OpenAI even when its base URL points at Azure, and its usage will not match your Azure costs.
* You run a [LiteLLM proxy](https://docs.litellm.ai/docs/proxy/deploy) where you can install the Vantage callback and run the collector as a sidecar or adjacent container. The collector needs a persistent filesystem for its spool and outbound HTTPS access to Vantage Core and the presigned Amazon S3 URLs it returns.
* You have a [Vantage API token](/api/authentication) for the collector, in addition to the installation token you create in [Step 1](#step-1-create-the-source-and-copy-the-installation-token).
* You have a Vantage **Organization Owner** or **Integration Owner** role. See [Role-Based Access Control](/rbac).
## Set Up LiteLLM Enrichment
Setup has three steps: [create the source and copy the installation token](#step-1-create-the-source-and-copy-the-installation-token), [install the callback and deploy the collector](#step-2-install-the-callback-and-deploy-the-collector), and [configure which cost integrations to enrich](#step-3-configure-cost-integrations).
### Step 1: Create the Source and Copy the Installation Token
In Vantage, go to the [Integrations page](https://console.vantage.sh/settings/integrations). Under **LLM Enrichment**, add **LiteLLM**, then select **Connect Source**. Vantage provisions a collector integration and shows a **Collector Setup** screen.
On that screen, copy the **installation token** from **Step 1: Copy the Installation Token**. It looks something like `srvc_data_intgrtn_9f8e7d6c5b4a3f21`. This token authorizes your collector to upload usage to Vantage. You paste it into your collector configuration in the next step.
The installation token identifies this collector integration to Vantage. Treat it as a secret and supply it to the collector through your platform's secret management rather than committing it to a task definition or config file in plaintext.
### Step 2: Install the Callback and Deploy the Collector
LiteLLM Enrichment has two runtime pieces that work together:
* **Vantage callback:** A Python package loaded inside your LiteLLM proxy process that records each request's usage.
* **Vantage collector:** A sidecar container that receives events from the callback over a Unix socket, batches them, and uploads them to Vantage.
Install the [`vantage-litellm-callback`](https://pypi.org/project/vantage-litellm-callback/) package into the same Python environment as your LiteLLM proxy (the callback requires Python 3.10 or later), then register it so LiteLLM loads it.
Install the callback package, pinning the version that matches your collector image (the current release is `0.0.7`):
```bash theme={null}
pip install vantage-litellm-callback==
```
Official LiteLLM images may ship a virtual environment without `pip` on `PATH`. If `pip` is not found, bootstrap it first, then install into the same interpreter:
```bash theme={null}
/app/.venv/bin/python -m ensurepip
/app/.venv/bin/python -m pip install vantage-litellm-callback==
```
Register the callback in your LiteLLM configuration:
```yaml config.yaml theme={null}
litellm_settings:
callbacks:
- vantage_callback.callback_instance
```
Installing the package makes `vantage_callback` importable, so the callback path above resolves on its own. Some LiteLLM images only load callbacks from Python files next to `config.yaml`. If LiteLLM does not pick up the callback after install, place a shim at `/app/vantage_callback.py` (the same directory as `config.yaml`) that imports `callback_instance`.
The callback is fail-open: collector outages, dropped acknowledgements, or queue pressure never block or fail a provider request. Usage events are buffered in a bounded in-process queue and delivered by a background worker, so enabling it does not add a hard dependency to your request path.
Run the Vantage collector as a sidecar or adjacent container in the same environment as your LiteLLM proxy, using the published image on [Quay](https://quay.io/repository/vantage-sh/litellm-collector), pinned to a full version:
```text theme={null}
quay.io/vantage-sh/litellm-collector:
```
A release tag `vX.Y.Z` publishes the image tags `X.Y.Z`, `X.Y`, `X`, `latest`, and an immutable commit-SHA tag. Pin a full version tag (`X.Y.Z`) rather than `latest`; the current release is `0.0.7`.
Run the collector image and the `vantage-litellm-callback` package on the **same version**, and upgrade them together. The callback-to-collector socket protocol and the batch schema are versioned in lockstep, so a mismatched pair can drop or reject usage.
Give the collector a persistent local spool, a Unix socket shared with LiteLLM, and outbound network access to Vantage. Configure it through environment variables (or your platform's equivalent, such as a Helm value or a command-line flag):
| Variable | Description |
| - | - |
| `VANTAGE_CORE_URL` | **Required.** The Vantage Core API base URL, for example `https://api.vantage.sh`. It must use `https://`; the collector refuses to start with a plain `http://` URL. |
| `VANTAGE_API_TOKEN` | **Required.** A Vantage API token, used to request presigned upload URLs. |
| `VANTAGE_INTEGRATION_TOKEN` | **Required.** The installation token you copied in [Step 1](#step-1-create-the-source-and-copy-the-installation-token). Authorizes the collector's uploads for this integration. |
| `VANTAGE_COLLECTOR_ID` | A stable, per-instance identifier so Vantage can distinguish batch streams across replicas and restarts. Defaults to the hostname; keep it stable for the life of a spool. |
| `VANTAGE_SOCKET` (or `VANTAGE_COLLECTOR_SOCKET_PATH`) | The path to the Unix socket shared between LiteLLM and the collector, default `/var/run/vantage-collector/collector.sock`. The collector accepts either name; the callback uses `VANTAGE_COLLECTOR_SOCKET_PATH`, so set matching values on both. |
| `VANTAGE_SPOOL` | The persistent spool directory, default `/var/lib/vantage/spool`. It must be persistent and must not be shared by more than one collector. |
| `VANTAGE_METRICS_ADDRESS` | Optional. The address for the health and metrics endpoints, default `:9090`. See [Container Deployment Constraints](#container-deployment-constraints). |
A minimal collector configuration looks like this:
```bash theme={null}
VANTAGE_CORE_URL=https://api.vantage.sh
VANTAGE_API_TOKEN=
VANTAGE_INTEGRATION_TOKEN=
VANTAGE_COLLECTOR_ID=litellm-collector-1
VANTAGE_SOCKET=/var/run/vantage-collector/collector.sock
VANTAGE_SPOOL=/var/lib/vantage/spool
```
Set `VANTAGE_COLLECTOR_SOCKET_PATH` to the same socket path on the LiteLLM container so the callback and collector connect.
The same installation token can be reused across multiple LiteLLM deployments and across multiple collector replicas behind one proxy. Each collector instance still needs its own stable `VANTAGE_COLLECTOR_ID` and its own persistent spool so Vantage can keep each batch stream distinct.
Restart or redeploy your LiteLLM proxy so the callback loads and usage records begin flowing to the collector. The collector buffers usage locally and uploads a batch once it fills, reaches its size limit, or crosses a UTC-day boundary (by default, about every 10 minutes, offset slightly per collector so replicas do not upload at the same moment), so the first upload can lag the restart.
#### Container Deployment Constraints
The release collector image is built `FROM scratch`, has no shell, runs as UID/GID `65532`, and declares volumes for its spool and socket. These properties shape how you run it on any container platform; the notes below call out what that means, with ECS Fargate as a worked example.
Do not add shell-based health checks to the collector container. Because the image has no shell, `CMD-SHELL`, `wget`, and `curl` checks will not work. Instead, probe the collector's HTTP health endpoint, `GET /healthz`, on its metrics address (`:9090` by default, configurable with `VANTAGE_METRICS_ADDRESS`).
* **Health and metrics endpoints:** The collector serves `GET /healthz` for readiness and Prometheus `GET /metrics` on its metrics address (`:9090` by default). Use these for orchestrator health checks and monitoring. These endpoints are unauthenticated, so do not expose the metrics port outside your private network.
* **Memory:** Request at least 256 MiB for the collector container and set a 512 MiB limit unless your own load testing supports a different value. The collector sizes its internal buffers from the container's memory limit.
* **Per-task isolation:** Each task or pod needs its own socket and spool volumes; do not share a spool across tasks. Use a stable `VANTAGE_COLLECTOR_ID` per instance, such as the task hostname.
* **Shared socket:** Mount the same socket volume into both the LiteLLM and collector containers, and set `VANTAGE_COLLECTOR_SOCKET_PATH` (LiteLLM) and `VANTAGE_SOCKET` (collector) to that socket.
* **Secrets:** Supply `VANTAGE_API_TOKEN` and `VANTAGE_INTEGRATION_TOKEN` through a secret store (for example, AWS Secrets Manager), not as plaintext values in a task definition or Compose file.
* **Volume ownership (ECS Fargate):** Because the collector runs as UID `65532`, and Fargate's ephemeral volumes are root-owned, the collector may be unable to write its socket and spool by default. Override the collector task's `user` to `"0"`, or wrap the image with an entrypoint that `chown`s the mounts before dropping privileges.
For production, follow LiteLLM's [production deployment guidance](https://docs.litellm.ai/docs/proxy/deploy): run two or more stateless proxy replicas behind a load balancer, each with its own collector and persistent collector state, and route traffic only through the load balancer.
On hosts that run LiteLLM outside a container (for example, on a VM), you can run the collector as a `systemd` service instead of a sidecar: install the binary, create a non-login `vantage` user, and provide the same environment variables through a mode-`0600` environment file. The socket, spool, tokens, and provider selection all work the same way.
### Step 3: Configure Cost Integrations
Back on the **Collector Setup** screen in Vantage, under **Configure Cost Integrations**, select **Configure Providers** and choose which connected cost integrations should receive enrichment from this collector.
Unlike the other LLM Enrichment integrations, which scan your logs and detect providers for you, LiteLLM requires you to **choose exactly one cost integration per provider**. LiteLLM usage records do not include a provider account identifier, so Vantage cannot tell apart multiple integrations for the same provider and will not enrich a provider that has more than one integration selected.
Vantage enriches costs for the selected integrations on each provider's next data refresh. Provider cost integrations you connect later are not enriched automatically; return to the source's **Manage Providers** screen to enable them.
On the Collector Setup screen, the **Data Received** indicator shows **Waiting** until your first usage arrives, then **Received**, usually within several minutes of your first traffic after the restart. If it shows **Unavailable**, see the [Troubleshooting](#troubleshooting) section.
## Manage LiteLLM Enrichment Sources
Manage your collector from the [**LiteLLM** integration page](https://console.vantage.sh/settings/lite_llm_enrichment_sources). The **Connected Collectors** table lists each collector with its **Installation Token**, **Cost Providers**, **Status** (for example, **Pending** before an import starts, **Importing** while one runs, **Stable** once all imports succeed, **Warning** if only some imports fail, **Error** if an import fails, or **Paused** if the collector is stopped), and creation date. Each row has an **Edit** button and an ellipses (**...**) menu with **View import history** and, for collectors that are not paused, **Stop**.
The **Collector Setup** (Edit) screen also shows a **Data Received** indicator (**Waiting**, **Received**, or **Unavailable**) so you can confirm the collector is delivering usage independently of whether enrichment has run yet.
### Choose Which Integrations Are Enriched
Select **Edit** on the collector, then **Manage Providers**, to change which connected cost integrations receive enrichment. Remember that only one cost integration per provider can be enriched. Disabling an integration here stops going-forward enrichment for it but leaves its existing enriched history in place.
### View Import History
In the sources table, click the ellipses (**...**) next to a row and select **View import history**. This opens the collector's **Import History**, where the **Enrichment Runs** table shows every run for this collector.
The **Enrichment Runs** table lists one row per provider cost integration and billing period that ran enrichment, newest first, with columns for the **Integration** (and its account), **Status**, **Tokens Kept**, **Log Lines Kept**, **Bill Match**, **Billing Period**, and **Last Enriched At**. Lifecycle changes appear as their own rows: **Added** when enrichment is first enabled for an integration, and **Paused** or **Resumed** when you stop, disable, resume, or re-enable it.
The three percentages look similar but measure different things at different stages, so a low number in one column means something very different from a low number in another:
| Metric | Stage | Counts | A Low Value Means |
| - | - | - | - |
| **Tokens Kept** | Join | Tokens | Your logs were read fine, but the usage in them did not line up with your provider bill. |
| **Log Lines Kept** | Log Scan | Log lines | Vantage could not read or index many of your log lines, usually because records are malformed or missing required fields. |
| **Bill Match** | Join | Provider cost rows | Many provider cost rows received no logged usage at all, so they passed through unsplit. Often your logs cover only part of your traffic. |
A low percentage does not change your totals. Usage Vantage cannot attribute stays on a **leftover** row, the unallocated remainder of the original cost row, so the enriched rows always add back up to what the provider billed.
Select the **Tokens Kept** percentage on any run to open **Token Metrics**, which breaks that run down by disposition across the two stages and lets you view sample records for anything that did not make it through.
Full reference for the Import History screen: every column and status, how to read the three percentages, the Log Scan and Join dispositions with a fix for each, sample record fields, and a troubleshooting table.
### Stop a Collector
To stop a collector, click the ellipses (**...**) next to the row and select **Stop**, then confirm in the **Stop enrichment source** dialog. This is a soft deactivation, not a hard delete: Vantage stops enriching new cost data for that collector, but your existing enriched history is left unchanged, and the collector stays visible in the list so you can bring it back at any time.
Stopping a collector does not re-import or roll back already-enriched costs. Going-forward enrichment simply pauses until you resume it. Stopping in Vantage does not stop the collector process itself. To stop sending usage, also stop the collector container.
### Resume a Collector
To resume a stopped collector, select **Resume** in its row. Resuming restarts going-forward enrichment for the integrations that were active when you stopped it (integrations you had already disabled individually stay disabled) and reopens the Edit screen so you can adjust the selection.
## View Enriched Costs on Cost Reports
Once enrichment runs, a single provider cost line is split into multiple rows, each carrying enrichment tags. You can filter and group by these tags anywhere tags are supported: [Cost Reports](/cost_reports), [Virtual Tags](/tagging), [Budgets](/budgets), and [Cost Alerts](/cost_alerts).
Because enrichment splits (allocates) your provider costs, enrichment tags behave like Vantage's [cost allocation tags](/tagging#cost-allocation-tags): you can build a Virtual Tag on them, but a cost can be allocated only once, so an enrichment tag can belong to only [one allocation chain](/tagging#virtual-tag-allocation-rules).
### Enrichment Tag Reference
The callback builds each usage record's tags from your LiteLLM request metadata. It merges the `metadata.tags` and `metadata.spend_logs_metadata` objects (when both set the same key, `metadata.tags` wins), and `metadata.tags` may also be a list of `key:value` strings. It also promotes these LiteLLM request attributes to tags automatically, under the same key names: `organization_id`, `organization_alias`, `team_id`, `team_alias`, `project_id`, `project_alias`, `user_id`, `end_user_id`, and `key_alias`. Tag keys must be strings, and values must be strings, booleans, integers, or floats (null, nested, and array values are dropped). Each record carries at most 32 tags, with keys up to 128 characters and string values up to 256 characters.
| Tag key | Description | Example value |
| - | - | - |
| *Your metadata keys* | Each key the callback captures from `metadata.tags`, `metadata.spend_logs_metadata`, and the promoted LiteLLM attributes becomes a tag on the enriched rows for that usage slice. | `team_alias`, `user_id`, `feature` |
| `vntg:ai:model` | The normalized model identifier that generated the cost, derived from the cost row. Vantage adds it to every enriched row. | `vntg:ai:model=gpt-5.2-2025-12-11` |
| `vntg:ai:model_provider` | The provider family inferred from the model (for example, OpenAI, Anthropic, Google), added automatically alongside `vntg:ai:model` when the family is recognized. | `vntg:ai:model_provider=OpenAI` |
| `vntg:ai:token_type` | The token kind the enriched row covers: `input`, `output`, `cache_read`, or `cache_write`. Added automatically to every enriched row. | `vntg:ai:token_type=input` |
| `vntg:ai:service_tier`, `vntg:ai:provider_region` | Promoted from the matching usage fields when present and renamed under the prefix, so you can group and allocate by them too. Batch usage is kept separate and surfaced as `vntg:ai:service_tier=batch`. | `vntg:ai:service_tier=default` |
| *Provider's existing tags* | Any tags Vantage already puts on the provider's cost rows are preserved on the enriched rows. If one of these shares a key with a slice tag, the enrichment value wins. | — |
Your own metadata keys appear as tags without a provider prefix. The fields Vantage derives and adds itself, such as the model identifier, carry a `vntg:ai:` prefix (for example, `vntg:ai:model`); this keeps them distinct from your keys and consistent with the AI tags Vantage applies to provider costs. Because a key like `team_alias` is not provider-namespaced, it lines up across OpenAI, Anthropic, and the other providers, so you can group your entire AI stack by one `team_alias` tag. Consistent key naming matters: `team` and `Team` are two different keys.
Enriched rows retain the provider's existing tags and add the Vantage-managed `vntg:ai:*` tags (such as `vntg:ai:model`); split rows also carry the tags from their usage slice. When a slice tag and an existing tag use the same key, the enrichment value wins. The leftover row (usage not covered by the collector) keeps the provider's existing tags and the applicable `vntg:ai:*` tags but carries none of the slice tags. Request identifiers are never turned into tags. Vantage may also apply a tag denylist to drop noisy or sensitive keys before they become tags.
Enrichment tags behave like any other provider tag in the console:
* **To group:** open the **Group By** menu, select **Tag**, and choose the tag key, for example `vntg:ai:model`, or one of your own keys such as `team`.
* **To filter:** open the **Filters** menu, click **New Rule**, select **Tag**, choose the **Tag Key**, then pick an operator and one or more values.
The tag keys appear in the **Tag Key** dropdown once enriched costs exist. If you use a handful of keys often, mark them as [preferred tags](/tagging#preferred-tags) so they sort to the top of these menus.
## Troubleshooting
The collector has not uploaded usage yet. Confirm that:
* Your application is sending traffic through the LiteLLM proxy, and LiteLLM was restarted after you added the callback.
* The callback is registered in `litellm_settings.callbacks` as `vantage_callback.callback_instance` and is importable in the LiteLLM process (installed with `pip`, or mounted so `/app` is on the import path).
* The collector container is running, has outbound network access to Vantage, and shares the Unix socket with LiteLLM (`VANTAGE_COLLECTOR_SOCKET_PATH` matches on both). If the collector exits right after it starts, confirm `VANTAGE_CORE_URL` begins with `https://`.
* `VANTAGE_INTEGRATION_TOKEN` matches the installation token from [Step 1](#step-1-create-the-source-and-copy-the-installation-token), and `VANTAGE_API_TOKEN` is a valid Vantage API token with integration permissions.
Vantage could not confirm the collector's uploads. This usually means the collector cannot reach Vantage or its tokens are rejected. Confirm outbound HTTPS access, that `VANTAGE_CORE_URL` uses `https://`, and that `VANTAGE_API_TOKEN` and `VANTAGE_INTEGRATION_TOKEN` are set correctly. If it persists, contact [Vantage Support](mailto:support@vantage.sh).
**Pending** means Vantage has not run an enrichment import for this source yet. Enrichment runs during each provider's regular cost ingestion, so a newly connected source shows **Pending** until the next data refresh of a provider it enriches. See the [provider data refresh documentation](/provider_data_refresh) for per-provider timing. If the status is still **Pending** after that refresh, check the following:
* The **Data Received** indicator on the collector's **Collector Setup** screen. **Waiting** means the collector has not uploaded usage yet: finish [Step 2](#step-2-install-the-callback-and-deploy-the-collector) and see the **Waiting** entry above.
* If **Data Received** shows **Received**, confirm that at least one cost integration is selected under **Configure Providers** ([Step 3](#step-3-configure-cost-integrations)), with exactly one integration per provider.
* Confirm the provider has exactly one cost integration selected on the **Manage Providers** screen. A provider with more than one integration selected is not enriched because LiteLLM usage does not carry an account identifier.
* Confirm the provider is one of the supported providers and that its cost integration is active.
* For Azure, confirm your LiteLLM deployments use the `azure/` or `azure_ai/` model prefix. Usage from an `openai/` deployment that points at Azure is reported as OpenAI. See [Prerequisites](#prerequisites).
* Allow a full data refresh for that provider to complete after connecting. Enrichment applies on the next refresh.
Enrichment can only split costs by dimensions present in your usage. Costs pass through without allocation splits when any of the following is true:
* There is no active collector for the account, or usage has not been ingested for that billing period.
* The cost row's model or token type could not be matched to a logged request for that provider, date, and token kind.
* Records were skipped during ingestion because a required field was missing, the provider was blank or unsupported, the model was blank or could not be matched to your provider cost data, the request was not successful, or no usage value was a positive integer.
Confirm the request went to a supported provider, carries a matching model, and has at least one positive usage count.
Enrichment tags appear in the console as regular provider tags. To confirm what was enriched:
* **Check coverage in Import History:** Open the source's [Import History](/llm_enrichment_import_history) and review **Tokens Kept** (the share of your logged tokens Vantage attached to a cost row) and **Bill Match** (the share of eligible provider cost rows that received logged usage) for each integration and billing period.
* **Check a Cost Report:** Filter to the provider, then group by one of your own tag keys. Costs from requests that carried that key show its values. The leftover row (the portion of the bill your usage did not cover) and any usage sent without that key appear as **Not tagged with** the key name.
Totals should not change. Splits are additive and always sum to the original cost row to the cent, even when multiple sources are connected. If a total appears different, this is not expected behavior; contact [Vantage Support](mailto:support@vantage.sh).
## Use Cases
Each row below shows example dimensions to attach to your LiteLLM requests and what that attribution enables in Vantage. Attach custom dimensions through LiteLLM's `metadata.tags` or `metadata.spend_logs_metadata`; LiteLLM's organization, team, project, user, end-user, and key attributes are captured automatically as `organization_id`, `organization_alias`, `team_id`, `team_alias`, `project_id`, `project_alias`, `user_id`, `end_user_id`, and `key_alias`. The key names are examples; you choose your own. All rows assume the collector is running and delivering usage.
| Use Case | Attach via metadata | What It Enables |
| - | - | - |
| Chargeback by team | `team_alias` or `team_id` (promoted automatically) | Group a [Cost Report](/cost_reports) by `team_alias` for per-team LLM chargeback, or roll `team_alias` values into a business hierarchy with a [Virtual Tag](/tagging). |
| Per-user attribution on shared keys | `user_id` or `key_alias` (promoted automatically) | Attribute spend to the individual or API key behind each request even when many callers share one provider key, which the provider bill cannot break apart. |
| Per-feature or per-workflow spend | `feature`, `workflow` in `metadata.tags` | Compare cost per product feature or workflow (for example, `summarization` vs. `classification`). |
| Model and effort mix | `mode`, `effort` in `metadata.tags` | Spot macro patterns (which models and effort levels dominate spend) and outliers to guide defaults. The `vntg:ai:model` tag is added automatically, so you do not need to attach it. |
| Environment separation | `environment` in `metadata.tags` | Filter non-production inference out of showback reports, or budget each environment (`production`, `staging`) separately. |
## Frequently Asked Questions
OpenAI, Anthropic, AWS Bedrock, Google Cloud (Vertex AI Gemini and Marketplace Claude), Azure, SpaceXAI, and Baseten. Vantage routes each usage record to the matching provider's costs based on the provider your proxy called. Azure support covers direct Azure integrations; Azure CSP billing accounts are not supported.
Both attribute LLM spend from gateway telemetry. With [Custom LLM Enrichment](/custom_llm_enrichment), you emit records in the Token Cost Allocation Specification and deliver them to an S3 bucket you own, and Vantage reads that bucket. With LiteLLM Enrichment, Vantage runs a managed collector next to your LiteLLM proxy that pushes usage to Vantage, so there is no bucket to create and no AWS role to grant. Use LiteLLM Enrichment when your traffic runs through a LiteLLM proxy.
No. You add the Vantage callback to your LiteLLM proxy configuration and run the collector sidecar; your application keeps calling LiteLLM as it does today. To attribute costs by your own dimensions, attach metadata to your LiteLLM requests as you normally would.
Yes. The same installation token can be reused across multiple LiteLLM deployments and across multiple collector replicas behind one proxy. Each collector instance needs its own stable `VANTAGE_COLLECTOR_ID` and its own persistent spool so Vantage can keep each batch stream distinct.
You need the **Organization Owner** or **Integration Owner** role to connect the source. Viewing the enriched costs does not require a special role; the resulting tags follow the same access rules as other cost data. See [Role-Based Access Control](/rbac).
No. Splits are additive and always sum to the original cost row. Existing provider-level reports continue to show the same totals; enrichment only makes new dimensions available on the underlying rows.
No. Enrichment is metadata-only. The collector sends the provider, model, token counts, and the tags you attach. Prompt and completion content and credentials are never collected, stored, or written to a Vantage-owned artifact.
# LLM Enrichment
Source: https://docs.vantage.sh/llm_enrichment
How Vantage LLM Enrichment attributes model-provider spend to teams, users, applications, and features by joining your token-usage telemetry to provider costs.
Contact Sales (or [support@vantage.sh](mailto:support@vantage.sh)/your account team) to enable LLM Enrichment for your account and discuss availability.
Vantage LLM Enrichment attributes your model-provider spend to the teams, users, applications, and features that generated it. Each source delivers per-request token usage and the tags you attach; Vantage joins that usage to your provider costs and splits each matching cost row into enriched, tagged rows you can filter and group in [Cost Reports](/cost_reports), [Virtual Tags](/tagging), [Budgets](/budgets), and [Cost Alerts](/cost_alerts). This surfaces attribution the provider bill never itemized, even when many applications share one API key.
Choose the source that matches how your LLM traffic is delivered:
Deliver your own per-request telemetry in the common schema to an S3 bucket Vantage reads.
Vantage reads your encrypted Cloudflare AI Gateway Logpush logs from S3.
Vantage reads the Bedrock Model Invocation Logs AWS already writes for you.
A Vantage collector next to your LiteLLM proxy uploads per-request usage for you.
Enrichment is metadata-only. Vantage reads the provider, model, token counts, and the tags you attach to each request. It does not collect or store your prompt or completion content or credentials, and no such content is written to a Vantage-owned artifact. This data is not used to train any models.
## How It Works
However usage reaches Vantage, every source runs through the same pipeline and joins to your provider costs during that provider's cost ingestion.
| Stage | What Happens |
| - | - |
| 1. Emit | Your application, gateway, or the provider records per-request usage: the provider, model, token counts, and the tags you attach to attribute cost by. |
| 2. Deliver | The usage reaches Vantage. Depending on the source, you deliver logs to an S3 bucket you own, or a Vantage collector uploads them for you. |
| 3. Index | Vantage normalizes and deduplicates records and aggregates tokens into a per-provider usage index keyed by date, provider, model, and token kind. |
| 4. Join and split | During each provider's cost ingestion, Vantage joins each cost row to the usage index and splits it proportionally by token share. |
| 5. Tag | Each enriched row is written with the tags from its usage slice plus Vantage-managed `vntg:ai:*` tags. |
| 6. Analyze | The enriched, tagged costs become available in Cost Reports, Virtual Tags, Budgets, and Alerts. |
## How Cost Rows Are Split
For each matched cost row, the cost is allocated proportionally across the tag slices present in your usage, weighted by token usage:
$$
\text{attributed cost} = \text{cost row} \times \frac{\text{slice tokens}}{\text{total matched tokens for row}}
$$
Splits are additive: the sum of the enriched rows always equals the original cost row to the cent. Existing provider-level reports continue to show the same totals; enrichment only *makes new dimensions available* on the underlying rows.
Consider the below example: one cost row for `gpt-5.2-2025-12-11` is `$100` for the day, covering 100M input tokens. Your usage for that day groups into these tag slices:
| Tag slice | Input tokens | Tags |
| - | - | - |
| Slice A | 50M | `team=growth, purpose=summarization` |
| Slice B | 30M | `team=research, purpose=eval` |
| (usage not covered) | 20M | (none) |
After enrichment, the single `$100` row becomes three rows:
| Amount | `team` | `purpose` | Source |
| - | - | - | - |
| `$50` | growth | summarization | Enriched split |
| `$30` | research | eval | Enriched split |
| `$20` | — | — | Leftover |
The total is unchanged at `$100`. The **leftover** row carries the portion of the cost row's tokens that your usage does not cover; it keeps the provider's existing tags and the `vntg:ai:model` tag but none of the slice tags, so totals always reconcile and no dollars are lost. Cost rows with no matching usage pass through without allocation splits.
The split reconciles in both directions. When your usage covers **fewer** tokens than the cost row, the uncovered remainder stays on the leftover row (as shown above). When your usage reports **more** tokens than the bill, Vantage scales the logged groups down proportionally to the billed amount. Either way, the enriched rows sum to the original cost row and the provider bill remains the source of truth. See the [Import History disposition reference](/llm_enrichment_import_history) for how each case surfaces per run.
## Enrichment Tags
Once enrichment runs, a single provider cost line is split into multiple rows, each carrying enrichment tags. You can filter and group by these tags anywhere tags are supported: [Cost Reports](/cost_reports), [Virtual Tags](/tagging), [Budgets](/budgets), and [Cost Alerts](/cost_alerts).
Because enrichment splits (allocates) your provider costs, enrichment tags behave like Vantage's [cost allocation tags](/tagging#cost-allocation-tags): you can build a Virtual Tag on them, but a cost can be allocated only once, so an enrichment tag can belong to only [one allocation chain](/tagging#virtual-tag-allocation-rules).
Enriched rows carry two kinds of tags: the tags you attach to your requests, and the Vantage-managed `vntg:ai:*` tags that Vantage derives.
| Tag key | Description | Example value |
| - | - | - |
| *Your tag keys* | Every tag you attach to a request becomes a tag on the enriched rows for that usage slice, with no provider prefix. | `team`, `purpose`, `environment` |
| `vntg:ai:model` | The normalized model identifier that generated the cost, derived from the cost row. Added to every enriched row. | `vntg:ai:model=gpt-5.2-2025-12-11` |
| `vntg:ai:model_provider` | The provider family inferred from the model (for example, OpenAI, Anthropic, Google), added when the family is recognized. | `vntg:ai:model_provider=OpenAI` |
| `vntg:ai:token_type` | The token kind the enriched row covers: `input`, `output`, `cache_read`, or `cache_write`. Added to every enriched row. | `vntg:ai:token_type=input` |
| *Provider's existing tags* | Any tags Vantage already puts on the provider's cost rows are preserved on the enriched rows. If one shares a key with a slice tag, the enrichment value wins. | — |
Your own tag keys appear exactly as you send them, with no provider prefix, so a key like `team` lines up across every provider and you can group your entire AI stack by one tag. The dimensions Vantage derives carry a `vntg:ai:` prefix to keep them distinct and consistent across providers. Each source also promotes provider-specific `vntg:ai:*` tags where the data supports them (for example, `vntg:ai:service_tier`, `vntg:ai:provider_region`, `vntg:ai:operation`, or `vntg:ai:principal_id`); see each source's page for its exact set and [Managed AI Tags](/managed_ai_tags) for the full cross-provider schema.
Enrichment tags behave like any other provider tag in the console:
* **To group:** open the **Group By** menu, select **Tag**, and choose the tag key, for example `vntg:ai:model` or a tag key such as `team`.
* **To filter:** open the **Filters** menu, click **New Rule**, select **Tag**, choose the **Tag Key**, then pick an operator and one or more values.
The tag keys appear in the **Tag Key** dropdown once enriched costs exist. If you use a handful of keys often, mark them as [preferred tags](/tagging#preferred-tags) so they sort to the top of these menus.
## Data Freshness and Backfill
Enrichment runs as part of each provider's existing cost ingestion, so it follows that provider's refresh cadence. Recent days are reprocessed within a rolling three-day window so late-arriving usage is picked up. See the [provider data refresh documentation](/provider_data_refresh) for per-provider timing.
A billing period is enriched whenever it is processed while an active source exists, for as long as the matching usage remains available to Vantage. Re-enrichment reads the already-normalized cost data, so it does not require a full cost re-import. Backfill behavior varies by source; see each source's page for specifics.
## Import History
Every source records an **Import History** for each run, showing how much of your logged usage became enriched cost and where the rest went. See [LLM Enrichment Import History](/llm_enrichment_import_history) for how to read every column, status, and disposition.
# LLM Enrichment Import History
Source: https://docs.vantage.sh/llm_enrichment_import_history
Understand every column, status, and percentage on the Import History screen for LLM Enrichment sources.
Every LLM Enrichment source has an **Import History** screen that answers one question: for a given provider and billing period, how much of your logged usage actually became enriched cost, and where the rest went. This page explains every column, status, and number on that screen.
Import History works the same way for all enrichment integrations, and you reach it the same way from each one: [Custom LLM Enrichment](/custom_llm_enrichment#view-import-history), [Cloudflare AI Gateway Enrichment](/cloudflare_ai_gateway_enrichment#view-import-history), and [AWS Bedrock LLM Enrichment](/aws_bedrock_enrichment#view-import-history).
In the sources table, select the **bucket name** to open that source's details page, which shows the **Enrichment Runs** table for that bucket.
The screen has two levels: the **Enrichment Runs** table gives you one line per run, and the **Token Metrics** screen behind it breaks a single run down into the two stages that can lose usage.
## Enrichment Runs Table
The table lists one row for each combination of provider cost integration (a connected provider account, such as a single OpenAI project or AWS account) and billing period that ran enrichment. Rows are ordered by the most recent run first. When a billing period is enriched more than once, only the latest run for that period appears. Re-enrichment replaces the row rather than adding a new one.
Enrichment runs in two stages, and the columns below report on both. In the **log scan**, Vantage reads your log files and builds an index of the token usage it finds. Your logs carry one record per request, written one record per line, so a log line and a log record are the same thing. In the **join**, Vantage matches that indexed usage to your **cost rows**, meaning the individual line items on your provider's bill.
| Column | What It Shows |
| - | - |
| **Integration** | The provider cost integration this run enriched, with the provider account (for example, an OpenAI project or an AWS account ID) on the second line. Two rows can name the same provider and differ only by account, so the second line is what tells them apart. |
| **Status** | The outcome of the run. See [Status Values](#status-values). |
| **Tokens Kept** | The share of indexed tokens that Vantage attached to a cost row. This is the only cell that contains a link: where a run has a percentage, select it to open [Token Metrics](#token-metrics-log-scan-and-join) for that run. |
| **Log Lines Kept** | The share of log lines Vantage could read and index. Lines expected to skip, like duplicates or failed requests, are left out of this number rather than counted against it. |
| **Bill Match** | The share of the provider cost rows Vantage tried to enrich that received logged usage. In other words, of the bill lines that could take logged usage, how many actually got some. Rows that carry no token usage, such as non-LLM charges, are not counted in either half of this number. |
| **Billing Period** | The period the run covered. A full calendar month shows as `Jul 2026`; a partial period shows as a date range. |
| **Last Enriched At** | When this enrichment run finished. The table sorts on this value, so the newest run is always at the top. |
Lifecycle changes appear as their own rows, mixed in with the runs by date: **Added** when enrichment is first enabled for an integration, and **Paused** or **Resumed** when you stop, disable, resume, or re-enable it. These rows record an event rather than a run, so they have no billing period and show `-` in all three percentage columns.
If the table shows an **Import history unavailable** alert, the page could not load the history data. Select **Retry**. If the table is empty and shows **No data available.**, no enrichment run has recorded a result for this source yet; this is expected until the provider's next data refresh completes.
## Status Values
| Status | What It Means |
| - | - |
| **Stable** | The run completed and wrote enriched cost rows. This is the healthy state. |
| **Warning** | The run found your logs but produced no enriched output. |
| **Error** | The run failed. The failure reason is shown on the source's row in the sources table on the integration page, not here. |
| **Paused** | Enrichment is stopped for this source or integration. Also appears as a lifecycle marker row at the moment you stopped it. |
| **No logs** | Vantage found no usable logs for this billing period, so there was nothing to enrich. Common for periods before you started delivering logs, or for a period where delivery to your bucket stopped. |
| **Added**, **Resumed** | Lifecycle marker rows, not runs. See [Enrichment Runs Table](#enrichment-runs-table). |
| **Unknown** | An unrecognized state. Contact [Vantage Support](mailto:support@vantage.sh) if a row stays in this state. |
Each row records a run that has already finished, so you will not see in-progress states like **Pending** or **Importing** here. Those describe the source as a whole and appear on the sources table on the integration page.
One message can appear in red beneath the status badge: `Multiple cost integrations share this bucket and the logs have no resource_account_id.` More than one cost integration for the same provider reads from this bucket, and your log records do not say which account each request belongs to. Vantage withholds that usage rather than attributing it to the wrong account. Add `resource_account_id` to your records, or point each integration at its own bucket.
## Reading the Three Percentages
The three percentages (Log Lines Kept, Tokens Kept, and Bill Match) look similar but measure different things at different stages, so a low number in one column tells you something very different from a low number in another. In short, Log Lines Kept is about your logs, while Tokens Kept and Bill Match are about matching those logs to the bill. Enrichment brings two streams together, the usage in your logs and the cost rows on your provider bill, and each arrow below is labeled with the percentage that measures that step:
```mermaid theme={null}
flowchart LR
Logs["Your log files in S3"] --> Scan["Log Scan"]
Scan -->|"Log Lines Kept"| Join["Join"]
Bill["Your provider bill"] -->|"Bill Match"| Join
Join -->|"Tokens Kept"| Enriched["Enriched cost rows"]
```
| Metric | Stage | Counts | A Low Value Means |
| - | - | - | - |
| **Log Lines Kept** | Log Scan | Log lines | Vantage could not read or index many of your log lines. The problem is in the logs themselves: malformed log records, missing required fields, or unreadable timestamps. |
| **Tokens Kept** | Join | Tokens | Your logs were read fine, but the usage in them did not line up with your provider bill. The problem is in matching, not in the logs. |
| **Bill Match** | Join | Provider cost rows | Many of your provider's cost rows received no logged usage at all, so they passed through unsplit. Often this means your logs cover only part of your traffic. |
A few things to keep in mind when you read these numbers:
* **Bill Match is calculated for the entire cost import:** If more than one enrichment source feeds the same cost integration, they share the same Bill Match value.
* **Tokens Kept and Log Lines Kept are not comparable to each other:** One counts tokens after the join, the other counts log lines before it. It is normal to see a high Log Lines Kept alongside a lower Tokens Kept.
* **A low percentage does not change your totals:** usage Vantage cannot attribute stays on a **leftover** row, the unallocated remainder of the original cost row, so the enriched rows always add back up to what the provider billed.
For the current month, the two most recent days are left out of these percentages (and out of the Token Metrics behind them). Vantage usually receives your logs before your provider's bill for the same day arrives, so it waits about two days for the bill to catch up. Scoring those days early would make the numbers look artificially low. Finished months are not affected.
## Token Metrics: Log Scan and Join
Select the **Tokens Kept** percentage on any run to open the **Token Metrics** screen.
The screen has two sections, **Log Scan** and **Join**, one for each stage. Both use the same columns:
| Column | What It Shows |
| - | - |
| **Disposition** | What happened to this group of tokens. |
| **Total Tokens** | All four token kinds added together (i.e., the Uncached Input, Output, Cache Read, and Cache Write columns that follow). |
| **Uncached Input** | Input tokens that were not served from a cache. |
| **Output** | Tokens the model generated. |
| **Cache Read** | Input tokens read from a cache. |
| **Cache Write** | Input tokens written to a cache. |
Each section starts with a shaded total row and ends with a shaded **Kept** row. Everything between them is usage that did not make it through that stage. Read a section top to bottom: the total at the top, the reasons in the middle, and what survived at the bottom.
In both tables, any reason row that carried tokens is a link. Select it to open [sample records](#view-sample-records): up to 25 real examples of the affected requests, which are the fastest way to see what actually went wrong. The shaded total rows are never links, and neither are **Duplicate event ID** or **Missing event ID**, which Vantage does not keep samples for.
### Log Scan Dispositions
Log Scan covers reading your log files and building the usage index. It starts from **Tokens in logs**, the total Vantage read for the period, and ends at **Kept**, the tokens handed to the join.
This table counts tokens, while the **Log Lines Kept** percentage on the previous screen counts log lines, so the two do not line up one for one. A single large request can move the token numbers here far more than it moves the log line percentage.
| Disposition | What It Means | What To Do |
| - | - | - |
| **Tokens in logs** | Every token Vantage read from your log objects for this period. This is the starting total. | Nothing; this is the baseline. |
| **Duplicate event ID** | Another record for the same day already used this identifier. Vantage keeps the record with the highest token count and drops the rest. | Usually expected if your pipeline can deliver a record more than once. Investigate only if the number is large relative to your traffic. |
| **Missing event ID** | The record had no identifier Vantage could use to deduplicate it. | Emit a stable, unique identifier on every record. |
| **Invalid record** | The line was not a JSON object Vantage could parse. | Confirm you write one JSON object per line, with no wrapping array and no truncated lines. |
| **Invalid metadata** | The record's metadata field was missing or was not an object. | Confirm your metadata is emitted as a key/value object. |
| **Invalid timestamp** | The timestamp was blank or could not be read as a date, so Vantage could not tell which billing day the record belongs to. | Emit UTC timestamps in a standard format. |
| **Missing model** | The record named no model, or the model value was blank after normalization. | Emit the model exactly as the provider reports it. |
| **Non-success status** | The request was not successful, so it is not billable usage. | Expected. These are requests that failed, were rate limited, or returned an error. |
| **Blank join ID** | The value Vantage joins on (the normalized model) was empty. | Same fix as **Missing model**: emit a model on every record. |
| **Unknown join ID** | A model was present, but Vantage could not match it to a model it recognizes in your cost data. | Check for typos, internal aliases, or a model your provider bill does not itemize. |
| **Other** | A drop reason that does not fall into the categories above. | Uncommon. Open its sample records to see what these are. |
| **Kept** | Tokens that made it into the usage index and were passed to the join. | Nothing; this is the surviving total. |
### Join Dispositions
Join covers matching indexed usage to your provider's cost rows. It starts from **Tokens indexed**, which equals the **Kept** value from Log Scan, and ends at **Kept**, the tokens that were allocated onto cost rows.
Each disposition names the point where matching stopped. Vantage first matches on the model and token kind, then narrows the result by account, API key, and calling identity.
| Disposition | What It Means | What To Do |
| - | - | - |
| **Tokens indexed** | Every token the Log Scan kept and handed to the join. This is the starting total. | Nothing; this is the baseline. |
| **Ambiguous sibling withheld** | Several cost integrations for the same provider share this bucket and the logs do not say which account each request belongs to, so Vantage withheld the usage rather than guessing. | Add `resource_account_id` to your records, or give each integration its own bucket. |
| **No matching bill row** | There was no cost row for that day, provider, model, and token kind. | The most common cause is a model your provider bill does not itemize separately, or a day whose bill has not landed yet. Recent days often resolve themselves on the next refresh. |
| **Ambiguous sibling scope empty** | The usage matched a cost row, but narrowing by account produced nothing because of the same shared-bucket ambiguity described above. | Same fix as **Ambiguous sibling withheld**. |
| **Account scope empty** | The usage matched on model and token kind, but no cost row came from the same provider account. | Confirm the `resource_account_id` in your logs matches the account on the connected cost integration. |
| **API key scope empty** | The usage matched, but no cost row carried the same API key identity. | Confirm the API key identifier in your logs matches the one your provider reports on the bill. |
| **Principal scope empty** | The usage matched, but no cost row carried the same calling identity (IAM principal). | Applies to [AWS Bedrock](/aws_bedrock_enrichment#iam-principal-normalization). Confirm the principal in your logs matches the caller identity on your cost rows. |
| **Bill demand short of log usage** | Matching succeeded on every field, but the bill reported less usage than your logs did, so the surplus tokens had no cost left to attach to. | Normal and not an error. Your logs simply counted more tokens than the provider billed for. No cost is lost. |
| **Kept** | Tokens that were allocated onto cost rows and became enriched, tagged spend. | Nothing; this is the surviving total. |
Unmatched tokens do not change your totals. Whatever portion of a cost row your logs did not account for stays on a **leftover** row, which keeps the provider's existing tags but none of your enrichment tags, so the enriched rows always add back up to the original cost row to the cent.
## View Sample Records
Where a disposition name appears as a link, select it to open a dialog with up to 25 sample records for that disposition.
* **Samples from Log Scan section:** Show the log record as Vantage read it, with your custom tags removed, plus the reason it was not indexed. Compare a sample to a record you expect to work and look for the missing or malformed field.
* **Samples from Join section:** Always name the `model` and `usage_kind` that went unmatched, and most dispositions add the fields described below. **Bill demand short of log usage** is the exception and shows only `model` and `usage_kind`, because nothing failed to match: the bill simply ran out of usage to attach.
A Log Scan sample is your own record with tags removed and the skip reason appended, so you can read it against a record you know works. In the example below, the application sent an internal alias instead of the model name the provider reports, so Vantage could not resolve it:
```json Log Scan sample: unknown join ID theme={null}
{
"event_id": "ail_9f2c41ba7d",
"timestamp": "2026-07-14T09:22:41.108Z",
"provider": "openai",
"model": "gpt5-mini-internal",
"resource_account_id": "proj_abc123",
"service_tier": "default",
"usage": {
"input_tokens": 1840,
"output_tokens": 96
},
"reason": "unknown_join_id"
}
```
A join sample describes one unmatched join key rather than one request. The record below never found a cost row at all: `stage` is `not_joined`, `matched_on` is empty because matching stopped at the very first comparison, and `failed_on` names the model as the reason.
```json Join sample: no matching bill row theme={null}
{
"model": "default:gpt-5.2-2025-12-11",
"usage_kind": "input",
"stage": "not_joined",
"matched_on": [],
"failed_on": "model",
"failed_on_log_values": [],
"log_records_indexed": 214,
"log_records_matched": 0,
"log_records_unmatched": 214
}
```
This next record got much further. It matched a cost row on the model and token kind, then lost it when Vantage narrowed by provider account. Because it reached the `not_matched` stage, `failed_on_log_values` shows the account identifier your logs actually carried, which you can compare against the account on the connected cost integration.
```json Join sample: account scope empty theme={null}
{
"model": "default:gpt-5.2-2025-12-11",
"usage_kind": "output",
"stage": "not_matched",
"matched_on": ["model", "usage_kind"],
"failed_on": "resource_account_id",
"failed_on_log_values": ["proj_abc123"],
"log_records_indexed": 512,
"log_records_matched": 0,
"log_records_unmatched": 512
}
```
**Bill demand short of log usage** is the one join disposition whose samples look different. Nothing failed to match, so there is no `stage`, `matched_on`, or `failed_on`. The record names only the model and token kind that had surplus tokens. This is expected, not an error.
```json Join sample: bill demand short of log usage theme={null}
{
"model": "default:gpt-5.2-2025-12-11",
"usage_kind": "input"
}
```
A join sample can include the following fields:
| Field | What It Tells You |
| - | - |
| `model` | The join key for the unmatched usage. See [Join Key Format](#join-key-format); this is not a plain model name. |
| `usage_kind` | The token kind involved: `input`, `output`, `cache_read`, or `cache_write`. |
| `stage` | How far the usage got. `not_joined` means it never found a cost row to attach to. `not_matched` means it found one, but narrowing by account, API key, or calling identity ruled it out. |
| `matched_on` | The fields that did agree, listed in the order Vantage compares them: model, usage kind, account, API key, then principal. An empty list means matching stopped at the very first comparison. |
| `failed_on` | The field where matching stopped. This is the most important value in the record. |
| `failed_on_log_values` | The values your logs carried for the field named in `failed_on`. Populated only at the `not_matched` stage, so it is empty for `not_joined` records. |
| `log_records_indexed`, `log_records_matched`, `log_records_unmatched` | How many logged requests for this key were indexed, how many attached to a cost row, and how many were left over. Useful for judging whether a disposition covers a handful of requests or a meaningful share of your traffic. |
For a **No matching bill row** record, `failed_on` narrows the cause considerably:
* `failed_on: "model"` means your bill has no cost row for that model at all. Check whether the provider bills it under a different name, or whether the tier encoded in the join key matches a tier the provider actually bills.
* `failed_on: "usage_kind"` means the model *is* on your bill, but not for that token kind. This is common for cache tokens on models where the provider does not itemize caching separately.
Not every row is selectable. Three kinds of row are plain text rather than links:
* **The shaded summary rows:** **Tokens in logs**, **Tokens indexed**, and **Kept** are totals rather than problems, so there is nothing to sample.
* **Duplicate event ID and Missing event ID:** Vantage does not retain sample records for these two, so they are never links even when they carry tokens.
* **Any disposition with zero tokens:** There is nothing to show.
If a disposition is a link but the dialog displays `No examples were recorded for this disposition.`, no samples were captured for it during that run. `Examples could not be loaded. Try again.` means the samples could not be fetched; reopen the dialog to retry.
### Join Key Format
In join samples, `model` is the **join key**, not just a model name. It packs together every dimension that both sides must agree on before usage can attach to a cost row, so it can look unfamiliar at first.
* For AWS Bedrock, the key is `region|operation|inference_scope|tier|model`, and `*` means "any value." So `*|*|*|standard|openai.gpt-5.6-luna` reads as: the model `openai.gpt-5.6-luna`, at standard (non-batch) tier, with no Region, operation, or inference profile reported by the logs, so any of those on the bill can match.
* For OpenAI, the key is `tier:model`, or `tier:regional:model` for regional-endpoint traffic. So `default:gpt-4o` is `gpt-4o` on the default service tier.
The part after the last separator is the normalized model. Everything before it is a qualifier, and a wildcard qualifier means your logs did not report that dimension. Sending those fields on your telemetry produces more precise attribution.
## Troubleshoot Using Import History
Use this table to turn what you see on the screen into a next step.
| What You See | Most Likely Cause | What To Do |
| - | - | - |
| Status is **No logs** for recent periods | Logs are not reaching the connected bucket, or are not in the expected path layout | Confirm your delivery pipeline is writing objects, then re-check the bucket and path in your integration's troubleshooting section |
| Status is **Error** | The source hit a failure | Open the sources table on the integration page to read the failure reason, then match it to your integration's troubleshooting section |
| **Log Lines Kept** is low | Malformed log records or missing required fields | On the Token Metrics screen, select the largest disposition in the **Log Scan** section to see its samples. See [Log Scan dispositions](#log-scan-dispositions) for what each one means |
| **Tokens Kept** is low but **Log Lines Kept** is high | Your logs are fine but do not line up with the bill | Open Token Metrics and read the [Join dispositions](#join-dispositions) |
| **Bill Match** is low | Your logs cover only part of the traffic on that bill | Confirm every application and Region that calls the provider is emitting logs |
| Large **No matching bill row** | Model names in your logs do not correspond to billed models, or the bill has not landed | On the Token Metrics screen, select **No matching bill row** to see which models are unmatched; recheck after the next data refresh |
| Large **Ambiguous sibling withheld** | Several cost integrations share one bucket without account identifiers | Add `resource_account_id` to your records or split the buckets |
| Large **Bill demand short of log usage** | Logs counted more usage than the provider billed | No action needed; totals still reconcile |
## Provider-Specific Troubleshooting
For setup and permission error messages, and for the case where costs are not split at all, see the Troubleshooting section on your integration's page.
Troubleshooting for common-schema telemetry sources.
Troubleshooting for Cloudflare AI Gateway Logpush sources.
Troubleshooting for Model Invocation Log sources.
Troubleshooting for LiteLLM collector sources.
# Managed AI Tags
Source: https://docs.vantage.sh/managed_ai_tags
Vantage automatically normalizes supported AI provider billing and usage fields into a consistent vntg:ai: tag schema, so you can filter, group, and allocate AI spend by model, token type, user, and more.
Managed AI Tags are a Vantage-managed tag schema that standardizes AI cost data across supported providers. As spend flows in from integrations such as Cursor, Anthropic, OpenAI Platform, AWS Bedrock, Azure OpenAI, and Google Cloud, Vantage maps each provider's billing and usage fields into a consistent set of `vntg:ai:` tags. The same keys, like `vntg:ai:model`, `vntg:ai:model_provider`, and `vntg:ai:token_type`, appear regardless of which supported provider the spend came from, so you can build [Cost Reports](/cost_reports), [Virtual Tags](/tagging), [Budgets](/budgets), and [Cost Alerts](/cost_alerts) on the same dimensions across your AI stack.
Each AI provider exposes different fields: the model name may be the service on one integration and a tag on another, and user identity may be an email, a user ID, or an API key depending on the vendor.
Managed AI Tags are metadata-only and included with Vantage at no additional cost for accounts with supported AI cost integrations. Vantage only normalizes fields your providers already report in cost and usage data; it does not collect prompt or completion content.
## How It Works
Managed AI Tags are applied automatically during each provider's cost ingestion. Vantage reads the provider's billing and usage fields, maps them to the normalized schema, and writes the resulting tags, prefixed with `vntg:ai:` by default, onto the cost rows. No configuration is required: once you connect a supported AI integration, the tags appear on that provider's costs and become available anywhere tags are supported in Vantage.
Not every provider supplies every field. Vantage only writes a tag when the source data provides a reliable value for that key, so the set of `vntg:ai:` tags you see depends on which providers you have connected and what each one reports.
## The Managed AI Tag Schema
The following keys make up the canonical Managed AI Tag schema. Each key is shown with the `vntg:ai:` prefix.
| Tag key | What it tells you | Example values |
| - | - | - |
| `vntg:ai:model` | The cleansed, normalized model name, so you can compare the same model across providers and release dates. | `gpt-4o`, `claude-sonnet-4` |
| `vntg:ai:raw_model` | The exact model name from the provider, kept when it differs from the normalized `vntg:ai:model` value. | `gpt-4o-2024-08-06`, `claude-sonnet-4-20250514` |
| `vntg:ai:model_provider` | Who built the model, even if another platform hosts or bills for it. Useful for standardizing models procured through cloud providers. | `Anthropic`, `OpenAI`, `Google`, `xAI` |
| `vntg:ai:token_type` | What kind of tokens this charge is for. | `input`, `output`, `cache_read`, `cache_write` |
| `vntg:ai:provider_region` | Where the request ran (region or geography). | `us-east-1`, `global` |
| `vntg:ai:service_tier` | The pricing or speed tier for this usage. Values vary by provider. | `default`, `priority`, `batch`, `flex` |
| `vntg:ai:api_key_id` | Which API key was used. | Provider key ID |
| `vntg:ai:user_email` | Email of the person who triggered the usage. | `alice@company.com` |
| `vntg:ai:user_name` | Display name of the person who triggered the usage. | `Alice Smith` |
| `vntg:ai:user_id` | User ID from the provider. | Provider user ID |
| `vntg:ai:principal_id` | A provider-specific caller identifier that is not tied to a specific user name or email (for example, the IAM principal on Amazon Bedrock). | `team-a/session` |
| `vntg:ai:operation` | How the model was invoked, when the provider prices streaming and non-streaming calls separately. | `inference`, `streaming` |
| `vntg:ai:inference_scope` | Whether the request used a global or regional inference profile. | `global`, `regional` |
Not every provider supplies every field. Vantage only writes a tag when the source data provides a reliable value for that key.
When [Custom LLM Enrichment](/custom_llm_enrichment) is enabled, Vantage also writes request metadata into the same schema, including `vntg:ai:endpoint` and, for AWS Bedrock, `vntg:ai:operation` (`inference` or `streaming`) and `vntg:ai:inference_scope` (`global` or `regional`). [AWS Bedrock LLM Enrichment](/aws_bedrock_enrichment) populates the same two Bedrock keys from your Model Invocation Logs. These keys come from per-request telemetry rather than native provider billing. See [Managed AI Tags vs. Custom LLM Enrichment](#managed-ai-tags-vs-custom-llm-enrichment).
Anthropic also emits `vntg:ai:inference_speed` (its service speed tier) alongside the canonical keys.
## Supported Providers
Managed AI Tags are emitted automatically for supported AI cost integrations. The keys each provider populates depend on the fields that provider reports.
| Provider | Emitted `vntg:ai:` keys |
| - | - |
| [Cursor](/connecting_cursor) | `model`, `raw_model`, `model_provider`, `user_email` |
| [Anthropic](/connecting_anthropic) (Claude API) | `model`, `model_provider`, `provider_region`, `service_tier`, `inference_speed`, `token_type` |
| [Anthropic](/connecting_anthropic) (Claude.ai) | Adds `user_email`, `user_name`, `user_id` |
| [OpenAI Platform](/connecting_openai) | `model`, `raw_model`, `model_provider`, `provider_region`, `service_tier`, `token_type`, `user_id`, `api_key_id` |
| [AWS Bedrock](/connecting_aws) | `model`, `raw_model`, `model_provider`, `provider_region`, `service_tier`, `token_type`, `principal_id`. Adds `operation` and `inference_scope` with [AWS Bedrock LLM Enrichment](/aws_bedrock_enrichment). |
| [Azure](/connecting_azure) (Azure OpenAI, Marketplace Anthropic) | `model`, `raw_model`, `model_provider`, `provider_region`, `service_tier`, `token_type` |
| [Google Cloud](/connecting_gcp) (Vertex AI Gemini, Marketplace Claude) | `model`, `raw_model`, `model_provider`, `provider_region`, `token_type` |
| [Anyscale](/connecting_anyscale) | `user_email`, `user_id` |
| [ElevenLabs](/connecting_elevenlabs) | `model`, `model_provider` |
| [Baseten](/connecting_baseten) | `model`, `model_provider`, `token_type` |
| [Fireworks AI](/connecting_fireworks_ai) | `model`, `model_provider`, `token_type` |
| [xAI](/connecting_spacexai) | `model`, `raw_model`, `model_provider`, `service_tier`, `token_type`, `api_key_id` |
For the hyperscalers, Managed AI Tags apply only to the AI portion of spend: Amazon Bedrock cost rows on AWS, Azure OpenAI, Foundry, and Marketplace Anthropic cost rows on Azure, and Vertex AI Gemini and Marketplace Claude cost rows on Google Cloud. Non-AI costs on those providers are unaffected.
OpenAI Codex costs currently use provider-specific `openai:` tags and do not receive Managed AI Tags. The OpenAI row above applies only to OpenAI Platform costs imported with an Admin API key.
## How Managed AI Tags Coexist with Provider Tags
Managed AI Tags add a cross-provider layer on top of the provider-specific tags Vantage already creates. Provider-specific native tags, such as `cursor:user`, `openai:api_key_id`, or `anthropic:model`, continue to exist and capture fields unique to that integration, while the managed `vntg:ai:` keys give you a single, consistent dimension that works across providers.
Managed AI Tags are also additive to your existing configuration: they do not modify your [Virtual Tags](/tagging), [Billing Rules](/sql_billing_rules), or reports. You can start using them in new reports and filters immediately alongside everything you already have.
## Renaming or Standardizing Managed AI Tags
Vantage maintains the canonical Managed AI Tag definitions with the set `vntg:ai:` prefix so the schema stays consistent across every account. If you want to present these tags under different key names, use [Tag Key Collapsing](/tagging#tag-key-collapsing) to map one or more `vntg:ai:` keys into a [Virtual Tag](/tagging) with your preferred naming.
## Backfill and Data Freshness
Managed AI Tags are applied as part of each provider's cost ingestion, so they follow that provider's refresh cadence. See the [provider data refresh documentation](/provider_data_refresh) for per-provider timing.
Normalized `vntg:ai:` tags are available from August 2026 onward. Vantage does not backfill managed tags onto earlier historical data.
## Use Managed AI Tags in Cost Reports
Once a supported AI integration is connected and its costs are processed, the `vntg:ai:` keys appear in the **Tag Key** dropdown wherever tags are supported. To analyze AI spend with them:
* **To group:** open the **Group By** menu on a [Cost Report](/cost_reports), select **Tag**, and choose a key such as `vntg:ai:model` (values like `gpt-4o`) or `vntg:ai:model_provider`.
* **To filter:** open the **Filters** menu, add a new rule, select **Tag**, choose the **Tag Key** (for example, `vntg:ai:user_email`), then pick an operator and one or more values.
Because the same keys span every AI provider, you can drill into a single developer's spend across Cursor and Anthropic in one view, or compare model mix across your whole AI stack. Managed AI Tags also work anywhere else tags are supported, including [Virtual Tags](/tagging), [Budgets](/budgets), and [Cost Alerts](/cost_alerts). If you use a handful of keys often, mark them as [preferred tags](/tagging#preferred-tags) so they sort to the top of these menus.
In the example below, a Cost Report groups by **Provider** and **Usage Unit** alongside `vntg:ai:model_provider` and `vntg:ai:model`. Because `vntg:ai:model_provider` reflects who built the model rather than who billed for it, the same Anthropic models roll up under one provider value whether they were purchased through Cursor, through Anthropic directly, or through AWS Bedrock, with normalized model names, token counts, and costs lined up side by side.
## Managed AI Tags vs. Custom LLM Enrichment
Managed AI Tags and [Custom LLM Enrichment](/custom_llm_enrichment) are complementary features that share the `vntg:ai:` vocabulary but solve different problems.
| | Managed AI Tags | [Custom LLM Enrichment](/custom_llm_enrichment) |
| - | - | - |
| What it does | Normalizes fields your providers **already report** into a consistent `vntg:ai:` schema. | Joins **your own** per-request token telemetry (delivered to S3) to provider costs to fill gaps the bill doesn't itemize. |
| Setup | Automatic once a supported AI integration is connected. | You emit telemetry in the common schema and connect an S3 source. |
| Typical dimensions | `model`, `model_provider`, `token_type`, `service_tier`, `provider_region`, and identity fields when the provider reports them. | Custom `tags` you define (for example, `team`, `feature`, `environment`) plus request metadata like `endpoint` and `service_tier`. |
In short, Managed AI Tags standardize what providers already send, while Custom LLM Enrichment enriches what providers leave out. Use them together for the most complete view of AI spend.
# Metronome
Source: https://docs.vantage.sh/metronome
Import Metronome revenue and usage data into Vantage as business metrics.
Vantage integrates with [Metronome](https://metronome.com/) to bring billing revenue and product usage data into Vantage as [Business Metrics](/business_metrics). You can then analyze Metronome revenue and usage alongside Vantage cost data to understand customer profitability, cost per unit, gross margin, and pricing efficiency.
Metronome is connected from the Apps section of Vantage. It does not import Metronome as a cost provider. Instead, Vantage imports Metronome data as labeled business metrics that can be assigned to [Cost Reports](/cost_reports), used in [Canvas](/canvas), and queried with the [FinOps Agent](/vantage_finops_agent).
## How It Works
Vantage connects to the Metronome API with a bearer token, discovers revenue and usage data, and imports the selected data into Vantage business metrics. Each imported row is daily and can be labeled by customer so you can compare cost, usage, and revenue at the same level of detail.
```mermaid theme={null}
flowchart LR
Metronome[Metronome API] --> Revenue["Daily Invoice Revenue"]
Metronome --> Usage["Billable Metric Usage"]
Revenue --> BusinessMetrics["Vantage Business Metrics"]
Usage --> BusinessMetrics
BusinessMetrics --> CostReports["Cost Reports and Unit Costs"]
BusinessMetrics --> Canvas["Canvas"]
BusinessMetrics --> Agent["FinOps Agent"]
```
Vantage can import two kinds of Metronome business metrics:
| Metric type | Metronome source | Use it for |
| - | - | - |
| Daily invoice revenue | Metronome invoice breakdowns | Revenue, gross margin, customer profitability, and cost as a percentage of revenue |
| Usage | Metronome billable metrics | Cost per compute hour, API request, storage GB-hour, AI token, seat, transaction, or other product usage unit |
Labels identify the customer associated with the metric value. When configuring the import, you can choose one of the following label sources:
| Label source | Best for |
| - | - |
| Customer name | Human-readable customer profitability and usage analysis |
| Ingest alias | Cleaner or external customer identifiers already maintained in Metronome |
| Customer ID | Stable joins and troubleshooting when names or aliases are not available |
Metronome business metrics sync daily. Initial imports and reimports can take time to finish, especially when importing historical data across many customers or billable metrics.
## Connect Metronome
### Prerequisites
Before you connect Metronome to Vantage, make sure you have:
* A Vantage role that can manage integrations, such as **Organization Owner** or **Integration Owner**. See [Role-Based Access Control](/rbac).
* Access to create or retrieve a Metronome API token.
* A Metronome token that can access customers, invoice breakdowns, usage queries, and billable metrics.
Metronome API tokens use bearer authentication. See Metronome's [API authentication documentation](https://docs.metronome.com/api-reference/authentication) and [RBAC documentation](https://docs.metronome.com/guides/platform-configuration/role-based-access-rbac#assign-a-role-to-an-api-token) for details on creating and scoping API tokens.
If your Metronome workspace uses RBAC roles for API tokens, use an Administrator, Writer, or custom role that can access customer records, invoice breakdowns, usage data, and billable metrics. Metronome roles cannot be changed after token creation, so create a new token if the current one is too limited.
### Create the Connection
In Vantage, navigate to [Settings > Metronome](https://console.vantage.sh/settings/metronome?connect=true). You can also open **Settings**, select **Integrations**, then choose **Metronome** from the Apps section.
Click **Add API Key**. Enter a descriptive account name and paste your Metronome API token.
Click **Connect Account**. Vantage validates the token by checking that it can read Metronome customers and query usage data.
After the account is connected, create one or more Metronome-backed business metrics from **Financial Planning > Business Metrics**. See [Import from Metronome](/business_metrics#import-from-metronome) for the full workflow.
Store your Metronome API token securely. Do not paste the token into Canvas, the FinOps Agent, Slack, or any client-side application.
## Validate the Setup
After connecting Metronome, create one revenue metric and one usage metric before building reports (see [Import from Metronome](/business_metrics#import-from-metronome) for details). This gives you a quick way to confirm the connection, metric discovery, labels, and imported values are working.
Create a new business metric, select **Import via Metronome**, choose your connected Metronome account, and select **Daily invoice revenue**. Use a clear name like `Metronome Revenue`.
Create a second business metric, select the same Metronome account, and choose a billable usage metric such as `Compute Hours`, `API Requests`, `Storage GB-Hours`, `AI Tokens`, or `Virtual Machine Hours`.
Open the **Imported Metrics** tab for each business metric. Confirm that rows appear by date and that labels match the customer naming style you expected.
Assign the metrics to Cost Reports only after the imported values look correct. For example, assign `Metronome Virtual Machine Hours` to a COGS Cost Report to calculate cost per VM hour.
## Example Workflows
The examples below assume you already created Metronome-backed business metrics in Vantage and that you have at least one Cost Report that represents COGS or product infrastructure cost. Replace the metric and report names with the names in your account.
### Top Customers by Usage
Use this when you want to find which customers are driving the most product usage before you look at cost or revenue.
Show my top customers by Metronome usage over the last 30 days. Use the "Metronome Virtual Machine Hours" business metric, group by customer label, include total usage, daily average usage, and share of total usage, and sort descending.
Expected output: one row per customer with usage totals and share of usage. Use this to identify the customers that should be reviewed first for unit cost, margin, or pricing analysis.
### COGS and Unit Cost by Customer
Use this when you have a Cost Report for product COGS and a Metronome usage metric with customer labels.
Using my "COGS" Cost Report and the "Metronome Virtual Machine Hours" business metric, calculate cost per VM hour by customer for the last 30 days. Include total COGS, total VM hours, cost per VM hour, and rank customers by total COGS.
Expected output: one row per customer with cost, usage, and cost per unit. Use this to find customers whose usage is disproportionately expensive.
### Gross Margin by Customer
Use this when you import Metronome revenue and want to compare it with Vantage COGS for the same customer labels.
Compare "Metronome Revenue" to my "COGS" Cost Report for the last month. Group by customer label and include revenue, COGS, gross margin dollars, and gross margin percent.
Expected output: a customer profitability table. Review low or negative margin customers first, then inspect the underlying Cost Report filters and usage metric labels.
### Pricing Targets from Current Unit Cost
Use this when you know the current cost per product unit and want to evaluate price points for target margins.
Use my current cost per VM hour from the "COGS" Cost Report and "Metronome Virtual Machine Hours" business metric to suggest prices that would produce 20%, 40%, and 60% gross margin. Show the formula and include one row per target margin.
Expected output: a table with current cost per unit and suggested price per unit for each target margin. Use the result as a pricing input in Metronome.
### Usage-Based Cost Allocation
Use this when a shared platform cost should be allocated to customers based on their share of Metronome usage.
Allocate shared cloud and platform costs in my "COGS" Cost Report to customers based on the "Metronome Virtual Machine Hours" labels, then show COGS by customer and cost per VM hour for the last 30 days.
Expected output: customer-level cost allocation based on usage share. If you want the allocation to be reusable across reports, create a [Virtual Tag](/tagging) that uses the Metronome business metric as the allocation basis.
### Product Usage Portfolio
Use this when you import several Metronome usage metrics and want to see which product dimension is growing fastest.
Show daily Metronome usage for Compute Hours, API Requests, Storage GB-Hours, and AI Tokens for the last 30 days. Include one row per product metric and day, and call out the fastest-growing metric.
Expected output: daily usage by product metric. Use this to decide which usage unit should be paired with a Cost Report first.
## Ask the FinOps Agent
You can also ask the [FinOps Agent](/vantage_finops_agent) one-off questions about Metronome-backed business metrics in the Vantage console. Name the relevant business metric and Cost Report so the agent can scope the analysis.
Try prompts like:
* `Which customers had the highest Metronome usage last month, and how did their COGS compare?`
* `Use my Metronome Revenue business metric and my COGS Cost Report to find customers below 30% gross margin.`
* `Explain why cost per VM hour increased last week for my Metronome Virtual Machine Hours metric.`
* `Create a Cost Report that uses my COGS filters and assign the Metronome API Requests business metric to show cost per thousand requests.`
## Related Metronome Documentation
The Vantage integration uses these Metronome concepts and APIs:
* [API authentication](https://docs.metronome.com/api-reference/authentication)
* [Assign an RBAC role to an API token](https://docs.metronome.com/guides/platform-configuration/role-based-access-rbac#assign-a-role-to-an-api-token)
* [Billable metrics](https://docs.metronome.com/guides/implement-metronome/core-concepts/create-billable-metrics)
* [List all billable metrics](https://docs.metronome.com/api-reference/billable-metrics/list-all-billable-metrics)
* [Get batched usage data](https://docs.metronome.com/api-reference/usage/get-batched-usage-data)
* [List invoice breakdowns](https://docs.metronome.com/api-reference/invoices/list-invoice-breakdowns)
## Troubleshooting
Confirm that your Vantage user has permission to manage integrations. You need a role such as **Organization Owner** or **Integration Owner**.
Vantage validates the token by checking customer and usage access. If the token is rejected, create a new Metronome API token with access to customers, invoice breakdowns, usage queries, and billable metrics.
If your Metronome account uses RBAC for API tokens, assign an Administrator, Writer, or custom role with access to those endpoints. See Metronome's [RBAC documentation](https://docs.metronome.com/guides/platform-configuration/role-based-access-rbac#assign-a-role-to-an-api-token).
The usage metric dropdown is populated from Metronome billable metrics. If it is empty, confirm that the token can access `GET /v1/billable-metrics` and that your Metronome account has active billable metrics.
After confirming permissions, refresh the metric list or try reconnecting with a new token.
Initial imports and daily refreshes can take time to finish. Check again after the import completes or after the next daily sync.
If the metric remains pending, confirm that the Metronome connection is still active and that the business metric is connected to the intended Metronome account and metric type.
Check the label source selected for the business metric. If you selected **Customer ID**, Vantage uses the raw Metronome customer ID.
If you selected **Ingest alias** or **Customer name**, Vantage can fall back to the customer ID when that value is not available in Metronome. Edit the business metric configuration if you want a different label source.
If two Metronome customers have the same name, Vantage disambiguates the labels with an ID suffix. This is expected and helps prevent two customers from being merged into one labeled metric.
Usage can exist before a customer is billed or before a product has billable revenue configured in Metronome. In that case, usage metrics appear in Vantage, but revenue may be zero or missing for the same customer and date range.
Confirm that the customer has invoice data in Metronome for the selected period, then rerun the analysis for a date range that includes billed revenue.
Compare the Canvas or FinOps Agent prompt against the Cost Report. Make sure the prompt uses the same workspace, report, date range, cost settings, and business metric labels.
For unit cost analysis, also confirm that the Cost Report contains the COGS or product costs you want to divide by the Metronome metric. If the report contains all company costs, the cost per unit may be inflated.
This is expected. Metronome is connected from Apps and imports revenue and usage as business metrics. It does not import provider costs into Vantage.
To analyze Metronome data with costs, assign the Metronome business metric to a Cost Report or reference it in Canvas or the FinOps Agent.
# Microsoft Teams
Source: https://docs.vantage.sh/microsoft_teams
Learn how to create an integration with Microsoft Teams and Vantage to send alerts and notifications.
Vantage integrates with Microsoft Teams so that you can send [Report Notifications](/report_notifications#set-up-cost-report-notifications), [Cost Alerts](/cost_alerts), [Cost Anomaly Alerts](/cost_anomaly_alerts), and [Budget Alerts](/budgets#budget-alerts) to your Teams channels. You can adjust notifications to be delivered to a specific public or private channel in Microsoft Teams.
The Vantage Microsoft Teams integration makes it easy for teams to stay on top of cloud costs without leaving Microsoft Teams. Your team gets real-time alerts right where you already work. You can configure notifications for things like:
* Unexpected spending spikes
* Budgets getting close to or over their limits
* Regular Cost Report summaries
* Custom alerts for specific thresholds or conditions
## Installation
To complete the integration, ensure you have permission to add integrations to your team's Microsoft Teams account.
From the top navigation, click **Settings**.
On the left navigation, click **Integrations**.
Under the **Apps** section, click **Teams**.
Click **Connect Teams**.
Log in with your Microsoft 365 account and provide Vantage with authorization to access your account. Vantage will ask for the following permissions on your Teams account:
* Read names and descriptions of Teams
* Read names and descriptions of channels
* Send messages to channels
The Vantage app for Microsoft Teams has been verified by Microsoft. Vantage interacts with Microsoft Office 365 to set the approved permissions for the app in your account and uses the Microsoft Graph API to get and send info to your Microsoft Teams account.
## Next Steps
After installation, you can configure various types of alerts to monitor your cloud costs:
| Alert Type | Description | Documentation |
| - | - | - |
| **Budget Alerts** | Set up budget alerts for your most critical cost centers | [Budget Alerts](/budgets) |
| **Cost Anomaly Detection** | Create cost anomaly detection for unexpected spending spikes | [Cost Anomaly Alerts](/cost_anomaly_alerts) |
| **Report Notifications** | Configure report notifications for regular cost summaries | [Report Notifications](/report_notifications) |
| **Cost Alerts** | Set up custom alerts for specific thresholds or conditions | [Cost Alerts](/cost_alerts) |
### Channel Support by Alert Type
The matrix below shows which Vantage alert types support delivery to Microsoft Teams (and to Slack, Jira, and email for cross-reference).
| Alert Type | Email | Slack | Microsoft Teams | Jira | Configured From |
| - | :-: | :-: | :-: | :-: | - |
| [Cost Anomaly Alerts](/cost_anomaly_alerts) | Yes | Yes | Yes | Yes | A Cost Report's **Anomalies** tab > **Configure Alert** |
| [Cost Alerts](/cost_alerts) | Yes | Yes | Yes | Yes | A Cost Report's **...** menu > **Create Cost Alert**, or **Notifications** > **Cost Alerts** > **Configure Cost Alert** |
| [Budget Alerts](/budgets#budget-alerts) | Yes | Yes | Yes | Yes | A Budget's **Manage** tab > **Manage Alerts** > **Configure Alert** |
| [Report Notifications](/report_notifications) (Cost Reports) | Yes | Yes | Yes | — | The **Notifications** page > **New Notification** > **Cost Report Notification**, or a Cost Report's **...** menu > **Create Report Notification** |
| [Dashboard Notifications](/report_notifications#set-up-dashboard-notifications) | Yes | — | — | — | The **Notifications** page > **New Notification** > **Dashboard Notification** |
Slack and Microsoft Teams are mutually exclusive at the integration level: you can connect either Slack or Microsoft Teams, not both. See the [Slack](/slack) and [Microsoft Teams](/microsoft_teams) integration docs for setup. Jira delivery requires the [Jira integration](/jira).
# MSP Invoicing
Source: https://docs.vantage.sh/msp_invoicing
Use the MSP Invoicing tool to generate, review, approve, and distribute invoices directly within Vantage.
Contact [support@vantage.sh](mailto:support@vantage.sh) or your dedicated Customer Success Manager to enable this feature.
Invoices are immutable, tied to cost data, and can be exported as PDF or CSV for record-keeping or import into general ledger systems. Each invoice reflects a customer's costs as calculated by Vantage, including any billing rules applied by the MSP. Customer and MSP metadata, such as billing addresses, banking information, Tax ID, VAT, and purchase order numbers, can be included to ensure invoices meet legal and business requirements.
Invoices are generated for billing periods, which are fixed to calendar months. Only full calendar months can be used; custom periods are not supported. The invoicing process includes:
* Creating a billing profile with your organization's billing details
* Adding managed account billing information for each customer
* Generating and distributing invoices
All MSP users can view invoices, while only Organization Owners have write access to invoices. See the [MSP RBAC documentation](/partners#user-permissions) for details on user roles. Customers in managed accounts can view only their approved invoices within their account, on the **Invoices** screen.
For MSPs who use [currency management](/partners#currency-management), if you change the currency for a month that has had an invoice generated, you will have to regenerate the invoice for the new exchange rate to be applied.
## Step 1 - Create a Billing Profile
A billing profile contains your MSP’s information that appears on the invoices generated for managed accounts. At least one billing profile is required before you can generate invoices.
Create separate billing profiles if you have multiple bank accounts that you need to assign to different customers.
To create a billing profile:
Navigate to **Partner Settings > [Billing Profiles](https://console.vantage.sh/settings/billing_profiles)**.
Click **New Billing Profile**.
Enter a **Nickname** to identify this billing profile.
To add the logo you want displayed on invoices, click **Select File** and select your logo image file. You can also check the box below this field if you want this logo to apply to all billing profiles so that you have to upload it only once.
Enter your organization's **Billing Information**, including **Company Name** and **Address**.
For **Business Information**, click **+Add Field** to add key-value pairs for fields like Tax ID, VAT, etc. These fields will appear on invoices below your billing address.
Under **Taxes and Additional Charges**, click **Add Charge** to add taxes and additional charges based on the subtotal to a customer's invoice. These charges will be calculated at the time of invoice creation based on the subtotal cost after credits, discounts, and billing rules. They will appear after the subtotal on an invoice.
Add your **Banking Information**.
At the top, click **Save**.
## Step 2 - Add Managed Account Billing Information
Each customer managed account has a section in account settings where you can enter account billing information. To add billing information for a customer:
Navigate to the [**Managed Accounts**](https://console.vantage.sh/settings/managed_accounts) screen.
Select a managed account or [create a new one](/partners#create-a-new-customer-managed-account).
On the **General** tab, in the **Account Details** section, the account name and contact email address are displayed.
In the **Invoice Settings** section, select a **Billing Profile** you want associated with invoices for this account. Optionally, set **Payment Terms** (e.g., Net 30, Net 60) to specify the number of days customers have to pay the invoice. Payment terms are displayed on generated invoices.
Optionally select **Include managed account integrations**. When enabled, invoice cost calculations will include integrations added directly by the managed account in addition to MSP-delegated integrations.
In the **Billing Information** section, enter the billing details for the managed account. The information will appear on this managed account's invoices. Ensure you enter the official company name used for billing purposes. In addition, you can add one or more email addresses, separated by commas, for which you will send invoices.
Email addresses do not have to be existing Vantage users.
In the **Business Information** section, you can optionally add key-value pairs for details such as Tax ID or VAT. These values will appear on invoices beneath your billing address.
At the top, click **Save**.
## Step 3 - Generate an Invoice
When the month closes, an invoice is generated based on the customer's **All Resources** Cost Report. Navigate to the **Invoices** screen. All invoices are displayed. At the top of the page, you can filter by **Account** and **Status**.
You can also view all invoices for a customer's managed account on the **Invoices** tab of the Managed Accounts screen.
```mermaid theme={null}
flowchart TB
A[Billing Period Closes] --> B[Ready to Invoice]
B -->|Click **Generate Invoice**| C[Generating Invoice]
C --> D[Awaiting Approval]
C -->|Error Occurs| G[Error]
G -->|Regenerate Invoice| C
D -->|Click **Approve & Send**| E[Approved]
D -->|Optionally Make Updates and Regenerate| C
E --> F[Invoice Sent PDF/CSV Copies Remain Available]
```
On the first of the month, once the previous period closes (or after the third of the month if [AWS Data Ingestion Delay](/connecting_aws/#aws-data-ingestion-delay) is enabled), a new invoice is displayed for each managed account with the status **Ready to Invoice**.
Click **Generate Invoice** to invoice the customer.
Click the ellipses (**...**) next to the **Generate Invoice** button to view the associated Cost Report.
Vantage generates a new invoice. The invoice status is displayed as **Generating Invoice**.
This process may take a few minutes.
If an error occurs during invoice generation, the invoice status is displayed as **Error**. Review the invoice details to identify the issue, make any necessary corrections, and then regenerate the invoice.
The **Awaiting Approval** status is displayed when the invoice is ready.
Click the download icon (looks like an arrow pointing down) next to the invoice to review a PDF copy of the current invoice.
Review the PDF invoice to ensure accuracy of costs, payment information, and customer data. If you find any issues, make the appropriate adjustments.
| Issue Type | What to Do | More Info |
| - | - | - |
| Certain billing rules, like credits, are not applied | Adjust or create billing rules accordingly. | [Docs](/partners#billing-rules) |
| Incorrect billing profile is displayed | Update your MSP's payment information and invoice metadata and ensure the right billing profile is associated with this customer. | [Docs](/msp_invoicing#step-1-create-a-billing-profile) |
| Incorrect customer billing data | Verify customer details are accurate in Managed Accounts screen. | [Docs](/msp_invoicing#step-2-add-managed-account-billing-information) |
* **If you needed to make updates**, click the ellipses (**...**) on the right, and select **Regenerate Invoice**.
Regenerated invoices use the same Invoice Number as the first time the invoice was generated. This number is displayed in the second column of the table.
* **If you did not need to make any updates**, click **Approve & Send**. A confirmation message is displayed. Click **Approve & Send** again.
Once an invoice is approved, the invoice will be emailed as a PDF attachment to the assigned recipients for the managed account. The email will come from `no-reply@vantage.sh`.
PDF and CSV versions remain available for download.
To resend an invoice, click the ellipses (**...**) at the end of the invoice row and select **Email PDF**.
## Bulk Actions
You can perform bulk actions to generate, approve/send, regenerate, and download copies of multiple invoices at once. Select the checkbox next to an invoice, then select an option at the top of the screen. Confirmation messages are displayed so that you can confirm any bulk actions.
## Troubleshooting
Invoices appear on the first of the month when the previous billing period has closed. If AWS [Data Ingestion Delay](/connecting_aws/#aws-data-ingestion-delay) is enabled, invoices will appear after the third of the month. If other upstream providers experience delays, billing periods may not be immediately ready for invoicing.
You need an associated [billing profile](/msp_invoicing#step-1-create-a-billing-profile) to generate an invoice.
Verify that provider billing information is set under **Partner Settings > Billing Profile** and that customer billing information is configured on the **Managed Accounts** page. Only fields entered in these locations appear on invoices.
Ensure that a [billing rule](/partners#billing-rules) with the **Charge Category: Tax** has been created and applied before generating the invoice. Regenerate the invoice after updating billing rules.
Confirm that the correct billing contact email addresses are set on the **Managed Accounts** page. Invoices are automatically sent to these contacts once approved. You can also manually resend invoices from the Invoices tab.
Invoices can be regenerated while in **Awaiting Approval** status. Once an invoice is approved, it cannot be regenerated.
# Network Flow Reports
Source: https://docs.vantage.sh/network_flow_reports
Analyze network traffic costs with Vantage Network Flow Reports and identify cost-driving flows.
For any network-enabled resource, Network Flow Reports provide visibility by source and destination to the flows within your network that are driving costs. You can filter these reports to identify resources that are accruing network costs, generate detailed views of the sources and destinations of the network traffic, and investigate metadata on specific resources in the flow. This feature makes it possible to correlate data transfer charges with both external services, such as Datadog, and internal applications.
At this time, only AWS is supported. Additional support for providers with flow log functionality, such as Azure and Google Cloud, is planned for the future.
## Set Up VPC Flow Log Integration
Network Flow Reports require an existing [AWS provider integration](/connecting_aws). The Vantage AWS account-specific IAM role needs to be granted access to the S3 buckets where you publish your VPC Flow Logs. Vantage can automatically detect any existing S3 buckets that contain VPC Flow Logs. You need to configure this integration for each AWS account that has an S3 bucket with VPC Flow Logs.
The Vantage configuration does not work with Amazon CloudWatch because of the high cost of querying CloudWatch. Logs need to be published to S3 for the Vantage integration to work.
### Prerequisites
Ensure you have at least the following fields in your VPC Flow Log format to increase the discoverability of network-related costs. If you do not have these fields enabled, Vantage may be unable to properly correlate your network flows to estimated costs.
```bash theme={null}
${action} ${bytes} ${dstaddr} ${start} ${end} ${flow-direction} ${log-status} ${region} ${srcaddr} ${account-id} ${instance-id} ${interface-id} ${subnet-id} ${vpc-id} ${az-id}
```
See the [AWS documentation](https://docs.aws.amazon.com/vpc/latest/userguide/flow-logs-s3.html#flow-logs-s3-create-flow-log) for information on how to set up VPC Flow Logs that publish to S3. Vantage can ingest both Text and Parquet log file formats.
#### Cost to Enable VPC Flow Logs in AWS
When you enable VPC Flow Logs, you incur both S3 storage costs and CloudWatch data ingestion costs on your AWS bill. These charges are represented in the costs for the S3 bucket where your flow logs are written to as well as an `S3-Egress` fee from CloudWatch. Unfortunately, there is no way around these costs being incurred. Vantage has contacted various AWS platform teams to attempt to remove this cost, but this is likely a limitation that AWS is unwilling to change or remove.
These logs are considered [Vended Logs](https://aws.amazon.com/cloudwatch/pricing/#Vended_Logs). You can create a [Cost Report](/cost_reports) that monitors these charges:
* Set **Provider** to **AWS**.
* Set **Subcategory** to **AmazonCloudWatch contains VendedLog**.
Note that Vended Logs can include other cost sources besides VPC Flow Logs, but you can expect an increase in those costs after enabling them. The filters for this Cost Report are provided below.
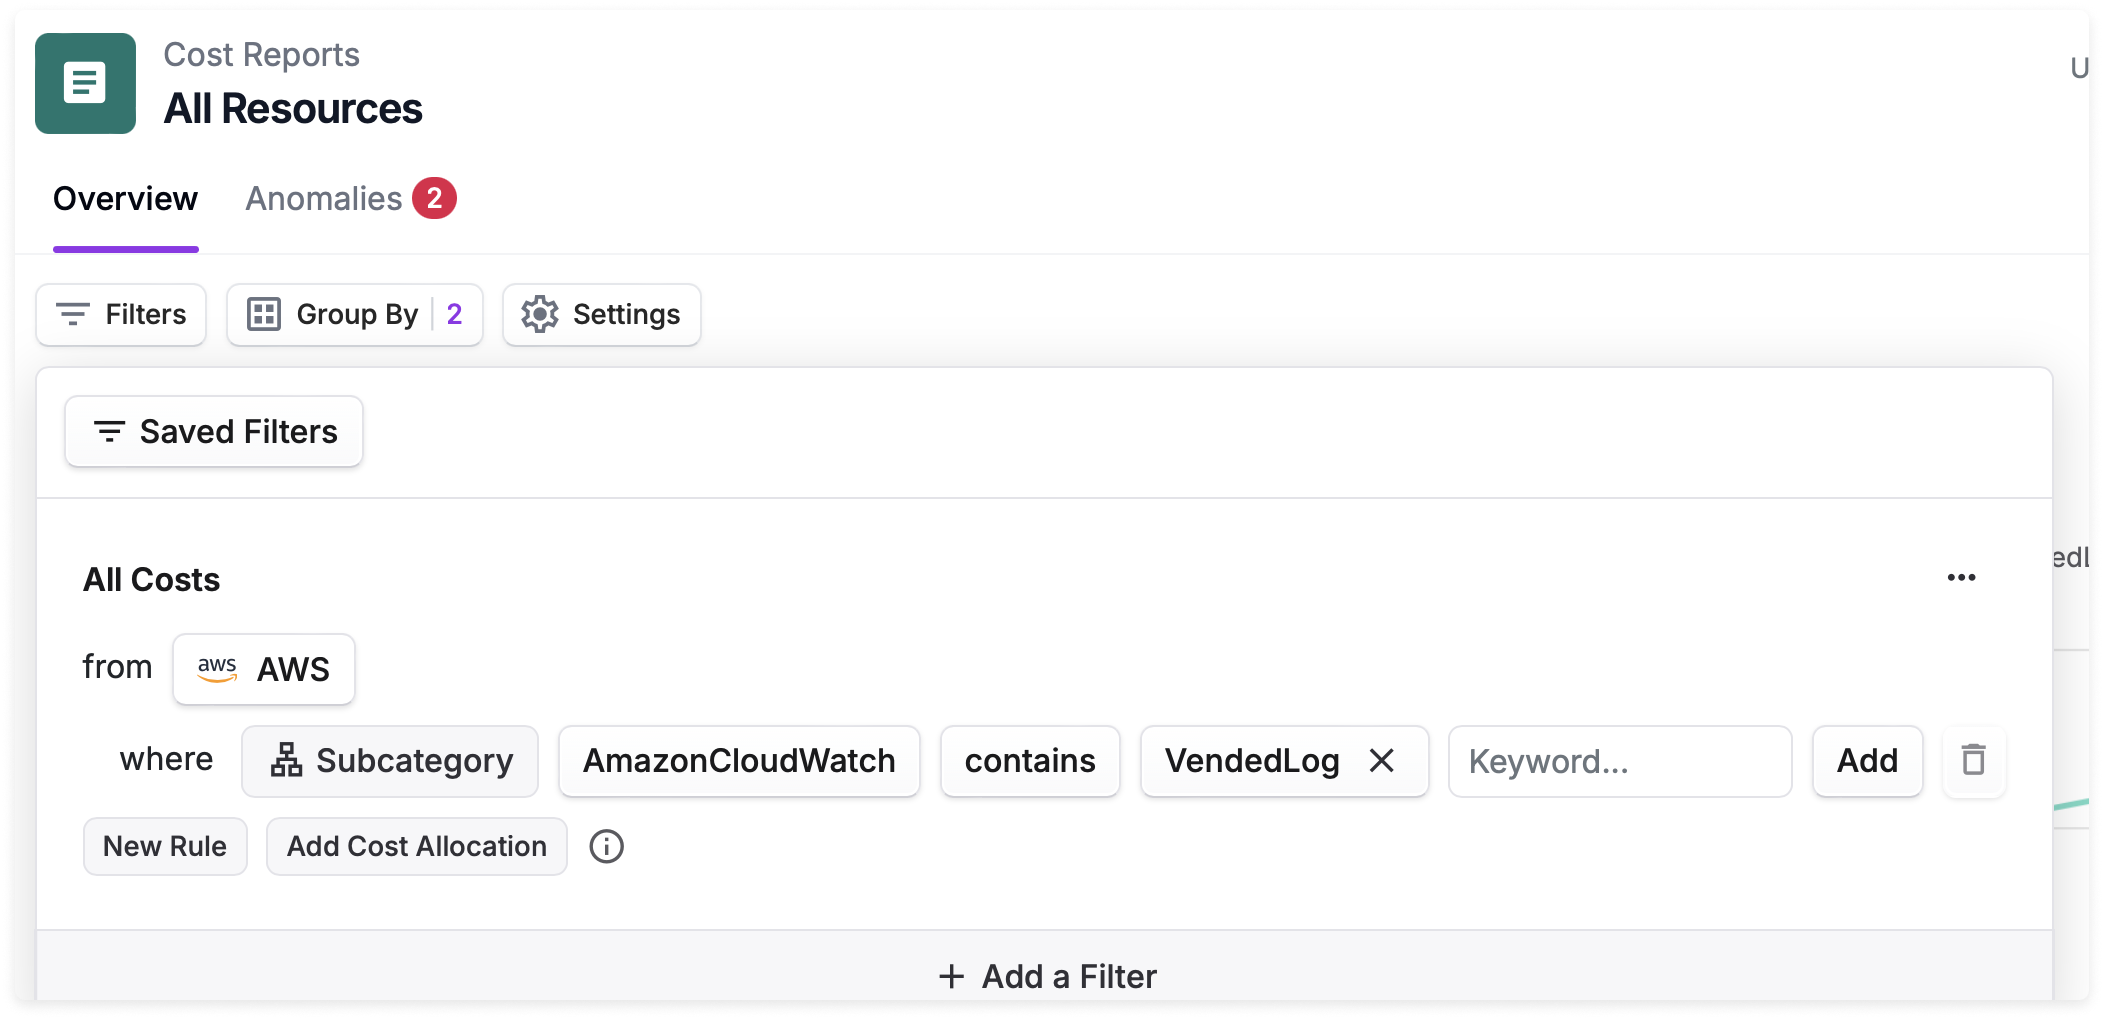
For more information about VPC Flow Logs pricing, see this [Cloud Cost Handbook article](https://handbook.vantage.sh/aws/services/vpc-flow-logs-pricing/).
### Enable the Integration
From the top navigation bar, click **Active Resources**.
From the side navigation bar, select **Network Flow Reports**.
Click **Configure VPC Flow Logs**.
See the [Troubleshooting](/network_flow_reports#troubleshooting) section if you are running into issues with seeing some of your flow logs on the onboarding workflow.
You can also start (or revisit) this workflow from the **VPC Flow Logs** tab on the [AWS Settings](https://console.vantage.sh/settings/aws) page. See [Manage Existing Integrations](#manage-existing-integrations) below.
All flow logs that have been synced as active resources in Vantage are displayed in the left panel of the onboarding workflow. Click the checkbox next to any listed flow log to select all log files. You can also click the down arrow to the right of any flow log and select or deselect specific log files listed.
If you do not see specific flow log files, check whether they are [synced as active resources](https://console.vantage.sh/resources/new?filter=%7B%22%7C%7C%22%3A%5B%7B%22%5E%22%3A%5B%7B%22%3D%22%3A%5B%22provider_id%22%2C1%5D%7D%2C%7B%22%7C%7C%22%3A%5B%7B%22%3D%22%3A%5B%22type%22%2C%22ProviderResource%3A%3AAws%3A%3AVpcFlowLog%22%5D%7D%5D%7D%5D%7D%5D%7D%7D\&resource_type=ProviderResource%3A%3AAws%3A%3AVpcFlowLog\&title=VPC+Flow+Logs) in Vantage. Ensure that all accounts where there are flow logs have [active resources enabled](/active_resources#aws-active-resources) in Vantage.
When you select the checkbox, the **Sync All** toggle is automatically enabled. You can disable this option if you do not want the files to automatically sync again each night.
The right panel contains instructions on how to get set up using the AWS CLI, AWS Management Console, or the [Vantage Terraform provider](/terraform). Select the tab for your preferred option. If you have multiple connected accounts with VPC Flow Logs, instructions or code samples are provided for each account.
After you run the code in the AWS CLI, deploy your Terraform configuration, or complete the steps in the AWS Management Console, click **Check Permissions**. A message is displayed that indicates whether the bucket permissions were successfully set up or if they are missing. A red **X** is displayed next to any buckets in the left panel that do not have sufficient permissions. Some log files may also be unsupported. See the [section below](/network_flow_reports#unsupported-logs) for details.
Once permissions are successfully set up, click **Connect**. A message is displayed that indicates your flow logs are being imported. Click **Check Import Status** to review the status of your integration. A **Processing…** status is displayed until the import is complete.
Data is usually available within 24 hours of initially enabling the integration. You will receive an email once the data import is complete. Vantage ingests your logs nightly.
### Unsupported Logs
When a particular log cannot be imported, Vantage displays a status label next to the log name in the **Manage VPC Flow Logs** window. Hover your mouse over the label to see additional information about the issue.
| Issue | Description |
| - | - |
| `UNSUPPORTED TRAFFIC` | Vantage does not import any `REJECT` flows, nor any flows that do not generate corresponding costs. |
| `UNSUPPORTED DESTINATION` | This message is displayed if a log is going to any destination other than S3. Logs need to be published to S3 to be imported by Vantage. |
| `UNSUPPORTED LOG FORMAT` | Unsupported log format means that your log may be missing some required columns. Hover over the `UNSUPPORTED LOG FORMAT` label to see a list of missing columns. Ensure your logs contain the columns noted in the [Prerequisites](/network_flow_reports#prerequisites) section. |
| `UNSUPPORTED RESOURCE` | The flow log is configured against a resource type that Vantage does not currently process for VPC Flow Log Reports. |
| `BUCKET NOT FOUND` | Vantage cannot locate the destination S3 bucket for this flow log. Verify the bucket still exists and that Vantage has read access to it. |
| `DELIVERY ERROR` | AWS reported an error delivering flow logs to the destination bucket. Check the flow log's delivery status in the AWS console for details. |
| `DELIVERY PENDING` | AWS has accepted the flow log configuration but has not yet started delivering data. This status typically clears within a few hours. |
### Troubleshooting
When you click **Check Permissions** during the onboarding process, an error is displayed when the correct permissions are not set up. Ensure that you add the correct permissions displayed in the onboarding workflow for *each* account.
#### KMS Encrypted Buckets
An error is displayed for buckets that are encrypted with AWS Key Management Service (KMS). You will need to either remove encryption on these buckets or provide Vantage the necessary permissions to decrypt (i.e., `kms:Decrypt`).
#### No Logs Displayed
You may see a message indicating *No VPC flow logs with log destination found. If you have recently created these resources it may take up to 24 hours for Vantage to sync the metadata.* Wait at least 24 hours if you recently created new resources. This can also be an issue if you have not enabled active resource syncing. To enable syncing:
Navigate to the [Workspaces](https://console.vantage.sh/settings/workspaces) section of the console.
Select the workspace where your AWS integration is set up.
At the top, ensure **Active Resource Syncing** is turned on.
### Manage Existing Integrations
After your integration is set up, you can view and manage your connected VPC Flow Logs directly from the [AWS Settings](https://console.vantage.sh/settings/aws) page:
On the **VPC Flow Logs** tab, the **Manage Connected VPC Flow Logs** panel lists each S3 bucket destination, the AWS account it belongs to, the current import status, and the connection date. Click any row to view the import history for that integration (including each VPC flow log's status, date, ingestion time, and row count), or click the trash icon to remove a bucket from syncing.
To add additional flow logs or deselect existing ones, click **Manage** at the top of the panel. The **Manage Flow Logs** pop-up window is displayed. From this window, you can:
* Select additional S3 buckets and logs to sync
* Deselect an S3 bucket or log files to remove the bucket from syncing
If no integrations exist yet, the **VPC Flow Logs** tab displays a **Connect VPC Flow Logs** link that opens the same **Manage Flow Logs** window. You can use it as an alternate starting point for the [Enable the Integration](#enable-the-integration) workflow.
If you add additional fields to your VPC Flow Log format in AWS, and you already sync these logs to Vantage, this new data will be imported to Vantage on the next nightly import.
## Create a New Network Flow Report
Follow the steps below to create a new Network Flow Report:
From the top navigation, click **Active Resources**.
From the side navigation, click **Network Flow Reports**. All your existing Network Flow Reports are displayed, along with who created the report and the date it was created.
Three reports are provided, by default, on this page: *All Network Flow Logs*, *Cross-AZ Traffic*, and *Public Traffic Destinations*. See the [Network Flow Report Examples section](/network_flow_reports#network-flow-report-examples) below for tips on how to get started with these reports.
To create a new report, click **New Network Flow Report**.
A new Network Flow Report is displayed.
* At the top of the report, a [Sankey diagram](https://en.wikipedia.org/wiki/Sankey_diagram) is provided. This diagram shows different network flows, based on your selected filters and grouping criteria. For example, in the image below, the nodes on the left side of the diagram show the sources of network traffic. Links, or network flows, flow from the nodes to their traffic destination (in this example, cross-AZ or public). The width of each flow corresponds with the volume of traffic or estimated cost, based on your settings, and the color corresponds with the source of the node (e.g., yellow for *public* in the example below).
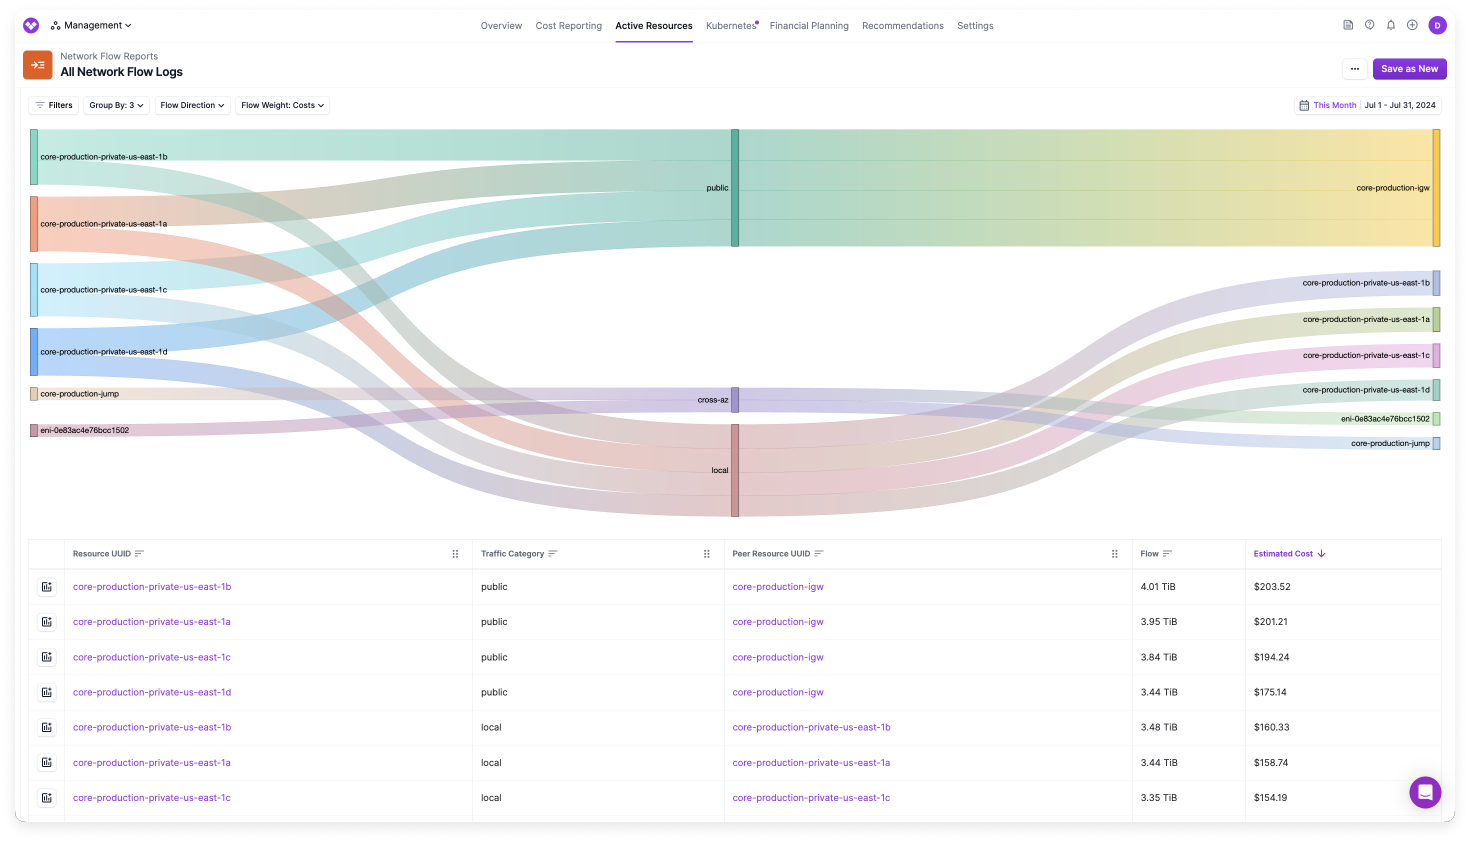
* In the table below the diagram, the network flow information is displayed along with the volume of traffic (in bytes). The table is sorted in descending order by the **Estimated Cost** column. Click any column header to change the sort order. Each flow shows the estimated cost associated with that specific traffic route, helping you identify the most expensive data transfers. (See the [section below](/network_flow_reports#estimated-cost-calculation-for-network-flows) for details on how the Estimated Cost column is calculated.)
* For each listed resource, a link to the [**Active Resources** screen](/active_resources) is provided. Click this link to view additional metadata about the resource. From the **Active Resources** screen, click the **Relationships** tab to view any associated resources, such as a corresponding IGW for a VPC resource.
You can update the criteria displayed in the Sankey diagram with the following options:
* By default, both egress and ingress traffic are displayed. Expand the **Flow Direction** menu above the diagram to change the flow to only **Egress** or **Ingress**.
This filter depends on whether `flow_direction` is present in your VPC Flow Log format. If `flow_direction` is not present in your VPC Flow Log format, then a *No data available in table* message is displayed on the report. See the [Prerequisites section](/network_flow_reports#prerequisites) for the recommended VPC Flow Log format. To add the field to your format, create a new VPC Flow Log configuration that includes the `flow_direction` field.
By default, Vantage ingests network flows into your account daily and keeps the data available for one week. For Enterprise customers, this retention period can be adjusted. Contact [support@vantage.sh](mailto:support@vantage.sh) if you need a longer retention period.
* You can move the columns in the table at the bottom to visualize different flows. The diagram is also updated to depict the new order in the table.
* You can also filter and group/add more columns to the report. See the next section for details.
To save the report, from the top right of the screen, click **Save as New**. Enter a report name, then click **Save**. (To edit this name, click the pencil icon in the breadcrumbs above the chart, next to the report's name.)
## Filter and Group a Network Flow Report
By default, a Network Flow Report is grouped by the following fields:
* Source Resource UUID
* Peer Resource UUID
* Traffic Category
You can filter and group by multiple criteria in Network Flow Reports. Expand the box below to see all available filter and grouping criteria with a description of each option.
| Vantage Field | Description | Example |
| - | - | - |
| Account ID | AWS account ID of the source network | production, 123456789012 |
| Availability Zone ID | ID of the source Availability Zone | us-east-1a |
| Destination Address | Specific IP address that identifies the location of where the traffic is being sent | An IP, like 1.23.456.90 |
| Destination Hostname | Domain name that corresponds with the IP address of the destination *(see note below table)* | 01234.broadband.com OR Datadog A `dsthostname:null` value means Vantage is unable to reverse DNS the `dst_address` IP address. |
| Flow Direction | Movement of network traffic relative to a specific network interface | Ingress or egress |
| Interface ID | Source ENI ID | eni-001d78b2agh4caa05 |
| Instance ID | Source instance ID | i-0b22a22eec53b9321 |
| Peer Resource UUID | Destination resource name, ARN, or tag (if available). When a Name tag exists, the human-readable name is displayed instead of the raw ARN. | my-instance OR eni-c123ab7f9c55af9a6d OR example-tag |
| Peer Account ID | Destination account ID | production, 123456789012 |
| Peer VPC ID | Destination VPC ID | vpc-12a34567b8g8a03ef |
| Peer Region ID | AWS Region of destination | us-west-2 |
| Peer Availability Zone ID | ID of the Availability Zone for the destination | us-east-1b |
| Peer Subnet ID | Destination subnet ID | subnet-123ab7f9c55af9a6d |
| Peer Interface ID | Destination ENI ID | eni-001d78b2agh4caa12 |
| Peer Instance ID | Destination instance ID | i-0b22a22eec53b9321 |
| Region | AWS Region of the source | us-east-1 |
| Resource UUID | Source resource name, ARN, or tag (if available). When a Name tag exists, the human-readable name is displayed instead of the raw ARN. | my-instance OR eni-c123ab7f9c55af9a6d OR example-tag |
| Source Address | Specific IP address from which the network traffic originates | An IP, like 1.23.456.90 |
| Source Hostname | Domain name that corresponds with the IP address of the source *(see note below table)* | 100.123.456.789.bc.googleusercontent.com OR Datadog |
| Subnet ID | ID of the source subnet | subnet-123ab7f9c55af9a6d |
| Traffic Category | The type of traffic | public, cross-AZ, cross-region, local, unknown A `Local` value means traffic between resources in the same Availability Zone, which typically does not incur data transfer charges. An `Unknown` value means Vantage is unable to categorize the type of traffic based on the available metadata. |
| Traffic Path | Path traffic takes to reach the destination, such as through a virtual private gateway | - In VPC - Internet Gateway or Gateway VPC Endpoint - Virtual Private Gateway - Intra-Region VPC Peering - Inter-Region VPC Peering - Local Gateway - Gateway VPC Endpoint (Nitro-based instances) - Internet Gateway (Nitro-based instances) |
| VPC ID | ID of the source VPC | vpc-12a34567b8g8a03ef |
To derive the hostname, Vantage checks against some hardcoded IP ranges, and then falls back to reverse DNS lookup for the IPs. If you have services with known IP ranges you want added, contact [support@vantage.sh](mailto:support@vantage.sh).
### Apply Filter Criteria
You can add additional fields via grouping and filtering criteria. To add a new filter:
Click the **Filters** button on the top left of the diagram.
* The **AWS costs where...** tile is displayed. Click **+ New Rule**.
* From the filter dropdown menu, select an option, like **Account ID**, **Instance ID**, etc.
* Two additional dropdown menus are displayed. Select **is**, **is not**, **contains**, or **does not contain** based on your desired filter criteria, then select one or more values from the second dropdown menu. For **contains** or **does not contain,** enter any text criteria to filter by.
If you are unable to see any values for a filter, this means that you are not capturing this information in your VPC Flow Logs format, and therefore, Vantage is unable to import this data.
* Click **Add**.
You can optionally edit your existing rule or add additional filter criteria.
* To edit the rule you just created, select the rule, make your changes, and click **Add**.
* If you want to add a rule to filter multiple criteria, such as filter by certain Regions and another rule to filter by certain Destination Hostnames, click **+ New Rule**. Add the additional criteria and click **Add**.
* To add a separate rule set, above the filter set, click **+ New Filter**. This rule set will be displayed as **Or AWS costs where...** on the new tile.
* To delete a rule set, click the trashcan icon on the top right of the rule set.
Above the rule set(s), click **Apply**. The diagram will update with your existing filter criteria.
### Apply Grouping Criteria
To add additional columns to the table and diagram, expand the **Group By** menu. Select or deselect grouping criteria. As you add grouping criteria, additional nodes and flows are displayed on the diagram. Additional columns are also added to the table for any new grouping criteria.
### Adjust Flow Weight
By default, the Sankey diagram is weighted by estimated cost. You can change this view to be weighted by bytes, or volume. Above the chart, click the **Flow Weight** menu and select **Costs** or **Bytes**. The Sankey diagram is updated accordingly. When you hover over a flow, the corresponding cost or volume in bytes is displayed in the tooltip.
## View Flow Log Metadata
For certain grouping criteria, you can view additional details about specific resources. Vantage provides this information when it can fetch provider resource metadata. If Vantage can resolve the IP address for the Source Address and Destination Address grouping criteria, it will also provide metadata for these groupings.
Expand the **Group By** menu and add one or more of the following options to your grouping criteria:
* Interface ID/Peer Interface ID
* Subnet ID/Peer Subnet ID
* VPC ID/Peer VPC ID
* UUID/Peer UUID
In the table, select the row for any resource. The **Flow Log Metadata** panel is displayed on the right side of the screen. Data is provided for the **Peer** and **Peer Resource**. In this panel, click the link for any listed resource to see a provider resource report displayed.
## Flow Log Sampling
Depending on the scale of your VPC and the volume of flow logs that Vantage needs to process, sampling may be automatically enabled for your account. When sampling is active, Vantage ingests a representative subset of your flow log records rather than the full dataset. This trade-off allows Vantage to process large volumes of flow log data efficiently while still providing meaningful proportions and comparisons of your network traffic.
When sampling is active, the **Flow** and **Cost** columns in the report table show estimated totals that have been scaled up from the sampled data to approximate what the full, unsampled traffic would look like. An info icon is displayed next to both column headers. Hover over this icon to see the maximum sampling rate that was applied to the data in the current report view.
Sampling is enabled automatically by Vantage based on the scale of your environment. You do not need to configure or manage sampling directly.
## Estimated Cost Calculation for Network Flows
The estimated cost for each flow is calculated by applying your blended data transfer rates to the flow of traffic. For example, if a flow is moving between one subnet to another and those subnets are in different Availability Zones, Vantage applies your cross-AZ data transfer rate to those bytes.
Because data transfer rates can be tiered, and the metadata associated with the destination may change, this calculation is a best-effort calculation; however, it does help to identify cost hotspots within your network.
The flow logs cost calculation is based on the following formula:
$$
Estimated\ Cost=\sum_{i=1}^{N} (Rate_{i} \times Volume_{i})
$$
* $N$ is the total number of data flows.
* $R_i$ is the rate (cost per unit of data) for the $i$-th flow.
* $V_i$ is the volume of data transferred for the $i$-th flow.
Vantage first identifies the different flows of data within your network. It uses information provided within the AWS Cost and Usage Reports (CUR) to determine the specific rate (cost per unit of data) that applies to each type of data flow (e.g., cross-AZ, public). Each rate for each data flow is multiplied by the amount of data transferred in that flow. The estimated cost is then determined by the sum of these products.
## Network Costs on Cost Reports
On [Cost Reports](/cost_reports), for resources that generate network traffic costs (e.g., NAT Gateways), a **Network Costs** button is displayed in the Cost Report list. Click this button to view a Network Flow Report that is filtered to flows coming from that specific resource.
The below Cost Report is grouped by **Service** and **Resource**.
## Network Flow Report Examples
The following examples demonstrate common scenarios for using Network Flow Reports. These examples are based on the three reports that Vantage provides by default: *All Network Flow Logs*, *Cross-AZ Traffic*, and *Public Traffic Destinations*.
### Example 1 - View All Network Traffic
The **All Network Flow Logs** report shows all your network flows. The flow’s Resource UUID and Peer Resource UUID are provided as well as the traffic category (e.g., public). Review this report to get a high-level view of all your traffic flows.

### Example 2 - Identify Cross-AZ Traffic
Cross-AZ data transfer within AWS incurs higher costs compared to intra-AZ data transfer. [According to AWS](https://aws.amazon.com/ec2/pricing/on-demand/#Data_Transfer), "For data transferred between a Local Zone and an Availability Zone within the same AWS Region, "in" to and "out" from Amazon EC2 in the Local Zone" data is charged at \$0.01/GB for *both* transfer in and transfer out. Transferring data between AZs requires more network bandwidth compared to transferring data within the same AZ. This additional bandwidth consumption contributes to higher costs.
In the provided cross-AZ report, you can view all cross-AZ traffic along with flow size and estimated cost. The **Peer Availability Zone ID** column shows exactly where the traffic is flowing. You can see both the source and peer AZs along with the associated source and peer resources.
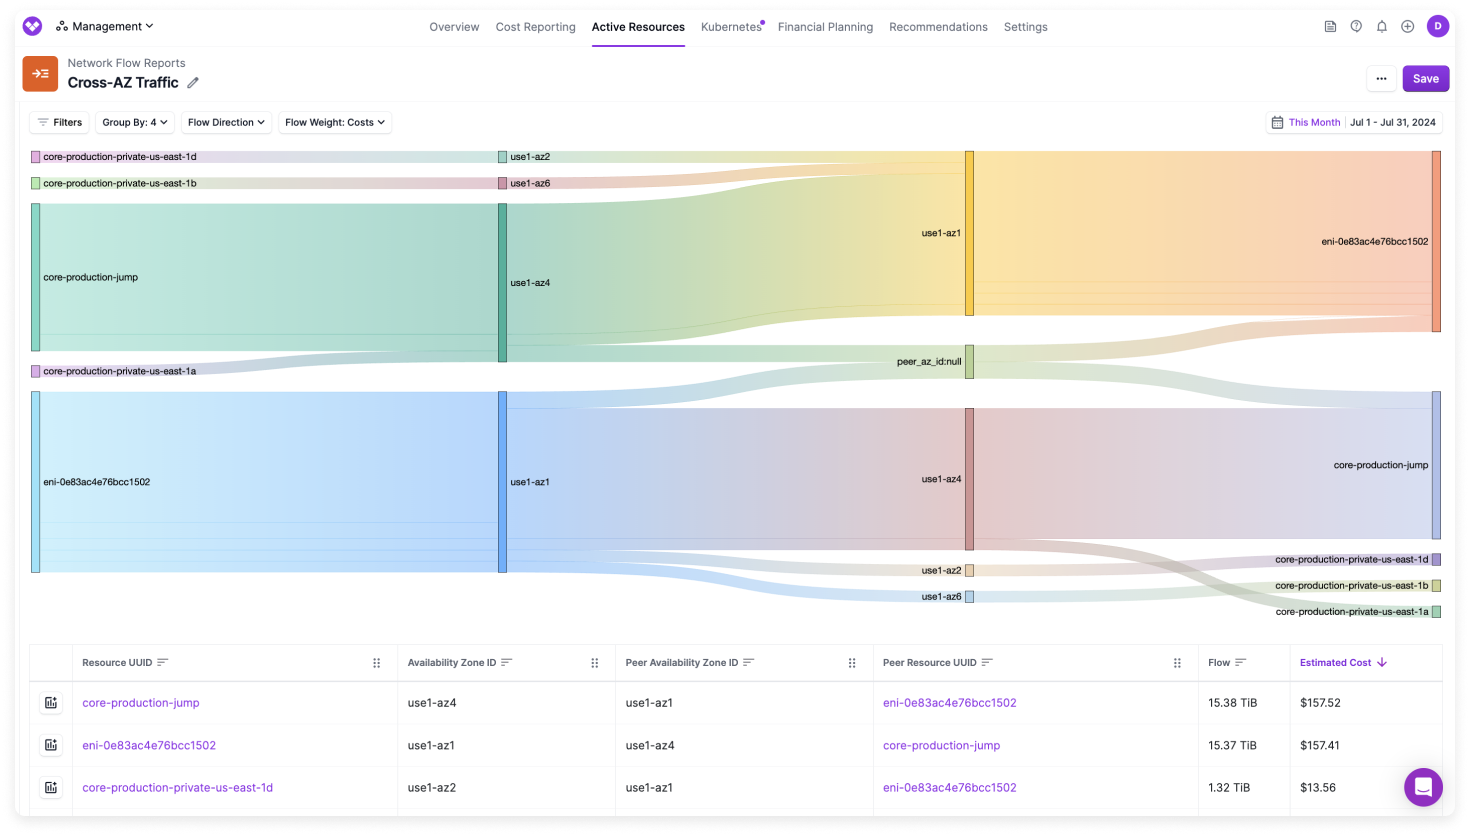
Review the highest-costing flows and consider the following tips:
* Try to place dependent resources within the same AZ to minimize cross-AZ data transfer.
* Use [VPC endpoints](https://docs.aws.amazon.com/vpc/latest/privatelink/privatelink-access-aws-services.html) to route traffic internally within AWS, reducing the need for cross-AZ traffic. This can help in minimizing data transfer costs and enhance security by keeping everything in the same VPC.
### Example 3 - Examine Public Traffic
When monitoring network costs, analyzing public traffic can reveal significant insights about where your traffic is going when it reaches the public internet. By analyzing destination details, you can ensure that traffic is taking the correct path or is going only to trusted and necessary endpoints. In this report, the **Destination Hostname** grouping/column provides a human-readable format of the destination, helping you quickly identify known destination services or endpoints.
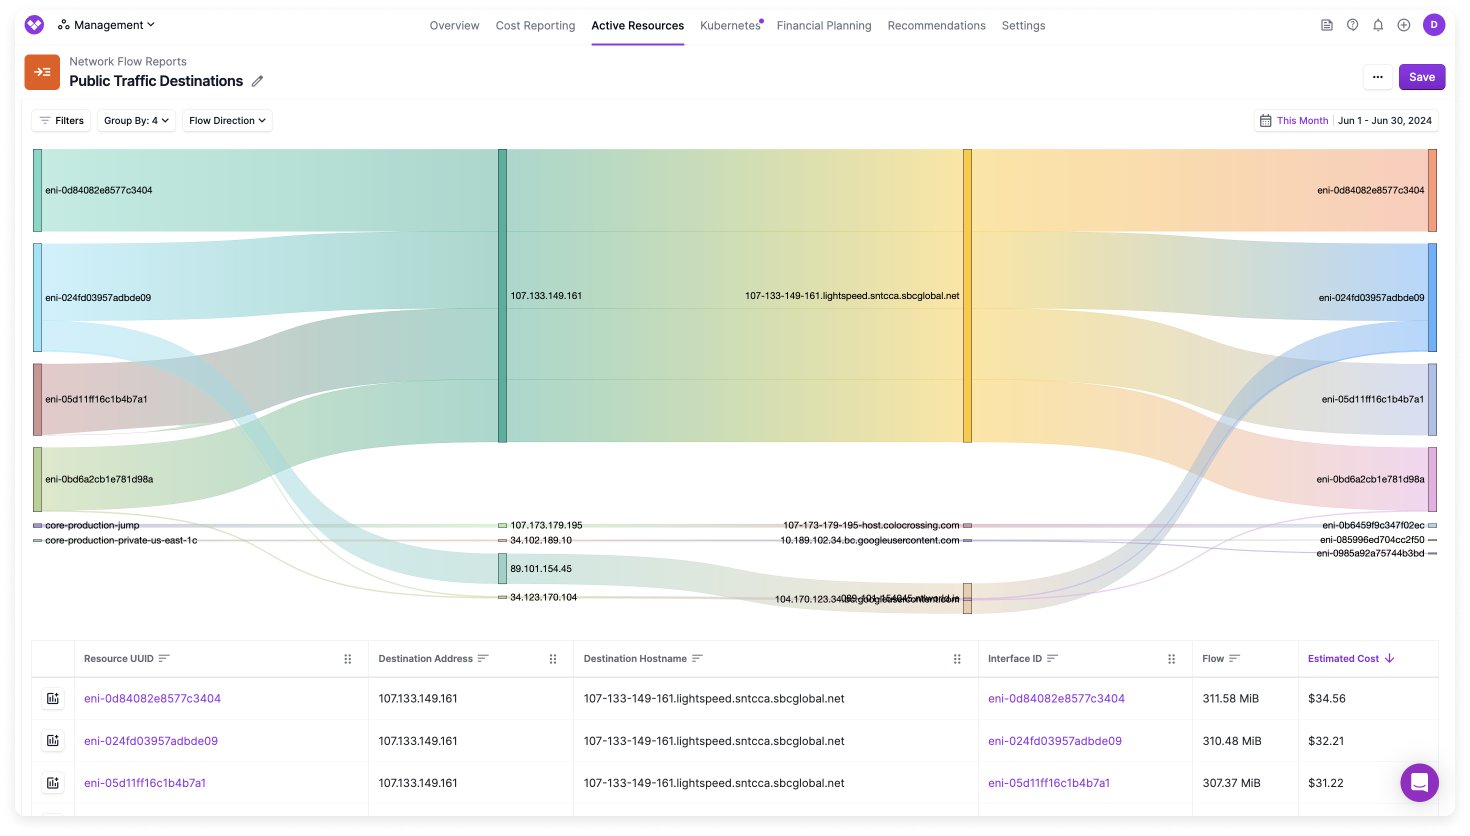
Vantage identifies hostnames using a reverse DNS lookup, or when vendors publish static IP address ranges, such as Datadog, Vantage can associate these IP addresses with the name of the service. The **Destination Address** provides the exact IP address, which is useful for detailed analysis to ensure traffic is reaching the intended destinations.
Examine this report to understand which resources are generating public traffic and where that traffic is going. Consider whether you might use alternative services, like AWS [Direct Connect](https://aws.amazon.com/directconnect/), [CloudFront](https://aws.amazon.com/cloudfront/), or [PrivateLink](https://docs.aws.amazon.com/whitepapers/latest/aws-vpc-connectivity-options/aws-privatelink.html), to optimize data transfer and reduce costs.
# Notion MCP
Source: https://docs.vantage.sh/notion_mcp
Connect the Notion MCP to the Vantage FinOps Agent to bring your team's documentation into cost investigations and draft new pages from Vantage data.
The Notion MCP Connector links the [Vantage FinOps Agent](/vantage_finops_agent) to your [Notion](https://notion.com) workspace through Notion's [hosted MCP server](https://developers.notion.com/docs/mcp). Once connected, the Agent can pull in the pages you have access to, like architecture docs and runbooks, and draft new pages summarizing a cost investigation, all in the same conversation that understands your Vantage cost data.
The Notion MCP Connector is one of several [MCP Connectors](/vantage_finops_agent#mcp-connectors) for the FinOps Agent. It is available to all Vantage customers using the FinOps Agent, in the [Vantage console](https://console.vantage.sh/agent), Slack, and [Canvas](/canvas).
## Prerequisites
Before you start, make sure you have:
* The [FinOps Agent](/vantage_finops_agent) enabled in Vantage. The Notion MCP settings page prompts you to enable it first if it is not already on.
* A Vantage role that can manage integrations, such as **Organization Owner** or **Integration Owner**, to enable the connector for your organization. See [Role-Based Access Control](/rbac) for details.
* A Notion account with access to the pages and databases you want the Agent to use. Each Vantage user authorizes their own Notion account.
## How the Connection Works
The Notion MCP uses a two-part connection model, and the order matters:
1. **Start here (Organization Owner or Integration Owner):** enable the Notion MCP for your organization once, from the **Organization Settings** tab on the [Integrations page](https://console.vantage.sh/settings/integrations). Until this is done, other users see a prompt to contact an Owner or Integration Owner.
2. **Then, each user:** authorize your own Notion account from the **MCP Settings** tab, or when the Agent prompts you mid-conversation.
Per-user authorization is required because Notion content is scoped to the requesting user. The Agent acts with your own Notion identity and can only read or write content you could access directly in Notion.
### Settings Tabs
The Notion MCP settings page has up to two tabs:
* **MCP Settings**: connect, disconnect, or reconnect your own Notion account and view your personal connection status. Every user has this tab.
* **Organization Settings** (Organization Owners and Integration Owners only): enable or disable the Notion MCP for the whole organization and view the list of users who have connected.
Once the Notion MCP is enabled for your organization, any Vantage role (down to Organization Viewer) can connect their own Notion account. Enabling it also lets **Organization Editors and Organization Viewers** open Settings > Integrations, where they see only the **MCP Connectors** section. A connector you have not connected yet shows as **Not Connected**. See [Role-Based Access Control](/rbac) for details.
Enterprise workspaces that use Notion's MCP Governance controls must approve Vantage on their AI apps allowlist before members can connect. If your connection is blocked, ask your Notion workspace administrator to allow the Vantage app.
## Permissions and Data Access
When you authorize Notion, the connection is scoped to your own Notion access. Once connected, the FinOps Agent can:
* Respect your existing page and database access and permissions.
* Take actions on your behalf, based on your access level, including reading and writing pages.
* Search across connected apps (requires a Notion AI plan).
* View your workspace's users and their email addresses.
Vantage stores only the data that is explicitly written into your FinOps Agent conversation responses or a [Canvas](/canvas) report; no ancillary Notion data is collected or stored outside of your conversation, and data retrieved through the connector is not used to train any models.
**Connections expire by design.** Notion authorizations expire after 180 days, or after 30 days of inactivity. When your connection lapses, reconnect from the **Notion MCP** page to restore access. This periodic reconnection is expected and routine.
## Available Tools
The FinOps Agent connects to Notion's hosted MCP server and chooses the right tools automatically based on your question. Available functionality includes:
* **Find and read**: search across pages and databases and read their content, and view your workspace's users and their emails.
* **Create and update**: create and update pages and add comments on your behalf.
The Agent only creates or modifies Notion content when you explicitly ask it to, and everything it reads or writes is bounded by your own Notion access. In [Canvas](/canvas), the Notion MCP is read-only, so write actions are not available there. Notion's MCP server does not currently support file or image uploads, and cross-app search requires a Notion AI plan. If a write returns an authorization or scope error, the Agent surfaces it and points you back to the **Notion MCP** settings page to reconnect rather than retrying.
## Connect the Notion MCP
As an **Organization Owner** or **Integration Owner**, click **Settings** in the top navigation. On the left navigation, select **Integrations**, then find the **MCP Connectors** section and select **Notion MCP**. In the **Organization Settings** tab, enable the connector for your organization.
If the page shows a banner asking you to enable the FinOps Agent, open the [FinOps Agent settings page](https://console.vantage.sh/settings/finops_agent) and enable it first, then return to the Notion MCP page.
On the **Notion MCP** page, open the **MCP Settings** tab and click **Connect Notion**. Vantage redirects you to Notion to complete the OAuth flow. Every user who wants to use the connector completes this step for their own account.
Sign in to Notion and authorize access. After you approve, Notion redirects you back to Vantage and your connection status changes to connected.
Back in Vantage, confirm the Notion MCP shows as connected. You can now ask the FinOps Agent Notion-aware questions in the console or in Slack.
You can also connect Notion directly from an Agent conversation. When you ask the Agent to do something that needs Notion and you have not connected yet, it prompts you to authorize your account inline.
## Example Use Cases
Once the Notion MCP is connected, the FinOps Agent decides when to reach for Notion tools based on the question you ask. It can call Notion tools in the same turn it uses Vantage tools, combining cost data with your team's documentation.
For prompting best practices and more copy-paste examples, see the [FinOps AI Prompt Guide](/finops_ai_prompt_guide).
### Pull Architecture Context Into an Investigation
Ask the Agent to reference a Notion doc describing a service's architecture while investigating why its costs changed.
Our data pipeline costs jumped this month. Pull the architecture doc for the pipeline from Notion and help me figure out which component is driving the increase.
### Find the Owner for a Cost Anomaly
Reference Notion pages that document team ownership when deciding who should act on a cost anomaly or recommendation.
Check our team ownership page in Notion and tell me which team owns the service behind this anomaly.
### Retrieve a Runbook
Ask the Agent to retrieve a relevant runbook from Notion while diagnosing an infrastructure cost issue.
Find the runbook in Notion for scaling down our staging environment and summarize the steps.
### Draft an Investigation Summary
Ask the Agent to draft a Notion page summarizing a cost investigation or optimization plan based on Vantage data.
Draft a Notion page summarizing this month's cost anomaly investigation, including the affected services, root cause, and the optimization actions we agreed on.
### Summarize Your Top Recommendations as a Notion Page
Ask the Agent to pull your top cost recommendations and draft a Notion page your team can act on, so the plan lives in your knowledge base instead of a chat transcript.
Create a Notion page with my top cost optimization recommendations for the month, including the estimated monthly savings for each and a short description of the change.
## Troubleshooting
Enable the [FinOps Agent](/vantage_finops_agent) first from the [FinOps Agent settings page](https://console.vantage.sh/settings/finops_agent), then return to **Settings** > **Integrations** > **MCP Connectors** > **Notion MCP**.
An **Organization Owner** or **Integration Owner** must enable the Notion MCP for your organization before individual users can authorize their accounts. If your workspace uses Notion's MCP Governance, a Notion administrator must also approve Vantage on the AI apps allowlist.
Notion authorizations expire after 180 days or 30 days of inactivity, and can also be revoked in Notion. Reconnect from the **Notion MCP** page to restore access. This is expected periodically and does not indicate a problem.
The Agent can only access content your own Notion account can access. Confirm the page or database is shared with your Notion user and, if your workspace restricts integrations, that Vantage is approved on the AI apps allowlist.
Notion's MCP server does not currently support image or file uploads, so the FinOps Agent cannot attach files or images to pages it creates or edits. Text-based content, such as drafting or editing a page, is unaffected.
If you disconnect your own account, the Notion tools are no longer available to the FinOps Agent for you. If an administrator disables the connector for the organization, every user's Notion connection is disconnected. Previous conversations retain their historical responses based on your data retention period, but the Agent can no longer call Notion after it is disconnected.
# Overview
Source: https://docs.vantage.sh/overview
Explore the Vantage Overview page, your executive dashboard for monitoring cloud costs.
Once you create some provider integrations, Vantage will automatically begin ingesting billing information for your account. The default landing page in the Vantage console is the **Overview** page. This page serves as an executive-level summary, providing a comprehensive snapshot of the cost metrics that matter most to you. Review widgets on the Overview page for high-level cost summaries.
Use the **Explore** bar in the top navigation to quickly access pages, reports, dashboards, and other resources in your current workspace, making it easier to get to the report or feature you need. It can also surface recent and starred items. The **Explore** bar only shows pages and resources you're authorized to access, based on your current workspace and permissions. Press `⌘K` on Mac or `Ctrl+K` on Windows/Linux to open it.
When a user navigates to `console.vantage.sh`, the **Overview** page is displayed. An individual user or owner of a team can configure a default dashboard to be displayed instead of the **Overview** page. See the [Default Dashboards](/dashboards#set-a-default-dashboard) documentation for details.
Depending on your provider connections, you will see some of the following widgets:
An AWS-specific widget that provides a clear comparison between your total on-demand vs. committed spend. This view helps you understand your expenses for on-demand resources in contrast to cost-saving strategies, like Savings Plans, Reserved Instances, Enterprise Discount Programs, and Committed Use Discounts.
Widgets that offer comprehensive cost breakdowns for providers. These widgets provide you with spending insights, displaying the current accrued costs and cost trends compared to the previous month.
A widget for each one of the [Cost Reports](/cost_reports) you create. One default Cost Report will be present in your account that is referred to as **All Resources**. As you create more Cost Reports in your account, a summary of each Cost Report will automatically show up on the Overview page.
# Vantage for MSPs
Source: https://docs.vantage.sh/partners
Manage multiple customer accounts with Vantage for MSPs.
Vantage provides an administrative portal for Managed Service Providers, or MSPs (also sometimes referred to as Resellers), to provision and centrally manage Vantage accounts on behalf of their end customers. MSPs can access this portal from their Management Account and move between each of their customers' Managed Accounts.
**GETTING STARTED**
If you are interested in this functionality, contact [partnerships@vantage.sh](mailto:partnerships@vantage.sh). Your Vantage account will be set up to include a Vantage for MSPs administrative portal.
If you already have separate accounts for your customers in Vantage and want to consolidate them to this model, contact [support@vantage.sh](mailto:support@vantage.sh).
## Terms to Know
The following terms are used throughout this documentation.
| Term | Definition |
| - | - |
| **Managed Account** | A customer account that is provisioned and administered by an MSP. Managed Accounts have full access to Vantage features but cannot manage their own subscription. |
| **Management Account** | The MSP’s central administrative account used to create and oversee customers' Managed Accounts, manage billing rules, and configure integrations. |
| **Manager User** | A user from the MSP’s organization who accesses a customer's Managed Account. This user will inherit their role from their user in the Management Account. When logged in to a Managed Account, the Manager User sees visual indicators showing they are acting on behalf of the customer. |
## Partner Settings
The **Partner Settings** section in the Vantage console contains the following pages:
The central administrative portal for MSPs to perform the following actions:
* Create new customer Managed Accounts and update their name/contact email
* Delete existing customer Managed Accounts
* Log in to a customer's Managed Account
* Add integrations on behalf of a customer's Managed Account
* Assign billing rules to a customer's Managed Account
See the [Managed Accounts](/partners#create-a-new-customer-managed-account) section for additional information.
Create custom billing adjustments, one-time charges, re-rating, and MSP-level discounts. See the [Billing Rules](/partners#billing-rules) section for additional information.
Define custom exchange rates and set the display currency for Managed Accounts. See the [Currency Management](/partners#configure-currency-management) section for additional information.
View all integrated accounts across providers, see which Managed Accounts each integration is assigned to, and assign or remove integrations in bulk. See the [Partner Integrations](/partners#manage-partner-integrations) section for additional information.
## Create a New Customer Managed Account
A customer Managed Account functions just like a regular Vantage account; however, customers cannot view or manage subscriptions to Vantage. All Vantage features, like reports, SSO, and Slack/MS Teams integrations, are available and scoped to each customer Managed Account.
To provision a new customer Managed Account:
Log in to your Vantage for MSPs Management Account.
From the top navigation, click **Settings**.
From the left navigation, under **Partner Settings**, select **Managed Accounts.**
The **Managed Accounts** administrative portal is displayed. All existing customer accounts are displayed along with the **Account Name**, **Contact Email**, and the date when the account was created. At the top, click **New Managed Account**.
The **Tracked Spend** shown for each Managed Account (and the total at the top of the screen) reflects the previous full calendar month of spend in USD, not a year-to-date or rolling total. For example, any time you view this screen during October, the figure reflects spend from **September 1–30**.
Enter an **Account Name** and a **Contact Email Address**. The email address is your administrator ID for this account and therefore must match your company's email domain. The email address cannot exist for another customer's Managed Account; however, an alias is acceptable, like `admin+customer@yourdomain.com`.
Click **Create Account**.
When you create a Managed Account, Vantage creates a default **All Resources** Cost Report for that account. The report inherits display settings from the oldest default Cost Report in the Management Account, including chart type, date binning, date interval, and cost settings. The Managed Account keeps its own report title and filters.
## Role-Based Access Control
Access to Customer Managed Accounts is managed through [Role-Based Access Control (RBAC)](/rbac). Users in the Management Account with the **Organization Owner** role can set access to Managed Accounts, based on a user's team, following the steps below:
From the top navigation, select **Settings**.
Under **General Settings**, select **Teams**.
Select the team you want to manage access for.
Select the **Access** tab.
In the **Managed Account Access** section, you can view a list of all Managed accounts. You can adjust a team's access accordingly based on the following options:
* **Can Access**: Members of the team will be granted explicit access to the Managed Account.
* **Cannot Access**: Members of the team will be explicitly denied access to this Managed Account.
* **Inherit Access**: Access to the Managed Account will be determined by the Everyone Team.
If a user is a part of a Team that **Cannot Access** a Managed Account, they will be unable to access that Managed Account, even if they are granted **Can Access** permission via a different team. Users will maintain the same role that they have in the Management Account when they enter a Managed Account.
### Access Examples
Team A is assigned **Can Access** to the **Customer A** Managed Account.
Result: Any user that belongs to Team A can access the **Customer A** account with their existing role (e.g., Editor).
A user belongs to Team A with **Can Access** to the **Customer A** Managed Account.
The same user also belongs to Team B, which has **Cannot Access** to the **Customer A** account.
Result: The user cannot access the **Customer A** account because the explicit denial overrides all other access.
The Everyone Team has **Can Access** to the **Customer A** Managed Account.
A new user is added to Team A, which has **Inherit Access** to the **Customer A** account.
Result: The user can access **Customer A** as it inherits access from Everyone Team.
### User Permissions
The following permissions apply based on a user's role.
| | Organization Owner | Integration Owner | Organization Editor | Organization Viewer |
| - | - | - | - | - |
| View Management Account | | | | |
| Create resources in Management Account | | | | |
| Add and remove Managed Accounts | | | | |
| Add and remove provider integrations | | | | |
| View Managed Accounts (if access is granted) | | | | |
| Create resources in Managed Accounts (if access is granted) | | | | |
| Perform additional administrative capabilities in Managed Accounts, like create new users, create new workspaces, manage teams, modify billing options, manage authentication, manage currency conversion, and manage Virtual Tags (if access is granted) | | | | |
## Configure Currency Management
Currency management lets MSP Owners define custom exchange rates and set the display currency for managed accounts. Currency management is available for any currency that is present in incoming cloud provider data.
Currency management has two main functions:
* **Custom Exchange Rates:** Override Vantage's default conversion rates with your own values.
* **Display Currency:** Choose the currency that's displayed on reports for managed accounts.
* If you set a currency at the MSP level, managed accounts cannot change it.
* If you do not set one, the managed account can choose its own display currency and exchange rate configuration following the [currency conversion documentation](/vantage_account#currency-conversion).
Setting a display currency does not require custom rates; if no custom rate exists, Vantage defaults to its own rates. Currencies set by a management account apply to all workspaces within a managed account.
Converted currency is currently available on Cost Reports (including forecasts), Provider Resources, Kubernetes Efficiency Reports, Financial Commitment Reports, Budgets, and any invoices generated for a Managed Account.
### Upload Exchange Rates
If you want to override Vantage's default currency conversion rates, you can upload your own custom exchange rates in bulk using a CSV file.
From the top navigation, click **Settings**.On the left navigation under **Partner Settings**, select **Currency Management**.
Select the **Currency Rates** tab.
On this page, the original and display currency are displayed along with the conversion rate and effective date for the rate. Use the filters at the top of the page to filter the table by original or display currency.
Click **Upload CSV**.
Create a CSV file that uses the following format:
Currency From,Currency To,Exchange Rate,Date
USD,PHP,57.19,2025-01-01
USD,PHP,56.21,2025-02-01
USD,PHP,57.09,2025-03-01
USD,PHP,56.01,2025-04-01
* **Currency From**: The source currency code (e.g., `USD`).
* **Currency To**: The target currency code (e.g., `PHP`).
* **Exchange Rate**: The conversion rate as a number (e.g., `57.19`). Supports up to 10 decimal places; values with more decimal places are rounded.
* **Date**: The effective start date for the exchange rate in `YYYY-MM-DD` format (e.g., `2025-01-01`). Each rate applies only for that month. At the start of the following month, Vantage reverts to its default exchange rates unless another custom rate is provided.
Click **Select CSV File**, then select your file.
Click **Upload CSV**.
Any file format or validation errors are displayed at the top of the page. Correct the error(s) and reupload the file. See the [Troubleshooting section](/partners#troubleshooting-currency-upload-errors) for details.
Once the file is uploaded, data must be reprocessed to display costs in your updated currency. While some updates will be shown immediately, updates to all parts of the Vantage console may take up to 15 minutes.
### Set Display Currency for Managed Accounts
You can set a display currency for managed accounts at any time. If a custom exchange rate exists, the account will use that rate; otherwise, Vantage defaults to its own conversion rates.
On the **Currency Management** page, select the **Managed Accounts** tab. A list of your managed accounts is displayed along with the **Currency Status**:
* An **Enabled** status indicates that you've selected the display currency that's shown to the right of the status column.
* A **Disabled** status indicates the account displays costs in the default currency (USD).
Select one or more accounts to update:
* Click **Set Display Currency**.
* Select a currency code.
* Click **Update Currency**.
### Troubleshooting Currency Upload Errors
If you encounter errors when uploading your CSV file, refer to the following common issues and solutions:
**Error:** `Row must be 4 items, found X items.`
**Cause:** A row in your CSV file does not have data for one or more columns.
**Solution:** Ensure each row has data for each column.
Missing data
Currency From,Currency To,Exchange Rate,Date
USD,PHP,57.19
All data present
Currency From,Currency To,Exchange Rate,Date
USD,PHP,57.19,2025-01-01
**Error:** `Must not have an empty row`
**Cause:** One or more rows in your CSV file is empty.
**Solution:** Remove any rows that are empty.
Empty row
Currency From,Currency To,Exchange Rate,Date
USD,PHP,57.19,2025-01-01
,,,,
USD,EUR,0.92,2025-01-01
No empty rows
Currency From,Currency To,Exchange Rate,Date
USD,PHP,57.19,2025-01-01
USD,EUR,0.92,2025-01-01
**Error:** `Base currency code [CODE] is not valid.`
**Cause:** The currency code in the `Currency From` column is not recognized by Vantage.
**Solution:** Use a valid ISO 4217 currency code. Common codes include `USD`, `EUR`, `GBP`, `JPY`, `CAD`, `AUD`, etc.
Invalid currency code
Currency From,Currency To,Exchange Rate,Date
USDOLLAR,PHP,57.19,2025-01-01
Valid currency code
Currency From,Currency To,Exchange Rate,Date
USD,PHP,57.19,2025-01-01
**Error:** `Currency code [CODE] is not valid.`
**Cause:** The currency code in the `Currency To` column is not recognized by Vantage.
**Solution:** Use a valid ISO 4217 currency code for the target currency.
Invalid currency code
Currency From,Currency To,Exchange Rate,Date
USD,PESO,57.19,2025-01-01
Valid currency code
Currency From,Currency To,Exchange Rate,Date
USD,PHP,57.19,2025-01-01
**Error:** `Rate [VALUE] is not valid, must be a number.`
**Cause:** The exchange rate contains non-numeric characters or formatting.
**Solution:** Use only numeric values for exchange rates. Do not include currency symbols, commas, or text.
Non-numeric rate
Currency From,Currency To,Exchange Rate,Date
USD,PHP,\$57.19,2025-01-01
USD,PHP,57.19 USD,2025-01-01
USD,PHP,fifty-seven,2025-01-01
Numeric rate only
Currency From,Currency To,Exchange Rate,Date
USD,PHP,57.19,2025-01-01
USD,PHP,0.92,2025-01-01
**Error:** `Date [DATE] is not valid, must be YYYY-MM-DD`
**Cause:** The date format is incorrect or the date is invalid.
**Solution:** Use the exact format `YYYY-MM-DD` with valid dates.
Wrong date format
Currency From,Currency To,Exchange Rate,Date
USD,PHP,57.19,01/01/2025
USD,PHP,57.19,2025-1-1
USD,PHP,57.19,Jan 1 2025
USD,PHP,57.19,2025-13-01
Proper YYYY-MM-DD format
Currency From,Currency To,Exchange Rate,Date
USD,PHP,57.19,2025-01-01
USD,PHP,57.19,2025-02-01
* Dates are normalized to the first day of the month (e.g., 2025-01-15 becomes 2025-01-01). Each custom rate is valid only for that month; after that, Vantage defaults back to its own exchange rates unless another custom rate is defined.
* Exchange rates should reflect how much of the target currency equals 1 unit of the source currency.
* All currency codes must be valid ISO 4217 codes that are present in your cloud provider data.
## Access a Customer's Managed Account
From the **Managed Accounts** screen, you can move between each of your customers' Managed Accounts.
Next to any Managed Account's name, click **Enter Account →**.
The Managed Account is displayed. When you enter a customer's account, you are considered the **Manager User** for that account.
* A yellow bar is displayed around the border of the screen to indicate you are logged in to the Managed Account.
* On the bottom left, a pop-up is displayed to indicate which Managed Account you are logged in to.
Perform one of the following actions to return to your Management Account:
* On the top right, click your user icon. Then, click **Return to MSP account**.
* On the bottom left of the screen, click the **X** in the **Logged in as** pop-up.
Once you are back in the Management Account, a confirmation message is displayed at the top.
### Single Sign-On for Managed Accounts
After a Managed Account is created, you can enable Single Sign-On (SSO) for each Managed Account. Enter the Managed Account, then follow the instructions provided in the [SSO documentation](/sso) to enable SSO directly within the customer's Managed Account. Customers can also enable SSO directly from their own account. SSO is scoped to the Managed Account.
## Add Integrations to a Managed Account
The way you add integrations to a Managed Account depends on how your MSP is set up. There are two available workflows:
* **Workflow 1 - Unconsolidated Organizations:** An example MSP structure for this workflow might be where you have completely separate AWS Organizations set up for each customer. As an MSP, you have access to the payer account, and the customer has access to a member account. In this case, follow the steps below to ***Configure Integrations in the Managed Account***.
* **Workflow 2 - Consolidated Organizations:** In this setup, the MSP uses a single AWS Organization that includes multiple linked accounts under a centralized Management Account. In this case, follow the steps below to ***Configure Integrations in the Management Account***.
For Azure CSP partners, you can connect the [Azure Partner Billing (CSP) integration](/connecting_azure_csp) in your Management Account to ingest costs across all your customers. Once connected, you can delegate these costs to managed accounts and create customer-specific Cost Reports and Dashboards using Azure CSP data. Follow Workflow 2 below for this setup.
### Configure Integrations in the Managed Account (Unconsolidated Organization Workflow)
If this is the first time you are adding an integration:
From the **Managed Accounts** screen, enter a customer’s account. If this is the first time you are connecting integrations for a customer, the **Connect Accounts** screen is displayed.
Select an integration and follow the steps provided in the console.
If you are adding another integration:
From the top navigation, select **Settings**.
On the left navigation, click **Integrations**. All available integrations are displayed. Select an integration to get started.
See the [Quickstart](/getting_started) for a list of all other existing Vantage provider integrations, with links to each provider integration walkthrough.
### Configure Integrations in the Management Account (Consolidated Organization Workflow)
This workflow requires that you first set up an integration in your MSP account. From the **Managed Accounts** screen, you can add any of your connected integrations to a Managed Account.
To get started, ensure that you have connected a provider integration to your Management Account.
For AWS integrations, see the [AWS multiple accounts documentation](/connecting_aws#connecting-multiple-aws-accounts) for information on how to connect a Management Account with multiple linked accounts. When you assign an AWS payer account integration to a Managed Account, all linked member accounts under that payer are automatically delegated as well. If new member accounts are later added to the AWS Organization, they are also automatically delegated to any Managed Accounts that already have the payer integration assigned. Note that provider integrations passed down to customer Managed Accounts from an MSP's provider integrations will only be available in the first workspace of that customer.
After you have connected an integration to your MSP account, follow the steps below to associate them with customer Managed Accounts.
From the **Managed Accounts** screen, select a customer's account.
Select the **Integrations** tab. All connected provider integrations for that customer are displayed. The account status, such as **Stable**, **Importing**, or **Error**, is also displayed.
To add a new connection, click **Connect** next to any listed provider.
Select any of the listed provider accounts that you want to import data from.
Click **Save**.
Once you have connected integrations in your Management Account, you can use the [Partner Integrations](/partners#manage-partner-integrations) page to view all integrations across providers and assign or remove them from Managed Accounts in bulk.
#### Customer Managed Account Integration View
When an MSP manages an integration in their MSP Management Account, a customer can view the managed integration's status. The customer cannot remove this type of integration.
From a customer's account, click **Settings** in the top navigation.
On the left navigation, under **MSP Settings**, click **Managed Integrations**.
Any connected integrations managed by the MSP are displayed.
## Manage Partner Integrations
After you have [connected integrations](/partners#add-integrations-to-a-managed-account) to your Management Account, the **Partner Integrations** page provides a centralized view of all your integrated accounts across providers. From this page, you can see which Managed Accounts each integration is assigned to and assign or remove integrations in bulk, without navigating into individual Managed Account profiles.
You must have the **Organization Owner** or **Integration Owner** role to access and manage Partner Integrations. Accessing this page does not affect any existing integration assignments.
To access the Partner Integrations page:
From the top navigation, click **Settings**.
On the left navigation, under **Partner Settings**, click **Partner Integrations**.
The Partner Integrations table is displayed. The table contains the following columns:
| Column | Description |
| - | - |
| **Account** | The name of the integrated account. A **Root** badge is displayed for root/payer accounts. |
| **Billing Account** | The parent billing or payer account that the integration belongs to. A dash (**—**) is displayed for integrations that do not have a parent billing account. |
| **Provider** | The cloud provider for the integration (e.g., AWS, Azure, GCP). |
| **Connected Managed Accounts** | The Managed Accounts that the integration is currently assigned to. If no Managed Accounts are assigned, a dash (**—**) is displayed. |
### Filter Integrations
Use the filter bar at the top of the Partner Integrations table to narrow down the list of displayed integrations. The following filters are available:
* **Billing Account**: Filter by one or more parent billing accounts.
* **Provider**: Filter by one or more cloud providers.
* **Managed Accounts**: Filter by connected Managed Accounts. Select **None** to display integrations that are not assigned to any Managed Account.
You can also use the search bar to search across integration account names, billing accounts, providers, and connected Managed Account names.
### Assign Integrations to Managed Accounts
You can assign one or more integrations to Managed Accounts. When you assign an integration, the associated costs become available in the Managed Account.
To assign a single integration:
On the Partner Integrations table, find the integration you want to assign. Click the edit icon () on the right side of the row.
The **Edit Connected Managed Accounts** modal is displayed. Use the **Managed Accounts** dropdown to select one or more Managed Accounts.
Click **Save**. The integration is assigned to the selected Managed Accounts.
To assign multiple integrations at once:
On the Partner Integrations table, use the checkboxes on the left side of each row to select the integrations you want to assign. You can also use the checkbox in the table header to select all visible integrations.
A toolbar is displayed at the top of the table showing the number of selected integrations. Click **Edit Connected Managed Accounts**.
The **Edit Connected Managed Accounts** modal is displayed. Use the **Managed Accounts** dropdown to select one or more Managed Accounts.
Click **Save**. All selected integrations are assigned to the selected Managed Accounts.
### Remove Integrations from Managed Accounts
To remove an integration from a Managed Account, follow the same steps as [assigning an integration](/partners#assign-integrations-to-managed-accounts). In the **Edit Connected Managed Accounts** modal, click the **X** on any Managed Account badge to remove it. Click **Save** to apply the changes.
Use the **Managed Accounts** filter with the **None** option selected to quickly identify integrations that have not been assigned to any Managed Account. This is useful for ensuring all of your costs are accounted for across your customer base.
### Audit Log for Integration Delegations
All additions and removals of integration assignments to Managed Accounts are logged in the [Audit Log](/audit_logs) of the Management Account. Each audit log entry shows the integration that was modified, which Managed Accounts were added or removed, and the current list of connected Managed Accounts. You can filter audit logs by the **Integration Delegations** object type to view only delegation-related events.
## Create Resources in a Managed Account
When you are logged in to a customer’s Managed Account, you can create Vantage resources, like Cost Reports, Virtual Tags, etc. For any resources, such as a Cost Report, that a Management Account user creates in a customer’s account, the **Created By** field displays the name **Manager User**.
## Billing Rules
Custom billing rules can be created in the Management Account and optionally applied to any of your customers’ Managed Accounts. The following billing rules are available:
* **Exclusion:** Exclusion of specific line items (such as EDP discounts)
* **Credits and Charges:** Additional charges or credits (such as one-time management fees)
* **Adjustment:** Four options are available:
* **Per Service Adjustment:** Re-rating of existing services or categories (such as Amazon CloudFront data transfer charges).
* **Re-Rate to Public Price:** Remove AWS discounts and private pricing for a Managed Account (further described in the [section below](/partners#re-rate-to-public-pricing-adjustment))
* **Remove SP/RI Discounts:** Re-rate any usage for a Managed Account that is covered by AWS Reserved Instances or Savings Plans purchased in the AWS Payer account (further described in the [section below](/partners#remove-spri-discounts-adjustment))
* **Re-Rate Tiered Discounts:** Recalculate AWS tiered pricing models for applicable services for a Managed Account (further described in the [section below](/partners#re-rate-tiered-discounts)).
* **Custom**: Custom Billing Rules allow you to craft your own billing rule using SQL based on logic you choose. This can be logic against any data within Vantage, or additionally any logic from the raw billing files from providers. At this time, only AWS is supported for applying logic to raw billing files. Further information is available in the [section below](/partners#custom-billing-rules).
### Re-Rate to Public Pricing Adjustment
At this time, this billing rule only supports AWS costs.
MSPs are often able to negotiate substantially higher Enterprise Discount Plans (EDPs) or Private Pricing Agreements (PPAs) from cloud providers based on the aggregate amount of usage across all of their customer base than what those customers would get if they were to purchase directly from a cloud provider. With the ability to re-rate to public pricing, you can revert your customers’ pricing back to list price, removing any enterprise discounts or private pricing.
When you apply the Re-rating to Public Pricing Billing rule adjustment, Vantage will re-map costs from `lineItem/UnblendedCost` to `pricing/publicOnDemandCost` from the AWS Cost and Usage Report. As a result, the following will apply in Vantage:
* **When you view your parent Management Account**, you will still see the price billed by AWS reflected, and the billing rule will not be applied. This enables margin analysis and understanding of where these commitments are applied.
* **When you view a customer’s Managed Account**, usage of services that are included in the billing rule will be presented at list price, with no indication that any price change was made on that usage.
### Remove SP/RI Discounts Adjustment
At this time, this billing rule only supports AWS costs.
With discount toggling, you can decide which Reserved Instance and Savings Plan benefits your end customers receive. Use this adjustment billing rule to select whether any of your customer accounts receive discounts from commitments purchased in an AWS Payer account, or if such commitment covered usage should be reset back to list price. Any usage that is covered by a commitment purchased in an AWS Payer account will be reset to list price when you view usage in the customer’s Managed Account. This billing rule applies to any `SavingsPlanCoveredUsage` and `DiscountedUsage` usage types.
**Example Use Case**
You manage 20 customer AWS accounts and buy Savings Plans centrally. You want any of your customers to see only their own discounts. You set up and apply the **Remove SP/RI Discounts** adjustment to your customers’ Managed Accounts, ensuring any centrally purchased Savings Plans are excluded from customer billing.
* After the rule is applied, you will still see the cost that is billed by AWS in your parent Management Account to enable margin comparisons for end customers. In the visual example below, Savings Plan Covered Spend is still visible at the parent account level.
* Vantage looks up the account that purchased the Committed Spend Discount, if that account is an AWS Payer account, Vantage removes the discount on any Cost and Usage line item from any customers’ Managed Accounts where the adjustment is enabled. The below visual example shows a customer’s Managed Account. When grouped by Charge Type, only the Usage and Tax charges are shown. The Usage amount of \$388.61 reflects the total list price of the usage, calculated by adding the parent account’s original Usage (\$173.14) and the Savings Plan Covered Spend (\$215.47) that would have otherwise reduced the cost.
### Re-Rate Tiered Discounts
At this time, this billing rule only supports AWS costs.
MSPs often benefit from tiered pricing models offered by cloud providers, where unit costs decrease as usage increases. Since MSPs manage multiple customers, they can aggregate usage across all accounts to achieve lower pricing tiers that individual customers would not qualify for on their own. The **Re-Rate Tiered Discounts** billing rule allows you to re-rate customer usage back to what it would have cost without aggregated discounts to maintain more predictable pricing structures and margins.
With the **Re-Rate Tiered Discounts** Billing Rule adjustment, MSPs can ensure that each customer’s costs reflect only their own usage-based tiered pricing, rather than benefiting from the MSP’s aggregated tiered discounts. This allows MSPs to align customer pricing with what they would have paid if purchasing directly from the cloud provider. Additionally, MSPs can remove AWS free-tier benefits from newly created accounts.
When you apply the adjustment, Vantage will re-calculate pricing tiers, on a per-customer level, and effectively reconstruct the pricing model based on each customer’s individual usage. Usage of a tiered service is recalculated for each customer’s Managed Account, and tiers are reapplied based on each customer’s usage. As a result, the following will apply in Vantage:
* **When you view your parent Management Account**, you will continue to see the original price billed by AWS, and the billing rule will not be applied. This enables margin analysis and helps MSPs track where discounts and commitments are applied.
* **When you view a customer’s Managed Account**, usage of services included in the billing rule will be presented at list price, with no indication that any adjustments were made on that usage.
This rule applies to the following services:
| | |
| - | - |
| **Removal of tiered discounts** | • Amazon S3 • Amazon CloudFront |
| **Removal of free tier** | Various services that fall under AWS's free tier, such as: • EC2 (t2.micro and t3.micro) • RDS (750 hrs per month) • S3 (5 GB per month)
For a full list of services, see the [AWS documentation](https://aws.amazon.com/free/?gclid=Cj0KCQiA_NC9BhCkARIsABSnSTZ0_36nI3dLY14YSvLLWTz5Bigmycp0_8D-2t1HSqHi7ZxSUVWjCBIaArLSEALw_wcB\&trk=578b2801-ffbb-4021-a1db-01a0bafb3a4a\&sc_channel=ps\&ef_id=Cj0KCQiA_NC9BhCkARIsABSnSTZ0_36nI3dLY14YSvLLWTz5Bigmycp0_8D-2t1HSqHi7ZxSUVWjCBIaArLSEALw_wcB:G:s\&s_kwcid=AL!4422!3!507162072479!p!!g!!aws!12563449882!121199905124\&all-free-tier.sort-by=item.additionalFields.SortRank\&all-free-tier.sort-order=asc\&awsf.Free%20Tier%20Types=*all\&awsf.Free%20Tier%20Categories=*all). |
### Custom Billing Rules
Custom Billing Rules let you modify cost data using SQL statements. You can apply various pricing adjustments like markups, discounts, one-time fees, credits, or exclusions to either raw provider data or processed Vantage data. For example, you can add charges for premium services, adjust costs to match negotiated rates, or remove unused resources from billing—all based on your customer agreements.
For comprehensive documentation on SQL billing rules, including detailed examples, best practices, and troubleshooting, see the dedicated [SQL Billing Rules](/sql_billing_rules) page.
### Create Billing Rules
Billing rules are evaluated in a fixed pipeline of execution stages. Within a stage, rules run in the order they are listed on a Managed Account's **Billing Rules** tab, where you can reorder them. See [Billing Rule Execution Order](#billing-rule-execution-order) for details.
On each billing rule detail page, the **Managed Accounts** section shows which Managed Accounts currently use the rule. Use this section to audit where a rule is applied before editing or deleting it.
To add new billing rules:
Log in to your Vantage for MSPs Management Account.
From the top navigation, click **Settings**.
From the left navigation, under **Partner Settings**, select **Billing Rules**.
All your existing billing rules are displayed. Click **New Billing Rule**, then select **Adjustment**, **Charge**, **Credit**, **Custom**, or **Exclusion**. Click the tabs below for instructions on each billing rule type.
With adjustments, you can select between four different re-rating options.
Enter a rule **Title**, such as *CloudFront Re-rating*.
Optionally, enter a **Start Date** and/or **End Date** to define when the billing rule should be active.
* If only a start date is set, the rule applies from that date onward, indefinitely.
* If only an end date is set, the rule applies from the beginning of your data up to that date.
Select an **Adjustment Type**:
* If you select **Per-Service Adjustment**:
* Select a **Service**, such as *Amazon CloudFront*.
* Optionally, enter a **Category**, such as *Data Transfer*.
> **Tip:** To see Category names, navigate to the Cost Reports screen and create a new Cost Report. Above the graph, expand the Group By menu and select **Category**. A list of existing category options is displayed.
* Enter a percentage value that will be shown to the customer. For example, if you enter *75.0*, then 75% of Amazon CloudFront Data Transfer costs will be shown to the customer. You can enter percentage values greater than 100% to apply markups and premium pricing scenarios where costs are shown to customers at rates above the original cost.
* Click **Save**.
* If you select **Remove RI/SP Discounts**:
* No other fields are displayed. Click **Save**.
* If you select **Re-Rate to Public Price**:
* No other fields are displayed. Click **Save**.
* If you select **Re-Rate Tiered Discounts**:
* Click the toggle to select whether to include **Free tier** costs when re-rating.
* Click **Save**.
Enter a rule **Title**, such as *CloudFront Re-rating*.
Select a **Service**, such as *Amazon CloudFront*.
Optionally, enter a **Category** or **Sub category**, such as *MSP Fee*.
Enter a positive number for the credit or charge.
Enter a rule **Title**, such as *9.5% discount unless Credit, Fee, Enterprise Support or Marketplace Purchase*.
Enter a **Start Date** and **End Date**.
Enter the SQL for the rule you are creating. For guidance on creating rules, see the [SQL Billing Rule Structure](/sql_billing_rules) documentation. Use the **Format** button above the editor to auto-format your SQL and the **Validate** button to check for syntax errors, schema mismatches, and common issues before saving.
Enter a rule **Title**, such as *Exclude RI Fees*.
Enter a **Charge Type**, such as *RIFee* or *DistributorDiscount*.
To see Charge Type names, navigate to the Cost Reports screen and create a new Cost Report. Above the graph, expand the Group By menu and select **Charge Type**. A list of existing charge type options is displayed.
*You can also select whether to automatically apply the new billing rule to all existing and new Managed Accounts from this modal.*
### Assign Billing Rules to a Managed Account
You can select which rules you want added to Managed Accounts.
From the **Managed Accounts** screen, select any of your listed Managed Accounts.
Select the **Billing Rules** tab.
Click **Assign a Billing Rule**.
Select one or more billing rules and click **Save**. The billing rule is applied to the customer's costs. A customer will only be able to see credits and charges. Exclusions and adjustments are not shown in the customer view.
After billing rules are applied to a Managed Account, re-processing of the data begins immediately. The time required depends on the scale of the data in the account and can take several hours to complete. Vantage processes the most recent data first, so the latest results are typically available before a full reprocessing finishes.
To delete a billing rule from being used on a Managed Account, from the **Billing Rules** tab, click the trashcan icon next to the rule's name.
When you remove a billing rule from one Managed Account, Vantage reprocesses that account's affected cost periods. When you delete a billing rule entirely, Vantage reprocesses the affected cost periods for every Managed Account the rule was assigned to. This removes the rule's effects from past periods within its configured date range. As with assignment, reprocessing is enqueued immediately and can take several hours depending on the amount of data.
### Billing Rule Execution Order
A Managed Account's assigned billing rules run as a fixed pipeline of execution stages. Rules are grouped by stage on the **Billing Rules** tab, and the stages always run in the order below. Within a stage, rules run top to bottom in the order they are listed, and you can [reorder them](#reorder-billing-rules-for-a-managed-account). This applies to every billing rule type (i.e., Adjustments, Charges, Credits, Exclusions, and Custom (SQL) rules).
| Stage | Rules | What runs |
| - | - | - |
| 1 | **AWS schema transform rules** | Rules written against the `aws` schema. They transform AWS-schema line items, including removing them. |
| 2 | **COST schema insert rules** | Charges, credits, and other `costs`-schema INSERT rules. These run before `costs` transforms so later transform rules can act on the inserted line items. |
| 3 | **COST schema transform rules** | Adjustments, exclusions, and other `costs`-schema rules that transform line items, including removing them. |
| 4 | **Monthly Insert rules** | Aggregate `costs`-schema INSERT rules, such as SQL rules that use `SUM()` to calculate a monthly management fee from the transformed cost set. |
Billing rules run before [Virtual Tags](/tagging). Virtual Tags are evaluated on the cost data that billing rules have already produced.
#### Why Order Matters
Billing rules are applied sequentially: within a stage, each rule operates on the cost data produced by the rule before it, not on the original data. The stages also feed into one another from top to bottom. Because of this, rules compound, and the order in which they run can change the final result.
This is most important when rules overlap (i.e., when a single cost line item matches more than one rule). For example, if one rule targets the Compute category and another targets the `us-east-1` region, a Compute line item in `us-east-1` is modified by both rules, in the order they are listed. It is easy to author a rule while thinking about it in isolation, but the saved result is the cumulative effect of every rule that matches a given line item.
Whether order changes the outcome depends on the operations involved:
* **Order-independent:** Stacking percentage adjustments on the same line item produces the same result regardless of order. A 10% discount followed by a 5% markup on a \$100 line item yields \$94.05, and so does the reverse (`100 × 0.90 × 1.05 = 100 × 1.05 × 0.90`).
* **Order-dependent:** Mixing a percentage adjustment with a fixed amount or an exclusion is *not* order-independent. Consider Rule A, which sets a line item to \$100, and Rule B, which applies a 90% rate:
* **A then B:** `$100 → $90`
* **B then A:** `(amount × 0.90) → $100`
The two orders produce different results, so the position of each rule matters.
* **Monthly Insert rules:** Aggregate SQL rules run after the transform stages, so they calculate from the monthly cost set produced by earlier rules. For example, if a stage 3 rule removes AWS Marketplace costs, a later Monthly Insert rule that charges 10% of AWS spend calculates the fee after those Marketplace rows have been removed. If a stage 3 rule applies a markup first, the Monthly Insert rule calculates from the marked-up amount.
As a rule of thumb, place broad, foundational adjustments earlier in a stage and narrower corrections later, then reorder to control which rule "wins" on overlapping line items. Always re-check totals after reprocessing completes.
#### Reorder Billing Rules for a Managed Account
You can change the order of rules within a stage. You cannot move a rule across stages. Each rule's stage is determined by its type and schema, and Vantage always re-buckets rules into the canonical stage order when you save.
From the **Managed Accounts** screen, select a Managed Account and open the **Billing Rules** tab.
Click **Reorder**.
Within a stage, use the up and down arrows next to a rule to move it. Rules can only be reordered relative to other rules in the same stage.
Click **Done Reordering** to save the new order.
The **Reorder** button only appears when at least one stage has two or more assigned rules. A single rule (or one rule per stage) has nothing to reorder.
Saving a new order re-triggers reprocessing of the Managed Account's data, just like assigning a rule. Reprocessing can take several hours depending on the size of the account.
## Remove a Managed Account
You can either *unlink* or *delete* a customer’s account. MSP customers cannot delete accounts.
If you are a customer with a Managed Account and want your account deleted, contact your MSP.
* If you want to only *unlink* an account, but not delete the account, contact [support@vantage.sh](mailto:support@vantage.sh). The account will still exist in Vantage.
* When an account is completely deleted, the account is unlinked from the MSP and also completely deleted from Vantage. To delete a customer's Managed Account, click the trash can icon next to the account name on the **Managed Accounts** screen.
Deleting a customer's account is a **permanent action** and will remove any connected customer integrations.
## Customers: Getting Started with Vantage
As you onboard your customers to Vantage, the following resources are available to help customers get started with Vantage features.
Information on how to get started with each Vantage provider integration and the cost reporting data that's collected
A suite of training videos and guides to introduce basic Vantage concepts and features
Create your first Cost Report on Vantage
# Provider Data Refresh
Source: https://docs.vantage.sh/provider_data_refresh
Understand Vantage's data refresh schedules.
For most provider integrations, Vantage refreshes data once every 24 hours. Some providers may have different data refresh schedules, which are listed here.
| Provider | Refresh Time |
| - | - |
| [AWS](/connecting_aws) | Updates every 8–12 hours depending on the account. |
| [Anthropic](/connecting_anthropic) | Refreshes once daily. Covers both the Claude API and Claude.ai (Claude Enterprise Analytics API) data sources. |
| [Anyscale](/connecting_anyscale) | Refreshes once daily. |
| [Azure](/connecting_azure) | Includes all Azure billing account types (i.e., EA, MCA, CSP, and Pay as You Go). Refreshes once daily. |
| [Baseten](/connecting_baseten) | Refreshes once daily. |
| [Cartesia](/connecting_cartesia) | Refreshes once daily. |
| [CircleCI](/connecting_circle_ci) | Refreshes once daily. |
| [Cloudflare](/connecting_cloudflare) | Refreshes once daily. |
| [Cursor](/connecting_cursor) | Refreshes once daily. |
| [DigitalOcean](/connecting_digitalocean) | Refreshes once daily. Because Vantage reads daily billing insights, in-month costs update daily and may differ from the finalized month-end invoice. |
| [Google Cloud](/connecting_gcp) | Refreshes once daily. |
| [Kubernetes](/connecting_kubernetes) | Refreshes once daily. |
| [Datadog](/connecting_datadog) | Refreshes once daily. |
| [New Relic](/connecting_new_relic) | Refreshes once daily. |
| [MongoDB Atlas](/connecting_mongodb-atlas) | Refreshes once daily. |
| [Modal](/connecting_modal) | Refreshes once daily. |
| [Snowflake](/connecting_snowflake) | Refreshes once daily. |
| [Databricks](/connecting_databricks) | Refreshes once daily. |
| [Elastic](/connecting_elastic) | Refreshes once daily. |
| [ElevenLabs](/connecting_elevenlabs) | Refreshes once daily. |
| [Fastly](/connecting_fastly) | Refreshes once daily. |
| [Fireworks AI](/connecting_fireworks_ai) | Refreshes once daily. |
| [Oracle](/connecting_oracle) | Refreshes once daily. |
| [Confluent](/connecting_confluent) | Refreshes once daily. |
| [PlanetScale](/connecting_planetscale) | Refreshes once daily. |
| [Redis](/connecting_redis) | Refreshes once daily. |
| [Coralogix](/connecting_coralogix) | Refreshes once daily. |
| [GitHub](/connecting_github) | Refreshes once daily. |
| [Linode](/connecting_linode) | Refreshes once daily; however, new data is available only after a new invoice has been generated by Akamai, which is typically monthly. When using the Vantage Kubernetes Agent, estimated costs will be based on real-time usage and updated daily in Vantage. |
| [OpenAI](/connecting_openai) | Both OpenAI Platform and OpenAI Codex data refresh once daily. |
| [Grafana Cloud](/connecting_grafana) | Grafana Cloud data refreshes daily in the console; however, due to Grafana’s billing process, billing data for the current month becomes available only on the 1st of the following month. |
| [ClickHouse Cloud](/connecting_clickhouse) | Refreshes once daily. |
| [Temporal Cloud](/connecting_temporal) | Refreshes once daily. |
| [Twilio](/connecting_twilio) | Refreshes once daily. |
| [Vercel](/connecting_vercel) | Refreshes once daily. |
| [SpaceXAI](/connecting_spacexai) | Refreshes once daily. |
| [Custom Providers](/connecting_custom_providers) | Refreshes when you manually add new data. |
## Two-Day Cost Data Delay
By default, Vantage applies a two-day delay to the cost data shown across the console. Cost Reports, [report notifications](/report_notifications), forecasts, and recommendation lookbacks clip their end date to two days before the current date (for example, on July 21 the most recent day shown is July 19).
This delay is applied to every account by default. It exists because cloud providers and SaaS vendors deliver billing data with a lag, and the most recent one to two days of data is often still landing and incomplete. Clipping the end date prevents partial data from being displayed as if it were final, which would otherwise cause the most recent days to appear artificially low and change as more data arrives.
The two-day delay is separate from each provider's refresh cadence listed above. Even after a provider refreshes, its two most recent days are held back from the console view for completeness.
### Removing the Delay
The two-day delay is a Vantage-managed account setting rather than a self-service option in the console. If you want to see the most recent days as soon as data lands, contact [support@vantage.sh](mailto:support@vantage.sh) and request that the cost data delay be removed from your account.
Removing the delay surfaces the most recent one to two days sooner, but those days may be incomplete and their totals will change as the remaining provider data lands. This is the trade-off the delay is designed to avoid.
# Role-Based Access Control (RBAC)
Source: https://docs.vantage.sh/rbac
Implement fine-grained access control with Vantage RBAC.
Advanced role-based access controls are available only for Enterprise tier accounts.
## Understanding RBAC Roles
Vantage uses two kinds of roles:
Roles that apply to a user once per organization and control organization-wide actions (such as who can invite users, manage billing, or access settings).
| Role | Description |
| - | - |
| Organization Owner | Full access to all items. Can also manage teams, integrations, and workspaces. |
| Integration Owner | All Organization Editor privileges, plus the ability to manage [provider integrations](/getting_started), [Virtual Tags](/tagging), [Custom Providers](/connecting_custom_providers), and [Business Metrics](/business_metrics) via **Settings**. Does *not* have access to other administrative settings (e.g., teams, billing). Only an Organization Owner can grant this role. |
| Organization Editor | Can create and edit Cost Reporting items, but cannot manage teams or integrations. |
| Organization Viewer | Read-only access to Cost Reporting items. |
**MCP Connectors are an exception to integration access.** [MCP Connectors](/vantage_finops_agent#mcp-connectors) for the FinOps Agent are enabled for the organization by an Organization Owner or Integration Owner. The user-authorized connectors (GitHub, Linear, Notion) then require each user to connect their own account. So once one is enabled, **Organization Editors and Organization Viewers can open Settings > Integrations**, where they see only the **MCP Connectors** section (not other integrations). See the [FinOps Agent](/vantage_finops_agent#how-connectors-are-enabled) documentation for details.
Roles that apply per team and control what a user can do with the Cost Reporting items that each team can access (such as Cost Reports or Dashboards). Every user has one organization-level role and, for each team they belong to, one team-level role.
| Role | Description |
| - | - |
| Team Owner | Full control over Cost Reporting items to which that team is granted access. Team Owners can manage access and members for their team. |
| Team Editor | Full control over Cost Reporting items to which that team is granted access; however, they cannot manage team members. |
| Team Viewer | Read-only access to all Cost Reporting items to which that team is granted access. |
## How Team Roles Work
### Understand Teams
A Vantage account contains one or more [**workspaces**](/workspaces), each with its own set of Cost Reporting items (Cost Reports, Dashboards, Folders, etc.). Each workspace also has [provider integrations assigned to it](/workspaces#manage-workspace-provider-integrations), which determine what underlying cost data is available in that workspace. **Teams** control which users can access which workspaces, and by extension, which cost data and Cost Reporting items they can see.
```mermaid theme={null}
flowchart TD
VA[Vantage Account] --- g1 & g2 & g3
subgraph g1[" "]
direction LR
T1[Team A] -->|access| W1[Workspace A]
I1[Provider Integrations] -.->|cost data| W1
end
subgraph g2[" "]
direction LR
T2[Team B] -->|access| W2[Workspace B]
I2[Provider Integrations] -.->|cost data| W2
end
subgraph g3[" "]
direction LR
T3[Team C] -->|access| W3[Workspace C]
I3[Provider Integrations] -.->|cost data| W3
end
W1 -->|contains| R1[Cost Reporting Items Reports, Dashboards, etc.]
W2 -->|contains| R2[Cost Reporting Items Reports, Dashboards, etc.]
W3 -->|contains| R3[Cost Reporting Items Reports, Dashboards, etc.]
style VA fill:#6742D6,color:#fff
style g1 fill:none,stroke:#6742D6
style g2 fill:none,stroke:#6742D6
style g3 fill:none,stroke:#6742D6
style W1 fill:#f5f5f5,stroke:#6742D6
style W2 fill:#f5f5f5,stroke:#6742D6
style W3 fill:#f5f5f5,stroke:#6742D6
style T1 fill:#fff,stroke:#6742D6
style T2 fill:#fff,stroke:#6742D6
style T3 fill:#fff,stroke:#6742D6
style I1 fill:#fff,stroke:#999,stroke-dasharray: 5 5
style I2 fill:#fff,stroke:#999,stroke-dasharray: 5 5
style I3 fill:#fff,stroke:#999,stroke-dasharray: 5 5
style R1 fill:#f5f5f5,stroke:#999
style R2 fill:#f5f5f5,stroke:#999
style R3 fill:#f5f5f5,stroke:#999
```
### Understand the Everyone Team
Every account starts with a default team called the **Everyone** team. All users are automatically members of this team and cannot be removed from it. A user's role in the Everyone team mirrors their organization-level role (e.g., an Organization Editor becomes a Team Editor on the Everyone team).
By default, the Everyone team has access to all workspaces, so every user can see everything. This works well for small organizations, but as your account grows you may need to restrict visibility, for example, ensuring that only the Finance department can see cost data in the Finance workspace. Additional teams let you control which users can see or edit items in each workspace, and optionally share individual items across team boundaries.
```mermaid theme={null}
flowchart TD
T2[Marketing Team] -->|Can Edit| W1[Marketing Workspace]
T1[Everyone Team] -.->|Can View| W1
T1 -.->|Can View| W2[Engineering Workspace]
T3[Engineering Team] -->|Can Edit| W2
style W1 fill:#f5f5f5,stroke:#6742D6
style W2 fill:#f5f5f5,stroke:#6742D6
style T1 fill:#fff,stroke:#999
style T2 fill:#fff,stroke:#6742D6
style T3 fill:#fff,stroke:#6742D6
```
In this example, the Everyone team has **Can View** access to both workspaces, so all users can see items in both. But only members of the Marketing team can create and edit items in the Marketing workspace, and only members of the Engineering team can create and edit items in the Engineering workspace.
Organization Owners are the exception—they always have full access to all workspaces and Cost Reporting items regardless of team membership.
### Role Precedence
A user's effective permission on a Cost Reporting item is determined by two criteria:
1. **Workspace access**: At least one of the user's teams (including the Everyone team) must have the appropriate access level (**Can Edit** or **Can View**) to the workspace.
2. **Team role**: The user must have an appropriate role (Team Owner, Team Editor, or Team Viewer) in that team.
If the user is on multiple teams with access to the same item, Vantage checks each team independently. If **any** team satisfies both conditions, access is granted, effectively giving the user the highest permission available across all their teams.
Meagan is an **Organization Editor**, which makes her a **Team Editor** on the Everyone team. She is also added to the Marketing team as a **Team Viewer**. Both teams have **Can Edit** access to the workspace.
**Result**: Meagan can edit items. Even though she is a Team Viewer on the Marketing team, Vantage checks each team independently. The Everyone team gives her Team Editor-level access, so she can edit.
Matt is an **Organization Viewer**, which makes him a **Team Viewer** on the Everyone team. He is also added to the Engineering team as a **Team Owner**. Both teams have **Can Edit** access to the workspace.
**Result**: Matt can fully manage items on the Engineering team. His Team Owner role on the Engineering team satisfies both conditions (the team has Can Edit access and he has a Team Owner role), so he gets full control, even though his Everyone team role is only Team Viewer.
Rajan is a **Team Editor** on the Marketing team, but the Marketing team only has **Can View** access to the workspace. Rajan is also a **Team Viewer** on the Everyone team, which has **Can Edit** access.
**Result**: Rajan can only view items. Through the Marketing team, the **Can View** workspace access prevents editing, regardless of his Team Editor role on that team. Through the Everyone team, he has **Can Edit** workspace access, but his Team Viewer role only allows viewing. Neither team satisfies both conditions for editing.
Tara is on the Marketing team as a **Team Owner** and on the Engineering team as a **Team Viewer**. Both teams have access to the same Saved Filter.
**Result**: Tara gets Team Owner-level access. Vantage checks each team independently, and the Marketing team gives her Team Owner permissions, so she can edit the Saved Filter and manage which teams can access it.
## Manage Account Access
Only Organization Owners can invite or remove users and change another user's organization-level role. Navigate to **Settings > People** to manage users.
1. Click **Invite People**.
2. Enter the new user's email, select their organization-level **Role**, and optionally assign them to **Teams**.
3. Click **Send Invitation**.
If you assign the user to a team during invite, ensure that at least one of their teams has **Can View** or **Can Edit** access to a workspace. Users without workspace access may see an error when accepting an invitation or when they first sign in.
1. Hover over the user's row, then click the ellipsis (**...**).
2. Click **Edit**, then select the new **Role**.
3. Click **Save Changes**.
Organization Owners cannot change their own role. Another Organization Owner must make the change.
## Manage Teams
### Create or Delete Teams
Only Organization Owners can create new teams. Organization Owners and Team Owners can delete teams (except the default Everyone team). By default, you will be made the Team Owner of any new team you create. You can invite and manage members once this team has been created.
Navigate to **Settings > Teams**:
* To create a team, click **Create a Team**, add a **Name** and **Description**, then click **Create Team**.
* To delete a team, hover over the team name and click the trashcan icon.
### Map Team to SSO Groups (Organization Owners Only)
Organization Owners can map SSO groups to teams within Vantage. Teams must be created first, then follow the [Set Up SSO Group Mapping for Teams](/sso#set-up-sso-group-mapping-for-teams) instructions.
### Manage Team Members and Access
To manage a team, select it from the **Teams** list. Organization Owners and Team Owners can perform the actions below.
Four tabs are available:
* **General**—Edit the team name, description, and set a default [dashboard](/dashboards#set-a-default-dashboard). The default dashboard option is not available for the Everyone team.
If you set a default dashboard, members who belong to other teams with default dashboards or with a personal default dashboard already configured, may be directed to those dashboards instead.
* **Members**—Add or remove members and change their team-level role.
* **Access**—Set workspace access levels and view Cost Reporting items with granted access.
* **API Access Tokens**—Create [API service tokens](/api/authentication#create-a-vantage-api-service-token) that inherit the team's permissions.
Service tokens used for organization-level actions—such as managing provider integrations or creating teams—must be assigned to the **Everyone** team. This includes tokens used by the [Kubernetes agent](/kubernetes_agent) and the [Terraform provider](/terraform). Tokens assigned to other teams will not have the necessary permissions for these operations.
1. On the **Members** tab, click **Add Members**.
2. Select member(s) from the list.
3. Click **Add People**.
1. On the **Members** tab, hover over the user's name.
2. Click **Remove**. (Note that you cannot remove yourself from a team and will need another Organization Owner or Team Owner to take this action.)
1. On the **Members** tab, click the **Role** dropdown next to the member.
2. Select a new role.
1. On the **Access** tab, click the dropdown next to the workspace name.
2. Select **Can Edit**, **Can View**, or **No Access**.
1. On the **Access** tab, under **Granted Access**, click an item to navigate to it. Items are organized by associated workspace.
2. From the item, you can edit or remove the access grant.
## Manage Access for Specific Cost Reporting Items
By default, a team's access to Cost Reporting items is determined by its workspace access level. If a team has **Can Edit** or **Can View** access to a workspace, its members can see all items in that workspace. However, Organization Owners and Team Owners can override this behavior for individual items using **direct item grants**. Direct item grants let you:
* **Share a specific item with a team that doesn't have access to the workspace it lives in.** For example, an Organization Owner can share an executive dashboard from the Finance workspace with the Engineering team, without giving Engineering access to everything in Finance.
* **Block a team from a specific item**, even if the team has access to the workspace. For example, a Team Owner on the Finance team can prevent the Everyone team from seeing a sensitive Cost Report, while still allowing the Finance team to access it.
Organization Owners always have full access to all Cost Reporting items, regardless of direct item grants. A **Cannot Access** grant does not block Organization Owners.
Direct item grants apply to Cost Reports, Dashboards, Folders, Saved Filters, Resource Reports, Kubernetes Efficiency Reports, and Financial Commitment Reports.
### Set Direct Item Grants
Organization Owners and Team Owners (on teams with **Can Edit** workspace access) can manage direct item grants.
1. Navigate to **Reporting** and select the item category (e.g., Cost Reports, Dashboards). For Resource Reports, click **Active Resources > Resource Reports**.
2. Hover over the item, click the ellipsis (**...**), and select **Manage Access**.
3. For each team, set the access level:
* **Can Access**—The team can see (and, depending on their role, edit) the item, even if the team doesn't have workspace access.
* **Cannot Access**—The team is explicitly blocked from the item, even if the team has workspace access.
* **Reset Access**—Removes the direct grant, so the team's access is determined by its workspace access level. If the team has no workspace access, they lose access to the item.
1. Open the item (e.g., a Cost Report or dashboard).
2. Click the ellipsis (**...**) at the top, then select **Manage Access**.
3. Set the desired access for each team, then click **Save**.
To restrict an item to a single team, set the Everyone team to **Cannot Access** and the target team to **Can Access**.
### Cross-Workspace Item Grants
When a team is granted direct access to an item in a workspace they don't otherwise have access to, team members can view that specific item, but they **cannot** browse other items in the workspace. Only items with an explicit grant are visible.
When a user opens a shared item in another workspace, Vantage temporarily switches them into that workspace for up to **24 hours**. During this time, a yellow banner appears at the top of the console indicating they are temporarily in the workspace. After 24 hours, the temporary access expires and the user is returned to their default workspace on the next page load. They can re-open the shared item at any time to get another temporary session.
If a team has a direct grant on a **folder**, team members can also see the items inside that folder.
## Best Practices: Setting Up RBAC
For organizations with multiple departments or business units, the recommended approach is to remove all workspace access from the Everyone team and create dedicated teams scoped to what each group needs. See the [RBAC Setup Guide](/guides/rbac_setup) for a step-by-step walkthrough with examples.
## Detailed Permissions
For a complete breakdown of what each role can do, including organization-level actions (settings, financial planning, recommendations, FinOps Agent) and team-based actions (create, edit, delete, view, and manage access for Cost Reporting items), see the [Permissions Reference](/rbac_permissions).
# Permissions Reference
Source: https://docs.vantage.sh/rbac_permissions
Detailed per-action permission tables for organization-level and team-based RBAC roles.
Advanced role-based access controls are available only for Enterprise tier accounts.
This page provides a complete reference of what each role can do across Vantage. For an overview of RBAC concepts, see [Role-Based Access Control](/rbac). For setup instructions, see the [RBAC Setup Guide](/guides/rbac_setup).
## Administration
The following actions are controlled solely by your organization-level role. Team membership and workspace access do not affect these permissions.
| Action | Org Owner | Integration Owner | Org Editor | Org Viewer |
| - | - | - | - | - |
| Invite/remove users | | | | |
| Change a user's role | | | | |
| Create/delete teams | | | | |
| Manage workspaces | | | | |
| Manage authentication/SSO | | | | |
| Manage billing and plans | | | | |
| View audit logs | | | | |
| Manage provider integrations | | | | |
| Manage custom providers | | | | |
| Enable/disable Autopilot | | | | |
| Approve Autopilot purchases | | | | |
| Manage Virtual Tags | | | | |
| Enable/configure the FinOps Agent | | | | |
| Approve FinOps Agent remediation actions | | | | |
Team Owners can manage their own team within the Teams UI, but cannot create new teams or manage other teams.
## Feature Permissions
The following permissions depend on your organization-level role **and** your team's workspace access. In the default configuration, where the Everyone team has Can Edit access to all workspaces, your organization-level role determines these permissions as shown in the tables below.
If the Everyone team does not have Can Edit access to a workspace, a user on a designated team with **Can Edit** workspace access and a **Team Editor or Team Owner** role can also create and edit these features in that workspace. Viewing requires at least **Can View** access to the workspace through any team. Organization Owners always have full access.
### Financial Planning
| Action | Org Owner | Integration Owner | Org Editor | Org Viewer |
| - | - | - | - | - |
| View Autopilot results and coverage | | | | |
| Create/edit budgets and budget alerts | | | | |
| View budgets and budget alerts | | | | |
| Create/edit business metrics | | | | |
| View business metrics | | | | |
| Create/edit/delete Scenario Models | | | | |
| View Scenario Models | | | | |
| Create issues | | | | |
| Edit issues (own or assigned) | | | | |
| View issues | | | | |
| Create/edit savings models | | | | |
| View savings models | | | | |
Any user who is assigned to an [issue](/issues) will have update permissions for that issue, regardless of their role.
### Recommendations
| Action | Org Owner | Integration Owner | Org Editor | Org Viewer |
| - | - | - | - | - |
| View recommendations | | | | |
| Archive recommendations | | | | |
### Notifications and Alerts
| Action | Org Owner | Integration Owner | Org Editor | Org Viewer |
| - | - | - | - | - |
| Create/edit cost alerts | | | | |
| View cost alerts | | | | |
| View cost anomaly alerts on accessible reports | | | | |
Report and dashboard notifications require edit access to the parent Cost Reporting item. See [Cost Reporting Items](/rbac_permissions#cost-reporting-items) below for details.
### FinOps Agent
| Action | Org Owner | Integration Owner | Org Editor | Org Viewer |
| - | - | - | - | - |
| Query the FinOps Agent | | | | |
| Enable or disable an [MCP Connector](/vantage_finops_agent#mcp-connectors) for the organization | | | | |
| Connect your own account to a user-authorized MCP Connector | | | | |
* **RBAC Enforcement**: The FinOps Agent matches your Vantage user permissions. You will only see data permitted by your role.
* **Authentication**: Your Slack email must match your Vantage email. If they don't match, contact [support@vantage.sh](mailto:support@vantage.sh).
* **Access Control**: In shared Slack channels, the FinOps Agent responds based on the identity and permissions of the user who sent the prompt.
* **MCP Connectors**: [MCP Connectors](/vantage_finops_agent#mcp-connectors) are enabled for the organization by an Organization Owner or Integration Owner. The user-authorized connectors (GitHub, Linear, Notion) then require each user to connect their own account, so once one is enabled, **Organization Editors and Organization Viewers can access Settings > Integrations**, where they see only the **MCP Connectors** section. Datadog is org-wide and managed only by roles that can manage integrations.
## Cost Reporting Items
The following permissions depend on **both** your team-level role **and** your team's workspace access level. These apply to Cost Reporting items: Cost Reports, Dashboards, Folders, Saved Filters, Resource Reports, Kubernetes Efficiency Reports, and Financial Commitment Reports.
**Organization Owners** always have full access to all Cost Reporting items, regardless of team membership. The tables below apply to non-Organization Owner roles.
### When your team has Can Edit workspace access
| Action | Team Owner | Team Editor | Team Viewer |
| - | - | - | - |
| Create items | | | |
| Edit/update items | | | |
| Delete items | | | |
| View items | | | |
| Manage report/dashboard notifications | | | |
| Manage item access | | | |
### When your team has Can View workspace access
| Action | Team Owner | Team Editor | Team Viewer |
| - | - | - | - |
| Create items | | | |
| Edit/update items | | | |
| Delete items | | | |
| View items | | | |
| Manage report/dashboard notifications | | | |
| Manage item access | | | |
If your team only has **Can View** workspace access, no team role (not even Team Owner) can create, edit, or delete items through that team. To edit items, you need to be on a team that has **Can Edit** access.
Team Viewers can still interact with Cost Reports, adjusting filters, date ranges, groupings, and other settings to explore the data. These changes are not saved and do not affect other users. Keep this in mind when assigning workspace access: any user who can view a workspace can see all cost data from the [integrations assigned to that workspace](/workspaces#manage-workspace-provider-integrations).
### When your team has a direct item grant (no workspace access)
If a team does not have workspace access but has been granted direct access to a specific Cost Reporting item:
| Action | Team Owner | Team Editor | Team Viewer |
| - | - | - | - |
| Edit/update item | | | |
| View item | | | |
| Manage report/dashboard notifications | | | |
If a user is on multiple teams with conflicting permissions, the higher level of permissions is granted. See [Role Precedence](/rbac#role-precedence) for details.
## Frequently Asked Questions
Your effective permission is based on the **highest** role from any team that has access. If you have Team Editor in the Everyone team (from your Organization Editor role) and the Everyone team has Can Edit, you can edit the item—even if your designated team only has Can View.
If the Everyone team is set to **Cannot Access** for an item, your access depends entirely on your designated team(s). If none of your other teams have access to the item, you will not be able to see it (unless you are an Organization Owner).
Only **Organization Owners** and **Team Owners** (on a team with Can Edit workspace access) can manage item access grants. Team Editors and Team Viewers cannot change access settings.
Yes. If an Organization Viewer is a Team Editor or Team Owner on a designated team with **Can Edit** workspace access, they can create and edit features like budgets, savings models, cost alerts, and issues in that workspace—even though their organization-level role is Viewer. The tables in [Feature Permissions](/rbac_permissions#feature-permissions) show the default behavior when access comes through the Everyone team.
Service tokens used for organization-level actions—such as managing provider integrations, creating teams, or managing [Virtual Tags](/tagging)—must be assigned to the **Everyone** team. This is especially important for tokens used by the [Kubernetes agent](/kubernetes_agent) and the [Terraform provider](/terraform), which need the Everyone team's permissions to manage provider integrations and Virtual Tags. Tokens assigned to other teams will not have the necessary permissions and may encounter authorization errors. See [API Service Tokens](/api/authentication#create-a-vantage-api-service-token) for details.
Assign the user the **Integration Owner** role and do not add them to any designated teams. This is useful for platform engineers or infrastructure admins whose responsibility in Vantage is managing provider integrations, Virtual Tags, Custom Providers, and Business Metrics. These users can access **Settings > Integrations**, **Settings > Tags**, **Settings > Custom Providers**, and create Business Metrics, and will still have access to items in workspaces where the Everyone team has access. To further restrict their visibility, you can remove the Everyone team's access from specific workspaces. In that case, they will see a message indicating they don't have workspace access when navigating to those workspace overviews, which is expected.
# Report Notifications
Source: https://docs.vantage.sh/report_notifications
Set up automated report notifications in Vantage for reports and dashboards via email, Slack, or Microsoft Teams with customizable delivery options.
Report Notifications provide either daily, weekly, or monthly notifications for:
* **Cost Reports:** One or more Cost Reports
* **Dashboards:** A specific [dashboard](/dashboards)
You can receive Report Notifications from the following methods:
* **Slack:** You can send a notification to one or more public or private channels in a Slack workspace (for Cost Reports only).
* **Microsoft Teams:** You can send a notification to one or more public or private channels in a Microsoft Teams account (for Cost Reports only).
* **Email:** You can send a notification to one or more email addresses (for both Cost Reports and Dashboards).
You can create either a Slack integration or a Microsoft Teams integration, but not both.
Dashboard notifications can only be sent via email. Cost Reports can be sent via email, Slack, or Microsoft Teams.
Before any notification is sent, Vantage ensures it has the most up-to-date representation of your cost data to give you an accurate report.
## Report Notifications vs. Other Alert Types
Report Notifications are scheduled digests, not alerts. They deliver a recurring snapshot of a Cost Report or dashboard regardless of whether anything is anomalous. For threshold-based and ML-based alerting, see [Cost Alerts](/cost_alerts), [Cost Anomaly Alerts](/cost_anomaly_alerts), and [Budget Alerts](/budgets#budget-alerts). The matrix below summarizes which Vantage alert types support which delivery channels; for a deeper comparison of when to use each, see [Anomaly Detection vs. Other Alert Types](/cost_anomaly_alerts#anomaly-detection-vs-other-alert-types).
| Alert Type | Email | Slack | Microsoft Teams | Jira | Configured From |
| - | :-: | :-: | :-: | :-: | - |
| [Cost Anomaly Alerts](/cost_anomaly_alerts) | Yes | Yes | Yes | Yes | A Cost Report's **Anomalies** tab > **Configure Alert** |
| [Cost Alerts](/cost_alerts) | Yes | Yes | Yes | Yes | A Cost Report's **...** menu > **Create Cost Alert**, or **Notifications** > **Cost Alerts** > **Configure Cost Alert** |
| [Budget Alerts](/budgets#budget-alerts) | Yes | Yes | Yes | Yes | A Budget's **Manage** tab > **Manage Alerts** > **Configure Alert** |
| [Report Notifications](/report_notifications) (Cost Reports) | Yes | Yes | Yes | — | The **Notifications** page > **New Notification** > **Cost Report Notification**, or a Cost Report's **...** menu > **Create Report Notification** |
| [Dashboard Notifications](/report_notifications#set-up-dashboard-notifications) | Yes | — | — | — | The **Notifications** page > **New Notification** > **Dashboard Notification** |
Slack and Microsoft Teams are mutually exclusive at the integration level: you can connect either Slack or Microsoft Teams, not both. See the [Slack](/slack) and [Microsoft Teams](/microsoft_teams) integration docs for setup. Jira delivery requires the [Jira integration](/jira).
## Set Up Slack Integration
See the [Slack](/slack) integration documentation for information on how to set up a connection. See the [Set Up Report Notifications](/report_notifications#set-up-cost-report-notifications) section for instructions on how to set up notifications for specific reports.
## Set Up Microsoft Teams Integration
See the [Microsoft Teams](/microsoft_teams) integration documentation for information on how to set up a connection. See the [Set Up Report Notifications](/report_notifications#set-up-cost-report-notifications) section for instructions on how to set up notifications for specific reports.
## Set Up Cost Report Notifications
To create Cost Report Notifications, follow the steps below. If you want to send notifications via Slack or Microsoft Teams, ensure you have set up the appropriate integration first.
If you instead want to create an email notification, the email report will contain a list of all of your views and a point-in-time cost for each view. Note that, like the rest of the console, notification data reflects the default [two-day cost data delay](/provider_data_refresh#two-day-cost-data-delay) to ensure completeness, so the most recent two days are not included.
If the Cost Report has linked budgets, the notification includes a **Budget Performance** section that compares actual spend against budget targets for the report.
Navigate to the [Notifications screen](https://console.vantage.sh/notifications/reportable_notifications).
You can also click the bell icon in the top right of the console.
Click **New Notification** in the top right corner.
Select **Report Notification**.
Enter a **Title** for the report.
If you want to send the report as an email, select the emails for any current Vantage users you want to receive the report.
**Optionally**, select if you want to include a PDF of the chart as an email attachment. PDF exports are not available for Slack or Teams notifications.
See the [Cost Report Exports](/cost_reports#export-cost-reports) docs for more information about PDF exports.
Report Notifications do not attach CSV files. To generate CSV exports on a recurring schedule or pull Cost Report data into another system, use the [Vantage API](/api) instead.
Depending on which integration you've enabled, a **Slack Channels** or **Microsoft Teams Channels** field is displayed. Select the channels you want to send the notification to. You can add as many channels as you want, and they will all receive the notification.
Select a report from the dropdown list, then select a **Frequency** (e.g., daily, weekly, or monthly).
Monthly notifications will be sent on the second of the month. Weekly notifications will be sent on Mondays.
For **Change**, select **Dollars** or **Percentage**.
Click **Save**.
You can edit the notification's settings (e.g., add or remove recipients or change which channels it's sent to) from this screen.
## Set Up Dashboard Notifications
Report Notifications can also be configured for dashboards. Dashboard notifications provide scheduled digests of a [dashboard](/dashboards) and can only be sent via email. Each notification is delivered as **one PDF** with all pages; the first page includes a link to open the dashboard in Vantage.
Navigate to the [Notifications screen](https://console.vantage.sh/notifications/reportable_notifications).
You can also click the bell icon in the top right of the console.
Click **New Notification** in the top right corner.
Select **Dashboard Notification**.
Enter a **Title** for the dashboard notification.
Select the emails for any current Vantage users you want to receive the notification.
Select a dashboard from the dropdown list.
Select a **Frequency** (e.g., daily, weekly, or monthly).
Monthly notifications will be sent on the second of the month. Weekly notifications will be sent on Mondays.
Click **Save**.
You can edit the notification's settings (e.g., add or remove recipients or change the dashboard) from this screen.
# Saved Filters
Source: https://docs.vantage.sh/saved_filters
Create reusable filter logic with Vantage Saved Filters.
Use saved filters to reuse filter logic across multiple Cost Reports. If you update the filter logic on a saved filter, all Cost Reports that use the saved filter will be automatically updated.
For example, you may have multiple Cost Reports for a specific team, business unit, or environment. If any filter criteria changes, such as tag names or account numbers, you can update the saved filter for all affected reports, without having to individually update each report.
You can also add saved filters to dashboards. See the [dashboards documentation](/dashboards) for more information.
## Create a Saved Filter
From the top navigation bar, click **Reporting**.
On the left menu, select **Saved Filters**. All existing saved filters are displayed.
Click **New Filter**.
Enter a **Filter Name**.
If you want to add a filter to a [folder](/folders), select the **Folders** tab. Then, select any applicable folders. The saved filter will be added to any existing Cost Reports within that folder, as well as any new Cost Reports you create within that folder. The saved filter will also apply to any sub-folders within that folder. For individual Cost Reports, saved filters can be assigned only from within that Cost Report. (See the next section for details.)
Under **Filters**, click **+ Add a Filter**. Select your filter criteria. You can also click **View as VQL** to [edit filter criteria as VQL](/vql#edit-vql-in-the-console) directly.
For more information about creating filters and filter options, see the [Cost Reports filter documentation](/cost_reports#filter-cost-reports).
At the top, click **Save**.
### Make a Copy of an Existing Saved Filter
You can also create a copy of any existing saved filter to use when creating a new saved filter.
At the top of any saved filter, click the **Duplicate** icon (to the left of **Save**). This action will replicate the filter logic but not the associated reports.
## Add Saved Filter to a Cost Report
Open any Cost Report.
At the top, click **Filters**.
Click **Saved Filters**. A list of existing saved filters is displayed.
Select a saved filter to add it to the Cost Report. You can select multiple saved filters. You can also add additional ad-hoc filter criteria as a separate filter set.
At the top, click **Save**.
When you combine multiple saved filters on Cost Reports that have the same provider (AWS, Azure, etc.) as an ad-hoc filter or another saved filter, "AND" logic is used between each filter set (i.e., costs where Saved Filter 1 *AND* Saved Filter 2 are true).
### Saved Filters within Folders
If a saved filter is applied to a folder, you will be unable to remove it from the individual Cost Reports within that folder.
To remove the saved filter from a folder, navigate to the [Saved Filters](https://console.vantage.sh/saved_filters) page.
Then, click the ellipses (**...**) next to the saved filter and click **Edit**.
Remove the folder from the **Folders** list and click **Save**.
# Savings Planner
Source: https://docs.vantage.sh/savings_planner
Plan and forecast AWS Savings Plans with Vantage's Savings Planner tool.
Savings Planner is a planning and forecasting tool you can use to view and model [AWS Savings Plans](https://www.vantage.sh/blog/what-is-an-aws-savings-plan) and maximize cost savings. Savings Planner provides a view into your on-demand vs. committed spend. You can create models and see the future impact of committing to additional Savings Plans. Vantage automatically detects all existing AWS Savings Plans within your account. Historical cost data and forecasted on-demand usage values for the next 12 months are displayed.
At this time, Savings Planner is available only for AWS.
If you use Azure under a Standard Azure, Azure MCA, or Azure EA agreement (not Azure CSP), you can sync Azure Reservations and Azure Savings Plans to the [Commitments](/commitments) page by following the [Optional Azure Reservations and Savings Plans](/connecting_azure#optional-azure-reservations-and-savings-plans) steps.
## Requirements
For all aspects of Savings Planner to work, you need an **AWS integration** with **Cost Explorer** and **Savings Plans** access (so Vantage can read your commitments and coverage) and **Cost and Usage Reports (CUR)** enabled (so Vantage can calculate your savings rates and run the forecasts described below). The feature becomes available once coverage has been synced from AWS and your first CUR data has been imported and processed.
If you see **"Data is Processing"**, Vantage is still waiting for coverage and/or CUR to be ready. Ensure [CUR is set up](/connecting_aws#create-a-connection) and that at least one billing period has been delivered to the S3 bucket Vantage reads from; for backfilling past months, see [Backfilling AWS CUR for previous reporting periods](/connecting_aws#backfilling-aws-cur-for-previous-reporting-periods).
## Savings Planner Calculations
Vantage has ingested over two million different savings rate permutations that are possible across EC2, Lambda, and Fargate. As Vantage processes your Cost and Usage Reports (CUR), it will use your usage data to infer what compute you're running and what your specific savings rates would be for each potential Savings Plan you buy.
This methodology for forecasting savings is as accurate as possible and is more accurate with each additional CUR that's processed. Vantage uses the most recent previous month for forecasting the potential savings rate. As your infrastructure changes each month, Vantage will automatically infer new savings rates.
Savings model predictions are based on *raw compute spend* and provide a *projected savings rate*. Descriptions and calculations are provided below.
### Raw Compute Spend
Raw compute spend is defined as any spend on AWS services that is coverable by a Savings Plan. This includes spending on services such as EC2, Lambda, ECS for Kubernetes, SageMaker, and Fargate ECS.
To calculate the raw compute spend, Vantage sums the costs of all coverable services before applying any discounts from Savings Plans. For a given period, this can be expressed as:
$$
{raw\_compute\_spend}= ∑coverable\_services
$$
### Projected Savings Rate
When calculating financial commitment discounts, Vantage uses the last full month of AWS Cost and Usage Reports to categorize the compute spend based on each AWS SKU. This allows Vantage to calculate the total cost (`cost_for_period`) for a given period per SKU. Vantage then uses the AWS API to obtain the hourly rate of the instance type (`sku_hourly_rate`) and the discounted hourly rate (`discounted_rate`), dimensioned by type, term, and payment for the possible discounts.
The following values are calculated for each EC2, Fargate, and Lambda SKU and all discount dimensions (type, term, payment) based on data available from the AWS API. Total hours and instances per hour are calculated as follows:
$$
total\_hours = \frac{cost\_for\_period}{sku\_hourly\_rate}
$$
$$
instances\_per\_hour = \frac{total\_hours}{hours\_in\_period}
$$
Vantage then calculates the cost and discounted cost for the instances per hour:
$$
{cost} = {sku\_hourly\_rate} \times{instances\_per\_hour}
$$
$$
{discounted\_cost} = {discounted\_rate} \times {instances\_per\_hour}
$$
These individual SKU costs are summed by type, term, and payment to get the total costs:
$$
{total\_cost} = \sum {cost}
$$
$$
{total\_discounted\_cost} = \sum {discounted\_cost}
$$
Finally, the projected savings rate is calculated using the total cost and total discounted cost:
$$
{projected\_savings\_rate} = \frac{total\_cost - total\_discounted\_cost}{total\_cost}
$$
## Create a Savings Model
From the top navigation, select **Financial Planning**.
On the left navigation, select **Savings Models**. Any savings models you already created will be displayed on this screen.
At the top, click **New Model**. Two sections are displayed: one that contains a set of values related to the last six months of committed vs. on-demand spend, with future predicted spend. Plans you've already purchased are displayed in the bottom table, with the option to model new plans.
To save a savings model, click **Save As New Model**.
Enter a name for the model, then click **Save**.
### View Current and Future Spend and Coverage
The table at the top contains a projected growth rate for the next 12 months based on the last 6 months of spend. A visualization above the table provides a view of covered/uncovered spend for each month.
The following data is included in the table:
| Metric | Description |
| - | - |
| Raw Compute Spend | The raw compute cost your account uses before any Savings Plans or Reserved Instances are applied. Raw compute comprises spend for EC2, Lambda, ECS for Kubernetes, SageMaker, and Fargate ECS services. |
| On-demand Spend | The amount of on-demand costs that your account has incurred. |
| Savings Plan Commitments | The amount of Savings Plan costs that your account has incurred. |
| Savings Plan Savings | The amount saved by using the Savings Plan. |
| Savings Plan Coverage | A percentage coverage rate of AWS Savings Plans for your compute cost spend. |
| Reserved Instances | The amount of Reserved Instance costs that your account has incurred. |
| Net Compute Spend | The total compute cost that your account has incurred after on-demand, Savings Plans, and Reserved Instance costs. |
To adjust the predictions for future compute spend, click any future date cell within the **Raw Compute Spend** row and manually edit the prediction value. Consider updating these values based on predicted events over the next few months. The **Savings Plan Savings/Coverage** and **Net Compute Spend** rows are automatically updated based on changes to predicted Raw Compute Spend.
In the **Savings Plan Coverage** row, cells are color-coded to provide a visual indication of coverage percentage levels:
* If the Savings Plan Coverage is greater than 100% or less than 20%, the cell will be red. When coverage is over 100%, this means you are overcommitted.
* If the Savings Plan Coverage is greater than or equal to 80%, the cell will be green, signaling good coverage.
* Cells that are greater than or equal to 20% but less than 80% will be gray.
### Model Future Savings Plan Purchases
In the **Savings Plans** table, you can add potential future Savings Plans. All your existing Savings Plans are listed, along with type, term, payment (e.g., No Upfront), purchase date, and expiration date. Upfront payment, recurring hourly payment, and a projected saving rate are also provided for each plan.
The latest savings rate for the plan is calculated by looking at the last full month of usage. You can click the top of any column to sort the table by that column.
For more information about Savings Plans and factors such as term, prepayment, and EC2 vs. Compute plans, see this [Vantage blog article](https://www.vantage.sh/blog/what-is-an-aws-savings-plan).
To add a new Savings Plan, click **Add potential savings plan**.
Enter an **Hourly Commitment** in dollars.
For **Type**, select **Compute** or **EC2**.
For **Term**, select **1 Year** or **3 Year**.
For **Payment**, select **No Upfront**, **Partial Upfront (50%)**, or **All Upfront**.
Select a **Purchase Date**.
Observe any change in the metrics within the table at the top. You can continue to change the hourly commitment and see how that affects your Savings Plan Coverage over time. Adjust other options, like the term or start date, to see how these changes affect coverage. You can also add additional potential Savings Plans.
To remove a Savings Plan, click the **X** in the last column of the Savings Plans table.
Vantage won't purchase the plans you model within the tool. The Savings Planner is available only for modeling purposes.
# Scenario Models
Source: https://docs.vantage.sh/scenario_models
Create reusable Scenario Models that represent known future costs, credits, or trends, and combine them into forecasts on your Cost Reports.
Scenario Models are available to Enterprise customers only.
A *Scenario Model* is a reusable set of monthly future-cost periods. Each Scenario Model represents a known future cost, credit, or trend, such as an upcoming committed-use discount, a provider credit, a one-time migration expense, or planned savings from an optimization project.
Once you create a Scenario Model, you can attach it to a forecast on any [Cost Report](/cost_reports). Vantage combines its [Baseline Forecast](/forecasting#baseline-forecast) with the amounts from your selected Scenario Models to produce a forecast that reflects your known future plans. The same Scenario Model can be reused across any number of Cost Reports and forecasts. See [Forecasts from Scenario Models](/forecasting#scenario-model-forecasts) for how the amounts combine with the Baseline Forecast.
## Create a Scenario Model
Managing Scenario Models requires an **Organization Owner**, **Organization Editor**, or **Integration Owner** role. See [RBAC Permissions](/rbac_permissions#financial-planning) for more details.
From the top navigation, click **Financial Planning**, then select **Scenario Models** in the left sidebar. The Scenario Models page lists every Scenario Model in your Vantage account, along with each model's net change, priority, the Cost Reports it is assigned to, when it was last updated, and who created it.
The **Net Change** column summarizes each model's total impact: the sum of its period amounts (a dollar total for Dollar Amount models or a percentage total for Percentage models). A net decrease (savings) is shown in green with a downward arrow, and a net increase in red with an upward arrow; a model with no net change shows a dash (`-`).
A Scenario Model is flagged as **expired** with a clock icon and a **Forecast Expired** tooltip when the latest end date across its periods is in the past. This calculation only considers periods that have an end date; periods with no end date (open-ended) are not counted.
Editing the model so its latest end date is in the current or a future month clears the flag. The flag is informational only—expired models remain selectable and continue to apply on any forecast they're attached to.
You can create Scenario Models manually or by importing a CSV.
### Create Manually
On the **Scenario Models** page, click **New Scenario Model** in the top right. A new model is displayed with a default name (for example, *New Scenario 1*).
Give the Scenario Model a descriptive name, such as *FY26 Committed Use Discount* or *AWS MAP Credits*.
Under **Model Details**, use the **Cost Adjustment** toggle to choose how the amounts on this model are interpreted:
* **Dollar Amount**: Each period's amount is treated as a dollar value that is added to the forecast for every month in the period's date range.
* **Percentage**: Each period's amount is treated as a percentage that is applied to the forecast for every month in the period's date range.
Use **negative values** in either mode to represent credits, refunds, planned savings, or projected reductions.
When you select **Percentage**, an optional **Priority** field is displayed. Priority sets the order in which percentage models are applied when more than one is attached to the same forecast: lower numbers are processed first. Priority is optional, but any priority you set must be unique within your account. Priority does not apply to Dollar Amount models. See [How Scenario Models combine](/forecasting#how-scenario-models-combine) for details.
Under **Optional Filters**, you can scope the model to a specific **Provider** and, optionally, a **Service** within that provider. Choose a provider to reveal the service selector. Leave these options set to **All Providers**/**All Services** to apply the model to the report's overall forecast.
Provider and service filters apply to both model types. For a **percentage** model, the percentage applies to the matching provider or service's portion of the forecast. For a **dollar** model, the amount is added to the report's total forecast only when that provider or service appears in the report. See [How Scenario Models combine](/forecasting#how-scenario-models-combine) for details.
Under **Forecast Periods**, click **Add Period** for each range of months that the model should cover. For each period, provide:
* **Start Month**: The first month the amount applies to, in `YYYY-MM` format. Month values are interpreted as whole months.
* **End Month**: The last month the amount applies to. Leave blank for an open-ended period. The end month must be on or after the start month.
* **Monthly Amount**: The value applied to each month in the range, interpreted according to the Cost Adjustment type selected above (a dollar amount or a percentage).
Click **Save Changes**. The Scenario Model is now available to attach to forecasts on your Cost Reports.
### Import from a CSV
To create or update many Scenario Models at once, click **Import** on the **Scenario Models** page and upload a CSV. Vantage previews the parsed result before you confirm the import.
Scenario Model CSVs use a row-per-model layout. Each row represents one Scenario Model, and each month column represents one forecasted month:
* **Title column**: The column whose header matches `title` or `name` is used as the model name. If no header matches, the first column is used as the title.
* **Month columns**: Include one column per forecasted month. Every month column header must be in `YYYY-MM` format (for example, `2026-07`). A row with no month values creates a model without any periods.
* **Amount Type column** (optional): Add a column whose header matches `amount type` (or `amount_type`) to control how each row is interpreted. A cell value of `percent` makes that row a percentage model; any other value, or omitting the column entirely, defaults to a dollar model.
* **Cell values**: Each month cell is the amount for that model in that month, a dollar value or a percentage depending on the row's amount type. Values may include `$` and `,`, which are stripped during parsing (for example, `$15,000` is parsed as `15000`). Use negative values for credits or savings (for example, `-8000`).
* **Blank cells**: A blank cell means no amount is applied for that model in that month.
CSV import sets each model's title, amount type, and monthly amounts only. **Priority** and **Provider/Service** filters are not imported from a CSV. You need to set those on the model's detail page after the import.
The following sample creates four Scenario Models: a committed-use discount that runs for the full second half of the year, an AWS MAP credit that applies for three months, a one-time Q4 data migration cost, and a percentage-based efficiency reduction across Q3.
```csv theme={null}
title,amount type,2026-07,2026-08,2026-09,2026-10,2026-11,2026-12
H2 Committed Use Discount,dollar,15000,15000,15000,15000,15000,15000
AWS MAP Credit,dollar,-8000,-8000,-8000,,,
Q4 Data Migration,dollar,,,,25000,25000,
Q3 Efficiency Program,percent,-5,-5,-5,,,
```
The `amount type` column is optional. If you omit it, every row is treated as a dollar model.
In the **Import Scenario Models** dialog, select your CSV file and click **Upload**.
Vantage parses the file and displays a preview of the Scenario Models that will be created or updated. If the file cannot be parsed, Vantage displays one of the following errors:
| Error | Cause | Solution |
| - | - | - |
| `The file is unparseable.` | The file is empty or is not valid CSV. | Confirm the file has content and is a valid CSV, then re-upload. |
| `'' has an invalid date format.` | One or more month column headers are not in `YYYY-MM` format. | Update the header to a valid `YYYY-MM` month and re-upload. |
| `'' appears more than once in the file.` | The CSV contains more than one row with the same name. | Rename or remove the duplicate rows so each Scenario Model name is unique within the file, then re-upload. |
Click **Confirm Import** to upload the Scenario Models. The import runs in the background, and the **Scenario Models** page updates when it completes.
If a Scenario Model in the CSV has the same name as an existing model, the existing model is overwritten with the values from the CSV.
## Edit or Delete a Scenario Model
On the main Scenario Models page, click a Scenario Model's row to open its detail page, where you can rename the model, change its Cost Adjustment type, add or remove periods, and change existing amounts or date ranges. Use the delete action to remove the model entirely.
When you **edit** a Scenario Model, Vantage automatically reprocesses every forecast that uses that model on every Cost Report. Affected Cost Reports typically reflect the updated values within approximately 10 minutes. **Deleting** a Scenario Model removes it from every forecast it was attached to.
## View Cost Reports Using a Scenario Model
The Scenario Model detail page includes an **Assigned Cost Reports** section that lists every Cost Report where the Scenario Model is attached to a forecast. For each entry, Vantage displays:
* **Report Name**: The title of the Cost Report. Click the report name to go directly to that report's **Forecasts** tab.
* **Forecast**: The name of the forecast that references this Scenario Model. If the same Scenario Model is attached to multiple forecasts on the same report, all forecast names are listed.
Scenario Models are attached to Cost Reports from the Cost Report side, not from this page. To attach this Scenario Model to a new Cost Report, open that report, click the **Forecasts** tab, and create a new forecast that includes this model. See [Forecasts from Scenario Models](/forecasting#scenario-model-forecasts) for the full flow.
## Apply a Scenario Model to a Cost Report
To use a Scenario Model, attach it to a forecast on a Cost Report.
See the Forecasting documentation for step-by-step instructions on creating a forecast from one or more Scenario Models, setting it as the default forecast on a Cost Report, and comparing scenarios.
# Security
Source: https://docs.vantage.sh/security
Learn about Vantage's security practices, such as read-only billing access, compliance, data protection, and secure cloud provider integrations.
As an infrastructure tool that requires access to your cloud provider, we understand there may be questions, concerns, and necessary clarification around our infrastructure, processes, and procedures. We, as developers at Vantage, are also customers of Vantage, which more closely aligns our security concerns with those of our customers.
## Read-Only Billing Access
Vantage uses read-only service accounts, service roles, API keys, and other read-only means to access billing data across all the integrations we use. This means we don't store sensitive information, like account access keys and access key secrets, to use Vantage. Should you have any other questions, please feel free to email us at [security@vantage.sh](mailto:security@vantage.sh).
## Cross-Account IAM Roles on AWS
Vantage uses a Cross-Account IAM Role to sync information about your infrastructure resources. This method is [the AWS-recommended](https://aws.amazon.com/blogs/apn/securely-accessing-customer-aws-accounts-with-cross-account-iam-roles/) approach. When you grant Vantage access to your account by running the provided CloudFormation stack, the stack creates a cross-account role with in-line policies selected by Vantage. These policies are a trimmed-down version of the policies in the AWS-managed `ReadOnlyAccess` policy, but we've removed actions that would otherwise allow us to access sensitive information in databases, buckets, and certain services. Our CloudFormation template is open source and [hosted publicly](https://vantage-public.s3.amazonaws.com/vantage-integration-latest.json) for transparency.
### Customizing Cross-Account Role Permissions
Vantage requests various in-line read-only permissions when creating the cross-account role on your behalf; however, we understand this can be too broad of a permission set for certain use cases. As a result, we do allow you to create Cross-Account IAM roles with whatever permissions you're comfortable with. However, keep in mind that narrowing the scope of the role's permissions will limit certain functionality in Vantage.
If you email [support@vantage.sh](mailto:support@vantage.sh) in advance, we can facilitate provisioning your account with a custom role. Please note that we will provide you with some custom attributes to associate with your Cross-Account IAM Role to prevent [the "confused deputy" problem](https://docs.aws.amazon.com/IAM/latest/UserGuide/confused-deputy.html). As a result, you will need to contact Vantage support *before* you create the role.
## Data Revocation
In the account **Settings** section, you can revoke the Cross-Account IAM Role at any time. Automatically and nearly instantly, Vantage will delete all data associated with that Cross-Account IAM Role. Note that the deletion doesn't remove the set of custom Vantage views you've created; however, these views will be empty, as there are no longer any resources.
In the account **Settings** section, you also can delete your account. Once you delete your account, all data is deleted as well.
## Data Sharing
We do not share any data externally. We do not sell or share any user data with any third parties.
## Frequently Asked Questions
Yes. Vantage has outsourced penetration tests to a third party that regularly performs these tests.
Yes. Vantage is both SOC 1 Type 2 and SOC 2 Type 2 certified. To request a copy of our report, visit the [Vantage Security Page](https://vantage.sh/security). With these certifications, we believe that we already roughly adhere to the standards outlined in ISO 27001.
Vantage receives reports via [security@vantage.sh](mailto:security@vantage.sh). We review every single report that we receive. We do not have a formal bug bounty program, but we do have [a process](https://www.vantage.sh/legal/security#security-and-vulnerability-disclosure-policy) as well as a set of policies and standards we follow to process security requests.
Yes. We support [SAML SSO](/sso), and 2FA is on the roadmap.
All data is encrypted in transit and at rest. Only a subset of senior employees has access to data on the Vantage side. We regularly review and revise the list of individuals on the Vantage team with access to customer data.
We use a subset of third parties, largely for analytics, support, and payment processing. See the [Trust Center](https://trust.vantage.sh/) for more insight into third parties and data policies.
A team responds to messages at [security@vantage.sh](mailto:security@vantage.sh). Upon request, a security employee can be temporarily assigned to your account as well.
Yes.
Yes. We store basic metadata on cloud infrastructure to be able to show corresponding costs for associated resources. We cannot access any of the underlying resources.
Yes, Vantage uses fixed IP addresses for outgoing traffic. All traffic from Vantage will originate from the following IP addresses:
Yes. Sessions expire after 3 days of inactivity, or after 7 days regardless of activity.
# Slack
Source: https://docs.vantage.sh/slack
Learn how to create an integration with Slack and Vantage to send alerts and notifications.
Vantage integrates with Slack so that you can send [Report Notifications](/report_notifications#set-up-cost-report-notifications), [Cost Alerts](/cost_alerts), [Cost Anomaly Alerts](/cost_anomaly_alerts), and [Budget Alerts](/budgets#budget-alerts) to your Slack channels. You can adjust notifications to be delivered to a specific public or private channel in Slack.
The Vantage Slack app makes it easy for teams to stay on top of cloud costs without leaving Slack. Your team gets real-time alerts right where you already work. You can configure notifications for things like:
* Unexpected spending spikes
* Budgets getting close to or over their limits
* Regular Cost Report summaries
* Custom alerts for specific thresholds or conditions
The Vantage Slack integration also powers the [Vantage FinOps Agent](/vantage_finops_agent), an AI assistant that can answer questions about your cloud costs, create reports, and take action on savings recommendations directly in Slack. The FinOps Agent uses the same Slack integration but provides additional AI-powered capabilities beyond notifications and alerts.

## Installation
To get started with Vantage in Slack, you'll need permission to add integrations to your team's Slack account.
From the top navigation in Vantage, click **Settings**.
On the left navigation, click **Integrations**.
Under the **Apps** section, click **Slack**.
Click **Connect Slack**. If prompted, enter your workspace's Slack URL. A Slack page that describes the requested permissions for Vantage is displayed. The Vantage integration has permission to list and join channels, as well as post messages to those channels.
Vantage does not read any message posted within your channels.
Select any channel where you would like to add the integration and allow access.
To receive notifications in a channel:
* Open the channel in Slack
* Create a new message in the channel
* Type `/invite @Vantage` and send the message
Your first notifications will appear the day after setup, giving you time to configure your preferred settings and channel assignments.
## Next Steps: Configure Notifications
After installation, you can configure various types of alerts to monitor your cloud costs:
| Alert Type | Description | Documentation |
| - | - | - |
| **Budget Alerts** | Set up budget alerts for your most critical cost centers | [Budget Alerts](/budgets) |
| **Cost Anomaly Detection** | Create cost anomaly detection for unexpected spending spikes | [Cost Anomaly Alerts](/cost_anomaly_alerts) |
| **Report Notifications** | Configure report notifications for regular cost summaries | [Report Notifications](/report_notifications) |
| **Cost Alerts** | Set up custom alerts for specific thresholds or conditions | [Cost Alerts](/cost_alerts) |
### Channel Support by Alert Type
The matrix below shows which Vantage alert types support delivery to Slack (and to Microsoft Teams, Jira, and email for cross-reference).
| Alert Type | Email | Slack | Microsoft Teams | Jira | Configured From |
| - | :-: | :-: | :-: | :-: | - |
| [Cost Anomaly Alerts](/cost_anomaly_alerts) | Yes | Yes | Yes | Yes | A Cost Report's **Anomalies** tab > **Configure Alert** |
| [Cost Alerts](/cost_alerts) | Yes | Yes | Yes | Yes | A Cost Report's **...** menu > **Create Cost Alert**, or **Notifications** > **Cost Alerts** > **Configure Cost Alert** |
| [Budget Alerts](/budgets#budget-alerts) | Yes | Yes | Yes | Yes | A Budget's **Manage** tab > **Manage Alerts** > **Configure Alert** |
| [Report Notifications](/report_notifications) (Cost Reports) | Yes | Yes | Yes | — | The **Notifications** page > **New Notification** > **Cost Report Notification**, or a Cost Report's **...** menu > **Create Report Notification** |
| [Dashboard Notifications](/report_notifications#set-up-dashboard-notifications) | Yes | — | — | — | The **Notifications** page > **New Notification** > **Dashboard Notification** |
Slack and Microsoft Teams are mutually exclusive at the integration level: you can connect either Slack or Microsoft Teams, not both. See the [Slack](/slack) and [Microsoft Teams](/microsoft_teams) integration docs for setup. Jira delivery requires the [Jira integration](/jira).
# Snowflake Costs per Query
Source: https://docs.vantage.sh/snowflake_cost_by_query
Use Vantage to identify expensive Snowflake queries by calculating weighted costs per query based on duration.
Vantage calculates a weighted cost per query by breaking down the use of Snowflake [compute credits](https://docs.snowflake.com/en/user-guide/credits.html#virtual-warehouse-credit-usage). This allows users to easily identify the most expensive queries.

## How It Works
Snowflake Compute is billed only when a query is running, rounded up to the hour; however, if multiple queries are running simultaneously, the cost is still only reported for that hour. This shared credit pool makes it difficult to understand which individual queries are contributing the most to costs.
Each day, Vantage ingests the compute credits used, and their equivalent cost, and assigns a weighted cost to each query based on the total duration for which the query ran. For example, if you had 3 queries that ran for 1, 2, and 3 minutes respectively, and a total bill of \$500, the query that ran for 3 minutes would be assigned a cost of \$250 as it accounted for half of the overall query time.
## Grouping Queries
Vantage groups queries based on the source and structure of a query, so users can easily identify it. To determine the source, Vantage looks at the warehouse in which the query was run as well as the user who ran the query. To determine the structure of a query, Vantage will strip all query values and the order of columns and generate a normalized, unique fingerprint for the query.
## Viewing the Costs
Query costs are available in two views: on Cost Reports and in Active Resources.
### Query Costs in Cost Reports
To view query costs on a [Cost Report](/cost_reports/):
In the console, navigate to [Cost Reports](https://console.vantage.sh/reporting).
Create a new report and add a provider filter for **Snowflake**.
Click the **Cost by Resource** icon next to the **Snowflake Data Cloud** line item and see a paginated list of each query, as well as a day-by-day breakdown of that query's costs.
### Query Costs in Active Resources View
To view query costs in the [Active Resources](/active_resources) view:
Navigate to the [Active Resources page](https://console.vantage.sh/services/snowflake_queries/resources) in the console.
Select **Snowflake Query** and see a list of active queries, as well as their associated costs. Queries are considered active if they have incurred costs in the past 30 days and are in the top 1,000 queries by cost for that account.
## Security
Vantage ensures that any sensitive data contained in queries is never stored in Vantage systems. When the `QUERY_HISTORY` view is queried from Snowflake, that data is immediately processed to strip all values from queries before they are stored.
# Snowflake Data Sharing
Source: https://docs.vantage.sh/snowflake_data_sharing
Query your processed Vantage cost data directly from your Snowflake account using a Secure Data Share.
Snowflake Data Sharing gives your Snowflake account read-only SQL access to a `daily_costs` table containing the same processed cost data you see in Vantage [Cost Reports](/cost_reports), delivered via [Secure Data Sharing](https://docs.snowflake.com/en/user-guide/data-sharing-intro).
This feature is built for data engineering teams and FinOps practitioners who already operate in warehouse-native workflows. Once enabled, you can query Vantage cost data alongside your own datasets, power your BI tools without building ingestion pipelines, and join cost data with revenue, usage, or organizational metadata directly in SQL.
`daily_costs` contains rows from every provider you have connected to Vantage—AWS, Azure, GCP, Snowflake, AI providers, and so on—distinguished by the `provider` column. The schema is normalized so that the same column set works across all providers. Where the meaning of a column varies by provider, [Discovering Your Data](#discovering-your-data) below shows you how to introspect what's actually in your table.
## How It Works
Vantage stores your processed cost data as an [Apache Iceberg](https://iceberg.apache.org/) table in Vantage-owned AWS infrastructure. A managed Snowflake catalog integration in the Vantage Snowflake account makes that table queryable, and a Secure Data Share exposes it to your Snowflake account.
```mermaid theme={null}
flowchart LR
ETL[Vantage ETL] --> Iceberg["daily_costs Iceberg table"]
Iceberg --> Catalog[Vantage Snowflake catalog integration]
Catalog --> Share[Secure Data Share]
Share --> Customer[Your Snowflake account]
```
Key properties of this architecture:
* **No data is copied into your Snowflake account.** The Secure Data Share gives your account queryable access to data that lives in the Vantage-managed Iceberg table.
* **Data refreshes whenever the Vantage ETL completes for a billing period.** This typically tracks the same cadence you see in the Vantage console for that provider. See the [provider data refresh](/provider_data_refresh) documentation for details.
* **The share lives in the same cloud region as your Snowflake account**, so your queries do not incur cross-region or internet egress on Vantage's side.
## Cost Considerations
You pay Snowflake for the compute used to run your queries ([warehouse credits](https://docs.snowflake.com/en/user-guide/cost-understanding-compute)). Vantage does not charge per query.
Because the Secure Data Share lives in the same cloud region as your Snowflake account, you do not incur cross-region or internet egress on Vantage's side when you query the data. For guidance on sizing the warehouse you point at the share, see Snowflake's [warehouse considerations](https://docs.snowflake.com/en/user-guide/warehouses-considerations).
## Get Access
Snowflake Data Sharing is available to Vantage Enterprise customers.
To enable Snowflake Data Sharing, first contact your Vantage Customer Success representative or email [support@vantage.sh](mailto:support@vantage.sh). Vantage will enable the connection screen for your account.
Once enabled, complete the setup in the Vantage console:
From the top navigation, click **Settings**. On the left navigation, select **Integrations**, then click **Snowflake Export**.
Enter your [**Data Sharing Account Identifier**](https://docs.snowflake.com/en/user-guide/admin-account-identifier#providing-your-data-sharing-account-identifier) (in the form `ORGNAME.ACCOUNTNAME`) and select the **Region** where your Snowflake account is hosted from the dropdown.
Click **Connect Snowflake**. Vantage provisions a Secure Data Share scoped to your account. When the share is ready, it will appear in your Snowflake account. Follow the steps below to connect it.
The share is one-way and read-only. Vantage cannot read or write into your Snowflake account, and your account cannot modify data through the share.
## Connect the Share in Snowflake
After Vantage confirms your share is ready, run the following in Snowflake to mount the data. Replace the placeholders with the values Vantage provided.
You can confirm the share is available in the Snowflake UI by navigating to **Data Sharing** > **Shared with you** in the left sidebar. The Vantage share will appear under **Direct shares**. Alternatively, run the following in the SQL console:
```sql theme={null}
SHOW SHARES LIKE 'VANTAGE_SHARE_%';
```
Choose any local database name. The examples on this page use `VANTAGE_DB`. See Snowflake's [`CREATE DATABASE … FROM SHARE`](https://docs.snowflake.com/en/sql-reference/sql/create-database) reference for full syntax.
```sql theme={null}
CREATE DATABASE VANTAGE_DB
FROM SHARE .;
```
Vantage will provide the full share identifier (e.g., `ACME123.VANTAGE_AWS_US_EAST_1.VANTAGE_SHARE_ACME`).
If you already have a `VANTAGE` database from the [Snowflake integration](/connecting_snowflake#snowflake-schema-for-vantage), use a different name to avoid a collision.
Grant the imported privileges to whichever role will run queries.
```sql theme={null}
GRANT IMPORTED PRIVILEGES ON DATABASE VANTAGE_DB TO ROLE ;
```
Snowflake folds unquoted identifiers to uppercase, so the namespace and table appear as `.DAILY_COSTS`. Queries can reference either case.
```sql theme={null}
SHOW SCHEMAS IN DATABASE VANTAGE_DB;
SHOW TABLES IN SCHEMA VANTAGE_DB.;
```
Pull the last seven days of spend by service to confirm the share is working.
```sql theme={null}
SELECT service_name, SUM(amortized_cost) AS total
FROM VANTAGE_DB..daily_costs
WHERE charge_period_start >= DATEADD(day, -7, CURRENT_DATE())
AND charge_category IN ('Usage', 'Discounted')
AND provider = 'aws'
GROUP BY service_name
ORDER BY total DESC
LIMIT 25;
```
## The `daily_costs` Table
`daily_costs` is the table exposed through Snowflake Data Sharing. It contains one row per resource per day, after Vantage's ETL has processed it and merged any [Virtual Tags](/tagging) you've configured. The numbers match what you see in [Cost Reports](/cost_reports) for the same filters.
### Schema
| Column | Type | Description |
| - | - | - |
| `provider` | `VARCHAR` | Identifies which connected provider the row came from, lowercase (e.g., `aws`, `azure`, `gcp`, `anthropic`, `datadog`). Always populated. |
| `service_name` | `VARCHAR` | The service the row belongs to (e.g., `AmazonEC2`, `claude-sonnet-4`, `Datadog Infrastructure`). Values are scoped per provider. |
| `region_id` | `VARCHAR` | Provider region identifier where the resource ran. May be empty for SaaS providers without a region concept. |
| `resource_id` | `VARCHAR` | Provider-native resource identifier (e.g., AWS ARN, Azure resource ID, GCP resource path). This is the raw identifier, not a friendly display name. May be empty for providers that do not expose a per-resource identity. |
| `service_category` | `VARCHAR` | Vantage's normalized service category (e.g., `Compute`, `Storage`, `AI and Machine Learning`). Values are scoped per provider. See [Discovering Your Data](#discovering-your-data) to see what's in your table. |
| `service_subcategory` | `VARCHAR` | Vantage's normalized service subcategory. Values are scoped per provider. |
| `consumed_unit` | `VARCHAR` | Unit of measurement for `consumed_quantity`. Varies by provider (e.g., `Hrs`, `GB-Mo`, `Tokens`, `Requests`). |
| `charge_period_start` | `DATE` | Day the charge applies to. |
| `charge_period_end` | `DATE` | Exclusive upper bound: always `charge_period_start + 1 day`. |
| `billed_cost` | `NUMBER(26,10)` | Cost without amortizing upfront commitments. Closest to AWS "Unblended". |
| `amortized_cost` | `NUMBER(26,10)` | Cost with upfront commitments (RIs, Savings Plans) spread across their term. |
| `consumed_quantity` | `NUMBER(26,10)` | Amount of `consumed_unit` consumed. |
| `billing_account_id` | `VARCHAR` | Top-level billing account (e.g., AWS payer/management account, GCP billing account, Azure billing account). May be empty for providers without a multi-account hierarchy. |
| `sub_account_id` | `VARCHAR` | Sub-account, project, or workspace within `billing_account_id` (e.g., AWS linked account, GCP project, Azure subscription). |
| `charge_category` | `VARCHAR` | Classifies the row as `Usage`, `Discounted`, `Undiscounted`, `Tax`, `Refund`, or `Credit`. See [`charge_category` values](#charge_category-values) below. |
| `tags` | `VARCHAR` | JSON-encoded resource tags plus any Vantage [Virtual Tags](/tagging). Default is `'{}'`. May be empty for providers that do not support tagging. |
`billed_cost` and `amortized_cost` can each be `NULL` on rows where that view doesn't apply. Always use `SUM()` (which ignores `NULL`) and pick one column or the other. Never add them together, because some rows populate both with the same value and would be double-counted.
The table also contains an `import_token` column. This is an internal Vantage identifier used for data loading and is not meaningful for querying. You can safely ignore it.
### Date Semantics
Rows are daily. `charge_period_start` is the day the charge applies to, and `charge_period_end` is always exactly one day later (exclusive). To select a date range, **filter on `charge_period_start` only**:
```sql theme={null}
WHERE charge_period_start >= DATE '2026-04-01'
AND charge_period_start < DATE '2026-05-01'
```
If you filter on `charge_period_end` instead, keep in mind that it's already a day ahead, which makes it easy to accidentally drop the first or last day of your range. Using `charge_period_start` on both sides avoids this issue. Every example on this page follows this logic.
### `charge_category` Values
`charge_category` is a normalized category that does not depend on the upstream provider's vocabulary. Rows fall into one of:
| Value | Meaning |
| - | - |
| `Usage` | Standard usage charges. The default for rows that do not match any specific bucket. |
| `Discounted` | Discounted usage rows (e.g., RI- or Savings-Plan-covered usage). |
| `Undiscounted` | Usage at on-demand rates with no commitment applied. |
| `Tax` | Tax line items. |
| `Refund` | Refund line items. |
| `Credit` | Credit line items. |
### Tags
The `tags` column stores resource tags as a JSON-encoded string with a default of `'{}'`. Use Snowflake's [`PARSE_JSON`](https://docs.snowflake.com/en/sql-reference/functions/parse_json) and the `:` accessor to read tag values. Rule-based [Virtual Tags](/tagging) are merged into this column.
Virtual Tags that use [cost allocation](/tagging#cost-allocation-tags) (Business Metrics-Based, Cost-Based, or Percent-Based) are not currently available in `daily_costs`. Those allocations are computed separately inside Vantage and do not yet flow into the export. Standard Virtual Tags that map tag values directly (e.g., renaming or consolidating tag keys) are included.
## Query Cookbook
The examples below all target `VANTAGE_DB..daily_costs`. Replace the database name and namespace with your own values.
Most examples use `SUM(amortized_cost)` with `charge_category IN ('Usage', 'Discounted')` to match the default view in [Cost Reports](/cost_reports). To match a different toggle combination (for example, on-demand rates without amortization), see [Matching Cost Report Toggles](#matching-cost-report-toggles) below.
### Discovering Your Data
Because the schema is normalized but the values are scoped per provider, the fastest way to understand what's in your table is to introspect it. The five queries below take you from "what providers do I have?" to "what categories and units does each provider report?" Run them in order the first time you connect.
```sql theme={null}
SELECT DISTINCT provider
FROM VANTAGE_DB..daily_costs
ORDER BY provider;
```
The list reflects every provider you have connected to your Vantage account. If a provider is missing, it has not yet been ingested or is not yet enabled for export.
```sql theme={null}
SELECT DISTINCT service_name
FROM VANTAGE_DB..daily_costs
WHERE provider = 'anthropic'
ORDER BY service_name;
```
Substitute any `provider` value from the previous query. The set of `service_name` values is the same as what you'd see in Vantage's filter dropdowns for that provider.
```sql theme={null}
SELECT DISTINCT service_category, service_subcategory
FROM VANTAGE_DB..daily_costs
WHERE provider = 'aws'
ORDER BY service_category, service_subcategory;
```
`service_category` and `service_subcategory` are Vantage's normalized rollups (e.g., `Compute`, `Storage`, `AI and Machine Learning`). The exact values depend on the provider. Running this for each of your providers tells you which buckets you can group by.
```sql theme={null}
SELECT DISTINCT consumed_unit
FROM VANTAGE_DB..daily_costs
WHERE provider = 'gcp'
ORDER BY consumed_unit;
```
Cloud providers tend to report units like `Hrs`, `GB-Mo`, and `Requests`. AI providers often report `Tokens`. Pair `consumed_unit` and `consumed_quantity` if you want to compute usage-based metrics.
```sql theme={null}
SELECT provider,
MIN(charge_period_start) AS first_day,
MAX(charge_period_start) AS last_day,
COUNT(*) AS row_count
FROM VANTAGE_DB..daily_costs
GROUP BY provider
ORDER BY provider;
```
Use this to check data freshness and backfill. If a provider's `last_day` lags the others, its data may not have finished loading yet. See [Provider Data Refresh](/provider_data_refresh) for the expected cadence.
### Total Cost for a Date Range
The simplest possible query: total amortized cost over a fixed window, matching the default Cost Report view.
```sql theme={null}
SELECT SUM(amortized_cost) AS total
FROM VANTAGE_DB..daily_costs
WHERE charge_period_start >= DATE '2026-04-01'
AND charge_period_start < DATE '2026-05-01'
AND charge_category IN ('Usage', 'Discounted');
```
When you bound a date range, put both bounds on `charge_period_start` (`>= start AND < end`). Avoid filtering on `charge_period_end` as it's exclusive (`charge_period_start + 1 day`) and easy to get off-by-one.
### Billed vs. Amortized: Which Column to Use
`billed_cost` is what you were billed for in the period. It closely corresponds to AWS "Unblended" cost. `amortized_cost` spreads upfront commitments (Reserved Instances, Savings Plans) across their term. It closely corresponds to AWS "Amortized" cost.
Pick one consistently for any given report. Either column is `NULL` for rows where the alternative view does not apply, so always use `SUM()`.
```sql Billed theme={null}
SELECT service_name, SUM(billed_cost) AS billed
FROM VANTAGE_DB..daily_costs
WHERE charge_period_start >= DATE '2026-04-01'
AND charge_period_start < DATE '2026-05-01'
GROUP BY service_name
ORDER BY billed DESC;
```
```sql Amortized theme={null}
SELECT service_name, SUM(amortized_cost) AS amortized
FROM VANTAGE_DB..daily_costs
WHERE charge_period_start >= DATE '2026-04-01'
AND charge_period_start < DATE '2026-05-01'
GROUP BY service_name
ORDER BY amortized DESC;
```
### Matching Cost Report Toggles
In [Cost Reports](/cost_reports), you control what's included via toggles. In SQL, you reproduce the same view by choosing which `charge_category` values to include and whether to use `billed_cost` or `amortized_cost`.
`Discounted` and `Undiscounted` are **mutually exclusive**. You can use one or the other, but never both. `Discounted` includes commitment-covered usage (the default in Cost Reports). `Undiscounted` shows on-demand rates instead.
Never include both `Discounted` and `Undiscounted` in the same query. A row is one or the other depending on whether a commitment covers it.
The four base combinations that match the Cost Report discount and amortization toggles:
| Discounts | Amortization | SQL |
| - | - | - |
| On (default) | On (default) | `charge_category IN ('Usage', 'Discounted')` + `SUM(amortized_cost)` |
| On | Off | `charge_category IN ('Usage', 'Discounted')` + `SUM(billed_cost)` |
| Off | On | `charge_category IN ('Usage', 'Undiscounted')` + `SUM(amortized_cost)` |
| Off | Off | `charge_category IN ('Usage', 'Undiscounted')` + `SUM(billed_cost)` |
To include additional line items, add them to the `IN (...)` list:
| Toggle | Add to `charge_category IN (...)` |
| - | - |
| Include Tax | `'Tax'` |
| Include Refunds | `'Refund'` |
| Include Credits | `'Credit'` |
The default Cost Report view (discounts on, amortization on):
```sql theme={null}
SELECT SUM(amortized_cost) AS total
FROM VANTAGE_DB..daily_costs
WHERE charge_period_start >= DATE '2026-04-01'
AND charge_period_start < DATE '2026-05-01'
AND charge_category IN ('Usage', 'Discounted');
```
The same period with discounts off:
```sql theme={null}
SELECT SUM(amortized_cost) AS total
FROM VANTAGE_DB..daily_costs
WHERE charge_period_start >= DATE '2026-04-01'
AND charge_period_start < DATE '2026-05-01'
AND charge_category IN ('Usage', 'Undiscounted');
```
To see exactly what falls in each bucket for a given period, break the totals out by `charge_category`:
```sql theme={null}
SELECT charge_category, SUM(amortized_cost) AS total
FROM VANTAGE_DB..daily_costs
WHERE charge_period_start >= DATE '2026-04-01'
AND charge_period_start < DATE '2026-05-01'
GROUP BY charge_category
ORDER BY total DESC;
```
### Cost by Service
```sql theme={null}
SELECT provider, service_name, SUM(amortized_cost) AS total
FROM VANTAGE_DB..daily_costs
WHERE charge_period_start >= DATE '2026-04-01'
AND charge_period_start < DATE '2026-05-01'
AND charge_category IN ('Usage', 'Discounted')
GROUP BY provider, service_name
ORDER BY total DESC;
```
### Cost by Account, Sub-Account, or Region
`billing_account_id` is the top-level billing account (AWS payer/management account, GCP billing account, Azure billing account). `sub_account_id` is the sub-account within it (AWS linked account, GCP project, Azure subscription).
```sql By billing account theme={null}
SELECT provider, billing_account_id, SUM(amortized_cost) AS total
FROM VANTAGE_DB..daily_costs
WHERE charge_period_start >= DATE '2026-04-01'
AND charge_period_start < DATE '2026-05-01'
AND charge_category IN ('Usage', 'Discounted')
GROUP BY provider, billing_account_id
ORDER BY total DESC;
```
```sql By sub-account theme={null}
SELECT provider, sub_account_id, SUM(amortized_cost) AS total
FROM VANTAGE_DB..daily_costs
WHERE charge_period_start >= DATE '2026-04-01'
AND charge_period_start < DATE '2026-05-01'
AND charge_category IN ('Usage', 'Discounted')
GROUP BY provider, sub_account_id
ORDER BY total DESC;
```
```sql By region theme={null}
SELECT provider, region_id, SUM(amortized_cost) AS total
FROM VANTAGE_DB..daily_costs
WHERE charge_period_start >= DATE '2026-04-01'
AND charge_period_start < DATE '2026-05-01'
AND charge_category IN ('Usage', 'Discounted')
GROUP BY provider, region_id
ORDER BY total DESC;
```
### Top Resources by Spend
```sql theme={null}
SELECT provider, resource_id, service_name, SUM(amortized_cost) AS total
FROM VANTAGE_DB..daily_costs
WHERE charge_period_start >= DATE '2026-04-01'
AND charge_period_start < DATE '2026-05-01'
AND charge_category IN ('Usage', 'Discounted')
GROUP BY provider, resource_id, service_name
ORDER BY total DESC
LIMIT 50;
```
### Multi-Cloud Filtering and Grouping
```sql theme={null}
SELECT provider, SUM(amortized_cost) AS total
FROM VANTAGE_DB..daily_costs
WHERE provider IN ('aws', 'azure', 'gcp')
AND charge_period_start >= DATE '2026-04-01'
AND charge_period_start < DATE '2026-05-01'
AND charge_category IN ('Usage', 'Discounted')
GROUP BY provider
ORDER BY total DESC;
```
### Filtering and Grouping by Tag
The `tags` column is a JSON-encoded string. Use [`PARSE_JSON`](https://docs.snowflake.com/en/sql-reference/functions/parse_json) and the `:` accessor to read individual values. See Snowflake's [Querying semi-structured data](https://docs.snowflake.com/en/user-guide/querying-semistructured) for the full syntax, including how to read keys with special characters via `PARSE_JSON(tags)['my-key']`.
```sql Exact-match filter theme={null}
SELECT SUM(amortized_cost) AS total
FROM VANTAGE_DB..daily_costs
WHERE PARSE_JSON(tags):environment::string = 'production'
AND charge_period_start >= DATE '2026-04-01'
AND charge_period_start < DATE '2026-05-01'
AND charge_category IN ('Usage', 'Discounted');
```
```sql Group by tag value theme={null}
SELECT PARSE_JSON(tags):team::string AS team,
SUM(amortized_cost) AS total
FROM VANTAGE_DB..daily_costs
WHERE charge_period_start >= DATE '2026-04-01'
AND charge_period_start < DATE '2026-05-01'
AND charge_category IN ('Usage', 'Discounted')
GROUP BY team
ORDER BY total DESC NULLS LAST;
```
```sql Restrict to rows with a specific tag set theme={null}
SELECT *
FROM VANTAGE_DB..daily_costs
WHERE PARSE_JSON(tags):cost_center IS NOT NULL
LIMIT 100;
```
```sql Handle missing or empty tag values theme={null}
SELECT
provider,
service_name,
COALESCE(
NULLIF(TRIM(TRY_PARSE_JSON(tags):team::string), ''),
'Not tagged'
) AS team,
SUM(amortized_cost) AS cost
FROM VANTAGE_DB..daily_costs
WHERE charge_period_start >= DATE '2026-04-01'
AND charge_period_start < DATE '2026-05-01'
AND charge_category IN ('Usage', 'Discounted')
GROUP BY provider, service_name, team
ORDER BY cost DESC;
```
Use [`TRY_PARSE_JSON`](https://docs.snowflake.com/en/sql-reference/functions/try_parse_json) instead of `PARSE_JSON` if you want to safely handle rows where `tags` might contain unexpected values. It returns `NULL` instead of raising an error. Wrap with `COALESCE` and `NULLIF` to replace missing or empty tag values with a fallback label like `'Not tagged'`.
### Daily and Monthly Trends
Use [`DATE_TRUNC`](https://docs.snowflake.com/en/sql-reference/functions/date_trunc) and [`DATEADD`](https://docs.snowflake.com/en/sql-reference/functions/dateadd) to bucket time series.
```sql Daily, last 30 days theme={null}
SELECT charge_period_start AS day, SUM(amortized_cost) AS total
FROM VANTAGE_DB..daily_costs
WHERE charge_period_start >= DATEADD(day, -30, CURRENT_DATE())
AND charge_category IN ('Usage', 'Discounted')
GROUP BY day
ORDER BY day;
```
```sql Monthly, last 12 months theme={null}
SELECT DATE_TRUNC('month', charge_period_start) AS month,
SUM(amortized_cost) AS total
FROM VANTAGE_DB..daily_costs
WHERE charge_period_start >= DATEADD(month, -12, CURRENT_DATE())
AND charge_category IN ('Usage', 'Discounted')
GROUP BY month
ORDER BY month;
```
### Month-over-Month Change
Use Snowflake's [window functions](https://docs.snowflake.com/en/sql-reference/functions-analytic) (in particular [`LAG`](https://docs.snowflake.com/en/sql-reference/functions/lag)) to compute month-over-month deltas. `NULLIF(..., 0)` avoids division by zero.
```sql theme={null}
WITH monthly AS (
SELECT DATE_TRUNC('month', charge_period_start) AS month,
SUM(amortized_cost) AS total
FROM VANTAGE_DB..daily_costs
WHERE charge_category IN ('Usage', 'Discounted')
GROUP BY month
)
SELECT month,
total,
total - LAG(total) OVER (ORDER BY month) AS mom_delta,
(total - LAG(total) OVER (ORDER BY month))
/ NULLIF(LAG(total) OVER (ORDER BY month), 0) * 100 AS mom_pct
FROM monthly
ORDER BY month;
```
### Service Category Rollups
Group by `service_category` and `service_subcategory` to see the Compute, Storage, Networking, etc. mix.
```sql theme={null}
SELECT service_category, service_subcategory, SUM(amortized_cost) AS total
FROM VANTAGE_DB..daily_costs
WHERE charge_period_start >= DATE '2026-04-01'
AND charge_period_start < DATE '2026-05-01'
AND charge_category IN ('Usage', 'Discounted')
GROUP BY service_category, service_subcategory
ORDER BY total DESC;
```
### Joining with Your Own Data
A common pattern is to compute a unit cost by dividing Vantage cost data by a customer-side metric (revenue, number of customers, requests, etc.). The example below assumes a customer-side table `MY_DB.PUBLIC.monthly_revenue(month DATE, revenue NUMBER)`.
```sql theme={null}
WITH monthly_costs AS (
SELECT DATE_TRUNC('month', charge_period_start) AS month,
SUM(amortized_cost) AS cost
FROM VANTAGE_DB..daily_costs
WHERE charge_category IN ('Usage', 'Discounted')
GROUP BY month
)
SELECT c.month,
c.cost,
r.revenue,
c.cost / NULLIF(r.revenue, 0) AS cost_per_revenue
FROM monthly_costs c
LEFT JOIN MY_DB.PUBLIC.monthly_revenue r USING (month)
ORDER BY c.month;
```
For a managed equivalent inside Vantage, see the [Business Metrics](/business_metrics) documentation.
### Materializing a View for BI Tools
Wrap frequently-used aggregates in a Snowflake [view](https://docs.snowflake.com/en/sql-reference/sql/create-view) (or a [dynamic table](https://docs.snowflake.com/en/user-guide/dynamic-tables-about)) so that BI dashboards can hit a stable interface without re-aggregating on every load.
The example below exposes both `billed_cost` and `amortized_cost` so the BI tool can choose between them, and includes all `charge_category` values so users can filter further on top. Adjust the columns and `WHERE` clause to match how your team uses the data.
```sql theme={null}
CREATE OR REPLACE VIEW MY_DB.PUBLIC.monthly_costs_by_service AS
SELECT DATE_TRUNC('month', charge_period_start) AS month,
service_name,
SUM(billed_cost) AS billed,
SUM(amortized_cost) AS amortized
FROM VANTAGE_DB..daily_costs
GROUP BY month, service_name;
```
## Query Efficiency and Table Metadata
`daily_costs` is an Iceberg table partitioned by `charge_period_start`. Filtering on `charge_period_start` in your `WHERE` clause allows Snowflake to skip partitions that don't match, which significantly reduces the amount of data scanned and the warehouse credits consumed.
Always include a `charge_period_start` filter in your queries, even if you're querying other dimensions. Without it, Snowflake scans the entire table.
To see how the table is partitioned, run:
```sql theme={null}
SHOW ICEBERG TABLES LIKE 'DAILY_COSTS';
WITH iceberg_table AS (
SELECT
"current_partition_spec_id" AS current_partition_spec_id,
PARSE_JSON("partition_specs") AS partition_specs
FROM TABLE(RESULT_SCAN(LAST_QUERY_ID()))
),
current_spec AS (
SELECT
spec.value:"spec-id"::number AS spec_id,
spec.value:fields AS fields
FROM iceberg_table,
LATERAL FLATTEN(input => partition_specs) spec
WHERE spec.value:"spec-id"::number = current_partition_spec_id
)
SELECT
spec_id,
f.index + 1 AS partition_position,
f.value:name::string AS partition_name,
f.value:transform::string AS transform
FROM current_spec,
LATERAL FLATTEN(input => fields) f
ORDER BY partition_position;
```
To check when the table was last refreshed and see how data is flowing in, query the snapshot refresh history:
```sql theme={null}
SELECT
refreshed_on,
snapshot_id,
is_current_snapshot,
snapshot_summary:"added-records"::number AS added_records,
snapshot_summary:"deleted-records"::number AS deleted_records,
snapshot_summary:"total-records"::number AS total_records
FROM TABLE(INFORMATION_SCHEMA.ICEBERG_TABLE_SNAPSHOT_REFRESH_HISTORY(
TABLE_NAME => 'DAILY_COSTS'
))
ORDER BY refreshed_on DESC;
```
This tells you when Vantage last pushed data, how many records were added or replaced, and the current total row count.
## Troubleshooting
Confirm with your Vantage Customer Success representative that provisioning has completed. Once it has, the share appears in **Data Sharing** > **Shared with you** in the Snowflake UI, or in the SQL console via:
```sql theme={null}
SHOW SHARES LIKE 'VANTAGE_SHARE_%';
```
If the share still doesn't appear, double-check that the **Data Sharing Account Identifier** you provided in the Vantage console matches the account you're checking. The identifier is case-sensitive and uses the form `ORGNAME.ACCOUNTNAME`.
Three things to check:
* The role you're using has been granted access: `GRANT IMPORTED PRIVILEGES ON DATABASE VANTAGE_DB TO ROLE ;`
* You're using the right schema name. Vantage assigns the schema name when provisioning. Run `SHOW SCHEMAS IN DATABASE VANTAGE_DB;` to confirm.
* Your date filter falls inside the loaded range. Run the [date range and row counts](#discovering-your-data) introspection query to see what's actually there.
The most common reasons are:
* **You're missing the default toggle filters.** Cost Reports defaults to `charge_category IN ('Usage', 'Discounted')` and `SUM(amortized_cost)`. See [Matching Cost Report Toggles](#matching-cost-report-toggles).
* **The console applies the [two-day cost delay](/provider_data_refresh#two-day-cost-data-delay).** This delay is on by default in the Vantage console but is not applied to the share. Add `WHERE charge_period_start < DATEADD(day, -2, CURRENT_DATE())` to match.
* **You're using allocation-based Virtual Tags.** [Cost allocation tags](/tagging#cost-allocation-tags) (Business Metrics-Based, Cost-Based, Percent-Based) are not currently included in `daily_costs`. Standard Virtual Tags are.
* **You added `billed_cost` and `amortized_cost` together.** They overlap on most rows. Pick one.
Run the [date range and row counts](#discovering-your-data) introspection query to see each provider's `last_day`. If one provider lags the others, its ETL has not yet caught up. Check [Provider Data Refresh](/provider_data_refresh) for the expected cadence per provider.
`daily_costs` is partitioned by `charge_period_start`. Always include a `charge_period_start` filter in your `WHERE` clause to allow Snowflake to skip partitions that don't match. Without it, every query scans the entire table. See [Query Efficiency and Table Metadata](#query-efficiency-and-table-metadata) for more.
## Frequently Asked Questions
Data refreshes whenever Vantage's ETL completes for a billing period. The cadence matches what you see in the Vantage console for that provider. See [Provider Data Refresh](/provider_data_refresh) for details.
No. The Secure Data Share gives your account queryable access in place. The underlying data lives in Vantage-managed storage, and queries against the share consume your Snowflake compute but do not store the data on your side.
Yes. The full retention range available in your Vantage account is backfilled into the share when Snowflake Data Sharing is enabled.
You can drop the database created from the share on your side with `DROP DATABASE VANTAGE_DB;`. To have Vantage stop publishing into the share, contact [support@vantage.sh](mailto:support@vantage.sh).
Virtual Tags are applied during the Vantage ETL before data lands in `daily_costs`, so the values you see through the export already reflect them.
The [Generate cost data export](https://docs.vantage.sh/api/costs/generate-cost-data-export) API is still available for one-off pulls. Snowflake Data Sharing is the warehouse-native option for continuous query access without managing an ingestion pipeline.
Not at this time. Vantage makes all integrated providers available in the data share. Inside Snowflake, you can create your own [views](https://docs.snowflake.com/en/sql-reference/sql/create-view), [masking policies](https://docs.snowflake.com/en/sql-reference/sql/create-masking-policy), and role-based access on top of the shared database to expose only certain providers, accounts, columns, or tag values to specific users in your organization.
The share is scoped to the data available in the specific Vantage account it is provisioned for. If you want separate shares for separate managed customers, the feature can be provisioned on each underlying Vantage account.
As Vantage processes new data or reprocesses existing data (for example, when tagging changes or a cloud provider updates historical costs), those updates are reflected automatically in the share. Queries always return the latest available data, in sync with Vantage. There is nothing to truncate and reload on your side.
The share is one-way and read-only. Vantage cannot read or write into your Snowflake account, and your account cannot modify data through the share. The share is provisioned specifically for the Snowflake account identifier you supply, so you can only access your own data. Inside Snowflake, your account admin controls which roles can query the shared database using standard Snowflake RBAC (`GRANT IMPORTED PRIVILEGES ON DATABASE … TO ROLE …`).
No. The [two-day cost delay](/provider_data_refresh#two-day-cost-data-delay) that the Vantage console applies by default is not applied to the share. Vantage sends all data to Snowflake to provide the most up-to-date view possible. If you want to exclude the most recent days to match the delayed view in the Vantage console, add a date filter:
```sql theme={null}
SELECT SUM(amortized_cost) AS total
FROM VANTAGE_DB..daily_costs
WHERE charge_period_start < DATEADD(day, -2, CURRENT_DATE());
```
# SQL Billing Rules
Source: https://docs.vantage.sh/sql_billing_rules
Custom billing rules to modify cost data, apply discounts, and exclude items from MSP billing.
SQL billing rules for MSPs let you modify cost data using SQL statements to apply custom pricing adjustments, discounts, markups, and exclusions based on your customer agreements. You can write SQL queries that run against either raw AWS Cost and Usage Report (CUR) data or processed Vantage cost data.
## Need Help Writing a Rule?
AI-Assisted Billing Rules
Describe what you need in plain language. The docs assistant will draft, validate, or troubleshoot your SQL using the reference on this page.
## SQL Billing Rule Datasets
SQL billing rules comprise two different datasets:
| Dataset | Description | When to Use |
| - | - | - |
| `aws` | Raw AWS Cost and Usage Report (CUR) data. | • Modify raw AWS CUR data before processing • Access columns of data that are not available in Vantage Cost Reports • Work with Reserved Instances, Savings Plans |
| `costs` | Vantage-processed cost data. Use when inserting or adjusting normalized costs. | • Apply provider-agnostic billing rules |
Rules written against `aws` only affect how data appears in Vantage and do not modify the original CUR file.
### AWS Dataset
For the `aws` dataset, you can query a supported subset of AWS CUR columns. Use the **Available Columns** list in the billing rule editor to see all queryable fields. Custom `resource_tag_%` columns that vary by account are not supported, though a small set of predefined resource tag columns are available.
See the [AWS Data Exports Data Dictionary](https://docs.aws.amazon.com/cur/latest/userguide/data-dictionary.html) for column definitions.
Expand the section below for the full list of supported `aws` columns, organized by CUR table. Use the format `aws.table/ColumnName` in your SQL (e.g., `aws.lineItem/UnblendedCost`). Quotes around the column name are optional; the editor accepts both `aws.lineItem/UnblendedCost` and `aws."lineItem/UnblendedCost"`.
**bill**: `BillingEntity`, `BillingPeriodEndDate`, `BillingPeriodStartDate`, `BillType`, `InvoiceId`, `InvoicingEntity`, `PayerAccountId`
The `bill/BillingEntity` field identifies whether a charge is for an AWS service or an AWS Marketplace purchase. These values are defined by AWS in the [CUR Billing Details documentation](https://docs.aws.amazon.com/cur/latest/userguide/billing-columns.html).
| Value | Description |
| - | - |
| `AWS` | AWS services (non-Marketplace) |
| `AWS Marketplace` | Purchases through AWS Marketplace |
The `bill/BillType` field indicates the type of bill that the line item covers. These values are defined by AWS in the [CUR Billing Details documentation](https://docs.aws.amazon.com/cur/latest/userguide/billing-columns.html).
| Value | Description |
| - | - |
| `Anniversary` | Line items for services used during the billing month |
| `Purchase` | Line items for upfront service fees |
| `Refund` | Line items for refunds |
**costCategory**: `Project`, `Team`, `Environment`
**discount**: `BundledDiscount`, `TotalDiscount`
**identity**: `LineItemId`, `TimeInterval`
**lineItem**: `AvailabilityZone`, `BlendedCost`, `BlendedRate`, `CurrencyCode`, `LegalEntity`, `LineItemDescription`, `LineItemType`, `NetUnblendedRate`, `NormalizationFactor`, `NormalizedUsageAmount`, `Operation`, `ProductCode`, `ResourceId`, `TaxType`, `UnblendedCost`, `UnblendedRate`, `UsageAccountId`, `UsageAmount`, `UsageEndDate`, `UsageStartDate`, `UsageType`
The `lineItem/ProductCode` field contains the AWS service code for the line item. The table below lists commonly used product codes. This is not an exhaustive list. AWS product codes can change as services are added or renamed.
| Product Code | Service |
| - | - |
| `AmazonAthena` | Amazon Athena |
| `AmazonCloudFront` | Amazon CloudFront |
| `AmazonCloudWatch` | Amazon CloudWatch |
| `AmazonCognito` | Amazon Cognito |
| `AmazonDocDB` | Amazon DocumentDB |
| `AmazonDynamoDB` | Amazon DynamoDB |
| `AmazonEC2` | Amazon Elastic Compute Cloud |
| `AmazonECR` | Amazon Elastic Container Registry |
| `AmazonECS` | Amazon Elastic Container Service |
| `AmazonEFS` | Amazon Elastic File System |
| `AmazonEKS` | Amazon Elastic Kubernetes Service |
| `AmazonElastiCache` | Amazon ElastiCache |
| `AmazonEMR` | Amazon EMR |
| `AmazonES` | Amazon OpenSearch Service (legacy code) |
| `AmazonGuardDuty` | Amazon GuardDuty |
| `AmazonKinesis` | Amazon Kinesis |
| `AmazonLightsail` | Amazon Lightsail |
| `AmazonMQ` | Amazon MQ |
| `AmazonMSK` | Amazon Managed Streaming for Apache Kafka |
| `AmazonNeptune` | Amazon Neptune |
| `AmazonQuickSight` | Amazon QuickSight |
| `AmazonRDS` | Amazon Relational Database Service |
| `AmazonRedshift` | Amazon Redshift |
| `AmazonRoute53` | Amazon Route 53 |
| `AmazonS3` | Amazon Simple Storage Service |
| `AmazonSageMaker` | Amazon SageMaker |
| `AmazonSES` | Amazon Simple Email Service |
| `AmazonSNS` | Amazon Simple Notification Service |
| `AmazonSQS` | Amazon Simple Queue Service |
| `AmazonVPC` | Amazon Virtual Private Cloud |
| `AmazonWorkSpaces` | Amazon WorkSpaces |
| `AWSBackup` | AWS Backup |
| `AWSCloudTrail` | AWS CloudTrail |
| `AWSCodeBuild` | AWS CodeBuild |
| `AWSConfig` | AWS Config |
| `AWSDataTransfer` | AWS Data Transfer |
| `AWSDirectConnect` | AWS Direct Connect |
| `AWSELB` | Elastic Load Balancing |
| `AWSFargate` | AWS Fargate |
| `AWSGlue` | AWS Glue |
| `AWSKMS` | AWS Key Management Service |
| `AWSLambda` | AWS Lambda |
| `AWSSecretsManager` | AWS Secrets Manager |
| `AWSShield` | AWS Shield |
| `AWSStepFunctions` | AWS Step Functions |
| `AWSSystemsManager` | AWS Systems Manager |
| `AWSTransferFamily` | AWS Transfer Family |
| `AWSWAF` | AWS WAF |
This is not an exhaustive list. Verify product codes against the [AWS Data Exports Data Dictionary](https://docs.aws.amazon.com/cur/latest/userguide/data-dictionary.html) or the product code values in your CUR data.
The `lineItem/LineItemType` field indicates the type of charge on each CUR row. These values are defined by AWS in the [CUR Line Item Details documentation](https://docs.aws.amazon.com/cur/latest/userguide/Lineitem-columns.html#l-L).
| Value | Description |
| - | - |
| `BundledDiscount` | Usage-based discount from using another service or feature |
| `Credit` | Credits applied to your bill |
| `Discount` | Discounts applied to your usage |
| `DiscountedUsage` | Usage covered by Reserved Instance benefits |
| `Fee` | Upfront annual fee for subscriptions (e.g., All Upfront RI) |
| `Refund` | Negative charges for refunds |
| `RIFee` | Monthly recurring fee for Reserved Instance subscriptions |
| `SavingsPlanCoveredUsage` | On-demand cost covered by Savings Plans |
| `SavingsPlanNegation` | Offset cost from Savings Plans benefits |
| `SavingsPlanRecurringFee` | Recurring hourly charges for Savings Plans |
| `SavingsPlanUpfrontFee` | One-time upfront fee for Savings Plans |
| `Tax` | Taxes applied to your bill |
| `Usage` | Usage charged at on-demand rates |
**pricing**: `LeaseContractLength`, `OfferingClass`, `publicOnDemandCost`, `publicOnDemandRate`, `PurchaseOption`, `RateCode`, `RateId`, `term`, `unit`
The `pricing/term` field indicates whether usage is On-Demand or Reserved. These values are defined by AWS in the [CUR Pricing Details documentation](https://docs.aws.amazon.com/cur/latest/userguide/pricing-columns.html). This field is empty for Spot Instances, Savings Plan rows, and Marketplace purchases.
| Value | Description |
| - | - |
| `OnDemand` | Usage billed at on-demand rates |
| `Reserved` | Usage covered by Reserved Instance terms |
The `pricing/PurchaseOption` field indicates the payment model for a Reserved Instance. These values are defined by AWS in the [CUR Pricing Details documentation](https://docs.aws.amazon.com/cur/latest/userguide/pricing-columns.html).
| Value | Description |
| - | - |
| `All Upfront` | Full upfront payment, no monthly charges |
| `Partial Upfront` | Partial upfront payment with recurring monthly charges |
| `No Upfront` | No upfront payment, all recurring monthly charges |
**product**: `APICalls`, `attachmentType`, `availability`, `cacheType`, `capacitystatus`, `clockspeed`, `component`, `databaseedition`, `dataTransfer`, `dedicatedEbsThroughput`, `deploymentoption`, `description`, `destinationCountryISOCode`, `directconnectlocation`, `directorysize`, `directorytype`, `directorytypedescription`, `disableactivationconfirmationemail`, `durability`, `ebsOptimized`, `ecu`, `endpointtype`, `enhancedNetworkingSupported`, `filesystemtype`, `findingGroup`, `findingSource`, `freeUsageIncluded`, `fromLocation`, `fromRegionCode`, `fromLocationType`, `gpu`, `gpuMemory`, `group`, `groupdescription`, `insightsType`, `instance`, `instanceFamily`, `instanceSize`, `instanceType`, `instanceTypeFamily`, `integratingApi`, `integratingService`, `intelAvxAvailable`, `intelAvx2Available`, `intelTurboAvailable`, `invocation`, `licenseModel`, `location`, `locationType`, `logsDestination`, `maxIopsBurstPerformance`, `maxIopsvolume`, `maxThroughputvolume`, `memory`, `messageCountfee`, `messageType`, `networkPerformance`, `normalizationSizeFactor`, `operatingSystem`, `operation`, `originationIdType`, `osType`, `parameterType`, `physicalCores`, `physicalProcessor`, `platoClassificationType`, `pricingUnit`, `primaryplaceofuse`, `processorArchitecture`, `processorFeatures`, `ProductFamily`, `ProductName`, `productSchemaDescription`, `provisioned`, `provisioningType`, `PurchaseOption`, `purchaseterm`, `region`, `regioncode`, `replicationType`, `resourceAssessment`, `resourcePriceGroup`, `routeType`, `servicecode`, `servicename`, `singleOrDualPass`, `sizeFlex`, `sku`, `storage`, `storageclass`, `storagemedia`, `storagetype`, `tenancy`, `throughputCapacity`, `tier`, `toLocation`, `toLocationType`, `toRegionCode`, `transcodingResult`, `trialProduct`, `upfrontCommitment`, `usagetype`, `vcpu`, `videoCodec`, `videoFrameRate`, `videoQualitySetting`, `volumeType`, `workforceType`
The `product/ProductFamily` field categorizes the type of product. The table below lists commonly seen values. This is not an exhaustive list; product family values vary by service and can change over time.
| Value | Typical Services |
| - | - |
| `Alarm` | CloudWatch Alarms |
| `API Request` | S3, DynamoDB, API Gateway |
| `AWS Budgets` | AWS Budgets |
| `Bundle` | WorkSpaces, Lightsail |
| `Cache Instance` | ElastiCache |
| `Cloud Connectivity` | Direct Connect, VPN |
| `Compute` | EC2 |
| `Compute Instance` | EC2, RDS, ElastiCache, Redshift |
| `CPU Credits` | T-family burstable instances |
| `Data Transfer` | Cross-region/cross-AZ transfers, CloudFront |
| `Database Instance` | RDS, Neptune, DocumentDB |
| `DNS Query` | Route 53 |
| `Elastic IP` | EC2 Elastic IPs |
| `Fee` | Various upfront fees |
| `Hosted Zone` | Route 53 |
| `IP Address` | Public IPv4 addresses |
| `Load Balancer` | Classic Load Balancer |
| `Load Balancer-Application` | Application Load Balancer |
| `Load Balancer-Network` | Network Load Balancer |
| `Machine Learning` | SageMaker |
| `NAT Gateway` | VPC NAT Gateways |
| `Provisioned IOPS` | EBS io1/io2 IOPS |
| `Provisioned Throughput` | DynamoDB |
| `Serverless` | Lambda, Fargate |
| `Storage` | S3, EBS, Glacier |
| `Storage Snapshot` | RDS Snapshots |
| `Stopped Instance` | Stopped EC2 instances |
| `System Operation` | EBS, RDS storage operations |
This is not an exhaustive list. Product family values vary by service and can change over time. Verify against the [AWS Data Exports Data Dictionary](https://docs.aws.amazon.com/cur/latest/userguide/product-columns.html) or the values in your CUR data.
**reservation**: `AmortizedUpfrontCostForUsage`, `AmortizedUpfrontFeeForBillingPeriod`, `AvailabilityZone`, `EffectiveCost`, `EndTime`, `ModificationStatus`, `NetAmortizedUpfrontCostForUsage`, `NetAmortizedUpfrontFeeForBillingPeriod`, `NetEffectiveCost`, `NetRecurringFeeForUsage`, `NetUnusedAmortizedUpfrontFeeForBillingPeriod`, `NetUnusedRecurringFee`, `NetUpfrontValue`, `NormalizedUnitsPerReservation`, `NumberOfReservations`, `RecurringFeeForUsage`, `ReservationARN`, `StartTime`, `SubscriptionId`, `TotalReservedNormalizedUnits`, `TotalReservedUnits`, `UnitsPerReservation`, `UnusedAmortizedUpfrontFeeForBillingPeriod`, `UnusedNormalizedUnitQuantity`, `UnusedQuantity`, `UnusedRecurringFee`, `UpfrontValue`
**resourceTags**: `user:creator`, `user:name`, `user:owner`, `user:purpose`
**savingsPlan**: `AmortizedUpfrontCommitmentForBillingPeriod`, `EndTime`, `InstanceTypeFamily`, `NetAmortizedUpfrontCommitmentForBillingPeriod`, `NetRecurringCommitmentForBillingPeriod`, `NetSavingsPlanEffectiveCost`, `OfferingType`, `PaymentOption`, `PurchaseTerm`, `RecurringCommitmentForBillingPeriod`, `Region`, `SavingsPlanARN`, `SavingsPlanEffectiveCost`, `SavingsPlanRate`, `StartTime`, `TotalCommitmentToDate`, `UsedCommitment`
**splitLineItem**: `ActualUsage`, `NetSplitCost`, `NetUnusedCost`, `ParentResourceId`, `PublicOnDemandSplitCost`, `PublicOnDemandUnusedCost`, `SplitCost`, `SplitUsage`, `SplitUsageRatio`, `UnusedCost`
### Costs Dataset
The table below is the full data dictionary of all `costs` columns you can use in billing rule SQL.
| Column | Type | Description | Example Values |
| - | - | - | - |
| `amount` | decimal | Cost amount in the specified currency | `100.18` |
| `cost_category` | string | High-level cost category | `API Request`, `Compute Instance`, `Storage` |
| `cost_sub_category` | string | Detailed cost subcategory | `DataTransfer-Out-Bytes` |
| `cost_type` | string | Charge type (see [supported `cost_type` values](#supported-cost-type-values) below) | `Usage`, `SppDiscount`, `Fee` |
| `currency_code` | string | Currency code | `USD`, `EUR` |
| `date` | string | Date of the cost line item | `2026-01-01` |
| `provider` | string | Cloud provider (see [supported providers](#supported-provider-values) below) | `aws`, `azure`, `gcp`, `snowflake` |
| `provider_account_id` | string | Provider-level account ID. For AWS, the payer account. For Azure, see [Azure-Specific Field Mapping](#azure-specific-field-mapping). | `111111111111` |
| `region` | string | Region | `us-east-1`, `us-west-2` |
| `resource_account_id` | string | Resource-level account ID. For AWS, the linked/usage account. For Azure, see [Azure-Specific Field Mapping](#azure-specific-field-mapping). | `222222222222` |
| `resource_id` | string | Unique resource identifier | `arn:aws:ec2:...` |
| `service` | string | Service name (may differ from CUR product code after normalization) | `Amazon S3`, `Azure Databricks` |
| `usage_amount` | decimal | Amount of usage | `25` |
| `usage_unit` | string | Unit of measurement | `request`, `GB`, `Hours` |
#### Supported Cost Type Values
The `cost_type` column corresponds to the **Charge Type** filter in Cost Reports. Expand the section below for the exact raw `costs.cost_type` values you can use in SQL.
| Exact `costs.cost_type` Value | Definition |
| - | - |
| `adjustment` | GCP adjustments due to reasons like goodwill or SLA violations. |
| `AllocatedAmortizedDiscount` | Savings from commitment-based pricing allocated to the account consuming the commitment. Appears as a negative amount that reduces effective cost from on-demand pricing to the commitment rate. |
| `AllocatedAmortizedFee` | Savings Plans and Reserved Instances that have been amortized and allocated to an account with usage. This value can appear as a negative cost in the payer account because it is subtracted from the payer account and added to a member account. |
| `AmortizedBundledDiscount` | Amortized variant of `BundledDiscount`. Appears when amortization and discounts are both enabled. |
| `AmortizedCredit` | Credit charges that span multiple billing days, amortized across the covered period. |
| `AmortizedDiscount` | The discount portion of a commitment fee that has been spread across the billing period. Represents the difference between the gross and net amortized upfront commitment cost. |
| `AmortizedDistributorDiscount` | Amortized variant of `DistributorDiscount`. Appears when amortization and discounts are both enabled. |
| `AmortizedEdpDiscount` | Amortized variant of `EdpDiscount`. Appears when amortization and discounts are both enabled. |
| `AmortizedFee` | Amortized Savings Plan and Reserved Instance purchases. |
| `AmortizedPrivateRateDiscount` | Amortized variant of `PrivateRateDiscount`. Appears when amortization and discounts are both enabled. |
| `AmortizedPurchase` | Azure reservation and Savings Plan purchases from the amortized cost dataset. |
| `AmortizedRefund` | Refund charges that span multiple billing days, amortized across the covered period. |
| `AmortizedRiVolumeDiscount` | Amortized variant of `RiVolumeDiscount`. Appears when amortization and discounts are both enabled. |
| `AmortizedSppDiscount` | Amortized variant of `SppDiscount`. Appears when amortization and discounts are both enabled. |
| `AmortizedTax` | Tax charges that span multiple billing days, amortized across the covered period. |
| `AmortizedUsage` | Usage charges in the amortized cost view. For AWS, this can include commitment-covered usage rewritten to gross cost when blended commitment discounts are enabled. |
| `BundledDiscount` | Discounted usage for one product or service based on the usage of another product or service. |
| `COMMITTED_USAGE_DISCOUNT` | GCP Compute Engine resource-based committed use discounts. |
| `COMMITTED_USAGE_DISCOUNT_DOLLAR_BASE` | GCP spend-based committed use discounts. |
| `Credit` | Credits applied to your bill. |
| `DISCOUNT` | Discounts applied by a provider for your usage. |
| `Discount` | Discounts applied to AWS usage. |
| `DiscountedUsage` | Reserved Instance discounted spend. |
| `DistributorDiscount` | Discounts through the AWS Distribution Resellers Program. |
| `EdpDiscount` | Discounts applied through the AWS Enterprise Discount Program (EDP). |
| `Fee` | Upfront annual fees paid for subscriptions, such as the fee paid for All Upfront subscriptions. Also used for AWS Marketplace and Support fees. |
| `FeeTax` | Tax related to `Fee` charges, such as AWS Marketplace tax. |
| `FEE_UTILIZATION_OFFSET` | Credit that offsets Committed Use Discount fee SKUs when commitments are fully utilized. |
| `FREE_TIER` | Credits related to GCP Free Tier usage. |
| `Monthly Minimum Fee` | Minimum fee for Fastly. |
| `PartnerEarnedCredit` | Credits earned by Azure CSP partners for managing customer Azure resources. |
| `PrivateRateDiscount` | AWS discount based on private pricing rates. |
| `PROMOTION` | GCP promotional credits related to items like marketing promotions. |
| `Purchase` | Azure Marketplace purchases. |
| `Refund` | Negative charges indicating money refunded by a provider. |
| `regular` | GCP regular charges. |
| `RESELLER_MARGIN` | Discounts for the GCP Reseller Program. |
| `RIFee` | Monthly recurring fees for Reserved Instance subscriptions. |
| `RiVolumeDiscount` | Volume discounts for large Reserved Instance purchases. |
| `RoundingAdjustment` | Small adjustments for rounding differences in Azure billing calculations. |
| `rounding_error` | GCP cost type for rounding errors. |
| `SavingsPlanCoveredUsage` | Savings Plan discounted spend. |
| `SavingsPlanRecurringFee` | Hourly recurring charges associated with a No Upfront or Partial Upfront Savings Plan. |
| `SavingsPlanUpfrontFee` | One-time upfront fee from purchasing All Upfront or Partial Upfront Savings Plans. |
| `SppDiscount` | Solution Provider Program discount. |
| `SUBSCRIPTION_BENEFIT` | Credits earned after purchase of long-term subscriptions. |
| `SUSTAINED_USAGE_DISCOUNT` | Credit for running certain Compute Engine resources for a large portion of the month. |
| `Tax` | Taxes applied, such as sales tax. |
| `tax` | Lowercase tax value used by GCP. |
| `UnamortizedBundledDiscount` | Unamortized variant of `BundledDiscount`. Appears when amortization is disabled and discounts are included. |
| `UnamortizedCredit` | The original lump-sum credit charge before amortization. |
| `UnamortizedDiscount` | The discount portion of an unamortized commitment fee. |
| `UnamortizedDistributorDiscount` | Unamortized variant of `DistributorDiscount`. Appears when amortization is disabled and discounts are included. |
| `UnamortizedEdpDiscount` | Unamortized variant of `EdpDiscount`. Appears when amortization is disabled and discounts are included. |
| `UnamortizedFee` | The original lump-sum fee charge before amortization. For AWS, Savings Plan recurring fees can appear as unamortized when blended commitment discounts are enabled. |
| `UnamortizedPrivateRateDiscount` | Unamortized variant of `PrivateRateDiscount`. Appears when amortization is disabled and discounts are included. |
| `UnamortizedPurchase` | Azure reservation and Savings Plan purchases from the actual, unamortized cost dataset. |
| `UnamortizedRefund` | The original lump-sum refund charge before amortization. |
| `UnamortizedRiVolumeDiscount` | Unamortized variant of `RiVolumeDiscount`. Appears when amortization is disabled and discounts are included. |
| `UnamortizedSppDiscount` | Unamortized variant of `SppDiscount`. |
| `UnamortizedTax` | The original lump-sum tax charge before amortization. |
| `UnamortizedUsage` | Usage charges from the actual, unamortized cost dataset. |
| `UnusedReservation` | Cost of unused Azure reservation capacity. |
| `UnusedSavingsPlan` | Cost of unused Azure Savings Plan capacity. |
| `Usage` | Charges for usage at regular or on-demand rates. |
Each AWS discount type in the table above, such as `BundledDiscount`, `EdpDiscount`, and `PrivateRateDiscount`, can also have amortized and unamortized variants that use the raw `costs.cost_type` value with a prefix. For example, `EdpDiscount` can also appear as `AmortizedEdpDiscount` or `UnamortizedEdpDiscount`.
* **Amortized variants** such as `AmortizedEdpDiscount` appear when amortization and discounts are both enabled. These represent the discount amount on fee rows, such as Marketplace or Enterprise Support charges, that has been spread across the billing period.
* **Unamortized variants** such as `UnamortizedEdpDiscount` appear when amortization is disabled and discounts are included. These represent the discount amount on unamortized fee or commitment rows, such as Reserved Instance fees or Savings Plan recurring fees.
The AWS discount types with these variants are: `EdpDiscount`, `BundledDiscount`, `SppDiscount`, `RiVolumeDiscount`, `PrivateRateDiscount`, and `DistributorDiscount`.
#### Supported Provider Values
The `costs.provider` field uses lowercase provider codes. Use these exact values when filtering by provider in your SQL.
| Provider | Value |
| - | - |
| Anthropic | `anthropic` |
| Anyscale | `anyscale` |
| AWS | `aws` |
| Azure | `azure` |
| Azure CSP | `azure_csp` |
| Baseten | `baseten` |
| Cartesia | `cartesia` |
| CircleCI | `circle_ci` |
| ClickHouse | `clickhouse` |
| Cloudflare | `cloudflare` |
| Confluent | `confluent` |
| Coralogix | `coralogix` |
| Cursor | `cursor` |
| Databricks | `databricks` |
| Datadog | `datadog` |
| DigitalOcean | `digital_ocean` |
| Elastic | `elastic` |
| ElevenLabs | `eleven_labs` |
| Fastly | `fastly` |
| Fireworks AI | `fireworks_ai` |
| GCP | `gcp` |
| GitHub | `github` |
| Grafana | `grafana` |
| Kubernetes | `kubernetes` |
| Linode | `linode` |
| MongoDB | `mongo` |
| Modal | `modal` |
| New Relic | `new_relic` |
| OpenAI | `open_ai` |
| Oracle | `oracle` |
| PlanetScale | `planetscale` |
| Redis Cloud | `redis_cloud` |
| Snowflake | `snowflake` |
| SpaceXAI | `xai` |
| Temporal | `temporal` |
| Twilio | `twilio` |
| Vercel | `vercel` |
| Custom Provider | `custom_provider:` |
To find the exact values to use in your SQL (service names, categories, regions, etc.), check the filter dropdowns in [Cost Reports](/cost_reports#filter-cost-reports). You can also use [editable VQL](/cost_reports#edit-filters-as-vql) to inspect stored values. These vary by workspace and provider.
#### Azure-Specific Field Mapping
For Azure, `costs.provider_account_id` and `costs.resource_account_id` map to different Azure identifiers depending on your workspace configuration:
| Column | Default (most accounts) | Non-default accounts |
| - | - | - |
| `costs.resource_account_id` | Azure subscription ID | May hold another dimension (e.g., resource group) |
| `costs.provider_account_id` | Billing account ID | May hold the subscription ID |
Some workspaces use a Vantage setting that swaps these two columns. If your Azure rule is not matching the expected rows, compare the values in your rule against a known cost line (via CSV export or API) to confirm which column holds the subscription for your workspace.
#### `costs` to `aws` Column Mapping
When Vantage processes AWS CUR data, it normalizes CUR columns into the `costs` schema. If you are choosing between writing a rule against the `aws` dataset (raw CUR) or the `costs` dataset (normalized), the table below shows how the primary CUR fields map to `costs` columns.
| Vantage `costs` Column | `aws` Column | Notes |
| - | - | - |
| `amount` | `lineItem/UnblendedCost` | Primary cost field for most usage rows |
| `cost_category` | `product/productFamily` | Falls back to `"Other"`; marketplace rows use `"AWS Marketplace"` |
| `cost_sub_category` | `lineItem/UsageType` | Falls back to `"Other"` if blank |
| `cost_type` | `lineItem/LineItemType` | Mapped to Vantage charge types (e.g., `Usage`, `Fee`, `SppDiscount`) |
| `currency_code` | `lineItem/CurrencyCode` | Uppercased |
| `date` | `lineItem/UsageStartDate` | Parsed to date only |
| `provider` | (hardcoded) | Always `'aws'` for AWS data |
| `provider_account_id` | `bill/PayerAccountId` | The AWS payer (management) account |
| `region` | `product/region` | |
| `resource_account_id` | `lineItem/UsageAccountId` | The linked (member) account |
| `resource_id` | `lineItem/ResourceId` | May be rewritten for ECS or commitment rows |
| `resource_id` | `reservation/ReservationARN` | On commitment fee rows only |
| `resource_id` | `savingsPlan/SavingsPlanARN` | On Savings Plan fee rows only |
| `service` | `lineItem/ProductCode` | After service name normalization (e.g., EBS is separated from EC2) |
| `usage_amount` | `lineItem/UsageAmount` | Quantity of usage |
| `usage_unit` | `pricing/unit` | Prettified (e.g., `Hrs` becomes `Hours`) |
Some CUR columns like `pricing/publicOnDemandCost` and `pricing/publicOnDemandRate` are only available in the `aws` dataset. If your rule needs to reference on-demand pricing (e.g., for RI/SP re-rating), use the `aws` dataset instead of `costs`.
## SQL Syntax Reference
This section starts with the basic structure for SQL billing rules: which [SQL operations](#sql-operations) are supported, how to [format column names](#column-name-format), which [operators and expressions](#supported-operators) you can use, and how [Monthly Insert aggregate rules](#monthly-insert-aggregate-rules) work.
See [Troubleshooting](#troubleshooting) for common mistakes and how to fix them.
### SQL Operations
Use the following SQL operations to define billing rules:
| Operation | Description | Guide | Examples |
| - | - | - | - |
| `UPDATE` | Adjust an existing cost value, such as applying a percentage discount. | [How to construct](/sql_billing_rules#update-statements) | [Discounts and Markups](/sql_billing_rules#discounts-and-markups) |
| `DELETE` | Remove specific line-items from being billed. | [How to construct](/sql_billing_rules#delete-statements) | [Exclusions](/sql_billing_rules#exclusions) |
| `INSERT` | Add new line-items, like charges, credits, or Monthly Insert fees calculated from existing costs (`costs` dataset only). | [How to construct](/sql_billing_rules#insert-statements) | [Insert Line Items](/sql_billing_rules#insert-line-items) |
### Column Name Format
All column references must be fully qualified with the dataset name:
* **`costs` dataset**: Use `costs.column_name` format (e.g., `costs.amount`, `costs.service`)
* **`aws` dataset**: Use `aws.table/ColumnName` format (e.g., `aws.lineItem/UnblendedCost`, `aws.bill/BillingEntity`)
### Supported Operators
The following operators and expressions are supported in `WHERE` clauses and `SET` assignments:
| Operator | Description | Example |
| - | - | - |
| `=` | Equal to | `costs.provider = 'aws'` |
| `!=` or `<>` | Not equal to | `costs.cost_type != 'Credit'` |
| `>`, `<`, `>=`, `<=` | Comparison | `costs.amount >= 100` |
| `IN (...)` | Matches any value in a list. Use this instead of chaining `OR` with bare values — see [Troubleshooting](#additional-troubleshooting). | `costs.service IN ('Amazon S3', 'AWS Lambda')` |
| `NOT IN (...)` | Does not match any value in a list | `costs.cost_type NOT IN ('Credit', 'Tax')` |
| `LIKE` | Case-sensitive pattern match using `%` as a wildcard. Works on string fields that look numeric, such as account IDs. | `costs.service LIKE 'Amazon%'` (starts with), `costs.service LIKE '%S3'` (ends with), `aws.lineItem/UsageAccountId LIKE '%123456%'` (contains) |
| `NOT LIKE` | Case-sensitive pattern exclusion | `costs.resource_id NOT LIKE '%reservationorders%'` |
| `ILIKE` | Case-insensitive version of `LIKE`. Same `%` wildcard. Also works on numeric-looking strings. | `aws.lineItem/LineItemDescription ILIKE '%enterprise discount%'` |
| `NOT ILIKE` | Case-insensitive pattern exclusion | `aws.product/ProductName NOT ILIKE '%free%'` |
| `AND` | Both conditions must be true | `costs.provider = 'aws' AND costs.service = 'Amazon S3'` |
| `OR` | Either condition can be true | `costs.cost_type = 'Credit' OR costs.cost_type = 'Tax'` |
| `*` | Multiplication | `costs.amount = costs.amount * 0.90` |
| `\|\|` | String concatenation | `aws.savingsPlan/SavingsPlanARN \|\| aws.lineItem/UsageAccountId` |
| `LOWER()` | Lowercase a string before comparing or assigning it | `LOWER(costs.service) = 'amazonsns'` |
| `()` | Grouping | `(costs.service LIKE 'Amazon%' OR costs.service LIKE 'AWS%') AND costs.cost_type = 'Usage'` |
The following are **not supported** and will cause a validation error: standalone `SELECT` statements, `INSERT INTO aws`, subqueries, JOINs, CTEs (`WITH`), `LIMIT`, `ORDER BY`, division (`/`), `BETWEEN`, unsupported SQL functions, and unqualified column names (every column must include the dataset prefix, e.g., `costs.amount`). `SELECT`, aggregate functions, `GROUP BY`, `HAVING`, and `CASE WHEN` are supported only in [Monthly Insert aggregate rules](#monthly-insert-aggregate-rules).
You can include leading SQL comments before the rule statement. Both `--` line comments and `/* */` block comments are supported.
### Monthly Insert Aggregate Rules
Monthly Insert aggregate rules use `INSERT INTO costs ... SELECT ... FROM costs` to calculate a value from existing cost rows and insert a new monthly cost row. Use them when the rule needs the total of a set of costs, such as a management fee, surcharge, or tiered support fee.
These rules run after the other billing rule stages have processed. They read from the transformed `costs` dataset, so prior markups, discounts, inserted charges, and exclusions can change the total that the aggregate rule sees. See [Billing Rule Execution Order](/partners#billing-rule-execution-order) for the full stage model.
```sql Monthly Insert Basic Structure theme={null}
INSERT INTO costs (amount, service, cost_category, cost_sub_category, cost_type)
SELECT
SUM(costs.amount) * 0.10,
'MSP Management Fee',
'Management Fee',
'Management Fee',
'Fee'
FROM costs
WHERE costs.provider = 'aws'
```
Supported aggregate expressions include `SUM()`, `AVG()`, `MIN()`, `MAX()`, and `COUNT()`. You can use `CASE WHEN` inside the `SELECT` to define conditional logic, and you can use `GROUP BY` and `HAVING` when the inserted rows need to be grouped.
A Monthly Insert aggregate rule must include at least one aggregate function in the `SELECT`. A rule without one is rejected, since an `INSERT ... SELECT` that does not aggregate is likely not the calculation you intended.
Monthly Insert aggregate rules are available only with the `costs` dataset. Use `INSERT INTO costs ... SELECT ... FROM costs`; do not use `INSERT INTO aws` or a standalone `SELECT`.
#### Cost Settings
The **Cost Settings** dropdown appears on SQL billing rules, but it only affects Monthly Insert aggregate rules that calculate from existing `costs` rows. Changing these settings on row-level `UPDATE`, `DELETE`, or fixed `VALUES` INSERT rules does not change how those rules run.
For Monthly Insert aggregate rules, Cost Settings control which source rows are available to the aggregate calculation before your SQL `WHERE` clause is applied:
| Setting | Default | What it controls |
| - | - | - |
| Credits | Included | Whether credit cost types are included in the source rows. |
| Discounts | Included | Whether discount cost types are included in the source rows. |
| Refunds | Included | Whether refund cost types are included in the source rows. |
| Taxes | Included | Whether tax cost types are included in the source rows. |
| Amortization | Disabled | Whether the source rows use amortized cost types instead of non-amortized cost types. |
Cost Settings and your SQL filters work together. For example, if **Credits** are excluded in Cost Settings, credit rows are not part of `SUM(costs.amount)` even if the SQL does not explicitly filter them out. If amortization is disabled, one-time upfront charges, such as upfront Reserved Instance and Savings Plan fees, are included as they appear.
**Examples:**
* If your rule calculates `SUM(costs.amount) * 0.10` and **Credits** are excluded, the 10% fee is calculated before credits reduce the total.
* If **Taxes** are included, tax rows are part of the total unless your SQL also filters them out, such as `AND costs.cost_type != 'Tax'`.
* If **Amortization** is disabled, a one-time upfront Reserved Instance or Savings Plan fee can be included in the month it appears. If **Amortization** is enabled, the fee is calculated from amortized cost rows instead.
#### Monthly Date Behavior
When a Monthly Insert aggregate rule omits the `date` column, Vantage derives the date from the source cost rows and creates one inserted row for each month of qualifying data. For a single-month period, this produces one row. If the source costs span multiple months, the rule produces one row per month.
The range of months a rule can produce is bounded by the rule's **Start Date** and **End Date**, which you set in the rule configuration rather than in the SQL. Use those fields to scope the rule to a specific period.
**Examples:**
* If the qualifying costs are all from January, the rule inserts one January fee row.
* If the qualifying costs include January and February rows, the rule inserts one January fee row and one February fee row.
* If you set the rule's Start Date and End Date to a single month, the rule inserts a row only for that month.
Do not use a literal `date` value in a Monthly Insert aggregate rule, such as `'2026-01-01'`. Vantage derives monthly dates from the source rows so the inserted charge aligns with the month being summed.
## How to Construct SQL Statements
Step-by-step guides for building [UPDATE](#update-statements), [DELETE](#delete-statements), and [INSERT](#insert-statements) statements.
### UPDATE Statements
```sql UPDATE Basic Structure theme={null}
UPDATE [dataset]
SET [column] = [new_value]
WHERE [condition]
```
Choose your dataset (`costs` or `aws`).
```sql theme={null}
UPDATE costs
```
Use `SET` to define the new value. You can update any column from the [costs data dictionary](#costs-dataset) or [AWS column list](#aws-dataset), not just `amount`.
```sql theme={null}
UPDATE costs
SET costs.amount = costs.amount * 0.90
```
Use `WHERE` to specify which rows to modify.
```sql theme={null}
UPDATE costs
SET costs.amount = costs.amount * 0.90
WHERE costs.service = 'Virtual Machines'
```
**Common patterns:**
* **Apply discount**: `SET costs.amount = costs.amount * 0.90` (10% discount)
* **Apply markup**: `SET costs.amount = costs.amount * 1.15` (15% markup)
* **Set fixed amount**: `SET costs.amount = 100.00`
See [Discounts and Markups](#discounts-and-markups) and [Reserved Instance and Savings Plan Adjustments](#reserved-instance-and-savings-plan-adjustments) for detailed UPDATE examples.
### DELETE Statements
```sql DELETE Basic Structure theme={null}
DELETE FROM [dataset]
WHERE [condition]
```
Choose your dataset (`costs` or `aws`).
```sql theme={null}
DELETE FROM costs
```
Use `WHERE` to specify which rows to remove.
```sql theme={null}
DELETE FROM costs
WHERE costs.cost_type = 'SppDiscount'
```
**Common patterns:**
* **Remove by service**: `WHERE costs.service LIKE 'AWS Support%'`
* **Remove by cost type**: `WHERE costs.cost_type = 'Fee'`
* **Remove by amount**: `WHERE costs.amount < 0.01`
* **Remove by multiple conditions**: `WHERE costs.provider = 'aws' AND costs.service = 'Amazon S3'`
See [Exclusions](#exclusions) for detailed DELETE examples.
### INSERT Statements
INSERT statements can only be used with the `costs` dataset. INSERT is not supported for the `aws` dataset.
```sql INSERT Basic Structure theme={null}
INSERT INTO costs (column1, column2, column3, ...)
VALUES (value1, value2, value3, ...)
```
Use `VALUES` when adding a fixed charge or credit. Values must be static literals; you cannot reference columns or use expressions (e.g., `costs.amount * 0.10`) in the `VALUES` clause.
Use `INSERT ... SELECT` for Monthly Insert aggregate rules that calculate a value from existing costs:
```sql Monthly Insert Basic Structure theme={null}
INSERT INTO costs (amount, service, cost_category, cost_sub_category, cost_type)
SELECT
SUM(costs.amount) * 0.10,
'MSP Management Fee',
'Management Fee',
'Management Fee',
'Fee'
FROM costs
WHERE costs.provider = 'aws'
```
The `cost_type` you insert must be one of the [supported `cost_type` values](#supported-cost-type-values), and any `provider` you filter on or insert must be one of the [supported provider values](#supported-provider-values).
Use the `costs` dataset for INSERT statements.
```sql theme={null}
INSERT INTO costs
```
Specify all necessary columns.
```sql theme={null}
INSERT INTO costs (provider, service, cost_category, cost_sub_category, cost_type, amount)
```
Provide values for each column.
```sql theme={null}
INSERT INTO costs (provider, service, cost_category, cost_sub_category, cost_type, amount)
VALUES ('aws', 'One Time Charge', 'One Time Charge', 'One Time Charge', 'Usage', 100)
```
**Common patterns:**
* **Add credit**: `VALUES ('aws', 'Billing Credit', 'Billing Credit', 'Billing Credit', 'Credit', -100)`
* **Add processing fee**: `VALUES ('aws', 'Processing Fee', 'Processing Fee', 'Processing Fee', 'Fee', 5)`
* **Add percentage fee on total spend**: `SELECT SUM(costs.amount) * 0.10, ... FROM costs WHERE ...`
See [Insert Line Items](#insert-line-items) and [Monthly Insert Aggregate Rule Examples](#monthly-insert-aggregate-rule-examples) for detailed INSERT examples.
## Create SQL Billing Rules
To create a new SQL billing rule:
* From the top navigation, click **Settings**.
* From the left navigation, under **Partner Settings**, select **Billing Rules**.
* Click **New Billing Rule**, then select **Custom**.
Add the following rule details:
* **Title:** Give your rule a descriptive name.
* **Start Date/End Date:** Define the date range for which the rule should apply. Use these fields instead of date logic in your SQL. If you leave both blank, the rule applies to all billing periods (past and future). You can set only a Start Date (applies from that date forward) or only an End Date (applies up to that date).
* Select whether you want to automatically apply this billing rule to all existing and new managed accounts.
* From the **Available Columns** list, select either the AWS/`aws` or Vantage/`costs` schema. The selected schema must match the dataset in your SQL. If you write a `costs` rule but leave the schema set to `aws`, saving will fail.
* Under **Cost Fields**, view available fields and click to copy, or type any column from the [costs data dictionary](#costs-dataset) or [AWS column list](#aws-dataset) directly into the editor.
* In the SQL editor, write your SQL statement using the selected dataset and columns. The editor supports autocomplete and syntax highlighting.
* Click **Format** above the editor to auto-format your SQL with consistent indentation and line breaks.
* Click **Validate** to check your query against the selected schema before saving. Validation catches syntax errors, unsupported operations, schema mismatches (e.g., using `costs` columns against the `aws` dataset), and common issues like missing spaces before SQL keywords or multiple statements in a single rule.
* Click **Submit** to create the rule.
### After You Save a Rule
Once you submit a rule, keep the following in mind about how it is processed and how it interacts with your other rules.
* **Reprocessing:** When you save a billing rule, Vantage automatically reprocesses your cost data back to the rule's start date. If you leave the start date empty, the rule applies to your entire history, which means more data to reprocess. Reprocessing can take several hours depending on the size of the account, and saving multiple times restarts the cycle. Finalize your SQL before saving, and test after reprocessing completes to confirm the result. On Managed Accounts, `UPDATE` and `DELETE` rules contribute [Build Hours](/build_hours) for this reprocessing.
* **Rule limit:** Each workspace can define up to 20 billing rules. If you need more, contact [support@vantage.sh](mailto:support@vantage.sh). For multiple adjustments with different conditions, create separate rules.
* **Monthly Insert rules:** Aggregate `INSERT ... SELECT` rules run in the Monthly Insert stage, after line-item transform rules. This lets a rule calculate a fee from the final monthly cost set after prior markups, discounts, exclusions, or inserted charges have been applied.
* **Rule order:** Rules are applied sequentially, so order matters when multiple rules touch the same line items. Each statement operates on the data left behind by the rules before it.
For example, consider two rules that both target the same Platform Fee line item—one that sets a fixed amount and one that applies a 10% discount:
```sql Rule A — set a fixed amount theme={null}
UPDATE costs
SET costs.amount = 100
WHERE costs.service = 'Platform Fee'
```
```sql Rule B — apply a 10% discount theme={null}
UPDATE costs
SET costs.amount = costs.amount * 0.90
WHERE costs.service = 'Platform Fee'
```
The final amount depends on which rule runs first:
* **A then B:** the amount is set to `$100`, then discounted to `$90`.
* **B then A:** the amount is discounted first, then overwritten to `$100`—the discount is lost.
Reorder the rules on the Managed Account's **Billing Rules** tab to control which one wins. For the full execution-stage model and how to reorder rules on a Managed Account, see [Billing Rule Execution Order](/partners#billing-rule-execution-order).
## Example Rules
Many of the below examples are also documented in the [FinOps as Code](https://github.com/vantage-sh/finops-as-code/tree/main/sql-billing-rules) repository.
### Discounts and Markups
#### Apply a 5% Discount (AWS)
Apply a 5% discount to all cost line items, excluding credits:
```sql theme={null}
UPDATE aws
SET aws.lineItem/UnblendedCost = aws.lineItem/UnblendedCost * 0.95
WHERE aws.lineItem/LineItemType != 'Credit'
```
At this time, multiplication is supported, but not division.
#### Apply Service-Specific Markup
Apply a 5% markup to specific services:
```sql theme={null}
UPDATE costs
SET costs.amount = costs.amount * 1.05
WHERE costs.service IN ('Amazon Relational Database Service', 'AWS Lambda')
```
#### Rename a Service
Rename a service label in normalized cost data:
```sql theme={null}
UPDATE costs
SET costs.service = 'Custom Compute'
WHERE costs.provider = 'aws' AND costs.service = 'Amazon Elastic Compute Cloud - Compute'
```
#### Apply Markup by Cost Category
Apply a 10% markup to all storage costs:
```sql theme={null}
UPDATE costs
SET costs.amount = costs.amount * 1.10
WHERE costs.cost_category = 'Storage'
```
#### Reduce Costs for a Specific AWS Account
Apply a 50% cost reduction to a specific linked account:
```sql theme={null}
UPDATE aws
SET aws.lineItem/UnblendedCost = aws.lineItem/UnblendedCost * 0.50
WHERE aws.lineItem/UsageAccountId = '111111111111'
```
#### Set Credits to Zero
Zero out all credit line items:
```sql theme={null}
UPDATE costs
SET costs.amount = 0
WHERE costs.cost_type = 'Credit'
```
#### Zero Out Cost and Rate for Internal Accounts
Set both the cost and rate to zero for specific internal accounts (e.g., cost optimization or internal operations accounts):
```sql theme={null}
UPDATE aws
SET aws.lineItem/UnblendedCost = '0', aws.lineItem/UnblendedRate = '0'
WHERE aws.lineItem/UsageAccountId IN ('111111111111', '222222222222', '333333333333')
```
### Exclusions
#### Exclude SPP Discounts
Remove Solution Provider Program discounts from billing:
```sql theme={null}
DELETE FROM costs
WHERE costs.cost_type = 'SppDiscount'
```
#### Exclude Multiple SPP Discount Types
Remove both SPP and unamortized SPP discounts:
```sql theme={null}
DELETE FROM costs
WHERE costs.cost_type IN ('SppDiscount', 'UnamortizedSppDiscount')
```
#### Exclude SPP/EDP Discount Line Items (AWS)
Remove Enterprise Discount Program and Solution Provider discount or credit line items at the CUR level:
```sql theme={null}
DELETE FROM aws
WHERE aws.lineItem/LineItemType IN ('Discount', 'Credit')
AND (
aws.lineItem/LineItemDescription ILIKE '%Enterprise Discount Program%'
OR aws.lineItem/LineItemDescription ILIKE '%Solution Provider%'
)
```
#### Exclude AWS Support Products (AWS)
Remove all AWS Support product costs at the CUR level:
```sql theme={null}
DELETE FROM aws
WHERE aws.lineItem/ProductCode IN ('AWSSupportBusiness', 'AWSSupportEnterprise', 'AWSSupportDeveloper')
```
#### Exclude Support Costs
Remove AWS Business support costs from billing:
```sql theme={null}
DELETE FROM costs
WHERE costs.service = 'AWS Support (Business)'
```
#### Exclude Marketplace Costs
Remove all AWS Marketplace costs from billing:
```sql theme={null}
DELETE FROM costs
WHERE costs.cost_category = 'AWS Marketplace'
```
#### Exclude Marketplace by Billing Entity (AWS)
Remove AWS Marketplace costs at the CUR level using the billing entity field:
```sql theme={null}
DELETE FROM aws
WHERE aws.bill/BillingEntity = 'AWS Marketplace'
```
#### Exclude BundledDiscount Line Items (AWS)
Remove BundledDiscount line items from the CUR:
```sql theme={null}
DELETE FROM aws
WHERE aws.lineItem/LineItemType = 'BundledDiscount'
```
#### Remove Costs for Specific AWS Accounts
Exclude all costs from specific linked AWS accounts:
```sql theme={null}
DELETE FROM aws
WHERE aws.lineItem/UsageAccountId IN (
'111111111111',
'222222222222',
'333333333333'
)
```
Account-based exclusions must use account IDs, not account names. The AWS CUR does not include an account name column that can be used in billing rules.
#### Exclude Other Provider Items
Remove Temporal Cloud Actions from billing:
```sql theme={null}
DELETE FROM costs
WHERE costs.provider = 'temporal' AND costs.service = 'Temporal Cloud' AND costs.cost_sub_category = 'Actions'
```
### Reserved Instance and Savings Plan Adjustments
#### Unamortize Reserved Instance and Savings Plan Costs
Convert amortized Reserved Instance and Savings Plan costs back to usage-based costs. This rule sets the line item type to `Usage` when the Savings Plan or reservation does not belong to the linked account (using string concatenation to compare account IDs within ARNs):
```sql theme={null}
UPDATE aws
SET aws.lineItem/LineItemType = 'Usage'
WHERE aws.lineItem/LineItemType IN ('SavingsPlanCoveredUsage', 'DiscountedUsage')
AND aws.savingsPlan/SavingsPlanARN || aws.reservation/ReservationARN NOT LIKE '%:' || aws.lineItem/UsageAccountId || ':%'
```
#### Unamortize Savings Plans for a Specific Account
Convert Savings Plan covered usage back to on-demand for a specific account by matching the account ID within the Savings Plan ARN:
```sql theme={null}
UPDATE aws
SET aws.lineItem/LineItemType = 'Usage', aws.savingsPlan/SavingsPlanARN = NULL
WHERE aws.lineItem/LineItemType = 'SavingsPlanCoveredUsage'
AND aws.savingsPlan/SavingsPlanARN LIKE 'arn:aws:savingsplans::111111111111%'
```
#### Rerate Reserved Instance Costs to On-Demand Pricing
Replace discounted Reserved Instance costs with public on-demand pricing by copying values from the `pricing` columns. This sets both the cost and rate to their on-demand equivalents for reservations belonging to specific accounts:
```sql theme={null}
UPDATE aws
SET aws.lineItem/UnblendedCost = aws.pricing/publicOnDemandCost, aws.lineItem/UnblendedRate = aws.pricing/publicOnDemandRate
WHERE aws.lineItem/LineItemType = 'DiscountedUsage'
AND (
aws.reservation/ReservationARN LIKE '%111111111111%'
OR aws.reservation/ReservationARN LIKE '%222222222222%'
)
```
When filtering by account ID within an ARN field, use `LIKE '%account_id%'` to match the account ID substring within the full ARN string. Do not use `IN` with bare account IDs — ARN fields contain full ARN strings (e.g., `arn:aws:ec2:us-east-1:111111111111:reserved-instances/...`), so an `IN` comparison against just `'111111111111'` will never match.
#### Exclude Reservation Fees for Specific Accounts
Remove Reserved Instance fees that belong to specific internal accounts without affecting other usage on those accounts. Use `LIKE` to match the account ID within the reservation ARN:
```sql theme={null}
DELETE FROM aws
WHERE aws.lineItem/LineItemType = 'RIFee'
AND (
aws.reservation/ReservationARN LIKE '%:111111111111:%'
OR aws.reservation/ReservationARN LIKE '%:222222222222:%'
)
```
### Monthly Insert Aggregate Rule Examples
Monthly Insert aggregate rules use `INSERT INTO costs ... SELECT ... FROM costs`. They calculate from existing monthly cost rows and insert new synthetic cost rows.
#### Add a 10% Management Fee on Qualifying AWS Spend
Insert a management fee equal to 10% of AWS spend, excluding Marketplace purchases and EDP/SPP discount line items:
```sql theme={null}
INSERT INTO costs (amount, service, cost_category, cost_sub_category, cost_type)
SELECT
SUM(costs.amount) * 0.10,
'MSP Management Fee',
'Management Fee',
'Management Fee',
'Fee'
FROM costs
WHERE costs.provider = 'aws'
AND costs.cost_category NOT IN ('AWS Marketplace', 'Marketplace')
AND costs.cost_type NOT IN ('EdpDiscount', 'SppDiscount')
```
#### Add a Tiered Support Fee
Use `CASE WHEN` around `SUM()` when the fee rate changes based on the customer's total qualifying spend. This example charges 10% on the first \$10,000, 7% on the next \$70,000, and 5% above \$80,000:
```sql theme={null}
INSERT INTO costs (amount, service, cost_category, cost_sub_category, cost_type)
SELECT
CASE
WHEN SUM(costs.amount) <= 10000.00
THEN SUM(costs.amount) * 0.10
WHEN SUM(costs.amount) <= 80000.00
THEN 1000.00 + (SUM(costs.amount) - 10000.00) * 0.07
ELSE
5900.00 + (SUM(costs.amount) - 80000.00) * 0.05
END,
'Tiered Support Fee',
'Support Fee',
'Tiered',
'Fee'
FROM costs
WHERE costs.provider = 'aws'
AND costs.cost_category NOT IN ('AWS Marketplace', 'Marketplace')
```
Validate tiered rules against expected invoice totals before applying them broadly, especially when the customer has large or multi-month billing periods.
### Insert Line Items
INSERT statements can only be used with the `costs` dataset.
#### Add a Monthly Charge
Insert a flat monthly charge as a new line item:
```sql theme={null}
INSERT INTO costs (provider, service, cost_category, cost_sub_category, cost_type, amount)
VALUES ('aws', 'Platform Fee', 'Platform Fee', 'Platform Fee', 'Fee', 1100)
```
#### Add a Credit
Insert a billing credit as a negative amount:
```sql theme={null}
INSERT INTO costs (provider, service, cost_category, cost_sub_category, cost_type, amount)
VALUES ('aws', 'Billing Credit', 'Billing Credit', 'Billing Credit', 'Credit', -500)
```
#### Add a Processing Fee
Insert a processing fee for services rendered:
```sql theme={null}
INSERT INTO costs (provider, service, cost_category, cost_sub_category, cost_type, amount)
VALUES ('aws', 'Processing Fee', 'Processing Fee', 'Processing Fee', 'Fee', 3500)
```
#### Add a Support Fee with a Specific Date
Insert a support fee for a specific billing period. You can include the `date` column to specify which month the charge applies to:
```sql theme={null}
INSERT INTO costs (provider, date, service, cost_category, cost_type, amount)
VALUES ('aws', '2026-01-31', 'Support Fee', 'Support Fee', 'Fee', 5000)
```
### Azure Examples
Azure billing rules use the `costs` dataset. There is no separate Azure CUR dataset. When writing Azure rules, use `costs.provider = 'azure'` for standard Azure or `costs.provider = 'azure_csp'` for Azure CSP. These are distinct provider values, and rules must target the correct one.
#### Apply Markup to Azure Services
Apply a 10% markup to Azure Virtual Machines:
```sql theme={null}
UPDATE costs
SET costs.amount = costs.amount * 1.10
WHERE costs.provider = 'azure' AND costs.service = 'Virtual Machines'
```
#### Apply Discount Excluding Reservations (Azure)
Apply a discount to all Azure costs while excluding reservation purchases:
```sql theme={null}
UPDATE costs
SET costs.amount = costs.amount * 0.95
WHERE costs.provider = 'azure'
AND LOWER(costs.resource_id) NOT LIKE '%/providers/microsoft.capacity/reservationorders%'
```
#### Apply Markup by Azure Subscription
Apply a 10% markup to costs from a specific Azure subscription. See the [Azure-Specific Field Mapping](#azure-specific-field-mapping) section to determine whether `costs.resource_account_id` or `costs.provider_account_id` contains the subscription ID for your workspace.
```sql theme={null}
UPDATE costs
SET costs.amount = costs.amount * 1.10
WHERE costs.provider = 'azure' AND costs.resource_account_id = 'your-subscription-id'
```
#### Exclude Partner Earned Credit (Azure CSP)
Remove Partner Earned Credits from Azure CSP billing. Note the use of `azure_csp` as the provider value:
```sql theme={null}
DELETE FROM costs
WHERE costs.provider = 'azure_csp' AND costs.cost_type = 'PartnerEarnedCredit'
```
#### Apply Discount to NCE Licenses (Azure CSP)
Apply a 5% discount to New Commerce Experience (NCE) License purchases for Azure CSP:
```sql theme={null}
UPDATE costs
SET costs.amount = costs.amount * 0.95
WHERE costs.provider = 'azure_csp' AND costs.service = 'NCE License' AND costs.cost_type = 'Purchase'
```
Need help writing or debugging a rule? [Try the AI assistant at the top of this page.](#need-help-writing-a-rule)
## Troubleshooting
If a billing rule fails to save, the editor displays an error message. Below are common errors and how to resolve them.
| Error Message | Cause | Resolution |
| - | - | - |
| "Query contains disallowed keywords: ..." | The SQL uses an unsupported keyword like `LIMIT`, `JOIN`, `WITH`, or `ORDER`, or uses aggregate-only syntax outside a Monthly Insert rule | Remove the unsupported keyword, or rewrite aggregate logic as `INSERT INTO costs (...) SELECT ... FROM costs ...`. See the warning under [Supported Operators](#supported-operators) for the full list. |
| "Columns must always specify a table: ..." | A column name is missing the dataset prefix | Prefix every column with the dataset name (e.g., `costs.amount` instead of `amount`). |
| "Query contains unknown tables: ..." | The dataset name is not `aws` or `costs` | Use only `aws` or `costs` as the dataset name. |
| "Query contains unknown columns: ..." | A column name is misspelled, uses the wrong casing, or is not available for that dataset | Check the column spelling and casing. Common mistakes include `costs.currency` instead of `costs.currency_code`. |
| "Query cannot be parsed: ..." | The SQL has a syntax error | Check for missing or mismatched quotes, unmatched parentheses, missing commas between `SET` assignments, or typos in keywords. |
| "Unsupported SQL operation. Only UPDATE, INSERT, and DELETE operations are supported at this time." | Used a `SELECT` statement or other unsupported operation | Rewrite as an `UPDATE`, `DELETE`, or `INSERT` statement. |
| "Unsupported SQL operation. INSERT operations can only be performed on the 'costs' schema at this time." | Attempted `INSERT INTO aws` | Change to `INSERT INTO costs`. INSERT is only supported with the `costs` dataset. |
| "SELECT-based INSERT rules are only supported by the Monthly Insert billing rule step" | Used `INSERT ... SELECT` where Vantage cannot run it as a Monthly Insert rule | Use `INSERT INTO costs (...) SELECT ... FROM costs ...` for aggregate Monthly Insert rules, and make sure the rule uses the `costs` dataset. |
| "Monthly Insert rules must not specify a literal date column..." | Used a fixed date value in a Monthly Insert aggregate rule | Omit the `date` column and let Vantage derive monthly dates from the source cost rows. |
| "post-transform aggregate INSERT cannot reference source columns outside an aggregate function or GROUP BY clause..." | Selected a source column directly in an aggregate rule without grouping by it | Wrap the column in an aggregate function, add it to `GROUP BY`, or replace it with a constant value for the inserted row. |
| "Monthly Insert rules (INSERT ... SELECT ...) must use an aggregate function..." | The Monthly Insert rule's `SELECT` has no aggregate function | Add an aggregate function such as `SUM()`, `AVG()`, `MIN()`, `MAX()`, or `COUNT()` to the `SELECT`. |
| "Unable to parse relevant SQL statements from input." | The SQL input was empty or didn't contain a recognizable statement | Enter a complete `UPDATE`, `DELETE`, or `INSERT` statement. |
| "Selected schema doesn't match schema detected in query." | The schema selected in the **Available Columns** dropdown (e.g., `aws`) does not match the dataset used in your SQL (e.g., `costs`) | Switch the **Available Columns** dropdown to the dataset that matches your SQL before saving. |
| "Invalid UPDATE statement detected near '...'. This can happen when columns aren't prepended with schema." | A `SET` column is missing the dataset prefix | Qualify all `SET` targets with the dataset (e.g., `aws.lineItem/UnblendedCost` not `lineItem/UnblendedCost`). |
| "Title can't be blank" | The rule name field is empty | Enter a descriptive name for the rule. |
| "must be before end date" | The start date is on or after the end date | Set a start date that is earlier than the end date. |
### Additional Troubleshooting
| Symptom | Likely Cause | Resolution |
| - | - | - |
| Rule has no effect on costs | Provider value uses wrong casing (e.g., `'Azure'` instead of `'azure'`) | Provider values are case-sensitive. Always use lowercase: `'aws'`, `'azure'`, `'azure_csp'`, `'gcp'`. |
| Rule has no effect on costs | Service name doesn't match actual values | Check the **Service** filter in Cost Reports for the exact service name to use. |
| Rule deletes all rows unexpectedly | Used `OR 'value'` instead of `IN ('value1', 'value2')` | A bare string after `OR` always evaluates as true. Use `IN (...)` or write the full comparison on both sides of `OR`. |
| Rule doesn't match expected rows with ARN fields | Used `IN ('account_id')` on a Reservation ARN or Savings Plan ARN field | ARN fields contain full ARN strings. Use `LIKE '%account_id%'` to match account IDs within ARNs. |
| Azure rule filters wrong rows | Using the wrong Azure account field for your workspace's mapping | See [Azure-Specific Field Mapping](#azure-specific-field-mapping) and verify whether the subscription lives in `costs.resource_account_id` or `costs.provider_account_id` for your workspace. |
| Changes are not visible yet | Data is still reprocessing after the rule was saved | Wait for reprocessing to complete. For large accounts, this can take several hours. |
# Single Sign-On (SSO)
Source: https://docs.vantage.sh/sso
Use Vantage SSO to connect your identity provider for secure, streamlined access with Just in Time user provisioning and group mapping capabilities.
Vantage supports single sign-on (SSO) via self-service single sign-on as well as several other supported IdPs. You can use self-service SSO to connect your SAML (Security Assertion Markup Language) Identity Provider (IdP) to your Vantage account. With self-service SSO, you can use your existing credentials to authenticate and access your Vantage account. SSO streamlines the login process since users don't need to create a new account or remember another set of login credentials for Vantage.
Vantage uses Just in Time (JIT) provisioning for user provisioning. As long as a user is granted access to your IdP, the user will be provisioned an account in Vantage when they first log in.
## Self-Service SSO via SAML
Currently, Vantage supports self-service connection for SAML. If you'd like to
connect one of the other supported IdPs (e.g., Google Workspace or Windows
Active Directory), view the instructions below. If you do not see your IdP
listed, contact [Vantage Support](mailto:support@vantage.sh).
### What Is SAML SSO?
SAML is an XML-based open standard for exchanging authentication and authorization data between parties. It enables secure and standardized communication between identity providers, service providers, and users. SAML allows for seamless and secure access to web applications and services.
Before you can connect your IdP to Vantage, you will need the following:
* A valid account with a SAML IdP
* Organization Owner role access to Vantage
* Your IdP's signing certificate and sign-on URL
### Connect Your SAML IdP
From the Vantage console, navigate to the [Authentication page](https://console.vantage.sh/settings/account_identity_providers).
Click **New Connection**.
Select the **SAML** connection type.
Copy the **Single Sign-On URL** and **Audience URL** that are provided on screen. You will need both of these URLs for your IdP's configuration.
To add a logo to your connection's thumbnail, use the provided [Vantage Logo](https://s3.amazonaws.com/assets.vantage.sh/www/vantage_avatar-social.jpg).
Once you create the Vantage application within your IdP, copy the following information:
* Copy the SAML Sign-On URL provided by your IdP, then paste it into the **SAML 2.0 Endpoint** field of the Vantage SAML page.
* Copy the Signing Certificate provided by your IdP, then paste it into the **Public Certificate** field of the Vantage SAML page.
Ensure you've entered the correct credentials, then click **Create Connection**. You'll be redirected back to the [Authentication page](https://console.vantage.sh/settings/account_identity_providers), where you will be able to see your connection.
To enable the connection, switch the Active toggle to **on**. You will remain logged in to Vantage, but the next time you attempt to log in, you will be redirected to your IdP's sign-on page.
**Optional:** If you would like to set up SSO group mappings based on your existing Vantage teams, [see the SSO Group Mappings](/sso#set-up-sso-group-mapping-for-teams) instructions below.
### View Connection Details
Once your identity provider is connected, you can view connection details on the [Authentication page](https://console.vantage.sh/settings/account_identity_providers).
#### Associated Domains
The connection details include a **Domains** section that displays all domains associated with your identity provider. This section shows the email domains that are configured to use this SSO connection for authentication. When users with email addresses from these domains attempt to log in to Vantage, they will be redirected to your configured identity provider.
#### Example: Create a SAML SSO Connection with Okta
For detailed instructions, see the [Okta support
documentation](https://help.okta.com/oie/en-us/content/topics/apps/apps_app_integration_wizard_saml.htm).
Create an app integration on Okta.
For **Sign-in method**, select **SAML 2.0**. Click **Next**.
For **App Name**, enter *Vantage*.
For **App Logo**, upload the [Vantage Logo](https://s3.amazonaws.com/assets.vantage.sh/www/vantage_avatar-social.jpg), then click **Next**.
Enter the requested **Single sign on URL** (for example, `https://auth.vantage.sh/login/callback?connection=company-com`) and **Audience URI (SP Entity ID)** (for example, `urn:auth0:vantage-production:company-com`), provided on the Vantage Authentication setup page.
Set the **Application username** to **Email**.
Once the app integration is set up, copy the Okta-provided **Identity Provider Single Sign On URL** and **X.509 Certificate** back into Vantage.
To enable the connection, switch the Active toggle to on. You will remain logged in to Vantage, but the next time you attempt to log in, you will be redirected to the Okta sign-on page.
### Test Your SSO Configuration
The recommended steps for testing your SSO configuration are as follows:
Once your connection is enabled, do not close or log out of your current Vantage application session.
Open a private browser or incognito window, and visit [https://console.vantage.sh](https://console.vantage.sh).
Enter your email address. If your SSO connection is configured correctly, you will be redirected to your IdP.
Enter your login credentials. If you can complete the login, your configuration is correct.
If you experience any issues with logging in after you've enabled your connection, [contact Vantage Support](mailto:support@vantage.sh).
### Rotate Your SAML Signing Certificate
SAML signing certificates issued by your IdP have an expiration date. When a certificate is approaching expiration, you need to update the certificate in Vantage before it expires to avoid SSO login disruptions.
In your IdP, generate or obtain the new X.509 signing certificate. The certificate can be in PEM (`.pem`) or CER (`.cer`) format.
Send the updated certificate to [Vantage Support](mailto:support@vantage.sh) using a secure file transfer method.
Vantage will update the signing certificate on your connection. Once Vantage confirms the update, test the connection in a private or incognito browser window before ending your current session. See [Test Your SSO Configuration](/sso#test-your-sso-configuration) for the recommended testing steps.
SAML signing certificates are currently updated by Vantage Support rather than directly in the Vantage console. Plan your rotation before the certificate expires so there is time to update the connection and test it.
Set a calendar reminder before your IdP signing certificate's expiration date to avoid SSO login disruptions.
### Disconnect Your IdP
If you ever need to disconnect your IdP from Vantage:
Navigate to the [Authentication page](https://console.vantage.sh/settings/account_identity_providers).
To *disable* your connection, switch the **Active** toggle off. To *permanently remove* your IdP, click the **Delete** button.
After disabling/removing the connection, you will be able to log in to the app with your original Vantage login credentials.
## Set Up Other IdPs
If you do not see your IdP listed, please contact [Vantage
Support](mailto:support@vantage.sh).
### Authenticate with Azure AD
The following instructions are based on the [Microsoft
documentation](https://learn.microsoft.com/en-us/azure/active-directory/develop/quickstart-register-app).
#### Step 1 - Obtain Your Primary Domain from Microsoft Entra ID
Log in to the Azure portal.
Navigate to **Microsoft Entra ID**.
On the **Overview** screen, copy the **Primary domain** to use in the last step.
#### Step 2 - Register an OAuth Application with Azure
From the Azure portal, navigate to **App registrations**, then click **New registration**.
Enter a name for your app (e.g., *Vantage*).
Set the **Supported account types** option to the appropriate setting for your organization.
For **Redirect URI**, select **Web** and enter `https://auth.vantage.sh/login/callback`.
Click **Register**.
Once the app registration is complete, copy the **Application (client) ID** displayed on the app's **Overview** page to send to Vantage.
#### Step 3 - Generate a Client Secret
On the left navigation, select **Certificates & secrets**.
Under the **Client secrets** tab, click **New client secret**.
Enter a description and select an expiration for the secret.
Azure client secrets have a set expiration date. If your secret expires, your SSO connection will stop working. Generate a new secret in Azure *before* the expiration date and contact [Vantage Support](mailto:support@vantage.sh) with the new secret value so the connection can be updated. See [Update Your Client Secret](/sso#update-your-azure-ad-client-secret) below.
Click **Add**.
Copy the secret's **Value**.
#### Step 4 - Add API Permissions
On the left navigation, select **API permissions**.
Select **Add a permission**.
Under the **Microsoft APIs** tab, find and select the appropriate permissions required by Vantage (e.g., `Directory.Read.All`, `User.Read`).
At the bottom, click **Add permissions**.
#### Step 5 - Grant Admin Consent (If Required)
Still under **API permissions**, you may see a section for **Grant admin consent for \{your domain}**.
Click **Grant admin consent**, and follow the prompts.
#### Step 6 - Add Credentials to Vantage
Navigate to the [**Authentication screen**](https://console.vantage.sh/settings/account_identity_providers) in Vantage.
Select **AzureAD**.
Under **Step 2**, enter the following information:
* **Primary Domain**: The value you obtained in step 1. *Ensure you enter only the domain name (e.g., `yourcompany.com`). Do not include `http://www`.*
* **Client ID**: The client ID you obtained in step 2.
* **Client Secret**: The secret you obtained in step 3.
Click **Configure Connection**.
After your connection is complete, if you would like to set up SSO group mappings based on your existing Vantage teams, [see the SSO Group Mappings](/sso#set-up-sso-group-mapping-for-teams) instructions below.
#### Update Your Azure AD Client Secret
The client secret you created in [Step 3](/sso#step-3---generate-a-client-secret) has an expiration date set in Azure. Unlike the Azure cost integration, SSO connection credentials are not editable through the Vantage console. To rotate your client secret:
In the Azure portal, navigate to your Vantage app registration, then go to **Certificates & secrets**.
Under the **Client secrets** tab, click **New client secret** to generate a new secret. Copy the secret **Value**.
Contact [Vantage Support](mailto:support@vantage.sh) with your new client secret value. Vantage will update the connection on their end.
Once Vantage confirms the update, you can delete the old secret from your Azure app registration.
Azure AD client secrets are currently updated through Vantage Support rather than directly in the Vantage console. Generate the replacement secret before the existing one expires so you can update the connection without interrupting sign-in.
Set a calendar reminder before your client secret's expiration date to avoid SSO login disruptions.
#### Azure Government Cloud (GCC High)
The Azure AD OAuth connection uses the standard Microsoft identity endpoint (`login.microsoftonline.com`) and does not support Azure Government Cloud (GCC High) tenants. If your organization uses a GCC High tenant (`login.microsoftonline.us`), use [SAML-based SSO](/sso#self-service-sso-via-saml) instead. Configure your GCC High Microsoft Entra ID tenant as a SAML Identity Provider by creating an Enterprise Application for Vantage in your GCC High tenant.
### Authenticate with Google Workspace
The following instructions are based on the [Google
documentation](https://support.google.com/googleapi/answer/6158849).
#### Step 1 - Register an OAuth Application with Google
From the [Google API Console](https://console.developers.google.com/), select an existing project or click **CREATE PROJECT**.
From the left navigation menu, click **Credentials**.
At the top, click **CREATE CREDENTIALS** > **OAuth client ID**.
If this is your first time working with this Google project, you will have to configure your consent screen. Follow the Google documentation linked
above.
For **Application type**, select **Web application**.
Enter a **Name** for your application (e.g., *Vantage*).
For **Authorized JavaScript origins**, click **ADD URI** and enter `https://auth.vantage.sh`.
For **Authorized redirect URIs**, click **ADD URI** and enter `https://auth.vantage.sh/login/callback`.
Click **CREATE**.

#### Step 2 - Obtain Application Credentials and Contact Vantage Support
* Copy your app's **CLIENT ID** and **CLIENT SECRET**.
* Contact [Vantage Support](mailto:support@vantage.sh) for information on how to send these credentials to finish connecting with the Vantage app.
After your connection is complete, if you would like to set up SSO group mappings based on your existing Vantage teams, [see the SSO Group Mappings](/sso#set-up-sso-group-mapping-for-teams) instructions below.
### Authenticate with Rippling
Vantage is available in the [Rippling App Shop](https://www.rippling.com/app-shop/app/vntg-inc-vantage), where you can find instructions for connecting your Vantage account to Rippling.
## Set Up SSO Group Mapping for Teams
With the SSO Team Assignment feature, you can automatically assign users to Vantage teams that match the name of a corresponding SSO group.
### Prerequisites
To use the SSO Team Assignment feature, you will need to have teams already set up in Vantage. See the [Role-Based Access Control: Create Teams](/rbac#create-or-delete-teams) documentation for information on how to create teams in Vantage.
### Enable SSO Team Assignment
From the top menu of the Vantage console, click **Settings**.
On the left navigation menu, select **Authentication**. You will see your SSO connection listed.
In the **SSO Team Assignment** section of the connection, click the toggle button to enable the feature.
Vantage will match SSO groups to Vantage teams based on the case-sensitive name of the SSO group. If a team name in Vantage matches an SSO group name, the user will be placed into that team in Vantage. Users will be mapped into the appropriate teams during their next login.
After the SSO Team Assignment setting is enabled, users will be removed from
Vantage teams that are not present in the SSO groups. If you want to modify
this behavior, contact [support@vantage.sh](mailto:support@vantage.sh). The
Everyone team will remain unchanged.
### Create Custom Mappings
If your team names in Vantage *do not match* your identity provider, or you want multiple groups to be added to the same team, you can create **custom mappings**.
To create custom mappings, click the **Show** dropdown menu next to **Custom Mappings**.
In the **SSO Group Name** column, enter the group names from your SSO provider. The SSO Group Name you enter should match the corresponding name in your identity provider. Note that the mapping is case-sensitive.
From the **Vantage Team** dropdown, select the corresponding Vantage team.
Click **Add** to add additional mappings. You can configure multiple SSO group-to-team mappings and save them together.
When you are finished, click **Save**.
A user's teams are updated on every login. Vantage will also automatically
remove users from teams that are no longer present in the SSO groups list.
### Group Mapping in Okta - Enabling `groups` Attribute
Vantage uses the `groups` field in the SSO payload for matching SSO groups to Vantage teams. As long as your identity provider can pass a `groups` attribute in the payload, you can use SSO group mapping. For some providers, like Okta, you may need to enable group mapping.
To enable group mapping in Okta:
Navigate to the Vantage SAML application in Okta.
Edit your **SAML Settings**.
For **Name**, enter `groups`.
If you would like to pass through all groups, set the **Filter** to **Matches regex** with a value of `.*`.
If you need help with your specific identity provider, contact
[support@vantage.sh](mailto:support@vantage.sh).
## Troubleshooting
### SSO Group Mapping Not Working
If users are not being placed into the expected Vantage teams after logging in:
| Symptom | Possible Cause | Resolution |
| - | - | - |
| Users remain in the **Everyone** team only | IdP is not sending a `groups` attribute | Verify that your IdP is configured to pass a `groups` field in the SAML assertion or OAuth payload. For Okta, see the [Enabling `groups` Attribute](/sso#group-mapping-in-okta-enabling-groups-attribute) section above. |
| Some groups map correctly but others do not | Team name mismatch | Group mapping is **case-sensitive**. Ensure the group name in your IdP exactly matches the team name in Vantage, or create a [Custom Mapping](/sso#create-custom-mappings). |
| Users are removed from teams unexpectedly | SSO Team Assignment override | When SSO Team Assignment is enabled, users are removed from Vantage teams that are not present in their SSO groups on each login. If you need users to belong to teams that don't exist in your IdP, create matching groups in your IdP or contact [support@vantage.sh](mailto:support@vantage.sh) to adjust this behavior. |
### Login Redirects to Wrong Page or Fails
If users encounter errors when attempting to log in via SSO:
* Verify the **Single Sign-On URL** and **Audience URL** in your IdP match the values shown on the Vantage [Authentication page](https://console.vantage.sh/settings/account_identity_providers).
* For Azure AD, ensure the **Redirect URI** is set to `https://auth.vantage.sh/login/callback`.
* For Azure AD, ensure the **Client Secret** in Vantage is the secret **Value**, not the secret ID.
* If Azure AD returns a public client flow error, such as `Proof Key for Code Exchange is required for cross-origin authorization code redemption`, confirm the redirect URI is configured under **Web**, not **Single-page application** or **Mobile and desktop applications**. In **Authentication** > **Advanced settings**, ensure **Allow public client flows** is set to **No**.
* Check that the signing certificate has not expired. If it has, follow the steps in [Rotate Your SAML Signing Certificate](/sso#rotate-your-saml-signing-certificate) to update the certificate.
* If the connection was recently set up, test in a private/incognito window before logging out of your existing session. See [Test Your SSO Configuration](/sso#test-your-sso-configuration) for the recommended testing steps.
# Tagging
Source: https://docs.vantage.sh/tagging
View provider tags, create Virtual Tags, and organize costs with flexible tagging strategies across AWS, Azure, GCP, and other cloud providers in Vantage.
With tagging visibility in Vantage, you can view your *provider tags*, use Vantage's *Managed AI Tags*, and create and manage *virtual tags*.
Tags managed in your cloud providers, such as AWS, Azure, or GCP. Vantage retrieves them so you can filter and group costs using your existing provider tagging strategy.
A Vantage-managed `vntg:ai:` tag schema that normalizes AI provider billing and usage fields—like model, token type, and user—into consistent keys across every AI provider. They are applied automatically to supported AI costs, with no configuration required. See [Managed AI Tags](/managed_ai_tags).
Tags you create in Vantage using values and filters. Use them to improve tagging coverage without changing cloud infrastructure. Virtual tags can be used in [Cost Reports](/cost_reports), [Resource Reports](/active_resources#add-tag-columns), and [saved filters](/saved_filters).
## Tag Management - Provider and Virtual Tags
On the **Tags** page, you can view all tags, including both provider and virtual tags. From the top navigation, click **Settings**. On the left navigation, under **General Settings**, click **Tags**.
Four tabs are displayed: **All Tags**, **Virtual Tags**, **Preferred Tags**, and **Hidden Tags**.
On the **All Tags** tab, you can view both your provider tags (denoted by a grey tag icon) and virtual tags (denoted by a purple tag icon). Tags are listed along with any associated providers. You can also mark tags as preferred, hide or unhide a tag, and view a corresponding Cost Report filtered to that tag.
If you select a virtual tag in this view, the virtual tag page is displayed, where you can edit any existing tag criteria.
On the **Virtual Tags** tab, you can view a list of all created virtual tags. A link to the virtual tag is provided. The **Tag Values** column indicates how many values are currently associated with the virtual tag. Any associated providers are listed, as well as when the tag was created and who created the tag in Vantage. You can also mark a virtual tag as preferred from this tab.
On the **Preferred Tags** tab, you can view all tag keys that have been marked as preferred. See [Preferred Tags](/tagging#preferred-tags) for details.
On the **Hidden Tags** tab, you can view all tag keys that have been hidden. See [Hide Tags](/tagging#hide-tags) for details.
### Tag Badges
Virtual tags may display badges next to the tag name to indicate special properties:
The allocated badge (calculator icon) appears when a virtual tag contains [cost allocations](/tagging#cost-allocation-tags), such as Business Metrics-Based, Cost-Based, or Percent-Based allocation tags. This indicates that the tag is used to allocate costs across teams, projects, or other organizational entities.
The collapsed badge (merge icon) appears in two scenarios:
* On the **All Tags** tab, it shows when a provider tag has been collapsed into one or more virtual tags. Hover over the badge to see which virtual tags have collapsed this tag key.
* On the **Virtual Tags** tab, it shows when a virtual tag has [collapsed tag keys](/tagging#tag-key-collapsing) configured, meaning it merges values from other tag keys into a standardized format.

At the top of the main Tags screen, you can search for specific tags and filter for tags by provider (e.g., AWS).
### Tag Management Options
Within the tag settings, you can [hide tags](/tagging#hide-tags), mark tags as [preferred](/tagging#preferred-tags), or [view a tag on a Cost Report](/tagging#view-tags-on-a-cost-report).
#### Hide Tags
From the **Tags** page, you can hide tag keys that you don't want to appear in report filters or grouping options. This is useful for removing redundant tags or preventing other users from seeing certain tags in reports.
To hide a tag key, click the eyeball icon next to the tag on the **All Tags** tab. As soon as a tag key is hidden, the following changes occur in Vantage:
* **Hidden from report menus:** The tag key is no longer displayed in the **Filters** or **Group By** menus on reports for other Vantage users; however, users with the Organization Owner role can still manage tag visibility (i.e., unhide the tag) via the **Tags** screen.
* **Existing reports remain functional:** If a report was already filtered or grouped by the hidden tag, it will continue to work, but if you edit the report's filters, the hidden tag will no longer be available in the filter's selection list.
* **Usable in virtual tags:** Hidden tags can still be used when creating virtual tags and will appear in virtual tag filters. If a hidden tag is included in a virtual tag's filter criteria, a message is displayed next to it, indicating that it is hidden and only usable for virtual tag creation.
* **Still accessible via API:** Hidden tags remain available through [API requests](/api).
You are working to clean up your tagging and notice that teams have applied multiple variations of the same environment-related tag key across different AWS resources:
* `env`
* `environment`
* `Environment`
Because all three tags represent the same concept, having them appear separately in report filters and grouping options creates inconsistencies and makes cost analysis more difficult. You are unable to see the full view of how costs are attributed to each environment.
**You complete the following steps to hide the redundant tags:**
* You navigate to the **Tags** page in Vantage to search for and identify the different versions of the environment tag. You then hide each iteration of this tag so that you can create a new standardized version of the tag with Vantage virtual tags.

* All three hidden tags no longer appear in the Filters and Group By menus for other users.

* Existing reports that were already filtered or grouped by these tags remain functional; however, if a user edits the report's filters, they will no longer see those hidden tag variations.
* The hidden tags are still available via API requests, so any external automation using them still continues to work.
You then complete the following steps to create a virtual tag that combines the values from all the previous tag iterations:
**Option 1: Using Tag Key Collapsing (Recommended)**
The simplest approach is to use [Tag Key Collapsing](/tagging#tag-key-collapsing):
* Create a new virtual tag named `environment`
* In the **Collapsed Keys** tab, add `env`, `environment`, and `Environment` as collapsed keys
* Vantage will automatically merge all values from these tag keys into your `environment` virtual tag
This approach automatically handles all tag values without requiring you to create individual filters for each value.
**Option 2: Using Virtual Tag Values with Filters**
Alternatively, you can create a virtual tag with custom value filters:
* Create a new virtual tag named `environment` that consolidates all three variations from the AWS provider tag
* For each tag value (e.g., `production`, `development`, etc.), create a separate filter that combines that specific value from all of the previous tag keys, and repeat this for each tag value you care about. You can then use this new virtual tag within reports

As a result, your users now see only the `environment` virtual tag in their report filters, reducing confusion and keeping reports standardized. This approach helps enforce tagging consistency without you having to further educate your users on which versions of a tag key to use in reports.
#### Preferred Tags
From the **Tags** page, you can mark tag keys as "preferred" so they are sorted to the top of every tag filter, group-by menu, and tag selector across Vantage. This is useful when your organization has dozens or hundreds of tag keys, but teams regularly use the same handful—such as `environment`, `team`, or `cost-center`—for the majority of their workflows.
Marking tags as preferred requires *Organization Owner* or *Integration Owner* permissions in Vantage. See the [Role-Based Access Control](/rbac) documentation for details.
To mark a tag as preferred, click the bookmark icon next to the tag on the **All Tags** tab or the **Virtual Tags** tab. The change takes effect immediately. Once a tag key is marked as preferred, the following changes occur in Vantage:
* **Sorted to the top of tag selectors:** Preferred tags appear first in **Filters** and **Group By** menus on Cost Reports, Resource Reports, [Financial Commitment Reports](/financial_commitment_reports), Cost Recommendations, and other tag selectors across the platform, with a bookmark badge for visual identification.
* **Account-wide:** When a tag is marked as preferred, all users in the account see it sorted to the top.
* **Independent from hidden tags:** Preferred and hidden are independent settings. Hidden tags are excluded from filter menus regardless of preferred status.
There is no hard limit on the number of preferred tags; however, the feature is most useful when the list is focused. Consider marking 5–15 of your most frequently used tags as preferred.
#### View Tags on a Cost Report
From the **Tags** page, you can view a Cost Report that is filtered and grouped based on a selected tag. You can do this for both provider and virtual tags. This can help you to view any current or past costs associated with the tag. In the following visual example:
* The user searches for the `environment` virtual tag and selects to view a Cost Report for that tag.
* The Cost Report is displayed. The report is filtered by the tag's associated providers and grouped by that tag's values.
## Virtual Tags
To get started with virtual tagging, you can also view a video demo on [Vantage University](/vantage_university_cost_allocation) .
Review examples for Custom Value Tags, allocation tags, nested Virtual Tags, time-bound ownership changes, untaggable AWS resources, and Tag Key Collapsing.
### Virtual Tags vs. Saved Filters
Virtual tags can be considered foundational to the rest of the data within Vantage. They should remain fairly static, and changes should be considered delicate. These changes will flow across all data and apply to all workspaces. The most common tag keys will be items like team, cost center, and environment.
Each time you create or change a Virtual Tag, Vantage reprocesses your cost data to apply the update. This processing is measured as [Build Hours](/build_hours), a usage metric that reflects the compute your tagging configuration requires.
To build hierarchical views of tagged data, such as rolling teams up to cost centers or splitting costs by OPEX and CapEx, use [nested virtual tags](/tagging#nested-virtual-tags) and then group Cost Reports by those tags.
Saved filters can then be used in a more ad-hoc fashion to add lenses on top of base data. For instance, you could create a saved filter just for *North America* that standardizes a set of regions across providers and can be used by teams on their reports or dashboards without having to know the set of filters needed to create the list of regions. When new regions come online, it's easy to modify the saved filter to include this region.
### Custom Value Tags
With Custom Value Tags, you can create new cross-provider Virtual Tags to strengthen your tagging strategy. For example, you may have a series of resource tags, by product, across each of your providers. You can create custom tags in Vantage to combine those costs into one unique product tag for all resources in that product group.
See the [Custom Values Examples](/tagging_examples#custom-values-examples) for details.
### Cost Allocation Tags
Vantage supports three types of cost allocation for Virtual Tags, allowing you to distribute costs across teams, applications, or internal financial models:
* Use **Business-Metric Allocation** when you want costs proportionally tied to an external driver (e.g., seats, requests, revenue).
* Use **Cost-Based Allocation** when allocating proportionally based on another set of costs.
* Use **Percent-Based Allocation** when you want full manual control or have negotiated/internal ratios that don't rely on metrics or proportional drivers.
Cost-Based and Business Metrics-Based allocation types allow for *dynamic cost allocation*, which is the process of allocating costs based on another existing cost or metric. Percent-Based allocation provides manual control for negotiated or predefined internal allocations that don't rely on external metrics or proportional usage.
See the following video for an introduction to dynamic cost allocation.
#### Cost-Based Allocation Tags
With cost-based allocation tags, you can create a dynamically allocated cost structure. Select a set of input costs (e.g., all AWS costs), an existing cost tag to use for allocation (e.g., a team tag), and an output cost (e.g., a static cost, like AWS Support) that you want to be allocated the same way as your input cost.
See the [Cost-Based Allocation Example](/tagging_examples#cost-based-allocation-example) for details.
#### Business Metrics-Based Allocation Tags
With business metrics-based allocation tags, you select an existing [business metric](/business_metrics) (e.g., CPU use per product) and indicate your output cost (e.g., all GCP Compute costs) so that the allocation of the output cost mimics the percentage allocation of the existing business metric. If the business metric has [multiple label columns](/business_metrics#labeled-business-metrics), you choose which label column drives the allocation values.
See the [Business Metrics-Based Allocation Example](/tagging_examples#business-metrics-based-allocation-example) for details.
#### Percent-Based Allocation Tags
With percent-based allocation tags, you can allocate costs using fixed percentages directly within a Virtual Tag. This gives you full control over how costs are distributed across teams, applications, or internal financial models, without needing external metrics or proportional usage data.
Percent-based allocation is ideal for:
* Predefined internal chargeback models with negotiated splits
* Manual cost-splitting requirements
* Costs with fixed allocation agreements (e.g., AWS Shield, Marketplace purchases)
Vantage will multiply the matched costs by the percentage and attribute the resulting amount to the tag value.
The total allocation across all tag values must equal exactly 100%. You cannot allocate more or less than 100% of the filtered costs.
If you change the percentage allocation later, Vantage will reprocess costs for that Virtual Tag. It will then update your costs accordingly. Historical and current months will reflect the new allocation percentage once processing completes, up to the date of your Billing Period Backfill. There is no limit to the number of Percent-Based allocations for a specific tag value, but each configuration applies to your [value limit for a Virtual Tag](/tagging#virtual-tags-limit).
See the [Percent-Based Allocation Example](/tagging_examples#percent-based-allocation-example) for details.
#### Virtual Tag Allocation Rules
When configuring virtual tag values with allocation types, keep in mind the following rules and restrictions:
When creating Business Metrics-Based, Cost-Based, or Percent-Based allocation tags, you can use provider tags, virtual tags that use Custom Values, and related allocated virtual tags in the **Output Costs Filter**.
Cost-Based allocation tags can also aggregate by an allocated virtual tag key when the referenced tag belongs to the same provider-specific allocation chain.
If you reference another allocated virtual tag, it must belong to the same provider-specific allocation chain. For example, a `Sub-Team` allocated tag can reference `Team = Engineering` in AWS, but it cannot reference allocated tags from separate AWS allocation chains in the same configuration.
If you attempt to combine allocated virtual tags that belong to separate hierarchies, Vantage will prevent the configuration from being saved.
You can use existing virtual tags in the **Output Costs Filter** for Custom Value virtual tags. See the [Nested Virtual Tags](/tagging#nested-virtual-tags) section for details.
You can mix different allocation types within the same Virtual Tag Key. Tag configuration rules will be evaluated sequentially, similar to standard Virtual Tag logic.
For example, you could create a `Team` virtual tag that includes the following separate sets of values:
* Custom Value allocations for costs directly tagged with team names in your cloud provider
* Cost-Based allocations for shared infrastructure costs (e.g., allocating AWS Support fees proportionally based on team usage)
* Percent-Based allocations for fixed cost splits (e.g., allocating Marketplace purchases with pre-negotiated percentages: 60% to Infrastructure, 30% to Mobile, 10% to Data)
Vantage will evaluate these rules in order and apply the first matching allocation type to each cost.
When you filter or group by a tag that uses cost allocation (Business Metrics-Based, Cost-Based, or Percent-Based) on a Cost Report, you can use multiple allocated tags from the same provider only when they belong to the same allocation chain. An allocation chain exists when one allocated tag references another allocated tag in its **Output Costs Filter**.
This restriction exists because allocated tags redistribute costs into a separate dataset. Vantage can reconcile one allocated hierarchy per provider at a time. Using two independent allocated tags from the same provider in the same query would produce inaccurate totals.
Keep in mind the following details about this restriction:
* **Regular tags are not affected.** Provider tags and virtual tags that use only Custom Values are never restricted. You can combine as many non-allocating tags as you want in filters and groupings.
* **The restriction is per provider.** You can use one allocation chain for AWS and a different allocation chain for Azure on the same report, since each provider's data is queried independently.
* **Applies to both filters and groupings.** The restriction is enforced across both the filter criteria and group-by selections on a Cost Report. For example, if you filter by one allocated AWS chain, you cannot also group by a different allocated AWS chain.
If you need to view costs for two independent allocated tags from the same provider, create separate Cost Reports for each.
See the [Allocation-on-Allocation Example](/tagging_examples#allocation-on-allocation-example) for a concrete example.
#### Small Allocation Grouping
When using cost allocation tags (Business Metrics-Based, Cost-Based, or Percent-Based), Vantage automatically groups allocations that are individually less than 0.01% of the total allocation together under a single label: **other allocations (≤ 0.01%/each)**.
This grouping helps simplify Cost Reports by consolidating many small allocations into a single category, making it easier to focus on the larger allocations while still accounting for all costs. The grouped allocations appear with this label in:
* **Filters**: When filtering by tag values, small allocations appear as "other allocations (≤ 0.01%/each)" instead of individual tag values
* **Groupings**: When grouping by tags in Cost Reports, small allocations are aggregated under this label
* **Reports**: The label appears wherever tag values are displayed, replacing what would normally show as individual tag values like "Cost Center A" or "Team B"
For example, if you have a cost allocation tag with 20 different team allocations, and 15 of those teams each receive less than 0.01% of the total allocation, those 15 teams will be grouped together and displayed as "other allocations (≤ 0.01%/each)" in your filters, groupings, and reports. The remaining 5 teams with allocations above 0.01% will continue to appear as individual tag values.
### Virtual Tag Time Frames
By default, a Virtual Tag rule applies to all matching costs regardless of when they were incurred. With time frames, you can optionally set a start date and end date on any Virtual Tag value to control the time period during which that rule applies. This is useful when cost ownership or allocation changes over time, such as during organizational restructuring, resource handoffs between teams, or evolving chargeback models.
Time frames are available for all Virtual Tag value types: Custom Value, Business Metric, Cost-Based, and Percent-Based.
If no time frame is set on a value, the rule applies to all historical costs up to your [Billing Period Backfill](/tagging#create-virtual-tags) and future costs that match the filter criteria, which is the default behavior.
**How time frames work:**
* **Granularity:** Time frames are applied at daily granularity. Start dates are inclusive, and end dates are inclusive of the full day. For example, setting an end date of June 30 means the rule applies through the end of June 30.
* **Open-ended ranges:** You can leave the start date, end date, or both empty. An empty start date means the rule applies from the beginning of your data. An empty end date means the rule applies indefinitely into the future.
* **Multiple time frames:** You can define the same tag value name multiple times, each with different time frames and potentially different filter criteria. For example, you can define "Team A" for January–June with one set of filters and "Team A" for July onward with a different set.
* **Priority and overlapping time frames:** Virtual Tag rules are evaluated in priority order within the Virtual Tag. If a cost matches multiple rules with overlapping time periods, the value from the first matching rule is applied, consistent with the standard [Virtual Tag order](/tagging#virtual-tag-order) behavior.
* **Nested Virtual Tags:** Time frames work with [nested Virtual Tags](/tagging#nested-virtual-tags). Nested Virtual Tags respect the time frames of the Virtual Tags they reference. Note that tag resolution occurs sequentially, so upstream time frame changes may affect downstream results.
### Virtual Tags Limit
You can create up to 50 virtual tag configurations, with each tag supporting up to 100 configuration values. A warning is displayed when you approach the virtual tag limit to help you manage your virtual tag usage before reaching the limit. There is no limit to the number of time frame configurations for a specific tag value, but each time frame configuration applies to the value limit for a Virtual Tag.
If you need to increase this limit, current customers should contact [support](mailto:support@vantage.sh). Prospective customers should contact [sales](mailto:sales@vantage.sh).
### Create Virtual Tags
This feature requires *Organization Owner* permissions in Vantage. See the [Role-Based Access Control](/rbac) documentation for details. Virtual tags apply to all [workspaces](/workspaces).
**Automating Virtual Tags:** If you manage Virtual Tags using the [Vantage API](/api) or [Terraform provider](/terraform), the user associated with a personal API token must have **Owner** permissions. For [service tokens](/api/authentication#create-a-vantage-api-service-token), the token must be assigned to the **Everyone** team. Service tokens on other teams will not have the required permissions. See the [Terraform provider documentation](/terraform) for additional details on service token configuration. Individual Virtual Tag values are addressable by token, so you can [retrieve](https://docs.vantage.sh/api/virtualtags/get-virtual-tag-config-value-by-token), [update](https://docs.vantage.sh/api/virtualtags/update-virtual-tag-config-value), and [delete](https://docs.vantage.sh/api/virtualtags/delete-virtual-tag-config-value) a single value without rewriting the whole config. For managing Vantage configuration as code at scale, see the [FinOps as Code guide](/guides/finops_as_code).
From the top navigation, click **Settings**.
From the side navigation, under **General Settings**, click **Tags**.
On the **All Tags** tab, all your tags—both provider and virtual—are displayed. Click the **Virtual Tags** tab. All existing virtual tags are displayed. You can edit any existing tags from this tab. To add a new virtual tag, click **Create a Virtual Tag**.
Enter a title for the **Tag Key**.
For **Billing Period Backfill**, select a billing period (e.g., **Apr 2024**) for which the tag should be backfilled.
Enable the **Can Override** toggle if you want the virtual tag to override an existing service cost value. For example, if you create a virtual tag that conflicts with an existing provider tag, this option will override the existing provider tag key in Vantage reports.
In the **Values** section, click **+Add**. Select whether you want to create a **Custom Value**, **Business Metric**, **Cost-Based**, or **Percent-Based** value. Click through the following tabs for instructions on each value type.
For important considerations about filter restrictions, using virtual tags in filters, and mixing allocation types, see the [Virtual Tag Allocation Rules](/tagging#virtual-tag-allocation-rules) section above.
Click **Assign Custom Value**.
Enter a **Tag Value** title. Titles can contain only letters, numbers, and the following characters: `_ - & + , . : / \ @`. You cannot use saved filters to define a virtual tag value's filters.
Specify the tag value's filter criteria (i.e., **Output Cost Filters**). These filters function just like filters on Cost Reports. To build a filter in the console, see [Filter Cost Reports](/cost_reports#filter-cost-reports). For API and Terraform configurations, see [VQL for Virtual Tags](/vql_virtual_tags). You can also click **View as VQL** to [edit filter criteria as VQL](/vql#edit-vql-in-the-console) directly.
You can choose **All Providers** to apply this rule uniformly across every connected provider (for example, a single `Team = Data Engineering` rule that matches AWS, Azure, GCP, and other providers in one configuration). Before doing so, review [Best Practices for Filtering Across All Providers](#best-practices-for-filtering-across-all-providers) for guidance on performance and tag processing time.
Click **Connect a Business Metric**.
Select an existing [business metric](/business_metrics).
For a metric created with named label columns, select the required **Label** column that becomes the Virtual Tag values (e.g., choose `team` so allocation is driven by team rather than `application` or `environment`). Optionally, limit which values from that column are included; leave values empty to include all values for the selected column.
Select the **Output Costs Filter** that will be split among your tag values based on your business metric. These filters function just like filters on Cost Reports. To build a filter in the console, see [Filter Cost Reports](/cost_reports#filter-cost-reports). For API and Terraform configurations, see [VQL for Virtual Tags](/vql_virtual_tags).
You can choose **All Providers** to apply the filter uniformly across every connected provider. Before doing so, review [Best Practices for Filtering Across All Providers](#best-practices-for-filtering-across-all-providers) for guidance on performance and tag processing time.
Select **Cost-Based**.
Select an **Input Costs Filter** to specify which category of input costs to include in the allocation. These filters function just like filters on Cost Reports. To build a filter in the console, see [Filter Cost Reports](/cost_reports#filter-cost-reports). For API and Terraform configurations, see [VQL for Virtual Tags](/vql_virtual_tags#cost-based-allocation-filters).
You can choose **All Providers** to apply the input filter uniformly across every connected provider. Before doing so, review [Best Practices for Filtering Across All Providers](#best-practices-for-filtering-across-all-providers) for guidance on performance and tag processing time.
For most use cases, you should set a filter for **Charge Type = Usage** on the input filter to ensure you are matching on only usage-related costs and ignoring costs related to items like credits, taxes, fees, etc.
Select an existing cost **Tag Key**. This value can be an existing tag you have in one of your cost providers, like AWS.
Select the **Output Costs Filter** to indicate the costs that will be split among your tag values based on your input cost filter.
Select **Percent-Based**.
Specify the **Output Costs Filter** to indicate which costs will be allocated. These filters function just like filters on Cost Reports. To build a filter in the console, see [Filter Cost Reports](/cost_reports#filter-cost-reports). For API and Terraform configurations, see [VQL for Virtual Tags](/vql_virtual_tags).
You can select any filterable dimension in Vantage to identify costs you want to allocate, such as filtering for specific providers, accounts, usage categories or subcategories, resource IDs, or tags. If you are creating an allocation-on-allocation workflow, you can also reference a related allocated virtual tag from the same provider-specific allocation chain.
You can choose **All Providers** to apply the filter uniformly across every connected provider. Before doing so, review [Best Practices for Filtering Across All Providers](#best-practices-for-filtering-across-all-providers) for guidance on performance and tag processing time.
Enter a **Tag Value** title for the allocation. Titles can contain only letters, numbers, and the following characters: `_ - @ & + , . : / \`. Then, select the corresponding percentage for that tag value (between 0 and 100). The percentage will be multiplied by the matched costs and attributed to this tag value.
Above the percentage column, the **Total Allocation** indicator shows your progress toward 100%. You can add additional tag values with different percentages to allocate the same filtered costs across multiple values. The total of all percentages across tag values with the same filter must equal exactly 100%.
The percentage you set applies consistently across all time periods within the configured time frame. To apply different allocations for different time periods, use [Virtual Tag Time Frames](/tagging#virtual-tag-time-frames) to create separate rules with distinct date ranges and percentages.
Click the **Set a Time Frame** toggle. When enabled, you can enter a **Start Date** and **End Date** to define when this tag rule should apply. Both fields are optional:
* Leave the **Start Date** empty for the rule to apply from the beginning of your data.
* Leave the **End Date** empty for the rule to apply indefinitely into the future.
* Set both dates to restrict the rule to a specific time period.
If the toggle is disabled, the rule applies to all time. For more information on how time frames work, see [Virtual Tag Time Frames](/tagging#virtual-tag-time-frames).
At the top, click **Save**.
Processing tag changes usually takes under an hour. At the top of the **Virtual Tags** screen, the processing status is displayed. Processing times vary based on the number of tags and volume of data you have imported into Vantage.

#### Nested Virtual Tags
With nested virtual tags, you can use virtual tags as part of the filter criteria for other virtual tag values. The most common use case is nesting [Custom Value Virtual Tags](/tagging#custom-value-tags) so you can align cloud provider data with internal taxonomies for effective grouping and querying. Allocation-on-allocation uses the same chaining concept for allocated tags, but only when the referenced allocated tags belong to the same provider-specific allocation chain.
To reference an existing virtual tag in another virtual tag:
Create a new Custom Value, Business Metric, Cost-Based, or Percent-Based value.
Enter a name.
For the **Output Costs Filter**:
* Select a provider.
* Select **Tag**, then select an existing virtual tag key. Look for the purple tag icon with the Vantage logo to identify existing virtual tags.

#### Nested Virtual Tag Considerations
* Do not create cyclical references between virtual tags, such as Tag A referencing Tag B while Tag B references Tag A; this results in an error. A filter that references a virtual tag's own key is not a cycle; it matches the provider tag with the same key.
* If you update the filters of a virtual tag that is referenced by another virtual tag, costs are reprocessed based on the updated hierarchy.
* If you delete or rename a virtual tag that is referenced by another virtual tag, you will see a warning. If you proceed, Vantage reprocesses costs with the new configuration.
* If a nested relationship includes cost allocation, every referenced allocated tag in that relationship must stay within the same provider-specific allocation chain.

* Changing the **Billing Period Backfill** on a virtual tag does not automatically update the backfill period on any tags it references. For example, if `Tag A` references `Tag B` and you extend `Tag A`'s backfill to an earlier period, `Tag B` keeps its original backfill period. To align data across nested tags, update the backfill period on each tag individually. If any of the tags use [cost allocation](/tagging#cost-allocation-tags), update the referenced tags first and wait for processing to complete before updating the parent tag.
* You can create up to 49 nested virtual tags, since an organization is [limited to](/tagging#virtual-tags-limit) 50 distinct virtual tag keys. Because nested virtual tags are processed sequentially, increasing the number of nested values will slow down the tagging process.
See the [Nested Virtual Tags Example](/tagging_examples#nested-virtual-tags-example) for a sample tag hierarchy.
#### Virtual Tag Order
Tag values are arranged in priority order on the **Virtual Tags** screen. You can move tag values up and down in the UI to reorder them, as demonstrated in the following visual example.

When cost data is ingested into Vantage, the first value that matches the corresponding filters will be applied to that line item. In cases where filters overlap, the order of tag values within each key determines the value that is applied.
#### Best Practices for Filtering Across All Providers
As you connect more providers and add more virtual tags, the way you scope each tag affects how long Vantage takes to process tag changes and how quickly reports load. The following practices help keep virtual tags fast and predictable at scale.
For a deeper walkthrough of how Vantage processes virtual tags and how to design hierarchies, allocation chains, and filters that stay fast at scale, see the Scaling Virtual Tags guide.
Want help choosing a tag type and scope? [Try the AI assistant in the Scaling Virtual Tags guide.](/guides/scaling_tagging#need-help-designing-a-tag)
When you select **All Providers** for a virtual tag, Vantage evaluates that tag against every connected provider's billing data. If you know a tag's rules will only ever match data on one or two providers, scope the filter to those providers instead. For example, a tag that maps AWS account IDs to teams should keep its filters scoped to AWS rather than running across every provider.
When you connect a new provider, Vantage automatically includes it in any virtual tag scoped to **All Providers**. Periodically review your providerless tags and tighten the scope on any rule that doesn't make sense for the new provider's data.
Filters that use `is` and `is one of` (equality) evaluate faster than filters that use `contains`, `starts with`, `ends with`, or `flexible match`. Equality and `IN` operators compare against indexed values; partial-match operators have to inspect each value to check whether it matches the pattern, which costs more time at scale.
Use partial-match operators only when you need to handle inconsistent values, for example, when team names are spelled `teamA`, `team-a`, and `Team A` and you want a single [flexible match](/cost_reports#flexible-match) rule to cover them. If you can normalize the underlying values, for example, by using [Tag Key Collapsing](#tag-key-collapsing) or by enforcing a tagging standard upstream, prefer that over a partial-match filter.
If a tag's logic should apply to a known set of providers (e.g., only AWS and Azure), create one filter rule per provider rather than going across all providers. Each provider-scoped rule only queries that provider's data, while a single **All Providers** rule queries every connected provider regardless of whether matching costs are likely.
Within a virtual tag key, the first value whose filter matches a given cost is the value applied (see [Virtual Tag Order](#virtual-tag-order)). Place the rules that match the most cost rows higher in the list so the majority of your data matches early instead of falling through every rule. This matters more when rules are providerless: every rule below a non-match still has to be evaluated against every provider's data.
### Filter and Group by Virtual Tags
You can filter by virtual tags in Cost Reports and when creating saved filters. Virtual tags are visible along with your existing provider tags. Use the **Tag** (**Label** in GCP) filter and grouping option.

When you filter by a virtual tag in a Cost Report, you can select **All Providers** in the filter set instead of a single provider. The filter then matches the tag across every connected provider in a single rule, without having to add a separate filter set per provider.

### Delete a Virtual Tag
To delete a virtual tag, navigate to the [Tags](https://console.vantage.sh/settings/tags) page. Select the **Virtual Tags** tab and open an existing virtual tag. Click the trashcan icon at the top of the tag page. Your data will be re-tagged, excluding the deleted virtual tag, going back to the deleted tag's backfill bill period. Newly ingested data will no longer be tagged with the deleted tag.
For Percent-Based Allocation tags, when you delete the tag, the allocation will be removed, and the costs will be reprocessed to reflect their unallocated state for that Virtual Tag key. Once reprocessed, your allocation will be removed from your cost data in Cost Reports.
## Tag Key Collapsing
Tag key collapsing allows you to consolidate semantically redundant tag keys into a single standardized virtual tag. When you create a virtual tag, you can collapse both provider tags (tags from your cloud providers like AWS, Azure, or GCP) and virtual tags (existing virtual tags you've created in Vantage) into that virtual tag.
See the [Tag Key Collapsing Examples](/tagging_examples#tag-key-collapsing-examples) for step-by-step examples of standardizing inconsistent tags, cross-provider normalization, and collapsing virtual tags.
### How It Works
Vantage automatically merges values from collapsed tag keys into your virtual tag. For example, if some teams use `env` while others use `Environment`, both can be collapsed into a single virtual tag key like `environment`. Tag Key Collapsing works across all connected providers in Vantage, and there is no hard limit on the number of tag keys you can collapse into a single standardized key.
**Evaluation order**
Virtual tag value configurations (i.e., any configurations added to the **Values** tab) take precedence over collapsed keys. If a cost matches both a value configuration and a collapsed key, the value configuration's value is used. Collapsed keys apply to costs that no value configuration matches. When you remove a collapsed tag key mapping, the collapsed values will be removed up until your specified [backfill period](/tagging#create-virtual-tags) for the virtual tag.
Each collapsed key can be expanded to configure two optional settings:
* **Filter:** Restrict which costs are eligible for that collapsed key (for example, a specific provider or account). If a filter is set, only costs that match both the source tag key and the filter can contribute a value. When filters on different collapsed keys overlap, the value from the first matching key (highest in the list) is used.
* **Value prefix:** Prepend a fixed string to every value taken from that collapsed key. This is useful when you need to distinguish which source key a value came from after collapsing. For example, with a prefix of `aws:`, a value of `production` becomes `aws:production` in the virtual tag.
**Priority**
When a resource has multiple collapsed tags, the value from the **highest-priority** key is used. Priority is determined by the order in your collapsed keys list—keys higher in the list have higher priority. For example, if a resource has both `env:prod` and `environment:production`, and `environment` is ranked higher, the resource will be tagged with `production`.
Priority works similarly to [Virtual Tag Order](/tagging#virtual-tag-order) for tag values—the first matching key in your list takes precedence.
Original tag keys remain in your data; you can choose to hide them from reports using the [Hide Tags](/tagging#hide-tags) feature.
### Collapse Tag Keys
To collapse tag keys, you first need to [create a virtual tag](/tagging#create-virtual-tags) or edit an existing one.
Navigate to **Settings > Tags** and select the **Virtual Tags** tab. Click **Create a Virtual Tag** or edit an existing virtual tag.
For a new virtual tag, enter a **Tag Key** name. This will be the standardized key that all collapsed tag keys will map to. Configure **Billing Period Backfill** and **Can Override** settings as needed.
In the tag configuration section, you will see two tabs: **Values** and **Collapsed Keys**. Select the **Collapsed Keys** tab.
In the search field, search for and select the tag keys you want to collapse into this virtual tag. You can select multiple tag keys, including both provider tags and existing virtual tags. Once added, each collapsed key appears in a list.

Reorder collapsed keys as needed by clicking the **Reorder** button in the top right and dragging the keys to your desired priority order.
Keys higher in the list take precedence over keys lower in the list.
Expand a collapsed key row to configure optional settings:
1. **Add a Filter** (optional): Use the same filter builder as [Cost Reports](/cost_reports) to limit which costs are eligible for collapsing from that source tag key. For example, you can scope to one or more **Provider** values, accounts, services, or other dimensions. If you do not add a filter, Vantage merges values from that tag key everywhere it appears in your account (across providers that have that key in your data).
2. **Add a Value Prefix** (optional): Turn on the prefix toggle and enter a string to prepend to every collapsed value from that key. The prefix is applied exactly as entered, and no separator is added automatically. For example, with the prefix `team:`, the value `engineering` becomes `team:engineering`. When a prefix is active, a badge displaying the prefix appears on the collapsed key row so you can see it at a glance without expanding the row. Turning the toggle off clears the prefix. Prefixes can contain letters, numbers, spaces, and the following characters: `_ - @ & + , . : /`.
Provider icons on each collapsed key row reflect the filter when one is set; otherwise, they reflect which providers expose that tag key in your account.
If a collapsed key corresponds to a [hidden tag](/tagging#hide-tags), a visibility icon is displayed on the row indicating it is hidden from reports.
This is useful when you want to standardize tag keys across specific providers while keeping other costs separate. For example, you might collapse `team` from AWS and `Team` from Azure into a single virtual tag by adding a **Provider** filter on each collapsed key, while leaving other providers' `team` tags out of scope.
When no per-key filter is set, any new provider integration that starts reporting the same tag key can be included automatically once that key appears in your data. When you scope a collapsed key with a filter (for example **Provider** = AWS only), only costs within that filter are eligible—other providers or accounts are not included unless you add them to the filter.
If you want to add additional value configurations, click the **Values** tab.
Remember that value configurations take precedence over collapsed keys, so any cost matched by a value configuration uses that value instead of a collapsed key value.
Click **Save** at the top of the page.
## Virtual Tagging Examples
For detailed scenarios and walkthroughs, see the [Virtual Tagging Examples](/tagging_examples) page.
# Virtual Tagging Examples
Source: https://docs.vantage.sh/tagging_examples
Review practical examples for Virtual Tags, allocation tags, time-bound tagging, untaggable AWS resources, and Tag Key Collapsing in Vantage.
Use these examples to design practical tagging workflows in Vantage. The examples show how to standardize existing tags, create Virtual Tags for allocation and ownership changes, handle untaggable resources, and collapse inconsistent tag keys into a cleaner reporting model.
Map provider costs to standardized team, product, or application values.
Allocate shared or fixed costs using cost-based, business metric-based, or percent-based rules.
Model hierarchies and ownership changes without rewriting every report.
Consolidate inconsistent provider tag keys into a single reporting key.
## Custom Values Examples
The following diagram shows how a single Virtual Tag can map provider costs into standardized team values that you can use in Cost Reports.
```mermaid theme={null}
flowchart LR
providerCosts[Provider costs] --> customValueTag["Virtual Tag: Teams"]
customValueTag --> dataTeam["Tag Value: data"]
customValueTag --> mobileTeam["Tag Value: mobile"]
dataTeam --> costReports[Cost Reports]
mobileTeam --> costReports
```
### Example 1 - Cross-Provider Tagging
You want to create a tag mapping for each of your teams that maps corresponding teams with certain services and provider accounts.
You create a tag key called `Teams`.

You add the corresponding set of virtual tag values and filters:
* The `data` team tag value corresponds with a filter for all costs for GCP BigQuery and Amazon Redshift.
* The `mobile` team tag value corresponds with a filter for its related GCP projects and AWS accounts.
* You continue this pattern and create similar values with corresponding filters for your other teams.


Within Cost Reports, you can filter and group by these tag options to see costs for an individual team. In the following visual example, the Cost Report is grouped by the **team** tag, and the **mobile** and **data** values are displayed along with the other team tag values you created.

If a team's filter logic is the same across every connected provider—for example, every provider tags resources with a `team` key—you can use **All Providers** in the filter set and add a single tag rule (e.g., `Tag team is data`) instead of one rule per provider. See [Best Practices for Filtering Across All Providers](/tagging#best-practices-for-filtering-across-all-providers) before using **All Providers** for high-volume tags.
### Example 2 - Consolidate Existing Tags
You have a tagging practice established at your organization, but teams often create tags with spelling variations, tags with typos, or they create duplicate tags. For example, the `data` team has resources tagged with `data`, `Data`, and `data-prod`. This is an issue across many of your teams. You want to consolidate all these tags, across providers, into one `data` tag.
You create a tag key called `Teams` to override existing tags.

You add the corresponding set of virtual tag values and filters. In this example, all permutations of the `data` team tag are combined into one virtual tag.

Within Cost Reports, you can filter by this tag to see all costs related to the `data` team. This saves you from repeatedly filtering for every permutation of the tag. You need to filter by only one tag.

### Example 3 - Using Flexible Match to Consolidate Similar Tag Values
Your teams use inconsistent tagging conventions, resulting in multiple variations in casing and formatting. For example, Team A’s tag appears in several forms across usage data, such as `teamA`, `team_a`, `team-a`, and `Team A`. You can use the [flexible match](/cost_reports#flexible-match) filter option to match for all of these variants, as well as future variants, in a single tag configuration.
You create a tag key called `Teams` to override existing tags.

Create a virtual tag configuration for Team A. For the **Output Costs Filter**, use the `Teams` flexible match to the string `Team A`.

This will automatically match all variants of Team A, such as `teamA`, `team_a`, `team-a`, and `Team A`.
## Cost-Based Allocation Example
In your organization, teams share resources, such as RDS databases or EC2 instances, and each team consumes different percentages of these resources each month. Your organization is also charged a static support fee each month for AWS. As shown in the following diagram, you want to allocate a portion of the support fee to each team based on their proportional use of AWS resources. In this example, since the Infra team is responsible for 50% of all AWS costs, they should also be responsible for 50% of the support fee. You can create a cost-based allocation virtual tag for allocating portions of the support fee to each respective team.
The diagram shows the input AWS usage costs determining how the separate AWS Support cost is distributed across teams.
```mermaid theme={null}
flowchart TD
awsCosts[AWS usage costs] --> infra["Infra: 50 percent"]
awsCosts --> mobile["Mobile: 20 percent"]
awsCosts --> data["Data: 30 percent"]
infra --> supportAllocation[AWS Support cost allocation]
mobile --> supportAllocation
data --> supportAllocation
supportAllocation --> infraSupport[Infra receives 50 percent of support costs]
supportAllocation --> mobileSupport[Mobile receives 20 percent of support costs]
supportAllocation --> dataSupport[Data receives 30 percent of support costs]
```
You have an existing provider tag in AWS that identifies resources for your teams. This tag will be used in the next step.
* Navigate to **Settings > Tags**.
* Create a new virtual tag.
* Select the **Cost-Based** option for the tag value.
For your input cost, select **All AWS Costs**. Set an additional filter for the **Usage** charge type to filter on only usage-related costs. This filter will ignore costs related to items like credits, taxes, fees, etc.
You select your existing **teams** tag key you have in AWS that will be used for allocating costs.
In this example, since your infrastructure team is responsible for 50% of all AWS costs, the mobile team for 20%, and the data team for 30%, you can mimic this allocation across another static cost, or your output cost. Select the filters for the AWS support fee.

Once the tag is created, create a new Cost Report and add the following criteria:
* Create a filter for AWS Support costs.
* Add grouping criteria to group by your new cost-based dynamic allocation tag.
The resulting report shows how much of the support fee each team is allocated.

## Business Metrics-Based Allocation Example
You are working with your infrastructure team and want to ensure that the proportional cost of CPU time on a shared resource is allocated to the distinct cost centers that are consuming the CPU. In this example, you want each team’s portion of CPU usage billed as a corresponding percentage of the overall Namespace CPU cost. So, if Team A uses 30% of the resource’s CPU, then they should be billed a proportional percentage of the total Namespace’s costs.
The diagram shows how labeled CPU usage acts as the allocation driver for the shared Namespace costs.
```mermaid theme={null}
flowchart TD
sharedCpu[Shared resource CPU usage] --> teamAUsage[Team A CPU usage]
sharedCpu --> teamBUsage[Team B CPU usage]
teamAUsage --> namespaceCosts[Namespace costs]
teamBUsage --> namespaceCosts
namespaceCosts --> teamAAllocation[Team A allocation based on CPU share]
namespaceCosts --> teamBAllocation[Team B allocation based on CPU share]
```
To determine the cost of CPU time to allocate to each respective team, you first create a [labeled business metric](/business_metrics#labeled-business-metrics) that includes the CPU time labeled by team. Vantage then calculates the respective percentage of CPU time for each team. The labeled business metric has the following format. You can use a named label column such as `team` (or the legacy single `label` column).
```bash theme={null}
date,amount,team
2024-01-09,825,teama
2024-01-09,600,teamb
2024-01-10,500,teama
2024-01-10,200,teamb
2024-01-11,723,teama
2024-01-11,456,teamb
```
You create a new business metrics-based tag:
* Navigate to **Settings > Tags**.
* Create a new virtual tag.
* Select the **Business Metric** option for the tag value.
Search for and select the labeled business metric you just created to use for allocation. For the **Label** column, select `team` so the Virtual Tag values are driven by the team dimension. Optionally limit which team values are included, or leave values empty to include all teams.
Select the Vantage costs that will be split based on the percentages calculated in your business metric. In this case, you select a filter to show costs for the specific Namespace you want to be allocated.

Once the tag is created, create a new Cost Report and add the following criteria:
* Create a filter for the specific Namespace.
* Add grouping criteria to group by your new business metrics-based dynamic allocation tag.
The resulting report shows how much of the Namespace costs each team is allocated.

## Percent-Based Allocation Example
Your organization has negotiated fixed cost splits for Marketplace purchases. For example, at the time of purchase, you pre-agreed that Marketplace costs should be split 60% to the Infrastructure team, 30% to the Mobile team, and 10% to the Data team. You want these allocations to be automatically applied in your chargeback models.
The diagram shows a fixed split where each team receives a predefined percentage of the same Marketplace purchase costs.
```mermaid theme={null}
flowchart TD
marketplace[Marketplace purchase] --> infra["Infra team: 60 percent"]
marketplace --> mobile["Mobile team: 30 percent"]
marketplace --> data["Data team: 10 percent"]
```
You have an existing provider tag in AWS that identifies resources for your teams. This tag will be used to attribute the allocated costs.
* Navigate to **Settings > Tags**.
* Create a new virtual tag (e.g., `Marketplace Allocation`).
* In the **Values** section, click **+Add** and select **Percent-Based**.
* Specify the **Output Costs Filter** to match your Marketplace purchase costs (i.e., costs where **Marketplace purchases Only**).
* Enter the tag value name: `infra`. Titles can contain only letters, numbers, and the following characters: `_ - @ & + , . : / \`.
* Enter the percentage: **60** (between 0 and 100).
* Click **+Add a Tag Value** to add another value.
* Enter the tag value name: `mobile`.
* Enter the percentage: **30**.
* Click **+Add a Tag Value** to add another value.
* Enter the tag value name: `data`.
* Enter the percentage: **10**.
Once the tag is created, create a new Cost Report and add the following criteria:
* Create a filter for Marketplace costs.
* Add grouping criteria to group by your new percent-based allocation tag.
The resulting report shows how much of the costs each team is allocated based on your fixed percentages.
## Allocation-on-Allocation Example
Many FinOps teams need a layered chargeback model. For example, you may first allocate shared AWS costs to high-level teams, then take one team's share and allocate it again to sub-teams for a second level of accountability. Allocation-on-allocation supports this pattern when the allocated tags are part of the same provider-specific allocation chain.
In this example, your organization has three Percent-Based allocated tags for AWS:
* **`Team`** splits all AWS costs across `Engineering`, `Sales`, and `Marketing`.
* **`Sub-Team`** takes the costs already allocated to `Engineering` via the `Team` tag and splits them further across `Frontend`, `Backend`, and `Platform`.
* **`Region`** independently splits all AWS costs across `US`, `EU`, and `APAC`.
Create a Percent-Based allocated tag called `Team` that splits all AWS costs across your primary owners, such as `Engineering`, `Sales`, and `Marketing`.
Create a second Percent-Based allocated tag called `Sub-Team`.
* In the **Output Costs Filter**, select AWS costs where `Team = Engineering`.
* Add the downstream values you need, such as `Frontend`, `Backend`, and `Platform`.
* Set the percentages so the `Engineering` share is fully reallocated across those sub-teams.
Because `Sub-Team` references `Team`, both tags belong to the same AWS allocation chain. That means you can use them together on the same Cost Report.
The diagram shows why `Team` and `Sub-Team` can be used together, while an independent `Region` allocation should be analyzed separately.
```mermaid theme={null}
flowchart LR
awsCosts[AWS costs] --> teamTag["Allocated Tag: Team"]
teamTag --> subTeamTag["Allocated Tag: Sub-Team"]
awsCosts --> regionTag["Allocated Tag: Region"]
teamTag --> sameChain["Same allocation chain: can be used together"]
subTeamTag --> sameChain
regionTag --> separateChain["Separate allocation chain: use a separate Cost Report"]
```
Create a Cost Report and:
* Filter to AWS if needed.
* Group by `Team`.
* Add a second grouping for `Sub-Team`.
This lets you keep the top-level team view while drilling into the `Engineering` portion of the allocation.
If you also create another allocated tag for AWS that does not reference `Team` or `Sub-Team`, such as the separate `Region` allocation in this example, that tag belongs to a different allocation chain. Create a separate Cost Report when you need to analyze that independent AWS allocation.
## Nested Virtual Tags Example
The diagram shows how one Virtual Tag can become an input to another, creating a reporting hierarchy without duplicating every filter rule.
```mermaid theme={null}
flowchart LR
providerCosts[Provider costs] --> applicationsTag["Virtual Tag: Applications"]
applicationsTag --> businessUnitsTag["Virtual Tag: Business Units"]
businessUnitsTag --> reporting[Cost Reports by business unit and application]
```
You want to maintain a hierarchy that reflects how your business units are associated with various applications, and track costs of all your applications per business unit over time. In addition, you also want to avoid having to manually update multiple virtual tags whenever an application changes ownership to another business unit, so you aim to set up a dynamic structure that’s automatically updated.
You create a new tag called **Applications**:
* Each value represents a specific application (e.g., app1, app2, app3, app4).
* The filters for each value are AWS costs related to specific resources, like RDS or EC2 instances.

Next, you define a virtual tag for **Business Units**:
* Each value represents a specific business unit (e.g., Core Production, Core Development).
* Each filter uses the preexisting **Applications** virtual tag you just created to associate specific apps with the corresponding business unit. Notice that virtual tags are denoted by a purple Vantage tag icon to differentiate them from provider tags (gray icon).

In associated reports, you can track all costs per business unit, knowing that each business unit comprises a set of corresponding apps. If an app ever changes its associated business unit, you need to update only the filter criteria on the **Business Units** virtual tag, and all other costs will be processed accordingly. The following report is grouped both by business unit and application to show the total breakdown.

## Time-Bound Virtual Tag Example
Your organization recently went through a re-org. A shared Kubernetes cluster was owned by the Infrastructure team through June, but in July, responsibility moved to the Platform team. You want your Virtual Tags to reflect this change so that chargeback reports correctly attribute costs to the right team during each period.
The diagram shows the same cluster receiving different Virtual Tag values for different ownership periods.
```mermaid theme={null}
flowchart LR
sharedCluster[Shared Kubernetes cluster] --> juneOwner["Through June: Infrastructure"]
sharedCluster --> julyOwner["July onward: Platform"]
```
Navigate to **Settings > Tags** and create a new virtual tag called `Cluster Owner`.
Click **+Add** and select **Assign Custom Value**:
* Enter the tag value name: `infrastructure`.
* Set the **Output Costs Filter** to match the shared Kubernetes cluster (e.g., filter for the specific cluster's resource IDs or namespace).
* Click the **Set a Time Frame** toggle to enable it.
* Leave the **Start Date** empty so the rule applies from the beginning of your data.
* Set the **End Date** to `June 30` to indicate the Infrastructure team's ownership ends at the close of June.
Click **+Add** and select **Assign Custom Value** again:
* Enter the tag value name: `platform`.
* Set the same **Output Costs Filter** to match the shared Kubernetes cluster.
* Click the **Set a Time Frame** toggle to enable it.
* Set the **Start Date** to `July 1`.
* Leave the **End Date** empty so the rule applies indefinitely into the future.
Click **Save**. Vantage will process costs and apply the `infrastructure` value to costs incurred through June 30 and the `platform` value to costs from July 1 onward. In your Cost Reports, you can now group by the `Cluster Owner` tag to see accurate cost attribution across the ownership transition.
## Tagging Untaggable Resources in AWS Example
While you can apply cost and metadata tags in AWS to many resources, there are many other resources that are untaggable in AWS. Therefore, it is hard, if not almost impossible, to achieve 100% allocation in AWS alone. One quick way to first get an inventory of all untagged resources in Vantage—regardless of if they are untaggable—is to create a [Cost Report](/cost_reports) with the following filters:
* Provider is **AWS**
* Where **Not Tagged** with **Any Key**

Then, add grouping criteria for **Service** and **Category** to get a view of the types of resources that are currently untagged. If these resources are taggable in AWS, you can add cost allocation tags there and see those tags represented in Vantage when you filter or group by specific tag.
See the [AWS documentation](https://docs.aws.amazon.com/ARG/latest/userguide/supported-resources.html) for more information on what you can tag directly in AWS.

Many services and resource categories, however, cannot be tagged in AWS. You can use virtual tags to create tags in Vantage for these untaggable resources. In the following table, the *Vantage Resource Filters* column represents the filters you can set as the **Output Costs Filter** in the virtual tag configuration.
For example, if you want to tag S3 Data Transfer for specific resources, you could use the following filter criteria.

| AWS Resource | Description | Vantage Resource Filters |
| - | - | - |
| Elastic IPs | [According to AWS](https://docs.aws.amazon.com/vpc/latest/userguide/vpc-eip-overview.html), "You can tag an Elastic IP address that's allocated for use in a VPC, however, cost allocation tags are not supported." | Provider: AWS Subcategory: Amazon Virtual Private Cloud contains `inuse` |
| CloudWatch Metrics | CloudWatch Metrics involve performance data from AWS services, which are not taggable and are used for monitoring and alerting. | Provider: AWS Category: AmazonCloudWatch is Metric Further filter by resource ID |
| S3 Data Transfer | Data transferred in and out of S3 buckets, which is tracked but not taggable. | Provider: AWS Category: Amazon Simple Storage Service is Data Transfer Further filter by resource ID |
| QuickSight resources | Resources within Amazon QuickSight, such as dashboards and analyses, which do not support tagging. | Provider: AWS Service: Amazon Quicksight Optional detailed filters for Category (e.g., Business Analytics) or individual resource ID |
| CloudSearch resources | Amazon CloudSearch domains and their configurations, which are untaggable. | Provider: AWS Service: Amazon CloudSearch Optional detailed filters for Category (e.g., Data Transfer, Search Instance) or individual resource ID |
## Tag Key Collapsing Examples
The diagram shows multiple provider tag keys flowing into one standardized Virtual Tag key for consistent reporting.
```mermaid theme={null}
flowchart LR
envKey["Tag key: env"] --> environmentTag["Virtual Tag: environment"]
environmentKey["Tag key: environment"] --> environmentTag
capitalEnvironmentKey["Tag key: Environment"] --> environmentTag
environmentTag --> reports[Consistent Cost Reports]
```
### Example 1 - Standardizing Inconsistent Provider Tags
Teams often use variations of the same tag key due to different tagging conventions across your cloud providers. For example:
* `env`, `environment`, `Environment`
* `team`, `Team`, `team_name`
* `app`, `Application`, `application`
With Tag Key Collapsing, you can map all these provider tag variations to a single standardized virtual tag key (e.g., "environment") without needing to update tags in your cloud providers.
Create a new virtual tag with the key name "environment" (or your preferred standardized name).
In the **Collapsed Keys** tab, add all the variations you want to consolidate:
* `env`
* `environment`
* `Environment`
Reorder the collapsed keys so that your preferred collapsed key (for example, if you prefer `environment` over `env`) appears first in the list. This ensures that if a resource has multiple of these tags, the value from the highest-priority collapsed key (the one highest in the list) is used.
Click **Save**. Vantage will automatically merge all values from the collapsed tag keys into your standardized "environment" virtual tag. You can now filter and group by this single tag in your reports.
### Example 2 - Cross-Provider Tag Normalization
If you have the same concept tagged differently across providers (e.g., "team" in AWS and "Team" in Azure), you can collapse both provider tags into a single virtual tag key for consistent reporting across all providers.
Create a new virtual tag with the key name "team" (or your preferred standardized name).
In the **Collapsed Keys** tab, add `team` and `Team` as separate collapsed keys. Expand each row and, under **Add a Filter**, scope to the right cloud provider (for example **Provider** = AWS for `team`, and **Provider** = Azure for `Team`). Set priority if a resource could match both.
Click **Save**. Your reports will now show a consistent "team" tag across both AWS and Azure, regardless of the original tag casing in each provider.
### Example 3 - Collapsing Virtual Tags
You can collapse existing virtual tag keys into other virtual tags, allowing you to create hierarchies or consolidate multiple virtual tags into a single standardized tag. For example, you might collapse several application-related virtual tags into a single "Application" virtual tag for simplified reporting.
Create a new virtual tag with the key name "Application" (or your preferred consolidated name).
In the **Collapsed Keys** tab, add your existing application-related virtual tags:
* "app"
* "App"
* "application"
Reorder the collapsed keys to set your preferred priority order, then click **Save**. All values from the collapsed virtual tags will now appear under the single "Application" virtual tag in your reports.
# Terraform Provider
Source: https://docs.vantage.sh/terraform
Use Vantage's official Terraform provider and AWS integration module to automate cloud cost management infrastructure as code.
Vantage is an official HashiCorp partner and offers a Terraform module for getting up and running with Vantage using Infrastructure as Code (IaC). Vantage also offers a Terraform provider with several resources.
* **Vantage Terraform Integrations module for AWS**: The Vantage [Terraform Integrations module](https://registry.terraform.io/modules/vantage-sh/vantage-integration/aws/latest) is available for registered users, across all Vantage tiers, to create the primitives needed to broker a connection with AWS. With the module, you can create a Cross-Account IAM Role as well as a Cost and Usage Report (CUR).
* **Vantage Terraform provider**: The [Terraform provider](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs) comprises several Vantage resources you can create, such as Cost Reports, dashboards, etc. Use the provider to automate and manage Vantage from within your existing Terraform codebase. Organizations with IaC practices can set up, create, and sync their cost reporting structure with Vantage.
The ability to create, edit, and destroy resources is keyed to the permissions of the user associated with the API token. For Enterprise customers, [role-based access controls](/rbac) also affect these actions.
**Service Token Permissions:** When using a [service token](/api/authentication#create-a-vantage-api-service-token) with Terraform, ensure the token is assigned to the **Everyone** team. Service tokens on the Everyone team have the permissions needed for organization-level actions, including managing provider integrations, creating teams, and managing [Virtual Tags](/tagging). Service tokens assigned to other teams will receive authorization errors when attempting these operations. For personal API tokens, the user must have an **Owner** role to manage Virtual Tags and integrations.
## Vantage Terraform Integrations Module for AWS
Use the Vantage Integrations module to link your AWS and Vantage accounts. Organizations can use the module to integrate thousands of AWS accounts with Vantage. You can view the source of the module on the module's GitHub repository:
* Module file: [`main.tf`](https://github.com/vantage-sh/terraform-aws-vantage-integration/blob/main/main.tf)
* Variables for module: [`variables.tf`](https://github.com/vantage-sh/terraform-aws-vantage-integration/blob/main/variables.tf)
You can also view the module's documentation on the [Terraform Registry](https://registry.terraform.io/modules/vantage-sh/vantage-integration/aws/latest).
When you upgrade the AWS integration module, Terraform may show changes to the IAM policy managed by the module. These changes are expected when Vantage adds or removes AWS permissions needed for cost and resource ingestion. Review the module changelog and the Terraform plan, then apply the updated policy as part of the module upgrade.
For root AWS accounts, you need to provision a bucket for the Cost and Usage Report (CUR) using the `cur_bucket_name` variable. For sub-accounts, you need to link access, but you don't need to configure a CUR bucket.
When `cur_bucket_name` is set, the module manages a legacy CUR 1.0 report by default. Set `upgrade_to_cur_2 = true` to replace it with a CUR 2.0 Data Export. The module requires version 5.48.0 or newer of the HashiCorp AWS provider.
By default, the CUR bucket is provisioned in `us-east-1`. To use a different region, set the `cur_bucket_region` variable. The module supports the following CUR bucket regions:
* `ap-southeast-1`
* `eu-west-1`
* `eu-west-2`
* `us-east-1`
* `us-west-2`
Provisioning the CUR bucket in a region other than `us-east-1` requires [version 1.1.0](https://registry.terraform.io/modules/vantage-sh/vantage-integration/aws/1.1.0) or above of the AWS integration module.
The AWS provider `region` and `cur_bucket_region` must match. This keeps the S3 bucket, CUR definition, and Vantage SNS notification topic in the same region, so Vantage is notified when new CUR files are delivered.
The below example shows how to add the management (root) AWS account integration where the CUR and an S3 bucket are provisioned:
```bash expandable theme={null}
terraform {
required_version = "~> 1.0"
required_providers {
vantage = {
source = "vantage-sh/vantage"
}
aws = {
source = "hashicorp/aws"
version = ">= 5.48.0"
}
}
}
provider "vantage" {
# A Vantage API Token is needed to use this module, it is recommended to either use env var VANTAGE_API_TOKEN
# or to use a tfvars file that's not committed to the repository.
api_token = YOUR_API_TOKEN
}
provider "aws" {
region = "us-east-1"
assume_role {
role_arn = "arn:aws:iam::123456789012:role/admin-role"
}
}
module "vantage-integration" {
source = "vantage-sh/vantage-integration/aws"
# Bucket names must be globally unique. It is provisioned with private acl's
# and only accessed by Vantage via the provisioned cross account role.
cur_bucket_name = "my-company-cur-vantage"
# Must match the AWS provider region above.
cur_bucket_region = "us-east-1"
# Opt in to replacing the legacy CUR 1.0 report with CUR 2.0.
upgrade_to_cur_2 = true
}
```
The below example shows how to add a member account *without* a CUR integration. Note the `cur_bucket_name` variable is not included within the module configuration. As a result, an IAM Role is created, which Vantage can assume to ingest the cost and resource metadata that are displayed within the Vantage console. See the [Terraform documentation](https://registry.terraform.io/modules/vantage-sh/vantage-integration/aws/latest) for more details.
```bash expandable theme={null}
terraform {
required_version = "~> 1.0"
required_providers {
vantage = {
source = "vantage-sh/vantage"
}
aws = {
source = "hashicorp/aws"
version = ">= 5.48.0"
}
}
}
provider "vantage" {
# A Vantage API Token is needed to use this module, it is recommended to either use env var VANTAGE_API_TOKEN
# or to use a tfvars file that's not committed to the repository.
api_token = YOUR_API_TOKEN
}
provider "aws" {
region = "us-east-1"
assume_role {
role_arn = "arn:aws:iam::123456789012:role/admin-role"
}
}
module "vantage-integration" {
source = "vantage-sh/vantage-integration/aws"
}
```
To grant read access for [AWS Bedrock LLM Enrichment](/aws_bedrock_enrichment), extend the cross-account role using the module's `additional_inline_policies` argument. See [AWS Bedrock LLM Enrichment](/aws_bedrock_enrichment#step-3-connect-the-log-buckets-in-vantage) for the exact policy, CloudFormation template URL, and a Terraform snippet.
## Vantage Resources and Data Sources
Using the Terraform provider, you can automate Vantage resources, such as Cost Reports, via the [Vantage Write API](/api)—or the backbone of the provider.
With the Terraform provider, you can create many [resources](https://developer.hashicorp.com/terraform/language/resources), like Cost Reports, report notifications, folders, dashboards, etc. The provider also includes many [data sources](https://developer.hashicorp.com/terraform/language/data-sources) you can use to pull data from the Vantage console. See the [documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs) for details.
By using these Terraform resources, engineering teams automate cost reporting in Vantage. Below are some example use cases.
* Build Cost Reports for hundreds of teams stored in another source of truth (e.g., database or GitHub)
* Update filters as resource names or tags change
* Add new reports to team dashboards when new services are deployed
* Create teams and access grants based on teams within an identity provider (IdP)
## Terraform Import
`terraform import` is a command used in Terraform that allows you to bring existing infrastructure resources into Terraform management. This command helps integrate resources that were created outside of Terraform—such as those provisioned directly in the Vantage console or API—into Terraform's state file. For example, if you initially set up your cost reporting resources through the Vantage console, you can use this command to import these resources into your Terraform state, which allows you to maintain a single source of truth for your infrastructure.
To use `terraform import`, run the following command:
```bash theme={null}
terraform import vantage_cost_report.demo_report rprt_1abc23456c7c8a90
```
In the above example, a Cost Report that was created within the Vantage console is brought into the Terraform state.
* `vantage_cost_report.demo_report`: The type of infrastructure component managed by Terraform (e.g., [`vantage_cost_report`](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/resources/cost_report)); followed by a user-defined identifier assigned to a resource in your Terraform configuration.
* `rprt_1abc23456c7c8a90`: Example of a Cost Report `token`. This can be found in the URL for a report within the console or [via the API](/api).
See the [example below](/terraform#use-terraform-import-to-manage-external-resources) for a walkthrough of how to use this command.
## Terraform Examples
Before you begin, ensure you have a valid [Write API token](/api/authentication).
### Create a Cost Report
The following example describes how to create a Cost Report for AWS using Terraform.
First, declare the Vantage provider.
```terraform theme={null}
terraform {
required_providers {
vantage = {
source = "vantage-sh/vantage"
}
}
}
provider "vantage" {
api_token = var.api_token
}
```
You can optionally save your API token as an environment variable and remove the `provider "vantage"{...}` block. Export your token with: `export VANTAGE_API_TOKEN=`.
Create the `vantage_folder` resource, with "AWS Costs" as the title.
```terraform theme={null}
resource "vantage_folder" "aws" {
title = "AWS Costs"
}
```
Create the `vantage_cost_report` resource using the token output from the `vantage_folder` resource. The Cost Report will be stored in the newly created AWS folder. The Cost Report's title is "AWS Costs." In addition, the `vantage_saved_filter` resource includes a `filter` parameter that uses [Vantage Query Language (VQL)](/vql), a SQL-like language for querying cloud cost and usage data. Here, the filter is set to show only AWS costs. Set the `groupings` parameter to have the report grouped by region and service.
Valid groupings include: `account_id`, `billing_account_id`, `charge_type`, `cost_category`, `cost_subcategory`, `provider`, `region`, `resource_id`, `service`, `tag:`. Enter multiple groupings as comma-separated values: `groupings=provider,service,region`.
```terraform theme={null}
resource "vantage_cost_report" "aws" {
folder_token = vantage_folder.aws.token
filter = "costs.provider = 'aws'"
title = "AWS Costs"
groupings = "region,service"
}
```
### Using Multiple Vantage Terraform Resources
In the following example, we will create a filter, report, and folder to track database costs. This example assumes you've already declared the appropriate providers.
First, create an RDS instance using the `aws_db_instance` resource from the AWS provider. Then, create a saved filter using the output of the `arn` from the RDS instance as part of the filter criteria.
```terraform theme={null}
resource "aws_db_instance" "rds" {
allocated_storage = 10
db_name = "primary-database"
engine = "mysql"
instance_class = "db.t3.micro"
username = "admin"
password = "password"
}
resource "vantage_saved_filter" "rds" {
title = "rds-costs"
filter = "costs.provider='aws' AND costs.resource_id = '${aws_db_instance.rds.arn}' AND costs.service = 'Amazon Relational Database Service'"
}
```
Then, create a folder to keep your RDS Cost Reports organized.
```terraform theme={null}
resource "vantage_folder" "rds" {
title = "RDS Costs"
}
```
Finally, use the tokens that are output from the saved filter and folder as input to create a new Cost Report.
```terraform theme={null}
resource "vantage_cost_report" "rds_costs" {
folder_token = vantage_folder.rds.token
saved_filter_tokens = [vantage_saved_filter.rds.token]
title = "RDS Costs"
}
```
In this manner, initial setup, deployments, and infrastructure changes are synced to Vantage. Further examples can be found in the `terraform-provider-vantage` [GitHub repository](https://github.com/vantage-sh/terraform-provider-vantage/tree/main/examples).
### Use `terraform import` to Manage External Resources
In the following example, you created a Cost Report in the Vantage console. You want to update the filter on this Cost Report to pull data for different RDS instances, and you want to do this automatically using Terraform. To update data on a resource made outside Terraform, you need to use the `terraform import` command.
First, obtain the `token` for this Cost Report. You can access this `token` using one of the following methods:
* If you are viewing the report in the Vantage console, copy the report's `token` from the end of the URL (e.g., in `https://console.vantage.sh/reports/rprt_123a47b5ba1234e1`, copy `rprt_123a47b5ba1234e1`).
* You can access a list of your reports from the `/cost_reports` [Vantage API endpoint](/api). The `token` is one of the values returned in the response.
* Use the `vantage_cost_reports` Terraform [data source](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/data-sources/cost_reports). You can call the data source and create an [output value](https://developer.hashicorp.com/terraform/language/values/outputs) to access a list of Cost Reports.
Ensure the `vantage_cost_report` [Terraform resource](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs/resources/cost_report) that you want to update is defined in the configuration. Below it is defined with the current parameters.
```terraform theme={null}
resource "vantage_cost_report" "demo_report" {
title = "Terraform Demo Report"
filter = "costs.provider = 'aws' AND costs.service = 'Amazon Relational Database Service' AND costs.resource_id IN ('arn:aws:rds:us-east-1:123456789:db:primary-01', 'arn:aws:rds:us-east-1:123456789:db:primary-02')"
workspace_token = "wrkspc_12c3254c789e0123"
}
```
At this point, Terraform is aware of the resource, but it doesn't manage it yet because the Cost Report was created outside of Terraform, in the Vantage console. To bring the external resource under Terraform's control, you need to import it using the `terraform import` command. Replace the placeholder `` with the `token` you just obtained for the Cost Report.
```bash theme={null}
terraform import vantage_cost_report.demo_report
```
For example, if your Cost Report token is `rprt_123a47b5ba1234e1`, run the following command:
```bash theme={null}
terraform import vantage_cost_report.demo_report rprt_123a47b5ba1234e1
```
After importing the resource, you can modify its attributes in your Terraform configuration. In this example, you can adjust the ARNs in the `filter` parameter to reflect two different RDS instances.
```terraform theme={null}
resource "vantage_cost_report" "demo_report" {
title = "Terraform Demo Report"
filter = "costs.provider = 'aws' AND costs.service = 'Amazon Relational Database Service' AND costs.resource_id IN ('arn:aws:rds:us-east-1:123456789:db:primary-03', 'arn:aws:rds:us-east-1:123456789:db:primary-04')"
workspace_token = "wrkspc_12c3254c789e0123"
}
```
Finally, apply the changes to your configuration:
```bash theme={null}
terraform plan
terraform apply
```
Terraform will detect the new filter and update the external resource accordingly. You can see this reflected in the Vantage console.
## Feature Requests
To request additional features, please open an issue on [GitHub](https://github.com/vantage-sh/terraform-aws-vantage-integration) or email us at [support@vantage.sh](mailto:support@vantage.sh).
# vantage_access_grants (Data Source)
Source: https://docs.vantage.sh/terraform_docs/data_sources/access_grants
Terraform data source reference for vantage_access_grants (Data Source). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this data source with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Schema
### Read-Only
* `access_grants` (Attributes List) (see [below for nested schema](#nestedatt--access_grants))
### Nested Schema for `access_grants`
Read-Only:
* `access` (String)
* `resource_token` (String)
* `team_token` (String)
* `token` (String)
# vantage_anomaly_notifications (Data Source)
Source: https://docs.vantage.sh/terraform_docs/data_sources/anomaly_notifications
Terraform data source reference for vantage_anomaly_notifications (Data Source). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this data source with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Schema
### Read-Only
* `anomaly_notifications` (Attributes List) (see [below for nested schema](#nestedatt--anomaly_notifications))
### Nested Schema for `anomaly_notifications`
Read-Only:
* `cost_report_token` (String) The token for the CostReport the AnomalyNotification is associated with.
* `created_at` (String) The date and time, in UTC, the AnomalyNotification was created. ISO 8601 Formatted.
* `id` (String) The id of the resource
* `recipient_channels` (List of String) The channels that the notification is sent to.
* `threshold` (Number) The threshold amount that must be met for the notification to fire.
* `token` (String)
* `updated_at` (String) The date and time, in UTC, the AnomalyNotification was last updated at. ISO 8601 Formatted.
* `user_tokens` (List of String) The tokens of the users that receive the notification.
# vantage_aws_provider_info (Data Source)
Source: https://docs.vantage.sh/terraform_docs/data_sources/aws_provider_info
Terraform data source reference for vantage_aws_provider_info (Data Source). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this data source with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Schema
### Read-Only
* `additional_resources_policy` (String) The policy that allows Vantage to list and describe resources from your AWS account.
* `autopilot_policy` (String) The policy that allows Vantage to manage autopilot.
* `cloudwatch_metrics_policy` (String) The policy that allows Vantage to retrieve cloudwatch metrics from your AWS account.
* `external_id` (String, Sensitive) The Vantage external ID to authenticate your account.
* `iam_role_arn` (String) The IAM role that Vantage assumes into your account.
* `root_policy` (String) The policy that allows Vantage to manage autopilot.
# vantage_billing_profiles (Data Source)
Source: https://docs.vantage.sh/terraform_docs/data_sources/billing_profiles
Terraform data source reference for vantage_billing_profiles (Data Source). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this data source with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Schema
### Read-Only
* `billing_profiles` (Attributes List) (see [below for nested schema](#nestedatt--billing_profiles))
### Nested Schema for `billing_profiles`
Read-Only:
* `banking_information_attributes` (Attributes) (see [below for nested schema](#nestedatt--billing_profiles--banking_information_attributes))
* `billing_information_attributes` (Attributes) (see [below for nested schema](#nestedatt--billing_profiles--billing_information_attributes))
* `business_information_attributes` (Attributes) (see [below for nested schema](#nestedatt--billing_profiles--business_information_attributes))
* `created_at` (String) The date and time, in UTC, the billing profile was created. ISO 8601 formatted.
* `id` (String) The id of the resource
* `invoice_adjustment_attributes` (Attributes) (see [below for nested schema](#nestedatt--billing_profiles--invoice_adjustment_attributes))
* `managed_accounts_count` (String) Number of managed accounts using this billing profile
* `nickname` (String) Display name for the billing profile
* `token` (String)
* `updated_at` (String) The date and time, in UTC, the billing profile was last updated. ISO 8601 formatted.
### Nested Schema for `billing_profiles.banking_information_attributes`
Read-Only:
* `bank_name` (String) Name of the bank
* `beneficiary_name` (String) Name of the account beneficiary
* `secure_data` (Attributes) (see [below for nested schema](#nestedatt--billing_profiles--banking_information_attributes--secure_data))
* `tax_id` (String) Tax identification number
* `token` (String)
### Nested Schema for `billing_profiles.banking_information_attributes.secure_data`
Read-Only:
* `account_number` (String) Bank account number (US)
* `iban` (String) International Bank Account Number (EU)
* `routing_number` (String) Bank routing number (US)
* `swift_bic` (String) SWIFT/BIC code (EU)
### Nested Schema for `billing_profiles.billing_information_attributes`
Read-Only:
* `address_line_1` (String) First line of billing address
* `address_line_2` (String) Second line of billing address
* `billing_email` (List of String) Array of billing email addresses
* `city` (String) City for billing address
* `company_name` (String) Company name for billing
* `country_code` (String) ISO country code
* `postal_code` (String) Postal or ZIP code
* `state` (String) State or province for billing address
* `token` (String)
### Nested Schema for `billing_profiles.business_information_attributes`
Read-Only:
* `metadata` (Attributes) (see [below for nested schema](#nestedatt--billing_profiles--business_information_attributes--metadata))
* `token` (String)
### Nested Schema for `billing_profiles.business_information_attributes.metadata`
Read-Only:
* `custom_fields` (Attributes List) Array of custom field objects (see [below for nested schema](#nestedatt--billing_profiles--business_information_attributes--metadata--custom_fields))
### Nested Schema for `billing_profiles.business_information_attributes.metadata.custom_fields`
Read-Only:
* `name` (String) Custom field name
* `value` (String) Custom field value
### Nested Schema for `billing_profiles.invoice_adjustment_attributes`
Read-Only:
* `adjustment_items` (Attributes List) Array of adjustment items (taxes, fees, etc.) (see [below for nested schema](#nestedatt--billing_profiles--invoice_adjustment_attributes--adjustment_items))
* `token` (String)
### Nested Schema for `billing_profiles.invoice_adjustment_attributes.adjustment_items`
Read-Only:
* `adjustment_type` (String) Type of adjustment
* `amount` (String) Amount or percentage value for the adjustment
* `calculation_type` (String) How the adjustment is calculated
* `name` (String) Name of the adjustment (e.g., 'State Tax', 'Processing Fee')
# vantage_billing_rules (Data Source)
Source: https://docs.vantage.sh/terraform_docs/data_sources/billing_rules
Terraform data source reference for vantage_billing_rules (Data Source). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this data source with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Schema
### Read-Only
* `billing_rules` (Attributes List) (see [below for nested schema](#nestedatt--billing_rules))
### Nested Schema for `billing_rules`
Read-Only:
* `amount` (String) The amount for the BillingRule (Charge).
* `apply_to_all` (Boolean) Whether the BillingRule applies to all future managed accounts.
* `category` (String) The category for the BillingRule (Charge).
* `charge_type` (String) The charge type for the BillingRule.
* `created_at` (String) The date and time, in UTC, the BillingRule was created. ISO 8601 Formatted.
* `created_by_token` (String) The token of the Creator of the BillingRule.
* `end_date` (String) The end date of the BillingRule.
* `id` (String) The id of the resource
* `percentage` (String) The percentage of the cost shown for the BillingRule (Adjustment).
* `service` (String) The service for the BillingRule (Charge).
* `sql_query` (String) The SQL query for the BillingRule (Custom).
* `start_date` (String) The start date of the BillingRule.
* `start_period` (String) The start period for the BillingRule (Charge).
* `sub_category` (String) The subcategory for the BillingRule (Charge).
* `title` (String) The title of the BillingRule.
* `token` (String)
* `type` (String) The type of the BillingRule.
# vantage_budget_alerts (Data Source)
Source: https://docs.vantage.sh/terraform_docs/data_sources/budget_alerts
Terraform data source reference for vantage_budget_alerts (Data Source). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this data source with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Example Usage
```terraform theme={null}
data "vantage_budget_alerts" "demo" {
budget_token = vantage_budget.demo_budget.token
}
```
## Schema
### Optional
* `budget_token` (String) Filter by budget token.
* `workspace_token` (String) Filter by workspace token.
### Read-Only
* `budget_alerts` (Attributes List) (see [below for nested schema](#nestedatt--budget_alerts))
### Nested Schema for `budget_alerts`
Read-Only:
* `budget_tokens` (List of String) The tokens for the Budgets that the Budget Alert is monitoring to trigger alerts on.
* `created_at` (String) The date and time, in UTC, the Budget Alert was created. ISO 8601 Formatted.
* `duration_in_days` (Number) The API's nullable integer duration. A null value means the full month; the `vantage_budget_alert` resource writes the same state as `""`.
* `id` (String) The id of the resource
* `integration_provider` (String) The provider used for sending alerts. This must be configured in the console. Possible values are: slack, microsoft\_graph.
* `period_to_track` (String) The period tracked on the alert. Used with duration\_in\_days to determine the time window of the alert. Possible values: start\_of\_the\_month, end\_of\_the\_month.
* `recipient_channels` (List of String) The channels receiving the alerts. Requires an integration provider to be connected.
* `recipient_emails` (List of String) The complete recipient address list, including organization users and freeform addresses on verified domains.
* `threshold` (Number) Alerts only send if they reach this number (as a percentage). When threshold is 100, that means alerts are triggered once costs reach 100% of the budget.
* `token` (String)
* `user_token` (String) The token for the User who created this BudgetAlert.
* `user_tokens` (List of String) The organization-user subset of recipients. Freeform verified-domain addresses are excluded; recipient\_emails contains the complete address list.
* `workspace_token` (String) The token for the Workspace the ResourceReport is a part of.
# vantage_budgets (Data Source)
Source: https://docs.vantage.sh/terraform_docs/data_sources/budgets
Terraform data source reference for vantage_budgets (Data Source). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this data source with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Schema
### Read-Only
* `budgets` (Attributes List) (see [below for nested schema](#nestedatt--budgets))
### Nested Schema for `budgets`
Read-Only:
* `budget_alert_tokens` (List of String) The tokens of the BudgetAlerts associated with the Budget.
* `child_budget_tokens` (List of String) The tokens of the child Budgets associated with the hierarchical Budget.
* `cost_report_token` (String) The token of the Report associated with the Budget.
* `created_at` (String) The date and time, in UTC, the Budget was created. ISO 8601 Formatted.
* `created_by_token` (String) The token of the Creator of the Budget.
* `id` (String) The id of the resource
* `name` (String) The name of the Budget.
* `performance` (Attributes List) The historical performance of the Budget. (see [below for nested schema](#nestedatt--budgets--performance))
* `period_cadence` (Attributes) The interval cadence for budget periods. (see [below for nested schema](#nestedatt--budgets--period_cadence))
* `periods` (Attributes List) The budget periods associated with the Budget. (see [below for nested schema](#nestedatt--budgets--periods))
* `token` (String)
* `type` (String) The type of Budget. One of: cost, usage.
* `unit` (String) The usage unit for usage Budgets.
* `user_token` (String) The token for the User who created this Budget.
* `workspace_token` (String) The token for the Workspace the Budget is a part of.
### Nested Schema for `budgets.performance`
Read-Only:
* `actual` (String) The date and time, in UTC, the Budget was created. ISO 8601 Formatted.
* `amount` (String) The amount of the Budget Period as a string to ensure precision.
* `date` (String) The date and time, in UTC, the Budget was created. ISO 8601 Formatted.
### Nested Schema for `budgets.period_cadence`
Read-Only:
* `interval_count` (Number) The number of interval units per budget period.
* `interval_unit` (String) The unit for budget period intervals. One of: day, week, month, year.
* `starts_at` (String) The anchor date for budget period intervals. ISO 8601 date (YYYY-MM-DD).
### Nested Schema for `budgets.periods`
Read-Only:
* `amount` (String) The amount of the Budget Period as a string to ensure precision.
* `end_at` (String) The date and time, in UTC, the Budget was created. ISO 8601 Formatted.
* `start_at` (String) The date and time, in UTC, the Budget was created. ISO 8601 Formatted.
# vantage_business_metrics (Data Source)
Source: https://docs.vantage.sh/terraform_docs/data_sources/business_metrics
Terraform data source reference for vantage_business_metrics (Data Source). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this data source with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Schema
### Read-Only
* `business_metrics` (Attributes List) (see [below for nested schema](#nestedatt--business_metrics))
### Nested Schema for `business_metrics`
Read-Only:
* `clickhouse_metric_fields` (Attributes) (see [below for nested schema](#nestedatt--business_metrics--clickhouse_metric_fields))
* `cloudwatch_fields` (Attributes) (see [below for nested schema](#nestedatt--business_metrics--cloudwatch_fields))
* `cost_report_tokens_with_metadata` (Attributes List) The tokens for any CostReports that use the BusinessMetric, the unit scale, and label filter. (see [below for nested schema](#nestedatt--business_metrics--cost_report_tokens_with_metadata))
* `created_by_token` (String) The token of the Creator of the BusinessMetric.
* `datadog_metric_fields` (Attributes) (see [below for nested schema](#nestedatt--business_metrics--datadog_metric_fields))
* `gcp_bigquery_metric_fields` (Attributes) (see [below for nested schema](#nestedatt--business_metrics--gcp_bigquery_metric_fields))
* `id` (String) The id of the BusinessMetric.
* `import_type` (String) The type of import for the BusinessMetric.
* `integration_token` (String) The Integration token used to import the BusinessMetric.
* `snowflake_metric_fields` (Attributes) (see [below for nested schema](#nestedatt--business_metrics--snowflake_metric_fields))
* `title` (String) The title of the BusinessMetric.
* `token` (String) The token of the BusinessMetric.
### Nested Schema for `business_metrics.clickhouse_metric_fields`
Read-Only:
* `query_endpoint_id` (String) The UUID of the ClickHouse query endpoint used to import metrics.
### Nested Schema for `business_metrics.cloudwatch_fields`
Read-Only:
* `dimensions` (Attributes List) The dimensions used to pull specific statistical data for Cloudwatch metrics. (see [below for nested schema](#nestedatt--business_metrics--cloudwatch_fields--dimensions))
* `label_dimension` (String) The dimension used to aggregate the Cloudwatch metrics.
* `metric_name` (String) The metric name used to import Cloudwatch metrics.
* `namespace` (String) The namespace used to import Cloudwatch metrics.
* `region` (String) The region used to import Cloudwatch metrics.
* `stat` (String) The time aggregation function used to import Cloudwatch metrics.
### Nested Schema for `business_metrics.cloudwatch_fields.dimensions`
Read-Only:
* `name` (String)
* `value` (String)
### Nested Schema for `business_metrics.cost_report_tokens_with_metadata`
Read-Only:
* `calculation_type` (String) The calculation type applied when this BusinessMetric is used in the CostReport.
* `cost_report_token` (String) The token of the CostReport the BusinessMetric is attached to.
* `label` (String) Optional custom display name for this BusinessMetric on the CostReport. When omitted, a default is derived from the calculation type.
* `label_filter` (List of String) The labels that the BusinessMetric is filtered by within a particular CostReport.
* `label_filters` (Map of List of String) The ClickHouse BusinessMetric label filters applied within a CostReport. Each key is required and values within a key are alternatives.
* `unit_scale` (String) Determines the scale of the BusinessMetric's values within a particular CostReport.
### Nested Schema for `business_metrics.datadog_metric_fields`
Read-Only:
* `query` (String) The query used to import Datadog metrics.
### Nested Schema for `business_metrics.gcp_bigquery_metric_fields`
Read-Only:
* `query_project_id` (String) The GCP project in which the BigQuery job runs.
* `sql_query` (String) The SQL query used to import GCP BigQuery metrics.
### Nested Schema for `business_metrics.snowflake_metric_fields`
Read-Only:
* `sql_query` (String) The SQL query used to import Snowflake metrics.
# vantage_cost_alerts (Data Source)
Source: https://docs.vantage.sh/terraform_docs/data_sources/cost_alerts
Terraform data source reference for vantage_cost_alerts (Data Source). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this data source with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Schema
### Read-Only
* `cost_alerts` (Attributes List) (see [below for nested schema](#nestedatt--cost_alerts))
### Nested Schema for `cost_alerts`
Read-Only:
* `created_at` (String) The date and time, in UTC, for when the alert was created. ISO 8601 Formatted.
* `email_recipients` (List of String) The email addresses that will receive the alert.
* `id` (String) The id of the resource
* `interval` (String) The period of time used to compare costs. Options are 'day', 'week', 'month', 'quarter'.
* `minimum_threshold` (Number) The minimum monetary amount threshold for percentage-based alerts. When set, alerts will only trigger if the cost change meets this minimum, even if the percentage threshold is exceeded.
* `report_tokens` (List of String) The tokens of the reports to alert on.
* `slack_channels` (List of String) The Slack channels that will receive the alert. Make sure your slack integration is connected at [https://console.vantage.sh/settings/slack](https://console.vantage.sh/settings/slack).
* `teams_channels` (List of String) The Microsoft Teams channels that will receive the alert. Make sure your teams integration is connected at [https://console.vantage.sh/settings/microsoft\_teams](https://console.vantage.sh/settings/microsoft_teams).
* `threshold` (Number) The cost change threshold to alert on.
* `title` (String)
* `token` (String)
* `unit_type` (String) The unit type used to compare costs. Options are 'currency' or 'percentage'.
* `updated_at` (String) The date and time, in UTC, for when the alert was last updated. ISO 8601 Formatted.
* `workspace_token` (String) The ID of the organization that owns the CostAlert.
# vantage_cost_reports (Data Source)
Source: https://docs.vantage.sh/terraform_docs/data_sources/cost_reports
Terraform data source reference for vantage_cost_reports (Data Source). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this data source with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Schema
### Read-Only
* `cost_reports` (Attributes List) (see [below for nested schema](#nestedatt--cost_reports))
### Nested Schema for `cost_reports`
Read-Only:
* `chart_settings` (Attributes) (see [below for nested schema](#nestedatt--cost_reports--chart_settings))
* `chart_type` (String)
* `date_bin` (String)
* `date_interval` (String)
* `end_date` (String)
* `filter` (String)
* `folder_token` (String)
* `groupings` (String)
* `previous_period_end_date` (String)
* `previous_period_start_date` (String)
* `saved_filter_tokens` (List of String)
* `start_date` (String)
* `title` (String)
* `token` (String)
* `workspace_token` (String)
### Nested Schema for `cost_reports.chart_settings`
Read-Only:
* `x_axis_dimension` (List of String)
* `y_axis_dimension` (String)
# vantage_dashboards (Data Source)
Source: https://docs.vantage.sh/terraform_docs/data_sources/dashboards
Terraform data source reference for vantage_dashboards (Data Source). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this data source with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Schema
### Optional
* `q` (String) Search dashboards by title.
* `workspace_token` (String) The workspace token of the dashboards to return.
### Read-Only
* `dashboards` (Attributes List) (see [below for nested schema](#nestedatt--dashboards))
### Nested Schema for `dashboards`
Read-Only:
* `created_at` (String) The date and time, in UTC, the Dashboard was created. ISO 8601 Formatted.
* `date_bin` (String) Determines how to group costs in the Dashboard.
* `date_interval` (String) Determines the date range for Reports in the Dashboard. Guaranteed to be set to 'custom' if 'start\_date' and 'end\_date' are set.
* `end_date` (String) The end date for the date range for Reports in the Dashboard. ISO 8601 Formatted. Overwrites 'date\_interval' if set.
* `id` (String) The id of the resource
* `saved_filter_tokens` (List of String) The tokens of the Saved Filters used in the Dashboard.
* `start_date` (String) The start date for the date range for Reports in the Dashboard. ISO 8601 Formatted. Overwrites 'date\_interval' if set.
* `title` (String) The title of the Dashboard.
* `token` (String)
* `updated_at` (String) The date and time, in UTC, the Dashboard was created. ISO 8601 Formatted.
* `widgets` (Attributes List) The widgets displayed in the Dashboard. Report-backed widgets include widgetable\_token and settings. Free text widgets include widgetable\_type set to free\_text and content, omit widgetable\_token, and include settings when a grid layout is persisted. (see [below for nested schema](#nestedatt--dashboards--widgets))
* `workspace_token` (String) The token for the Workspace the Dashboard is a part of.
### Nested Schema for `dashboards.widgets`
Read-Only:
* `content` (String) JSON-encoded TipTap document for a free text widget. Example: `{"type":"doc","content":[...]}`
* `settings` (Attributes) (see [below for nested schema](#nestedatt--dashboards--widgets--settings))
* `title` (String) The title of the Widget.
* `token` (String) The token of the Dashboard Widget.
* `widgetable_token` (String) The token of the represented Resource.
* `widgetable_type` (String) The widget type. Present instead of widgetable\_token for free text widgets.
### Nested Schema for `dashboards.widgets.settings`
Read-Only:
* `display_type` (String)
* `grid` (Attributes) (see [below for nested schema](#nestedatt--dashboards--widgets--settings--grid))
* `kpi_calculation` (String) The aggregation used when display\_type is kpi.
* `kpi_type` (String) The metric represented by the KPI.
* `kpi_usage_unit` (String) The usage unit represented by the KPI.
### Nested Schema for `dashboards.widgets.settings.grid`
Read-Only:
* `h` (Number) The widget height in grid rows.
* `w` (Number) The widget width in grid columns.
* `x` (Number) The zero-based horizontal position in the 12-column grid.
* `y` (Number) The zero-based vertical position in the grid.
# vantage_enrichment_source (Data Source)
Source: https://docs.vantage.sh/terraform_docs/data_sources/enrichment_source
Terraform data source reference for vantage_enrichment_source (Data Source). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this data source with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Schema
### Required
* `token` (String) The token of the enrichment source
### Read-Only
* `active` (Boolean) Whether the EnrichmentSource is active.
* `created_at` (String) The date and time, in UTC, the EnrichmentSource was created. ISO 8601 Formatted.
* `integration_token` (String) The token for the Integration that owns this EnrichmentSource.
* `title` (String) The display name for the enrichment source type.
* `type` (String) The enrichment source type.
# vantage_enrichment_sources (Data Source)
Source: https://docs.vantage.sh/terraform_docs/data_sources/enrichment_sources
Terraform data source reference for vantage_enrichment_sources (Data Source). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this data source with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Schema
### Read-Only
* `enrichment_sources` (Attributes List) (see [below for nested schema](#nestedatt--enrichment_sources))
### Nested Schema for `enrichment_sources`
Read-Only:
* `active` (Boolean) Whether the EnrichmentSource is active.
* `created_at` (String) The date and time, in UTC, the EnrichmentSource was created. ISO 8601 Formatted.
* `id` (String) The id of the resource
* `integration_token` (String) The token for the Integration that owns this EnrichmentSource.
* `title` (String) The display name for the enrichment source type.
* `token` (String) The token for the EnrichmentSource.
* `type` (String) The enrichment source type.
# vantage_financial_commitment_reports (Data Source)
Source: https://docs.vantage.sh/terraform_docs/data_sources/financial_commitment_reports
Terraform data source reference for vantage_financial_commitment_reports (Data Source). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this data source with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Schema
### Read-Only
* `financial_commitment_reports` (Attributes List) (see [below for nested schema](#nestedatt--financial_commitment_reports))
### Nested Schema for `financial_commitment_reports`
Read-Only:
* `created_at` (String) The date and time, in UTC, the report was created. ISO 8601 Formatted.
* `date_bucket` (String) How costs are grouped and displayed in the FinancialCommitmentReport. Possible values: day, week, month.
* `date_interval` (String) The date range for the FinancialCommitmentReport. Only present if a custom date range is not specified.
* `default` (Boolean) Indicates whether the FinancialCommitmentReport is the default report.
* `end_date` (String) The end date for the FinancialCommitmentReport. Only set for custom date ranges. ISO 8601 Formatted.
* `filter` (String) The filter applied to the FinancialCommitmentReport. Additional documentation available at [https://docs.vantage.sh/vql](https://docs.vantage.sh/vql).
* `groupings` (String) The grouping aggregations applied to the filtered data.
* `id` (String) The id of the resource
* `on_demand_costs_scope` (String) The scope for the costs. Possible values: discountable, all.
* `start_date` (String) The start date for the FinancialCommitmentReport. Only set for custom date ranges. ISO 8601 Formatted.
* `title` (String) The title of the FinancialCommitmentReport.
* `token` (String)
* `user_token` (String) The token for the User who created this FinancialCommitmentReport.
* `workspace_token` (String) The token for the Workspace the FinancialCommitmentReport is a part of.
# vantage_folder (Data Source)
Source: https://docs.vantage.sh/terraform_docs/data_sources/folder
Terraform data source reference for vantage_folder (Data Source). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this data source with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
Looks up a folder by title and returns its token. Use `workspace_token` and `parent_folder_token` to narrow the search.
## Schema
### Required
* `title` (String) The title of the folder to find.
### Optional
* `parent_folder_token` (String) Filter folders by parent folder token. Set to an empty string (`""`) to match only root-level folders (those with no parent). Also populated as an output with the parent folder token of the matched folder.
* `workspace_token` (String) Filter folders by workspace token. If not specified, the first folder matching the title is returned. Also populated as an output with the workspace token of the matched folder.
### Read-Only
* `token` (String) The unique token of the matched folder.
# vantage_folders (Data Source)
Source: https://docs.vantage.sh/terraform_docs/data_sources/folders
Terraform data source reference for vantage_folders (Data Source). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this data source with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Schema
### Read-Only
* `folders` (Attributes List) (see [below for nested schema](#nestedatt--folders))
### Nested Schema for `folders`
Read-Only:
* `parent_folder_token` (String)
* `saved_filter_tokens` (List of String)
* `title` (String)
* `token` (String)
* `workspace_token` (String)
# vantage_integration_by_name (Data Source)
Source: https://docs.vantage.sh/terraform_docs/data_sources/integration_by_name
Terraform data source reference for vantage_integration_by_name (Data Source). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this data source with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
Looks up an integration by name. Searches up to 1,000 integrations returned by the Vantage API. Use `provider_filter` to narrow the search to a specific integration type.
## Schema
### Required
* `name` (String) The display name of the integration to find.
### Optional
* `provider_filter` (String) Filter integrations by provider type before searching (e.g. `custom_provider`). Corresponds to the `provider` query parameter on the Get All Integrations endpoint.
### Read-Only
* `created_at` (String) The date and time (UTC, ISO 8601) when the integration was created.
* `last_updated` (String) The date and time (UTC, ISO 8601) when the integration was last updated.
* `managed_account_tokens` (Set of String) The tokens of any Managed Accounts associated with this integration.
* `status` (String) The status of the integration (e.g. connected, pending, importing, imported, error, disconnected).
* `token` (String) The unique token of the matched integration.
* `workspace_tokens` (Set of String) The tokens of the Workspaces associated with this integration.
# vantage_integrations (Data Source)
Source: https://docs.vantage.sh/terraform_docs/data_sources/integrations
Terraform data source reference for vantage_integrations (Data Source). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this data source with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
Returns all integrations visible to the API token, optionally filtered by provider type. Fetches up to 1,000 results.
## Schema
### Optional
* `provider_filter` (String) Filter results by provider type (e.g. `custom_provider`). Corresponds to the `provider` query parameter on the Get All Integrations API endpoint.
### Read-Only
* `integrations` (Attributes List) The list of integrations returned by the API. (see [below for nested schema](#nestedatt--integrations))
### Nested Schema for `integrations`
Read-Only:
* `created_at` (String) The date and time (UTC, ISO 8601) when the integration was created.
* `last_updated` (String) The date and time (UTC, ISO 8601) when the integration was last updated. Null if never updated.
* `managed_account_tokens` (Set of String) The tokens of any Managed Accounts associated with this integration.
* `name` (String) The display name of the integration.
* `status` (String) The status of the integration (e.g. connected, pending, importing, imported, error, disconnected).
* `token` (String) The unique token of the integration.
* `workspace_tokens` (Set of String) The tokens of the Workspaces associated with this integration.
# vantage_invoices (Data Source)
Source: https://docs.vantage.sh/terraform_docs/data_sources/invoices
Terraform data source reference for vantage_invoices (Data Source). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this data source with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Schema
### Optional
* `managed_account_token` (String) Filter invoices by managed account token (MSP accounts only)
### Read-Only
* `invoices` (Attributes List) (see [below for nested schema](#nestedatt--invoices))
### Nested Schema for `invoices`
Read-Only:
* `account_name` (String) Name of the managed account this invoice belongs to
* `account_token` (String) Token of the managed account this invoice belongs to
* `billing_period_end` (String) End date of the billing period. ISO 8601 formatted.
* `billing_period_start` (String) Start date of the billing period. ISO 8601 formatted.
* `created_at` (String) The date and time, in UTC, the invoice was created. ISO 8601 formatted.
* `id` (String) The id of the resource
* `invoice_number` (String) Sequential invoice number for the MSP account
* `msp_account_token` (String) Token of the MSP account that owns this invoice
* `status` (String) Current status of the invoice
* `token` (String)
* `total` (String) Total amount for the invoice period
* `updated_at` (String) The date and time, in UTC, the invoice was last updated. ISO 8601 formatted.
# vantage_kubernetes_efficiency_reports (Data Source)
Source: https://docs.vantage.sh/terraform_docs/data_sources/kubernetes_efficiency_reports
Terraform data source reference for vantage_kubernetes_efficiency_reports (Data Source). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this data source with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Schema
### Read-Only
* `kubernetes_efficiency_reports` (Attributes List) (see [below for nested schema](#nestedatt--kubernetes_efficiency_reports))
### Nested Schema for `kubernetes_efficiency_reports`
Read-Only:
* `aggregated_by` (String) How costs are aggregated by. Possible values: idle\_cost, amount, cost\_efficiency.
* `created_at` (String) The date and time, in UTC, the report was created. ISO 8601 Formatted.
* `date_bucket` (String) How costs are grouped and displayed in the KubernetesEfficiencyReport. Possible values: day, week, month.
* `date_interval` (String) The date range for the KubernetesEfficiencyReport. Only present if a custom date range is not specified.
* `default` (Boolean) Indicates whether the KubernetesEfficiencyReport is the default report.
* `end_date` (String) The end date for the KubernetesEfficiencyReport. Only set for custom date ranges. ISO 8601 Formatted.
* `filter` (String) The filter applied to the KubernetesEfficiencyReport. Additional documentation available at [https://docs.vantage.sh/vql](https://docs.vantage.sh/vql).
* `groupings` (String) Grouping values for aggregating costs on the KubernetesEfficiencyReport. Valid groupings: cluster\_id, namespace, labeled, category, pod, label, `label:`.
* `id` (String) The id of the resource
* `start_date` (String) The start date for the KubernetesEfficiencyReport. Only set for custom date ranges. ISO 8601 Formatted.
* `title` (String) The title of the KubernetesEfficiencyReport.
* `token` (String)
* `user_token` (String) The token for the User who created this KubernetesEfficiencyReport.
* `workspace_token` (String) The token for the Workspace the KubernetesEfficiencyReport is a part of.
# vantage_managed_accounts (Data Source)
Source: https://docs.vantage.sh/terraform_docs/data_sources/managed_accounts
Terraform data source reference for vantage_managed_accounts (Data Source). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this data source with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Schema
### Read-Only
* `managed_accounts` (Attributes List) (see [below for nested schema](#nestedatt--managed_accounts))
### Nested Schema for `managed_accounts`
Read-Only:
* `access_credential_tokens` (List of String) The tokens for the Access Credentials assigned to the Managed Account.
* `billing_information_attributes` (Attributes) (see [below for nested schema](#nestedatt--managed_accounts--billing_information_attributes))
* `billing_rule_tokens` (List of String) The tokens for the Billing Rules assigned to the Managed Account.
* `business_information_attributes` (Attributes) (see [below for nested schema](#nestedatt--managed_accounts--business_information_attributes))
* `contact_email` (String)
* `email_domain` (String) Email domain associated with this Managed Account for SSO.
* `id` (String) The id of the resource
* `include_managed_account_integrations` (Boolean) Whether to include managed account's own integrations in invoice cost calculations (MSP invoicing accounts only)
* `msp_billing_profile_token` (String) Token of the MSP billing profile used for this managed account (MSP invoicing accounts only)
* `name` (String)
* `parent_account_token` (String) The token for the parent Account.
* `payment_terms_days` (Number) Number of days until payment is due after invoice date (MSP invoicing accounts only)
* `token` (String)
### Nested Schema for `managed_accounts.billing_information_attributes`
Read-Only:
* `address_line_1` (String) First line of billing address
* `address_line_2` (String) Second line of billing address
* `billing_email` (List of String) Array of billing email addresses
* `city` (String) City for billing address
* `company_name` (String) Company name for billing
* `country_code` (String) ISO country code
* `postal_code` (String) Postal or ZIP code
* `state` (String) State or province for billing address
* `token` (String)
### Nested Schema for `managed_accounts.business_information_attributes`
Read-Only:
* `metadata` (Attributes) (see [below for nested schema](#nestedatt--managed_accounts--business_information_attributes--metadata))
* `token` (String)
### Nested Schema for `managed_accounts.business_information_attributes.metadata`
Read-Only:
* `custom_fields` (Attributes List) Array of custom field objects (see [below for nested schema](#nestedatt--managed_accounts--business_information_attributes--metadata--custom_fields))
### Nested Schema for `managed_accounts.business_information_attributes.metadata.custom_fields`
Read-Only:
* `name` (String) Custom field name
* `value` (String) Custom field value
# vantage_network_flow_reports (Data Source)
Source: https://docs.vantage.sh/terraform_docs/data_sources/network_flow_reports
Terraform data source reference for vantage_network_flow_reports (Data Source). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this data source with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Schema
### Read-Only
* `network_flow_reports` (Attributes List) (see [below for nested schema](#nestedatt--network_flow_reports))
### Nested Schema for `network_flow_reports`
Read-Only:
* `created_at` (String) The date and time, in UTC, the report was created. ISO 8601 Formatted.
* `created_by_token` (String) The token for the User or Team that created this NetworkFlowReport.
* `date_interval` (String) The date range for the NetworkFlowReport. Only present if a custom date range is not specified.
* `default` (Boolean) Indicates whether the NetworkFlowReport is the default report.
* `end_date` (String) The end date for the NetworkFlowReport. Only set for custom date ranges. ISO 8601 Formatted.
* `filter` (String) The filter applied to the NetworkFlowReport. Additional documentation available at [https://docs.vantage.sh/vql](https://docs.vantage.sh/vql).
* `flow_direction` (String) The flow weight of the NetworkFlowReport. Possible values: costs, bytes.
* `flow_weight` (String) The flow weight of the NetworkFlowReport. Possible values: costs, bytes.
* `groupings` (String) The grouping aggregations applied to the filtered data.
* `id` (String) The id of the resource
* `start_date` (String) The start date for the NetworkFlowReport. Only set for custom date ranges. ISO 8601 Formatted.
* `title` (String) The title of the NetworkFlowReport.
* `token` (String)
* `workspace_token` (String) The token for the Workspace the NetworkFlowReport is a part of.
# vantage_recommendation_views (Data Source)
Source: https://docs.vantage.sh/terraform_docs/data_sources/recommendation_views
Terraform data source reference for vantage_recommendation_views (Data Source). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this data source with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Schema
### Read-Only
* `recommendation_views` (Attributes List) (see [below for nested schema](#nestedatt--recommendation_views))
### Nested Schema for `recommendation_views`
Read-Only:
* `account_ids` (List of String) Filter by cloud account identifiers.
* `billing_account_ids` (List of String) Filter by billing account identifiers.
* `created_at` (String) The date and time, in UTC, the view was created. ISO 8601 Formatted.
* `created_by` (String) The token for the Creator of this RecommendationView.
* `end_date` (String) Filter recommendations created on/before this YYYY-MM-DD date.
* `provider_ids` (List of String) Filter by one or more providers.
* `regions` (List of String) Filter by region slugs (e.g. us-east-1, eastus, asia-east1).
* `start_date` (String) Filter recommendations created on/after this YYYY-MM-DD date.
* `tag_key` (String) Filter by tag key (must be used with tag\_value).
* `tag_value` (String) Filter by tag value (requires tag\_key).
* `title` (String) The title of the RecommendationView.
* `token` (String) The token of the RecommendationView.
* `workspace_token` (String) The token for the Workspace the RecommendationView is a part of.
# vantage_report_forecasts (Data Source)
Source: https://docs.vantage.sh/terraform_docs/data_sources/report_forecasts
Terraform data source reference for vantage_report_forecasts (Data Source). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this data source with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Example Usage
```terraform theme={null}
data "vantage_report_forecasts" "demo" {
cost_report_token = vantage_cost_report.demo_report.token
}
```
## Schema
### Required
* `cost_report_token` (String)
### Read-Only
* `report_forecasts` (Attributes List) (see [below for nested schema](#nestedatt--report_forecasts))
### Nested Schema for `report_forecasts`
Read-Only:
* `business_metric_token` (String)
* `cost_report_token` (String)
* `created_at` (String)
* `created_by_token` (String)
* `id` (String) The id of the resource
* `is_default` (Boolean)
* `scenario_model_tokens` (List of String)
* `title` (String)
* `token` (String)
* `updated_at` (String)
# vantage_report_notifications (Data Source)
Source: https://docs.vantage.sh/terraform_docs/data_sources/report_notifications
Terraform data source reference for vantage_report_notifications (Data Source). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this data source with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Schema
### Read-Only
* `report_notifications` (Attributes List) (see [below for nested schema](#nestedatt--report_notifications))
### Nested Schema for `report_notifications`
Read-Only:
* `change` (String) The type of change the ReportNotification is tracking.
* `cost_report_token` (String) The token for a CostReport the ReportNotification is applied to.
* `frequency` (String) The frequency the ReportNotification is sent.
* `id` (String) The id of the resource
* `recipient_channels` (List of String) The Slack or Microsoft Teams channels that receive the notification.
* `title` (String) The title of the ReportNotification.
* `token` (String)
* `user_tokens` (List of String) The Users that receive the notification.
# vantage_resource_report_columns (Data Source)
Source: https://docs.vantage.sh/terraform_docs/data_sources/resource_report_columns
Terraform data source reference for vantage_resource_report_columns (Data Source). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this data source with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
Data source for retrieving available columns for a specific resource type in resource reports.
## Schema
### Required
* `resource_type` (String) VQL resource type name (e.g., 'aws\_instance', 'aws\_ebs\_volume'). See [https://docs.vantage.sh/vql\_resource\_report#resource-type](https://docs.vantage.sh/vql_resource_report#resource-type) for available types.
### Read-Only
* `columns` (List of String) Array of available column names for the specified resource type.
# vantage_resource_reports (Data Source)
Source: https://docs.vantage.sh/terraform_docs/data_sources/resource_reports
Terraform data source reference for vantage_resource_reports (Data Source). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this data source with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Schema
### Read-Only
* `resource_reports` (Attributes List) (see [below for nested schema](#nestedatt--resource_reports))
### Nested Schema for `resource_reports`
Read-Only:
* `created_at` (String)
* `title` (String)
* `token` (String)
* `user_token` (String)
* `workspace_token` (String)
# vantage_saved_filters (Data Source)
Source: https://docs.vantage.sh/terraform_docs/data_sources/saved_filters
Terraform data source reference for vantage_saved_filters (Data Source). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this data source with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Schema
### Read-Only
* `filters` (Attributes List) (see [below for nested schema](#nestedatt--filters))
### Nested Schema for `filters`
Read-Only:
* `cost_report_tokens` (List of String)
* `title` (String)
* `token` (String)
* `workspace_token` (String)
# vantage_scenario_models (Data Source)
Source: https://docs.vantage.sh/terraform_docs/data_sources/scenario_models
Terraform data source reference for vantage_scenario_models (Data Source). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this data source with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Example Usage
```terraform theme={null}
data "vantage_scenario_models" "demo" {}
```
## Schema
### Read-Only
* `scenario_models` (Attributes List) (see [below for nested schema](#nestedatt--scenario_models))
### Nested Schema for `scenario_models`
Read-Only:
* `cloud_provider` (String) The cloud provider filter for the ScenarioModel.
* `created_at` (String)
* `created_by_token` (String)
* `id` (String) The id of the resource
* `periods` (Attributes List) (see [below for nested schema](#nestedatt--scenario_models--periods))
* `priority` (Number)
* `service` (String)
* `title` (String)
* `token` (String)
* `updated_at` (String)
* `workspace_token` (String)
### Nested Schema for `scenario_models.periods`
Read-Only:
* `amount` (String) The period amount as a string to preserve decimal precision.
* `amount_type` (String) Whether the amount is in dollars or percent.
* `end_at` (String) The ISO 8601 end date of the period.
* `start_at` (String) The ISO 8601 start date of the period.
# vantage_teams (Data Source)
Source: https://docs.vantage.sh/terraform_docs/data_sources/teams
Terraform data source reference for vantage_teams (Data Source). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this data source with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Schema
### Read-Only
* `teams` (Attributes List) (see [below for nested schema](#nestedatt--teams))
### Nested Schema for `teams`
Read-Only:
* `default_dashboard_token` (String)
* `description` (String)
* `name` (String)
* `token` (String)
* `user_emails` (Set of String)
* `user_tokens` (Set of String)
* `workspace_tokens` (Set of String)
# vantage_users (Data Source)
Source: https://docs.vantage.sh/terraform_docs/data_sources/users
Terraform data source reference for vantage_users (Data Source). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this data source with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Schema
### Read-Only
* `users` (Attributes List) (see [below for nested schema](#nestedatt--users))
### Nested Schema for `users`
Read-Only:
* `email` (String)
* `name` (String)
* `role` (String)
* `token` (String)
# vantage_virtual_tag_configs (Data Source)
Source: https://docs.vantage.sh/terraform_docs/data_sources/virtual_tag_configs
Terraform data source reference for vantage_virtual_tag_configs (Data Source). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this data source with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Schema
### Read-Only
* `virtual_tag_configs` (Attributes List) (see [below for nested schema](#nestedatt--virtual_tag_configs))
### Nested Schema for `virtual_tag_configs`
Read-Only:
* `backfill_until` (String) The earliest month VirtualTagConfig should be backfilled to.
* `collapsed_tag_keys` (Attributes List) Tag keys to collapse values for. (see [below for nested schema](#nestedatt--virtual_tag_configs--collapsed_tag_keys))
* `created_by_token` (String) The token of the Creator of the VirtualTagConfig.
* `hidden` (Boolean) Whether the VirtualTagConfig key is hidden from the Vantage UI.
* `id` (String) The id of the VirtualTagConfig.
* `key` (String) The key of the VirtualTagConfig.
* `overridable` (Boolean) Whether the VirtualTagConfig can override a provider-supplied tag on a matching Cost.
* `preferred` (Boolean) Whether the VirtualTagConfig key is marked as preferred in the Vantage UI.
* `token` (String) The token of the VirtualTagConfig.
* `values` (Attributes List) Values for the VirtualTagConfig, with match precedence determined by their relative order in the list. (see [below for nested schema](#nestedatt--virtual_tag_configs--values))
### Nested Schema for `virtual_tag_configs.collapsed_tag_keys`
Read-Only:
* `filter` (String) The VQL filter this collapsed tag key applies to. Null when the key is provider-scoped or unset.
* `key` (String) The tag key to collapse values for.
* `providers` (List of String) The providers this collapsed tag key applies to. Empty when it applies to all providers.
### Nested Schema for `virtual_tag_configs.values`
Read-Only:
* `business_metric_token` (String) The token of the associated BusinessMetric.
* `cost_metric` (Attributes) (see [below for nested schema](#nestedatt--virtual_tag_configs--values--cost_metric))
* `date_ranges` (Attributes List) Date ranges restricting when this value applies. (see [below for nested schema](#nestedatt--virtual_tag_configs--values--date_ranges))
* `display_name` (String) The display name for this allocation value.
* `filter` (String) The filter VQL for the Value.
* `label_key` (String) The business metric label key used for this virtual tag value.
* `label_transforms` (Attributes List) Label transforms applied to business metric labels. (see [below for nested schema](#nestedatt--virtual_tag_configs--values--label_transforms))
* `label_values` (List of String) Optional business metric label values. An empty array includes every value for the label key.
* `name` (String) The name of the Value.
* `percentages` (Attributes List) Labeled percentage allocations for matching costs. (see [below for nested schema](#nestedatt--virtual_tag_configs--values--percentages))
* `token` (String) The token of the Value.
### Nested Schema for `virtual_tag_configs.values.cost_metric`
Read-Only:
* `aggregation` (Attributes) (see [below for nested schema](#nestedatt--virtual_tag_configs--values--cost_metric--aggregation))
* `filter` (String) The filter VQL for the cost metric.
### Nested Schema for `virtual_tag_configs.values.cost_metric.aggregation`
Read-Only:
* `tag` (String) The tag to aggregate on.
### Nested Schema for `virtual_tag_configs.values.date_ranges`
Read-Only:
* `end_date` (String) The end date of the range (inclusive), or null for unbounded.
* `start_date` (String) The start date of the range (inclusive), or null for unbounded.
### Nested Schema for `virtual_tag_configs.values.label_transforms`
Read-Only:
* `delimiter` (String) Delimiter used by split transforms.
* `index` (Number) Zero-based index used by split transforms.
* `template` (String) Template used by format transforms.
* `type` (String) The label transform type.
### Nested Schema for `virtual_tag_configs.values.percentages`
Read-Only:
* `pct` (Number) The percentage of matched costs associated with the value.
* `value` (String) The tag value associated with a percentage of matched costs.
# vantage_workspace (Data Source)
Source: https://docs.vantage.sh/terraform_docs/data_sources/workspace
Terraform data source reference for vantage_workspace (Data Source). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this data source with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
Looks up a workspace by name and returns its token.
## Schema
### Required
* `name` (String) The name of the workspace to find.
### Read-Only
* `token` (String) The unique token of the matched workspace.
# vantage_workspaces (Data Source)
Source: https://docs.vantage.sh/terraform_docs/data_sources/workspaces
Terraform data source reference for vantage_workspaces (Data Source). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this data source with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Schema
### Read-Only
* `workspaces` (Attributes List) (see [below for nested schema](#nestedatt--workspaces))
### Nested Schema for `workspaces`
Read-Only:
* `name` (String)
* `token` (String)
# vantage Provider
Source: https://docs.vantage.sh/terraform_docs/index
Terraform provider reference for vantage Provider. Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
This page documents the configuration schema for the Vantage Terraform provider. For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Example Usage
```terraform theme={null}
terraform {
required_providers {
vantage = {
source = "vantage-sh/vantage"
}
}
}
provider "vantage" {
# This can also be configured with the `VANTAGE_API_TOKEN` environment variable
# and this block removed entirely:
# export VANTAGE_API_TOKEN=an-api-token
# terraform plan
api_token = var.api_token
}
resource "vantage_folder" "aws" {
title = "AWS Costs"
}
resource "vantage_cost_report" "aws" {
folder_token = vantage_folder.aws.token
filter = "costs.provider = 'aws'"
title = "AWS Costs"
}
```
## Schema
### Optional
* `api_token` (String, Sensitive)
* `host` (String)
* `timeout` (String) The timeout duration for API requests (e.g., "30s", "5m"). Defaults to "30s".
# vantage_access_grant (Resource)
Source: https://docs.vantage.sh/terraform_docs/resources/access_grant
Terraform resource reference for vantage_access_grant (Resource). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this resource with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
Manages an AccessGrant.
## Example Usage
```terraform theme={null}
resource "vantage_access_grant" "demo_access_grant" {
team_token = "team_bd5c2d8abc233bfd"
resource_token = "rprt_39d256c871cb6b2b"
}
```
## Schema
### Required
* `resource_token` (String) Token of the resource being granted.
* `team_token` (String) Token of the team being granted.
### Optional
* `access` (String) Access level of the grant. Must be either `allowed` or `denied`.
### Read-Only
* `id` (String) Id of the access grant.
* `token` (String) Token of the access grant.
# vantage_access_policy (Resource)
Source: https://docs.vantage.sh/terraform_docs/resources/access_policy
Terraform resource reference for vantage_access_policy (Resource). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this resource with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
Manages an Access Policy.
## Example Usage
```terraform theme={null}
resource "vantage_access_policy" "demo_access_policy" {
title = "Engineering costs"
description = "Limits cost visibility to the Engineering team."
team_tokens = [vantage_team.demo_team.token]
policy = {
api_version = "v1"
filter = "(vantage.provider = 'aws')"
}
}
```
## Schema
### Required
* `policy` (Attributes) Access Policy definition using vantage.\* VQL. (see [below for nested schema](#nestedatt--policy))
* `title` (String) Title of the Access Policy.
### Optional
* `description` (String) Description of the Access Policy.
* `team_tokens` (List of String) Tokens for Teams this Access Policy is assigned to.
### Read-Only
* `id` (String) Same as token, for Terraform import compatibility.
* `token` (String) Unique Access Policy identifier.
### Nested Schema for `policy`
Required:
* `api_version` (String) Access Policy document version. Currently only `v1` is supported.
* `filter` (String) Vantage Query Language (VQL) that controls which costs this Access Policy allows.
# vantage_anomaly_notification (Resource)
Source: https://docs.vantage.sh/terraform_docs/resources/anomaly_notification
Terraform resource reference for vantage_anomaly_notification (Resource). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this resource with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Example Usage
```terraform theme={null}
resource "vantage_anomaly_notification" "demo_anomaly_notification" {
cost_report_token = "rpt_47c3254c790e9351"
threshold = 10
recipient_channels = ["#alerts"]
}
```
## Schema
### Required
* `cost_report_token` (String) The token of the Cost Report that has the notification.
### Optional
* `recipient_channels` (List of String) The Slack/MS Teams channels that receive the notification.
* `threshold` (Number) The threshold amount that must be met for the notification to fire.
* `user_tokens` (List of String) The tokens of the Users that receive the notification.
### Read-Only
* `created_at` (String) The date and time, in UTC, the AnomalyNotification was created. ISO 8601 Formatted.
* `id` (String) The id of the report alert
* `token` (String) The token of the AnomalyNotification
* `updated_at` (String) The date and time, in UTC, the AnomalyNotification was last updated at. ISO 8601 Formatted.
# vantage_aws_provider (Resource)
Source: https://docs.vantage.sh/terraform_docs/resources/aws_provider
Terraform resource reference for vantage_aws_provider (Resource). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this resource with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
Manages an AWS Account Integration.
## Schema
### Required
* `cross_account_arn` (String) ARN to use for cross account access.
### Optional
* `bucket_arn` (String) Bucket ARN for where CUR data is being stored.
### Read-Only
* `id` (Number) Service generated identifier for the the account access.
# vantage_billing_profile (Resource)
Source: https://docs.vantage.sh/terraform_docs/resources/billing_profile
Terraform resource reference for vantage_billing_profile (Resource). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this resource with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Example Usage
```terraform theme={null}
# Fetch all billing profiles
data "vantage_billing_profiles" "all_profiles" {}
# Basic billing profile with minimal configuration
resource "vantage_billing_profile" "basic_profile" {
nickname = "Basic Company Profile Test"
}
# Billing profile with nested billing information attributes
resource "vantage_billing_profile" "complete_profile_nested" {
nickname = "Complete Company Profile Testng"
billing_information_attributes = {
company_name = "Example Corp"
address_line_1 = "123 Business Ave"
address_line_2 = "Suite 100"
city = "New York"
state = "NY"
postal_code = "10001"
country_code = "US"
billing_email = ["billing@example.com"]
}
banking_information_attributes = {
beneficiary_name = "John Doe"
bank_name = "Example Bank"
}
business_information_attributes = {
metadata = {
custom_fields = [
{
name = "VAT"
value = "123456789"
}
]
}
}
}
```
## Schema
### Required
* `nickname` (String) Display name for the billing profile
### Optional
* `banking_information_attributes` (Attributes) Banking details (MSP accounts only) (see [below for nested schema](#nestedatt--banking_information_attributes))
* `billing_information_attributes` (Attributes) Billing address and contact information (see [below for nested schema](#nestedatt--billing_information_attributes))
* `business_information_attributes` (Attributes) Business information and custom fields (see [below for nested schema](#nestedatt--business_information_attributes))
* `invoice_adjustment_attributes` (Attributes) Invoice adjustments (taxes, fees, etc.) (see [below for nested schema](#nestedatt--invoice_adjustment_attributes))
### Read-Only
* `created_at` (String) The date and time, in UTC, the billing profile was created. ISO 8601 formatted.
* `id` (String) The id of the billing profile
* `managed_accounts_count` (String) Number of managed accounts using this billing profile
* `token` (String) The token of the billing profile
* `updated_at` (String) The date and time, in UTC, the billing profile was last updated. ISO 8601 formatted.
### Nested Schema for `banking_information_attributes`
Optional:
* `bank_name` (String) Name of the bank
* `beneficiary_name` (String) Name of the account beneficiary
* `secure_data` (Attributes) Encrypted banking details (see [below for nested schema](#nestedatt--banking_information_attributes--secure_data))
* `tax_id` (String) Tax identification number
* `token` (String)
### Nested Schema for `banking_information_attributes.secure_data`
Optional:
* `account_number` (String) Bank account number (US)
* `iban` (String) International Bank Account Number (EU)
* `routing_number` (String) Bank routing number (US)
* `swift_bic` (String) SWIFT/BIC code (EU)
### Nested Schema for `billing_information_attributes`
Optional:
* `address_line_1` (String) First line of billing address
* `address_line_2` (String) Second line of billing address
* `billing_email` (List of String) Array of billing email addresses
* `city` (String) City for billing address
* `company_name` (String) Company name for billing
* `country_code` (String) ISO country code
* `postal_code` (String) Postal or ZIP code
* `state` (String) State or province for billing address
* `token` (String)
### Nested Schema for `business_information_attributes`
Optional:
* `metadata` (Attributes) Business metadata including custom fields (see [below for nested schema](#nestedatt--business_information_attributes--metadata))
* `token` (String)
### Nested Schema for `business_information_attributes.metadata`
Optional:
* `custom_fields` (Attributes List) Array of custom field objects (see [below for nested schema](#nestedatt--business_information_attributes--metadata--custom_fields))
### Nested Schema for `business_information_attributes.metadata.custom_fields`
Optional:
* `name` (String) Custom field name
* `value` (String) Custom field value
### Nested Schema for `invoice_adjustment_attributes`
Optional:
* `adjustment_items` (Attributes List) Array of adjustment items (see [below for nested schema](#nestedatt--invoice_adjustment_attributes--adjustment_items))
* `token` (String)
### Nested Schema for `invoice_adjustment_attributes.adjustment_items`
Required:
* `amount` (Number) Amount or percentage value
* `calculation_type` (String) How the adjustment is calculated
* `name` (String) Name of the adjustment
Optional:
* `adjustment_type` (String) Type of adjustment
# vantage_billing_rule (Resource)
Source: https://docs.vantage.sh/terraform_docs/resources/billing_rule
Terraform resource reference for vantage_billing_rule (Resource). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this resource with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Schema
### Required
* `title` (String) The title of the BillingRule.
* `type` (String) The type of the BillingRule. Note: the values are case insensitive.
### Optional
* `amount` (Number) The amount for the BillingRule. Required for Charge and Credit rules. Example value: 300
* `apply_to_all` (Boolean) Determines if the BillingRule applies to all current and future managed accounts.
* `category` (String) The category of the BillingRule. Required for Charge and Credit rules.
* `charge_type` (String) The charge type of the BillingRule. Required for Exclusion rules.
* `end_date` (String) The end date of the BillingRule. ISO 8601 formatted.
* `percentage` (Number) The percentage of the cost shown. Required for Adjustment rules. Example value: 75.0
* `service` (String) The service of the BillingRule. Required for Charge and Credit rules.
* `sql_query` (String) The SQL query for the BillingRule. Required for Custom rules. Example value: UPDATE costs SET costs.amount = costs.amount \* 0.95
* `start_date` (String) The start date of the BillingRule. ISO 8601 formatted.
* `start_period` (String) The start period of the BillingRule. DEPRECATED: use start\_date instead.
* `sub_category` (String) The subcategory of the BillingRule. Required for Charge and Credit rules.
### Read-Only
* `created_at` (String) The date and time, in UTC, the BillingRule was created. ISO 8601 Formatted.
* `created_by_token` (String) The token of the Creator of the BillingRule.
* `id` (String) The id of the billing rule
* `token` (String) The token of the billing rule
# vantage_budget (Resource)
Source: https://docs.vantage.sh/terraform_docs/resources/budget
Terraform resource reference for vantage_budget (Resource). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this resource with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Example Usage
```terraform theme={null}
resource "vantage_budget" "demo_budget" {
name = "Demo Budget"
cost_report_token = vantage_cost_report.demo_report.token
period_cadence = {
starts_at = "2024-01-22"
interval_count = 2
interval_unit = "week"
}
periods = [
{
start_at = "2024-01-22"
end_at = "2024-02-04"
amount = 100
}
]
}
```
## Schema
### Required
* `name` (String) The name of the Budget.
### Optional
* `child_budget_tokens` (List of String) The tokens of any child Budgets when creating a hierarchical Budget. Child budgets must share the same current period dates.
* `cost_report_token` (String) The CostReport token. Ignored for hierarchical Budgets.
* `period_cadence` (Attributes) The interval cadence for standard Budget periods. Requires the `flexible_budget_periods` feature. Changing a configured cadence replaces the Budget; removing the block stops managing it but does not clear the API cadence. (see [below for nested schema](#nestedatt--period_cadence))
* `periods` (Attributes List) The periods for the Budget. The start\_at and end\_at must be iso8601 formatted e.g. YYYY-MM-DD. Ignored for hierarchical Budgets. (see [below for nested schema](#nestedatt--periods))
* `type` (String) The type of Budget. One of: cost, usage.
* `unit` (String) The usage unit for usage Budgets.
* `workspace_token` (String) The token of the Workspace to add the Budget to.
### Read-Only
* `budget_alert_tokens` (List of String) The tokens of the BudgetAlerts associated with the Budget.
* `created_at` (String) The date and time, in UTC, the Budget was created. ISO 8601 Formatted.
* `created_by_token` (String) The token of the Creator of the Budget.
* `id` (String) The id of the budget
* `performance` (Attributes List) The historical performance of the Budget. (see [below for nested schema](#nestedatt--performance))
* `token` (String) The token of the budget
* `user_token` (String) The token for the User who created this Budget.
### Nested Schema for `period_cadence`
Optional:
* `interval_count` (Number) The number of interval units per budget period.
* `interval_unit` (String) The unit for budget period intervals. One of: day, week, month, year.
* `starts_at` (String) The required anchor date for configured budget period intervals. ISO 8601 date (`YYYY-MM-DD`).
### Nested Schema for `periods`
Required:
* `amount` (Number) The amount of the period.
* `start_at` (String) The start date of the period.
Optional:
* `end_at` (String) The end date of the period.
### Nested Schema for `performance`
Read-Only:
* `actual` (String) The date and time, in UTC, the Budget was created. ISO 8601 Formatted.
* `amount` (String) The amount of the Budget Period as a string to ensure precision.
* `date` (String) The date and time, in UTC, the Budget was created. ISO 8601 Formatted.
# vantage_budget_alert (Resource)
Source: https://docs.vantage.sh/terraform_docs/resources/budget_alert
Terraform resource reference for vantage_budget_alert (Resource). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this resource with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Example Usage
```terraform theme={null}
resource "vantage_budget_alert" "demo_budget_alert" {
workspace_token = "wrkspc_47c3254c790e9351"
budget_tokens = [vantage_budget.demo_budget.token]
threshold = 90
# Days from the start or end of the month to evaluate. Use "" for the full month.
duration_in_days = "7"
period_to_track = "start_of_the_month"
# Organization users or addresses on a verified domain.
recipient_emails = ["finops@example.com"]
}
```
## Schema
### Required
* `budget_tokens` (List of String) The tokens of the Budget that has the alert.
* `duration_in_days` (String) The number of days from the start or end of the month to trigger the alert if the threshold is reached. Use `""` for the full month. This write attribute is a string because the API uses an empty-string sentinel; the `vantage_budget_alerts` data source returns the API's nullable integer response.
* `threshold` (Number) The threshold amount that must be met for the alert to fire.
### Optional
* `period_to_track` (String) The period tracked on the alert. Used with duration\_in\_days to determine the time window of the alert. Defaults to start\_of\_the\_month if not passed. Possible values: start\_of\_the\_month, end\_of\_the\_month.
* `recipient_channels` (List of String) The channels receiving the alerts. Requires an integration provider to be connected. At least one recipient list must resolve to a non-empty value when the alert is created.
* `recipient_emails` (List of String) The complete list of email addresses that receive the alert, including addresses derived from user\_tokens and freeform addresses on verified domains. At least one recipient list must resolve to a non-empty value when the alert is created.
* `user_tokens` (List of String) The tokens of organization users that receive the alert. The API also exposes their addresses in recipient\_emails; freeform verified-domain addresses appear only in recipient\_emails. At least one recipient list must resolve to a non-empty value when the alert is created.
* `workspace_token` (String) The token of the Workspace to add the BudgetAlert to. Required if the API token is associated with multiple Workspaces.
### Read-Only
* `created_at` (String) The date and time, in UTC, the Budget Alert was created. ISO 8601 Formatted.
* `id` (String) The id of the budget alert
* `integration_provider` (String) The provider used for sending alerts. This must be configured in the console. Possible values are: slack, microsoft\_graph.
* `token` (String) The token of the budget alert
* `user_token` (String) The token for the User who created this BudgetAlert.
# vantage_business_metric (Resource)
Source: https://docs.vantage.sh/terraform_docs/resources/business_metric
Terraform resource reference for vantage_business_metric (Resource). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this resource with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Schema
### Required
* `title` (String) The title of the BusinessMetrics.
### Optional
* `clickhouse_metric_fields` (Attributes) ClickHouse metric configuration fields. Changing this block replaces the business metric. (see [below for nested schema](#nestedatt--clickhouse_metric_fields))
* `cloudwatch_fields` (Attributes) Cloudwatch configuration fields. (see [below for nested schema](#nestedatt--cloudwatch_fields))
* `cost_report_tokens_with_metadata` (Attributes List) The tokens for any CostReports that use the BusinessMetric, the unit scale, and label filter. (see [below for nested schema](#nestedatt--cost_report_tokens_with_metadata))
* `datadog_metric_fields` (Attributes) Datadog metric configuration fields (see [below for nested schema](#nestedatt--datadog_metric_fields))
* `forecasted_values` (Attributes List) The dates, amounts, and (optional) labels for forecasted BusinessMetric values. (see [below for nested schema](#nestedatt--forecasted_values))
* `gcp_bigquery_metric_fields` (Attributes) GCP BigQuery metric configuration fields. Changing this block replaces the business metric. (see [below for nested schema](#nestedatt--gcp_bigquery_metric_fields))
* `snowflake_metric_fields` (Attributes) Snowflake metric configuration fields. (see [below for nested schema](#nestedatt--snowflake_metric_fields))
* `values` (Attributes List) The dates, amounts, and (optional) labels for the BusinessMetric. (see [below for nested schema](#nestedatt--values))
### Read-Only
* `created_by_token` (String) The token of the Creator of the BusinessMetric.
* `id` (String) The id of the business metric
* `import_type` (String) The type of import for the BusinessMetric.
* `integration_token` (String) The Integration token used to import the BusinessMetric.
* `token` (String) The token of the business metric
### Nested Schema for `clickhouse_metric_fields`
Optional:
* `integration_token` (String) Integration token for the ClickHouse integration from which you would like to fetch metrics.
* `query_endpoint_id` (String) UUID of the ClickHouse query endpoint used to fetch metrics.
### Nested Schema for `cloudwatch_fields`
Optional:
* `dimensions` (Attributes List) The dimensions used to pull specific statistical data for Cloudwatch metrics. (see [below for nested schema](#nestedatt--cloudwatch_fields--dimensions))
* `integration_token` (String) Integration token for the account from which you would like to fetch metrics.
* `label_dimension` (String) The dimension used to aggregate the Cloudwatch metrics.
* `metric_name` (String) The metric name used to import Cloudwatch metrics.
* `namespace` (String) The namespace used to import Cloudwatch metrics.
* `region` (String) The region used to import Cloudwatch metrics.
* `stat` (String) The time aggregation function used to import Cloudwatch metrics.
### Nested Schema for `cloudwatch_fields.dimensions`
Optional:
* `name` (String)
* `value` (String)
### Nested Schema for `cost_report_tokens_with_metadata`
Required:
* `cost_report_token` (String) The token of the CostReport the BusinessMetric is attached to.
Optional:
* `calculation_type` (String) The calculation type applied when this BusinessMetric is used in the CostReport.
* `label` (String) Optional custom display name for this BusinessMetric on the CostReport. When omitted, a default is derived from the calculation type.
* `label_filter` (List of String) Include only values with these labels in the CostReport.
* `label_filters` (Map of List of String) Include only ClickHouse BusinessMetric values matching every label key and one of its values.
* `unit_scale` (String) Determines the scale of the BusinessMetric's values within the CostReport.
### Nested Schema for `datadog_metric_fields`
Optional:
* `integration_token` (String) Integration token for the account from which you would like to fetch metrics.
* `query` (String) Datadog metrics query string. e.g. `sum:aws.applicationelb.request_count{region:us-east-1}.rollup(avg,daily)`
### Nested Schema for `forecasted_values`
Required:
* `amount` (Number)
* `date` (String)
Optional:
* `label` (String)
### Nested Schema for `gcp_bigquery_metric_fields`
Optional:
* `integration_token` (String) Integration token for the GCP integration from which you would like to fetch metrics.
* `query_project_id` (String) GCP project in which the BigQuery job should run.
* `sql_query` (String) BigQuery SQL query returning date, value, and optional label columns.
### Nested Schema for `snowflake_metric_fields`
Optional:
* `integration_token` (String) Integration token for the Snowflake integration from which you would like to fetch metrics.
* `sql_query` (String) Snowflake SQL query returning date, value, and optional label columns.
### Nested Schema for `values`
Required:
* `amount` (Number)
* `date` (String)
Optional:
* `label` (String)
# vantage_canvas (Resource)
Source: https://docs.vantage.sh/terraform_docs/resources/canvas
Terraform resource reference for vantage_canvas (Resource). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this resource with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
Manages a Canvas.
## Example Usage
```terraform theme={null}
data "vantage_workspaces" "demo" {}
resource "vantage_canvas" "demo" {
title = "Monthly Cost Overview"
prompt = "Show me monthly costs by provider"
workspace_token = element(data.vantage_workspaces.demo.workspaces, 0).token
}
```
## Schema
### Required
* `prompt` (String) The prompt used to generate the Canvas.
* `title` (String) The title of the Canvas.
### Optional
* `workspace_token` (String) The token of the Workspace to add the Canvas to. Required if the API token is associated with multiple Workspaces.
### Read-Only
* `created_at` (String) The date and time, in UTC, the Canvas was created. ISO 8601 Formatted.
* `data` (Attributes) The structured table data of the Canvas. (see [below for nested schema](#nestedatt--data))
* `id` (String) The id of the canvas
* `token` (String) The token of the canvas
* `updated_at` (String) The date and time, in UTC, the Canvas was last updated. ISO 8601 Formatted.
### Nested Schema for `data`
Read-Only:
* `error` (String) Error message if the refresh workflow failed.
* `table` (String) JSON-encoded tabular data produced by the Canvas refresh workflow.
# vantage_cost_alert (Resource)
Source: https://docs.vantage.sh/terraform_docs/resources/cost_alert
Terraform resource reference for vantage_cost_alert (Resource). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this resource with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Schema
### Required
* `interval` (String) The period of time used to compare costs. Options are 'day', 'week', 'month', 'quarter'.
* `report_tokens` (List of String) The tokens of the reports to alert on.
* `threshold` (Number) The threshold value for the Cost Alert.
* `title` (String) The title of the Cost Alert.
* `unit_type` (String) The unit type used to compare costs. Options are 'currency' or 'percentage'.
* `workspace_token` (String) The token of the Workspace to add the Cost Alert to.
### Optional
* `email_recipients` (List of String) The email recipients for the Cost Alert.
* `minimum_threshold` (Number) The minimum monetary amount threshold for percentage-based alerts. Only applicable when unit\_type is 'percentage'.
* `slack_channels` (List of String) The Slack channels that will receive the alert.
* `teams_channels` (List of String) The Microsoft Teams channels that will receive the alert.
### Read-Only
* `created_at` (String) The date and time, in UTC, for when the alert was created. ISO 8601 Formatted.
* `id` (String) The id of the cost alert
* `token` (String) The token of the cost alert
* `updated_at` (String) The date and time, in UTC, for when the alert was last updated. ISO 8601 Formatted.
# vantage_cost_report (Resource)
Source: https://docs.vantage.sh/terraform_docs/resources/cost_report
Terraform resource reference for vantage_cost_report (Resource). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this resource with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
Manages a CostReport.
## Example Usage
```terraform theme={null}
resource "vantage_cost_report" "demo_report" {
title = "Demo Report"
folder_token = "fldr_3555785cd0409118"
filter = "costs.provider = 'aws'"
saved_filter_tokens = ["svd_fltr_e844a2ccace05933", "svd_fltr_1b4b80a380ef4ba2"]
workspace_token = "wrkspc_47c3254c790e9351"
chart_type = "line" # Allowed: area, line, pie, bar, multi-bar
date_bin = "day" # Allowed: cumulative, day, week, month, quarter
settings = {
include_credits = true
include_refunds = true
include_discounts = true
include_tax = true
amortize = false
unallocated = false
aggregate_by = "cost" # Allowed: cost, usage, count
show_previous_period = false
}
# optionally, use folder_token instead of workspace_token
# folder_token = "fldr_47c3254c790e9351"
}
```
## Schema
### Required
* `title` (String) The title of the CostReport.
### Optional
* `business_metric_tokens_with_metadata` (Attributes List) The tokens for any BusinessMetrics to attach to the CostReport, and the unit scale. (see [below for nested schema](#nestedatt--business_metric_tokens_with_metadata))
* `chart_settings` (Attributes) Report chart settings. (see [below for nested schema](#nestedatt--chart_settings))
* `chart_type` (String) The chart type of the CostReport.
* `date_bin` (String) The date bin of the CostReport.
* `date_interval` (String) The date interval of the CostReport. Incompatible with 'start\_date' and 'end\_date' parameters. Defaults to 'this\_month' if start\_date and end\_date are not provided.
* `default_forecast` (Attributes) (see [below for nested schema](#nestedatt--default_forecast))
* `end_date` (String) The end date of the CostReport. ISO 8601 Formatted. Required when start\_date is provided. Incompatible with 'date\_interval' parameter.
* `filter` (String) The filter query language to apply to the CostReport. Additional documentation available at [https://docs.vantage.sh/vql](https://docs.vantage.sh/vql).
* `folder_token` (String) The token of the Folder to add the CostReport to. Determines the Workspace the report is assigned to.
* `groupings` (String) Grouping values for aggregating costs on the report. Valid groupings: account\_id, billing\_account\_id, charge\_type, cost\_category, cost\_subcategory, provider, region, resource\_id, service, tagged, usage\_unit, `tag:`. If providing multiple groupings, join as comma separated values: groupings=provider,service,region
* `previous_period_end_date` (String) The previous period end date of the CostReport. ISO 8601 Formatted. Required when previous\_period\_start\_date is provided.
* `previous_period_start_date` (String) The previous period start date of the CostReport. ISO 8601 Formatted.
* `saved_filter_tokens` (List of String) The tokens of the SavedFilters to apply to the CostReport.
* `settings` (Attributes) Report settings. (see [below for nested schema](#nestedatt--settings))
* `start_date` (String) The start date of the CostReport. ISO 8601 Formatted. Incompatible with 'date\_interval' parameter.
* `workspace_token` (String) The token of the Workspace to add the Cost Report to. Ignored if 'folder\_token' is set. Required if the API token is associated with multiple Workspaces.
### Read-Only
* `created_at` (String) The date and time, in UTC, the report was created. ISO 8601 Formatted.
* `id` (String) The id of the cost report
* `token` (String) The token of the cost report
### Nested Schema for `business_metric_tokens_with_metadata`
Required:
* `business_metric_token` (String) The token of the BusinessMetric to attach to the CostReport.
Optional:
* `calculation_type` (String) The calculation type applied when this BusinessMetric is used in the CostReport.
* `label` (String) Optional custom display name for this BusinessMetric on the CostReport. When omitted, a default is derived from the calculation type.
* `label_filter` (List of String) Include only values with these labels in the CostReport.
* `label_filters` (Map of List of String) Include only ClickHouse BusinessMetric values matching every label key and one of its values.
* `unit_scale` (String) Determines the scale of the BusinessMetric's values within the CostReport.
### Nested Schema for `chart_settings`
Optional:
* `x_axis_dimension` (List of String) The dimension used to group or label data along the x-axis (e.g., by date, region, or service). NOTE: Only one value is allowed at this time. Defaults to \['date'].
* `y_axis_dimension` (String) The metric or measure displayed on the chart's y-axis. Possible values: 'cost', 'usage', 'count'. Defaults to 'cost'.
### Nested Schema for `default_forecast`
Required:
* `kind` (String) The default forecast selection kind.
Optional:
* `report_forecast_token` (String) The token for the report forecast selected as the default.
### Nested Schema for `settings`
Optional:
* `aggregate_by` (String) Report will aggregate by cost, usage, or count.
* `amortize` (Boolean) Report will amortize.
* `complete_period` (Boolean) Report will restrict date ranges to completed periods only.
* `include_credits` (Boolean) Report will include credits.
* `include_discounts` (Boolean) Report will include discounts.
* `include_refunds` (Boolean) Report will include refunds.
* `include_tax` (Boolean) Report will include tax.
* `show_previous_period` (Boolean) Report will show previous period cost, usage, or count comparison.
* `unallocated` (Boolean) Report will show unallocated costs.
# vantage_custom_provider (Resource)
Source: https://docs.vantage.sh/terraform_docs/resources/custom_provider
Terraform resource reference for vantage_custom_provider (Resource). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this resource with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
Manages a Custom Provider integration.
## Example Usage
```terraform theme={null}
resource "vantage_custom_provider" "example" {
name = "My Custom Provider"
description = "An optional description for this provider"
}
```
## Schema
### Required
* `name` (String) The display name for the custom provider. Cannot be changed after creation.
### Optional
* `description` (String) A description for the custom provider. Cannot be changed after creation.
* `workspaces` (Set of String) Workspace tokens to associate with the integration. Can be updated in-place. Note: the Vantage API requires at least one token — workspace associations cannot be fully removed once set.
### Read-Only
* `id` (String) Same as token.
* `status` (String) The status of the integration. This is system-managed and cannot be configured.
* `token` (String) Unique token of the custom provider integration.
# vantage_custom_provider_costs_upload (Resource)
Source: https://docs.vantage.sh/terraform_docs/resources/custom_provider_costs_upload
Terraform resource reference for vantage_custom_provider_costs_upload (Resource). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this resource with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
Uploads a CSV of costs for a Custom Provider integration.
## Example Usage
```terraform theme={null}
resource "vantage_custom_provider" "example" {
name = "My Custom Provider"
}
resource "vantage_custom_provider_costs_upload" "example" {
integration_token = vantage_custom_provider.example.token
csv_content = file("${path.module}/costs.csv")
auto_transform = true
}
```
## Schema
### Required
* `csv_content` (String, Sensitive) CSV content to upload as costs data.
* `integration_token` (String) The token of the Custom Provider integration to upload costs for.
### Optional
* `auto_transform` (Boolean) When true, attempts to automatically transform the CSV to match the FOCUS format.
* `filename` (String) Filename to use when uploading the CSV. Defaults to `costs.csv`. The API records this name and returns it in the `filename` attribute after upload. Changing this value forces a new upload.
### Read-Only
* `amount` (String) The total amount of costs in the upload.
* `end_date` (String) The end date of the costs in the upload.
* `id` (String) Same as token.
* `import_status` (String) The import status of the upload (e.g. processing, complete, error).
* `start_date` (String) The start date of the costs in the upload.
* `token` (String) Unique token of the costs upload.
# vantage_dashboard (Resource)
Source: https://docs.vantage.sh/terraform_docs/resources/dashboard
Terraform resource reference for vantage_dashboard (Resource). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this resource with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Example Usage
```terraform theme={null}
resource "vantage_dashboard" "demo_dashboard" {
title = "Demo Dashboard"
date_interval = "last_month"
widgets = [
{
settings = {
display_type = "chart"
grid = {
x = 0
y = 0
w = 6
h = 4
}
}
widgetable_token = "rprt_a2846903070824f4"
},
{
settings = {
display_type = "kpi"
kpi_calculation = "sum"
kpi_type = "cost"
grid = {
x = 6
y = 0
w = 6
h = 4
}
}
title = "Total Spend"
widgetable_token = "rprt_a2846903070824f4"
},
{
title = "Notes"
widgetable_type = "free_text"
content = jsonencode({
type = "doc"
content = [
{
type = "paragraph"
content = [
{
type = "text"
text = "Use free text widgets for dashboard context."
}
]
}
]
})
}
]
workspace_token = "wrkspc_47c3254c790e9351"
}
```
## Schema
### Optional
* `date_bin` (String) Determines how to group costs in the Dashboard.
* `date_interval` (String) Determines the date range in the Dashboard. Incompatible with 'start\_date' and 'end\_date' parameters.
* `end_date` (String) The end date for the date range for costs in the Dashboard. ISO 8601 Formatted. Incompatible with 'date\_interval' parameter.
* `saved_filter_tokens` (List of String) The tokens of the Saved Filters used in the Dashboard.
* `start_date` (String) The start date for the date range for costs in the Dashboard. ISO 8601 Formatted. Incompatible with 'date\_interval' parameter.
* `title` (String) The title of the Dashboard.
* `widgets` (Attributes List) The widgets to add to the Dashboard. Report-backed widgets use widgetable\_token. Free text widgets use widgetable\_type set to free\_text and require content. (see [below for nested schema](#nestedatt--widgets))
* `workspace_token` (String) The token of the Workspace to add the Dashboard to. Required if the API token is associated with multiple Workspaces.
### Read-Only
* `created_at` (String) The date and time, in UTC, the Dashboard was created. ISO 8601 Formatted.
* `id` (String) The id of the dashboard
* `token` (String) The token of the dashboard
### Nested Schema for `widgets`
Optional:
* `content` (String) JSON-encoded TipTap document for a free text widget. Example: `{"type":"doc","content":[...]}`
* `settings` (Attributes) The display and grid layout settings for the DashboardWidget. (see [below for nested schema](#nestedatt--widgets--settings))
* `title` (String) The title of the Widget (defaults to the Resource title, or Free Text for a free text widget).
* `widgetable_token` (String) The token of the represented Resource.
* `widgetable_type` (String) The widget type. Use free\_text for a free text widget.
Read-Only:
* `token` (String) The token of the Dashboard Widget.
### Nested Schema for `widgets.settings`
Required:
* `display_type` (String)
Optional:
* `grid` (Attributes) The widget's size and position in the dashboard's 12-column grid. (see [below for nested schema](#nestedatt--widgets--settings--grid))
* `kpi_calculation` (String) The aggregation used when display\_type is kpi.
* `kpi_type` (String) The metric represented when display\_type is kpi.
* `kpi_usage_unit` (String) The usage unit represented when kpi\_type is usage.
### Nested Schema for `widgets.settings.grid`
Required:
* `h` (Number) The widget height in grid rows.
* `w` (Number) The widget width in grid columns.
* `x` (Number) The zero-based horizontal position.
* `y` (Number) The zero-based vertical position.
# vantage_financial_commitment_report (Resource)
Source: https://docs.vantage.sh/terraform_docs/resources/financial_commitment_report
Terraform resource reference for vantage_financial_commitment_report (Resource). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this resource with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Schema
### Required
* `title` (String) The title of the FinancialCommitmentReport.
* `workspace_token` (String) The Workspace in which the FinancialCommitmentReport will be created.
### Optional
* `date_bucket` (String) The date bucket of the FinancialCommitmentReport.
* `date_interval` (String) The date interval of the FinancialCommitmentReport. Unless 'custom' is used, this is incompatible with 'start\_date' and 'end\_date' parameters. Defaults to 'last\_3\_months'.
* `end_date` (String) The end date of the FinancialCommitmentReport. YYYY-MM-DD formatted. Incompatible with 'date\_interval' parameter.
* `filter` (String) The filter query language to apply to the FinancialCommitmentReport. Additional documentation available at [https://docs.vantage.sh/vql](https://docs.vantage.sh/vql).
* `groupings` (List of String) Grouping values for aggregating costs on the FinancialCommitmentReport. Valid groupings: cost\_type, commitment\_type, commitment\_id, service, resource\_account\_id, provider\_account\_id, region, cost\_category, cost\_sub\_category, instance\_type, tag, `tag:`.
* `on_demand_costs_scope` (String) The scope for the costs. Possible values: discountable, all.
* `start_date` (String) The start date of the FinancialCommitmentReport. YYYY-MM-DD formatted. Incompatible with 'date\_interval' parameter.
### Read-Only
* `created_at` (String) The date and time, in UTC, the report was created. ISO 8601 Formatted.
* `default` (Boolean) Indicates whether the FinancialCommitmentReport is the default report.
* `id` (String) The id of the report
* `token` (String) The token of the report
* `user_token` (String) The token for the User who created this FinancialCommitmentReport.
# vantage_folder (Resource)
Source: https://docs.vantage.sh/terraform_docs/resources/folder
Terraform resource reference for vantage_folder (Resource). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this resource with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
Manages a Folder.
## Example Usage
```terraform theme={null}
resource "vantage_folder" "demo_folder" {
title = "Demo Folder"
# Optional: Create a folder for provider resources instead of cost reports
# type = "ProviderResourceFolder"
# Include either the parent_folder_token or workspace_token
# If both are included, the API will use the parent_folder_token
# Uncomment one of the following:
# parent_folder_token = "fldr_47c3254c790e9351"
workspace_token = "wrkspc_47c3254c790e9351"
# Optional: Apply saved filters to all Cost Reports in this folder
# saved_filter_tokens = ["svd_fltr_1234567890abcdef"]
}
```
## Schema
### Required
* `title` (String) Title of the folder
### Optional
* `parent_folder_token` (String) Token of the folder's parent folder
* `saved_filter_tokens` (List of String) Tokens of the SavedFilters to apply to any Cost Report contained within the Folder.
* `type` (String) The type of the folder. The API defaults to `CostFolder`. Changing this value forces replacement.
* `workspace_token` (String) Workspace token to add the cost report to.
### Read-Only
* `token` (String) Unique folder identifier
# vantage_invoice (Resource)
Source: https://docs.vantage.sh/terraform_docs/resources/invoice
Terraform resource reference for vantage_invoice (Resource). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this resource with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Example Usage
```terraform theme={null}
data "vantage_invoices" "all_invoices" {}
resource "vantage_invoice" "demo_invoice" {
account_token = "acct_f87c7c90365bcdcd"
billing_period_start = "2024-01-01"
billing_period_end = "2024-01-31"
}
```
## Schema
### Required
* `account_token` (String) Token of the managed account to invoice
* `billing_period_end` (String) End date of billing period (YYYY-MM-DD)
* `billing_period_start` (String) Start date of billing period (YYYY-MM-DD)
### Read-Only
* `account_name` (String) Name of the managed account this invoice belongs to
* `created_at` (String) The date and time, in UTC, the invoice was created. ISO 8601 formatted.
* `id` (String) The id of the invoice
* `invoice_number` (String) Sequential invoice number for the MSP account
* `msp_account_token` (String) Token of the MSP account that owns this invoice
* `status` (String) Current status of the invoice
* `token` (String) The token of the invoice
* `total` (String) Total amount for the invoice period
* `updated_at` (String) The date and time, in UTC, the invoice was last updated. ISO 8601 formatted.
# vantage_kubernetes_efficiency_report (Resource)
Source: https://docs.vantage.sh/terraform_docs/resources/kubernetes_efficiency_report
Terraform resource reference for vantage_kubernetes_efficiency_report (Resource). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this resource with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Schema
### Required
* `title` (String) The title of the KubernetesEfficiencyReport.
* `workspace_token` (String) The Workspace in which the KubernetesEfficiencyReport will be created.
### Optional
* `aggregated_by` (String) The column by which the costs are aggregated.
* `date_bucket` (String) The date bucket of the KubernetesEfficiencyReport.
* `date_interval` (String) The date interval of the KubernetesEfficiencyReport. Incompatible with 'start\_date' and 'end\_date' parameters. Defaults to 'this\_month' if start\_date and end\_date are not provided.
* `end_date` (String) The end date of the KubernetesEfficiencyReport. ISO 8601 Formatted. Incompatible with 'date\_interval' parameter.
* `filter` (String) The filter query language to apply to the KubernetesEfficiencyReport. Additional documentation available at [https://docs.vantage.sh/vql](https://docs.vantage.sh/vql).
* `groupings` (List of String) Grouping values for aggregating costs on the KubernetesEfficiencyReport. Valid groupings: cluster\_id, namespace, labeled, category, pod, label, `label:`.
* `start_date` (String) The start date of the KubernetesEfficiencyReport. ISO 8601 Formatted. Incompatible with 'date\_interval' parameter.
### Read-Only
* `created_at` (String) The date and time, in UTC, the report was created. ISO 8601 Formatted.
* `default` (Boolean) Indicates whether the KubernetesEfficiencyReport is the default report.
* `id` (String) The id of the report
* `token` (String) The token of the report
* `user_token` (String) The token for the User who created this KubernetesEfficiencyReport.
# vantage_managed_account (Resource)
Source: https://docs.vantage.sh/terraform_docs/resources/managed_account
Terraform resource reference for vantage_managed_account (Resource). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this resource with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Example Usage
```terraform theme={null}
terraform {
required_providers {
vantage = {
source = "vantage-sh/vantage"
}
}
}
resource "vantage_managed_account" "terraform-managed-account" {
contact_email = "support+terraform@vantage.sh"
name = "Terraform managed account"
access_credential_tokens = [
"accss_crdntl_145aa8924bdc55a9"
]
billing_rule_tokens = [
"bllng_rule_bc95e52f2af7bac6",
]
}
```
## Schema
### Required
* `contact_email` (String) The contact email address for the Managed Account.
* `name` (String) The name of the Managed Account.
### Optional
* `access_credential_tokens` (List of String) Access Credential (aka Integrations) tokens to assign to the Managed Account.
* `billing_rule_tokens` (List of String) Billing Rule tokens to assign to the Managed Account.
* `email_domain` (String) Email domain to associate with this Managed Account for SSO.
### Read-Only
* `id` (String) The id of the managed account
* `include_managed_account_integrations` (Boolean) Whether to include managed account's own integrations in invoice cost calculations (MSP invoicing accounts only)
* `parent_account_token` (String) The token for the parent Account.
* `payment_terms_days` (Number) Number of days until payment is due after invoice date (MSP invoicing accounts only)
* `token` (String) The token of the managed account
# vantage_network_flow_report (Resource)
Source: https://docs.vantage.sh/terraform_docs/resources/network_flow_report
Terraform resource reference for vantage_network_flow_report (Resource). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this resource with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Schema
### Required
* `title` (String) The title of the NetworkFlowReport.
* `workspace_token` (String) The Workspace in which the NetworkFlowReport will be created.
### Optional
* `date_interval` (String) The date interval of the NetworkFlowReport. Unless 'custom' is used, this is incompatible with 'start\_date' and 'end\_date' parameters. Defaults to 'last\_7\_days'.
* `end_date` (String) The end date of the NetworkFlowReport. YYYY-MM-DD formatted. Incompatible with 'date\_interval' parameter.
* `filter` (String) The filter query language to apply to the NetworkFlowReport. Additional documentation available at [https://docs.vantage.sh/vql](https://docs.vantage.sh/vql).
* `flow_direction` (String) The flow direction of the NetworkFlowReport.
* `flow_weight` (String) The dimension by which the logs in the report are sorted. Defaults to costs.
* `groupings` (List of String) Grouping values for aggregating data on the NetworkFlowReport. Valid groupings: account\_id, az\_id, dstaddr, dsthostname, flow\_direction, interface\_id, instance\_id, peer\_resource\_uuid, peer\_account\_id, peer\_vpc\_id, peer\_region, peer\_az\_id, peer\_subnet\_id, peer\_interface\_id, peer\_instance\_id, region, resource\_uuid, srcaddr, srchostname, subnet\_id, traffic\_category, traffic\_path, vpc\_id.
* `start_date` (String) The start date of the NetworkFlowReport. YYYY-MM-DD formatted. Incompatible with 'date\_interval' parameter.
### Read-Only
* `created_at` (String) The date and time, in UTC, the report was created. ISO 8601 Formatted.
* `created_by_token` (String) The token for the User or Team that created this NetworkFlowReport.
* `default` (Boolean) Indicates whether the NetworkFlowReport is the default report.
* `id` (String) The id of the report
* `token` (String) The token of the report
# vantage_recommendation_view (Resource)
Source: https://docs.vantage.sh/terraform_docs/resources/recommendation_view
Terraform resource reference for vantage_recommendation_view (Resource). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this resource with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Example Usage
```terraform theme={null}
# Basic recommendation view
resource "vantage_recommendation_view" "production" {
title = "Production Recommendations"
workspace_token = data.vantage_workspaces.main.workspaces[0].token
}
# Recommendation view with provider filter
resource "vantage_recommendation_view" "aws_only" {
title = "AWS Recommendations"
workspace_token = data.vantage_workspaces.main.workspaces[0].token
provider_ids = ["aws"]
}
# Recommendation view with multiple filters
resource "vantage_recommendation_view" "filtered" {
title = "Filtered Recommendations"
workspace_token = data.vantage_workspaces.main.workspaces[0].token
provider_ids = ["aws", "gcp"]
regions = ["us-east-1", "us-west-2"]
start_date = "2024-01-01"
end_date = "2024-12-31"
}
# Recommendation view with tag filter
resource "vantage_recommendation_view" "tagged" {
title = "Production Environment Recommendations"
workspace_token = data.vantage_workspaces.main.workspaces[0].token
tag_key = "environment"
tag_value = "production"
}
```
## Schema
### Required
* `title` (String) The title of the RecommendationView.
* `workspace_token` (String) The Workspace to associate the RecommendationView with.
### Optional
* `account_ids` (List of String) Filter by cloud account identifiers.
* `billing_account_ids` (List of String) Filter by billing account identifiers.
* `end_date` (String) Filter recommendations created on/before this YYYY-MM-DD date.
* `provider_ids` (List of String) Filter by one or more providers (e.g. aws, gcp, azure, kubernetes, datadog).
* `regions` (List of String) Filter by region slugs (e.g. us-east-1, eastus, asia-east1).
* `start_date` (String) Filter recommendations created on/after this YYYY-MM-DD date.
* `tag_key` (String) Filter by tag key (must be used with tag\_value).
* `tag_value` (String) Filter by tag value (requires tag\_key).
### Read-Only
* `created_at` (String) The date and time, in UTC, the view was created. ISO 8601 Formatted.
* `created_by` (String) The token for the Creator of this RecommendationView.
* `id` (String) The id of the recommendation view
* `token` (String) The token of the recommendation view
# vantage_report_forecast (Resource)
Source: https://docs.vantage.sh/terraform_docs/resources/report_forecast
Terraform resource reference for vantage_report_forecast (Resource). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this resource with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Example Usage
```terraform theme={null}
resource "vantage_scenario_model" "demo" {
title = "Hiring Plan"
periods = [{
start_at = "2026-01-01"
end_at = "2026-03-31"
amount = 1250.75
amount_type = "dollar"
}]
}
resource "vantage_report_forecast" "demo" {
title = "Board Plan"
cost_report_token = vantage_cost_report.demo_report.token
scenario_model_tokens = [vantage_scenario_model.demo.token]
set_as_default = true
}
```
## Schema
### Required
* `cost_report_token` (String)
* `title` (String)
### Optional
* `business_metric_token` (String)
* `scenario_model_tokens` (List of String)
* `set_as_default` (Boolean)
### Read-Only
* `created_at` (String)
* `created_by_token` (String)
* `id` (String) The id of the report forecast
* `is_default` (Boolean)
* `token` (String) The token of the report forecast
* `updated_at` (String)
# vantage_report_notification (Resource)
Source: https://docs.vantage.sh/terraform_docs/resources/report_notification
Terraform resource reference for vantage_report_notification (Resource). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this resource with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
Manages a Report Notification.
## Example Usage
```terraform theme={null}
resource "vantage_report_notification" "test_notif" {
cost_report_token = vantage_cost_report.demo_report.token
title = "Test Notification"
user_tokens = ["usr_36b848747e1683bc", "usr_899b013c355547db"]
frequency = "daily"
change = "dollars"
workspace_token = "wrkspc_47c3254c790e9351"
}
```
## Schema
### Required
* `change` (String) The kind of change sent ReportNotification. One of percentage/dollars
* `cost_report_token` (String) Token for the cost report to be used in the notification
* `frequency` (String) The frequency at which the ReportNotification is sent. One of daily/weekly/monthly
* `title` (String) Title of the report notification
* `user_tokens` (Set of String) Tokens for the users to be notified
### Optional
* `workspace_token` (String) Token for the workspace the report notification is added toe notification
### Read-Only
* `token` (String) Unique report notification identifier
# vantage_resource_report (Resource)
Source: https://docs.vantage.sh/terraform_docs/resources/resource_report
Terraform resource reference for vantage_resource_report (Resource). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this resource with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Example Usage
```terraform theme={null}
resource "vantage_resource_report" "demo_resource_report" {
workspace_token = "wrkspc_47c3254c790e9351"
title = "Demo Resource Report"
filter = "resources.provider = 'aws' AND resources.type = 'aws_cloudtrail'"
}
```
## Schema
### Required
* `workspace_token` (String) The token of the Workspace to add the ResourceReport to.
### Optional
* `columns` (List of String) Array of column names to display in the table. Column names should match those returned by the /resource\_reports/columns endpoint. The order determines the display order. Only available for reports with a single resource type filter.
* `filter` (String) The VQL filter for the ResourceReport.
* `folder_token` (String) The token of the Folder to add the ResourceReport to.
* `title` (String) The title of the ResourceReport.
### Read-Only
* `created_at` (String) The date and time, in UTC, the report was created. ISO 8601 Formatted.
* `created_by_token` (String) The token for the User or Team who created this ResourceReport.
* `id` (String) The token of the report
* `token` (String) The token of the report
* `user_token` (String) The token for the User who created this ResourceReport.
# vantage_saved_filter (Resource)
Source: https://docs.vantage.sh/terraform_docs/resources/saved_filter
Terraform resource reference for vantage_saved_filter (Resource). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this resource with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
Manages a SavedFilter.
## Example Usage
```terraform theme={null}
resource "vantage_saved_filter" "demo_filter" {
title = "Demo Saved Filter"
filter = "(costs.provider = 'aws')"
}
```
## Schema
### Required
* `title` (String) Title of the Saved Filter
* `workspace_token` (String) Workspace token to add the saved filter into.
### Optional
* `filter` (String) VQL Query used for this saved filter.
### Read-Only
* `token` (String) Unique saved filter identifier
# vantage_scenario_model (Resource)
Source: https://docs.vantage.sh/terraform_docs/resources/scenario_model
Terraform resource reference for vantage_scenario_model (Resource). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this resource with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Example Usage
```terraform theme={null}
resource "vantage_scenario_model" "demo" {
title = "Hiring Plan"
periods = [
{
start_at = "2026-01-01"
end_at = "2026-03-31"
amount = 1250.75
amount_type = "dollar"
},
{
start_at = "2026-04-01"
amount = 10
amount_type = "percent"
}
]
}
```
## Schema
### Required
* `title` (String)
### Optional
* `cloud_provider` (String) The cloud provider filter for the ScenarioModel.
* `periods` (Attributes List) The periods for the ScenarioModel. (see [below for nested schema](#nestedatt--periods))
* `priority` (Number)
* `service` (String)
* `workspace_token` (String)
### Read-Only
* `created_at` (String)
* `created_by_token` (String)
* `id` (String) The id of the scenario model
* `token` (String) The token of the scenario model
* `updated_at` (String)
### Nested Schema for `periods`
Required:
* `amount` (Number)
* `amount_type` (String) Whether the amount is in dollars or percent.
* `start_at` (String) The ISO 8601 start date of the period.
Optional:
* `end_at` (String) The ISO 8601 end date of the period.
# vantage_team (Resource)
Source: https://docs.vantage.sh/terraform_docs/resources/team
Terraform resource reference for vantage_team (Resource). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this resource with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Example Usage
```terraform theme={null}
resource "vantage_team" "demo_team" {
name = "Demo Team"
description = "Demo Team Description"
default_dashboard_token = "dshbrd_a2846903070824f4"
user_emails = ["support@vantage.sh"]
workspace_tokens = ["wrkspc_47c3254c790e9351"]
}
```
## Schema
### Required
* `name` (String) The name of the Team.
### Optional
* `default_dashboard_token` (String) The token of the dashboard to use as the default for the Team.
* `description` (String) The description of the Team.
* `role` (String) The role to assign to the provided Users. Defaults to 'editor' which has editor permissions.
* `user_emails` (List of String) The User emails to associate to the Team.
* `user_tokens` (List of String) The User tokens to associate to the Team.
* `workspace_tokens` (List of String) The Workspace tokens to associate to the Team.
### Read-Only
* `id` (String) The id of the team
* `token` (String) The token of the Team
# vantage_virtual_tag_config (Resource)
Source: https://docs.vantage.sh/terraform_docs/resources/virtual_tag_config
Terraform resource reference for vantage_virtual_tag_config (Resource). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this resource with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
## Example Usage
```terraform theme={null}
data "vantage_virtual_tag_configs" "demo" {}
resource "vantage_virtual_tag_config" "demo_virtual_tag_config" {
key = "Demo Tag"
backfill_until = "2024-01-01"
overridable = true
preferred = true
values = [
{
name = "Demo Value 0"
filter = "(costs.provider = 'aws' AND costs.region = 'us-east-1') OR (costs.provider = 'gcp' AND costs.region = 'us-central1')"
},
{
filter = "(costs.provider = 'aws' AND costs.service = 'AwsApiGateway')"
cost_metric = {
aggregation = {
tag = "environment"
}
filter = "(costs.provider = 'aws' AND costs.service = 'AmazonECS')"
}
},
# {
# filter = "(costs.provider = 'aws' AND costs.service = 'AmazonECS')"
# business_metric_token = ""
# }
# Example: apply label_transforms to a business-metric-backed value to
# split a "&&&"-delimited project label and reformat it into a team tag.
# {
# filter = "costs.provider = 'aws'"
# business_metric_token = "bsnss_mtrc_XXXXXXXX"
# label_transforms = [
# { type = "split", delimiter = "&&&", index = 0 },
# { type = "format", template = "team-{0}" },
# ]
# }
]
}
```
## Schema
### Required
* `key` (String) The key of the VirtualTagConfig.
* `overridable` (Boolean) Whether the VirtualTagConfig can override a provider-supplied tag on a matching Cost.
### Optional
* `backfill_until` (String) The earliest month the VirtualTagConfig should be backfilled to.
* `collapsed_tag_keys` (Attributes List) Tag keys to collapse values for. (see [below for nested schema](#nestedatt--collapsed_tag_keys))
* `preferred` (Boolean) Whether this virtual tag key is marked as preferred in the Vantage UI.
* `values` (Attributes List) Values for the VirtualTagConfig, with match precedence determined by order in the list. (see [below for nested schema](#nestedatt--values))
### Read-Only
* `created_by_token` (String) The token of the Creator of the VirtualTagConfig.
* `hidden` (Boolean) Whether the VirtualTagConfig key is hidden from the Vantage UI.
* `id` (String) The id of the VirtualTagConfig.
* `token` (String) The token of the VirtualTagConfig.
### Nested Schema for `collapsed_tag_keys`
Required:
* `key` (String) The tag key to collapse values for.
Optional:
* `filter` (String) The VQL filter this collapsed tag key applies to. When set, do not also set providers; include any provider restrictions directly in filter.
* `providers` (List of String) Provider-only scope for this collapsed tag key. Invalid when filter is set; include provider restrictions in filter instead. Defaults to all providers.
### Nested Schema for `values`
Required:
* `filter` (String) The filter query language to apply to the value. Additional documentation available at [https://docs.vantage.sh/vql](https://docs.vantage.sh/vql).
Optional:
* `business_metric_token` (String) The token of an associated business metric.
* `cost_metric` (Attributes) (see [below for nested schema](#nestedatt--values--cost_metric))
* `date_ranges` (Attributes List) Date ranges restricting when this value applies. Each range has optional start\_date and end\_date (inclusive, YYYY-MM-DD). (see [below for nested schema](#nestedatt--values--date_ranges))
* `display_name` (String) The display name for an allocation value (cost\_metric or percentages). Invalid when name is set.
* `label_key` (String) The business metric label key used for this virtual tag value.
* `label_transforms` (Attributes List) Label transforms applied to business metric labels. (see [below for nested schema](#nestedatt--values--label_transforms))
* `label_values` (List of String) Optional business metric label values. An empty array includes every value for the label key.
* `name` (String) The name of the value.
* `percentages` (Attributes List) Labeled percentage allocations for matching costs. (see [below for nested schema](#nestedatt--values--percentages))
* `token` (String) The token of the Value.
### Nested Schema for `values.cost_metric`
Optional:
* `aggregation` (Attributes) (see [below for nested schema](#nestedatt--values--cost_metric--aggregation))
* `filter` (String) The filter VQL for the cost metric.
### Nested Schema for `values.cost_metric.aggregation`
Optional:
* `tag` (String) The tag to aggregate on.
### Nested Schema for `values.date_ranges`
Optional:
* `end_date` (String) Inclusive end date (YYYY-MM-DD), or null for unbounded.
* `start_date` (String) Inclusive start date (YYYY-MM-DD), or null for unbounded.
### Nested Schema for `values.label_transforms`
Required:
* `type` (String) The label transform type.
Optional:
* `delimiter` (String) Delimiter used by split transforms.
* `index` (Number) Zero-based index used by split transforms.
* `template` (String) Template used by format transforms.
### Nested Schema for `values.percentages`
Required:
* `pct` (Number)
* `value` (String) The tag value associated with a percentage of matched costs.
# vantage_workspace (Resource)
Source: https://docs.vantage.sh/terraform_docs/resources/workspace
Terraform resource reference for vantage_workspace (Resource). Auto-generated from the vantage-sh/terraform-provider-vantage repository.
This page is auto-generated based on the official [Terraform documentation](https://registry.terraform.io/providers/vantage-sh/vantage/latest/docs).
## Overview
Use this resource with the [Vantage Terraform provider](/terraform). For installation and authentication, see the [Terraform provider quickstart](/terraform#quickstart). The schema below is generated directly from the provider source.
Manages a Workspace.
## Example Usage
```terraform theme={null}
resource "vantage_workspace" "example" {
name = "Example Workspace"
currency = "USD"
enable_currency_conversion = false
exchange_rate_date = "daily_rate"
}
```
## Schema
### Required
* `name` (String) Name of the workspace.
### Optional
* `currency` (String) Currency code for the workspace.
* `enable_currency_conversion` (Boolean) Enable currency conversion for the workspace.
* `exchange_rate_date` (String) The date to use for currency conversion.
### Read-Only
* `created_at` (String) The date and time, in UTC, the Workspace was created. ISO 8601 Formatted.
* `id` (String) Alias of `token`.
* `token` (String) The token of the workspace
# Usage-Based Reporting
Source: https://docs.vantage.sh/usage_based_reporting
Track cloud infrastructure consumption with Vantage Usage-Based Reporting.
To get started with Usage-Based Reports, you can also watch a video demo on [Vantage University](/vantage_university_cost_reporting) .
Usage-Based Reporting shows infrastructure consumption in non-monetary metrics, such as virtual machine running hours, stored gigabytes of data, and read/write units consumed. Cost Reports provide **Cost**, **Usage**, and [**Count**](/cost_reports#count-reporting) Y-axis display types. Select **Usage** to analyze provider-reported consumption; select **Count** to track how many distinct grouped items contribute cost over time.
## Supported Providers
The following providers populate usage data in Vantage. Units are normalized in the console for consistent spelling and capitalization (for example, `hrs` and `Hours` both display as **Hours**).
| Provider | Usage units | Examples |
| - | - | - |
| Anthropic | Tokens | Input, output, and cache token counts |
| Anyscale | Credits | Anyscale credits consumed |
| AWS | Dynamic (provider-metered) | Hours, GB-Months, Tokens, Requests, Units |
| Azure | Dynamic (provider-metered) | Quantity with Azure unit of measure (e.g., `10 GB`) |
| Azure CSP | Dynamic (provider-metered) | Hours, GB-Months, and other CSP unit types |
| Baseten | Hours, Tokens | Compute hours for Dedicated Inference and Training; input, output, and cached input tokens for Model APIs |
| Cartesia | Credits, Minutes | Credits for model capabilities (e.g., Text-to-Speech, Pro Voice Cloning); minutes for Line agents |
| CircleCI | Credits | CircleCI credits consumed |
| ClickHouse Cloud | CHC | ClickHouse Credits |
| Cloudflare | Dynamic (provider-metered) | Requests, DNS queries, rows, operations, and other Cloudflare usage units |
| Cursor | Tokens, Requests | Token totals for model usage; request counts for non-token usage |
| Custom Providers | User-defined | Values from `ConsumedQuantity` and `ConsumedUnit` in your CSV upload |
| Databricks | Dynamic (provider-metered) | DBU, DSU, GB |
| Elastic | Dynamic (provider-metered) | Hours and other Elastic line-item units |
| ElevenLabs | Credits, Minutes, Seconds, Milliseconds, Duration | Voice generation and related product usage |
| Fireworks AI | Tokens, GPU-Hours | LLM input/output/cached/training tokens; on-demand deployment GPU-hours |
| GitHub | Dynamic (provider-metered) | Quantity with GitHub `unit_type` |
| Google Cloud | Dynamic (provider-metered) | Hours, GB-Months, Tokens (Vertex AI), Requests |
| Grafana Cloud | Dynamic (provider-metered) | GB and other Grafana usage units |
| Kubernetes | vCPU-Hours, GB-Hours, GPU-Hours, GB | Allocated compute, memory, GPU, and network usage |
| OpenAI | Tokens | Token counts when usage enrichment data is available |
| Oracle Cloud | Dynamic (provider-metered) | GB-Months and other billed quantity units |
| Redis | Dynamic (provider-metered) | Hours and other FOCUS pricing units |
| SpaceXAI | Tokens, Images, Videos, Searches | Prompt, completion, cached, and reasoning text tokens; generated images and videos; web and X searches; code executions; input audio seconds; file storage |
| Temporal Cloud | Number, Gigabyte-hours, Pricing units | Actions, storage, and FOCUS pricing quantities |
| Twilio | Dynamic (provider-metered) | Numbers, minutes, messages, and other Twilio usage categories |
| Vercel | Dynamic (provider-metered) | FOCUS consumed or pricing units |
If a provider is not listed above, the **Usage Unit** column is empty and **Accrued Usage** displays 0.00. Vantage plans to add support for additional providers. Contact [support@vantage.sh](mailto:support@vantage.sh) with providers you'd like to see added.
Per-request LLM cost attribution by team, user, application, and feature is available when [Custom LLM Enrichment](/custom_llm_enrichment) is enabled and you deliver token telemetry to a connected S3 bucket. On Amazon Bedrock, the same attribution is available through [AWS Bedrock LLM Enrichment](/aws_bedrock_enrichment) once Model Invocation Logs are connected.
## Create Usage-Based Reports
Navigate to any Cost Report, or create a new report. By default, the **Y-Axis** displays **Cost**.
Apply any desired filters and **Group By** criteria. If the selected provider has multiple units of measure, use the **Usage Unit** filter to select the unit you want to analyze, such as **Hours**, **GB-Months**, or **Requests**. This filter is also available for Custom Providers and the **All Providers** filter context when the selected context contains multiple units.
Then, open the **Chart Settings** menu and select **Usage** for the **Y-Axis**.
Filter to a single Usage Unit so the report compares like-for-like consumption instead of combining incompatible units.
The following elements are displayed on the **Usage** view:
* The graph and chart display usage over the selected timeframe.
* The total cost is displayed as a trendline on the chart.
* **Usage Unit** is automatically selected and locked in the **Group By** menu. This prevents values with different units from being combined. If you switch the **Y-Axis** back to **Cost**, the grouping becomes optional and can be removed.
* In the table below the graph, the **Usage Unit** (e.g., GB-Hours or Metrics) and **Accrued Usage (a numerical value of calculated usage for that unit)** columns are displayed to show accrued usage for each grouping. The **Usage Unit** column is normalized for consistency across usage type for spelling, abbreviation, and capitalization.
* **Accrued Usage**, **Previous Period Usage**, **Accrued Cost**, **Previous Period Cost**, and **Change** between these cost values are also displayed. Click the **By Date** option above the table to see the usage data split out by date.
Save the report.
Usage data refreshes daily in the Vantage console. At this time, you cannot view retroactive usage metrics. Contact [support@vantage.sh](mailto:support@vantage.sh) if you want to view historical usage data.
### Export Usage Reports
To export usage reports, [follow the steps](/cost_reports#export-cost-reports) provided in the Cost Reports documentation. Ensure you are on the **Usage** view. **Usage Unit** is automatically selected as an export grouping so each unit of measure is identified in the exported data.
### View Usage Data for Custom Costs
When you create a [Custom Provider](/connecting_custom_providers), you can add usage data to your CSV upload files. Ensure you complete the `ConsumedQuantity` and `ConsumedUnit` columns. See the [Custom Providers documentation](/connecting_custom_providers#data-format) for information on the required schema.
## Understand Usage Units
The Usage Units displayed on Usage-Based Reporting include any dimension that a supported provider meters and bills. Vantage standardizes these dimensions for inconsistencies in unit case and spelling across providers. For example, Vantage standardizes `Hours`, `hrs`, `Hrs`, and `hours` to `Hours`. See the [Supported Providers](#supported-providers) table for the units available per provider.
When the selected provider context contains more than one distinct, non-empty unit, **Usage Unit** is available as a [Cost Report filter](/cost_reports#filter-by-usage-unit). If the context contains zero or one unit, Vantage omits the filter because it would not further narrow the report.
## Use Virtual Tags with Usage-Based Reporting
[Virtual Tags](/tagging) work across both cost and usage consumption for supported providers. If you created Virtual Tags based on cost, the associated usage consumption will inherit the same Virtual Tag. You can use Virtual Tags within your filter criteria to apply Virtual Tags based on usage.
## Usage-Based Reporting on Dashboards
You can add Usage-Based Reports to dashboards. Ensure **Usage** is selected for the **Y-Axis**, save the report, and then add it to a dashboard. Follow the [Dashboards](/dashboards) documentation for details on how to add a report to a dashboard.
## Usage Reports Examples
The following examples provide some common use cases for working with Usage-Based Reporting.
### Understand EC2 Running Hours
As an Engineering Manager, you want to view your Amazon EC2 usage by instance hours, so that you can get a profile of your compute usage. This is important because it helps you identify patterns in compute resource consumption. This type of report can help you create more efficient resource planning and cost optimization based on your team's workload needs.
You create the following Usage-Based Report in Vantage:
* Filter: All costs from **AWS** where Category **Amazon Elastic Compute Cloud - Compute** is **Compute Instance**
* Filter: **Usage Unit** is **Hours**
* Group By: **Subcategory**

The table below the chart includes the accrued usage and the unit of measure for each line item being viewed, such as EC2 instance bill code. To get the most value from this report, focus on identifying high-usage instance families and regions to optimize compute resources and explore opportunities for cost-saving strategies, like instance rightsizing or transitioning to Savings Plans.
### View S3 Storage by Tier
As a Storage Admin or Engineering Manager, you want to view detailed storage metrics across specific AWS services, such as the total data stored in S3 by tier. With this report, you can better understand the overall profile and efficiency of stored assets and potentially determine whether additional storage policies are required to optimize storage usage and growth.
You create the following Usage-Based report to see total data stored in S3 in Vantage:
* Filter: All costs from **AWS** where Category **Amazon Simple Storage Service** is **Storage**
* Filter: **Usage Unit** is **GB-Months**
* Group By: **Subcategory**

In the table below the graph, usage data is displayed in GB-Months for subcategories like:
* **TimedStorage-INT-AIA-ByteHrs** (Infrequent Access Tier)
* **TimedStorage-INT-IA-ByteHrs** (Intelligent Tiering)
* **TimedStorage-ByteHrs** (Standard Tier)
These metrics provide an overview of how data is distributed across different S3 storage tiers. Next steps could include analyzing whether data in the **Infrequent Access** and **Intelligent Tiering** categories is optimally stored, or you could decide whether more aggressive lifecycle policies are needed to move infrequently accessed data to cheaper storage tiers, like Glacier. You could also use this usage information to identify potential cost savings by reducing the storage volume in higher-cost tiers, such as the **Standard Tier**.
# Account Settings
Source: https://docs.vantage.sh/vantage_account
Manage your Vantage account settings; configure personal profiles, API tokens, organizational settings, currency preferences, and user access controls.
From the Vantage account [Settings page](https://console.vantage.sh/account/profile), you can edit your personal profile, create API access tokens, and configure organizational settings.
## General Settings
Only Organization Owners can configure organization settings. See the [Role-Based Access Control (RBAC)](/rbac) documentation for details.
From the top navigation bar of the Vantage console, click **Settings**. On the side navigation bar, review the options under **General Settings**.
### Create an API Token
Create API tokens to authenticate requests to the Vantage API. See the [API Reference](/api/authentication) documentation for more information.
### View Audit Logs
View a complete audit trail of actions taken in your Vantage account, including changes to resources, user actions, and FinOps Agent activities. See the [Audit Logs](/audit_logs) documentation for more information.
### Configure Authentication
Vantage supports many Single Sign-On (SSO) options. See the [SSO](/sso) documentation for more information.
### View Billing & Plans
From the **Billing & Plans** section, you can view your usage, current plan, and previous payments/invoices.
If you need to update any billing details on your invoices, such as email address or company name, contact Vantage Support at [support@vantage.sh](mailto:support@vantage.sh).
### Configure Integrations
From the **Integrations** section under General Settings, you can view and manage all your provider integrations. This page displays all connected providers, their connection status, and allows you to configure workspace access for each integration.
From the top navigation, click **Settings**.
On the left navigation, under **General Settings**, click **Integrations**.
All your provider integrations are displayed. You can view the status of each integration and manage workspace access by clicking the settings icon next to an integration.
#### Integration Status
Each integration displays a status indicator that shows the current state of the connection:
| Status | Description |
| - | - |
| **Stable** | The integration is connected and functioning normally. Cost data is being imported successfully. |
| **Importing** | The integration is actively importing data for the first time and hasn't been assigned to any workspaces yet. This status appears during the initial data import process. Once the integration is assigned to a workspace or the initial import completes, the status will change to **Stable**. |
| **Warning** | Some accounts within the integration have failed imports, but other accounts are still functioning normally. This status appears when you have multiple accounts connected (e.g., multiple AWS accounts or Azure subscriptions) and some are experiencing import failures while others continue to import successfully. Review the integration settings for the affected accounts to identify and resolve any issues. |
| **Error** | The integration has encountered an error and is not functioning properly. Check the integration settings, verify credentials, or contact [support@vantage.sh](mailto:support@vantage.sh) for assistance. |
The **Importing** status is only shown for integrations that are actively importing data for the first time and haven't been assigned to any workspaces. This provides visibility into the integration setup process.
#### Connection Validation Checks
AWS and Snowflake integration settings include an **Integration Status** panel that validates whether Vantage can access and import your data. The panel shows the latest checks by category, including whether each check succeeded, failed, or was skipped, along with the time of the latest run and details for any errors.
To check a connection on demand, open the integration's **Manage Connection** page and click **Run Checks**. Validation may take a few minutes. Refreshing the page while checks are running does not stop them.
An optional check can fail without preventing Vantage from importing required cost data. The result is labeled **Error (Optional Check)** so you can distinguish it from a required check.
Each failed check names the specific permission or setting to fix. If a check still fails after you follow its message, see the provider-specific troubleshooting: [AWS Permissions](/connecting_aws#aws-permissions) for missing IAM permissions, [Troubleshoot Snowflake Errors](/connecting_snowflake#troubleshoot-snowflake-errors) for authentication and view errors, or the [Integration Troubleshooting](/vantage_account#integration-troubleshooting) steps below.
For detailed instructions on connecting specific providers, see the [Integrations](/getting_started) documentation.
#### Integration Troubleshooting
If your integration is not importing data as expected, use the guidance below to diagnose common issues.
##### Duplicate Integrations Causing Double-Counted Costs
If costs for a provider appear to be exactly double the expected amount, you may have two integrations importing the same data. This can happen when a provider is connected multiple times with different credentials that access the same underlying billing data.
To check for duplicates:
Navigate to **Settings > Integrations**. Select a provider. The **Manage** tab is displayed. Look for multiple entries for the same provider.
Select an integration to view its **Manage Connection** page. Some integrations display an associated account ID that you can compare. If two integrations are showing the same costs, one is likely a duplicate.
Before you delete an integration, you can toggle integrations on and off per workspace without fully removing it. See the [workspaces](/workspaces#manage-workspace-provider-integrations) documentation.
##### Connection Errors After Credential Changes
If you rotated API keys, client secrets, or service account credentials in your provider without updating Vantage, the integration will enter an **Error** state. To resolve this, generate new credentials in your provider's console and add them to Vantage. For provider-specific credential rotation steps, see the documentation for your provider (e.g., [Azure client secret](/connecting_azure#update-your-client-secret), [Snowflake RSA keys](/connecting_snowflake#rotate-snowflake-rsa-keys)).
##### Data Delays After Initial Connection
After connecting a new integration, cost data typically appears within 24–48 hours. Some providers may take longer for the initial backfill of historical data. During this time, the integration status shows **Importing**. If data has not appeared after 48 hours and the status still shows **Importing** or has moved to **Error**, contact [support@vantage.sh](mailto:support@vantage.sh).
##### Integration Is Stable but Costs Are Missing in Reports
If an integration shows **Stable** but you still cannot find its costs in reports, the most common cause is workspace visibility rather than a broken connection.
Use the following checks:
Go to **Settings > Integrations**, open the provider connection, and verify that the relevant workspace is selected under **Workspace Access**. See [Workspaces](/workspaces#manage-workspace-provider-integrations).
Switch to the workspace where the integration is assigned. Reports in other workspaces will not include that provider's data.
If your organization uses [RBAC](/rbac), make sure one of your teams has access to that workspace. A healthy integration can still be invisible if your team does not have workspace access.
### Configure FinOps Agent
Manage FinOps Agent settings, including automation preferences, recommendation types, and Slack channel configuration. See the [Vantage FinOps Agent](/vantage_finops_agent) documentation for more information.
### Invite Users to Your Account
From the **People** section, you can invite new users, view a user's role and team associations, and remove users. To invite a new user:
Under **General Settings**, select **People**.
Click **Invite People**.
Enter the user's email and select a role and associated teams.
Click **Send Invitation**. The new user's name will appear in the **People** list with *Invite Pending* as well as a link to *Resend* the invite.
Click the ellipses (**...**) next to a user's name to edit or remove a user.
The **People** page displays a **Last Login** timestamp for each user, showing when they last accessed the Vantage console. This information is also available via the [Vantage API](/api/vantage_api_reference) as the `last_seen_at` field in the user object.
### Tags
Manage provider tags and create Virtual Tags to organize and allocate costs across your cloud infrastructure. See the [Tagging](/tagging) documentation for more information.
### Configure Teams
See the [Role-Based Access Control (RBAC)](/rbac) documentation for details on team configuration.
### Manage Workspaces
Provider integrations are organized into workspaces. From the **Workspaces** section, you can manage each of your workspaces as well as create a new one. See the [Workspaces](/workspaces) documentation for more information.
### Currency Conversion
At this time, presentational currency conversion is available on Vantage reports, such as Cost Reports, Kubernetes Efficiency Reports, Financial Commitment Reports, Budgets and Budget Alerts, Provider Resource Reports, and Cost Alert email notifications. It is also available on Cost Recommendations.
Vantage offers two options for displaying currency within the console: a *Display Preference* and *Currency Conversion*.
* **Display Preference**: If your imported costs are already billed in a currency other than USD, you can enable a *Display Preference*. This lets you view your costs with the appropriate currency symbol—without using Vantage's currency conversion rates. This option is ideal for users who prefer their costs to reflect the currency in which they are billed.
* **Currency Conversion**: With *Currency Conversion*, you can choose to view costs in a different currency by converting amounts using exchange rates. This is configured per workspace and offers two options:
* **End of Billing Period Rate**: Uses the closing exchange rate for the last day of the previous month.
* **Daily Rate**: Applies the current exchange rate for each day.
Vantage calculates the exchange rate based on a [public API](https://exchangeratesapi.io/).
#### Enable Display Preference
To enable a display preference:
From the top navigation, click **Settings**.
On the side navigation, click **Workspaces**. All your existing workspaces are displayed. Select the workspace where you want to configure your display preference.
At the top of the **Workspaces** page, under **Currency Settings > Display Preference**, select your preferred currency from the list. Reports will now display your selected currency symbol next to costs.
#### Enable Currency Conversion
To enable currency conversion:
From the top navigation, click **Settings**.
On the side navigation, click **Workspaces**. All your existing workspaces are displayed. Select the workspace where you want to enable currency conversion.
At the top of the **Workspaces** page, under **Currency Settings > Currency Conversion**, select **Enable**, then select your preferred currency from the list.
Anything currently set in the **Display Preference** section is overridden by your currency conversion selection.
For **Exchange Rate Dates**, select one of the following conversion date options. For the most accurate results, use the currency method in which you are billed:
* **Daily Rate:** Vantage maintains a daily snapshot of exchange rates to provide estimated currency conversions. With the **Daily Rate** option, the costs' corresponding daily exchange rate will be used for the conversion.
* **End of Billing Period Rate:** Uses the closing exchange rate for the last day of the previous month.
Your settings are automatically saved and available on your reports.
If you disable currency conversion, your presentational currency will default back to USD.
## Personal Settings
From the top navigation bar of the Vantage console, click **Settings**. On the side navigation bar, review the options under **Personal Settings**.
### Update Your Profile
In the **Profile** section, you can change your display name as well as your email address. Note that changing your email will log you out and require you to re-confirm. You can also select a default dashboard that's displayed when you navigate to `console.vantage.sh`. See the [Default Dashboards](/dashboards#set-a-default-dashboard) documentation for details.
### Reset Your Password
The following steps are for users who directly sign in to Vantage.
If you forget your password or would like to change your password, follow the below steps.
From the top-right corner of the console, click the profile icon, then click **Logout**.
You will return to the **Login** screen. Type your email in the **Email Address** field. Then, click **Continue**.
On the **Sign In** page, click **Forgot your password?** and enter your email again.
You will receive an email with a link to reset your password. Click **confirm the password change**, then enter a new password.
Click the right-facing arrow, then go to [console.vantage.sh](https://console.vantage.sh) to sign in with your new password.
## Additional Account Information
### Cost Display and Rounding
Vantage calculates accrued costs from full-precision data and rounds up to two decimal places for display. Individual line items in reports are also rounded independently. Because of this rounding behavior, the displayed total may differ by a few cents from the sum of the displayed line items.
For example, if you sum the individual line items shown in a Cost Report, you may notice a small discrepancy (typically a few cents) compared to the total displayed at the top of the report. This is expected behavior and occurs because each cost value is rounded independently before being displayed.
### Data Retention
Vantage retains cost data for a default period of **6 months**. This retention period determines how far back you can view, filter, and analyze cost data across Cost Reports, Financial Commitment Reports, and other features.
The following retention defaults apply:
| Data Type | Default Retention |
| - | - |
| Cost data (all providers) | 6 months |
| Network Flow Logs | 7 days |
Vantage stores its own copy of the cost data it imports from your providers. Because of this, a provider's own retention limit only constrains how far back Vantage can reach on the **initial import**. It does not limit how long Vantage keeps that data afterward. Once a month has been imported, it remains available for your full retention period even after the provider stops returning it.
Extended data retention is available for customers who need longer historical analysis. Contact [support@vantage.sh](mailto:support@vantage.sh) to discuss extending your retention period.
### Email Notifications
Vantage sends the following emails to account contacts and Organization Owners.
* **Account contact**: The primary email address associated with your Vantage account. This is the email used during account creation and serves as the main contact for billing and account lifecycle communications.
* **Organization Owner**: Any user assigned the [Organization Owner](/rbac) role. There can be multiple Organization Owners on a single account.
#### Emails Sent to Account Contact
| Email | Description |
| - | - |
| **Data Ingestion Complete** | Sent when new cloud cost data is imported and new providers are detected |
| **Autopilot Monthly Savings** | A monthly summary of savings generated by Autopilot |
| **Payment Processed - Thank You** | Sent when a subscription payment is successfully processed. Includes a PDF invoice attachment. Also CC'd to any billing emails on the account |
| **Subscription Cancellation Confirmation** | Sent when the account's subscription is cancelled |
| **Subscription Reactivation Confirmation** | Sent when a previously cancelled subscription is reactivated |
| **Subscription Payment Failure** | Sent when a subscription payment fails |
| **Welcome to your Vantage Free Trial** | Sent when a free trial begins |
#### Emails Sent to Organization Owners
| Email | Description |
| - | - |
| **Expiring Financial Commitment / Expiring Savings Plan / Expiring Reserved Instance** | Sent to each Organization Owner when Reserved Instances or Savings Plans are approaching expiration. The subject line varies based on the type of commitment |
| **Request for FinOps Agent Installation** | Sent to Organization Owners when a team member requests that the FinOps Agent be enabled |
| **Flow Log Ingestion Complete / Data Ingestion Complete** | Sent to Organization Owners when service data (e.g., VPC flow logs) finishes ingestion |
| **Savings Plan Purchased** | Sent to Organization Owners after Autopilot purchases a Savings Plan |
| **Savings Plan recommendation generated** | Sent to Organization Owners when a new recommendation is ready for review |
# Vantage FinOps Agent
Source: https://docs.vantage.sh/vantage_finops_agent
Identify and remediate cloud waste automatically.
The FinOps Agent is an AI assistant that helps you understand and act on your cloud costs in plain language. It is available in two places, and the same agent powers both:
A dedicated, full-screen agent page with threaded, persistent conversations. Available to all customers, including free trials.
Tag `@Vantage` in any channel where the agent has been invited. Required for cost recommendation approvals and automation.
You can use the agent in two ways:
* **Ask questions**: Get answers about your cloud spend (via the [Vantage MCP](/vantage_mcp)), how to use Vantage (via the [Vantage Docs MCP](/docs_mcp)), public AWS, Azure, and GCP instance specifications and list pricing (via [instances.vantage.sh](https://instances.vantage.sh)), and context from connected third-party tools like Datadog, GitHub, Linear, and Notion (via [MCP Connectors](#mcp-connectors)).
* **Take action**: Have the agent create and update Vantage resources (Cost Reports, Dashboards, Budgets, Virtual Tags, etc.), investigate cost anomalies, and—through Slack—automatically remediate cost optimization opportunities with optional approval workflows.
When enabled for automation in Slack, the FinOps Agent operates in three stages:
Your cloud environment for issues like unused or underutilized resources.
Optimization opportunities and waste found within your environments.
To remediate issues on your behalf, while keeping track of any actions taken.
Pick the surface that fits how you want to work with the agent. Start [In the Console](#in-the-console) for chat, threads, and Vantage resource creation. Use [In Slack](#in-slack) for cost recommendation approvals, automated remediation, and team collaboration.
For a complete view of what you can ask the agent, plus best practices and ready-to-copy prompts, see the dedicated FinOps AI Prompt Guide.
Use the agent to build saved, refreshable custom reports from a natural-language prompt with the Canvas feature.
If you import revenue or usage from [Metronome](/metronome), the agent can use those imported business metrics in cost, usage, unit cost, and margin analysis. Metronome is not an MCP Connector; it is connected as an app and imported through [Business Metrics](/business_metrics#import-from-metronome).
## MCP Connectors
MCP Connectors let you connect supported third-party MCP servers to the FinOps Agent so it can bring context from the rest of your stack into the same place that already understands your cloud costs. An **Organization Owner** or **Integration Owner** first enables a connector for your organization from the [Integrations page](https://console.vantage.sh/settings/integrations). Some connectors, like Datadog, are then available to your whole organization. Others, like GitHub, Linear, and Notion, additionally require **each user to authorize their own account** so the agent acts with that user's own permissions. Connectors work in the console, Slack, and [Canvas](/canvas). The agent decides when to call a connected tool based on the question you ask, and can use it in the same turn as its Vantage tools.
Join live Datadog telemetry, like metrics, logs, monitors, dashboards, APM, and events, with your Vantage cost data to investigate anomalies, validate rightsizing, and correlate cost with performance.
Work with your GitHub issues, pull requests, and code, and optionally turn rightsizing recommendations into actionable GitHub issues, pre-filled with cost data.
Search issues, projects, and teams, and create issues for recommendations, anomalies, or budget overruns without leaving a conversation.
Pull architecture docs, runbooks, and team ownership pages into cost investigations, or draft new pages that summarize your findings.
More connectors are planned. If there is a specific MCP integration you would like to see, contact your Vantage account team or reach out to [support@vantage.sh](mailto:support@vantage.sh).
### How Connectors Are Enabled
Connectors follow one of two models:
* **Org-wide (Datadog):** an **Organization Owner** or **Integration Owner** connects it once for the organization, and it is then available to everyone. There is no per-user step.
* **User-authorized (GitHub, Linear, Notion):** an **Organization Owner** or **Integration Owner** first enables the connector for the organization, and then **each user connects their own account**, so the agent acts with that user's own permissions. A user cannot connect until the connector has been enabled for the organization.
On a user-authorized connector's settings page, you may see two tabs:
* **MCP Settings**: where you connect, disconnect, or reconnect your own account and see your personal connection status. Every user has this.
* **Organization Settings** (Organization Owners and Integration Owners only): enable or disable the connector for the whole organization and see the list of users who have connected.
To let users connect their own accounts, user-authorized MCP connectors are visible to every role on the [Integrations page](https://console.vantage.sh/settings/integrations). Once an Organization Owner or Integration Owner enables one, **Organization Editors and Organization Viewers can open Settings > Integrations too**, where they see only the **MCP Connectors** section. A connector you have not connected yet shows as **Not Connected** (Linear, Notion) or **Update Required** (GitHub, when your organization has set it up but you have not connected your own account). See [Role-Based Access Control](/rbac) for details.
Connecting, reconnecting, or disconnecting an MCP connector creates an **MCP Connection** event in your organization's [audit logs](/audit_logs). Credentials and authentication tokens are not included in the event.
## In the Console
The console agent is a dedicated, full-screen page in the Vantage console where you can have ongoing conversations with the FinOps Agent. It is available to all Vantage customers, including users on free trials, and requires no setup.
From the Vantage console, click the **Agent** tab in the top navigation, or go directly to [console.vantage.sh/agent](https://console.vantage.sh/agent).
You can also access the agent from anywhere in the Vantage console. Press **⌘K** (Ctrl+K) to open global search. Enter a question or request, then press **⌘⇧A** (Ctrl+Shift+A) to open the FinOps Agent and use the current search text as your prompt. If the search field is empty, the shortcut opens a new Agent conversation without a prompt.
Type a question or request in plain language, then press Enter. The agent automatically names the conversation based on your first message and saves it to your sidebar so you can return to it later.
Use the conversation sidebar on the left to revisit previous conversations or start a new one at any time. You can also find a conversation by title in global search, which you open with **⌘K** (Ctrl+K). Results include only conversations you own. Each conversation is private to your Vantage user and respects your [RBAC](/rbac) permissions.
For comprehensive prompting examples, see the [FinOps AI Prompt Guide](/guides/finops_ai_prompt_guide).
### Conversations and Threads
Each conversation is a self-contained thread that captures your back-and-forth with the agent.
* **Auto-named**: The agent names each new conversation based on your first message. You can rename a conversation at any time by clicking the ellipsis (**...**) next to it in the sidebar.
* **Persistent**: Conversations are saved per user and retained according to your account's data retention period. Return to any prior conversation to continue where you left off.
* **Private**: Console conversations are visible only to your authenticated user. They are not shared with teammates and do not appear in Slack.
* **Scoped to your permissions**: All agent responses respect your [RBAC](/rbac) role and only access data you are authorized to view.
* **Resource-aware**: The agent recognizes Vantage console URLs and resource tokens (Cost Reports, Folders, Dashboards, Virtual Tags, Budgets, Cost Alerts, anomalies, and more). Paste a link or token directly into your prompt and the agent will use it as context.
For example, you can add a Cost Report URL into your prompt to scope the question:
```md theme={null}
What was the biggest change in cost between September 2025 and October 2025 in https://console.vantage.sh/go/rprt_xyz789abc123def4? What resources contributed?
```
* **File-friendly**: The agent currently accepts text-based file inputs, including CSVs. Support for additional file types is planned.
* **Audited**: Any Cost Report, Dashboard, Virtual Tag, Budget, or other asset the agent creates or updates on your behalf is attributed to your user. Audit log entries reflect actions taken by the agent as if you performed them yourself. View these in the [Vantage Audit Log](/audit_logs).
## In Slack
Slack is required if you want the agent to send recommendation notifications, run automated remediation, or collaborate with your team in shared channels. The console agent works without Slack.
### Set Up the Slack Integration
Before starting, ensure you meet the following requirements for automation:
The Slack FinOps Agent is available to paying Vantage customers. The Agent is not available to the free tier.
To learn more about Vantage plans, visit the [Vantage pricing page](https://www.vantage.sh/pricing).
Ensure you have a payment method in place for charges related to cost remediation and token consumption (either a credit card saved within Vantage or be on a metered agreement through AWS Marketplace).
From the Vantage console, navigate to the [**Recommendations** tab](https://console.vantage.sh/recommendations). A banner is displayed at the top. Click **Get Started**. (If you dismiss the prompt, click **FinOps Agent**.)
You can also access the [FinOps Agent settings page](https://console.vantage.sh/settings/finops-agent) to open the onboarding workflow.
The agent sends notifications directly to your Slack workspace.
* If you've already installed the Vantage [Slack integration](/slack) for Cost Report notifications or alerts, you'll be prompted to update your permissions to enable the agent.
* If you haven't installed the Slack integration yet, you'll be prompted to log in to your workspace.
Follow the on-screen instructions to complete the Slack authorization. When prompted, select a channel where Vantage will post action approvals and recommendations.
If no channels appear in the selection list, you must first invite the @Vantage app to a Slack channel using the `/invite @Vantage` command in Slack. Once invited, the channel will appear in the list for selection.
For **Automation Preference**, select one of the following options:
* **Autonomous**: The agent acts immediately.
* **Owner Approval**: Your team approves each recommendation action sent via Slack.
Your selection applies to every enabled recommendation type. Select which recommendation types you'd like the agent to monitor (e.g., Compute Savings Plans, Database Savings Plans, Redshift Reserved Instances).
For detailed information about how the approval workflow operates, see [Approval Workflow](#approval-workflow).
To enable the agent to take actions on your behalf, you may need to add additional provider permissions. If your AWS access credentials are already configured in Vantage, this step is automatically completed and you can proceed to the next step. If required, the onboarding wizard will display instructions for updating your AWS permissions using the AWS CLI, Terraform, or the IAM Console. After updating your permissions, click **Complete Setup** to continue.
You can navigate between onboarding steps using the stepper navigation on the left side of the screen to review or modify previous steps.
Once all steps are complete, a confirmation screen is displayed. The Slack-based FinOps Agent is now active and ready to use. An introductory message is sent to the channel you selected during onboarding.
Invite the agent to additional channels at any time after onboarding using the `/invite @Vantage` command. Once invited, the FinOps Agent will introduce itself and explain its capabilities. You can invoke the agent by tagging `@Vantage` in any channel where it's present, including in threads.
### Update Slack Settings
After onboarding, you can change the connected Slack channel directly from the [FinOps Agent settings page](https://console.vantage.sh/settings/finops-agent) without needing to re-onboard. If the Slack integration needs re-authorization, a prompt is displayed on the settings page with instructions to reconnect.
### Interact with the Agent
Tag `@Vantage` directly to interact with the agent in Slack. The agent only responds when explicitly mentioned. This applies to both new conversations and follow-up replies in threads.
For general help on using Slack, such as how to mention users or apps, create threads, or use commands, see the [Slack Help Center](https://slack.com/help/categories/200111606).
In a Slack channel, tag the agent directly to start a conversation:
```md theme={null}
@Vantage What was our AWS EC2 spend last month?
```
The FinOps Agent will reply in the thread:
```md theme={null}
Last month's AWS EC2 spend was $3,240...
```
Whenever you ask follow-up questions, be sure to tag `@Vantage` in your reply so the agent is notified. If you do not tag `@Vantage`, the agent will not reply:
```md theme={null}
Reply in thread:
@Vantage Can you show me the top three regions by EC2 spend?
```
Keep in mind that if multiple people are conversing in the same channel or thread, anyone can prompt `@Vantage`, but the FinOps Agent will only respond with information relevant to the identity and permissions of the user issuing the prompt.
Slack threads and console conversations are independent. Messages and history do not cross over between the two surfaces.
### Investigate Cost Anomalies
When [Cost Anomaly Alerts](/cost_anomaly_alerts) are sent to Slack, the FinOps Agent can automatically investigate the root cause of a cost spike. If the FinOps Agent is enabled, anomaly alert notifications in Slack include an **Investigate Anomaly** button alongside the existing **View Anomaly** link.
Click **Investigate Anomaly** to start an investigation. The agent runs a multi-step analysis directly in the Slack thread:
The agent retrieves the anomaly's metadata, including the provider, service, cost category, observed amount, prior-period amount, 7-day rolling average, and attributed resources.
If specific resources are attributed to the anomaly, the agent retrieves details for each resource (instance type, region, account, per-category cost breakdown). It also loads the parent Cost Report's title, filters, and groupings for context.
The agent pulls daily cost data for the affected provider and service, centered on the anomaly date (7 days before and after), to show exactly when the spike began and whether it has recovered.
The agent synthesizes everything into a structured summary:
* **What happened** -- The service, provider, cost change (with percentage), and detection date.
* **Cost trend** -- A day-by-day breakdown showing the spike and recovery pattern.
* **Attributed resources** -- Resources identified as contributors, with metadata like instance type and region.
* **Report context** -- The Cost Report name and any base filters, so you understand the monitoring scope.
* **Console links** -- Direct links to the anomaly and Cost Report in the Vantage console.
You can also trigger an investigation by tagging `@Vantage` in any Slack channel and asking about a cost anomaly or sharing an anomaly alert token.
```md theme={null}
@Vantage Can you investigate the anomaly on my AWS EC2 report from yesterday?
```
### Approval Workflow
The console agent can describe and explain recommendations but cannot take remediation actions at this time.
When the FinOps Agent finds a savings opportunity, it sends a message to your designated Slack channel, similar to the below example:
💰 Compute Plan Recommendations Available
Based on your recent usage, I found that your account could save by purchasing an AWS Compute Savings Plan. Here are savings options for a 1-year, no upfront payment savings plan:
1️⃣ Conservative: 0.31/hr coverage — Est. 112/mo savings
2️⃣ Moderate: 0.46/hr coverage — Est. 168/mo savings
3️⃣ Aggressive: 0.61/hr coverage — Est. 224/mo savings
The agent curates messages for each recommendation type it detects and provides multiple options for approval when appropriate.
When the FinOps Agent proceeds to take an action (either after approval or autonomously), it follows these steps:
1. The agent posts a message in the Slack channel where recommendations are directed, outlining its action plan. An explicit click is required to initiate the action.
2. The agent executes the action in your cloud environment.
3. An entry is logged to the [Vantage Audit Log](/audit_logs) for full transparency and traceability.
4. The agent reports back in the Slack thread with a summary of what was completed and the estimated savings achieved.
## Frequently Asked Questions
Below are categorized answers to frequently asked questions.
### Getting Started
Chatting with the agent is available to all Vantage customers, including users on free trials. **Automated cost remediation** through the Slack approval workflow is available to paying Vantage customers only.
Yes. You can use the FinOps Agent in the console and in Slack to ask questions about your costs and Vantage in natural language. Automated cost remediation is not available on free trials.
Slack is required if you want the agent to send cost recommendation notifications, run automated remediation, or have your team collaborate with the agent in shared channels. The console agent works without Slack.
Yes. The FinOps Agent is also available as a dedicated page in the Vantage console at [console.vantage.sh/agent](https://console.vantage.sh/agent). Additional surfaces, such as Microsoft Teams, are planned for the future.
No. Console conversations are scoped to your authenticated user and are not visible in Slack. Slack threads—especially those across multiple users in shared channels—are not carried over into the console.
There are currently no usage limits on the in-console FinOps Agent.
### Using the Agent
Yes. Conversations in the console are stored and scoped per user. The agent automatically names each conversation based on your first message; you can rename it at any time by clicking the ellipsis (**...**) next to the conversation in the sidebar. Conversations are retained for the duration of your account's data retention period.
Cost Reports, Dashboards, Virtual Tags, Budgets, and other resources the agent creates or updates are attributed to your user. Audit log entries reflect actions taken by the agent on your behalf, just as if you had created or updated the resource yourself. See the [Vantage Audit Log](/audit_logs) for details.
During onboarding, you'll select at least one Slack channel to invite the agent to. You can invite the agent to additional channels at any time using the `/invite @Vantage` command. Once invited, you can interact with the agent by tagging `@Vantage`.
Once integrated, you can add the FinOps Agent to as many channels as you like. Your cost recommendations will always be sent to the channel designated for approvals during onboarding.
At this time, the FinOps Agent can only be messaged in Slack channels. Support for direct messaging is planned. The console agent provides a private, per-user chat experience today.
The FinOps Agent has guardrails in place to only answer questions pertinent to use of Vantage and the data within your Vantage account.
The console agent can accept text-based file inputs, including CSVs. Support for additional file types is planned for the future. The agent responds in plain text and, in Slack, with [Slack Blocks](https://docs.slack.dev/block-kit/) for richer formatting like tables.
Not at this time. The agent's behavior is consistent across all customers. Vantage continuously refines the agent's prompts and tooling based on customer feedback.
No. Vantage selects the model based on response accuracy and may update it at any time without notice.
Yes. Ask the agent—in the console or in Slack—for details about any recommendation. The agent will provide context about the usage patterns, historical data, and calculations that led to the recommendation. This transparency helps you make informed decisions about which optimizations to approve.
Yes. The FinOps Agent is fully aware of your existing Reserved Instances and Savings Plans commitments. All recommendations are calculated based on your uncovered usage after applying existing commitments, ensuring you don't over-commit or duplicate coverage.
Yes. While the Vantage console UI is currently available in English only, the FinOps Agent can understand questions and provide responses in other languages when you interact with it both in Slack and on the Agent console page. You can ask questions about your costs in your preferred language.
The FinOps Agent uses Vantage's MCP servers ([Vantage MCP](/vantage_mcp), [Vantage Docs MCP](/docs_mcp), and the [instances.vantage.sh MCP](https://instances-mcp.vantage.sh/)) under the hood to access your cost data, documentation, and public instance specifications and pricing. However, the agent provides a pre-configured experience—available in both the Vantage console and Slack—that doesn't require you to set up your own MCP client.
**Vantage MCP**: Allows you to connect your own AI tools (like Claude, Cursor, or Goose) directly to Vantage's APIs to query cost data and create reports using natural language. You have full control over which AI tool you use and how you interact with it.
**FinOps Agent**: A ready-to-use AI assistant built into the Vantage console and Slack that uses the MCP servers on your behalf. The agent can answer questions, create reports, and—through Slack—take action on savings recommendations, all without requiring you to configure an MCP client. It's designed for teams who want an immediate, integrated solution without the setup overhead.
Both options respect your RBAC permissions and provide access to the same underlying Vantage data and APIs.
### Permissions and Security
Only Vantage account Owners are allowed to approve cost remediation actions in Slack.
In the **console**, the agent uses your existing Vantage session—no additional authentication is required.
In **Slack**, the agent looks up the email of the Slack user against the list of authenticated Vantage users. The email of your Slack user must match the email of your Vantage user in order for authentication to be successful. If this is not the case, please reach out to [support@vantage.sh](mailto:support@vantage.sh) for assistance.
Yes, in order to use the FinOps Agent, you must be a registered user in Vantage.
Yes. The agent inherits the roles and permissions of your Vantage user and can only access or act on data you are authorized to view.
No, your data will not be used to train models. The agent only uses data fetched directly from your account via Vantage's APIs. All enhancements to the model will be done as prompt engineering from Vantage engineering teams to address feedback from customers and provide more guided answers.
The Vantage Slack app will request the following permissions in order to perform its functions:
* Content and info about channels & conversations
* View messages and other content in direct and group direct messages that "Vantage" has been added to
* View basic information about public channels in your workspace
* View basic information about private channels that "Vantage" has been added to
* Content and info about your workspace
* View people in your workspace
* View email addresses of people in your workspace
* Perform actions in channels & conversations
* View messages that directly mention @vantage in conversations that the app is in
* Join public channels in your workspace
* Send messages as @vantage
* Start direct messages with people
* Perform actions in your workspace
* Allow "Vantage" to act as your App Agent
* Add shortcuts and/or slash commands that people can use
### Actions and Automation
When the FinOps Agent proceeds to take an action (either after approval or autonomously), it follows these steps:
1. The agent posts a message in the Slack channel where recommendations are directed, outlining its action plan. An explicit click is required to initiate the action.
2. The agent executes the action in your cloud environment.
3. An entry is logged to the Vantage Audit Log for full transparency and traceability.
4. The agent reports back in the Slack thread with a summary of what was completed and the estimated savings achieved.
Customers can opt to disable automated actions at any time. Many optimizations (like rightsizing or Savings Plans) will be reversible within specified periods, while some purchases (i.e., RIs) are permanent. Audit logs provide traceability for governance.
Certain meaningful actions will also be queued for later in the day vs instantaneously to allow a human to potentially intervene. For example, if you are making a commitment for a Savings Plan for hundreds of thousands or millions of dollars, it will put into place an arbitrary delay in case you decide to reverse it.
All actions are logged in the Vantage Audit Log for full transparency and traceability, allowing you to review what was changed and when.
Currently, the FinOps Agent only supports automated remediation actions for AWS. Future provider support is planned for Azure, GCP, Datadog, and more.
You can view all actions taken by the FinOps Agent in AWS CloudTrail by filtering for events initiated by the IAM role that the FinOps Agent assumed. This allows you to see exactly what changes were made, when they occurred, and which role was used to execute them.
Within the Vantage Audit Logs, you will be able to see the following:
* Time the recommendation was provided
* Time the recommendation was approved
* Vantage User that approved the remediation
* What Resources were altered as a part of the recommendation remediation
* Time the action was taken in the cloud provider
### Configuration and Management
Yes, once the FinOps Agent is configured, you will have access to an agent settings page where you can opt in and out of all offered recommendations.
You can pause the FinOps Agent's automated actions and recommendation notifications at any time through the Vantage console by turning off a particular recommendation or all recommendations at once. This might be useful during periods of significant infrastructure changes, migrations, or organizational transitions. You can resume the agent whenever you're ready.
Yes, you can change the connected Slack channel at any time from the [FinOps Agent settings page](https://console.vantage.sh/settings/finops-agent) without needing to re-onboard. See [Update Slack Settings](#update-slack-settings) for details.
If the designated Slack channel is deleted, the FinOps Agent will no longer be able to send notifications about new recommendations or completed actions. If you have the Vantage Slack application added to other channels, you will be notified that a new channel needs to be set. You will also see your Slack integration in an Error state within the Vantage console. You'll need to reconfigure the FinOps Agent's Slack integration and designate a new channel through the Vantage console to resume receiving notifications.
If you have multiple integrations of the same provider, the FinOps Agent will provide additional context about which integration it is acting on.
You can provide feedback in two ways:
* **Quick feedback in Slack**: Add a thumbs up or thumbs down emoji reaction to any agent message in Slack.
* **Detailed feedback (console or Slack)**: Tell the agent you have feedback to share. The agent will use the `submit-user-feedback` tool from the Vantage MCP, and your message will be sent directly to the Vantage team for review.
This depends on your organization's Slack settings. As the application is currently under Marketplace review from Slack, this may require elevated permissions, such as Workspace Owner, in order to install. Check with your Slack Admin if you encounter any permission errors installing the Vantage app.
Vantage is currently in contact with Slack to have the application approved for downloading through the Slack Marketplace.
Yes, the OAuth URL for installing the app is created through the Vantage console, so any user that is looking to install the Vantage Slack App will need to do this through the Vantage Console until it is approved in the Slack Marketplace.
Autopilot will continue to function as normal. If you are currently set to "requires approval" and you integrate the agent into your Slack, you will begin to get notifications via Slack as well.
The configuration settings for Autopilot have moved to the agent section of the settings page, and the graphs for AWS Compute and the additional RI services will remain unchanged. Autopilot can be accessed from **Financial Planning** > **Autopilot** in the navigation menu.
The Vantage FinOps Agent is scoped to the account your Vantage user has direct access to. In an MSP setup, this means you can use the agent within your MSP Management account, but not across child Managed accounts by default. For automated remediation through Slack, the same scoping applies—only resources in your Management account are remediated.
To use the agent within a specific Managed account, [masquerade into that account](/partners#access-a-customer%E2%80%99s-managed-account) and access the agent there. Any questions you ask while masquerading are scoped to your user and are not visible to the Managed account.
### Technical Details
The FinOps Agent is powered by Anthropic's Claude and Cloudflare, providing the AI capabilities and infrastructure needed for natural language processing and cloud cost optimization.
# Vantage MCP
Source: https://docs.vantage.sh/vantage_mcp
Use natural language to explore your organization’s cloud costs via MCP clients, like Claude, Cursor, Goose, and others.
With the Vantage MCP ([Model Context Protocol](https://modelcontextprotocol.io/introduction)), you can ask questions about your organization's previous and current cloud cost spend, cost tagging, provider integrations, and more. The MCP lets you interact with your cloud cost data through AI assistants and MCP clients. By acting as a bridge to Vantage's existing APIs, the Vantage MCP Server lets you query cloud spend data using natural language and makes cost analysis more intuitive.
The Vantage MCP is [open source](https://github.com/vantage-sh/vantage-mcp-server) and available in two deployment modes:
* **Self-Hosted MCP**: With the Self-Hosted MCP, customers are responsible for deploying and managing their own instance of the MCP server, which includes managing API keys, handling authentication, and performing regular updates to keep up with new releases. The codebase is available on GitHub, allowing you to review, extend, and contribute to the code.
* **Remote MCP:** With the Remote Vantage MCP, Vantage manages all deployment and infrastructure. Customers do not need to deploy a new instance of the MCP when updates are released. Both the Remote and Self-Hosted MCPs use the same unified, open-source codebase, ensuring feature parity across deployment modes.
A separate [Vantage Docs MCP](/docs_mcp) is also available to query the documentation and find answers to common questions about how to use Vantage.
The [Vantage FinOps Agent](/vantage_finops_agent) uses both the Vantage MCP and Vantage Docs MCP to provide an AI assistant directly in Slack. The Agent can answer questions about your cloud costs, create reports, and take action on savings recommendations—all without requiring you to set up an MCP client. If you prefer to use your own AI tools (like Claude, Cursor, or Goose) with Vantage's MCP servers, you can configure them using the instructions on this page.
## MCP Clients
An MCP client (e.g., Claude, Cursor, Goose) is any AI agent or interface that can communicate using the Model Context Protocol to query backend services (i.e., servers), such as the Vantage MCP Server. The Vantage MCP Server acts as a backend service that translates natural language queries from clients into API calls to systems like Vantage.
The Vantage MCP Server is compatible with any AI agent that provides MCP client functionality. Examples of supported clients include:
* ChatGPT via the official [Vantage ChatGPT app](/chatgpt_app)
* Anthropic's [Claude](https://claude.ai/) Desktop application
* [Cursor](https://www.cursor.com/) IDE via the official [Vantage plugin in the Cursor Marketplace](https://cursor.com/marketplace/vantage)
* Block's local AI agent, [Goose](https://github.com/block/goose)
* OpenAI Codex agent
You can find a complete list of example clients in the [MCP documentation](https://modelcontextprotocol.io/clients).
## Access and Rate Limits
Prompts sent to the Vantage MCP are processed entirely within the AI client's environment and are not visible to Vantage. While Vantage can see which APIs are called on your behalf, it does not have access to the content of your prompts.
The Vantage MCP Server itself does not impose explicit rate limits; however, usage is subject to Vantage's underlying API rate limits, which are applied at the account level. These limits include a general rate limit of 1,000 requests per hour across all API endpoints, and a more restrictive limit of 5 requests per 5 seconds, specifically for Cost Report endpoints.
These limits are account-wide rather than per-user restrictions, meaning all API activity within your Vantage account contributes to these thresholds. In addition, when using the MCP with AI agents, you should consider the token limits and processing constraints of your chosen AI platform, as these may also impact your overall usage patterns and workflow efficiency.
For [Vantage for MSPs](/partners) customers, the MCP cannot perform any queries on child MSP accounts when calling from the parent account.
## Configure the Self-Hosted Vantage MCP
The Vantage MCP is open source and available on [GitHub](https://github.com/vantage-sh/vantage-mcp-server). Follow the steps provided in the repository's README to set up and deploy the self-hosted MCP. The repository includes instructions for running locally via stdio or deploying remotely using multiple authentication methods. You can also contribute to the codebase by submitting issues and pull requests.
## Configure the Remote Vantage MCP
Before getting started, make sure you have an active Vantage account. Authentication with the remote MCP uses OAuth. Once you’ve configured your client, a browser window is displayed, which prompts you to log in to Vantage, just like you would at [console.vantage.sh](https://console.vantage.sh/).
If you have an LLM or script that is not compatible with OAuth, you can also pass a [Vantage API token](/api/authentication) the same way you would a regular call to the Vantage API. The below example shows how this is done in a sample Python script:
```python theme={null}
token = os.getenv("VANTAGE_API_TOKEN")
config = {
"service": {
"url": "https://mcp.vantage.sh/mcp",
"transport": "http",
"headers": {
"Authorization": f"Bearer {token}"
}
}
}
```
You can't use a remote MCP instance without linking it to a Vantage user, since authentication is handled through existing Vantage accounts. If you need to support users who don't have Vantage accounts, use the [self-hosted MCP](https://github.com/vantage-sh/vantage-mcp-server), which supports API key-based authentication.
Guidance is provided below for how to install the remote MCP with some popular clients, like Claude, Cursor, and Goose. If you want to use ChatGPT, see the dedicated [Vantage ChatGPT App](/chatgpt_app) page. Instructions for your specific client may vary.
### Step 1 - Download and Install an MCP Client
Download [Claude for Desktop](https://claude.ai/download) for your operating system.
Download [Cursor](https://www.cursor.com/) for your operating system. Once Cursor is installed, the recommended way to add Vantage is the official [Vantage plugin in the Cursor Marketplace](https://cursor.com/marketplace/vantage).
Download [Goose](https://block.github.io/goose/docs/getting-started/installation/) for your operating system and configure an LLM provider.
Install [Codex CLI](https://openai.com/codex/) for your operating system.
### Step 2 - Configure the Vantage MCP Server
* Open Claude in your browser, then click your profile icon.
* Select **Settings** from the dropdown menu.
* Click **Connectors** in the sidebar.
If you don't see **Connectors** in the sidebar, you may need to click **Admin settings** first.
* At the top, click **Add** > **Add custom connector**.
* Give it a name and enter the remote MCP server URL: `https://mcp.vantage.sh/mcp`.
* Click **Add** to proceed.
The recommended way to add Vantage to Cursor is through the official [Vantage plugin in the Cursor Marketplace](https://cursor.com/marketplace/vantage). The plugin packages the Vantage MCP as a one-click install, which makes it easy to discover and standardize across an engineering team without each developer maintaining their own `mcp.json` configuration.
Open the [Vantage Cursor Marketplace listing](https://cursor.com/marketplace/vantage) and click **Add to Cursor**. Alternatively, in the Cursor chat panel, run:
```
/add-plugin vantage
```
Cursor walks you through adding the plugin to your environment.
Once installed, the Vantage plugin is listed under **Plugins** in Cursor and `VantageMCP` is registered as an active MCP server. No manual `mcp.json` editing is required.
If you prefer to configure the Vantage MCP manually instead of using the Marketplace plugin (e.g., to check `mcp.json` into a repo for project-level use), you can add the server directly:
* Press Cmd/Ctrl + Shift + P to open the command palette.
* Type "MCP" and select **Open MCP Settings**.
* Click **Add MCP Server**.
* Add the following configuration to your `mcp.json` file:
```json mcp.json theme={null}
{
"mcpServers": {
"VantageMCP": {
"url": "https://mcp.vantage.sh/mcp"
}
}
}
```
* Save the file.
* From the left navigation pane in Goose, click **Extensions**.
* On the **Extensions** screen, click **+ Add custom extension**.
* Enter the following extension details:
* For **Extension Name**, enter *Vantage*.
* For **Type**, select **Streamable HTTP**.
* For **Endpoint**, enter `https://mcp.vantage.sh/mcp`.

* Click **Add Extension**.
Run the following command in your terminal:
```bash theme={null}
codex mcp add Vantage -- npx -y "https://mcp.vantage.sh/mcp"
```
This command adds the Vantage MCP server to your Codex configuration.
### Step 3 - Authorize the Vantage MCP Server
You may need to close and reopen your client for the authorization screen to display.
After you configure the MCP server, an authorization screen is displayed in your browser.
Read the authorization information, then click **Allow Access** to proceed.

You will then be prompted to log in to Vantage with your username and password or authenticate via SSO. After you log in to Vantage, you will have access to the Vantage MCP server.
### Step 4 - Prompt the Vantage MCP Server
Start a new chat to begin prompting Claude. For example, you can ask, *"In Vantage, which workspaces do I have access to?"* Claude uses the appropriate [MCP tool](/vantage_mcp#vantage-mcp-tools) and replies with workspace access details.

Each time Claude uses a new tool, you'll be asked to approve it. Click **Allow Always** to grant ongoing access, or **Allow Once** to approve it just this time.

You may encounter conversation limits when prompting Claude. If you encounter a limit, create a new chat. As a best practice, keep separate topics in separate chats for better organization.
Start a new chat to begin prompting Cursor. For example, you can ask, *"In Vantage, which workspaces do I have access to?"* Cursor uses the appropriate [MCP tool](/vantage_mcp#vantage-mcp-tools) and replies with workspace access details.
Start a new chat to begin prompting Goose. For example, you can ask, *"In Vantage, which workspaces do I have access to?"* Goose uses the appropriate [MCP tool](/vantage_mcp#vantage-mcp-tools) and replies with workspace access details.

Start Codex and begin prompting. For example, you can ask, *"In Vantage, which workspaces do I have access to?"* Codex uses the appropriate [MCP tool](/vantage_mcp#vantage-mcp-tools) and replies with workspace access details.
## Revoke MCP Access Token
You can revoke your MCP Access Token at any time in the Vantage console.
From the top navigation in Vantage, click **Settings**.
On the left navigation, under **General Settings**, select **API Access Tokens**.
Select the **MCP Server Token** tab.
To delete your token, click **Remove MCP Access**. You can restore access at any time by re-entering the authentication flow with an MCP client.
## Vantage MCP Tools
MCP tools "are a powerful primitive in the Model Context Protocol (MCP) that enable servers to expose executable functionality to clients. Through tools, LLMs can interact with external systems, perform computations, and take actions in the real world" ([Source](https://modelcontextprotocol.io/docs/concepts/tools)). The Vantage MCP exposes the following tools:
For prompt examples that exercise these tools through the [Vantage FinOps Agent](/vantage_finops_agent), see the [FinOps AI Prompt Guide](/guides/finops_ai_prompt_guide#what-the-agent-can-do).
Some tools are available only on [Vantage for MSPs](/partners) Management Accounts. Today, that includes the billing rules tools (`create-billing-rule`, `get-billing-rule`, `list-billing-rules`, `update-billing-rule`, and `delete-billing-rule`). [Billing rules](/partners#billing-rules) adjust, exclude, credit, charge, or re-rate Managed Account cost data. They are not the same as [Virtual Tags](/tagging), which normalize cost attribution with derived tag keys—use `create-virtual-tag-config` for Virtual Tags.
| Tool | Description |
| - | - |
| `add-team-member` | Add a user to a team. |
| `create-annotation` | Create an [annotation](/annotations) on one or more Cost Reports for a specific date, such as a note, explanation, or event marker. |
| `create-billing-rule` | **MSP-only.** Create a [billing rule](/partners#billing-rules) on a [Vantage for MSPs](/partners) Management Account to adjust, exclude, credit, charge, or apply custom modifications to Managed Account cost data. Not for Virtual Tags—use `create-virtual-tag-config` instead. |
| `create-budget` | Create a budget based on the parameters specified. Useful for managing budgets or building cost reports with budgets in mind. |
| `create-budget-alert` | Create a budget alert that notifies recipients when a budget's spend crosses a configured threshold. |
| `create-canvas` | Create a [Canvas](/canvas) from a natural-language prompt. A Canvas is an AI-generated cost analysis view; creating one triggers an asynchronous refresh to generate the data. |
| `create-cost-alert` | Create a cost alert that notifies you when spending on one or more cost reports exceeds a specified threshold over a given interval. |
| `create-cost-report` | Create new Cost Reports with VQL filters, date ranges, chart settings, date binning, and other configuration options. |
| `create-dashboard` | Create a new Dashboard in Vantage. Dashboards are collections of widgets that visualize cost data. You can attach widgets (cost reports, usage reports, resource reports, Kubernetes efficiency reports, financial commitment reports, recommendation saved views) and saved filters, and control the time range using date intervals or custom date ranges. |
| `create-financial-commitment-report` | Create a Financial Commitment Report with a title, workspace, date range, grouping, and optional VQL filter. |
| `create-folder` | Create a folder for organizing Cost Reports. Folders can be nested via a parent folder token; saved filters can be applied so reports in the folder inherit them. |
| `create-kubernetes-efficiency-report` | Create a [Kubernetes Efficiency Report](/kubernetes#create-efficiency-reports) with a title, workspace, date range, groupings, and optional VQL filter. |
| `create-network-flow-report` | Create a saved [Network Flow Report](/network_flow_reports) for analyzing cloud network traffic by cost or bytes. |
| `create-recommendation-view` | Create a saved Recommendation View scoped by provider, account, region, recommendation type, tags, date range, or minimum savings. |
| `create-report-forecast` | Assign one or more [Scenario Models](/scenario_models) (and optionally a Business Metric) to a Cost Report as a forecast. Requires Scenario Models (Enterprise). |
| `create-report-notification` | Create a Report Notification that delivers scheduled Cost Report summaries to users, Slack channels, or Microsoft Teams channels on a daily, weekly, or monthly cadence. |
| `create-resource-report` | Create a Resource Report with a workspace, resource type, title, VQL filter, selected columns, and optional folder. |
| `create-saved-filter` | Create a [Saved Filter](/saved_filters) with a title and VQL filter for reuse across Cost Reports. |
| `create-scenario-model` | Create a [Scenario Model](/scenario_models) with optional periods and provider/service filters, then assign it to Cost Report forecasts. Requires Scenario Models (Enterprise). |
| `create-team` | Create a team and optionally associate it with Workspaces, users, roles, and a default Dashboard. |
| `create-virtual-tag-config` | Create a Virtual Tag Config in Vantage. Virtual Tag Configs define a derived (virtual) tag key and a set of values determined by VQL filters. This is useful for normalizing cost attribution, mapping multiple provider tag formats into a single tag, collapsing noisy tag keys, and optionally overriding provider-supplied tags. Virtual Tags are available to all accounts and are distinct from MSP-only billing rules. |
| `create-virtual-tag-config-value` | Add a value to an existing [Virtual Tag](/tagging) Config, defined by a VQL filter and, optionally, a business metric or date ranges. |
| `create-workspace` | Create a new Workspace for organizing cost data and access control across teams, with optional currency conversion settings. |
| `delete-annotation` | Delete a Cost Report [annotation](/annotations) by its token. This action is irreversible. |
| `delete-billing-rule` | **MSP-only.** Delete a [billing rule](/partners#billing-rules) by its token on a [Vantage for MSPs](/partners) Management Account. |
| `delete-budget` | Delete a Budget by its token. |
| `delete-budget-alert` | Delete a budget alert by its token. |
| `delete-canvas` | Delete a [Canvas](/canvas) by its token. This action is irreversible. |
| `delete-cost-alert` | Delete a cost alert by its token. This action is irreversible. |
| `delete-cost-report` | Delete a Cost Report by its token. |
| `delete-dashboard` | Delete a Dashboard by its token. |
| `delete-financial-commitment-report` | Delete a Financial Commitment Report by its token. |
| `delete-folder` | Delete a folder by its token. |
| `delete-kubernetes-efficiency-report` | Delete a [Kubernetes Efficiency Report](/kubernetes#create-efficiency-reports) by its token. |
| `delete-network-flow-report` | Delete a [Network Flow Report](/network_flow_reports) by its token. |
| `delete-recommendation-view` | Delete a Recommendation View by its token. |
| `delete-report-forecast` | Delete a [Scenario Model](/scenario_models) forecast from a Cost Report by its token. Requires Scenario Models (Enterprise). |
| `delete-report-notification` | Delete a Report Notification by its token, stopping the scheduled Cost Report summary from being delivered. |
| `delete-resource-report` | Delete a Resource Report by its token. |
| `delete-saved-filter` | Delete a [Saved Filter](/saved_filters) by its token. |
| `delete-scenario-model` | Delete a [Scenario Model](/scenario_models) by its token, regenerating any forecasts that referenced it. Requires Scenario Models (Enterprise). |
| `delete-team` | Delete a team by its token. |
| `delete-virtual-tag-config` | Delete a [Virtual Tag](/tagging) Config by its token. |
| `delete-virtual-tag-config-value` | Delete a single value from a [Virtual Tag](/tagging) Config by its token. |
| `get-anomaly` | Get a specific cost anomaly by its token, including details about the anomaly's trigger, affected service, and date range. |
| `get-billing-rule` | **MSP-only.** Get a specific [billing rule](/partners#billing-rules) by its token on a [Vantage for MSPs](/partners) Management Account, including its type, configuration, and applicable dates. |
| `get-budget` | Get a specific Budget by its token. Optionally includes performance data showing actual spend vs. budget amounts by period. |
| `get-budget-alert` | Get a specific budget alert by its token. |
| `get-business-metric` | Get a specific Business Metric by its token. Business Metrics can be attached to Cost Reports for per-unit cost analysis. |
| `get-business-metric-forecasted-values` | Get forecasted values for a Business Metric by date, with optional labels. |
| `get-business-metric-values` | Get historical values for a Business Metric by date, with optional labels. |
| `get-canvas` | Get a specific [Canvas](/canvas) by its token, including its title, prompt, status, and structured table data. |
| `get-cost-alert` | Get a specific cost alert by its token. |
| `get-cost-alert-event` | Get a specific cost alert event (an individual alert trigger record) by its token. |
| `get-cost-provider-accounts` | Get cost provider accounts with human-readable names and IDs. |
| `get-cost-report` | Get a specific Cost Report by its token, including its VQL filter, groupings, date range, and other configuration. |
| `get-cost-report-forecast` | List all spending forecasts related to a Cost Report. |
| `get-dashboard` | Get a specific Dashboard by its token, including its widgets, saved filters, and date settings. |
| `get-financial-commitment-report` | Get a specific Financial Commitment Report, including its title, workspace, date range, grouping, cost scope, and filter configuration. |
| `get-folder` | Get a specific folder by its token, including its title, parent folder, and saved filter configuration. |
| `get-kubernetes-efficiency-report` | Get a specific [Kubernetes Efficiency Report](/kubernetes#create-efficiency-reports) by its token, including its filter, groupings, and date configuration. |
| `get-myself` | A utility to list available workspaces and check the access level of your authentication token. |
| `get-network-flow-report` | Get a saved [Network Flow Report](/network_flow_reports) by its token. |
| `get-provider-resource` | Get detailed information about a specific provider resource using its token or UUID, including resource metadata, account information, and optional cost breakdown by category. |
| `get-recommendation-details` | Get comprehensive details about a specific recommendation. |
| `get-recommendation-resource-details` | Get detailed information about a specific resource within a recommendation. |
| `get-recommendation-resources` | Get infrastructure resources affected by a recommendation. |
| `get-recommendation-view` | Get a specific Recommendation View by token. |
| `get-report-forecast` | Get a specific [Scenario Model](/scenario_models) forecast for a Cost Report by its token. Requires Scenario Models (Enterprise). |
| `get-report-notification` | Get a specific Report Notification by its token, including its Cost Report, recipients, delivery channels, frequency, and tracked change type. |
| `get-resource-report` | Get a specific Resource Report by its token, including its resource type, columns, VQL filter, folder, and workspace. |
| `get-saved-filter` | Get a specific [Saved Filter](/saved_filters) by its token, including its title and VQL filter. |
| `get-scenario-model` | Get a specific [Scenario Model](/scenario_models) by its token, including its periods and filters. Requires Scenario Models (Enterprise). |
| `get-team` | Get a specific team with its token. |
| `get-team-members` | Return all users in a team. |
| `get-teams` | Return all teams that the user has access to. |
| `get-user` | Get a specific user by their token. Use `get-users` to discover user tokens in the workspace. |
| `get-users` | Return all users that the user can see in the workspace. |
| `get-virtual-tag-config` | Get a specific [Virtual Tag](/tagging) Config by its token, including its values. |
| `get-virtual-tag-config-value` | Get a single [Virtual Tag](/tagging) Config value by its token. |
| `get-workspace` | Get a specific Workspace by its token. |
| `list-annotations` | List Cost Report [annotations](/annotations), ordered newest to oldest, optionally filtered to a specific Cost Report. |
| `list-anomalies` | List of anomalies that were detected on Cost Reports. |
| `list-audit-logs` | List audit logs for actions taken within the Vantage workspace. |
| `list-billing-rules` | **MSP-only.** List all [billing rules](/partners#billing-rules) on a [Vantage for MSPs](/partners) Management Account. Billing rules adjust, exclude, credit, charge, or re-rate Managed Account cost data; they are not Virtual Tags. |
| `list-budget-alerts` | List all budget alerts, optionally filtered by workspace. |
| `list-budgets` | List all budgets available to compare against a Cost Report and track spending. |
| `list-business-metric-labels` | List the distinct label values for a [Business Metric](/business_metrics#labeled-business-metrics). For multi-label metrics, values are flattened across label keys. Use this before `get-business-metric-values` when a request depends on labels. |
| `list-business-metrics` | List all Business Metrics available to the current token. Business Metrics represent KPIs, such as requests, users, or revenue, for per-unit cost analysis. |
| `list-canvases` | List all saved [Canvases](/canvas) available in the Vantage account. |
| `list-cost-alert-events` | List events (individual alert trigger records) for a cost alert, optionally filtered by Cost Report token. |
| `list-cost-alerts` | List all cost alerts in the Vantage account. Cost alerts notify you when spending exceeds a specified threshold for a cost report. |
| `list-cost-integrations` | List all cost provider integrations (e.g., AWS, Azure, GCP) available to provide costs data from and their associated accounts. |
| `list-cost-providers` | List of the providers that the given workspace has shared with it, for filtering in [Vantage Query Language (VQL)](/vql) queries. |
| `list-cost-reports` | List all available Cost Reports. Accepts an optional `folder_token` argument to return only Cost Reports within the specified folder. |
| `list-cost-services` | Lists all the services and their associated providers that are shared with the given workspace. |
| `list-costs` | Display all the costs in an associated Cost Report. Supports date binning, cost settings, and grouping controls such as credits, refunds, discounts, taxes, amortization, unallocated costs, aggregate-by mode, previous-period comparison, and grouping fields. |
| `list-dashboards` | List of all dashboards created in the Vantage account. |
| `list-financial-commitment-reports` | List Financial Commitment Reports available in the Vantage account. |
| `list-folders` | List all folders for organizing Cost Reports. Folders can be nested; each folder’s title and saved filter tokens are returned. |
| `list-kubernetes-efficiency-reports` | List [Kubernetes Efficiency Reports](/kubernetes#create-efficiency-reports) available in the Vantage account. |
| `list-network-flow-reports` | List saved [Network Flow Reports](/network_flow_reports). Use `get-network-flow-report` for a report's configuration. |
| `list-provider-resources` | List infrastructure provider resources (instances, volumes, load balancers, etc.) from your cloud accounts. Resources can be fetched from a specific Resource Report or using VQL filters. |
| `list-recommendations` | List all cost optimization recommendations available in the Vantage account. Supports filtering by status, provider, workspace, provider account, billing account, region, tag key/value, date range, recommendation type, and minimum monthly savings. |
| `list-recommendation-views` | List saved Recommendation Views available in the Vantage account. |
| `list-report-forecasts` | List [Scenario Model](/scenario_models) forecasts for a Cost Report. Requires Scenario Models (Enterprise). |
| `list-report-notifications` | List Report Notifications (scheduled deliveries of Cost Report summaries to users, Slack, or Microsoft Teams channels) available in the Vantage account. |
| `list-resource-report-columns` | List the available columns for a Resource Report resource type. |
| `list-resource-reports` | List Resource Reports available in the Vantage account, with pagination support. |
| `list-saved-filters` | List [Saved Filters](/saved_filters), optionally searching by title or filtering by workspace. |
| `list-scenario-models` | List [Scenario Models](/scenario_models) available to the current token. Requires Scenario Models (Enterprise). |
| `list-tag-values` | List of tag values that can be used to filter Cost Reports. |
| `list-tags` | List of tags that can be used to filter Cost Reports. |
| `list-unit-costs` | Retrieve the unit costs for a given Cost Report. |
| `list-virtual-tag-configs` | List [Virtual Tag](/tagging) Configs available to the current token. |
| `list-workspaces` | List all Workspaces available to the authenticated token. Workspaces are isolated environments for organizing cost data and access control across teams. |
| `query-costs` | A general-purpose way to fetch cost data using VQL. Supports date binning, cost settings, and grouping controls such as credits, refunds, discounts, taxes, amortization, unallocated costs, aggregate-by mode, previous-period comparison, and grouping fields. |
| `query-financial-commitment-report-costs` | Query costs for a Financial Commitment Report with date range, grouping, filter, cost scope, ordering, and pagination controls. |
| `query-kubernetes-efficiency-report-costs` | Query costs for a [Kubernetes Efficiency Report](/kubernetes#create-efficiency-reports) with date range, grouping, and filter controls. |
| `query-network-flow-logs` | Query aggregated [network flow log](/network_flow_reports) data, by costs and bytes. Pass a saved report token or an ad hoc filter. |
| `remove-team-member` | Remove a user from a team. |
| `submit-user-feedback` | Send feedback about the MCP or overall Vantage experience to the Vantage team. |
| `update-annotation` | Update the title, date, message, or associated Cost Reports of an existing [annotation](/annotations). |
| `update-anomaly` | Update an existing cost anomaly alert's status (e.g., active, archived, ignored) and optionally provide feedback. |
| `update-billing-rule` | **MSP-only.** Update an existing [billing rule](/partners#billing-rules) on a [Vantage for MSPs](/partners) Management Account, including its title, dates, and type-specific fields. |
| `update-budget` | Update an existing Budget. You can update the name, linked Cost Report, child Budget tokens for hierarchical budgets, or budget periods. |
| `update-budget-alert` | Update an existing budget alert's threshold, recipients, or notification channels. |
| `update-canvas` | Update an existing [Canvas](/canvas). You can update the title, the prompt, or both; updating the prompt triggers an asynchronous refresh to regenerate the data. |
| `update-cost-alert` | Update an existing cost alert's title, threshold, interval, monitored Cost Reports, or notification destinations. |
| `update-cost-report` | Update an existing Cost Report's title, VQL filter, groupings, date range, chart type, folder, report settings, or attached business metrics. |
| `update-dashboard` | Update an existing Dashboard's title, widgets, saved filters, date settings, or workspace. |
| `update-financial-commitment-report` | Update an existing Financial Commitment Report, including its title, date range, grouping, and VQL filter. |
| `update-folder` | Update an existing folder's title, parent folder, or saved filter configuration. |
| `update-kubernetes-efficiency-report` | Update an existing [Kubernetes Efficiency Report](/kubernetes#create-efficiency-reports), including its title, date range, groupings, and VQL filter. |
| `update-network-flow-report` | Update a saved [Network Flow Report](/network_flow_reports). Use `list-network-flow-reports` to discover tokens. |
| `update-recommendation-view` | Update an existing Recommendation View's title or filters (provider, account, region, tags, recommendation type, date range, or minimum savings). |
| `update-report-forecast` | Update a [Scenario Model](/scenario_models) forecast on a Cost Report; providing `scenario_model_tokens` replaces the assigned models, and you can set it as the default forecast. Requires Scenario Models (Enterprise). |
| `update-report-notification` | Update an existing Report Notification's title, Cost Report, recipients, Slack or Microsoft Teams channels, delivery frequency, or tracked change type. |
| `update-resource-report` | Update an existing Resource Report's title, VQL filter, columns, folder, or workspace. |
| `update-saved-filter` | Update a [Saved Filter](/saved_filters) title or VQL filter. |
| `update-scenario-model` | Update an existing [Scenario Model](/scenario_models); providing periods replaces the full period set. Requires Scenario Models (Enterprise). |
| `update-team` | Update a team's name, description, Workspace and user associations, user role, or default Dashboard. |
| `update-virtual-tag-config` | Update an existing [Virtual Tag](/tagging) Config's key, values, or overrides. |
| `update-virtual-tag-config-value` | Update a single [Virtual Tag](/tagging) Config value's filter, business metric, or date ranges by its token. |
| `update-workspace` | Update an existing Workspace's name, currency conversion settings, currency code, or exchange rate date method. |
## Examples - Prompt the Vantage MCP
When you use the Vantage MCP, consider constructing clear and well-structured prompts to get the exact response you are looking for. This method helps your AI client understand your intent and provides you with the best response. You can provide relevant context, such as specific workspaces, timeframes, or services. See the [Prompting Best Practices](/vantage_mcp#prompting-best-practices) section for some additional tips.
Consider the below example. In this example, the user has chosen to use Claude to interact with the Vantage MCP. This user is part of an organization that has multiple workspaces on Vantage.
The user asks:
> *How much did we spend on S3 in us-east-1 over the last 30 days?*
Claude responds:
> *I'll help you find your S3 spending in us-east-1 over the last 30 days. First, let me check your workspace information and available cost providers.*
The MCP’s `get-myself` tool is then used to retrieve:
* User identity
* Accessible workspaces
* Cost provider connections (e.g., AWS)
Claude identifies that the user has access to multiple workspaces and selects the default one to proceed:
> *I can see you have access to multiple workspaces. To get your S3 spending data, I'll need to know which workspace you'd like me to query. I'll start with the first workspace ('Marketing Workspace') and check for AWS S3 costs.*
Now that Claude has the necessary context, it calls the MCP’s `query-costs` tool with scoped filters:
```json theme={null}
{
"filter": "(costs.provider = 'aws' AND costs.service = 'Amazon Simple Storage Service' AND costs.region = 'us-east-1')",
"date_bin": "day",
"end_date": "2025-07-22",
"start_date": "2025-06-22",
"workspace_token": "wrkspc_1234567"
}
```
Claude responds:
> *It looks like there are no S3 costs in us-east-1 for Marketing Workspace. Let me try a few other workspaces to see if your S3 costs might be in a different workspace. Let me check the "Management" workspace which seems like it might be a primary workspace.*
It then uses the `query-costs` tool again to look in other workspaces until it finds spend in a workspace:
> *Based on your query for S3 costs in us-east-1 over the last 30 days (June 22 - July 22, 2025), here's what I found:*
>
> ***S3 Spending Summary (us-east-1, Last 30 Days)***
>
> *Total S3 Spend: \$55,089.92*
>
> *The costs are distributed across multiple AWS accounts:*
>
> ***Top Spending Accounts:***
>
> *- Account 123456789: \~\$25,850+ (dominant portion of spend)*
>
> *...*
In addition, daily spending patterns and other insights are provided.
For quicker, more relevant results, if the user had specified the workspace in the initial question, for example:
> *How much did we spend on S3 in us-east-1 over the last 30 days in the Management Workspace?*
Claude would immediately have the necessary context and could skip the workspace confirmation step, which would result in a quicker, more relevant response.
## Prompting Best Practices
Consider using the following best practices when working with the Vantage MCP:
* Add context to your prompts. Mention primitives like provider, time frame, workspace, specific service, or tags, when applicable.
* *Example: What was our GCP BigQuery spend for September and October 2024?*
* Construct your prompts using group-by statements to help reduce token consumption (e.g., group costs by month as opposed to day).
* Ask one thing at a time and avoid stacking various unrelated questions. Instead of, *"What were our EC2 costs last month, and also which accounts are over budget, and can you tell me if any tags are missing?"* consider asking these as separate prompts to keep responses organized and information relevant.
* Be specific. Don’t assume the client knows what terms like "important" mean. Instead of *"What are my most important costs to monitor?"*, try something more specific, like, *"Which services have the highest costs without tags?"* or *"Which accounts had the biggest increase in spend over the past two months?"*
* Be clear about the format of the output you want. If you'd like results in a table, chart, or summary, specify that in your prompt.
* *Example: Show me EC2 spend in us-east-1 last month by instance type in a table, with instance types in the first column and costs in the second.*
### Validating Responses
Because MCP relies on an LLM, responses are not always deterministic. This means that the same prompt may return slightly different answers, and results heavily depend on the context provided. You can follow the below best practices when validating outputs:
* Use your existing Cost Reports as a source of truth. For example, if you ask about EC2 spend last month, you can validate the answer against your saved report for that timeframe.
* When you prompt a client, like Goose or Claude, you can expand the tool calls (such as `query-costs`) to view the underlying request details. You can then use this logic to help confirm whether the filters and groupings align with your intent.
* If you find a response that appears inaccurate or misleading, share the full prompt and result with our team. See the [Feedback](/vantage_mcp#feedback) section below for details.
### Additional Prompt Examples
Additional examples are provided below for how you can interact with the Vantage MCP.
* How much did we spend on S3 in us-east-1 over the last 30 days in the Management workspace?
* What are the top 5 most expensive GCP services this month across all workspaces?
* Compare GCP and Azure spend for the last quarter.
* Show me my EC2 costs that are tagged with the environment tag.
* What is our forecasted cloud spend for next month across all providers?
* If we deprecate the ap-northeast-2 AWS region, how much could we save?
* List all tags available in our default workspace.
* Get last month’s Datadog spend filtered by the infra team tag.
* Break down Azure costs by the owner tag for the past 90 days.
* Are there any recent major anomalies in our GitHub spend?
* Which AWS services spiked in cost over the last 7 days?
## Privacy and Data Handling
The Vantage MCP uses your existing Vantage account for authentication. It respects the same Vantage account and workspace permissions that apply in the Vantage console and APIs. If a user does not have access to a given workspace, report, or other resource in Vantage, the MCP cannot access it on that user's behalf.
Prompts are handled in the AI client environment, while Vantage receives the underlying API calls needed to fulfill the request. For more information, see the [Privacy Policy](https://www.vantage.sh/legal/privacy-policy) and [Service Agreement](https://www.vantage.sh/legal/service-agreement).
## Feedback
You can join the free [Vantage Community Slack](https://vantage.sh/slack) to connect with other users and the Vantage team. In the `#mcp` channel, share feedback, ask questions, and see how others are using the Vantage MCP server.
You can also use the `submit-user-feedback` tool within the MCP to submit feedback. Send a prompt, like:
> *Can you provide Vantage the following feedback: I love using the MCP!*
# Vantage University
Source: https://docs.vantage.sh/vantage_university
Learn Vantage through hands-on practice and interactive tutorials.
## 📚 Feature Video Lessons
Reference these focused lessons to learn specific Vantage features in detail.
Set up and navigate workspaces.
Connect cloud providers and custom sources.
Create, filter, and visualize Cost Reports.
Create virtual tags and tag hierarchies.
Set up anomaly alerts and act on recommendations.
Track cost per unit and business metrics.
Create budgets and configure alerts.
Monitor per-resource costs and network flows.
***
## 🚀 Hands-On Learning
Use your knowledge to complete a hands-on demo.
***
## 👥 Role-Specific Learning Tracks
Explore Vantage from the perspective of your role. Lessons include a mix of videos and hands-on learning.
Learn about how to use Vantage effectively as your organization's FinOps power user, building a culture of cloud cost optimization.
Learn about how you can best use Vantage to manage and optimize the cloud resources you are responsible for.
Learn about how you can use Vantage to manage and analyze the total cost of your organization.
# Account Management
Source: https://docs.vantage.sh/vantage_university_account_management
Welcome to the Account Management learning track on Vantage University!
## What Are Workspaces?
Workspaces in Vantage let you separate your provider integrations into distinct cost views. You connect cloud provider accounts to Vantage, then assign each integration to one or more workspaces. Each workspace is its own environment where you can organize and analyze costs and resources—for a single provider or across multiple providers.
## Why Should I Use Workspaces?
Workspaces in Vantage offer several benefits.
Workspaces enable users to gain a comprehensive view of expenses within a specific cloud provider account or across multiple providers, facilitating better cost management and optimization.
By grouping resources within workspaces, teams can create focused views tailored to their specific needs.
With role-based access controls (RBAC) (Enterprise feature), administrators can also limit user access to different workspaces.
## Workspaces Use Cases
As a **cloud administrator** overseeing a diverse infrastructure, you can create a distinct Vantage workspace for each of your environments, such as *Production*, *Staging*, and *Development*. Then, specify which provider accounts are associated with which workspace. For example, a particular Datadog account may be associated with only your *Development* workspace.
As a **product manager** who is responsible for overseeing various products or services, attributing costs accurately is important for team accountability. By creating separate workspaces for each product or service, you can isolate expenses, track resource utilization, and easily assess the financial performance of individual offerings.
## Lesson 1: Navigate Workspaces
## Lesson 2: Manage Workspace Provider Integrations
## Additional Resources
# Budgeting
Source: https://docs.vantage.sh/vantage_university_budgeting
Welcome to the Budgeting learning track on Vantage University!
## What Is Budgeting in Vantage?
In Vantage, you can create budgets and be alerted if costs are trending over budget. Budgets can track dollar spend or a usage quantity, such as tokens or instance-hours, so you can plan in the same units you're billed or metered in. You can import budgets for hundreds of accounts, organizational units, and services as part of annual planning. Configure alerts for email, Slack, or Microsoft Teams when spend is trending over budget, with quick links to investigate.
## Why Should I Use Vantage Budgets?
Using Vantage budgets allows you to control cloud spending effectively, ensuring costs stay within planned limits. You can create multiple alerts for various teams or projects to ensure budgets stay on track.
## Budgets Use Cases
As a **financial analyst**, you create a budget for the entire organization on the period that matches your planning cadence (for example, monthly or quarterly). You configure the associated alert to notify you within the first or last several days of the budget period if costs are trending over budget. This allows you to review and adjust spending in time to stay within financial targets, ensuring that there are no surprises at period-end and supporting accurate financial reporting and planning.
As an **application owner**, you are responsible for ensuring that costs don't exceed the budget allocated to your specific application. You create a budget and alert that notifies you when costs have exceeded 75% of the budget. This way, you can take proactive measures to adjust resource usage for your application and stay within your team's allocated budget.
## Lesson 1: Create Standard Budgets
## Lesson 2: Create Hierarchical Budgets
## Lesson 3: Create Budget Alerts
## Lesson 4: Create Usage Budgets
## Additional Resources
# Cost Allocation
Source: https://docs.vantage.sh/vantage_university_cost_allocation
Welcome to the Cost Allocation learning track on Vantage University!
## What Is Cost Allocation?
Cost allocation is the process of assigning costs to different parts of an organization, such as teams, projects, or business units, to accurately track and manage expenses. In Vantage, cost allocation is built on virtual tags.
Virtual tags allow you to create consistent and standardized tags across all cloud providers within Vantage. You can tag costs without needing to make changes to your existing cloud infrastructure. Virtual tags are useful for ensuring uniform tagging practices. With [nested virtual tags](/tagging#nested-virtual-tags), you can also build hierarchies, such as mapping applications to teams and teams to business units, and then view that allocation in Cost Reports.
## Why Should I Use Cost Allocation?
Using virtual tags in Vantage helps you gain better control over your cloud spending. Virtual tags ensure consistent and accurate cost tagging across all cloud providers, making your financial reporting more reliable. Nested virtual tags let you organize that tagged data into a hierarchy that mirrors your organization, so you can allocate costs effectively and find costs that have not been assigned an owner.
## Cost Allocation Use Cases
As a **financial analyst**, you can:
* Use **virtual tags** to standardize tagging across all cloud providers without involving the engineering team, ensuring that your financial reports are uniform and reliable.
* Use **nested virtual tags** to roll tagged costs up to business units or cost centers, then group a Cost Report by that tag to see which costs still lack an owner. This improves financial accountability by ensuring no costs are overlooked in your financial reports.
As a **cloud operations manager**, you can:
* Use **virtual tags** for tag consolidation. You may manage a large infrastructure with an inconsistent tagging schema. You also need reports that help you quickly filter and group cloud resources to identify cost-saving opportunities and optimize resource usage, such as changing instance types or selected databases.
* Use **nested virtual tags** to map costs to the different cloud operations teams and their corresponding applications you are responsible for, providing a detailed and organized view of cost distribution across your division.
## Lesson 1: Introduction to Tagging
## Lesson 2: Create Virtual Tags
## Lesson 3: Additional Tagging Workflows
## Additional Resources
# Cost Reporting
Source: https://docs.vantage.sh/vantage_university_cost_reporting
Welcome to the Cost Reporting learning track on Vantage University!
## What Is Cost Reporting?
Cost Reports are one of the fundamental tools in Vantage. They provide complex reporting to slice and dice the data for many use cases. You can create numerous reports in Vantage and use filters, grouping parameters, and timeframe options to see the exact data you want to see. Cost Reports include a chart view and a cost table. You can manipulate the view to highlight certain data points and zoom in on particular dates or areas where you see anomalies.
## Why Should I Use Cost Reporting?
Cost Reports can help any user or stakeholder to view the exact costs they want to see across any cloud provider (e.g., AWS), a set of accounts, or even check on their current tagging schema. If you want to see a longitudinal view of your cost data and have the ability to filter by multiple parameters, then you can start with Cost Reports to get an overall picture of the state of your costs.
## Cost Reporting Use Cases
Cost Reports are helpful for any FinOps stakeholder—from engineering managers to organizational management.
As an **engineering manager**, you may want to see why data transfer costs are increasing for storage resources. You can create a Cost Report with filters for AWS data transfer costs and view down to the resource level where you're seeing the highest cost spikes. You use the Annotations and Vantage Issues feature to collaborate with other teams and understand changes in data transfer costs over time. You also create a dashboard to monitor team projects and present current costs over time to management.
As a **FinOps stakeholder**, you may want to review your tagged resources and ensure teams are following tagging standards. You can create a report to check for untagged resources across one or more providers. Use this report to help you add missing tags or update existing tags.
As an **application owner**, create a monthly overview of all costs related to your application. You can create a report that breaks down expenses by resource and cost category. Filter for resources with your application's corresponding tag. Use the report to track spending trends and variations to understand the cost impact of application usage and changes over time. You set up Report Notifications to send you a monthly digest of specific reports so you can remember to go in and check where things are at each month.
## Lesson 1: Create and View a Cost Report
## Lesson 2: Filter a Cost Report
## Lesson 3: View Cost Report Forecasts
## Lesson 4: Create Report Notifications
## Lesson 5: Add Annotations to Cost Reports
## Lesson 6: Create Cost Alerts
## Lesson 7: Create Usage-Based Reports
## Lesson 8: View and Manage Dashboards
## Lesson 9: Create Vantage Issues
## Additional Resources
# Hands-On Demo
Source: https://docs.vantage.sh/vantage_university_demo
Interactive demo to practice using Vantage features in a real-world scenario.
This interactive demo brings together everything you've learned in Vantage University. Work through a realistic FinOps scenario to build a basic reporting structure for management using multiple Vantage features.
## Demo Scenario
You're the FinOps Analyst at TechFlow SaaS, a fast-growing company where cloud costs have been increasing. Leadership wants visibility into spending patterns and a clear view of where costs are going.
Build a comprehensive reporting structure for management that provides visibility into cloud spending, cost allocation, and optimization opportunities.
Build an Executive Dashboard using Cost Reports, Virtual Tags, and Resource Reports to provide complete visibility for leadership decision-making.
***
## Demo Walkthrough
Follow along with this step-by-step walkthrough. Each step includes an interactive demo to practice the concepts.
For the most seamless experience in this interactive demo, we recommend using a desktop or laptop device. Some features and embedded demos may not display or function properly on mobile devices.
### Step 1: Create Your First Cost Report
Start by creating a basic Cost Report to understand your overall cloud spending. Create a Cost Report that shows costs by provider for the past month, displayed as a pie chart.
***
### Step 2: Set Up Cost Allocation with Virtual Tags
This section includes two parts. First, you'll create a virtual tag to allocate costs back to different operating divisions. After you complete the tag creation, you can continue directly in the demo to create a Cost Report filtered by that division tag. This will help you understand how costs are distributed across your organization.
**Additional Cost Reports to Consider:** While you won't create these in the demo, consider building these reports for your executive dashboard:
* **3-month forecast:** A forecast report showing predicted costs for the next 3 months
* **6-month forecast:** A longer-term forecast for strategic planning
* **Provider-specific reports:** Create detailed reports for providers like AWS or Azure costs grouped by region to identify geographic spending patterns
**Default Reports Available:** Vantage also provides default reports that you can add to your dashboard for other features:
* **All Kubernetes Efficiency Metrics:** The default Kubernetes efficiency report that provides a comprehensive view of all Kubernetes efficiency metrics. See the [Kubernetes documentation](/kubernetes) for more information.
* **All AWS Financial Commitments:** The default financial commitment report that tracks all AWS Reserved Instances, Savings Plans, and other financial commitments. See the [Financial Commitment Reports documentation](/financial_commitment_reports) for more information.
You can choose to add these reports to your final dashboard as well.
***
### Step 3: Create a Snowflake Resource Report
Analyze your Snowflake query costs by creating a Resource Report that shows the highest cost queries. This will help identify expensive queries that may need optimization.
***
### Step 4: Build Your Executive Dashboard
Bring everything together by creating an executive dashboard. Add all the reports you created throughout this demo to provide comprehensive visibility into your cloud spending, cost allocation, optimization opportunities, and financial commitments.
***
## What You Built
Through this demo, you've created a comprehensive reporting structure for management:
* **Cost Report by Provider and Suggestions for Other Reports** - Overall cloud spending visibility
* **Virtual Tag for Operating Division** - Cost allocation by business unit
* **Snowflake Resource Report** - Analysis of highest cost queries
* **Executive Dashboard** - Unified view combining all reports for leadership
This structure provides the foundation for ongoing FinOps practices and helps drive cost optimization initiatives.
***
## Related Lessons
This interactive demo incorporates concepts from multiple Vantage University lessons. Review the below lessons to deepen your understanding:
Learn how to create, filter, and customize Cost Reports.
Master virtual tags and nested tag hierarchies.
Analyze individual resource costs and network flows.
# Developer
Source: https://docs.vantage.sh/vantage_university_developer
Welcome to the Developer learning track on Vantage University!
## Lesson 1: Introduction to the Developer Track
## Lesson 2: Managing Resources
## Lesson 3: Optimizing Kubernetes Efficiency
## Lesson 4: Get Started with Vantage Developer Resources
Choose a path below. Replace placeholders with your own token and workspace, then run the commands or follow the setup.
Call the Vantage API to list workspaces. You need a [Vantage API token](/api/authentication) with Read scope.
```bash List workspaces theme={null}
curl --request GET \
--url https://api.vantage.sh/v2/workspaces \
--header 'accept: application/json' \
--header 'authorization: Bearer ACCESS_TOKEN'
```
Replace `ACCESS_TOKEN` with your token. The response includes workspace tokens for Terraform or more API calls.
Create a folder in Vantage with the Terraform provider. Set `VANTAGE_API_TOKEN` in your environment and replace `wrkspc_YOUR_WORKSPACE_TOKEN` with a workspace token.
```terraform main.tf theme={null}
terraform {
required_providers {
vantage = {
source = "vantage-sh/vantage"
}
}
}
provider "vantage" {}
resource "vantage_folder" "demo" {
title = "Demo Folder"
workspace_token = "wrkspc_YOUR_WORKSPACE_TOKEN"
}
```
Run `terraform init`, then `terraform plan`. Use `terraform apply` to create the folder.
Query costs and recommendations from your IDE in natural language. Install the Vantage MCP in Cursor (or another MCP client), then ask, "What are my top cost reports?" or "List open cost recommendations."
Same API and Terraform concepts, from your editor, in plain language.
***
### Additional Resources by Lesson
# Finance Manager
Source: https://docs.vantage.sh/vantage_university_finance_manager
Welcome to the Finance Manager learning track on Vantage University!
## Lesson 1: Introduction to the Finance Manager Track
## Lesson 2: Set Up Budget Visibility
## Lesson 3: Understanding the Cost of Your Business
## Lesson 4: Using the Vantage FinOps Agent
***
### Additional Resources by Lesson
# FinOps Analyst
Source: https://docs.vantage.sh/vantage_university_finops_analyst
Welcome to the FinOps Analyst learning track on Vantage University!
## Lesson 1: Introduction to the FinOps Analyst Track
## Lesson 2: Building Comprehensive Cloud Cost Visibility
## Lesson 3: Achieving 100% Cost Allocation
## Lesson 4: Detecting and Preventing Unusual Spending
***
### Additional Resources by Lesson
# Integrations
Source: https://docs.vantage.sh/vantage_university_integrations
Welcome to the Integrations learning track on Vantage University!
## What Are Vantage Integrations?
Vantage offers a number of native integrations to help you understand all your cloud costs. In addition to integrations within Vantage, you can connect [Custom Providers](/connecting_custom_providers) so that you can monitor costs across your entire tech stack. Vantage also offers app integrations, such as a connection with Jira, so that you can push Vantage alerts and issues directly to your team's native issue-tracking software.
## Integrations Use Cases
As a **DevOps Engineer**, you need to consolidate cost data from various cloud providers into a single platform for better visibility. You connect both AWS and GCP, which are your main cloud providers. You also want to view monitoring costs from **Datadog**, which you help to oversee, so you use the native Datadog integration in Vantage to view the total cost impact of your work. You also set up anomaly alerts on Datadog reports and send these alerts to Jira so that the team can triage and work on these issues as soon as they occur.
As a **FinOps Analyst**, you are very familiar with the FOCUS schema. You currently have a few of your major cloud providers connected to Vantage, but there are some other tools your organization uses that you would like to see displayed alongside those cloud providers. You convert cost and usage reports from these other providers to the FOCUS-based schema used on Vantage and use the Custom Providers feature to see costs for your organization's entire tech stack.
## Lesson 1: Creating Integrations in Vantage
## Lesson 2: Connecting Custom Providers
## Lesson 3: Creating Jira Issues in Vantage
## Additional Resources
# Observability
Source: https://docs.vantage.sh/vantage_university_observability
Welcome to the Observability learning track on Vantage University!
## What Is Observability?
Cloud cost observability is the practice of monitoring cloud spending to gain insights into resource usage, what's driving your costs, and opportunities to optimize. Vantage offers the following observability tools:
**Cost anomalies** in Vantage notify teams of excess costs and help engineers fix misconfigurations or other problems before they become very expensive.
Vantage analyzes your infrastructure as it evolves and changes and provides **cost recommendations** to lower your bill.
## Why Should I Use Observability Tools?
It's always better to know about something before it happens. Recommendations and anomaly alerts are tools that let you know about increasing costs. They provide a way for you to quickly act and implement cost-saving measures for your organization before costs get out of hand.
## Observability Tools Use Cases
You are a **site reliability engineer (SRE)** and you are responsible for monitoring Datadog logs. You create a Cost Report for Datadog costs and set up an anomaly alert that will let you know if Log Management costs get out of hand.
As a **platform engineer**, you are responsible for ensuring that Kubernetes clusters are properly configured with the right amount of resources to optimize performance and cost. You use Vantage Kubernetes rightsizing recommendations to see your current usage and notice many of your clusters are overprovisioned. You implement these recommendations to realize the potential monthly savings.
## Lesson 1: View Cost Anomalies and Alerts
## Lesson 2: View Cost Recommendations
## Additional Resources
# Per Resource Costs
Source: https://docs.vantage.sh/vantage_university_per_resource_costs
Welcome to the Per Resource Costs learning track on Vantage University!
## What Are Per Resource Costs?
Per resource costs refer to the expenses associated with individual cloud resources, including both direct costs and those incurred through network traffic. By analyzing data from Active Resources, Resource Reports, and Network Flow Reports, you can gain a detailed understanding of how each resource contributes to your overall cloud spending.
**Active Resources** provide an overview of all active resources (e.g., an active virtual machine) and their associated costs.
**Resource Reports** break down costs by specific resources, providing insights into cost distribution.
**Network Flow Reports** analyze the costs of network traffic associated with your resources.
## Why Should I Use Them?
Combining data from Active Resources, Resource Reports, and Network Flow Reports offers a complete picture of how each resource impacts your total expenses. This visibility helps in identifying major cost drivers and optimizing resource usage.
By pinpointing high-cost resources and inefficient network traffic, you can make informed decisions to optimize resource allocation and reduce unnecessary spending. Use rightsizing recommendations for EC2 instances and Kubernetes workloads to rightsize specific expensive resources.
## Per Resource Cost Use Cases
As a **cloud architect**, you can use these tools to ensure that your cloud infrastructure is designed efficiently. By analyzing Active Resources and Resource Reports, you identify underutilized or unused resources that could be downsized or terminated to save costs.
As a **DevOps engineer** managing a complex application with multiple microservices, Network Flow Reports help you detect that high cross-AZ traffic between microservices is leading to increased costs. You can then focus on optimizing network configurations, such as reducing cross-AZ traffic or implementing VPC endpoints, to lower costs while maintaining application performance.
## Lesson 1: Create Resource Reports
## Lesson 2: Understand Network Flow Reports
## Additional Resources
# Unit Costs
Source: https://docs.vantage.sh/vantage_university_unit_costs
Welcome to the Unit Costs learning track on Vantage University!
## What Are Unit Costs?
A **unit cost** is any metric that your business tracks, like users, requests, transactions, or customers. In Vantage, you can add unit costs as a visualization on Cost Reports to visualize your cloud infrastructure costs on a per unit basis.
A **business metric** is a unit of data from your business that's aggregated and combined with costs to produce a per unit cost—like cost per daily active user, cost per customer, or cost per million API requests. Business metrics can be solely related to business goals, like cost per user, or related to system metrics, like cost per API request.
## Why Should I Use Them?
Most organizations already have key performance indicators, or KPIs, as a part of their company's goals. They help to measure efficiency and provide a better context for why you may be experiencing cost spikes. For example, some spikes may be justified based on adding a new user or increasing your customer base. Tracking per unit costs helps to provide some details as to why costs are changing.
## Unit Costs Use Cases
You are a **financial analyst** at a SaaS company and use unit costs and business metrics to understand the cost per daily active user (DAU). By visualizing cloud infrastructure costs on a per unit basis, you can determine how changes in user activity impact overall costs. For example, if there's a spike in costs, you can correlate it with an increase in DAUs, justifying the expenditure and helping the company plan budgets more accurately.
As a **DevOps engineer**, you can use business metrics to track the cost per million API requests for a microservices-based application. By visualizing these costs, you can pinpoint which services are driving up expenses. If a particular microservice shows a disproportionate cost increase per API request, you can investigate performance tuning, resource optimization, or architectural changes to reduce costs and improve efficiency without compromising on service quality.
## Lesson 1: Understand Unit Costs and Business Metrics
## Lesson 2: Create Business Metrics
## Additional Resources
# VQL (Vantage Query Language)
Source: https://docs.vantage.sh/vql
Learn Vantage Query Language (VQL), a SQL-like language for filtering cloud cost data across providers for API and Terraform integrations.
The Vantage Query Language (VQL) is a SQL-like language for filtering cloud cost data. It includes a normalized schema across cloud providers and basic filter syntax for creating complex filters. VQL is available in the Vantage console, as part of the [Vantage API](/api), and within the [Vantage Terraform provider](/terraform).
* **Console:** On Cost, Kubernetes Efficiency, Financial Commitment, and Network Flow Reports, as well as [Virtual Tag](/tagging) filter configurations and [Saved Filters](/saved_filters), you can view and [edit VQL directly](/vql#edit-vql-in-the-console) in the filter builder. On Resource Reports, you can view and copy VQL.
* **API:** On supported endpoints, such as `/cost_reports`, `/resource_reports`, `/financial_commitment_reports`, `/kubernetes_efficiency_reports`, `/network_flow_log_reports`, `/virtual_tag_configs`, and `/saved_filters`, you can use VQL in filter fields.
* **Terraform provider:** In supported resources, such as `vantage_cost_report`, `vantage_saved_filter`, and `vantage_virtual_tag_config`, you can use VQL in filter arguments.
## Edit VQL in the Console
On supported reports and filter configurations, you can edit VQL directly within the Vantage console. This allows you to modify filter logic as code, making it faster to adjust complex filters, reuse queries across reports and Virtual Tags, and iterate on cost analysis without rebuilding filters from scratch.
Navigate to a supported report, such as a [Cost Report](/cost_reports), a [Virtual Tag](/tagging) filter configuration, or a [Saved Filter](/saved_filters).
Open the **Filters** menu. Create a filter or view an existing one.
At the top of the **Filters** menu, click **View as VQL** to see the current filter represented in VQL.
Click **Edit VQL**. The VQL text becomes editable.
Modify the VQL query as needed. You can adjust filter conditions, add or remove criteria, or paste in VQL from another source, such as a different report or a Terraform configuration.
Click **Apply**. Vantage validates the query and updates the filter configuration. If the VQL contains errors, an error message is displayed, and the filter is not updated until the query is corrected.
You can also use the VQL view to copy filter logic between different parts of Vantage. For example, copy VQL from a Cost Report and paste it into a Virtual Tag filter configuration to reuse the same filter criteria.
You can switch between the visual filter builder and the VQL editor at any time. Changes made in one view are reflected in the other.
To edit VQL in reports, you need editor or higher permissions and access to the report. To edit VQL in Virtual Tags, you must have the Organization Owner role.
The below example shows how to use VQL on both the API and the Terraform provider. This example creates a [saved filter](/cost_reports#saved-filters) in your Vantage account using VQL.
```bash theme={null}
curl --request POST \
--url https://api.vantage.sh/v2/saved_filters \
--header 'content-type: application/json' \
--header 'authorization: Bearer ' \
--data @- <
```terraform theme={null}
resource "vantage_saved_filter" "rds_cloud_sql" {
title = "RDS and Cloud SQL"
filter = "(costs.provider = 'aws' AND costs.service = 'Amazon Relational Database Service') OR (costs.provider = 'gcp' AND costs.service = 'Cloud SQL')"
workspace_token = "wrkspc_abcde1234"
}
```
## Key Concepts
VQL is based on the following key concepts, further described in subsequent sections.
VQL uses a schema that organizes filters into namespaces. These namespaces comprise various fields that you can leverage to filter and retrieve specific cost-related data.
VQL includes keywords, like `AND`, `OR`, `IN`, `LIKE`, and `NOT`, to create complex and precise filter conditions. These keywords vary per report type/scope.
VQL syntax closely resembles the `WHERE` clause of a SQL query. You can construct filter operations to extract desired cost insights.
## Scopes
VQL has a separate scope for each type of report—meaning that you cannot use Cost Reports VQL when querying Resource Reports. Virtual Tags and Saved Filters use the Cost Reports scope.
# VQL for Cost Reports
Source: https://docs.vantage.sh/vql_cost_report
Learn how to use VQL when querying Cost Reports in the API or using the Terraform Provider.
If you need help constructing a VQL query, navigate to a [**Cost Report**](https://console.vantage.sh/reporting) and open the **Filters** menu. Create a filter and click **View as VQL** at the top of the **Filters** menu to see a filter's VQL representation. You can also [edit VQL directly](/vql#edit-vql-in-the-console) and click **Apply** to update the filter.
Cost Reports, [Virtual Tags](/vql_virtual_tags), and [Saved Filters](/saved_filters) use the same Cost Reports VQL scope.
## Schema
VQL comprises two namespaces: `costs` and `tags`, which represent the available [filters](/cost_reports#filter-cost-reports) on Cost Reports in the Vantage console. Reference a filter as `namespace.field`, such as `costs.provider` or `tags.name`.
Availability of the fields listed below varies among different cloud providers. For a comprehensive list of available fields per provider, including the source billing field each one maps to, see the [Data Dictionary](/data_dictionary).
| Namespace | Field | Description | Example |
| - | - | - | - |
| `costs` | `provider` (optional) | Provider that generated the cost | [Filter across all providers](/vql_cost_report#filter-across-all-providers) or [combine providers](/vql_cost_report#combining-providers) |
| `costs` | `allocation` | Fraction of a cost allocated to the result | [Cost allocation](/vql_cost_report#cost-allocation) |
| `costs` | `region` | Provider region associated with the cost | [Regions](/vql_cost_report#costs-from-a-list-of-regions) |
| `costs` | `marketplace` | Whether an AWS cost is a Marketplace transaction | [Marketplace transactions](/vql_cost_report#get-marketplace-transactions) |
| `costs` | `account_id` | Resource account, project, or subscription identifier | [Account ID](/vql_cost_report#costs-by-account-id) |
| `costs` | `provider_account_id` | Billing account identifier | [Provider account ID](/vql_cost_report#costs-by-provider-account-id) |
| `costs` | `service` | Normalized provider service name | [Service](/vql_cost_report#per-resource-costs-and-costs-by-service) |
| `costs` | `category` | Normalized cost category | [Category](/vql_cost_report#costs-by-specific-category) |
| `costs` | `subcategory` | Provider-specific cost subcategory | [Subcategory](/vql_cost_report#costs-by-specific-subcategory) |
| `costs` | `resource_id` | Provider identifier for a resource | [Resource ID](/vql_cost_report#per-resource-costs-and-costs-by-service) |
| `costs` | `charge_type` | Normalized charge type, such as usage or credit | [Charge type](/vql_cost_report#cost-by-charge-type) |
| `costs` | `usage_unit` | Unit used to measure usage | [Usage unit](/vql_cost_report#filter-by-usage-unit) |
| `tags` | `name` | Provider or Virtual Tag key | [Tags](/vql_cost_report#filter-by-tag) |
| `tags` | `value` | Value associated with a tag key | [Untagged costs](/vql_cost_report#filter-for-untagged-resources) |
`costs.provider` is optional. Omit it to filter across every connected provider in a single query—see [Filter Across All Providers](/vql_cost_report#filter-across-all-providers). Provider-specific fields (such as AWS `costs.marketplace`) only apply when `costs.provider` is included for that provider.
## Keywords
VQL includes a set of keywords to create complex filter conditions. These keywords function similar to their SQL equivalents.
| Keyword | Description | VQL Sample | Explanation |
| - | - | - | - |
| `AND` | Logical AND operator | `costs.provider = 'aws' AND costs.service = 'Amazon Elastic Compute Cloud - Compute'` | This example filters AWS costs for the Amazon Elastic Compute Cloud - Compute service, where both conditions must be true. |
| `OR` | Logical OR operator | `costs.provider = 'azure' OR costs.provider = 'aws'` | This example retrieves costs from either Azure or AWS. At least one condition must be true. |
| `IN` | Used to compare against an array list | `costs.provider = 'azure' AND costs.account_id IN ('account-1', 'account-2')` | This example filters based on a list of account IDs, returning data for the specified accounts.
You can also use `IN` along with a special syntax for filtering by multiple tags. See [Filter by Multiple Tags](/vql_cost_report#filter-by-multiple-tags) for details.
`costs.provider IN (...)` is supported and is expanded into one filter set per provider. `costs.provider NOT IN (...)` is not supported. |
| `LIKE` | Performs string comparisons | `costs.provider = 'gcp' AND tags.name = 'environment' AND tags.value LIKE '%prod%'` | This example selects data where the tag value contains `prod`, such as `production-1`. |
| `NOT` | Represents negation | `costs.provider = 'aws' AND costs.region NOT IN ('us-east-1', 'us-east-2')` | This example filters out data from both specified regions, providing all AWS costs *not* in these regions. Use `NOT IN` to specify a list of single or multiple values.
You can also use the `!=` or `<>` operators for "is not."
`costs.provider = 'aws' AND costs.region != 'us-east-1'`
You can use `NOT LIKE` to perform string comparisons:
`costs.provider = 'gcp' AND tags.name = 'environment' AND tags.value NOT LIKE '%prod%'` |
| `~*` | Flexible match operator for tag values | `costs.provider = 'aws' AND (tags.name = 'teams' AND tags.value ~* 'Team A')` | Searches for all items where the tag value loosely matches `Team A`, ignoring case, whitespace, hyphens, and punctuation. |
| `!~*` | Negated flexible match operator for tag values | `costs.provider = 'aws' AND (tags.name = 'teams' AND tags.value !~* 'Team A')` | Filters out all items where the tag value loosely matches `Team A`, ignoring case, whitespace, hyphens, and punctuation. |
With these keywords, you can construct complex filter conditions in VQL, providing flexibility and precision when querying and analyzing cloud cost data.
## Syntax
You can think of VQL in its current iteration as the `WHERE` clause of a SQL query. By combining the schema and keywords above with parentheses, you can form complex filter operations, such as:
```vql theme={null}
(costs.provider = 'mongo' AND costs.allocation = 1.0 AND (costs.service = 'REALM' AND costs.resource_id IN ('s3'))) OR (costs.provider = 'aws' AND costs.allocation = 1.0 AND costs.account_id IN ('123456789012'))
```
## Examples
The following examples cover common use cases for VQL.
### Filter Across All Providers
You can omit `costs.provider` to filter across every connected provider in a single query. This is useful for multi-cloud questions where the same filter logic should apply regardless of where the cost was incurred—for example, finding all costs tagged with a specific team across AWS, Azure, GCP, and any other connected providers.
```sql theme={null}
tags.name = 'Team' AND tags.value = 'Data Engineering'
```
The query above returns costs from every connected provider that has a matching tag, without you having to repeat the filter for each one. The same pattern works for any field in the [Cost Reports VQL schema](#schema).
You can still include `costs.provider` when you want to scope a filter to a single provider; this feature only removes the requirement to do so. Provider-specific fields (such as AWS-only `costs.marketplace`) still need `costs.provider` to be set for that provider.
An entirely empty filter (no rules at all) is also valid VQL and is equivalent to filtering across every connected provider with no constraints. This is the representation used for the default unfiltered All Resources Cost Report and for any other report whose filter set spans all providers with no rules applied. If you click **View as VQL** on such a report, the query string will be empty.
Filtering across all providers queries data from every connected provider, which is more work than filtering by a single provider. The impact is most pronounced on tag-heavy queries and Virtual Tag rules. For guidance on scoping providerless filters efficiently, including granular filters, exact-match operators, and when to prefer per-provider `OR` over a fully providerless query, see [Best Practices for Filtering Across All Providers](/tagging#best-practices-for-filtering-across-all-providers) in the Tagging documentation.
### Combining Providers
To reference a [Custom Provider](/connecting_custom_providers) in VQL queries, navigate to the [**Integrations** page](https://console.vantage.sh/settings/custom_providers). Use the displayed **Provider ID** (e.g., `custom_provider:accss_crdntl_123a45bfdaf38765`).
Filter for provider costs associated with either MongoDB Atlas or AWS.
```sql theme={null}
costs.provider = 'mongo' OR costs.provider = 'aws'
```
### Cost Allocation
Set cost allocation to `0.5`.
```sql theme={null}
costs.provider = 'gcp' AND costs.allocation = 0.5
```
### Costs from a List of Regions
Filter for Snowflake costs in two regions. Note that you will need to use the region code, such as `us-east-1` in the case of AWS, or `AWS_US_EAST_1` in the case of Snowflake, below.
```sql theme={null}
costs.provider = 'snowflake' AND costs.region IN ('AWS_US_EAST_1', 'AWS_US_EAST_2')
```
### Get Marketplace Transactions
Retrieve costs associated with the AWS Marketplace.
```sql theme={null}
costs.provider = 'aws' AND costs.marketplace = true
```
### Costs by Account ID
Costs for a specific set of services and account ID.
```sql theme={null}
costs.provider = 'aws' AND costs.account_id = '123456758' AND costs.service IN ('Amazon Relational Database', 'Amazon Elastic Compute Cloud - Compute')
```
### Costs by Provider Account ID
The following example represents costs from a specific AWS billing account or costs from a specific Azure subscription.
```sql theme={null}
(costs.provider = 'aws' AND costs.provider_account_id = 'abcd1234') OR (costs.provider = 'azure' AND costs.provider_account_id = 'abcd1234')
```
### Per-Resource Costs and Costs by Service
Resource costs require both `provider` and `service` in addition to the `resource_id`.
```sql theme={null}
costs.provider = 'aws' AND costs.service = 'Amazon Relational Database Service' AND costs.resource_id = 'arn:aws:rds:us-east-1:123456789:db:primary-01'
```
#### Multiple Resource IDs
```sql theme={null}
costs.provider = 'aws' AND costs.service = 'Amazon Relational Database Service' AND costs.resource_id IN ('arn:aws:rds:us-east-1:123456789:db:primary-01', 'arn:aws:rds:us-east-1:123456789:db:primary-02')
```
### Costs by Specific Category
Filter costs to see a specific cost category. Category costs require `provider`, `service`, and `category`. To filter across all services, use `costs.service = '*'` as a wildcard.
```sql theme={null}
costs.provider = 'fastly' AND costs.service = 'CDN' AND costs.category = 'Data Transfer'
```
Filter by category across all services for a provider:
```sql theme={null}
costs.provider = 'aws' AND costs.service = '*' AND costs.category = 'Data Transfer'
```
### Costs by Specific Subcategory
Filter costs by a specific service and subcategory. Subcategory costs require `provider`, `service`, and `subcategory`. To filter across all services, use `costs.service = '*'` as a wildcard.
```sql theme={null}
costs.provider = 'aws' AND costs.service = 'AWS Certificate Manager' AND costs.subcategory = 'USE1-PaidPrivateCA'
```
Filter by subcategory across all services for a provider:
```sql theme={null}
costs.provider = 'aws' AND costs.service = '*' AND costs.subcategory = 'DataTransfer-Out-Bytes'
```
### Cost by Charge Type
Filter costs by a specific charge type.
```sql theme={null}
costs.provider = 'aws' AND costs.charge_type = 'Usage'
```
### Filter by Usage Unit
Filter AWS costs to include only usage measured in hours.
```sql theme={null}
costs.provider = 'aws' AND costs.usage_unit = 'Hours'
```
You can omit `costs.provider` to apply the Usage Unit filter across every connected provider, or use `IN` to match multiple units.
The Vantage console normalizes Usage Unit labels for display, but VQL matches the underlying value exactly. Build the filter in the console and click **View as VQL** to copy the correct value when a displayed label differs from the provider's stored value. See [Understand Usage Units](/usage_based_reporting#understand-usage-units) and the [Data Dictionary](/data_dictionary#usage-unit) for more information.
### Filter by Tag
#### Filter by Single Tag
Filter costs based on a specific tag, such as `environment`, with the value `production`, in AWS.
```sql theme={null}
costs.provider = 'aws' AND tags.name = 'environment' AND tags.value = 'production'
```
#### Filter for Multiple Values from a Single Tag Key
If you want to filter for multiple tag values that are tied to one tag key (e.g., costs tagged with the `team` tag of `mobile` and `data`), use the below syntax.
```sql theme={null}
costs.provider = 'aws' AND tags.name = 'team' AND tags.value IN ('mobile', 'data')
```
#### Filter by Multiple Tags
If you want to filter for resources that have more than one tag associated, you can use the syntax shown in the example below.
```sql theme={null}
costs.provider = 'aws' AND (tags.name, tags.value) IN (('environment', 'staging'), ('team', 'engineering'))
```
This example filters for resources that are tagged with the `environment` tag with a value of `staging` as well as the `team` tag with a value of `engineering`. This filter is the same as creating the following manual filter in the console.

#### Filter for Matching Tags Using `LIKE`
```sql theme={null}
costs.provider = 'azure' AND (tags.name = 'environment' AND tags.value LIKE '%prod%')
```
#### Filter for Tags Using Flexible Matching
```sql theme={null}
costs.provider = 'azure' AND (tags.name = 'Team' AND tags.value ~* 'Team A')
```
Matches on applied tag values, such as `TeamA`, `team-a`, and `team_a` to a single `Team A` tag value. See the [Flexible Match](/cost_reports#flexible-match) documentation for details.
### Filter for Untagged Resources
On providers that have a **Not Tagged**/**Not Labeled** filter option in the console, you can use the below VQL to see untagged resources across every connected provider.
```sql theme={null}
tags.name = NULL
```
If you only want to check a specific subset of providers, list them explicitly with `OR`:
```sql theme={null}
(costs.provider = 'aws' AND tags.name = NULL) OR (costs.provider = 'azure' AND tags.name = NULL) OR (costs.provider = 'gcp' AND tags.name = NULL)
```
### Real-World Examples
Find production database costs across AWS and GCP:
```sql theme={null}
(costs.provider = 'aws' AND costs.service = 'Amazon Relational Database Service' AND tags.name = 'environment' AND tags.value = 'production') OR (costs.provider = 'gcp' AND costs.service = 'Cloud SQL' AND tags.name = 'environment' AND tags.value = 'production')
```
Find usage charges for the platform team in two AWS regions:
```sql theme={null}
costs.provider = 'aws' AND costs.charge_type = 'Usage' AND costs.region IN ('us-east-1', 'us-west-2') AND tags.name = 'team' AND tags.value = 'platform'
```
## Troubleshooting
If you are receiving an error when trying to complete a query, check the following troubleshooting tips.
* Each provider exposes certain names to the API. Those names are normalized within the schema. Check the [Data Dictionary](/data_dictionary) for normalized field names.
* Query parameter values should be wrapped in single quotes.
**THIS WORKS**
```sql theme={null}
costs.provider='aws'
```
**THIS DOES NOT WORK**
```sql theme={null}
costs.provider="aws"
```
* Currently, there is a limitation where `AND` and `OR` are not supported together in a single "query group."
**THIS WORKS**
```sql theme={null}
(costs.provider = 'aws' AND tags.name = 'environment' AND tags.value = 'dev') OR (costs.provider = 'aws' AND tags.name = 'environment' AND tags.value = 'prod')
```
**THIS DOES NOT WORK**
```sql theme={null}
costs.provider = 'aws' AND ((tags.name = 'environment' AND tags.value = 'dev') OR (tags.name = 'environment' AND tags.value = 'prod'))
```
* The `costs.provider` field is optional. Omit it to filter across every connected provider in a single query, or include it to scope the filter to a specific provider. See [Filter Across All Providers](/vql_cost_report#filter-across-all-providers) for details and performance considerations.
**BOTH WORK**
Filter across every connected provider:
```sql theme={null}
costs.service = 'CDN'
```
Filter for a specific provider:
```sql theme={null}
costs.provider = 'fastly' AND costs.service = 'CDN'
```
* Provider-specific fields only apply when `costs.provider` is set for that provider. For example, AWS exposes `costs.marketplace`, but it has no effect when used without an AWS provider scope.
**THIS WORKS**
```sql theme={null}
costs.provider = 'aws' AND costs.marketplace = true
```
**THIS DOES NOT WORK**
```sql theme={null}
costs.marketplace = true
```
`costs.marketplace` is only meaningful for AWS, so it must be paired with `costs.provider = 'aws'`.
* The `costs.provider` field supports `IN` (which is expanded into one filter set per provider), but does not support `NOT IN`.
**THIS WORKS**
```sql theme={null}
costs.provider IN ('aws', 'azure')
```
Vantage expands `costs.provider IN ('aws', 'azure')` into the equivalent of two filter sets, one per provider. You can also combine `IN` on `costs.provider` with provider-specific filters using `OR`:
```sql theme={null}
(costs.provider = 'aws' AND costs.account_id IN ('123456789', '987654321')) OR (costs.provider = 'azure' AND costs.account_id IN ('account-1', 'account-2'))
```
**THIS DOES NOT WORK**
```sql theme={null}
costs.provider NOT IN ('aws', 'azure')
```
* Resource costs require both provider and service in addition to the resource ID.
**THIS WORKS**
```sql theme={null}
costs.provider = 'aws' AND costs.service = 'Amazon Relational Database Service' AND costs.resource_id = 'arn:aws:rds:us-east-1:123456789:db:primary-01'
```
**THIS DOES NOT WORK**
```sql theme={null}
costs.provider = 'aws' AND costs.resource_id = 'arn:aws:rds:us-east-1:123456789:db:primary-01'
```
* Category and subcategory costs also require provider and service. To filter across all services, use `costs.service = '*'` as a wildcard.
**THESE WORK**
```sql theme={null}
costs.provider = 'fastly' AND costs.service = 'CDN' AND costs.category = 'Data Transfer'
```
```sql theme={null}
costs.provider = 'aws' AND costs.service = 'AWS Certificate Manager' AND costs.subcategory = 'USE1-PaidPrivateCA'
```
```sql theme={null}
costs.provider = 'aws' AND costs.service = '*' AND costs.category = 'Data Transfer'
```
**THESE DO NOT WORK**
```sql theme={null}
costs.provider = 'fastly' AND costs.category = 'Data Transfer'
```
```sql theme={null}
costs.provider = 'aws' AND costs.subcategory = 'USE1-PaidPrivateCA'
```
# VQL for Financial Commitment Reports
Source: https://docs.vantage.sh/vql_financial_commitment_report
Learn how to use VQL when querying Financial Commitment Reports in the API or using the Terraform Provider.
If you need help constructing a VQL query, navigate to the [**Financial Commitment Reports**](https://console.vantage.sh/financial_planning/financial_commitment_reports) page and click **New Report**. From the top left, open the **Filters** menu. Create a filter and click the **View as VQL** button at the top of the **Filters** menu to see a filter's VQL representation. You can copy this syntax to use within your API calls. You can also [edit VQL directly](/vql#edit-vql-in-the-console) and click **Apply** to update the filter.
## Financial Commitment Reports VQL Schema
VQL for Financial Commitment Reports comprises one namespace, `financial_commitments`, which represents the available [filters](/financial_commitment_reports#create-a-financial-commitment-report) on Financial Commitment Reports in the Vantage console. To reference a filter, use the following syntax: `namespace.field` (e.g., `financial_commitments.service`). The following fields are available within the `financial_commitments` namespace.
| Namespace | Field | Description | VQL Example |
| - | - | - | - |
| `financial_commitments` | `provider` | Cloud provider. Include `provider = 'aws'` at the start of each statement | [Syntax](/vql_financial_commitment_report#syntax) |
| `financial_commitments` | `service` | Provider service name | [Service example](/vql_financial_commitment_report#financial-commitments-by-service) |
| `financial_commitments` | `resource_account_id` | Account that used the commitment | [Account example](/vql_financial_commitment_report#financial-commitments-by-specific-account) |
| `financial_commitments` | `provider_account_id` | Billing account identifier | [Billing Account example](/vql_financial_commitment_report#financial-commitments-by-specific-billing-account) |
| `financial_commitments` | `commitment_type` | Type of financial commitment | [Commitment Type example](/vql_financial_commitment_report#see-specific-commitment-types) |
| `financial_commitments` | `commitment_id` | Commitment identifier, such as an ARN | [Commitment ARN example](/vql_financial_commitment_report#financial-commitments-by-commitment-arn) |
| `financial_commitments` | `cost_type` | Charge type, such as Usage | [Charge Type example](/vql_financial_commitment_report#financial-commitments-by-charge-type) |
| `financial_commitments` | `cost_category` | Cost category | [Category example](/vql_financial_commitment_report#financial-commitments-by-category) |
| `financial_commitments` | `cost_sub_category` | Provider-specific cost subcategory | [Subcategory example](/vql_financial_commitment_report#financial-commitments-by-subcategory) |
| `financial_commitments` | `instance_type` | Instance type covered by the commitment | [Instance Type example](/vql_financial_commitment_report#financial-commitments-by-instance-types) |
| `financial_commitments` | `region` | Provider region | [Region example](/vql_financial_commitment_report#financial-commitments-by-region) |
| `financial_commitments` | `resource_tags` | Resource tag key and value, selected with `->>` | [Tags example](/vql_financial_commitment_report#financial-commitments-by-tags) |
### Keywords
VQL includes a set of keywords to create complex filter conditions. These keywords function similar to their SQL equivalents. Note that each expression starts with `provider = 'aws'`, followed by additional filters.
| Keyword | Description | VQL Sample | Explanation |
| - | - | - | - |
| `AND` | Logical AND operator | `(financial_commitments.provider = 'aws' AND (financial_commitments.resource_tags->>'business-metric' = 'us-east-1a') AND (financial_commitments.cost_category = 'Alarm'))` | This example filters for a specific tag and category, where both conditions must be true. |
| `OR` | Logical OR operator | `(financial_commitments.provider = 'aws' AND ((financial_commitments.resource_tags->>'business-metric' = 'us-east-1a') OR (financial_commitments.resource_tags->>'business-metric' = 'us-east-1b')))` | This example looks for results where the `business-metric` tag has a value of either `us-east-1a` or `us-east-1b`. At least one condition must be true. |
| `!=` | Is not | `(financial_commitments.provider = 'aws' AND (financial_commitments.cost_type != 'Credit'))` | This example looks for results that are any charge type except for `Credit`. |
| `IN` and `NOT IN` | Used to compare against an array/list | `(financial_commitments.provider = 'aws' AND (financial_commitments.resource_tags->>'business-metric' IN ('us-east-1a','us-east-1b','us-east-1c')))` | This example searches for results with the `business-metric` tag key and multiple values.
This same query also works for `NOT IN` where the results are anything matching the tag key except for those particular values: `(financial_commitments.provider = 'aws' AND (financial_commitments.resource_tags->>'business-metric' NOT IN ('us-east-1a','us-east-1b','us-east-1c')))`. |
| `LIKE` and `NOT LIKE` | Performs string comparisons | `(financial_commitments.provider = 'aws' AND (financial_commitments.commitment_id LIKE '%arn:aws:ec2%'))` | This example selects data where the commitment ARN value contains `arn:aws:ec2`, such as `arn:aws:ec2:us-west-2:1234`.
This same query also works for `NOT LIKE` where data does not contain a particular string: `(financial_commitments.provider = 'aws' AND (financial_commitments.commitment_id NOT LIKE '%arn:aws:ec2%'))`. |
| `->>` | This operator is used only when constructing queries related to tags | `(financial_commitments.provider = 'aws' AND (financial_commitments.resource_tags->>'environment' = 'staging'))` | This example looks for results with the tag name of `environment` and value of `staging`. |
With these operators and keywords, you can construct complex filter conditions in VQL.
## Syntax
VQL resembles the `WHERE` clause of a SQL query. Start every expression with the AWS provider condition:
```sql theme={null}
financial_commitments.provider = 'aws' AND financial_commitments.service = 'AmazonEC2' AND financial_commitments.region = 'us-east-1'
```
For `OR` queries, repeat the provider condition in every branch:
```sql theme={null}
(financial_commitments.provider = 'aws' AND financial_commitments.service = 'AmazonEC2') OR (financial_commitments.provider = 'aws' AND financial_commitments.service = 'AmazonRDS')
```
Use single quotes around string values.
## VQL Examples
The following examples cover common use cases for VQL.
### Financial Commitments by Service
Filter for multiple services.
```sql theme={null}
(financial_commitments.provider = 'aws' AND (financial_commitments.service IN ('AmazonAthena','AmazonCloudFront','AmazonECS')))
```
### Financial Commitments by Specific Account
Filter down to an individual account.
```sql theme={null}
(financial_commitments.provider = 'aws' AND (financial_commitments.resource_account_id = '123456789012'))
```
### Financial Commitments by Specific Billing Account
Filter down to an individual billing account.
```sql theme={null}
(financial_commitments.provider = 'aws' AND (financial_commitments.provider_account_id = '123456789012'))
```
### See Specific Commitment Types
Filter out certain commitment types to see everything else.
```sql theme={null}
(financial_commitments.provider = 'aws' AND (financial_commitments.commitment_type NOT IN ('credit','free')))
```
### Financial Commitments by Commitment ARN
See the impact of specific financial commitments related to EC2 by ARNs.
```sql theme={null}
(financial_commitments.provider = 'aws' AND (financial_commitments.commitment_id LIKE '%arn:aws:ec2%'))
```
### Financial Commitments by Charge Type
See only usage-related commitments.
```sql theme={null}
(financial_commitments.provider = 'aws' AND (financial_commitments.cost_type = 'Usage'))
```
### Financial Commitments by Category
All data transfer-related commitments.
```sql theme={null}
(financial_commitments.provider = 'aws' AND (financial_commitments.cost_category = 'Data Transfer'))
```
### Financial Commitments by Subcategory
Filter for Cloudfront and data transfer egress in APN2.
```sql theme={null}
(financial_commitments.provider = 'aws' AND (financial_commitments.cost_sub_category IN ('APN2-DataTransfer-Out-Bytes','APN2-CloudFront-Out-Bytes')))
```
### Financial Commitments by Instance Types
Filter from a list of different instance types.
```sql theme={null}
(financial_commitments.provider = 'aws' AND (financial_commitments.instance_type IN ('c7a.12xlarge','c7gn.large','c7gn.medium')))
```
### Financial Commitments by Region
See all financial commitments in `us-east-1`.
```sql theme={null}
(financial_commitments.provider = 'aws' AND (financial_commitments.region = 'us-east-1'))
```
### Financial Commitments by Tags
Filter based on a specific tag called `business-metric` and a list of provided values.
```sql theme={null}
(financial_commitments.provider = 'aws' AND (financial_commitments.resource_tags->>'business-metric' IN ('us-east-1a','us-east-1b','us-east-1c')))
```
### Multiple Filters
Complex filter that shows combining two different statements using `OR` with multiple criteria.
```sql theme={null}
((financial_commitments.provider = 'aws' AND (financial_commitments.resource_account_id = '123456789012') AND (financial_commitments.service = 'AmazonEC2')) OR (financial_commitments.provider = 'aws' AND (financial_commitments.resource_account_id = '098765432109') AND (financial_commitments.service = 'AmazonRDS')))
```
### Real-World Examples
Find EC2 usage commitments for an account in `us-east-1`:
```sql theme={null}
financial_commitments.provider = 'aws' AND financial_commitments.service = 'AmazonEC2' AND financial_commitments.resource_account_id = '123456789012' AND financial_commitments.cost_type = 'Usage' AND financial_commitments.region = 'us-east-1'
```
Find production commitments that are not credits:
```sql theme={null}
financial_commitments.provider = 'aws' AND financial_commitments.cost_type != 'Credit' AND financial_commitments.resource_tags->>'environment' = 'production'
```
## Troubleshooting
* Wrap string values in single quotes, not double quotes.
* Start every expression, including each `OR` branch, with `financial_commitments.provider = 'aws'`.
* Use `financial_commitments.resource_tags->>'KEY'` to filter a tag.
* Keep complete conditions together when mixing `AND` and `OR`; use parentheses to separate each branch.
# VQL for Kubernetes Efficiency Reports
Source: https://docs.vantage.sh/vql_kubernetes_efficiency_report
Learn how to use VQL when querying Kubernetes Efficiency Reports in the API or using the Terraform Provider.
If you need help constructing a VQL query, navigate to the [**Kubernetes Efficiency Reports**](https://console.vantage.sh/kubernetes/efficiency_reports) page and click **New Report**. From the top left, open the **Filters** menu. Create a filter and click the **View as VQL** button at the top of the **Filters** menu to see a filter's VQL representation. You can copy this syntax to use within your API calls. You can also [edit VQL directly](/vql#edit-vql-in-the-console) and click **Apply** to update the filter.
## Kubernetes Efficiency Reports VQL Schema
VQL for Kubernetes Efficiency Reports comprises one namespace, `kubernetes`, which represents the available [filters](/kubernetes#create-efficiency-reports) on Kubernetes Efficiency Reports in the Vantage console. To reference a filter, use the following syntax: `namespace.field` (e.g., `kubernetes.category`). The following fields are available within the `kubernetes` namespace.
| Namespace | Field | Description | VQL Example |
| - | - | - | - |
| `kubernetes` | `namespace` | Kubernetes namespace | [Namespace example](/vql_kubernetes_efficiency_report#multiple-namespaces) |
| `kubernetes` | `cluster_id` | Cluster identifier | [Cluster ID example](/vql_kubernetes_efficiency_report#results-from-a-list-of-clusters) |
| `kubernetes` | `category` | Efficiency category, such as cpu | [Category example](/vql_kubernetes_efficiency_report#costs-by-category) |
| `kubernetes` | `labels` | Kubernetes label key and value, selected with `->>` | [Labels example](/vql_kubernetes_efficiency_report#filter-by-label) |
| `kubernetes` | `pod` | Pod name | [Pod example](/vql_kubernetes_efficiency_report#filter-by-pod) |
| `kubernetes` | `region` | Cluster region | [Region example](/vql_kubernetes_efficiency_report#filter-by-region) |
### Keywords
VQL includes a set of keywords to create complex filter conditions. These keywords function similar to their SQL equivalents.
| Keyword | Description | VQL Sample | Explanation |
| - | - | - | - |
| `AND` | Logical AND operator | `(kubernetes.namespace = 'kube-system') AND (kubernetes.labels->>'app' = 'vantage-agent')` | This example filters for a specific namespace and label, where both conditions must be true. |
| `OR` | Logical OR operator | `(kubernetes.namespace = 'gpu-operator') OR (kubernetes.namespace = 'vantage-dev')` | This example looks for results in two different namespaces. At least one condition must be true. |
| `!=` | Is not | `(kubernetes.cluster_id != 'dev-eks-gpu-0')` | This example looks for results that are in any cluster except for `dev-eks-gpu-0`. |
| `IN` and `NOT IN` | Used to compare against an array/list | `(kubernetes.labels->>'app.kubernetes.io/component' IN ('csi-driver','gpu-operator','metrics'))` | This example searches for results with the `app.kubernetes.io/component` key and multiple values.
This same query also works for `NOT IN` where the results are anything matching the label key except for those particular values: `(kubernetes.labels->>'app.kubernetes.io/component' NOT IN ('csi-driver','gpu-operator','metrics'))`. |
| `LIKE` and `NOT LIKE` | Performs string comparisons | `(kubernetes.labels->>'app' LIKE '%test%')` | This example selects data where the `app` label value contains `test`, such as `test-app`.
This same query also works for `NOT LIKE` where data does not contain a particular string: `(kubernetes.labels->>'app' NOT LIKE '%test%')`. |
| `->>` | This operator is used only when constructing queries related to labels | `(kubernetes.labels->>'container' = 'kube-prometheus-stack-48.4.0')` | This example looks for results with the label name of `container` and value of `kube-prometheus-stack-48.4.0`. |
With these operators and keywords, you can construct complex filter conditions in VQL.
## Syntax
VQL resembles the `WHERE` clause of a SQL query. Use `->>` to select a Kubernetes label:
```sql theme={null}
kubernetes.cluster_id IN ('production-1', 'production-2') AND kubernetes.namespace = 'payments' AND kubernetes.labels->>'app' = 'api'
```
Use single quotes around string values.
## VQL Examples
The following examples cover common use cases for VQL.
### Multiple Namespaces
Filter for one or the other namespace.
```sql theme={null}
(kubernetes.namespace = 'kube-system') OR (kubernetes.namespace = 'default')
```
### Results from a List of Clusters
Filter for a list of different clusters.
```sql theme={null}
(kubernetes.cluster_id IN ('dev-eks-gpu-0','dev-eks-UVmPe9YN'))
```
### Costs by Category
Costs for a specific category, like `cpu`.
```sql theme={null}
(kubernetes.category = 'cpu')
```
### Filter by Label
Filter based on a specific Kubernetes label, such as `app`, with the value `rollouts-demo`.
```sql theme={null}
(kubernetes.labels->>'app' = 'rollouts-demo')
```
### Filter by Pod
Filter for a specific pod.
```sql theme={null}
(kubernetes.pod = 'my-pod-name')
```
### Filter by Region
Filter for clusters in multiple regions.
```sql theme={null}
kubernetes.region IN ('us-east-1', 'us-west-2')
```
### Multiple Filters
Complex filter that shows combining two different statements using `OR` with multiple criteria.
```sql theme={null}
((kubernetes.cluster_id IN ('dev-eks-gpu-0','dev-eks-UVmPe9YN')) AND (kubernetes.category = 'cpu')) OR ((kubernetes.cluster_id IN ('dev-eks-gpu-0','dev-eks-UVmPe9YN')) AND (kubernetes.category = 'gpu'))
```
### Real-World Examples
Find CPU costs for production API workloads:
```sql theme={null}
kubernetes.cluster_id IN ('production-1', 'production-2') AND kubernetes.category = 'cpu' AND kubernetes.labels->>'app' = 'api'
```
Find platform workloads running outside the primary region:
```sql theme={null}
kubernetes.namespace = 'platform' AND kubernetes.region != 'us-east-1' AND kubernetes.labels->>'team' = 'platform'
```
## Troubleshooting
* Wrap string values in single quotes, not double quotes.
* Use `kubernetes.labels->>'KEY'` to filter a label; `kubernetes.labels.KEY` is not valid VQL.
* Keep complete conditions together when mixing `AND` and `OR`; use parentheses to separate each branch.
* Use the cluster, region, category, and label values shown by **View as VQL**.
# VQL for Network Flow Reports
Source: https://docs.vantage.sh/vql_network_flow_report
Learn how to use VQL when querying Network Flow Reports in the API or using the Terraform Provider.
If you need help constructing a VQL query, navigate to the [**Network Flow Reports**](https://console.vantage.sh/network_flow_log_reports) page and click **New Network Flow Report**. From the top left, open the **Filters** menu. Create a filter and click the **View as VQL** button at the top of the **Filters** menu to see a filter's VQL representation. You can copy this syntax to use within your API calls. You can also [edit VQL directly](/vql#edit-vql-in-the-console) and click **Apply** to update the filter.
## Network Flow Reports VQL Schema
VQL for Network Flow Reports comprises one namespace, `network_flow_logs`, which represents the available [filters](/network_flow_reports#filter-and-group-a-network-flow-report) on Network Flow Reports in the Vantage console. To reference a filter, use the following syntax: `namespace.field` (e.g., `network_flow_logs.account_id`). The following fields are available within the `network_flow_logs` namespace.
| Namespace | Field | Description | VQL Example |
| - | - | - | - |
| `network_flow_logs` | `account_id` | AWS account ID of the source network | [Account ID example](/vql_network_flow_report#network-flows-by-account-id) |
| `network_flow_logs` | `az_id` | ID of the source Availability Zone | [Availability Zone ID example](/vql_network_flow_report#network-flows-by-availability-zone-id) |
| `network_flow_logs` | `dstaddr` | Destination IP address | [Destination Address example](/vql_network_flow_report#network-flows-by-destination-address) |
| `network_flow_logs` | `dsthostname` | Domain name for the destination IP address | [Destination Hostname example](/vql_network_flow_report#network-flows-by-destination-hostname) |
| `network_flow_logs` | `interface_id` | Source ENI ID | [Interface ID example](/vql_network_flow_report#network-flows-by-interface-id) |
| `network_flow_logs` | `instance_id` | Source instance ID | [Instance ID example](/vql_network_flow_report#network-flows-by-instance-id) |
| `network_flow_logs` | `peer_resource_uuid` | Destination resource name, ARN, or tag | [Peer Resource UUID example](/vql_network_flow_report#network-flows-by-peer-resource-uuid) |
| `network_flow_logs` | `peer_account_id` | Destination account ID | [Peer Account ID example](/vql_network_flow_report#network-flows-by-peer-account-id) |
| `network_flow_logs` | `peer_vpc_id` | Destination VPC ID | [Peer VPC ID example](/vql_network_flow_report#network-flows-by-peer-vpc-id) |
| `network_flow_logs` | `peer_regions` | AWS Region of the destination | [Peer Regions example](/vql_network_flow_report#network-flows-by-peer-regions) |
| `network_flow_logs` | `peer_az_id` | ID of the destination Availability Zone | [Peer AZ ID example](/vql_network_flow_report#network-flows-by-peer-az-id) |
| `network_flow_logs` | `peer_subnet_id` | Destination subnet ID | [Peer Subnet ID example](/vql_network_flow_report#network-flows-by-peer-subnet-id) |
| `network_flow_logs` | `peer_interface_id` | Destination ENI ID | [Peer Interface ID example](/vql_network_flow_report#network-flows-by-peer-interface-id) |
| `network_flow_logs` | `peer_instance_id` | Destination instance ID | [Peer Instance ID example](/vql_network_flow_report#network-flows-by-peer-instance-id) |
| `network_flow_logs` | `region` | AWS Region of the source | [Region example](/vql_network_flow_report#network-flows-by-region) |
| `network_flow_logs` | `resource_uuid` | Source resource name, ARN, or tag | [Resource UUID example](/vql_network_flow_report#network-flows-by-resource-uuid) |
| `network_flow_logs` | `srcaddr` | Source IP address | [Source Address example](/vql_network_flow_report#network-flows-by-source-address) |
| `network_flow_logs` | `srchostname` | Domain name for the source IP address | [Source Hostname example](/vql_network_flow_report#network-flows-by-source-hostname) |
| `network_flow_logs` | `subnet_id` | ID of the source subnet | [Subnet ID example](/vql_network_flow_report#network-flows-by-subnet-id) |
| `network_flow_logs` | `traffic_category` | Type of traffic, such as cross-region or local | [Traffic Category example](/vql_network_flow_report#network-flows-by-traffic-category) |
| `network_flow_logs` | `traffic_path` | Path traffic takes to reach the destination | [Traffic Path example](/vql_network_flow_report#network-flows-by-traffic-path) |
| `network_flow_logs` | `vpc_id` | ID of the source VPC | [VPC ID example](/vql_network_flow_report#network-flows-by-vpc-id) |
### Keywords
VQL includes a set of keywords to create complex filter conditions. These keywords function similar to their SQL equivalents.
| Keyword | Description | VQL Sample | Explanation |
| - | - | - | - |
| `AND` | Logical AND operator | `(network_flow_logs.account_id = '123456789012') AND (network_flow_logs.dsthostname = 'datadoghq.com')` | This example filters for a specific account and destination hostname, where both conditions must be true. |
| `OR` | Logical OR operator | `((network_flow_logs.account_id = '123456789012') AND (network_flow_logs.dsthostname = 'datadoghq.com')) OR ((network_flow_logs.account_id = '09876543212') AND (network_flow_logs.dsthostname = 'github.com'))` | This example looks for results associated with two accounts and destination hostnames. At least one condition must be true. |
| `!=` | Is not | `(network_flow_logs.dsthostname != 'github.com')` | This example looks for results that are any destination hostname type except for `github.com`. |
| `IN` and `NOT IN` | Used to compare against an array/list | `(network_flow_logs.peer_regions IN ('us-east-1','us-west-2'))` | This example searches for results within a set of regions.
This same query also works for `NOT IN` where the results are anything matching everything except for these regions: `(network_flow_logs.peer_regions NOT IN ('us-east-1','us-west-2'))`. |
| `LIKE` and `NOT LIKE` | Performs string comparisons | `(network_flow_logs.az_id LIKE '%use1%')` | This example selects data where the Availability Zone contains `use1`, such as `use1-az1`.
This same query also works for `NOT LIKE` where data does not contain a particular string: `(network_flow_logs.az_id NOT LIKE '%use1%')`. |
With these operators and keywords, you can construct complex filter conditions in VQL.
## Syntax
VQL resembles the `WHERE` clause of a SQL query:
```sql theme={null}
network_flow_logs.account_id = '123456789012' AND network_flow_logs.region = 'us-east-1' AND network_flow_logs.dsthostname IN ('datadoghq.com', 'github.com')
```
Use single quotes around string values.
## VQL Examples
The following examples cover common use cases for VQL.
### Network Flows by Account ID
Network flows from a set of account IDs.
```sql theme={null}
(network_flow_logs.account_id IN ('123456789012','098765432109'))
```
### Network Flows by Availability Zone ID
Filter for a substring based on Availability Zone.
```sql theme={null}
(network_flow_logs.az_id LIKE '%use1%')
```
### Network Flows by Destination Address
All network flows that do not match a particular destination address.
```sql theme={null}
(network_flow_logs.dstaddr != '1.123.45.67')
```
### Network Flows by Destination Hostname
Network flows from a set of destination hostnames.
```sql theme={null}
(network_flow_logs.dsthostname IN ('datadoghq.com','github.com','sentry.io'))
```
### Network Flows by Interface ID
Network flows for a particular interface ID.
```sql theme={null}
(network_flow_logs.interface_id = 'eni-000012345a6789123')
```
### Network Flows by Instance ID
Network flows for a particular instance ID.
```sql theme={null}
(network_flow_logs.instance_id = 'i-0001a23b456c780c1')
```
### Network Flows by Peer Resource UUID
Network flows for peer resource UUIDs matching a substring.
```sql theme={null}
(network_flow_logs.peer_resource_uuid LIKE '%arn:aws:ec2%')
```
### Network Flows by Peer Account ID
Network flows for anything that's not a particular peer account ID.
```sql theme={null}
(network_flow_logs.peer_account_id != '123456789012')
```
### Network Flows by Peer VPC ID
Network flows for two different peer VPC IDs.
```sql theme={null}
(network_flow_logs.peer_vpc_id IN ('vpc-12345678','vpc-0987654'))
```
### Network Flows by Peer Regions
Network flows for anything outside a set of peer regions.
```sql theme={null}
(network_flow_logs.peer_regions NOT IN ('us-east-1','us-west-2'))
```
### Network Flows by Peer AZ ID
Network flows for a specific peer AZ.
```sql theme={null}
(network_flow_logs.peer_az_id = 'use1-az1')
```
### Network Flows by Peer Subnet ID
Network flows for any peer subnet IDs that do not contain a substring.
```sql theme={null}
(network_flow_logs.peer_subnet_id NOT LIKE '%subnet-022%')
```
### Network Flows by Peer Interface ID
Network flows based on a peer interface ID substring.
```sql theme={null}
(network_flow_logs.peer_interface_id LIKE 'eni-0a1b2c3d%')
```
### Network Flows by Peer Instance ID
Network flows excluding a particular peer instance ID.
```sql theme={null}
(network_flow_logs.peer_instance_id != 'i-0a1b2c3d4e5f67890')
```
### Network Flows by Region
Network flows in multiple regions.
```sql theme={null}
(network_flow_logs.region IN ('us-east-1', 'us-west-2', 'eu-central-1'))
```
### Network Flows by Resource UUID
Network flows for resources not matching a specific UUID substring.
```sql theme={null}
(network_flow_logs.resource_uuid NOT LIKE '123e4567%')
```
### Network Flows by Source Address
Network flows from a set of source addresses.
```sql theme={null}
(network_flow_logs.srcaddr IN ('192.168.1.1', '10.0.0.5', '172.16.0.10'))
```
### Network Flows by Source Hostname
Network flows excluding specific source hostnames.
```sql theme={null}
(network_flow_logs.srchostname NOT IN ('example.com', 'internal.service.local'))
```
### Network Flows by Subnet ID
Network flows for subnets with a specific prefix.
```sql theme={null}
(network_flow_logs.subnet_id LIKE 'subnet-0a1b%')
```
### Network Flows by Traffic Category
Only cross-region traffic.
```sql theme={null}
(network_flow_logs.traffic_category = 'cross-region')
```
### Network Flows by Traffic Path
Network flows for Inter-Region VPC Peering. Traffic paths have a specific key, as described below.
| Key | Traffic Path |
| - | - |
| 1 | In VPC |
| 2 | Internet Gateway or Gateway VPC Endpoint |
| 3 | Virtual Private Gateway |
| 4 | Intra-Region VPC Peering |
| 5 | Inter-Region VPC Peering |
| 6 | Local Gateway |
| 7 | Gateway VPC Endpoint (Nitro-based instances) |
| 8 | Internet Gateway (Nitro-based instances) |
```sql theme={null}
(network_flow_logs.traffic_path = '5')
```
### Network Flows by VPC ID
Everything except for a specific VPC.
```sql theme={null}
(network_flow_logs.vpc_id != 'vpc-12c12345a12345678')
```
### Multiple Filters
Complex filter that shows combining two different statements using `OR` with multiple criteria.
```sql theme={null}
((network_flow_logs.dsthostname = 'datadoghq.com') AND (network_flow_logs.account_id = '123456789012')) OR ((network_flow_logs.dsthostname = 'github.com') AND (network_flow_logs.account_id = '098765432109'))
```
### Real-World Examples
Find cross-region traffic from a production account:
```sql theme={null}
network_flow_logs.account_id = '123456789012' AND network_flow_logs.traffic_category = 'cross-region' AND network_flow_logs.region = 'us-east-1'
```
Find internet traffic to common observability services:
```sql theme={null}
network_flow_logs.traffic_path IN ('2', '8') AND network_flow_logs.dsthostname IN ('datadoghq.com', 'sentry.io')
```
## Troubleshooting
* Wrap string values in single quotes, not double quotes.
* Use the IDs and normalized values shown by **View as VQL**.
* Keep complete conditions together when mixing `AND` and `OR`; use parentheses to separate each branch.
* `traffic_path` is stored as a string, so wrap its numeric-looking value in single quotes.
# VQL for Resource Reports
Source: https://docs.vantage.sh/vql_resource_report
Learn how to use VQL when querying Resource Reports in the API or using the Terraform Provider.
If you need help constructing a VQL query, navigate to the [**Resource Reports**](https://console.vantage.sh/resources) page and click **New Resource Report**. From the top left, open the **Filters** menu. Create a filter and click the **View as VQL** button at the top of the **Filters** menu to see a filter's VQL representation. You can copy this syntax to use within your API calls.
## Resource Reports VQL Schema
VQL for Resource Reports comprises two namespaces: `resources` and `tags`, which represent the available [filters](/active_resources#create-a-resource-report) on Resource Reports in the Vantage console. To reference a filter, use the following syntax: `namespace.field` (e.g., `resources.region` or `tags.name`). The following fields are available within these namespaces.
| Namespace | Field | Description | VQL Example |
| - | - | - | - |
| `resources` | `provider` | Cloud provider | [Providers example](/vql_resource_report#combining-providers) |
| `resources` | `region` | Provider region | [Region example](/vql_resource_report#resources-from-a-list-of-regions) |
| `resources` | `account_id` | Resource account, project, or subscription identifier | [Account example](/vql_resource_report#resources-by-account-id) |
| `resources` | `provider_account_id` | Billing account identifier | [Billing Account example](/vql_resource_report#resources-by-billing-account) |
| `resources` | `type` | Resource type | [Resource Type example](/vql_resource_report#resources-by-resource-type) |
| `resources` | `label` | Resource name or label | [Label example](/vql_resource_report#resources-by-label) |
| `resources` | `uuid` | Resource UUID, or ARN on AWS | [UUID (AWS ARN) example](/vql_resource_report#resources-for-specific-arn) |
| `resources` | `metadata` | Provider metadata for the resource type, selected with `->>` | [Metadata example](/vql_resource_report#resources-by-metadata) |
| `tags` | `name` | Tag key | [Tags name/value example](/vql_resource_report#filter-by-tag) |
| `tags` | `value` | Value associated with a tag key | [Untagged example](/vql_resource_report#filter-for-untagged-resources) |
Availability of the fields listed above varies among different cloud providers. See the [Resource Reports documentation](/active_resources#resource-report-filters) for a full list of filter fields available per provider.
The VQL `tags.name` and `tags.value` fields above are **filter** fields used inside the `filter` parameter when [creating](https://docs.vantage.sh/api/resourcereports/create-resource-report) or [updating](https://docs.vantage.sh/api/resourcereports/update-resource-report) a Resource Report via the API, or in the `filter` attribute on the [`vantage_resource_report`](/terraform_docs/resources/resource_report) Terraform resource.
These are distinct from the `tags.KEY` strings (for example, `tags.environment`) used inside the `columns` array on the same API endpoints and Terraform resource. Those are column identifiers for adding tag values as dedicated columns in a Resource Report, not VQL. See [Add Tag Columns](/active_resources#add-tag-columns) for details.
### Keywords
VQL includes a set of keywords to create complex filter conditions. These keywords function similar to their SQL equivalents.
| Keyword | Description | VQL Sample | Explanation |
| - | - | - | - |
| `AND` | Logical AND operator | `resources.provider = 'aws' AND resources.label = '123456'` | This example filters AWS resources, with a specific associated label, where both conditions must be true. |
| `OR` | Logical OR operator | `(resources.provider = 'aws') OR (resources.provider = 'gcp')` | This example retrieves resources from either AWS or GCP. At least one condition must be true. |
| `LIKE` and `NOT LIKE` | Performs string comparisons | `resources.provider = 'aws' AND resources.uuid LIKE '%arn:aws:s3:::my-bucket%'` | This example selects data where the resource ARN contains `arn:aws:s3:::my-bucket`, such as `arn:aws:s3:::my-bucket-123`.
This same query also works for `NOT LIKE` where data does not contain a particular string: `resources.provider = 'aws' AND resources.uuid NOT LIKE '%arn:aws:s3:::my-bucket%'`. |
| `IN`/`NOT IN` | Used to compare against an array list | `(resources.provider = 'aws' AND (resources.region IN ('ap-northeast-1','ap-northeast-3')))` | This example filters based on a list of regions, returning data for the specified regions.
You can also use `NOT IN` to find results that are anything but the items within the list: `(resources.provider = 'aws' AND (resources.region NOT IN ('ap-northeast-1','ap-northeast-3')))` |
| `!=` | Represents negation, "is not" | `resources.provider = 'azure' AND (resources.type != 'azurerm_public_ip' AND resources.type != 'azurerm_kubernetes_cluster')` | This example filters out data from two specified resource types, providing all Azure resources that are *not* these types. |
| `<`, `>`, `<=`, `>=` | Mathematical operators for numerical queries | `resources.provider = 'azure' AND (resources.type = 'azurerm_virtual_machine' AND resources.metadata->>'virtual_machine_size' > '7')` | This example looks for Virtual Machines that have a size greater than 7. |
| `->>` | This operator is used only when constructing queries related to metadata | `resources.provider = 'aws' AND (resources.type = 'aws_instance' AND resources.metadata->>'architecture' = 'x86_64')` | This example looks for EC2 instances with an architecture of `x86_64`. |
With these operators and keywords, you can construct complex filter conditions in VQL.
## Syntax
VQL resembles the `WHERE` clause of a SQL query. Metadata filters require a provider and resource type, and use `->>` to select a metadata key:
```sql theme={null}
resources.provider = 'aws' AND resources.type = 'aws_instance' AND resources.region IN ('us-east-1', 'us-west-2') AND resources.metadata->>'architecture' = 'x86_64'
```
Use single quotes around string values.
## VQL Examples
The following examples cover common use cases for VQL.
### Combining Providers
Filter for provider resources associated with either AWS or GCP.
```sql theme={null}
(resources.provider = 'aws') OR (resources.provider = 'gcp')
```
### Resources from a List of Regions
Filter for AWS resources in two regions. Note that you will need to use the region code, such as `us-east-1`.
```sql theme={null}
resources.provider = 'aws' AND (resources.region = 'us-east-1' OR resources.region = 'us-west-1')
```
### Resources by Account ID
Resources for a specific set of resource types and account ID.
```sql theme={null}
resources.provider = 'gcp' AND (resources.account_id = 'user-proj-1234') AND (resources.type = 'google_compute_disk' OR resources.type = 'google_compute_instance')
```
### Resources by Billing Account
Resources for a specific billing account.
```sql theme={null}
resources.provider = 'aws' AND (resources.provider_account_id = '111111111111')
```
### Resources by Resource Type
Filter resources to see a specific resource type. In the example below, the query is looking for any AWS resource that is *not* an AWS CloudFront Distribution. Resource types are represented like `aws_cloudfront_distribution`. Expand the box below for a list of all available resource types and their VQL equivalents.
```sql theme={null}
resources.provider = 'aws' AND (resources.type != 'aws_cloudfront_distribution')
```
| Provider | VQL Representation | Friendly Name |
| - | - | - |
| AWS | aws\_app\_stream\_fleet | App Stream Fleet |
| AWS | aws\_app\_stream\_image\_builder | App Stream Image Builder |
| AWS | aws\_auto\_scaling\_group | Auto Scaling Group |
| AWS | aws\_backup\_vault\_recovery\_point | Backup Vault Recovery Point |
| AWS | aws\_batch\_job\_definition | Batch Job Definition |
| AWS | aws\_carrier\_gateway | Carrier Gateway |
| AWS | aws\_cloudfront\_distribution | CloudFront Distribution |
| AWS | aws\_cloudtrail | CloudTrail |
| AWS | aws\_cloudwatch\_log\_group | CloudWatch Log Group |
| AWS | aws\_codebuild\_project | CodeBuild Project |
| AWS | aws\_codepipeline | CodePipeline |
| AWS | aws\_config\_config\_rule | Config Rule |
| AWS | aws\_db\_instance | RDS Instance |
| AWS | aws\_db\_snapshot | RDS Snapshot |
| AWS | aws\_docdb\_cluster\_instance | DocumentDB Cluster Instance |
| AWS | aws\_dx\_connection | Direct Connect Connection |
| AWS | aws\_dx\_virtual\_interface | Direct Connect Virtual Interface |
| AWS | aws\_dynamodb\_table | DynamoDB Table |
| AWS | aws\_ebs\_volume | EBS Volume |
| AWS | aws\_ec2\_managed\_prefix\_list | EC2 Managed Prefix List |
| AWS | aws\_ec2\_reserved\_instance | EC2 Reserved Instance |
| AWS | aws\_ec2\_transit\_gateway | EC2 Transit Gateway |
| AWS | aws\_ecr\_repository | ECR Repository |
| AWS | aws\_ecs\_service | ECS Service |
| AWS | aws\_ecs\_task\_definition | ECS Task Definition |
| AWS | aws\_efs\_file\_system | EFS File System |
| AWS | aws\_egress\_only\_internet\_gateway | Egress-Only Internet Gateway |
| AWS | aws\_eip | Elastic IP |
| AWS | aws\_eks\_cluster | EKS Cluster |
| AWS | aws\_elasticache\_cluster | ElastiCache Cluster |
| AWS | aws\_elasticsearch\_domain | Elasticsearch Domain |
| AWS | aws\_emr\_cluster | EMR Cluster |
| AWS | aws\_flow\_log | Flow Log |
| AWS | aws\_fsx\_volume | FsX Volume |
| AWS | aws\_fsx\_file\_system | FsX File System |
| AWS | aws\_glacier\_vault | Glacier Vault |
| AWS | aws\_globalaccelerator\_accelerator | Global Accelerator |
| AWS | aws\_glue\_job | Glue Job |
| AWS | aws\_instance | EC2 Instance |
| AWS | aws\_internet\_gateway | Internet Gateway |
| AWS | aws\_kms\_key | KMS Key |
| AWS | aws\_lambda\_function | Lambda Function |
| AWS | aws\_lb | Load Balancer |
| AWS | aws\_mediaconnect\_flow | MediaConnect Flow |
| AWS | aws\_mediaconvert\_job | MediaConvert Job |
| AWS | aws\_medialive\_channel | MediaLive Channel |
| AWS | aws\_media\_package\_channel | MediaPackage Channel |
| AWS | aws\_media\_package\_vod\_asset | MediaPackage VOD Asset |
| AWS | aws\_media\_store\_container | MediaStore Container |
| AWS | aws\_media\_tailor\_channel | MediaTailor Channel |
| AWS | aws\_media\_tailor\_playback\_configuration | MediaTailor Playback Configuration |
| AWS | aws\_memorydb\_cluster | MemoryDB Cluster |
| AWS | aws\_mq\_broker | MQ Broker |
| AWS | aws\_msk\_cluster | MSK Cluster |
| AWS | aws\_nat\_gateway | NAT Gateway |
| AWS | aws\_neptune\_cluster\_instance | Neptune Cluster Instance |
| AWS | aws\_network\_interface | Network Interface |
| AWS | aws\_outposts\_outpost | Outposts Outpost |
| AWS | aws\_rds\_reserved\_instance | RDS Reserved Instance |
| AWS | aws\_redshift\_cluster | Redshift Cluster |
| AWS | aws\_report\_definition | Report Definition |
| AWS | aws\_route53\_resolver\_query\_log\_config | Route 53 Resolver Query Log Config |
| AWS | aws\_route53\_zone | Route 53 Zone |
| AWS | aws\_route\_table | Route Table |
| AWS | aws\_s3\_bucket | S3 Bucket |
| AWS | aws\_sagemaker\_model | SageMaker Model |
| AWS | aws\_savings\_plan | Savings Plan |
| AWS | aws\_secretsmanager\_secret | Secrets Manager Secret |
| AWS | aws\_sns\_topic | SNS Topic |
| AWS | aws\_sqs\_queue | SQS Queue |
| AWS | aws\_subnet | Subnet |
| AWS | aws\_transfer\_server | Transfer Server |
| AWS | aws\_vpc | VPC |
| AWS | aws\_vpc\_endpoint | VPC Endpoint |
| AWS | aws\_vpc\_peering\_connection | VPC Peering Connection |
| AWS | aws\_vpn\_gateway | VPN Gateway |
| AWS | aws\_wafv2\_web\_acl | WAFv2 Web ACL |
| AWS | aws\_workspaces\_workspace | WorkSpaces Workspace |
| Anthropic | anthropic\_api\_key | API Keys |
| Anthropic | anthropic\_user | Users |
| Anthropic | anthropic\_model | Models |
| Azure | azurerm\_application\_gateway | Application Gateway |
| Azure | azurerm\_application\_insights | Application Insights |
| Azure | azurerm\_app\_service\_plan | App Service Plan |
| Azure | azurerm\_firewall | Firewall |
| Azure | azurerm\_snapshot | Snapshot |
| Azure | azurerm\_container\_registry | Container Registry |
| Azure | azurerm\_cosmosdb\_account | CosmosDB Account |
| Azure | azurerm\_databricks\_workspace | Databricks Workspace |
| Azure | azurerm\_managed\_disk | Managed Disk |
| Azure | azurerm\_dns\_zone | DNS Zone |
| Azure | azurerm\_sql\_elasticpool | SQL Elastic Pool |
| Azure | azurerm\_express\_route\_circuit | ExpressRoute Circuit |
| Azure | azurerm\_iothub | IoT Hub |
| Azure | azurerm\_lb | Load Balancer |
| Azure | azurerm\_log\_analytics\_workspace | Log Analytics Workspace |
| Azure | azurerm\_logic\_app\_workflow | Logic App Workflow |
| Azure | azurerm\_kubernetes\_cluster | Kubernetes Cluster |
| Azure | azurerm\_nat\_gateway | NAT Gateway |
| Azure | azurerm\_postgresql\_flexible\_server | PostgreSQL Flexible Server |
| Azure | azurerm\_postgresql\_server | PostgreSQL Server |
| Azure | azurerm\_powerbi\_dedicated\_capacity | Power BI Dedicated Capacity |
| Azure | azurerm\_private\_endpoint | Private Endpoint |
| Azure | azurerm\_public\_ip | Public IP |
| Azure | azurerm\_backup\_protected\_item | Backup Protected Item |
| Azure | azurerm\_recovery\_services\_vault | Recovery Services Vault |
| Azure | azurerm\_redis\_cache | Redis Cache |
| Azure | azurerm\_security\_center\_pricing | Security Center Pricing |
| Azure | azurerm\_sql\_database | SQL Database |
| Azure | azurerm\_sql\_managed\_instance | SQL Managed Instance |
| Azure | azurerm\_storage\_account | Storage Account |
| Azure | azurerm\_synapse\_workspace | Synapse Workspace |
| Azure | azurerm\_virtual\_machine | Virtual Machine |
| Azure | azurerm\_virtual\_machine\_scale\_set | Virtual Machine Scale Set |
| Azure | azurerm\_virtual\_network\_gateway | Virtual Network Gateway |
| ClickHouse Cloud | clickhouse\_service | Services |
| Confluent | confluent\_kafka\_cluster | Kafka Cluster |
| Datadog | datadog\_custom\_metric | Custom Metric |
| Google | google\_alloydb\_backup | AlloyDB Backup |
| Google | google\_alloydb\_cluster | AlloyDB Cluster |
| Google | google\_alloydb\_instance | AlloyDB Instance |
| Google | google\_app\_engine\_service | App Engine Service |
| Google | google\_bigquery\_dataset | BigQuery Dataset |
| Google | google\_bigtable\_instance | Bigtable Instance |
| Google | google\_compute\_disk | Compute Disk |
| Google | google\_compute\_instance | Compute Instance |
| Google | google\_container\_cluster | Container Cluster |
| Google | google\_dataflow\_job | Dataflow Job |
| Google | google\_firestore\_database | Firestore Database |
| Google | google\_cloudfunctions\_function | Cloud Functions Function |
| Google | google\_logging\_project\_bucket\_config | Logging Project Bucket Config |
| Google | google\_redis\_instance | Redis Instance |
| Google | google\_cloud\_run\_service | Cloud Run Service |
| Google | google\_secret\_manager\_secret | Secret Manager Secret |
| Google | google\_spanner\_instance | Spanner Instance |
| Google | google\_sql\_database\_instance | SQL Database Instance |
| Google | google\_storage\_bucket | Storage Bucket |
| Kubernetes | kubernetes\_workload | Kubernetes Workload |
| Linode | linode\_instance | Instances |
| Linode | linode\_node\_balancer | Node Balancer |
| Linode | linode\_node\_balancer\_type | Node Balancer Type |
| Linode | linode\_volume | Volume |
| Linode | linode\_volume\_type | Volume Type |
| Linode | linode\_object\_storage | Object Storage |
| Linode | linode\_linode\_type | Linode Type |
| Linode | linode\_object\_storage\_type | Object Storage Type |
| Linode | linode\_kubernetes\_cluster | Kubernetes Clusters |
| Linode | linode\_kubernetes\_type | Kubernetes Type |
| Linode | linode\_image | Images |
| Modal | modal\_app | App |
| MongoDB | mongodbatlas\_cluster | Atlas Cluster |
| OpenAI | open\_ai\_api\_key | API Keys |
| PlanetScale | planetscale\_database | Database |
| Snowflake | snowflake\_query | Queries |
| Temporal | temporal\_namespace | Namespaces |
### Resources by Label
Resources by specific label.
```sql theme={null}
resources.provider = 'aws' AND resources.label = '123456'
```
### Resources for Specific ARN
The UUID is the unique identifier for the resource. In the case of AWS resources, this is the ARN. The below example shows a query for resources that contain specific text within the ARN.
```sql theme={null}
resources.provider = 'aws' AND resources.uuid LIKE '%arn:aws:s3:::my-bucket%'
```
### Resources by Metadata
Resource metadata queries require both `provider` and `type` as well as `metadata`. Metadata uses a specific syntax (e.g., `resources.metadata->>'domain' = 'vantage.sh'`).
```sql theme={null}
resources.provider = 'aws' AND (resources.type = 'aws_cloudfront_distribution' AND resources.metadata->>'domain' = 'vantage.sh')
```
### Filter by Tag
Filter resources based on a specific tag, such as `terraform`, with the value `true`, in AWS.
```sql theme={null}
resources.provider = 'aws' AND (tags.name = 'terraform' AND tags.value = 'true')
```
### Filter for Untagged Resources
On providers that have a **Not Tagged** filter option in the console, you can use the below VQL to see untagged resources. This example looks for untagged resources in a multi-cloud environment.
```sql theme={null}
(resources.provider = 'gcp' AND tags.name = NULL) OR (resources.provider = 'aws' AND tags.name = NULL)
```
### Real-World Examples
Find production compute resources in approved AWS regions:
```sql theme={null}
resources.provider = 'aws' AND resources.region IN ('us-east-1', 'us-west-2') AND resources.type = 'aws_instance' AND tags.name = 'environment' AND tags.value = 'production'
```
Find public IP and load balancer resources in an Azure subscription:
```sql theme={null}
resources.provider = 'azure' AND resources.account_id = 'subscription-1234' AND resources.type IN ('azurerm_public_ip', 'azurerm_lb')
```
Find x86 AWS instances managed by Terraform:
```sql theme={null}
resources.provider = 'aws' AND resources.type = 'aws_instance' AND resources.metadata->>'architecture' = 'x86_64' AND tags.name = 'terraform' AND tags.value = 'true'
```
## Troubleshooting
* Wrap string values in single quotes, not double quotes.
* Use the normalized provider and resource type values shown by **View as VQL**.
* Include both `resources.provider` and `resources.type` when filtering `resources.metadata`.
* Keep complete conditions together when mixing `AND` and `OR`; use parentheses to separate each branch.
# VQL for Virtual Tags
Source: https://docs.vantage.sh/vql_virtual_tags
Learn how to use VQL to define Virtual Tag values, cost allocations, and collapsed tag keys in the Vantage API and Terraform provider.
Virtual Tags use VQL to determine which costs receive a value or allocation. Virtual Tag filters use the same `costs` and `tags` schema, keywords, and syntax as Cost Reports.
To build a Virtual Tag filter in the console, navigate to the [**Tags** page](https://console.vantage.sh/settings/tags), create or edit a Virtual Tag, and add a value. In an input or output costs filter, click **View as VQL**, then **Edit VQL**, to edit the query directly.
You must have the Organization Owner role to edit Virtual Tag VQL in the console.
## Where Virtual Tags Use VQL
A Virtual Tag configuration can contain VQL in the following locations:
| Location | API or Terraform field | Purpose |
| - | - | - |
| [Value output filter](#value-output-filters) | `values[].filter` | Identifies the costs that receive a custom value or that are allocated using a business metric, cost metric, or percentages |
| [Cost-based input filter](#cost-based-allocation-filters) | `values[].cost_metric.filter` | Identifies the input costs used to calculate the allocation percentages |
| [Collapsed tag key filter](#collapsed-tag-key-filters) | `collapsed_tag_keys[].filter` | Limits the costs for which values from a collapsed tag key are copied into the Virtual Tag |
The API examples on this page are request bodies for [`POST /v2/virtual_tag_configs`](https://docs.vantage.sh/api/virtualtags/create-virtual-tag-config).
The order of objects in `values` determines precedence among value filters. When more than one value filter matches a cost, Vantage applies the first matching value. Value filters also take precedence over [collapsed tag keys](#collapsed-tag-key-filters).
## Schema
The schema below is the same one used for [Cost Reports](/vql_cost_report).
VQL comprises two namespaces: `costs` and `tags`, which represent the available [filters](/cost_reports#filter-cost-reports) on Cost Reports in the Vantage console. Reference a filter as `namespace.field`, such as `costs.provider` or `tags.name`.
Availability of the fields listed below varies among different cloud providers. For a comprehensive list of available fields per provider, including the source billing field each one maps to, see the [Data Dictionary](/data_dictionary).
| Namespace | Field | Description | Example |
| - | - | - | - |
| `costs` | `provider` (optional) | Provider that generated the cost | [Filter across all providers](/vql_cost_report#filter-across-all-providers) or [combine providers](/vql_cost_report#combining-providers) |
| `costs` | `allocation` | Fraction of a cost allocated to the result | [Cost allocation](/vql_cost_report#cost-allocation) |
| `costs` | `region` | Provider region associated with the cost | [Regions](/vql_cost_report#costs-from-a-list-of-regions) |
| `costs` | `marketplace` | Whether an AWS cost is a Marketplace transaction | [Marketplace transactions](/vql_cost_report#get-marketplace-transactions) |
| `costs` | `account_id` | Resource account, project, or subscription identifier | [Account ID](/vql_cost_report#costs-by-account-id) |
| `costs` | `provider_account_id` | Billing account identifier | [Provider account ID](/vql_cost_report#costs-by-provider-account-id) |
| `costs` | `service` | Normalized provider service name | [Service](/vql_cost_report#per-resource-costs-and-costs-by-service) |
| `costs` | `category` | Normalized cost category | [Category](/vql_cost_report#costs-by-specific-category) |
| `costs` | `subcategory` | Provider-specific cost subcategory | [Subcategory](/vql_cost_report#costs-by-specific-subcategory) |
| `costs` | `resource_id` | Provider identifier for a resource | [Resource ID](/vql_cost_report#per-resource-costs-and-costs-by-service) |
| `costs` | `charge_type` | Normalized charge type, such as usage or credit | [Charge type](/vql_cost_report#cost-by-charge-type) |
| `costs` | `usage_unit` | Unit used to measure usage | [Usage unit](/vql_cost_report#filter-by-usage-unit) |
| `tags` | `name` | Provider or Virtual Tag key | [Tags](/vql_cost_report#filter-by-tag) |
| `tags` | `value` | Value associated with a tag key | [Untagged costs](/vql_cost_report#filter-for-untagged-resources) |
`costs.provider` is optional. Omit it to filter across every connected provider in a single query—see [Filter Across All Providers](/vql_cost_report#filter-across-all-providers). Provider-specific fields (such as AWS `costs.marketplace`) only apply when `costs.provider` is included for that provider.
## Keywords
The keywords below are the same ones used for [Cost Reports](/vql_cost_report).
VQL includes a set of keywords to create complex filter conditions. These keywords function similar to their SQL equivalents.
| Keyword | Description | VQL Sample | Explanation |
| - | - | - | - |
| `AND` | Logical AND operator | `costs.provider = 'aws' AND costs.service = 'Amazon Elastic Compute Cloud - Compute'` | This example filters AWS costs for the Amazon Elastic Compute Cloud - Compute service, where both conditions must be true. |
| `OR` | Logical OR operator | `costs.provider = 'azure' OR costs.provider = 'aws'` | This example retrieves costs from either Azure or AWS. At least one condition must be true. |
| `IN` | Used to compare against an array list | `costs.provider = 'azure' AND costs.account_id IN ('account-1', 'account-2')` | This example filters based on a list of account IDs, returning data for the specified accounts.
You can also use `IN` along with a special syntax for filtering by multiple tags. See [Filter by Multiple Tags](/vql_cost_report#filter-by-multiple-tags) for details.
`costs.provider IN (...)` is supported and is expanded into one filter set per provider. `costs.provider NOT IN (...)` is not supported. |
| `LIKE` | Performs string comparisons | `costs.provider = 'gcp' AND tags.name = 'environment' AND tags.value LIKE '%prod%'` | This example selects data where the tag value contains `prod`, such as `production-1`. |
| `NOT` | Represents negation | `costs.provider = 'aws' AND costs.region NOT IN ('us-east-1', 'us-east-2')` | This example filters out data from both specified regions, providing all AWS costs *not* in these regions. Use `NOT IN` to specify a list of single or multiple values.
You can also use the `!=` or `<>` operators for "is not."
`costs.provider = 'aws' AND costs.region != 'us-east-1'`
You can use `NOT LIKE` to perform string comparisons:
`costs.provider = 'gcp' AND tags.name = 'environment' AND tags.value NOT LIKE '%prod%'` |
| `~*` | Flexible match operator for tag values | `costs.provider = 'aws' AND (tags.name = 'teams' AND tags.value ~* 'Team A')` | Searches for all items where the tag value loosely matches `Team A`, ignoring case, whitespace, hyphens, and punctuation. |
| `!~*` | Negated flexible match operator for tag values | `costs.provider = 'aws' AND (tags.name = 'teams' AND tags.value !~* 'Team A')` | Filters out all items where the tag value loosely matches `Team A`, ignoring case, whitespace, hyphens, and punctuation. |
With these keywords, you can construct complex filter conditions in VQL, providing flexibility and precision when querying and analyzing cloud cost data.
## Syntax
The syntax below is the same one used for [Cost Reports](/vql_cost_report).
You can think of VQL in its current iteration as the `WHERE` clause of a SQL query. By combining the schema and keywords above with parentheses, you can form complex filter operations, such as:
```vql theme={null}
(costs.provider = 'mongo' AND costs.allocation = 1.0 AND (costs.service = 'REALM' AND costs.resource_id IN ('s3'))) OR (costs.provider = 'aws' AND costs.allocation = 1.0 AND costs.account_id IN ('123456789012'))
```
## Value Output Filters
Every object in `values` requires a `filter`. For a custom value, the filter identifies the costs assigned that value. For business metric, cost-based, and percent-based values, it identifies the output costs to allocate.
The following examples map AWS accounts to team values. Because `Platform` appears first, it takes precedence if the filters overlap.
```json theme={null}
{
"key": "Team",
"overridable": false,
"values": [
{
"name": "Platform",
"filter": "costs.provider = 'aws' AND costs.account_id IN ('111111111111', '222222222222')"
},
{
"name": "Data",
"filter": "costs.provider = 'aws' AND costs.account_id = '333333333333'"
}
]
}
```
```terraform theme={null}
resource "vantage_virtual_tag_config" "team" {
key = "Team"
overridable = false
values = [
{
name = "Platform"
filter = "costs.provider = 'aws' AND costs.account_id IN ('111111111111', '222222222222')"
},
{
name = "Data"
filter = "costs.provider = 'aws' AND costs.account_id = '333333333333'"
}
]
}
```
### Business Metric and Percentage Output Filters
Business metric and percent-based values also use `values[].filter` as their output costs filter:
```json theme={null}
{
"key": "Allocated Team",
"overridable": false,
"values": [
{
"business_metric_token": "bsnss_mtrc_1234",
"label_key": "team",
"filter": "costs.provider = 'aws' AND costs.service = 'Amazon Elastic Compute Cloud - Compute'"
},
{
"display_name": "Shared support",
"filter": "costs.provider = 'aws' AND costs.service = 'AWS Support (Business)'",
"percentages": [
{ "value": "Platform", "pct": 60 },
{ "value": "Data", "pct": 40 }
]
}
]
}
```
```terraform theme={null}
resource "vantage_virtual_tag_config" "allocated_team" {
key = "Allocated Team"
overridable = false
values = [
{
business_metric_token = "bsnss_mtrc_1234"
label_key = "team"
filter = "costs.provider = 'aws' AND costs.service = 'Amazon Elastic Compute Cloud - Compute'"
},
{
display_name = "Shared support"
filter = "costs.provider = 'aws' AND costs.service = 'AWS Support (Business)'"
percentages = [
{ value = "Platform", pct = 60 },
{ value = "Data", pct = 40 }
]
}
]
}
```
`label_key` selects the [label column](/business_metrics#labeled-business-metrics) whose values become the tag values, and it's required for business metrics that support named label columns. Business metrics created before multiple label columns were supported use a single `label` column; omit `label_key` for those metrics, because Vantage rejects it.
### Normalize Values Across Tag Keys
Use a value filter to map inconsistent provider tag keys to one Virtual Tag value. Repeat the provider condition in each `OR` branch so each branch forms a complete filter set:
```sql theme={null}
(costs.provider = 'aws' AND tags.name = 'environment' AND tags.value = 'production') OR (costs.provider = 'aws' AND tags.name = 'env' AND tags.value = 'prod') OR (costs.provider = 'aws' AND tags.name = 'stage' AND tags.value = 'production')
```
## Cost-Based Allocation Filters
A cost-based value uses two VQL filters:
* `values[].filter` selects the output costs to allocate.
* `values[].cost_metric.filter` selects the input costs used to calculate the allocation percentages.
For most cost-based allocations, include `costs.charge_type = 'Usage'` in the input filter so credits, taxes, and fees do not affect the allocation.
```json theme={null}
{
"key": "Team",
"overridable": false,
"values": [
{
"display_name": "Allocate shared infrastructure",
"filter": "costs.provider = 'aws' AND costs.service = 'Amazon Elastic Compute Cloud - Compute'",
"cost_metric": {
"filter": "costs.provider = 'aws' AND costs.charge_type = 'Usage' AND tags.name = 'team'",
"aggregation": {
"tag": "team"
}
}
}
]
}
```
```terraform theme={null}
resource "vantage_virtual_tag_config" "team_allocation" {
key = "Team"
overridable = false
values = [
{
display_name = "Allocate shared infrastructure"
filter = "costs.provider = 'aws' AND costs.service = 'Amazon Elastic Compute Cloud - Compute'"
cost_metric = {
filter = "costs.provider = 'aws' AND costs.charge_type = 'Usage' AND tags.name = 'team'"
aggregation = {
tag = "team"
}
}
}
]
}
```
## Collapsed Tag Key Filters
[Tag Key Collapsing](/tagging#tag-key-collapsing) copies the values of an existing tag key, either a provider tag or another Virtual Tag, into this Virtual Tag. Use `collapsed_tag_keys[].filter` to restrict which costs are eligible.
When `filter` is set, do not also set `providers`. Put provider restrictions directly in the VQL filter. If you need only provider-level scoping and no other conditions, use `providers` instead of `filter`.
Collapsed tag keys follow these precedence rules:
* If a value filter and a collapsed tag key both match a cost, the value filter's value is applied.
* If more than one collapsed tag key matches a cost, the key listed first is applied.
```json theme={null}
{
"key": "Environment",
"overridable": false,
"collapsed_tag_keys": [
{
"key": "environment",
"filter": "costs.provider = 'aws' AND costs.account_id IN ('111111111111', '222222222222')"
},
{
"key": "env",
"filter": "costs.provider = 'gcp'"
}
]
}
```
```terraform theme={null}
resource "vantage_virtual_tag_config" "environment" {
key = "Environment"
overridable = false
collapsed_tag_keys = [
{
key = "environment"
filter = "costs.provider = 'aws' AND costs.account_id IN ('111111111111', '222222222222')"
},
{
key = "env"
filter = "costs.provider = 'gcp'"
}
]
}
```
## Nested Virtual Tags
To reference an existing Virtual Tag, use its key and value with the `tags` namespace, just as you would use a provider tag:
```sql theme={null}
costs.provider = 'aws' AND tags.name = 'Environment' AND tags.value = 'Production'
```
This example can be used as the output filter for a second Virtual Tag. Vantage evaluates nested tags in dependency order.
Nested Virtual Tags cannot contain cyclical references, such as Tag A referencing Tag B while Tag B references Tag A. A filter that references the Virtual Tag's own key isn't a cycle; it matches the provider tag with the same key. If a nested relationship includes cost allocation, every referenced allocated tag must belong to the same provider-specific allocation chain. See [Nested Virtual Tags](/tagging#nested-virtual-tags) for configuration details and limitations.
## Performance Guidelines
* Scope a filter to the providers it needs. A filter without `costs.provider` is evaluated against every connected provider.
* Prefer exact matches with `=` and `IN` over `LIKE`, `NOT LIKE`, `~*`, and `!~*`.
* When a filter applies to only a few providers, use a complete provider-specific expression in each `OR` branch.
* Put high-volume value rules first so most costs match early.
See [Best Practices for Filtering Across All Providers](/tagging#best-practices-for-filtering-across-all-providers) for more guidance.
## Troubleshooting
* Wrap string values in single quotes, not double quotes.
* Do not use a saved filter to define a Virtual Tag value. Enter or paste the VQL expression directly.
* Do not combine `providers` and `filter` on the same collapsed tag key.
* If multiple value filters match the same cost, reorder the values so the intended value appears first.
* If a nested tag fails validation, check for a cyclical reference between tags or a reference to an allocated tag outside the same provider-specific allocation chain.
* `costs.provider IN (...)` is supported, but `costs.provider NOT IN (...)` is not.
* For invalid VQL, Vantage returns a `filter:` error. An invalid cost-based input filter returns a `cost metrics filter:` error.
# Workspaces
Source: https://docs.vantage.sh/workspaces
Organize cloud cost data with Vantage workspaces.
In Vantage, a *workspace* is a way to separate your provider integrations into distinct cost views. Teams can use workspaces to create focused views of costs and even restrict access to costs within each workspace using [Role-Based Access Controls (RBAC)](/rbac) (Enterprise customers). You can specify which [integrations](/workspaces#manage-workspace-provider-integrations) are available in which workspaces. Some use cases for workspaces are listed below.
* You may have multiple accounts within the same cloud provider, such as Azure or AWS. You can use a single Vantage workspace to ingest costs for all these accounts into the same view.
* Create a distinct Vantage workspace for each of your environments, such as *Production*, *Staging*, and *Development*. Then, specify which provider accounts are associated with which workspace. For example, a particular Datadog account may be associated with only your *Development* workspace.
* If you manage multiple customers, you can create individual workspaces for each customer account (Customer A, Customer B, etc.). This allows you to separate and manage cost data for each customer independently. Then, you can connect only the corresponding integrations to each customer's workspace, ensuring that they have access only to their data and reports.
To get started with workspaces and workspace integrations, you can also view a video demo on [Vantage University](/vantage_university_account_management) .
## Navigate between Workspaces
If you have more than one workspace in your Vantage account, the **Workspaces** menu is displayed on the top left of the console. You can select any of the listed workspaces to move between each workspace.
## Create a Workspace
When your Vantage account is created, you are assigned a **Default** workspace. You can create other workspaces in addition to the default workspace. To create a new workspace, complete the following steps:
From the top navigation menu, click **Settings**.
On the left navigation, under **General Settings**, click **Workspaces**.
Click **Create a Workspace**.
Enter a **Name** for your new workspace (e.g., *Management*), then click **Create**.
## Manage Workspaces
All your existing workspaces are displayed on the [**Workspaces**](https://console.vantage.sh/settings/workspaces) Settings screen. Select a listed workspace to view additional details, such as:
* Turn off **Active Resource Syncing**. Turn off automatic syncing if you do not want Vantage to be automatically pulling active resource details from your account. This option is useful if you find Vantage is making too many API calls to your AWS endpoints.
* View team workspace access. See the [Role-Based Access Control](/rbac) documentation for more information about teams.
* View configuration details for the workspace, including the workspace token, which is used as the workspace identifier in [API calls](/api).
* Delete the workspace.
Note that this action is not reversible.
## Manage Workspace Provider Integrations
Once you connect a cloud provider to Vantage, and the integration status is **Stable** with costs fully imported, you'll need to specify the workspaces where this integration should be accessible for creating reports and viewing costs. To manage the workspaces associated with an integration:
From the top navigation, click **Settings**.
From the left navigation, click **Integrations**.
All your provider integrations are displayed. Select an integration from the list.
The provider's integration page is displayed. Click the settings icon next to a listed account.
The **Manage Connection** page is displayed. Under **Workspace Access**, select or deselect the checkbox next to a listed workspace to specify which workspaces the integration is associated with.
An integration can be fully healthy and still not appear in Cost Reports, Dashboards, or other features until both of the following are true:
* The integration is assigned to the workspace you are currently viewing.
* Your user or team can access that workspace.
If an integration looks **Stable** on the Integrations page but you still cannot see its costs, first verify workspace assignment and workspace access before troubleshooting the provider connection itself.
Workspaces are the boundary for cost data visibility. Sharing a Cost Report, Dashboard, or other Cost Reporting item lets recipients view that item, but it does not lock the item's filters as a security boundary. If a team should only see a subset of provider data, assign only the corresponding provider integrations to a separate workspace and grant that team access to that workspace.
**AWS Management Account and Member Accounts**
When you connect an AWS management account (root account) to Vantage, all member accounts in your AWS organization are automatically linked to the management account. Member accounts inherit the workspace assignments from the management account and cannot be assigned to different workspaces while they remain linked.
If you want to assign a member account to a separate workspace from the management account, you must first unlink it from the management account. When viewing a linked member account's integration settings, you'll see a message stating: "To assign this account to separate workspaces, you must first unlink it from the management account." The workspace checkboxes will be disabled until you click the **Unlink from Management Account** button. Once unlinked, you can then assign the member account to different workspaces independently.
Note that unlinking member accounts has its own implications. See the [Unlinking Member Accounts](/connecting_aws#unlinking-member-accounts) documentation for details.
In the below example, the Fastly integration is only available in the *Demo Accounts* workspace. If you navigate to the *Management* or *Marketing* workspace, you'll be unable to view Fastly cost data in Cost Reports or other Vantage features.